# Mixture of Experts (MoE)

> Source: https://aiwiki.ai/wiki/mixture_of_experts
> Updated: 2026-11-08
> Fact-checked: 2026-10-31
> Categories: AI Inference, Deep Learning, Machine Learning, Neural Networks
> License: CC BY 4.0 (https://creativecommons.org/licenses/by/4.0/) - attribute to "AI Wiki (aiwiki.ai)"
> Cite as: AI Wiki. "Mixture of Experts (MoE)." aiwiki.ai, 8 Nov 2026. https://aiwiki.ai/wiki/mixture_of_experts
> From AI Wiki (https://aiwiki.ai), the free encyclopedia of artificial intelligence. Reuse freely with attribution.

A mixture of experts (MoE) is a [machine-learning](https://aiwiki.ai/wiki/machine_learning) architecture that contains multiple component functions called experts and a gating or routing mechanism that determines how their outputs contribute to a result. In the original formulation, the gate assigned continuous weights to several local expert networks. In many modern sparse MoE systems, the router instead selects only a small subset of experts for each input or token.[1][2][3]

Sparse activation separates two quantities that are identical in a conventional dense layer: the total parameters stored in the layer and the parameters used for one input. Adding experts can therefore increase parameter capacity without requiring every expert to run on every token. It does not make computation or memory constant. Shared layers, the router, selected experts, data movement, and output combination still incur costs, while all expert weights must be stored, sharded, compressed, or loaded somehow.[5][6][12]

An expert is normally a trainable subnetwork inside one [neural network](https://aiwiki.ai/wiki/neural_network), not a separately deployed model. Modern language-model implementations often use independent feed-forward networks as experts in selected blocks of a [Transformer](https://aiwiki.ai/wiki/transformers), while leaving attention and other parts dense. MoE is not limited to Transformers, language models, or sparse routing, and learned experts are not guaranteed to correspond to human-readable topics.[3][9]

<div class="my-6">
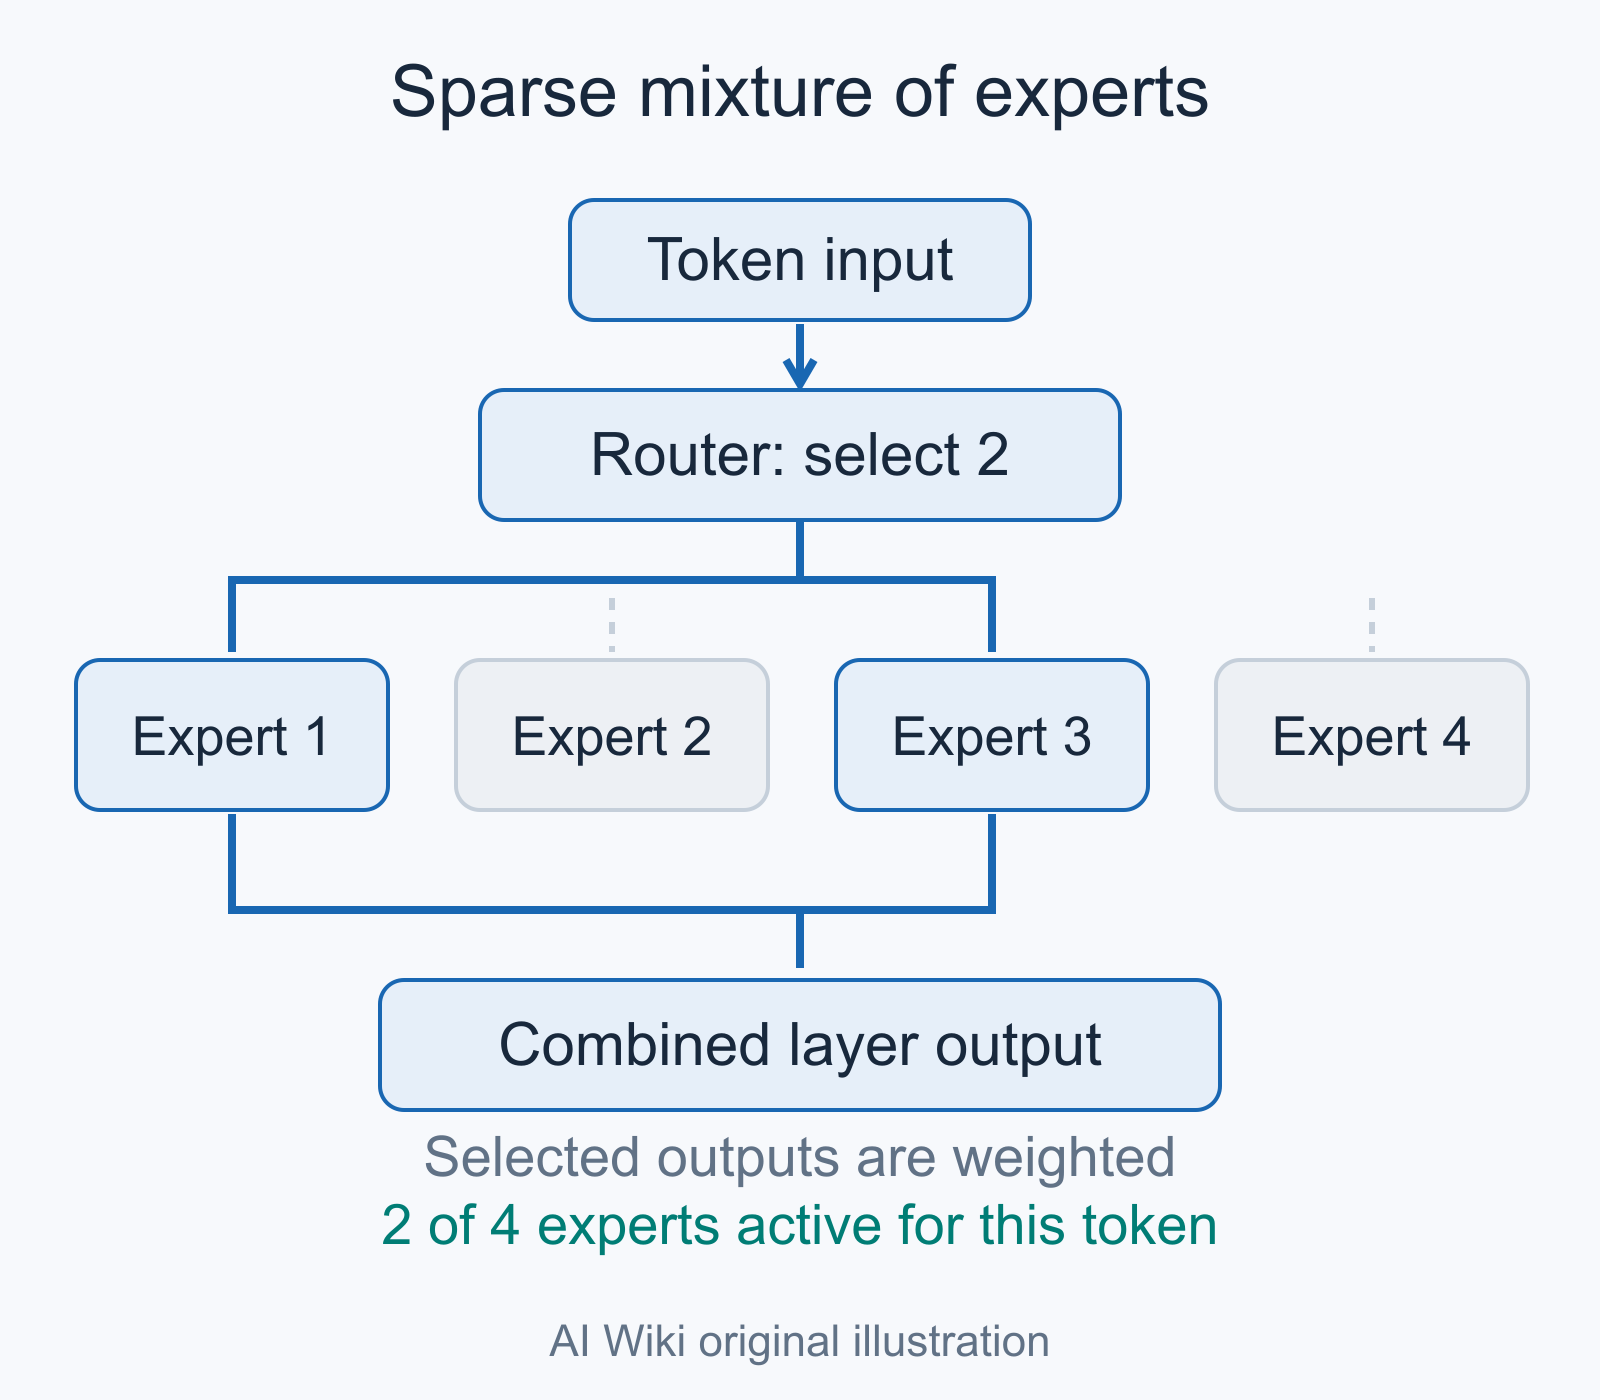
<div><a href="https://aiwiki.ai/images/audit-fill-2026-10-05-mixture_of_experts-5e5b69021c82.png"><img src="/images/audit-fill-2026-10-05-mixture_of_experts-5e5b69021c82.png" alt="Original diagram of a token routed to experts 1 and 3 out of four, followed by weighted output combination." /></a></div>
<p>Illustrative top-2 routing: a router selects two of four experts for one token, then their weighted outputs are combined. The expert count and selection are examples, not a named model specification.[21] Illustration: <a href="https://aiwiki.ai/images/audit-fill-2026-10-05-mixture_of_experts-5e5b69021c82.png">AI Wiki original diagram</a>. <a href="https://creativecommons.org/publicdomain/zero/1.0/">CC0 1.0</a>.</p>
</div>

## Core architecture

Let $$x$$ be an input representation and let $$E_i(x)$$ denote the output of expert $$i$$. A router produces a score $$s_i(x)$$ for each of $$N$$ experts. A common token-choice implementation converts the scores to probabilities, selects a set $$S_k(x)$$ containing the $$k$$ highest-scoring experts, and combines their outputs:

$$
y(x)=\sum_{i\in S_k(x)} \alpha_i(x)E_i(x).
$$

The coefficients $$\alpha_i(x)$$ are derived from the router scores. They may be normalized across all experts before selection, renormalized across the selected experts, or handled in another implementation-specific way. The sparse selection means that only the chosen expert functions run for that token, but dense attention, normalization, residual paths, embeddings, and other shared components still run if the surrounding model contains them.[4][5]

In a typical language-model MoE block, the router operates on each token representation and replaces one or more dense feed-forward sublayers with a bank of expert feed-forward networks. GShard used a form of top-2 token routing in a multilingual [machine-translation](https://aiwiki.ai/wiki/machine_translation) Transformer, while the [Switch Transformer](https://aiwiki.ai/wiki/switch_transformer) simplified this design to one selected expert per token.[4][5] These are influential designs, not definitions of MoE.

Three parameter counts should be distinguished:

- **Total parameters** include every expert and all shared components.
- **Active parameters for one token** include the selected experts plus the shared components used for that token.
- **Parameters touched by a batch or sequence** are the union of the parameters activated by all of its tokens and can approach the total model size even when each individual token uses few experts.[12]

The same distinction applies to computation. Sparse expert activation can reduce expert arithmetic relative to evaluating every expert, but per-token floating-point operations also include the dense parts of the model. Router and communication work can be material at distributed scale.[5][11][20]
<figure class="embedvideo">
<iframe src="https://www.youtube-nocookie.com/embed/sYDlVVyJYn4" title="What is Mixture of Experts?"></iframe>
<figcaption>"What is Mixture of Experts?", video from IBM Technology, published August 28, 2024. <a href="https://www.youtube.com/watch?v=sYDlVVyJYn4">Watch on YouTube</a>.</figcaption>
</figure>

## Historical development

Robert Jacobs, [Michael Jordan](https://aiwiki.ai/wiki/michael_i_jordan), Steven Nowlan, and [Geoffrey Hinton](https://aiwiki.ai/wiki/geoffrey_hinton) introduced adaptive mixtures of local experts in a 1991 Neural Computation paper. They presented a supervised learning procedure for systems composed of many separate networks, each of which learns to handle a subset of the complete set of training cases, with a gating network assigning input-dependent mixture weights. In their demonstration, the procedure divided a vowel discrimination task into subtasks that very simple expert networks could solve.[1] Michael Jordan and Robert Jacobs extended the idea in 1994 with a hierarchical mixture in which gating and expert components were arranged as a tree. Both the mixture coefficients and the mixture components were generalized linear models, learning was posed as a maximum-likelihood problem, and the parameters were fitted with an expectation-maximization (EM) algorithm; the paper also gave an on-line learning variant.[2]

The modern large-scale sparse line developed from conditional computation. In 2017, [Noam Shazeer](https://aiwiki.ai/wiki/noam_shazeer) and colleagues described a sparsely gated MoE layer with up to thousands of feed-forward experts and a trainable gate that chose a sparse combination for each example.[3] Their noisy top-k gating added tunable Gaussian noise to the gate logits and kept only the $$k$$ largest values before the softmax, so that only $$k$$ experts had to be evaluated; the noise was included to help load balancing.[3] The MoE layers were applied convolutionally between stacked [LSTM](https://aiwiki.ai/wiki/lstm) layers for language modeling and translation, showing that the idea did not depend on the Transformer architecture. The largest language models had up to 131,072 experts, corresponding to up to 137 billion parameters in the MoE layer. After training on 100 billion words, the authors reported that test perplexity improved up to 65,536 experts and degraded at 131,072, possibly because of too much sparsity.[3]

GShard (posted in June 2020 and presented at ICLR 2021) combined sparse MoE layers, a variant of top-2 gating, and automatic sharding through annotation APIs and an extension to the XLA compiler. It replaced every other feed-forward layer of a multilingual translation Transformer with an MoE layer and scaled the model beyond 600 billion parameters, which the authors trained on 2,048 TPU v3 accelerators in 4 days for translation from 100 languages into English.[4] Switch Transformer (posted in January 2021 and published in JMLR in 2022) studied top-1 routing, expert capacity, load-balancing losses, selective router precision, and combinations of data, model, and expert parallelism.[5] Its authors reported up to 7x increases in pre-training speed over T5-Base and T5-Large baselines with the same computational resources, and trained a Switch-C model with 1.6 trillion parameters and 2,048 experts.[5]

GLaM (posted in December 2021 and presented at ICML 2022) was a decoder-only language model that, like GShard, replaced the feed-forward component of every other Transformer layer with an MoE layer and activated the best two experts for each token. Its largest version had 1.2 trillion total parameters with 64 experts per MoE layer and activated 96.6 billion parameters (8% of the total) per token. The authors reported that it consumed one third of the energy used to train [GPT-3](https://aiwiki.ai/wiki/gpt-3) and required half the inference computation while achieving better overall zero-shot, one-shot, and few-shot performance across 29 NLP tasks.[46] ST-MoE (February 2022) addressed training instability and uncertain fine-tuning quality, introduced the router z-loss, and scaled a sparse encoder-decoder model to 269 billion parameters with a computational cost comparable to a 32-billion-parameter dense model.[9]

Later work broadened the design space rather than establishing one standard recipe: balanced assignment, expert-choice routing, soft routing, dropless sparse kernels, fine-grained experts, shared experts, and continuous sparse routers each address different optimization or systems constraints.[7][8][10][15][16][18][19] Open-weight MoE language models became common from late 2023. [Mistral AI](https://aiwiki.ai/wiki/mistral_ai) announced [Mixtral 8x7B](https://aiwiki.ai/wiki/mixtral) under the Apache 2.0 license on 11 December 2023, describing a decoder-only model whose feed-forward block picks from 8 distinct groups of parameters, with a router choosing two of them for every token at every layer.[47] The accompanying paper, posted in January 2024, gives 47 billion total and 13 billion active parameters.[41] DeepSeekMoE (January 2024; ACL 2024) proposed fine-grained expert segmentation and shared expert isolation, and DeepSeek-V3 (December 2024) paired that architecture with auxiliary-loss-free load balancing at 671 billion total parameters.[16][28] Sparse MoE feed-forward layers have since been adopted in many open-weight large language models, including Mixtral 8x7B, [DeepSeek-V3](https://aiwiki.ai/wiki/deepseek_v3), [gpt-oss](https://aiwiki.ai/wiki/gpt_oss), and [Kimi K3](https://aiwiki.ai/wiki/kimi_k3); published parameter counts for several of them are listed under Applications.[26][28][35][41]

### Selected milestones

| Year first posted | Work | Contribution | Source |
| --- | --- | --- | --- |
| 1991 | Adaptive mixtures of local experts (Jacobs, Jordan, Nowlan, Hinton) | Gating network assigns input-dependent weights to separate expert networks | [1] |
| 1994 | Hierarchical mixtures of experts (Jordan, Jacobs) | Tree-structured gating and experts trained with EM | [2] |
| 2017 | Sparsely-gated MoE layer (Shazeer et al.) | Noisy top-k gating; up to 137 billion MoE parameters between LSTM layers | [3] |
| 2020 | GShard | Top-2 gating and automatic sharding for a 600-billion-parameter translation Transformer | [4] |
| 2021 | Switch Transformer | Top-1 routing; 1.6-trillion-parameter Switch-C with 2,048 experts | [5] |
| 2021 | BASE Layers | Token-to-expert allocation as a balanced linear assignment | [7] |
| 2021 | V-MoE | Sparse expert layers in a Vision Transformer | [14] |
| 2021 | GLaM | 1.2-trillion-parameter decoder with 96.6 billion parameters active per token | [46] |
| 2022 | ST-MoE | Router z-loss for training stability; 269-billion-parameter sparse model | [9] |
| 2022 | Expert choice routing | Experts select tokens instead of tokens selecting experts | [8] |
| 2022 | Sparse upcycling | MoE initialized from a dense checkpoint | [13] |
| 2023 | Soft MoE | Differentiable slot-based routing | [15] |
| 2023 | Mixtral 8x7B | Open-weight decoder routing each token to 2 of 8 experts | [41][47] |
| 2024 | DeepSeekMoE | Fine-grained routed experts plus always-active shared experts | [16] |
| 2024 | Loss-Free Balancing | Per-expert routing bias replaces the auxiliary balancing loss | [17] |
| 2024 | DeepSeek-V3 | 671 billion total and 37 billion active parameters; auxiliary-loss-free balancing at scale | [28] |

## Routing methods

### Token-choice routing

In token-choice routing, each token independently selects its highest-scoring $$k$$ experts. Top-1 routing minimizes expert computation and routing fan-out, while top-2 or higher $$k$$ evaluates more experts and combines their outputs. Increasing $$k$$ changes both compute and communication, so models with different $$k$$ values are not directly comparable from total parameter count alone.[4][5]

Gate formulas differ between implementations. Shazeer and colleagues wrote the layer output as $$y=\sum_{i=1}^{n}G(x)_iE_i(x)$$, with noisy top-k gating $$G(x)=\mathrm{Softmax}(\mathrm{KeepTopK}(H(x),k))$$ and $$H(x)_i=(x\cdot W_g)_i+\mathrm{StandardNormal}()\cdot\mathrm{Softplus}((x\cdot W_{noise})_i)$$, where KeepTopK leaves the $$k$$ largest values unchanged and sets the others to $$-\infty$$, so their gate values become zero.[3] DeepSeek-V3 instead computes a token-to-expert affinity with a sigmoid, $$s_{i,t}=\mathrm{Sigmoid}(u_t^{T}e_i)$$, where $$u_t$$ is the token's FFN input and $$e_i$$ is a centroid vector for routed expert $$i$$; it keeps the $$K_r$$ highest affinities and normalizes the selected values to produce the gating weights.[28]

The top-$$k$$ operation is discrete and discontinuous. The selected experts and the router probabilities on the selected path can receive gradients, but the selection boundary itself is not an ordinary differentiable mapping. Training therefore relies on the particular gating formulation, auxiliary objectives, noise, or other estimators used by the implementation.[3][4][19]

### Balanced and expert-choice routing

Token-choice routing does not guarantee equal expert loads. BASE Layers instead posed allocation as a balanced linear-assignment problem so that each expert received the same number of tokens in the studied training setup.[7] Expert Choice Routing reversed the usual direction: each expert selected a fixed-size bucket of high-scoring tokens, allowing the number of experts used by a token to vary.[8]

These methods make balancing part of the assignment, but their scope matters. An assignment computed across a batch lets one token's route depend on other tokens in that batch. For an autoregressive [large language model](https://aiwiki.ai/wiki/large_language_model), a naive global expert-choice assignment can also let later tokens affect earlier assignments. A causal implementation must restrict or modify that computation.[17] Balanced assignment is therefore not a universal drop-in replacement for token-local routing.

### Soft and continuous routing

Soft MoE forms a fixed number of weighted input slots for each expert and then combines expert outputs back into token representations. It is fully differentiable and avoids hard token dropping, but it changes the computation being performed and was evaluated primarily in vision settings.[15] ReMoE is a different continuous approach that uses ReLU-based sparse routing instead of top-$$k$$ plus [softmax](https://aiwiki.ai/wiki/softmax).[19] Results for either method are evidence about the tested models and workloads, not proof that continuous routing is always preferable.

Routing can also be static, hashed, task-conditioned, or hierarchical. The term MoE describes the use of gated experts, not a single routing algorithm.

## Load balancing and expert capacity

If too many tokens choose the same expert, that expert can become a memory or latency bottleneck while other experts remain underused. Persistent imbalance can also leave some experts with relatively few training examples. Load balancing is therefore both an optimization problem and a systems-utilization problem.[4][5][8]

Many distributed implementations allocate a fixed token buffer to each expert. For a routing group containing $$T$$ tokens, $$N$$ experts, $$k$$ selected experts per token, and capacity factor $$c$$, a useful general approximation is

$$
C=\left\lceil c\frac{Tk}{N}\right\rceil .
$$

For Switch-style top-1 routing, this reduces to $$C=\lceil cT/N\rceil$$. Exact rounding, minimum capacity, routing-group boundaries, and whether second-choice assignments count in the same way vary by implementation. The formula should therefore be read as an average-assignment budget, not a universal API definition.[4][5]

A larger capacity factor leaves more room for imbalanced routes but may allocate more memory, communication volume, or padded computation. A smaller capacity can overflow. Depending on the design, an overflowing assignment may be skipped through a residual path, redirected to another expert, or processed by a variable-size or dropless kernel.[4][5][10]

Common balancing approaches include:

- an auxiliary loss that encourages the mean router probability and realized token fraction to be more uniform across experts;
- a balanced assignment or fixed expert bucket;
- router-score biases updated from recent load without backpropagating a balancing loss; and
- systems measures such as expert replication or adaptive placement.

Auxiliary losses add a second objective that can compete with the main learning objective if weighted too strongly. The auxiliary-loss-free bias method reported by Lean Wang and colleagues avoids those balancing gradients, but its published evidence is bounded to the studied models, data, and training scales.[17] MegaBlocks addressed a different part of the problem by using block-sparse operations that processed variable expert loads without dropping tokens or padding every expert to the maximum load.[10]

Router stability is related to, but distinct from, load balance. The ST-MoE study found training instabilities associated with large router logits and introduced a router z-loss to keep those logits small in its tested setup.[9] A z-loss does not by itself guarantee balanced expert use.

### Auxiliary-loss-free balancing

Loss-Free Balancing, proposed by Lean Wang, Huazuo Gao, Chenggang Zhao, Xu Sun, and Damai Dai in August 2024, adds an expert-wise bias to the routing scores before the top-K decision and updates each bias according to that expert's recent load, so that balance is controlled without adding a gradient term to the training loss.[17] The authors validated it on MoE models with up to 3 billion parameters trained on up to 200 billion tokens, and reported better performance and better load balance than auxiliary-loss-controlled baselines in that setting.[17] They also argued that expert-choice routing breaks the causal constraint of language modeling, because a token's target experts are conditioned on future tokens in the same sequence or batch.[17]

DeepSeek-V3 adopted the method in a 671-billion-parameter model. Its bias term $$b_i$$ is added to the affinity score only to decide which experts are selected:

$$
g'_{i,t}=\begin{cases} s_{i,t}, & s_{i,t}+b_i\in \operatorname{Topk}(\{s_{j,t}+b_j \mid 1\le j\le N_r\},K_r),\\ 0, & \text{otherwise.}\end{cases}
$$

The gating value multiplied with the expert output is still derived from the original affinity $$s_{i,t}$$. At the end of each training step, the bias of an expert that was overloaded on the whole batch is decreased by $$\gamma$$ and that of an underloaded expert is increased by $$\gamma$$, a hyperparameter the report calls the bias update speed.[28] DeepSeek-V3 set $$\gamma$$ to 0.001 for the first 14.3 trillion training tokens and to 0 for the remaining 500 billion, and kept a complementary sequence-wise balance loss with a very small weight ($$\alpha=0.0001$$) to avoid extreme imbalance within any single sequence.[28] Its released configuration names the routing method `noaux_tc`, and the reference modeling code, under that setting, adds a per-expert `e_score_correction_bias` to the scores used for expert selection.[52] As of October 2026, the Hugging Face configuration files of DeepSeek-V4-Pro, DeepSeek-V4-Flash, Kimi K2, Kimi K3, and Ling-3.0-flash also set `topk_method` to `noaux_tc`.[45][53] See [MoE load-balancing loss](https://aiwiki.ai/wiki/load_balancing_loss) for the auxiliary-loss methods this approach replaces or supplements.

### Quantile balancing and local load

Quantile balancing computes per-expert biases from routing-margin quantiles rather than moving each bias by a fixed increment. The statistics from one global batch determine the biases for the next step. Computing this statistic independently on each data-parallel rank and averaging the results is generally different from computing the quantile over the complete batch.[56]

Neitemeier and colleagues' September 2026 preprint proposed Exact Quantile Balancing (EQB), using two 256-bin all-reduces per layer to recover exact global-batch BF16 quantiles. For 256 experts, the count exchange is 0.5 MiB per layer, independent of the number of tokens. They also proposed Load-Error Injection (LEI), which sends local hard-load errors directly into router-score gradients.[56]

These methods address different scales: a globally balanced batch can contain uneven expert-parallel microbatches. Experiments used 7.5-billion-parameter models trained for up to 500 billion tokens. The authors reported improved global balance with EQB and improved local balance with LEI, but used one model scale and seed without estimating variance. Their local imbalance measure was a proxy for dispatch cost, not a measurement of expert-parallel throughput.[56]

## Distributed execution

Sparse MoE becomes a distributed-systems problem when experts are placed on different accelerators. [Expert parallelism](https://aiwiki.ai/wiki/expert_parallelism) assigns different experts, or replicas of experts, to different devices. A common forward pass has four stages:

1. compute router scores and assignments;
2. group and dispatch token representations to the devices that own the selected experts;
3. evaluate each expert on its received tokens; and
4. return and combine the expert outputs in the original token order.

The dispatch and return stages are commonly implemented as two all-to-all collective communications.[5][11] Their cost depends on the interconnect topology, message size, number of participating devices, token distribution, precision, and whether communication can overlap with expert computation. Tutel showed that the best parallel layout and pipelining strategy changed with workload and scale, while COMET continued this line of work with finer-grained communication-computation overlap.[11][20] Their measured speedups are properties of their experimental systems, not fixed characteristics of MoE.

Expert parallelism complements rather than replaces other forms of [distributed training](https://aiwiki.ai/wiki/distributed_training). [Data parallelism](https://aiwiki.ai/wiki/data_parallelism) distributes examples, [tensor parallelism](https://aiwiki.ai/wiki/tensor_parallelism) partitions operations within layers, and [pipeline parallelism](https://aiwiki.ai/wiki/pipeline_parallelism) partitions groups of layers. [Model parallelism](https://aiwiki.ai/wiki/model_parallelism) is the broader category that can include several of these approaches. A deployment may combine them, which changes memory placement and collective-communication patterns.[5][11]

Load balance at the model level does not guarantee balanced wall-clock execution. Experts can have equal token counts but different effective costs if sequence grouping, token shapes, kernel efficiency, replicas, or device placement differ. Conversely, some imbalance may be acceptable if popular experts are replicated or placed on faster links. The relevant target is end-to-end time and resource use under the intended workload.

## Training behavior

Sparse routing changes which parameters receive updates. On a given step, each expert is trained only from the tokens routed to it. If early routing strongly favors a small subset, positive feedback can produce overloaded experts and poorly trained alternatives. Balancing objectives, capacity policies, router initialization, routing noise, expert assignment methods, and numerical precision are among the controls studied in the literature.[3][4][5][9]

Expert specialization can emerge, but it should be measured rather than assumed. The 2017 sparsely gated study found syntactic and semantic patterns in some language experts.[3] ST-MoE later reported visible specialization in selected encoder experts, much less meaningful specialization in decoder experts, and no simple language-per-expert partition in its multilingual analysis.[9] An expert number is therefore not a dependable topic label, and inspecting a few routed examples does not establish a complete semantic role.

Sparse upcycling initializes an MoE from a pretrained dense checkpoint, commonly by copying a dense feed-forward layer into multiple experts and then continuing training with a new router. Komatsuzaki and colleagues demonstrated this approach for language and vision models, while also showing that its benefit depended on the additional training budget and configuration.[13] In their ICLR 2023 paper, upcycled T5 Base, Large, and XL language models and Vision Transformer Base and Large models significantly outperformed their dense counterparts on SuperGLUE and ImageNet using about 50% of the initial dense pretraining sunk cost. A language MoE trained from scratch needed about 120% of the original dense checkpoint's computation budget to catch up, and the authors concluded that [sparse upcycling](https://aiwiki.ai/wiki/sparse_upcycling) was the more efficient use of resources for budgets below 100% of the initial computation, while training from scratch may be preferable with larger budgets.[13] Upcycling reuses a checkpoint; it does not eliminate the need to train routing and differentiate initially identical experts.

### Fine-grained and shared experts

The size and organization of experts are additional design variables. Fine-grained MoE divides a comparable expert parameter budget into more, smaller experts and activates a larger combination of them. Scaling-law experiments have treated this granularity as a separate hyperparameter rather than assuming a fixed expert size.[18] DeepSeekMoE combined fine-grained routed experts with shared experts that were always active in its tested architecture.[16] Its fine-grained expert segmentation splits each of $$N$$ experts into $$m$$ smaller ones by dividing the feed-forward intermediate hidden dimension and activates $$mK$$ of the resulting $$mN$$ experts, keeping parameter count and computation constant while increasing the number of possible expert combinations. Shared expert isolation reserves $$K_s$$ experts that every token uses, intended to capture common knowledge and reduce redundancy among the routed experts.[16] The authors reported that DeepSeekMoE 2B performed comparably to GShard 2.9B, which has 1.5 times the expert parameters and computation, and that DeepSeekMoE 16B, with 2 shared and 64 routed experts per MoE layer and 6 routed experts activated per token, performed comparably to LLaMA2 7B with about 40% of the computation.[16] Most of the large open-weight models in the table under Applications use hundreds of small routed experts, and several add one or two shared experts. Those designs illustrate alternatives to uniform, wholly routed experts, but their reported quality and efficiency comparisons do not transfer automatically to other models.

### Reproducible training comparisons

[Hugging Face](https://aiwiki.ai/wiki/hugging_face) published *The Ultimate MoE Training Handbook*, by Nouamane Tazi, Leandro von Werra, and Thomas Wolf, on 5 November 2026. It combines training recipes, interactive explanations, and cluster experiments covering routing, balancing, expert design, stability, and serving.[55]

Its introductory comparison holds data, optimizer, batch size, and sequence length fixed between a dense baseline and a sparse model. Both use 16 layers and a hidden size of 2,048. The MoE replaces 8,192-wide dense feed-forward blocks with 64 experts of width 1,024, selecting eight per token. This produces approximately 6.86 billion total and 1.22 billion active parameters, compared with 1.22 billion parameters in the dense baseline. The recipes assume an eight-GPU node with roughly 80 GB per GPU; the authors' cluster used AWS P5 nodes with H100 accelerators.[55]

The handbook separates hardware diagnostics from model tuning. An all-reduce benchmark does not establish the performance of the all-to-all exchanges used by expert parallelism. Likewise, its matched active-parameter counts do not imply matched step times, and the short setup runs do not establish final model quality.[55]

### Training memory and execution layout

The March 2026 [Megatron-LM](https://aiwiki.ai/wiki/megatron_lm) technical report describes memory, communication, and kernel efficiency as coupled constraints. Dispatch can expand token representations across selected experts, and changing the expert-parallel group can reduce per-device expert storage while increasing communication. Its Parallel Folding design permits different parallel mappings for attention and expert computation instead of forcing both through an identical layout.[57]

| Technique in Megatron Core | Resource tradeoff |
| --- | --- |
| Activation recomputation | Repeats forward operations to reduce saved activation memory |
| Fine-grained activation offloading | Moves selected activations to host memory and overlaps transfers with computation |
| Grouped expert matrix multiplication and operation fusion | Reduces the overhead of many small expert operations |
| Overlapped expert-parallel dispatch and combine | Hides some communication behind available computation |
| Reduced-precision training | Changes activation, weight, and communication costs; requires format-specific support |

The report evaluates combinations of these techniques on specified NVIDIA systems and models. Its throughput results describe those configurations; they do not establish a hardware-independent speedup or show that enabling every optimization together is optimal.[57]

## Inference and deployment

Sparse arithmetic does not imply a proportionally small deployment. For low-latency [inference](https://aiwiki.ai/wiki/inference), all experts that might be selected generally need to be resident somewhere in the serving system or available through a loading policy. Sharding spreads their weights across devices; replication trades more memory for reduced contention; offloading reduces accelerator residency but adds data movement; and [quantization](https://aiwiki.ai/wiki/quantization) changes storage and arithmetic precision. The memory per device can therefore be much lower than the total model size, but the aggregate model weights still exist.[12]

A token may activate only one or two experts while a batch of heterogeneous tokens activates many experts. This makes active parameters per token an incomplete predictor of memory traffic and latency. Prompt processing often offers more tokens to group by expert than single-token autoregressive decoding, while decoding efficiency depends strongly on concurrent request batching. Small expert batches can underuse matrix hardware, and communication or weight reads can dominate.[12]

Serving metrics also pull in different directions. Replicating a frequently selected expert may improve throughput but consume memory needed for other experts. Increasing capacity may reduce overflow but enlarge buffers. Restricting an all-to-all group may lower communication distance while reducing placement flexibility. A configuration should be evaluated on the intended hardware, traffic distribution, sequence lengths, batch policy, and latency objective rather than inferred from an architecture label.

### Memory-bound decoding

Autoregressive decoding produces one new token per sequence per step, so at small batch sizes each step performs little arithmetic for every byte of weights it reads. In roofline terms, a workload whose arithmetic intensity is below the hardware's ridge point (peak compute divided by peak memory bandwidth) is memory-bound: its step time is set mainly by memory traffic, and extra computation adds little time.[24] For a sparse MoE at a small batch size, only the experts selected by the current tokens have to be read, so per-step expert weight traffic depends on how many distinct experts the batch selects rather than on the total expert count. As the batch grows, tokens select different experts. Huang and colleagues describe a moderate-batch regime in which all expert parameters must be loaded while the GPU's arithmetic units are still far from fully used.[24]

The total parameter count still sets the memory requirement. OpenAI's gpt-oss-120b has 117 billion total and 5.1 billion active parameters, and OpenAI attributes its ability to run on a single 80 GB GPU to MXFP4 quantization of the MoE weights; the smaller gpt-oss-20b (21 billion total, 3.6 billion active) runs within 16 GB of memory.[26]

An October 2026 NVIDIA technical blog post illustrates where decode time goes. NVIDIA profiled the FP4 checkpoint of [Ling-3.0-flash](https://aiwiki.ai/wiki/ling_3_0_flash), an [inclusionAI](https://aiwiki.ai/wiki/inclusionai) model with 124 billion total and 5.1 billion active parameters that routes each token to 8 of 512 routed experts alongside one shared expert, on an [NVIDIA DGX Spark](https://aiwiki.ai/wiki/nvidia_dgx_spark) at batch size 1.[22][23] The DGX Spark's listed memory bandwidth is 273 GB/s, with 64 GB or 128 GB of unified LPDDR5x memory.[25] NVIDIA reported that decoding was memory-bound, that reading model weights drove execution time, and that two operations stood out: the routed-expert MoE computation and the output projection (LM head), a 157,184 by 2,560 matrix whose entire weight block is read for every generated token.[22] It then tested three changes: kernels from the Humming library for the MXFP4 expert computation, online [FP8](https://aiwiki.ai/wiki/fp8) quantization of the LM head (stored in BF16 in the checkpoint), and multi-token-prediction speculative decoding using the model's built-in NEXTN prediction layer as the draft.[22]

| Configuration (cumulative) | Time per output token | Decode throughput | Change vs. baseline |
| --- | --- | --- | --- |
| Baseline (FlashInfer MXFP4 MoE kernels, FP32 LM-head option) | 27.71 ms | 36.09 tok/s | (baseline) |
| + Humming MoE backend | 25.35 ms | 39.45 tok/s | +9.3% |
| + Online FP8 LM head | 22.76 ms | 43.94 tok/s | +21.7% |
| + MTP speculative decoding (3 draft steps, 4-token verification) | 9.72 ms | 102.88 tok/s | +185.1% |

These figures come from a synthetic workload of 32K input tokens, 2K output tokens, greedy decoding, and batch size 1, which NVIDIA said systematically overestimates speculative-decoding gains.[22] On all 1,319 GSM8K test questions with sampling enabled, the combined configuration raised decode throughput from 37.81 to 53.89 tokens per second (42.5%) and cut mean end-to-end latency by 24.5%, while GSM8K accuracy moved from 96.89% to 96.82%. The average number of accepted tokens per verification round was 2.68, compared with 3.90 on the synthetic workload.[22] NVIDIA also reported an integration failure: when the FP8 LM head and MTP were enabled together without the draft sharing the full LM-head module, the draft read FP8 weights as BF16, the accept length fell to 1.00, and throughput dropped below the unoptimized baseline.[22] All of these measurements are vendor-reported for one model, one device, and one serving configuration.

### Expert parallelism at serving scale

[DeepSeek-V3](https://aiwiki.ai/wiki/deepseek_v3), with 671 billion total parameters and 37 billion activated per token, documents one large-scale serving layout.[28] Each of its MoE layers has 1 shared expert and 256 routed experts, with 8 routed experts activated per token; during training, node-limited routing sent each token to at most 4 nodes, a limit the report ties to reducing cross-node InfiniBand traffic.[28] DeepSeek deployed prefill and decoding separately. The minimum prefill unit was 4 nodes with 32 GPUs and used 32-way expert parallelism (EP32), which the report says ensures each expert processes a sufficiently large batch. The minimum decoding unit was 40 nodes with 320 GPUs and used EP320: each GPU hosted one expert, 64 GPUs hosted redundant and shared experts, and the dispatch and combine all-to-all steps used direct point-to-point InfiniBand transfers for low latency.[28]

The same report describes balancing load at serving time by duplicating high-load experts. The heavy experts were detected from statistics collected during online deployment and adjusted periodically (the report gives every 10 minutes as an example), and the prefill configuration used 32 redundant experts.[28] DeepSeek later open-sourced the placement algorithm as the Expert Parallelism Load Balancer (EPLB), which computes an expert replication and placement plan from estimated expert loads; predicting those loads is outside the repository's scope.[29]

The communication itself is usually handled by specialized libraries. DeepSeek's [DeepEP](https://aiwiki.ai/wiki/deepep) provides high-throughput and low-latency expert-parallel all-to-all GPU kernels for MoE dispatch and combine, including FP8 dispatch, and uses NVLink within a node and RDMA across nodes.[30] Serving engines expose such collectives as interchangeable backends. As of October 2026, [vLLM](https://aiwiki.ai/wiki/vllm) documents DeepEP high-throughput and low-latency backends and FlashInfer NVLink backends for expert parallelism; the DeepEP high-throughput path returns activations in a contiguous layout and the low-latency path in a batched per-expert layout.[32] See [expert parallelism](https://aiwiki.ai/wiki/expert_parallelism) for the general technique.

### Fused and grouped expert kernels

On a single device, an MoE layer is a sequence of operations rather than one dense matrix multiplication. vLLM's design documentation divides a fused MoE operation into dispatch, a permutation that groups tokens by expert, the expert matrix multiplications, an unpermute step, application of the top-k router weights with reduction over each token's experts, and combine.[31] It supports two activation layouts. In the contiguous layout, activations form one tokens-by-hidden-size tensor accompanied by each token's top-k expert IDs and weights. In the batched layout, activations form an experts-by-maximum-tokens-by-hidden-size tensor, and a separate count records how many rows are valid for each expert.[31] MegaBlocks took a different route for training, using block-sparse operations so that variable expert loads did not require dropping tokens or padding every expert to the maximum load.[10]

Expert kernels are specialized by data format and hardware. vLLM's kernel table lists Triton fused_experts, [DeepGEMM](https://aiwiki.ai/wiki/deepgemm), [CUTLASS](https://aiwiki.ai/wiki/cutlass) FP8 and FP4, FlashInfer, Marlin, and trtllm MXFP4 and NVFP4 expert kernels, among others, each supporting particular quantization formats.[32] Humming, a JIT-compiled GEMM library for quantized inference hosted in the vLLM project's GitHub organization, supports both dense and MoE GEMMs.[33] In NVIDIA's DGX Spark test it compiled kernels at runtime through NVRTC for the actual matrix shapes, data types, and GPU architecture, including Ling-3.0-flash's narrow expert intermediate size of 768. An individual kernel compiled in seconds, whereas the FlashInfer CUTLASS path built 97 targets and took on the order of tens of minutes.[22]

### Low-precision expert weights

Several MoE releases store expert weights at lower precision than the rest of the network. gpt-oss was post-trained with MXFP4 quantization of its MoE weights, and its published configuration leaves attention, the router, the embeddings, and the LM head unconverted.[26][27] DeepSeek-V4-Pro and DeepSeek-V4-Flash (the non-base checkpoints) use FP4 for MoE expert parameters and FP8 for most other parameters.[34] Kimi K3 uses MXFP4 weights with MXFP8 activations, applied through quantization-aware training from the supervised fine-tuning stage onward.[35]

[MXFP4](https://aiwiki.ai/wiki/mxfp4) belongs to the microscaling (MX) family of formats, which pair narrow floating-point or integer element types with a scaling factor shared by a block of elements.[36] NVIDIA describes MXFP4 as 4-bit E2M1 values with one shared power-of-two scale per 32-value block, and its own [NVFP4](https://aiwiki.ai/wiki/nvfp4) as E2M1 values with an FP8 (E4M3) scale per 16-value block plus a second-level FP32 scale per tensor.[37] In the memory-bound regime the aim is to reduce the bytes read per decoding step; in NVIDIA's Ling-3.0-flash example, moving the LM head alone from BF16 to FP8 halved that layer's read volume.[22] Accuracy effects of low-precision experts are model-specific and need to be measured; [quantization](https://aiwiki.ai/wiki/quantization) covers the general tradeoffs.

### Expert offloading on limited memory

When the full set of experts does not fit in accelerator memory, inference engines can keep some expert weights in host memory. [llama.cpp](https://aiwiki.ai/wiki/llama_cpp) provides a `--cpu-moe` option that keeps all MoE weights in the CPU and an `--n-cpu-moe N` option that keeps the MoE weights of the first N layers in the CPU, alongside a general `--override-tensor` option for choosing where tensors are stored.[38]

Research systems treat offloading as a scheduling problem. Eliseev and Mazur proposed an offloading strategy that takes advantage of properties of MoE language models and used it to run Mixtral-8x7B with mixed quantization on desktop hardware and free-tier Google Colab instances.[39] Fiddler (ICLR 2025) argued that systems which frequently move data between CPU and GPU pay a significant overhead, and instead chooses an execution strategy that uses both CPU and GPU resources.[40] Related work prefetches experts predicted for upcoming layers or caches frequently activated experts in GPU memory.[24]

### Interaction with speculative decoding

[Speculative decoding](https://aiwiki.ai/wiki/speculative_decoding) drafts several tokens cheaply and verifies them in one pass of the target model. In a memory-bound dense model, the weights are loaded once for the whole verification pass. In an MoE, the draft tokens can route to different experts, so verification activates and loads more experts than a normal decoding step, and earlier work had found that speculative decoding's acceleration diminishes for MoE models.[24] The MoESD study by Huang and colleagues, a NeurIPS 2025 spotlight paper, argued that the outcome depends on batch size: at moderate batch sizes MoE models can benefit more from speculative decoding than dense models, and sparser MoE designs widen the batch-size range where it helps. The authors reported up to a 2.29x speedup for Qwen2-57B-A14B at medium batch sizes.[24]

NVIDIA's DGX Spark measurements show the small-batch cost directly. A normal Ling-3.0-flash decoding step activates 8 routed experts for one token, while verifying four positions can activate up to 32. NVIDIA measured a verification step at about 2.26 times the cost of a normal step and attributed the extra cost mainly to expert activation rather than attention, because key-value cache reads were small relative to weight reads at batch size 1.[22]

Built-in [multi-token prediction](https://aiwiki.ai/wiki/multi_token_prediction) modules can supply the draft without a separate model. DeepSeek-V3 reported that the acceptance rate of its second predicted token ranged between 85% and 90% across generation topics and that combining MTP with speculative decoding delivered 1.8 times the tokens per second.[28] Ling-3.0-flash's NEXTN layer played the same role in NVIDIA's test.[22]

## Evaluation and tradeoffs

MoE and dense models have more than one scale axis. Routed-language-model experiments found that total parameter count and computation both affected performance and could not be collapsed into the usual dense-model parameter count without an additional model of their relationship.[6] Fine-grained MoE experiments added expert granularity and training tokens to that comparison.[18] As a result, neither total parameters nor active parameters alone establishes model quality or efficiency.

### Scaling laws

Clark and colleagues (ICML 2022) derived scaling laws on two variables, parameter count and computational requirement, for routing networks trained with three different techniques across five orders of magnitude of size, including models with hundreds of experts. They used the laws to define an Effective Parameter Count along which all the models scale at the same rate.[6] Krajewski, Ludziejewski, and colleagues (ICML 2024) introduced granularity as a hyperparameter controlling expert size and fitted laws over training tokens, model size, and granularity. They reported that MoE models consistently outperformed dense Transformers in their experiments, that the efficiency gap widened as model size and training budget grew, and that the common practice of making each expert the same size as the dense feed-forward layer was not optimal at almost any computational budget.[18]

Developers of later models have published their own sparsity studies. The Kimi K2 technical report (July 2025) defined sparsity as the ratio of the total number of experts to the number of activated experts and reported that, with activated parameters held fixed, increasing sparsity consistently lowered training and validation loss in small-scale experiments. To reach a validation loss of 1.5, sparsity 48 reduced FLOPs by 1.69x, 1.39x, and 1.15x compared with sparsity levels 8, 16, and 32. Because higher sparsity also adds infrastructure complexity, Moonshot AI chose sparsity 48 for [Kimi K2](https://aiwiki.ai/wiki/kimi_k2), activating 8 of 384 experts.[50] Such results are fits to the authors' own training setups rather than universal constants.

### Systems-aware scaling

Sarkar, Tang, and Zha's August 2026 MOSAIC preprint couples a fitted loss law with a calibrated model of utilization, memory, communication, and parallel layout. Its scaling sweep covers 104 million to 2.7 billion active parameters and up to 79 billion total parameters. Within the fitted sparsity range, optimizing only model FLOPs favors the sparsest boundary of the tested space. Including a cluster's execution costs can instead favor a less sparse architecture that trains on more tokens during the available time.[58]

This distinguishes an algorithmic compute budget from the useful computation a specific cluster can deliver. The authors caution that their selected architectures depend on the geometry family, hardware, software stack, and training recipe; some optima require substantial extrapolation. They did not propagate uncertainty in unidentified scaling coefficients through the architecture search. The evidence supports hardware-aware comparison rather than a universal expert count or sparsity setting.[58]

A useful comparison reports at least:

| Dimension | Information needed |
| --- | --- |
| Model | total parameters, shared parameters, expert count and size, layers using MoE, routing method, and $$k$$ |
| Training | data, tokens, objective, optimizer, precision, total training compute, and failed or dropped-token rate |
| Per-token work | active expert parameters, dense shared work, measured or estimated operations, and router work |
| Placement | devices, weight precision, sharding, replication, offloading, and aggregate memory |
| Communication | expert-parallel group, topology, bytes moved, collective implementation, and overlap policy |
| Quality | held-out loss and downstream evaluations under matched data and evaluation procedures |
| Serving | prompt and decode latency, throughput, batch policy, sequence lengths, and service-level target |

Wall-clock speedups in GShard, Switch, DeepSpeed-MoE, Tutel, MegaBlocks, or COMET were measured with particular models, baselines, software, hardware, and parallel layouts.[4][5][10][11][12][20] They should not be presented as a general MoE multiplier. The same caution applies to energy use and cost.

Reported operation counts also need a declared boundary. Expert matrix multiplications may dominate an arithmetic estimate while routing, padding, collective communication, synchronization, and weight movement are measured elsewhere or omitted. FLOPs can support a matched algorithmic comparison, but they do not replace elapsed time, memory, network traffic, or service-level measurements on the target system.

MoE also differs from an ordinary ensemble. An ensemble usually combines predictions from multiple component models, often after separate training. An MoE commonly learns routing and experts jointly and can place routed layers inside a larger network. The terminology overlaps in some fields, so the training and routing structure is more informative than the name alone.

## Applications

The first neural mixtures of local experts were general supervised architectures.[1][2] Large sparse MoE work later focused heavily on language modeling and translation.[3][4] The technique also applies beyond language: V-MoE inserted sparse expert layers into a [Vision Transformer](https://aiwiki.ai/wiki/vision_transformer) and evaluated them on image recognition, while Soft MoE studied differentiable slot-based routing in visual recognition.[14][15]

These examples show that MoE is a conditional-computation pattern rather than a synonym for a particular [language model](https://aiwiki.ai/wiki/language_model). Whether it helps depends on the data, task, optimization method, expert design, router, and execution system. A dense model can be preferable when parameter storage, communication, small-batch latency, implementation complexity, or training stability matters more than expanding conditional capacity.

### Open-weight MoE language models

Model cards for open-weight MoE language models usually report total and activated parameters per token. As discussed above, those two numbers do not by themselves establish quality or serving cost. The figures below are as published by each developer (as of 30 October 2026).

| Model | Developer | Total parameters | Active parameters per token | Experts selected per token | Source |
| --- | --- | --- | --- | --- | --- |
| [Mixtral 8x7B](https://aiwiki.ai/wiki/mixtral) | [Mistral AI](https://aiwiki.ai/wiki/mistral_ai) | 47B | 13B | 2 of 8 | [41] |
| [DeepSeek-V3](https://aiwiki.ai/wiki/deepseek_v3) | [DeepSeek](https://aiwiki.ai/wiki/deepseek) | 671B | 37B | 8 of 256 routed, plus 1 shared | [28] |
| Qwen3-235B-A22B ([Qwen3](https://aiwiki.ai/wiki/qwen_3)) | Qwen team, [Alibaba](https://aiwiki.ai/wiki/alibaba) | 235B | 22B | 8 of 128 | [42] |
| [Kimi K2](https://aiwiki.ai/wiki/kimi_k2) | [Moonshot AI](https://aiwiki.ai/wiki/moonshot_ai) | 1T | 32B | 8 of 384, plus 1 shared | [43] |
| gpt-oss-120b ([gpt-oss](https://aiwiki.ai/wiki/gpt_oss)) | [OpenAI](https://aiwiki.ai/wiki/openai) | 117B | 5.1B | 4 of 128 | [26][27] |
| Qwen3.5-397B-A17B ([Qwen3.5](https://aiwiki.ai/wiki/qwen3_5)) | Qwen team, Alibaba | 397B | 17B | 10 of 512 routed, plus 1 shared | [44] |
| DeepSeek-V4-Flash ([DeepSeek V4](https://aiwiki.ai/wiki/deepseek_v4)) | DeepSeek | 284B | 13B | 6 of 256 routed, plus 1 shared | [34][45] |
| DeepSeek-V4-Pro ([DeepSeek V4](https://aiwiki.ai/wiki/deepseek_v4)) | DeepSeek | 1.6T | 49B | 6 of 384 routed, plus 1 shared | [34][45] |
| [Kimi K3](https://aiwiki.ai/wiki/kimi_k3) | Moonshot AI | 2.8T | 104B | 16 of 896, plus 2 shared | [35] |
| [Ling-3.0-flash](https://aiwiki.ai/wiki/ling_3_0_flash) | inclusionAI | 124B | 5.1B | 8 of 512 routed, plus 1 shared | [23] |

### Trends in released models

Expert counts in released open-weight models rose steeply between 2023 and 2026. Mixtral 8x7B (December 2023) selected 2 of 8 experts per token, DeepSeek-V3 (December 2024) 8 of 256 routed experts, and Kimi K2 (2025) 8 of 384. As of October 2026, Qwen3.5-397B-A17B and Ling-3.0-flash each have 512 routed experts, and Kimi K3 has 896, of which 16 are selected per token.[41][28][43][44][23][35] The share of parameters active for each token fell over the same period, from about 28% for Mixtral 8x7B (13 billion of 47 billion) to roughly 3-4% for Kimi K2 (32 billion of 1 trillion), DeepSeek-V4-Pro (49 billion of 1.6 trillion), and Kimi K3 (104 billion of 2.8 trillion), calculated from the figures in the table above. Meta moved its Llama line to MoE with [Llama 4](https://aiwiki.ai/wiki/llama_4), released on 5 April 2025: Llama 4 Scout has 17 billion active and 109 billion total parameters with 16 experts, and Llama 4 Maverick has 17 billion active and 400 billion total parameters with 128 experts.[51]

### Proprietary models

Developers of proprietary models rarely disclose their architectures, so whether a closed model uses MoE generally cannot be established from outside. Google has stated it for several Gemini generations. The Gemini 1.5 technical report (March 2024) says that "Gemini 1.5 Pro is a sparse mixture-of-expert (MoE) Transformer-based model", and the Gemini 2.5 technical report (July 2025) describes the Gemini 2.5 models as sparse mixture-of-experts transformers with native multimodal support for text, vision, and audio inputs.[48][49] The Gemini 3 Pro model card (November 2025) likewise describes Gemini 3 Pro as a sparse mixture-of-experts transformer-based model.[54] See [Gemini 1.5 Pro](https://aiwiki.ai/wiki/gemini_1_5_pro) and [Gemini](https://aiwiki.ai/wiki/gemini).

## References

1. Jacobs, Robert A., Michael I. Jordan, Steven J. Nowlan, and Geoffrey E. Hinton. "Adaptive Mixtures of Local Experts." Neural Computation 3, no. 1 (1991): 79-87. https://www.cs.toronto.edu/~hinton/mixex.html
2. Jordan, Michael I., and Robert A. Jacobs. "Hierarchical Mixtures of Experts and the EM Algorithm." Neural Computation 6, no. 2 (1994): 181-214. https://doi.org/10.1162/neco.1994.6.2.181
3. Shazeer, Noam, et al. "Outrageously Large Neural Networks: The Sparsely-Gated Mixture-of-Experts Layer." International Conference on Learning Representations (2017). https://arxiv.org/abs/1701.06538
4. Lepikhin, Dmitry, et al. "GShard: Scaling Giant Models with Conditional Computation and Automatic Sharding." International Conference on Learning Representations (2021). https://arxiv.org/abs/2006.16668
5. Fedus, William, Barret Zoph, and Noam Shazeer. "Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity." Journal of Machine Learning Research 23, no. 120 (2022): 1-39. https://jmlr.org/papers/v23/21-0998.html
6. Clark, Aidan, et al. "Unified Scaling Laws for Routed Language Models." Proceedings of the 39th International Conference on Machine Learning (2022): 4057-4086. https://proceedings.mlr.press/v162/clark22a.html
7. Lewis, Mike, et al. "BASE Layers: Simplifying Training of Large, Sparse Models." Proceedings of the 38th International Conference on Machine Learning (2021): 6265-6274. https://proceedings.mlr.press/v139/lewis21a.html
8. Zhou, Yanqi, et al. "Mixture-of-Experts with Expert Choice Routing." Advances in Neural Information Processing Systems 35 (2022). https://proceedings.neurips.cc/paper_files/paper/2022/hash/2f00ecd787b432c1d36f3de9800728eb-Abstract-Conference.html
9. Zoph, Barret, et al. "ST-MoE: Designing Stable and Transferable Sparse Expert Models." arXiv (2022). https://arxiv.org/abs/2202.08906
10. Gale, Trevor, Deepak Narayanan, Cliff Young, and Matei Zaharia. "MegaBlocks: Efficient Sparse Training with Mixture-of-Experts." Proceedings of Machine Learning and Systems 5 (2023). https://proceedings.mlsys.org/paper_files/paper/2023/hash/5a54f79333768effe7e8927bcccffe40-Abstract-mlsys2023.html
11. Hwang, Changho, et al. "Tutel: Adaptive Mixture-of-Experts at Scale." Proceedings of Machine Learning and Systems 5 (2023). https://proceedings.mlsys.org/paper_files/paper/2023/hash/5616d34cf8ff73942cfd5aa922842556-Abstract-mlsys2023.html
12. Rajbhandari, Samyam, et al. "DeepSpeed-MoE: Advancing Mixture-of-Experts Inference and Training to Power Next-Generation AI Scale." Proceedings of the 39th International Conference on Machine Learning (2022): 18332-18346. https://proceedings.mlr.press/v162/rajbhandari22a.html
13. Komatsuzaki, Aran, et al. "Sparse Upcycling: Training Mixture-of-Experts from Dense Checkpoints." International Conference on Learning Representations (2023). https://openreview.net/forum?id=T5nUQDrM4u
14. Riquelme, Carlos, et al. "Scaling Vision with Sparse Mixture of Experts." Advances in Neural Information Processing Systems 34 (2021). https://proceedings.neurips.cc/paper/2021/hash/48237d9f2dea8c74c2a72126cf63d933-Abstract.html
15. Puigcerver, Joan, Carlos Riquelme Ruiz, Basil Mustafa, and Neil Houlsby. "From Sparse to Soft Mixtures of Experts." International Conference on Learning Representations (2024). https://proceedings.iclr.cc/paper_files/paper/2024/hash/79fea214543ba263952ac3f4e5452b14-Abstract-Conference.html
16. Dai, Damai, et al. "DeepSeekMoE: Towards Ultimate Expert Specialization in Mixture-of-Experts Language Models." Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (2024): 1280-1297. https://aclanthology.org/2024.acl-long.70/
17. Wang, Lean, Huazuo Gao, Chenggang Zhao, Xu Sun, and Damai Dai. "Auxiliary-Loss-Free Load Balancing Strategy for Mixture-of-Experts." arXiv (2024). https://arxiv.org/abs/2408.15664
18. Ludziejewski, Jan, et al. "Scaling Laws for Fine-Grained Mixture of Experts." Proceedings of the 41st International Conference on Machine Learning (2024): 33270-33288. https://proceedings.mlr.press/v235/ludziejewski24a.html
19. Wang, Ziteng, Jun Zhu, and Jianfei Chen. "ReMoE: Fully Differentiable Mixture-of-Experts with ReLU Routing." International Conference on Learning Representations (2025). https://proceedings.iclr.cc/paper_files/paper/2025/hash/94dc604e115237a7f4a758b3146cd976-Abstract-Conference.html
20. Zhang, Shulai, et al. "COMET: Fine-grained Computation-communication Overlapping for Mixture-of-Experts." Proceedings of Machine Learning and Systems 7 (2025). https://proceedings.mlsys.org/paper_files/paper/2025/hash/e27ea0cd50b798ff8942caf9203f0992-Abstract-Conference.html
21. AI Wiki. ["Sparse mixture of experts"](https://aiwiki.ai/images/audit-fill-2026-10-05-mixture_of_experts-5e5b69021c82.png). [CC0 1.0](https://creativecommons.org/publicdomain/zero/1.0/). Original geometric illustration; not a reproduction of a source figure. Technical basis: [Shazeer et al., Outrageously Large Neural Networks: The Sparsely-Gated Mixture-of-Experts Layer](https://arxiv.org/abs/1701.06538).
22. Liu, Yang. "3 Ways to Boost MoE Inference on NVIDIA DGX Spark." NVIDIA Technical Blog, 27 October 2026. https://developer.nvidia.com/blog/3-ways-to-boost-moe-inference-on-nvidia-dgx-spark/
23. inclusionAI. "Ling-3.0-flash" model card. Hugging Face. Accessed 30 October 2026. https://huggingface.co/inclusionAI/Ling-3.0-flash
24. Huang, Zongle, et al. "MoESD: Unveil Speculative Decoding's Potential for Accelerating Sparse MoE." Advances in Neural Information Processing Systems (2025). https://arxiv.org/abs/2505.19645
25. NVIDIA. "NVIDIA DGX Spark" product page and specifications. Accessed 30 October 2026. https://www.nvidia.com/en-us/products/workstations/dgx-spark/
26. OpenAI. "gpt-oss-120b" model card. Hugging Face. Accessed 30 October 2026. https://huggingface.co/openai/gpt-oss-120b
27. OpenAI. gpt-oss-120b configuration file (config.json). Hugging Face. Accessed 30 October 2026. https://huggingface.co/openai/gpt-oss-120b/blob/main/config.json
28. DeepSeek-AI. "DeepSeek-V3 Technical Report." arXiv:2412.19437 (2024). https://arxiv.org/abs/2412.19437
29. DeepSeek. "Expert Parallelism Load Balancer (EPLB)." GitHub repository. Accessed 30 October 2026. https://github.com/deepseek-ai/EPLB
30. DeepSeek. "DeepEP." GitHub repository README. Accessed 30 October 2026. https://github.com/deepseek-ai/DeepEP
31. vLLM. "Fused MoE Modular Kernel." vLLM design documentation. Accessed 30 October 2026. https://docs.vllm.ai/en/latest/design/fused_moe_modular_kernel.html
32. vLLM. "Fused MoE Kernel Features." vLLM design documentation. Accessed 30 October 2026. https://docs.vllm.ai/en/latest/design/moe_kernel_features.html
33. Humming contributors. "Humming" (humming-kernels). GitHub repository and PyPI package. Accessed 30 October 2026. https://github.com/vllm-project/humming
34. DeepSeek. "DeepSeek-V4-Pro" model card. Hugging Face. Accessed 30 October 2026. https://huggingface.co/deepseek-ai/DeepSeek-V4-Pro
35. Moonshot AI. "Kimi K3" model card. Hugging Face. Accessed 30 October 2026. https://huggingface.co/moonshotai/Kimi-K3
36. Rouhani, Bita Darvish, et al. "Microscaling Data Formats for Deep Learning." arXiv:2310.10537 (2023). https://arxiv.org/abs/2310.10537
37. Alvarez, Eduardo, et al. "Introducing NVFP4 for Efficient and Accurate Low-Precision Inference." NVIDIA Technical Blog, 24 June 2025. https://developer.nvidia.com/blog/introducing-nvfp4-for-efficient-and-accurate-low-precision-inference/
38. ggml-org. "llama.cpp HTTP Server" README (common parameters). GitHub. Accessed 30 October 2026. https://github.com/ggml-org/llama.cpp/blob/master/tools/server/README.md
39. Eliseev, Artyom, and Denis Mazur. "Fast Inference of Mixture-of-Experts Language Models with Offloading." arXiv:2312.17238 (2023). https://arxiv.org/abs/2312.17238
40. Kamahori, Keisuke, Tian Tang, Yile Gu, Kan Zhu, and Baris Kasikci. "Fiddler: CPU-GPU Orchestration for Fast Inference of Mixture-of-Experts Models." International Conference on Learning Representations (2025). https://arxiv.org/abs/2402.07033
41. Jiang, Albert Q., et al. "Mixtral of Experts." arXiv:2401.04088 (2024). https://arxiv.org/abs/2401.04088
42. Qwen Team. "Qwen3-235B-A22B" model card. Hugging Face. Accessed 30 October 2026. https://huggingface.co/Qwen/Qwen3-235B-A22B
43. Moonshot AI. "Kimi-K2-Instruct" model card. Hugging Face. Accessed 30 October 2026. https://huggingface.co/moonshotai/Kimi-K2-Instruct
44. Qwen Team. "Qwen3.5-397B-A17B" model card. Hugging Face. Accessed 30 October 2026. https://huggingface.co/Qwen/Qwen3.5-397B-A17B
45. DeepSeek. DeepSeek-V4-Pro and DeepSeek-V4-Flash configuration files (config.json). Hugging Face. Accessed 30 October 2026. https://huggingface.co/deepseek-ai/DeepSeek-V4-Pro/blob/main/config.json and https://huggingface.co/deepseek-ai/DeepSeek-V4-Flash/blob/main/config.json
46. Du, Nan, et al. "GLaM: Efficient Scaling of Language Models with Mixture-of-Experts." Proceedings of the 39th International Conference on Machine Learning (2022): 5547-5569. https://proceedings.mlr.press/v162/du22c.html
47. Mistral AI. "Mixtral of experts." Mistral AI news, 11 December 2023. https://mistral.ai/news/mixtral-of-experts
48. Gemini Team, Google. "Gemini 1.5: Unlocking multimodal understanding across millions of tokens of context." arXiv:2403.05530 (2024). https://arxiv.org/abs/2403.05530
49. Comanici, Gheorghe, et al. (Gemini Team, Google). "Gemini 2.5: Pushing the Frontier with Advanced Reasoning, Multimodality, Long Context, and Next Generation Agentic Capabilities." arXiv:2507.06261 (2025). https://arxiv.org/abs/2507.06261
50. Kimi Team. "Kimi K2: Open Agentic Intelligence." arXiv:2507.20534 (2025). https://arxiv.org/abs/2507.20534
51. Meta. "Llama 4" model card. GitHub, meta-llama/llama-models. Accessed 31 October 2026. https://github.com/meta-llama/llama-models/blob/main/models/llama4/MODEL_CARD.md
52. DeepSeek. DeepSeek-V3 configuration file (config.json) and reference modeling code (modeling_deepseek.py). Hugging Face. Accessed 31 October 2026. https://huggingface.co/deepseek-ai/DeepSeek-V3/blob/main/config.json and https://huggingface.co/deepseek-ai/DeepSeek-V3/blob/main/modeling_deepseek.py
53. Configuration files (config.json) for moonshotai/Kimi-K2-Instruct, moonshotai/Kimi-K3, and inclusionAI/Ling-3.0-flash. Hugging Face. Accessed 31 October 2026. https://huggingface.co/moonshotai/Kimi-K2-Instruct/blob/main/config.json , https://huggingface.co/moonshotai/Kimi-K3/blob/main/config.json , and https://huggingface.co/inclusionAI/Ling-3.0-flash/blob/main/config.json
54. Google DeepMind. "Gemini 3 Pro Model Card." November 2025, last updated May 2026. Accessed 31 October 2026. https://storage.googleapis.com/deepmind-media/Model-Cards/Gemini-3-Pro-Model-Card.pdf
55. Tazi, Nouamane, Leandro von Werra, and Thomas Wolf. ["The Ultimate MoE Training Handbook"](https://huggingface.co/spaces/huggingface/moe-blogpost). Hugging Face, 5 November 2026. [Rendered handbook](https://huggingface-moe-blogpost.hf.space/).
56. Neitemeier, Pit, Jiaze Li, Alessio Serra, Philipp Scholl, and Sohir Maskey. ["Exact Quantile Balancing and Load-Error Injection for Mixture-of-Experts"](https://arxiv.org/abs/2609.28053). arXiv:2609.28053v1, 23 September 2026.
57. Yan, Zijie, et al. ["Scalable Training of Mixture-of-Experts Models with Megatron Core"](https://arxiv.org/abs/2603.07685). arXiv:2603.07685v2, 10 March 2026.
58. Sarkar, Soumajyoti, Yuxin Tang, and Sheng Zha. ["Compute-Optimal Is Not Cluster-Optimal: Systems-Aware Scaling for Sparse Mixture-of-Experts"](https://arxiv.org/abs/2608.10605). arXiv:2608.10605v1, 11 August 2026.

