

NVIDIA Spectrum-X
NVIDIA Spectrum-X is an Ethernet networking platform built by NVIDIA specifically for large-scale AI data center workloads, pairing the Spectrum-4 Ethernet switch with the BlueField-3 SuperNIC to deliver the lossless, low-latency fabric that distributed AI training requires.[1][3] Announced at Computex on May 28, 2023, it was marketed as the world's first 51.2 Tb/s Ethernet platform built for AI, and NVIDIA claims it delivers 1.7x better overall AI performance and power efficiency than conventional Ethernet, and 1.6x higher AI network performance than off-the-shelf Ethernet.[1][18] First deployed in the Israel-1 supercomputer later that year, Spectrum-X has since become the networking fabric for some of the largest AI clusters in the world, including xAI's Colossus supercomputer in Memphis, Tennessee, and systems at Meta, Oracle, and CoreWeave.[1][5][8]
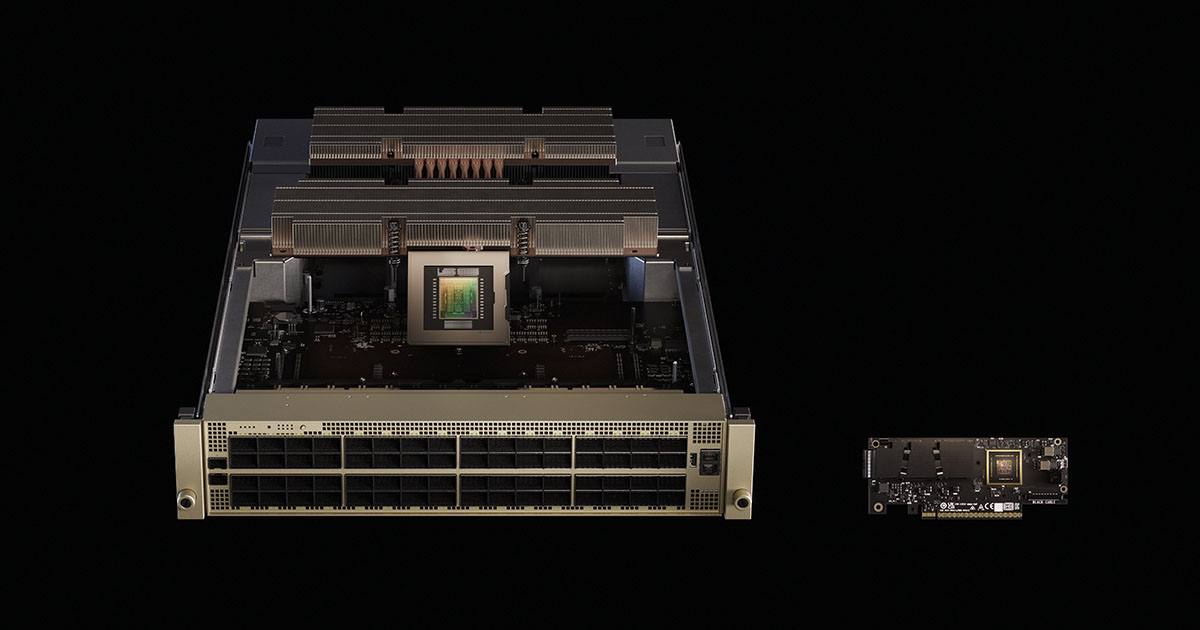
The platform brings a set of InfiniBand-derived techniques to Ethernet, including per-packet adaptive routing, NIC-driven congestion control, and lossless RDMA over Converged Ethernet (RoCE), allowing operators to stay within the open Ethernet ecosystem while closing much of the performance gap with proprietary InfiniBand fabrics.[3][17] In the second quarter of 2025, according to IDC, NVIDIA held the largest share of the datacenter Ethernet switch segment at 25.9 percent, ahead of Arista and Cisco, on 2.3 billion dollars of quarterly Ethernet switch revenue, up 647 percent year over year.[19]
What problem does Spectrum-X solve for AI networks?
Distributed AI training relies on collective communication operations, particularly all-reduce, which synchronizes gradient updates across every GPU in a cluster after each training step. In a 100,000-GPU cluster, this means tens of thousands of simultaneous flows converge on the same switch ports in a pattern called incast. Conventional Ethernet handles incast poorly: queues fill, packets are dropped, and TCP or RoCE senders back off. The result, according to NVIDIA, is that off-the-shelf Ethernet at scale suffers thousands of flow collisions and delivers only about 60 percent data throughput, and tail latency spikes unpredictably.[6][8]
InfiniBand avoided this problem through lossless transport, fine-grained congestion signals, and in-network computing via SHARP (Scalable Hierarchical Aggregation and Reduction Protocol).[17] But InfiniBand is a proprietary fabric: cabling, optics, switches, and network interface cards must all come from NVIDIA/Mellanox, and the ecosystem is less commoditized than Ethernet.[17]
Hyperscale operators, particularly those building multi-tenant AI clouds, wanted the interoperability and vendor flexibility of Ethernet with performance closer to InfiniBand. Spectrum-X was NVIDIA's answer to that requirement.[1] At launch, Gilad Shainer, NVIDIA's senior vice president of networking, framed the motivation directly: "Transformative technologies such as generative AI are forcing every enterprise to push the boundaries of data center performance in pursuit of competitive advantage."[1]
How is Spectrum-X built? Architecture
Spectrum-4 switch (SN5600)
The primary switch in the Spectrum-X platform is the SN5600, based on the Spectrum-4 ASIC.[12] The SN5600 is a 2U rack-mounted switch with 64 OSFP ports running at 800 GbE each, for a total switching capacity of 51.2 Tbps.[12] Packet forwarding reaches 33.3 billion packets per second.[12] The switch includes a 160 MB shared packet buffer and an Intel Xeon Hexa-core processor for control-plane processing.[12] Two hot-swap power supplies are included, drawing approximately 940 watts under load.[12]
The Spectrum-4 ASIC is responsible for several functions that commodity Ethernet switches do not implement: per-packet adaptive routing decisions, real-time egress queue telemetry, and congestion notification generation.[3] Combined with the SuperNICs, which NVIDIA says react to congestion events with microsecond latency, these capabilities let the fabric respond quickly to congestion.[3]
In a standard two-tier leaf-spine topology, Spectrum-X can connect 256 ports at 200 Gb/s through a single switch, or up to 16,000 ports in a two-tier topology.[1] The Spectrum-X Multiplane configuration, which splits each GPU's SuperNIC traffic across two or more independent network planes, can scale a flat two-tier fabric to 128,000 GPUs.[18]
BlueField-3 SuperNIC
The endpoint device in Spectrum-X is the BlueField-3 SuperNIC, which connects each GPU server to the fabric at up to 400 Gb/s using RDMA over Converged Ethernet (RoCE).[3] Unlike a conventional network interface card, the BlueField-3 includes an Arm-based multi-core processor complex that runs congestion control algorithms in the NIC itself, offloading this work from the host CPU.[3]
The BlueField-3 can handle millions of congestion control events per second at microsecond reaction latency.[3] It also performs packet reordering at the receive side, which is necessary because Spectrum-X's per-packet adaptive routing can deliver packets out of order.[3] By reordering packets in the NIC before presenting them to the RDMA layer, the BlueField-3 makes adaptive routing transparent to applications.[3]
The BlueField-3 supports quality-of-service isolation, which allows different AI training jobs running on shared infrastructure to be separated at the network layer so that one noisy workload does not affect the latency of another.[3]
ConnectX-8 SuperNIC (800 Gb/s, 2025)
In 2025, NVIDIA introduced the ConnectX-8 SuperNIC to support the Blackwell GPU generation, including the NVIDIA GB300 NVL72.[11] The ConnectX-8 doubles the total bandwidth of the BlueField-3 SuperNIC to 800 Gb/s: a single OSFP port runs at 800 Gb/s in InfiniBand (XDR) mode, while Ethernet ports run at up to 400 Gb/s each, so 800 Gb/s of Ethernet comes from two 400 GbE ports.[11]
The ConnectX-8 uses a PCIe Gen 6 x16 host interface, with an optional additional x16 link through an auxiliary card for Socket Direct or Multi-Host configurations in dense GPU systems.[11] It retains telemetry-based congestion control and packet reordering for Spectrum-X. NVIDIA's documentation describes the ConnectX-8's extension of SHARP in-network computing as a feature of its InfiniBand SuperNICs, used with the Quantum-X800 InfiniBand platform, so SHARP remains an InfiniBand feature in NVIDIA's portfolio.[22][23]
The ConnectX-8 also integrates with the Spectrum-X telemetry infrastructure, providing end-to-end visibility from NIC to switch to allow fine-grained monitoring of flow behavior across a large fabric.[11]
How does adaptive routing work in Spectrum-X?
Conventional Ethernet load-balancing uses Equal-Cost Multi-Path (ECMP) routing, which assigns each flow to a path at connection setup time and keeps it there. Under incast conditions, ECMP produces severe imbalance: some paths fill while others remain idle, because flow assignments are made without knowledge of instantaneous queue depth.[3]
Spectrum-X uses RoCE Adaptive Routing, which makes routing decisions on a per-packet basis.[3] The Spectrum-4 switch evaluates the congestion state of each egress port in real time and selects the least-loaded port for each packet.[3] Switches also exchange congestion status with neighboring switches so that routing decisions account for downstream congestion, not just local queue depth.[3]
Because per-packet routing can deliver packets out of order, the BlueField-3 and ConnectX-8 SuperNICs perform receive-side reordering before handing data to the RDMA layer.[3] Applications see in-order delivery and are unaware that individual packets took different paths through the fabric.[3]
The effect on bandwidth utilization is substantial. According to NVIDIA, standard Ethernet at scale delivers only about 60 percent data throughput in AI training workloads, where flow patterns are highly synchronized and collisions are common.[6] NVIDIA reports that Spectrum-X adaptive routing enables up to 95 percent effective bandwidth at scale, and xAI's Colossus cluster maintained 95 percent data throughput across a 100,000-GPU system with zero packet loss due to flow collisions.[3][6]
How does Spectrum-X make Ethernet lossless for AI?
RDMA over Converged Ethernet requires a lossless network. Unlike TCP, RoCE does not retransmit dropped packets through its own transport layer; a dropped RoCE packet causes the entire RDMA operation to fail, forcing a restart of the collective communication.[17] At scale, even low packet loss rates translate into significant throughput degradation.
Standard lossless Ethernet uses Priority Flow Control (PFC), which allows a congested receiver to pause a sender.[17] PFC has a well-known problem: a pause frame sent to one sender can cascade backward through the network, creating head-of-line blocking for unrelated flows on the same priority class.[17] In a large cluster, PFC cascades can stall large portions of the fabric.
Spectrum-X achieves losslessness through a different mechanism. The Spectrum-4 switch generates in-band congestion notification (CN) signals that are delivered directly to the BlueField-3 or ConnectX-8 SuperNIC handling the sending flow.[3] The NIC reduces its sending rate before queues fill to the point where PFC would trigger.[3] By keeping queues below the PFC threshold, Spectrum-X avoids PFC cascades entirely in normal operation, using PFC only as a last-resort backstop.[3]
This combination, proactive ECN-based rate reduction in the NIC plus per-packet adaptive routing in the switch, allows Spectrum-X to maintain lossless behavior at scale without the instability that PFC cascades introduce in naive lossless Ethernet deployments.[3]
What is Spectrum-X Photonics?
At GTC on March 18, 2025, NVIDIA announced Spectrum-X Photonics, which integrates silicon photonics directly onto the switch package.[10] This co-packaged optics (CPO) approach eliminates the pluggable transceiver module and the short electrical link between the switch ASIC and the optics cage, reducing insertion loss and power consumption.[10] NVIDIA CEO Jensen Huang positioned it as a step change for scale-out networking: "By integrating silicon photonics directly into switches, NVIDIA is shattering the old limitations of hyperscale and enterprise networks and opening the gate to million-GPU AI factories."[10]
Spectrum-X Photonics switches are available in configurations of 128 ports at 800 Gb/s (100 Tb/s total) or 512 ports at 800 Gb/s (400 Tb/s total).[10] Compared with traditional pluggable-transceiver networking, NVIDIA cited 3.5x more power efficiency, 63x greater signal integrity, 10x better network resiliency at scale, 4x fewer lasers, and 1.3x faster deployment.[10] NVIDIA said the Quantum-X Photonics InfiniBand switches would ship in the second half of 2025, with the Spectrum-X Photonics Ethernet switches following from infrastructure and system vendors in 2026.[10]
Spectrum-XGS: extending across distributed data centers
Announced at Hot Chips in August 2025, Spectrum-XGS is an extension of the Spectrum-X platform designed for multi-data-center AI training.[9][15] As individual data center sites reach power limits, operators are building AI clusters that span multiple buildings, campuses, or geographic locations. Standard Ethernet suffers from increased latency, jitter, and unpredictable performance over longer distances.
Spectrum-XGS adds distance-aware congestion control algorithms that adapt to the round-trip time between facilities.[9] It includes precision latency management and end-to-end telemetry across the inter-facility links.[9] NVIDIA reported that Spectrum-XGS nearly doubles NCCL performance in cross-data-center environments, citing a 1.9x improvement in NCCL collective performance.[9][18]
CoreWeave announced it would be among the first operators to deploy Spectrum-XGS to interconnect its distributed data centers.[9]
How does Spectrum-X compare with Quantum-2 InfiniBand?
NVIDIA's Quantum series is its InfiniBand platform, which predates Spectrum-X and remains in wide use for high-performance computing. The table below compares Spectrum-X (Spectrum-4 / ConnectX-8) against Quantum-2 (NDR InfiniBand, QM9700 switch / ConnectX-7 HCA).
| Feature | Spectrum-X (Ethernet) | Quantum-2 NDR (InfiniBand) |
|---|---|---|
| Max port speed | 800 GbE (ConnectX-8) | 400 Gb/s NDR |
| Switch fabric capacity | 51.2 Tbps (SN5600) | 25.6 Tbps, 51.2 Tb/s bidirectional (QM9700) |
| Port count per switch | 64x 800G | 64x 400G NDR |
| Latency (8B message) | ~1.7 us (RoCE) | ~0.9 us |
| Protocol | Ethernet (RoCE v2) | InfiniBand (native RDMA) |
| In-network computing | No SHARP (InfiniBand-only feature) | SHARP v3 (full support) |
| Congestion control | NIC-driven, per-packet adaptive routing | Native IB CC, per-packet adaptive routing |
| Lossless mechanism | ECN + proactive NIC rate reduction | Native lossless transport |
| Multi-tenancy / isolation | Yes (QoS isolation) | Limited |
| Ecosystem | Open Ethernet (SONiC, Cumulus, OCP) | Proprietary IB ecosystem |
| Primary use case | AI clouds, multi-tenant factories | AI-dedicated HPC, supercomputers |
| Notable deployments | xAI Colossus, Meta, Oracle | NVIDIA DGX SuperPOD, many TOP500 systems |
The latency advantage of InfiniBand (approximately 0.9 microseconds vs. 1.7 microseconds for RoCE) remains relevant for very tightly coupled HPC workloads, but for large-scale LLM training the all-reduce collective operations that dominate training time are less sensitive to raw latency than to sustained bandwidth.[17] Meta reported in 2024 that, through careful co-design of network, software and model architectures, it had run large generative AI model training workloads (including Llama 3) on both its RoCE cluster, built on Arista switches rather than Spectrum-X, and its InfiniBand cluster without network bottlenecks, a result that supported the broader case for Ethernet in AI training.[21]
The Quantum-X800 InfiniBand platform announced in 2024 further raises the bar: the Q3400 switch provides 144 ports at 800 Gb/s for 115.2 Tbps of total fabric capacity, compared to 51.2 Tbps for the SN5600. NVIDIA said the Quantum-X800 platform delivers 5x higher bandwidth capacity and a 9x increase in SHARPv4 in-network computing, to 14.4 TFLOPS, compared with the previous generation.[23] For AI-dedicated infrastructure where performance per dollar justifies the proprietary ecosystem, Quantum-X800 retains a clear lead.
How does Spectrum-X compare with Arista and Cisco AI Ethernet?
NVIDIA Spectrum-X competes with Ethernet solutions from Arista Networks and Cisco in the AI data center market.
| Feature | NVIDIA Spectrum-X | Arista 7060X series | Cisco N9100 |
|---|---|---|---|
| Switch ASIC | NVIDIA Spectrum-4 | Broadcom Tomahawk 5 | NVIDIA Spectrum-X switch silicon |
| Max port speed | 800 GbE | 800 GbE | 800 GbE |
| Switching capacity (per switch) | 51.2 Tbps | 51.2 Tbps | 51.2 Tbps |
| AI-specific congestion control | Yes (NIC+switch integrated) | Partial (DSCP-based ECN) | Yes (via Spectrum-4 ASIC) |
| Adaptive routing | Per-packet (with BlueField/CX-8 NIC) | Flowlet ECMP (ETA) | Per-packet (with BlueField/CX-8) |
| Requires NVIDIA NIC | Yes | No | No (but recommended) |
| Network OS | SONiC, NVIDIA Cumulus | EOS | NX-OS, SONiC |
| OCP participation | Yes | Yes | Yes |
| AI performance vs. OTS Ethernet | 1.6x (NVIDIA claim) | Varies | Varies |
Arista's primary differentiation in AI networking is EOS, its network operating system, which has deep programmability and a large installed base in enterprise and cloud data centers. Arista's 7060X switches use Broadcom's Tomahawk 5 ASIC, which provides competitive port density but lacks the NIC-integrated congestion control that Spectrum-X provides through BlueField-3 or ConnectX-8.
Cisco's N9100 series, introduced in October 2025, takes a different approach: it is a Cisco-developed switch built on NVIDIA Spectrum-X Ethernet switch silicon, gaining Spectrum-X's hardware congestion control capabilities, while running Cisco's NX-OS or SONiC operating system.[14] This makes the Cisco N9100 compatible with Spectrum-X-enabled NICs and reference architectures. Building on the Cisco-NVIDIA collaboration announced in February 2025, Cisco offers a NVIDIA Cloud Partner-compliant reference architecture built on the N9100.[14]
In Q1 2025, IDC data analyzed by The Next Platform put NVIDIA at 21.1 percent of datacenter Ethernet switch sales, just behind Arista's 21.3 percent.[13] By Q2 2025, IDC said NVIDIA led the datacenter segment with 25.9 percent, while Arista held 18.9 percent of the datacenter segment and Cisco held 27.3 percent of the total Ethernet switch market.[19]
Where is Spectrum-X deployed? Major deployments
Israel-1 supercomputer
Israel-1 was the first large-scale deployment of Spectrum-X.[5] Built at a data center in Israel, the system comprised 128 NVIDIA HGX H100 servers (with eight H100 GPUs each), 1,280 BlueField-3 DPUs, and more than 40 Spectrum-4 switches.[5] The first phase went online in November 2023, two months ahead of its planned schedule, having been assembled in approximately 20 weeks.[5] The complete system was designed to deliver eight exaflops of peak AI performance and 130 petaflops for high-performance computing.[5] Israel-1 served as both a production AI system and a testbed for Spectrum-X in a real data center environment.[5]
xAI Colossus
xAI's Colossus cluster in Memphis, Tennessee, built using Spectrum-X, became one of the most closely watched Spectrum-X deployments.[6] The cluster was assembled in 122 days and reached 100,000 NVIDIA Hopper (NVIDIA H100 and H200) GPUs in its initial configuration, with plans to expand to 200,000 total GPUs.[6][7] The RDMA fabric uses Spectrum-X SN5600 switches paired with BlueField-3 SuperNICs.[6]
xAI reported that across all three tiers of the Colossus network fabric, the system experienced zero application latency degradation or packet loss due to flow collisions, and maintained 95 percent data throughput throughout production training runs on Grok models.[6] By comparison, standard Ethernet at similar scale typically produces thousands of flow collisions and delivers around 60 percent data throughput.[6] The Colossus deployment was described by NVIDIA as a direct validation of Spectrum-X performance at the scale of the world's largest AI supercomputer.[6]
Meta
Meta's AI infrastructure uses a mix of Ethernet and InfiniBand fabrics. For its open networking platform, Meta integrates Spectrum-X Ethernet into its Minipack3N switch hardware running FBOSS, Meta's open-source network operating system.[8] By combining Spectrum-X's adaptive routing and congestion control with Meta's in-house switching hardware and software stack, Meta can apply Spectrum-X capabilities while retaining control of the switch platform. Meta announced the Spectrum-X integration at OCP Summit in October 2025, describing it as enabling the efficiency and predictability required to train increasingly large models.[8]
Meta is also part of the Ultra Ethernet Consortium (UEC), which is developing open standards for AI-grade Ethernet independent of any single vendor. Meta's participation in both UEC and the Spectrum-X ecosystem reflects its strategy of keeping multiple options open.
Oracle
Oracle announced at OCP Summit in October 2025 that it is building giga-scale AI supercomputers using Spectrum-X Ethernet switches within Oracle Cloud Infrastructure (OCI).[8] Oracle's planned systems, based on the NVIDIA Vera Rubin GPU architecture, will use Spectrum-X for the GPU-to-GPU communication fabric.[8] Oracle said adopting Spectrum-X would let it interconnect millions of GPUs with breakthrough efficiency.[8]
CoreWeave
CoreWeave, a GPU cloud provider that has become one of the largest users of NVIDIA hardware, became the first cloud provider to deploy NVIDIA GB300 NVL72 systems in July 2025, although that deployment used NVIDIA Quantum-X800 InfiniBand rather than Spectrum-X for its scale-out network.[24] CoreWeave also announced plans to deploy Spectrum-XGS to interconnect its geographically distributed data centers into a unified AI training fabric.[9]
Stargate Initiative
The Stargate Initiative, the private AI infrastructure joint venture of OpenAI, SoftBank, Oracle and MGX announced at the White House in January 2025, named NVIDIA among its key initial technology partners. Oracle, a Stargate partner, has said its giga-scale AI factories will be interconnected by Spectrum-X Ethernet, though the sources cited here do not specify the network fabric at individual Stargate sites.[8]
Spectrum-X versus InfiniBand: tradeoffs in practice
The choice between Spectrum-X Ethernet and Quantum InfiniBand involves several practical considerations beyond raw performance numbers.
Ecosystem openness is the primary advantage of Spectrum-X. Ethernet cabling, optics, and management tooling are available from many vendors. Standard network operating systems including SONiC and Cumulus Linux run on Spectrum-4 switches.[17] This reduces vendor lock-in and allows operators to use existing Ethernet infrastructure investments. InfiniBand, by contrast, uses a proprietary physical layer and requires NVIDIA switches, cables, and host adapters throughout.[17]
Multi-tenancy is another area where Spectrum-X is better suited than InfiniBand. The QoS isolation features in the BlueField-3 and ConnectX-8 SuperNICs allow multiple AI training jobs to share the same fabric without interfering with each other.[3] InfiniBand networks typically require dedicated partitions for isolation, which reduces flexibility in cloud environments where job mixes change continuously.
Latency still favors InfiniBand. NDR InfiniBand achieves approximately 0.9 microsecond message latency at small message sizes, while Spectrum-X RoCE runs at approximately 1.7 microseconds.[17] For distributed training of large language models, where all-reduce operations involve messages on the order of gigabytes, this latency difference is not the primary bottleneck. For traditional HPC workloads with fine-grained synchronization, InfiniBand's latency advantage remains meaningful.
In-network computing via SHARP has historically been a clear InfiniBand advantage. SHARP offloads all-reduce operations into the switch fabric itself, reducing the number of data copies and the amount of host-side compute needed for collective operations.[17] NVIDIA describes ConnectX-8 SHARP support as a feature of its InfiniBand SuperNICs, and the Quantum-X800 InfiniBand platform offers SHARPv4 with 14.4 TFLOPS of in-network computing, so this remains an InfiniBand advantage.[22][23]
Operational complexity is a real consideration with Spectrum-X. Achieving full performance requires correct configuration of PFC thresholds, ECN marking, QoS classes, and adaptive routing parameters.[17] NVIDIA and its partners provide reference configurations, but deploying a properly tuned Spectrum-X fabric requires networking expertise that goes beyond standard Ethernet administration.
Scaling ceilings have narrowed. Spectrum-X Multiplane configurations can reach 128,000 GPUs in a flat two-tier topology.[4] InfiniBand with fat-tree or dragonfly topologies can scale to similar counts. At 100,000-GPU scale, as demonstrated at xAI Colossus, Spectrum-X has proven adequate for production AI training.[6]
What is Spectrum-X used for? Use cases
Spectrum-X is most commonly deployed in three scenarios.
Large-scale LLM training is the primary use case. Pre-training runs for models like GPT-4-class systems and beyond involve all-reduce operations across tens of thousands of GPUs every few hundred milliseconds. The combination of lossless Ethernet and adaptive routing that Spectrum-X provides directly addresses the bottlenecks that degrade training throughput on standard Ethernet.[3]
Multi-tenant AI clouds are a second use case where Spectrum-X has advantages. Cloud providers running many different AI training jobs simultaneously on shared GPU clusters benefit from the performance isolation features.[3] A workload that causes incast on one tenant's traffic does not spill over into other tenants' flows, which is difficult to guarantee on standard Ethernet or even on InfiniBand without dedicated partitions.
AI inference at scale is a growing use case. Large-scale inference clusters serving inference requests for frontier models require efficient GPU-to-GPU communication for tensor parallelism and pipeline parallelism. The latency and throughput characteristics of Spectrum-X are suited to these workloads, and the ability to share infrastructure between training and inference on the same Ethernet fabric is operationally attractive.
What are the limitations of Spectrum-X?
Spectrum-X is not a drop-in replacement for standard Ethernet. It requires NVIDIA BlueField or ConnectX-8 SuperNICs at every endpoint.[3] Servers connected with other vendors' NICs cannot participate in adaptive routing or NIC-driven congestion control, meaning they operate at standard Ethernet performance levels on the same fabric.
The platform's performance depends on the tight integration between the Spectrum-4 switch and the NVIDIA NIC. This integration is partly opaque: the specific algorithms for congestion notification, routing decisions, and rate adaptation are implemented in NVIDIA hardware and firmware, not in an open standard. The Ultra Ethernet Consortium published its first open specification for similar capabilities (UEC 1.0) in June 2025, but hardware built to it was still limited.
Performance headroom compared to InfiniBand remains at the extreme end of the scale. InfiniBand retains advantages in latency and in-network computing for the most latency-sensitive collective operations. For LLM training workloads specifically, Meta reported running large generative AI training on both its RoCE and InfiniBand clusters without network bottlenecks.[21] For traditional scientific HPC, InfiniBand remains the default choice.
NVIDIA said in June 2026 that it had begun shipping Spectrum-X co-packaged optics switches, developed with TSMC, to select partners, but field experience with CPO in high-density AI clusters remains limited.[10][20]
Finally, the newest Spectrum-X switch generation, built for NVIDIA Vera Rubin AI factories, uses the Spectrum-6 ASIC with 102.4 Tb/s per switch chip and 200G SerDes (the SN6600 offers 128 ports of 800G and the SN6800 512 ports of 800G), matching the per-chip capacity of Broadcom's Tomahawk 6, which began shipping in 2025.[18]
Continue reading
- NvidiaNvidia Corporation is an American technology company that designs graphics processing units (GPUs) and is the world's dominant supplier of hardware for artificial intelligenceMentioned 57 times above
- InfiniBandInfiniBand is a high throughput, low latency networking interconnect standard used to connect servers, storage, and accelerators inside high performance computing systems and large artificial intelligence…Mentioned 39 times above
- Data CenterA data center is a purpose-built facility, or a dedicated part of a facility, that houses and interconnects information technology and telecommunications equipment together with the power…Mentioned 10 times above
- xAIxAI is an artificial intelligence business established in 2023 under Elon Musk, who led it before the SpaceX acquisition.Mentioned 7 times above
- NVIDIA GB300 NVL72The NVIDIA GB300 NVL72 is a liquid-cooled, rack-scale AI computing system that integrates 72 NVIDIA Blackwell Ultra (B300) GPUs and 36 Arm-based NVIDIA Grace CPUs into a single NVLink fabric, delivering 1.1…Mentioned twice above
- Stargate ProjectThe Stargate Project is a private American AI infrastructure joint venture, announced at the White House on January 21, 2025, under which SoftBank, OpenAI, Oracle and MGX said they intended to invest $500…Mentioned twice above
More from See also
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6NVIDIA Newsroom. "NVIDIA Launches Accelerated Ethernet Platform for Hyperscale Generative AI." May 28, 2023. nvidianews.nvidia.com/...-hyperscale-generative-ai
- NVIDIA Newsroom. "NVIDIA's New Ethernet Networking Platform for AI Available Soon From Dell Technologies, Hewlett Packard Enterprise, Lenovo." November 2023. nvidianews.nvidia.com/...packard-enterprise-lenovo
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25NVIDIA Technical Blog. "Turbocharging Generative AI Workloads with NVIDIA Spectrum-X Networking Platform." developer.nvidia.com/...trum-x-networking-platform
- ^NVIDIA Technical Blog. "Optimize Large-Scale AI Workloads with NVIDIA Spectrum-X." developer.nvidia.com/...ads-with-nvidia-spectrum-x
- ^1 ^2 ^3 ^4 ^5 ^6Data Center Dynamics. "Nvidia's Israel-1 supercomputer starts operations." November 2023. datacenterdynamics.com/...mputer-starts-operations
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10NVIDIA Newsroom. "NVIDIA Ethernet Networking Accelerates World's Largest AI Supercomputer, Built by xAI." 2024. nvidianews.nvidia.com/...t-networking-xai-colossus
- ^Data Center Dynamics. "xAI to double Colossus compute capacity, reveals cluster uses Nvidia Spectrum-X ethernet." 2024. datacenterdynamics.com/...idia-spectrum-x-ethernet
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8NVIDIA Newsroom. "NVIDIA Spectrum-X Ethernet Switches Speed Up Networks for Meta and Oracle." October 13, 2025. nvidianews.nvidia.com/...works-for-meta-and-oracle
- ^1 ^2 ^3 ^4 ^5 ^6NVIDIA Newsroom. "NVIDIA Introduces Spectrum-XGS Ethernet to Connect Distributed Data Centers Into Giga-Scale AI Super-Factories." August 22, 2025. nvidianews.nvidia.com/...-scale-ai-super-factories
- ^1 ^2 ^3 ^4 ^5 ^6 ^7NVIDIA Newsroom. "NVIDIA Announces Spectrum-X Photonics, Co-Packaged Optics Networking Switches to Scale AI Factories to Millions of GPUs." March 18, 2025. nvidianews.nvidia.com/...ing-switches-ai-factories
- ^1 ^2 ^3 ^4NVIDIA Docs. "ConnectX-8 SuperNIC Specifications." docs.nvidia.com/...specifications
- ^1 ^2 ^3 ^4 ^5NVIDIA Docs. "Spectrum SN5000 Series Switches." docs.nvidia.com/...sn5000
- ^Next Platform. "Nvidia Passes Cisco And Rivals Arista In Datacenter Ethernet Sales." June 23, 2025. nextplatform.com/...a-in-datacenter-ethernet-sales
- ^1 ^2Cisco Newsroom. "Cisco Delivers AI Innovations across Neocloud, Enterprise and Telecom with NVIDIA." October 2025. newsroom.cisco.com/...rise-and-telecom-with-nvidia
- ^Hyperframe Research. "Hot Chips 2025: NVIDIA Ushers in the Scale Across Giga-Scale AI Super-Factories Era." August 2025. hyperframeresearch.com/...e-ai-super-factories-era
- NVIDIA Technical Blog. "Benchmarking NVIDIA Spectrum-X for AI Network Performance, Now Available from Supermicro." developer.nvidia.com/...-available-from-supermicro
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12Spheron Blog. "GPU Networking for AI Clusters: InfiniBand vs RoCE vs Spectrum-X Decision Guide (2026)." spheron.network/...nfiniband-roce-spectrum-x-guide
- ^1 ^2 ^3 ^4NVIDIA Networking. "Spectrum-X Ethernet Platform." nvidia.com/...spectrumx
- ^1 ^2IDC. "Worldwide Ethernet Switch Market Grew 42.1% in the Second Quarter of 2025, According to IDC's Quarterly Ethernet Switch Tracker." September 11, 2025. idc.com/...-idcs-quarterly-ethernet-switch-tracker
- ^Focus Taiwan (CNA). "Nvidia ships TSMC-backed CPO switches to tackle AI data center bottlenecks." June 3, 2026. focustaiwan.tw/...202606030020
- ^1 ^2Engineering at Meta. "Building Meta's GenAI Infrastructure." March 12, 2024. engineering.fb.com/...g-metas-genai-infrastructure
- ^1 ^2NVIDIA Docs. "ConnectX-8 SuperNIC User Manual: Introduction." docs.nvidia.com/...introduction
- ^1 ^2 ^3NVIDIA Newsroom. "NVIDIA Announces New Switches Optimized for Trillion-Parameter GPU Computing and AI Infrastructure." March 18, 2024. nvidianews.nvidia.com/...switches-gpu-computing-ai
- ^Converge Digest. "CoreWeave Implements NVIDIA GB300 NVL72 in Cloud." July 2025. convergedigest.com/...-nvidia-gb300-nvl72-in-cloud
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
9 revisions · v9 · 4,291 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (120 claims, 29 sources fetched); 15 material + 17 minor fixed
Cite this page: AI Wiki. "NVIDIA Spectrum-X." aiwiki.ai, updated 28 Oct 2026, fact-checked 4 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/nvidia_spectrum_x