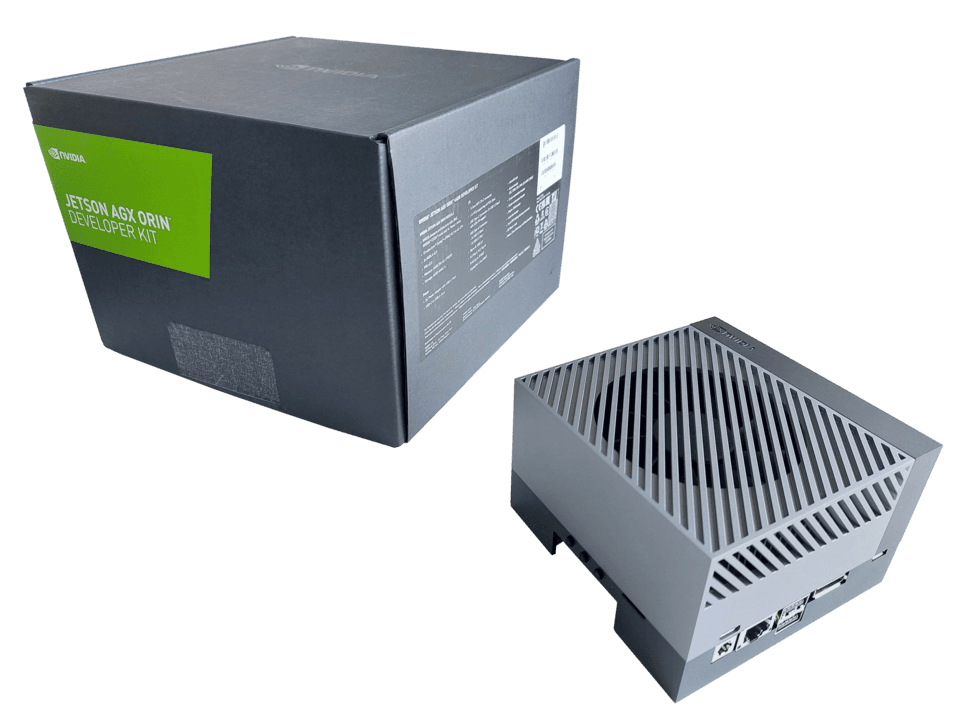
NVIDIA Jetson is NVIDIA's family of compact, power-efficient system-on-modules (SoMs) that bring GPU-accelerated computing to machines that cannot lean on a data-center connection: robots, drones, cameras, and other devices that have to sense and decide on…
Artificial Analysis is an independent benchmarking and analytics platform that evaluates artificial intelligence models and API providers across intelligence, speed, price, and latency, and it is best known for the Artificial Analysis Intelligence Index
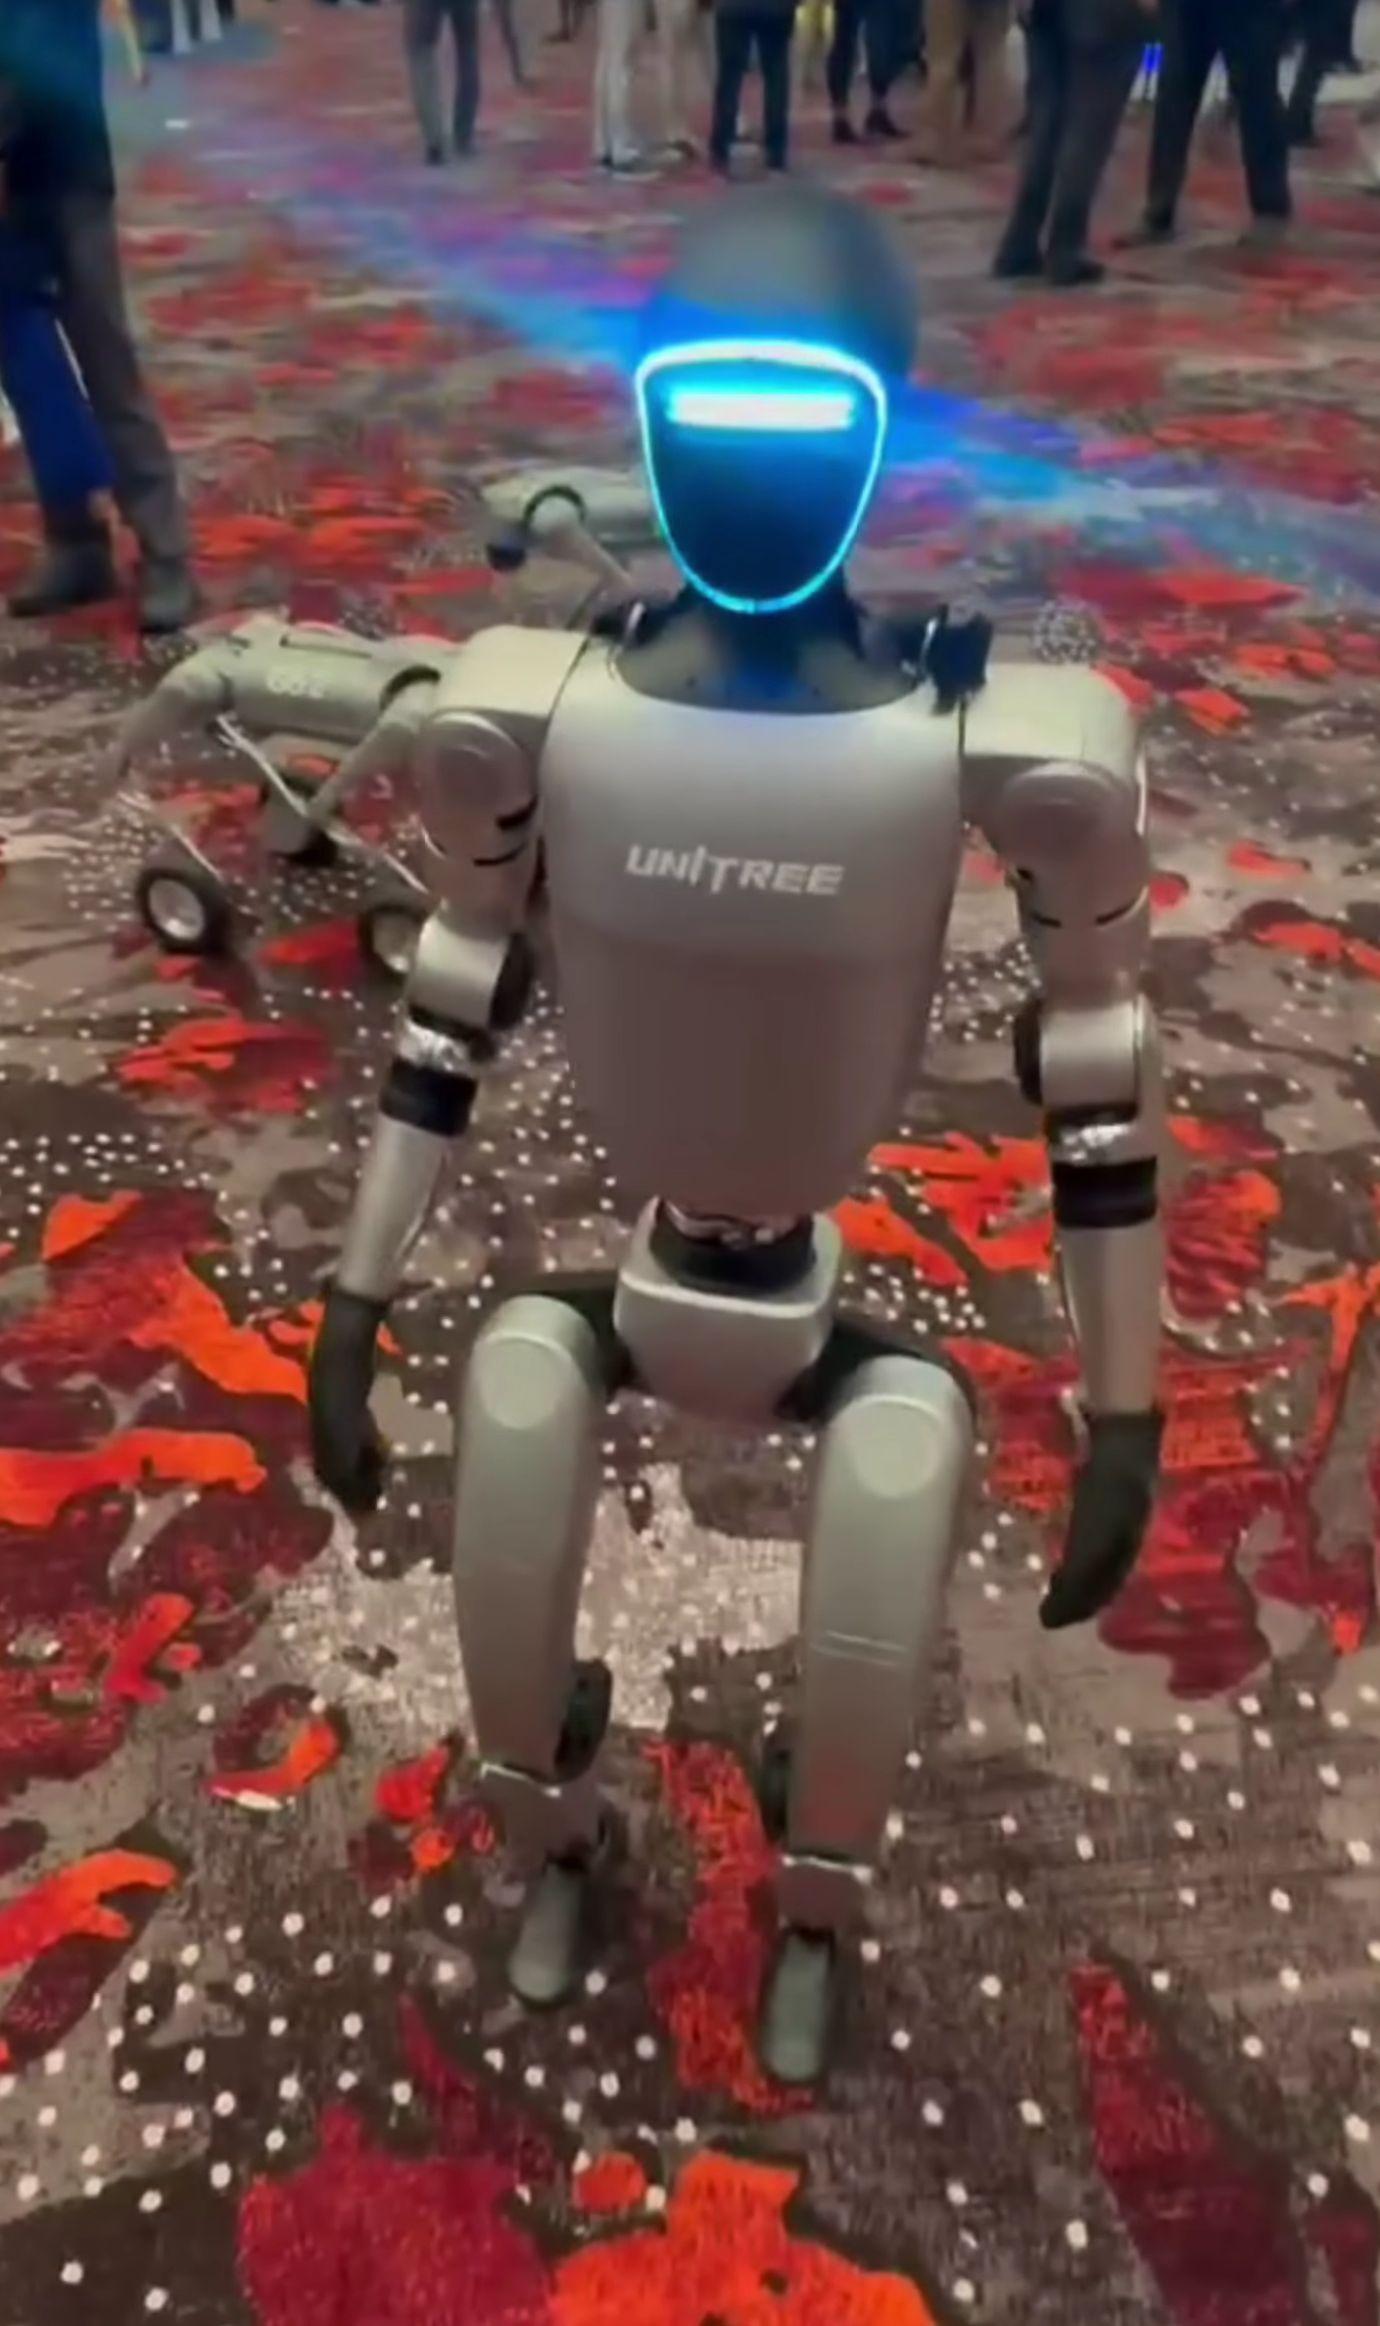
The Unitree G1 is a compact, general-purpose humanoid robot developed by Unitree Robotics, a Chinese robotics company headquartered in Hangzhou, Zhejiang.
A world model is an artificial intelligence system that learns an internal representation of how an environment works, enabling it to predict future states, simulate the consequences of actions, and support planning without needing to interact with the real…
Taiwan Semiconductor Manufacturing Company (TSMC) is the world's largest dedicated semiconductor foundry and the company that physically manufactures the overwhelming majority of advanced AI chips, including Nvidia data-center GPUs, AMD accelerators, Apple…
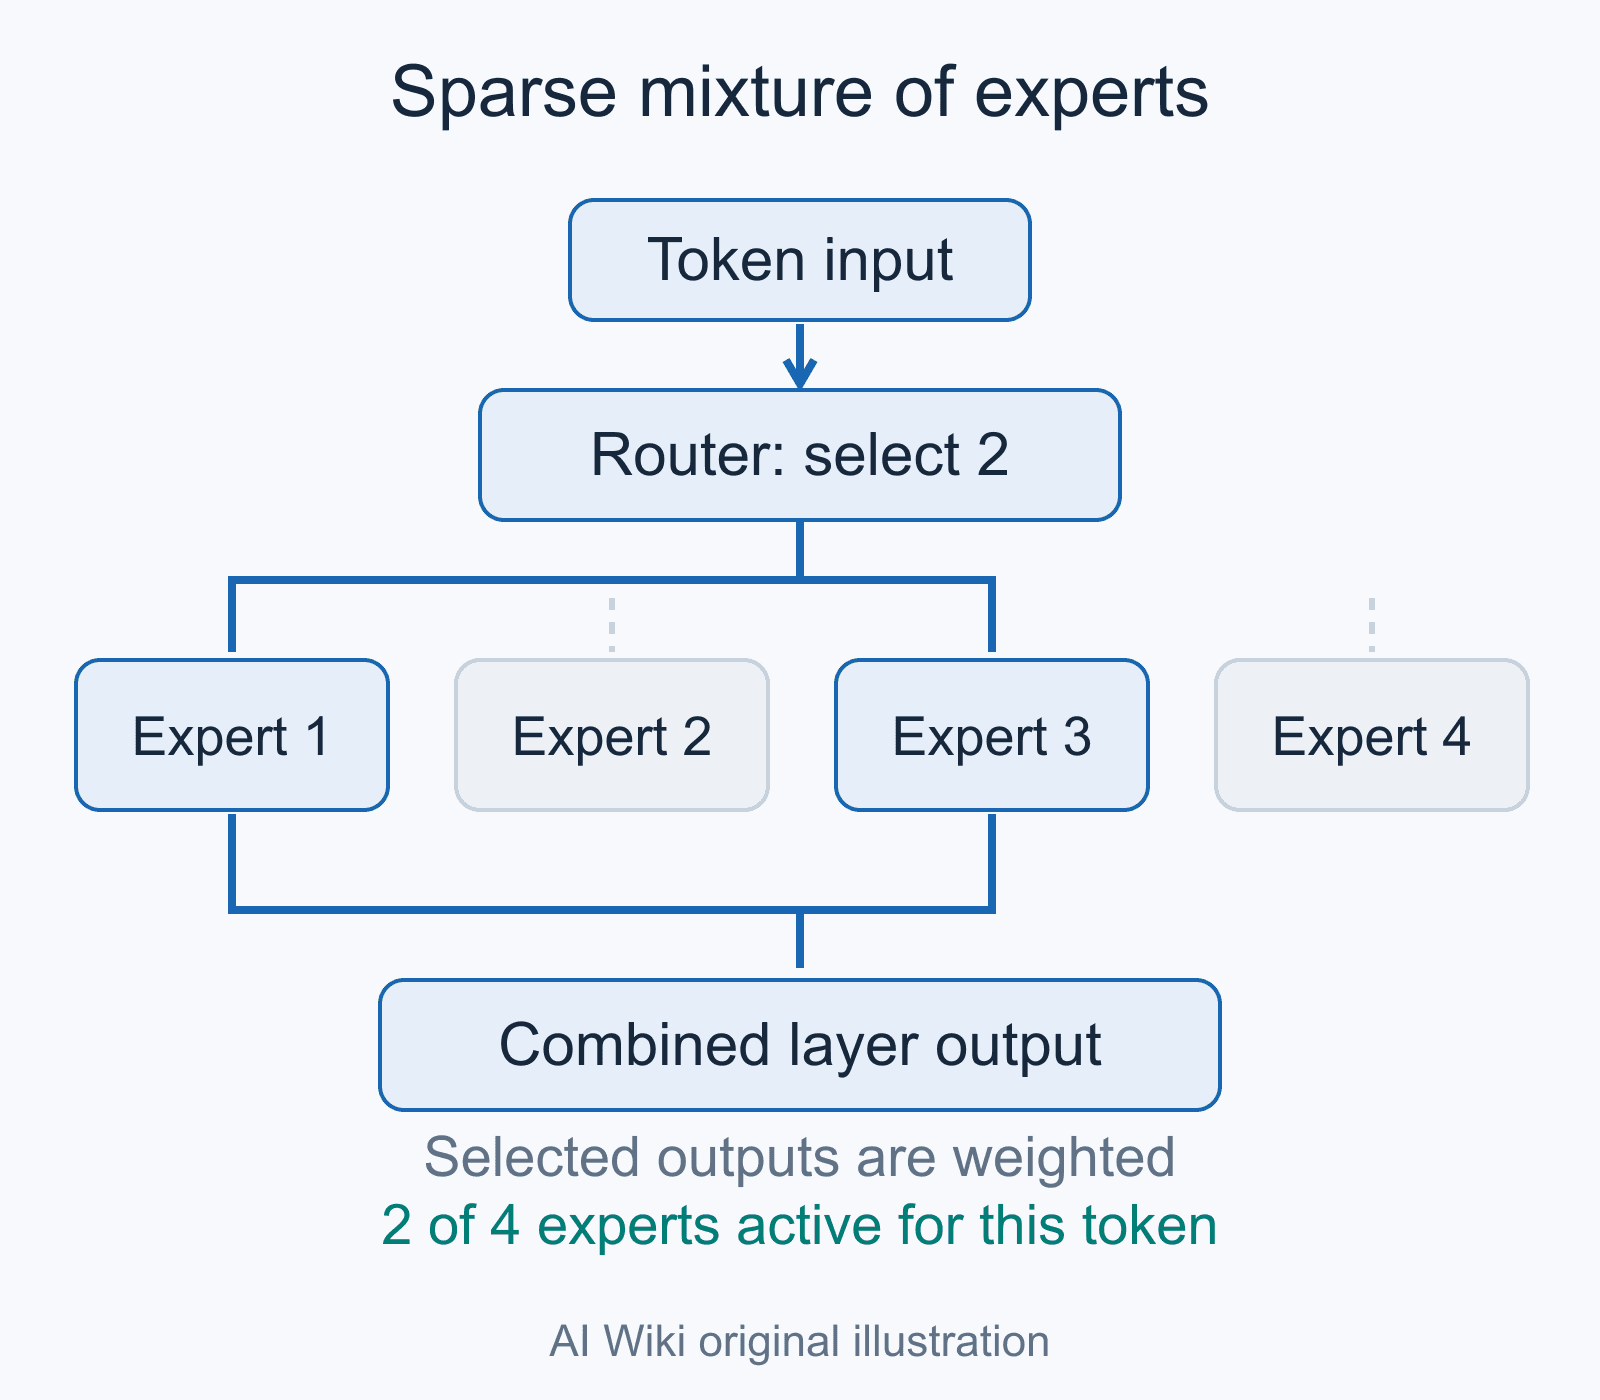
A mixture of experts (MoE) is a machine-learning architecture that contains multiple component functions called experts and a gating or routing mechanism that determines how their outputs contribute to a result.
Ricursive Intelligence is an American artificial intelligence company based in Palo Alto, California, that develops AI systems for designing semiconductors.
AI Compute Tracker reviewed standard (non-batch) provider list prices in USD per 1M tokens, at the short-context or peak-hour tier. Cached input is shown only when recorded in that row; it is not inferred from a discount. Long-context, cache writes, batch, tools, media and other charges are not included.
Higher is better, not an IQ or percentage. Catalogue metadata does not disclose the index version, reasoning configuration, or evaluation date; checked time is retrieval time. Treat comparisons as indicative.
Benchmark version: not supplied. Test configuration: not supplied.
AI Compute Tracker reviewed standard (non-batch) provider list prices in USD per 1M tokens, at the short-context or peak-hour tier. Cached input is shown only when recorded in that row; it is not inferred from a discount. Long-context, cache writes, batch, tools, media and other charges are not included. Tracker row notes: ≤272K prompt tokens; above 272K $4/$15
Higher is better, not an IQ or percentage. Catalogue metadata does not disclose the index version, reasoning configuration, or evaluation date; checked time is retrieval time. Treat comparisons as indicative.
Benchmark version: not supplied. Test configuration: not supplied.
AI Compute Tracker reviewed standard (non-batch) provider list prices in USD per 1M tokens, at the short-context or peak-hour tier. Cached input is shown only when recorded in that row; it is not inferred from a discount. Long-context, cache writes, batch, tools, media and other charges are not included. Tracker row notes: Current price through Nov 30, 2026; $4/$20 from Dec 1, 2026; batch $2/$10 from Dec 1, 2026
Higher is better, not an IQ or percentage. Catalogue metadata does not disclose the index version, reasoning configuration, or evaluation date; checked time is retrieval time. Treat comparisons as indicative.
Benchmark version: not supplied. Test configuration: not supplied.
AI Compute Tracker reviewed standard (non-batch) provider list prices in USD per 1M tokens, at the short-context or peak-hour tier. Cached input is shown only when recorded in that row; it is not inferred from a discount. Long-context, cache writes, batch, tools, media and other charges are not included. Tracker row notes: Peak-hour cache-miss input; off-peak $0.15/$0.60; deepseek-flash alias
Example cost: 1,000 requests, each with 2,000 input and 500 output tokens, at the listed standard text rates. No caching, batch discount, long-context surcharge, tools, media or tax; not a capability or availability check. Adjust this workload in the cost planner (choose a model there).