

τ-bench
τ-bench (Tau-bench), short for Tool-Agent-User Interaction Benchmark, is an AI benchmark that evaluates language agents' ability to complete complex tasks through realistic, multi-turn interactions with simulated users and domain-specific tools. Released on June 17, 2024, by Sierra, τ-bench tests whether agents can follow domain-specific rules, maintain context over long conversations, and coordinate with users to reach a single correct outcome.[1] Its headline finding was that even the strongest function-calling agents of the time succeeded on fewer than 50% of tasks and were highly inconsistent, scoring below 25% on pass^8 in the retail domain.[1] As the original paper concluded, "even state-of-the-art function calling agents (like gpt-4o) succeed on <50% of the tasks, and are quite inconsistent (pass^8 <25% in retail). Our findings point to the need for methods that can improve the ability of agents to act consistently and follow rules reliably."[1] The paper was accepted as a poster at the International Conference on Learning Representations (ICLR) 2025.[12]
Unlike earlier agent benchmarks such as WebArena, SWE-bench, and AgentBench, which evaluate agents in single-round human-agent interactions, τ-bench requires agents to handle multiple dynamic exchanges where information is gathered incrementally over the course of a conversation.[1] This design mirrors the way customer service agents operate in practice, where a single interaction can involve identity verification, information retrieval, policy checking, multi-step tool calls, and explicit user confirmation before taking action.
Quick Facts
| Attribute | Value |
|---|---|
| Full name | Tau-bench: Tool-Agent-User Interaction Benchmark |
| Abbreviation | τ-bench |
| Description | A benchmark for evaluating AI agents' ability to complete complex tasks through realistic tool-agent-user interactions in real-world domains |
| Release date | 2024-06-17 [1] |
| Latest version | τ³-bench (2026: task fixes plus banking and voice extensions) [7][8] |
| Benchmark updated | February 2026 (τ³ task fixes) [8] |
| Authors | Shunyu Yao, Noah Shinn, Pedram Razavi, Karthik Narasimhan [1] |
| Organization | Sierra [1] |
| Type | Agent Evaluation, Multi-turn Interaction |
| Modality | Text, API Calls |
| Task format | Conversational task completion |
| Number of tasks | 165 total (115 retail, 50 airline) [1] |
| Evaluation metric | pass^k, Database State Comparison [1] |
| Domains | Airline, Retail [1] |
| Languages | English |
| Human performance | Not reported |
| SOTA score | 82.4% (Retail pass^1), 62.0% (Airline pass^1), self-reported [10][11] |
| SOTA model | Claude Opus 4.1 (retail), MiniMax M1 80K (airline) [10][11] |
| SOTA date | 2025 |
| Saturated | No (airline); approaching saturation (retail) |
| Website | Official website |
| Paper | arXiv:2406.12045 |
| GitHub | sierra-research/tau-bench |
| License | MIT [2] |
| Conference | ICLR 2025 (Poster) [12] |
| Successor | τ²-bench, τ³-bench |
What does τ-bench measure?
τ-bench represents a paradigm shift in AI agent evaluation, moving beyond simple task completion to assess agents' performance in dynamic, multi-turn conversations that mirror real-world applications. The benchmark emulates scenarios where an AI agent must interact with both users (simulated by large language models) and domain-specific API tools while adhering to complex policy guidelines.[1] The paper frames the core motivation plainly: "Existing benchmarks do not test language agents on their interaction with human users or ability to follow domain-specific rules, both of which are vital for deploying them in real world applications."[1]
Key Innovation
Unlike traditional benchmarks that focus on single-turn interactions or isolated capabilities, τ-bench introduces:
- Stateful Evaluation: Compares database states after task completion
- User Simulation: LLM-simulated users provide realistic conversational dynamics
- Policy Adherence: Tests agents' ability to follow domain-specific rules
- Consistency Measurement: Introduces the pass^k metric, a reliability counterpart to pass@k
The benchmark revealed that even state-of-the-art function calling agents (like GPT-4o) succeed on less than 50% of the tasks and are quite inconsistent (pass^8 <25% in retail).[1]
Background and Motivation
Why was τ-bench created?
By mid-2024, large language models had demonstrated strong capabilities in isolated tasks like text generation, code completion, and question answering. However, deploying these models as autonomous agents in real-world settings revealed a gap between benchmark performance and actual reliability. Existing agent benchmarks at the time tested agents on well-defined, single-turn problems: SWE-bench measured software engineering ability, HumanEval tested code generation, and AgentBench evaluated agents across several environments. None of these benchmarks required agents to interact with a human user over multiple turns while simultaneously calling tools and following complex policies.[1] As Sierra's research team put it, "there is a dearth of good benchmarks to measure the reliability of agents in dynamic real-world scenarios with humans in the loop."[3]
Sierra, the conversational AI company co-founded by Bret Taylor (former Salesforce co-CEO, who became chair of OpenAI's board in November 2023) and Clay Bavor (former Google executive), had direct experience with the gap between benchmark scores and real-world agent performance.[3] Sierra's research team, led by Karthik Narasimhan, identified three capabilities that existing benchmarks failed to measure:[3]
- Dynamic multi-party interaction: Agents must interact with both human users and backend APIs over extended periods, gathering information incrementally rather than receiving all inputs up front.
- Policy compliance: Agents must accurately follow domain-specific rules and guidelines, which can be lengthy and contain subtle edge cases.
- Reliability at scale: A customer service agent that resolves a problem 60% of the time on the first try is not useful if it fails on the same problem the next time a different customer asks.
Who created τ-bench?
Shunyu Yao, the lead author of τ-bench, is known for creating the ReAct framework (ICLR 2023), which introduced the paradigm of interleaving reasoning traces with actions in language models. He also created WebShop (NeurIPS 2022), an earlier e-commerce interaction benchmark, and co-developed SWE-agent. The paper's title block lists Sierra as the only affiliation for all four authors, with a footnote stating that Yao's contribution was made during an internship.[1] Noah Shinn, another co-author, is known for his work on Reflexion, a framework for language agent self-reflection. Pedram Razavi contributed from Sierra, and Karthik Narasimhan is Head of Research at Sierra as well as an associate professor of computer science at Princeton University.[1][16]
Architecture and Design
τ-bench employs a modular three-component architecture that simulates realistic customer service interactions. Each component plays a distinct role in creating a closed-loop evaluation environment.[1]
Three-Component Framework
| Component | Role | Implementation Details |
|---|---|---|
| User Simulator | Generates realistic user messages based on hidden instructions | LLM-based (GPT-4, Claude, etc.); guided by task-specific instructions that define user identity, intent, and preferences |
| Agent System | Processes user requests, calls tools, and follows policies | Supports multiple architectures: tool-calling (function calling), ReAct, and Act |
| Environment | Provides API tools, maintains database state, and enforces domain rules | Domain-specific databases with realistic data; tools exposed as callable functions |
The interaction loop works as follows: the user simulator initiates a conversation with a request (for example, "I need to cancel my flight to Denver"). The agent responds by calling tools to look up information, asking clarifying questions, or taking actions. The user simulator replies based on its hidden instruction set, which specifies the user's identity, preferences, and constraints. This back-and-forth continues until the agent resolves the request or the conversation reaches a maximum number of turns.[1]
Critically, the user instructions are hidden from the agent. The agent only sees the user's natural language messages and must infer what the user wants through conversation, just as a real customer service agent would.[1]
User Simulation
Each task in τ-bench includes a structured user instruction that defines:
- User identity: Name, email, membership tier, payment methods on file
- User intent: What the user wants to accomplish (cancel a flight, exchange a product, modify an address)
- User preferences: Specific constraints (preferred payment method, desired cabin class, acceptable alternatives)
- Behavioral guidelines: How cooperative or difficult the simulated user should be
The instruction is designed so that only one correct outcome exists under the domain's policy. This constraint is essential for automated evaluation: because there is exactly one valid goal state, the benchmark can verify success by comparing the final database state against the annotated expected state without requiring subjective human judgment.[1]
The user simulator itself is powered by an LLM (typically GPT-4 or Claude). While the instructions are synthetic, the utterances the simulator generates are open-ended and natural-sounding. The benchmark supports several user simulation strategies:
| Strategy | Description | Use Case |
|---|---|---|
| LLM (default) | Direct LLM-generated responses based on user instructions | Standard evaluation |
| ReAct | Adds explicit reasoning steps before generating user responses | Complex reasoning tasks |
| Verify | Includes an LLM verification loop after each response | High-accuracy requirements |
| Reflection | Adds self-correction to improve response quality | Improved consistency |
In the ICLR 2025 version of the paper, the authors manually examined 50 randomly sampled failed airline trajectories (gpt-4o function calling) and found that fewer than 4% of errors were caused by the user simulator, across all four user strategies; the reflection strategy performed best.[19]
Domains and Tasks
The benchmark covers two primary domains:
Retail Domain (τ-retail)
The retail domain simulates an e-commerce customer support environment. It contains 115 tasks built on a synthetic database of 500 users, 50 products, and 1,000 orders.[1]
- Scenario: E-commerce customer support
- Tools: Order management, inventory, returns, payment APIs
- Policies: Return windows, warranty terms, pricing rules
- Challenges: Product availability, order modifications, refund processing
- Difficulty: Noticeably easier to navigate compared to airline
Available API Tools (15 total: 7 write, 8 read)
The retail agent has access to tools for retrieving and modifying customer data:
| Tool Category | Examples | Description |
|---|---|---|
| User lookup | get_user_details | Retrieve user profile information after authentication |
| Order retrieval | get_order_details | Look up order status, items, shipping, and payment |
| Product information | get_product_details | Check product availability, options, and pricing |
| Order cancellation | cancel_pending_order | Cancel orders with status "pending" only |
| Order modification | modify_pending_order_address, modify_pending_order_items, modify_pending_order_payment | Change shipping address, payment method, or item options on pending orders |
| Returns | return_delivered_order_items | Process returns on delivered orders within the return window |
| Exchanges | exchange_delivered_order_items | Exchange delivered items for different options of the same product |
| Profile updates | modify_user_address | Update user shipping or billing addresses |
Key Retail Policies
- The agent must authenticate the user at the start of every conversation by locating their user ID via email, or via name plus zip code.
- Only one user can be helped per conversation. Requests related to other users must be denied.
- Before any consequential action (cancel, modify, return, exchange), the agent must list the action details and obtain explicit user confirmation.
- Exchange and modify order tools can only be called once per conversation. All items to be changed must be collected into a single tool call.
- Only pending orders can be cancelled or modified. Only delivered orders can be returned or exchanged.
- The agent must make at most one tool call at a time and should not respond to the user simultaneously with a tool call.
Example Retail Task: A user contacts support wanting to exchange a blue medium t-shirt from their delivered order for a red large version of the same product. The agent must authenticate the user, look up the order, verify the order status is "delivered," check that the red large option is available, collect all exchange details, confirm with the user, and execute the exchange in a single tool call.
Airline Domain (τ-airline)
The airline domain simulates a flight reservation customer service environment. It contains 50 tasks built on a synthetic database of 500 users, 300 flights, and 2,000 reservations.[1]
- Scenario: Customer service for airline bookings
- Tools: Flight search, booking, cancellation, modification APIs
- Policies: Fare rules, refund policies, upgrade procedures
- Challenges: Multi-leg trips, schedule changes, policy compliance
- Difficulty: More challenging than retail domain
Available API Tools (13 total: 6 write, 7 read)
The airline agent has access to tools for managing flight reservations:
| Tool Category | Examples | Description |
|---|---|---|
| Flight search | search_direct_flight, search_onestop_flight | Find available direct or connecting flights |
| Reservation lookup | get_reservation_details | Retrieve booking information, passengers, and flight details |
| User lookup | get_user_details | Authenticate and retrieve user profile |
| Booking | book_reservation | Create new flight reservations (max 5 passengers) |
| Modification | update_reservation_flights, update_reservation_baggages, update_reservation_passengers | Change flights, cabin class, checked bags, or passenger details (insurance cannot be added after booking) |
| Cancellation | cancel_reservation | Cancel reservations subject to policy rules |
Key Airline Policies
- All reservations can be cancelled within 24 hours of booking regardless of cabin class.
- Outside the 24-hour window, basic economy and economy reservations can only be cancelled if the passenger purchased travel insurance and meets the insurance conditions.
- Business class reservations can always be cancelled.
- If the airline cancels a flight, all passengers are eligible for cancellation and potential compensation.
- Cabin class upgrades are allowed without changing flights, but the user must pay the fare difference.
- Modifications cannot change the origin, destination, or trip type (one-way vs. round-trip).
- Only silver and gold members, travelers with insurance, or business-class passengers qualify for service recovery certificates in cases of delays or cancellations.
- Maximum of five passengers per reservation, and all passengers must be on identical flights and cabin class.
Example Airline Task: A user calls about a delayed flight and wants to rebook on an earlier connection. The agent must verify the user's identity, check the reservation details, determine if the passenger's membership tier qualifies them for compensation, search for alternative flights, confirm the new itinerary with the user, and process the modification while applying the correct fare difference.
Task Complexity
Tasks in τ-bench are designed to apply pressure in diverse ways. In the paper's retail analysis, tasks that require more database write actions were markedly harder for function-calling agents.[1]
| Complexity Factor | Description | Example |
|---|---|---|
| Long-chain dependencies | Multiple sequential steps where later actions depend on earlier results | Booking a multi-passenger reservation where each passenger has different preferences |
| Buried essential details | Critical information hidden deep in the conversation or policy document | A checked-bag allowance that depends on both the booking user's membership tier and each passenger's cabin class |
| Realistic forgetting scenarios | Situations where an agent might lose track of earlier conversation context | A user who mentions their email early in the conversation and later asks the agent to use it for a different purpose |
| Policy conflicts | Requests that conflict with domain rules, requiring the agent to refuse or offer alternatives | A user asking to cancel a basic economy ticket without insurance outside the 24-hour window |
| Compound requests | Multiple distinct actions needed in a single conversation | A user who wants to cancel one order, modify another, and update their address |
How does τ-bench evaluate agents?
Database State Comparison
τ-bench uses an objective, automated evaluation approach that avoids the subjectivity of LLM-as-judge methods. The process works as follows:[1]
- Initial state capture: The database is recorded before the conversation begins.
- Conversation execution: The agent interacts with the user simulator over multiple turns, calling tools as needed.
- Final state capture: The database state is recorded after the conversation ends.
- Goal state comparison: The final database state is compared against a pre-annotated goal state that represents the single correct outcome for that task.
- Binary success determination: The task is scored as a success (1) if the final state matches the goal state and the agent's replies contain any information the task requires (for example, a quoted price), or a failure (0) otherwise.
This approach is both efficient (no human evaluators or LLM judges needed per evaluation) and faithful (the comparison is deterministic and objective). Partial credit is not awarded; a task either succeeds completely or fails.
What is the pass^k metric?
One of τ-bench's most significant contributions is the introduction of the pass^k ("pass hat k") metric, which measures agent reliability across repeated trials.[1]
The standard pass@k metric, widely used in code generation benchmarks like HumanEval, asks: "Did the agent succeed on at least one of k attempts?" This measures peak capability. In contrast, pass^k asks: "Did the agent succeed on all k independent attempts?" This measures consistency.[1]
Formally, for a given task with n independent trials of which c are successful:
- pass^1 = E[r] = E[c/n], the expected success rate on a single attempt (equivalent to pass@1)
- pass^k = the probability that all k independent, identically distributed trials succeed
The distinction matters enormously for real-world deployment. A customer service agent that resolves a particular type of issue 60% of the time will, over 8 independent instances of that issue, succeed on all 8 only about 1.7% of the time (0.6^8). The pass^k metric captures this compounding unreliability.[1]
| Metric | Question Answered | Significance |
|---|---|---|
| Pass@1 / pass^1 | What fraction of tasks does the agent solve on a single attempt? | Basic capability measure |
| pass^4 | What fraction of tasks does the agent solve on all 4 independent attempts? | Moderate reliability threshold |
| pass^8 | What fraction of tasks does the agent solve on all 8 independent attempts? | High reliability threshold |
| pass^k | Chance that all k i.i.d. trials succeed, averaged across tasks | General reliability metric |
The benchmark doesn't just test whether an agent can complete a task once; it measures whether it can do so consistently multiple times. The original paper showed that GPT-4o achieved a pass^1 of 61.2% on retail tasks but dropped to approximately 25% on pass^8, which Sierra described as a 60% drop.[1][3] Sierra's research team described the practical meaning bluntly: "there is only a 25% chance that the agent will resolve 8 cases of the same issue with different customers, a number that is far behind the expectation of a real-world user-facing agent."[3] This dramatic drop revealed that even capable models are highly inconsistent when handling the same type of request with different conversational variations.
Auto Error Identification
τ-bench includes an automatic error identification tool (available in the GitHub repository as auto_error_identification.py) that analyzes failed trajectories to classify errors.[2] The tool categorizes failures along two dimensions:
Fault Assignment (who caused the failure):
- Agent fault (the agent made an incorrect decision)
- User simulator fault (the simulated user behaved unrealistically)
- Environment fault (a tool or database issue)
Fault Type (what kind of error occurred):
| Fault Type | Description |
|---|---|
| goal_partially_completed | The agent completed only part of what the user wanted |
| used_wrong_tool | The agent called the wrong tool |
| used_wrong_tool_argument | The agent called the right tool with incorrect arguments |
| took_unintended_action | The agent took an action the task did not call for |
The README cautions that the tool relies on an LLM and may misidentify errors.[2] In the paper's own manual analysis of 36 failed GPT-4o function-calling trajectories in τ-retail, wrong arguments or wrong information accounted for about 55% of failures, wrong decisions (misapplying domain rules) for 25%, and partial resolution of compound requests for 19%.[1]
Experimental Results
Original Paper Results (June 2024)
The original paper tested 12 popular LLMs with different agent architectures. The key findings were striking:[1]
- Even GPT-4o, the best-performing model at the time, averaged under 50% across the two domains (48.2%: 61.2% retail, 35.2% airline).
- Function-calling (tool-calling) agents consistently outperformed text-formatted agent methods like ReAct.
- Even the best agent, GPT-4o with function calling, fell below 25% on pass^8 in the retail domain, revealing severe consistency problems.
- The airline domain was harder for most models (GPT-4o: 35.2% vs 61.2%), though gemini-1.5-flash, mixtral-8x22b and claude-3-sonnet scored higher on airline than on retail.
Early Model Performance Comparison
Early performance of leading models on τ-bench:
| Model | Version/Mode | Airline Pass@1 | Retail Pass@1 | Notes |
|---|---|---|---|---|
| Claude 3.7 Sonnet | Planning-tool prompt addendum | 58.4% | 81.2% | Top performer at its February 2025 launch [17] |
| Claude 3.5 Sonnet | Upgraded (October 2024) | 46.0% | 69.2% | Improved from 36.0%/62.6% [13] |
| GPT-OSS-120B | Standard | Not reported | 67.8% | Open-weight model [14] |
| GPT-4o | Function calling | 35.2% | 61.2% | Original paper baseline [1] |
| GPT-4o | ReAct | 32.5% | Not reported | Repository leaderboard [2] |
| Claude 3.5 Sonnet | Original (June 2024) | 36.0% | 62.6% | Before upgrade [13] |
Note: pass^4 and pass^8 scores are substantially lower than pass^1; in the original paper even the best agent (GPT-4o with function calling) fell below 25% on pass^8 in retail.[1]
Current Leaderboard: Retail Domain
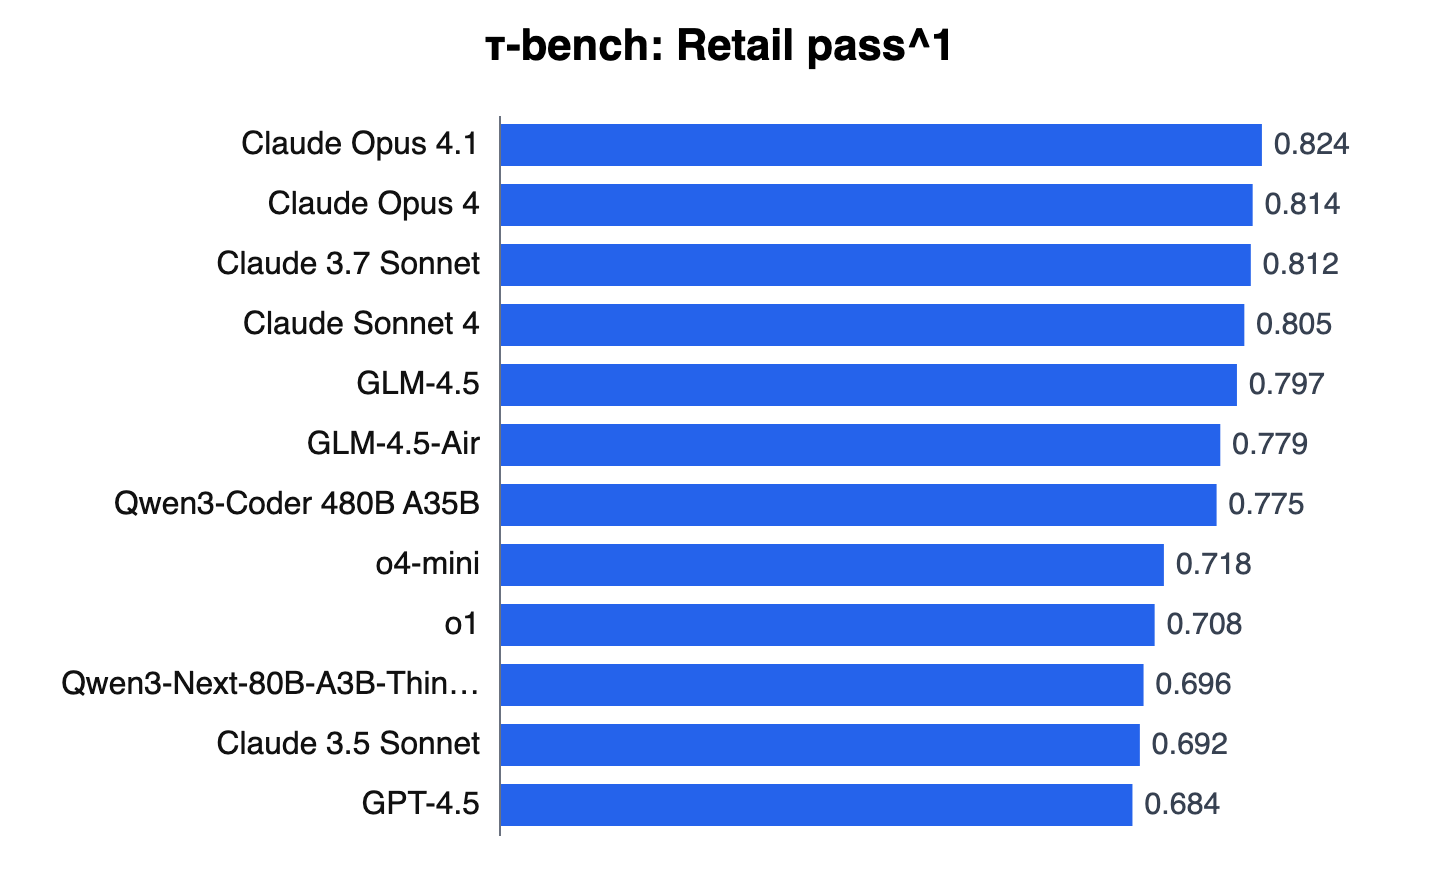
LLM-Stats compiles original τ-bench retail results, all self-reported by model developers (list last updated November 2026). They show substantial improvement over the 2024 paper, with the best models crossing 80% pass^1. Newer frontier models are generally reported on τ²-bench instead (Anthropic's Claude Sonnet 4.5 launch, for example, reported τ²-bench scores), so they do not appear here:[10][18]
| Rank | Model | Organization | Retail pass^1 |
|---|---|---|---|
| 1 | Claude Opus 4.1 | Anthropic | 0.824 |
| 2 | Claude Opus 4 | Anthropic | 0.814 |
| 3 | Claude 3.7 Sonnet | Anthropic | 0.812 |
| 4 | Claude Sonnet 4 | Anthropic | 0.805 |
| 5 | GLM-4.5 | Zhipu AI | 0.797 |
| 6 | GLM-4.5-Air | Zhipu AI | 0.779 |
| 7 | Qwen3-Coder 480B A35B | Alibaba | 0.775 |
| 8 | o4-mini | OpenAI | 0.718 |
| 9 | o1 | OpenAI | 0.708 |
| 10 | Qwen3-Next-80B-A3B-Thinking | Alibaba | 0.696 |
| 11 | Claude 3.5 Sonnet | Anthropic | 0.692 |
| 12 | GPT-4.5 | OpenAI | 0.684 |
| 13 | GPT-4.1 | OpenAI | 0.680 |
| 14 | Qwen3-235B-A22B-Thinking-2507 | Alibaba | 0.678 |
| 14 | GPT OSS 120B | OpenAI | 0.678 |
| 14 | MiniMax M1 40K | MiniMax | 0.678 |
| 17 | MiniMax M1 80K | MiniMax | 0.635 |
| 18 | Qwen3-Next-80B-A3B-Instruct | Alibaba | 0.609 |
| 19 | GPT-4o | OpenAI | 0.603 |
| 20 | o3-mini | OpenAI | 0.576 |
| 21 | GPT-4.1 mini | OpenAI | 0.558 |
| 22 | GPT OSS 20B | OpenAI | 0.548 |
| 23 | Claude 3.5 Haiku | Anthropic | 0.510 |
| 24 | GPT-4.1 nano | OpenAI | 0.226 |
LLM-Stats reports an average of 0.678 across its 25 retail entries. Its listed leader, Claude Sonnet 4.5 at 0.862 (0.700 in airline), is omitted above because Anthropic reported those figures on τ²-bench, not on the original τ-bench.[10][18] Among original τ-bench results, Anthropic's Claude models hold the top four retail positions, led by Claude Opus 4.1 at 0.824.[10]
Current Leaderboard: Airline Domain
The airline domain remains substantially harder, with the best self-reported τ-bench results around 62% compared to 82% in retail:[11]
| Rank | Model | Organization | Airline pass^1 |
|---|---|---|---|
| 1 | MiniMax M1 80K | MiniMax | 0.620 |
| 2 | GLM-4.5-Air | Zhipu AI | 0.608 |
| 3 | GLM-4.5 | Zhipu AI | 0.604 |
| 4 | MiniMax M1 40K | MiniMax | 0.600 |
| 4 | Claude Sonnet 4 | Anthropic | 0.600 |
| 4 | Qwen3-Coder 480B A35B | Alibaba | 0.600 |
| 7 | Claude Opus 4 | Anthropic | 0.596 |
| 8 | Claude 3.7 Sonnet | Anthropic | 0.584 |
| 9 | Claude Opus 4.1 | Anthropic | 0.560 |
| 10 | o1 | OpenAI | 0.500 |
| 10 | GPT-4.5 | OpenAI | 0.500 |
| 12 | GPT-4.1 | OpenAI | 0.494 |
| 13 | o4-mini | OpenAI | 0.492 |
| 14 | Qwen3-Next-80B-A3B-Thinking | Alibaba | 0.490 |
| 15 | Qwen3-235B-A22B-Thinking-2507 | Alibaba | 0.460 |
| 15 | Claude 3.5 Sonnet | Anthropic | 0.460 |
| 17 | Qwen3-Next-80B-A3B-Instruct | Alibaba | 0.440 |
| 18 | GPT-4o | OpenAI | 0.428 |
| 19 | GPT-4.1 mini | OpenAI | 0.360 |
| 20 | o3-mini | OpenAI | 0.324 |
| 21 | Claude 3.5 Haiku | Anthropic | 0.228 |
| 22 | GPT-4.1 nano | OpenAI | 0.140 |
LLM-Stats reports an average of 0.495 across its 23 airline entries, a figure that includes the τ²-bench Claude Sonnet 4.5 score.[11] The HAL evaluation team at Princeton independently verified that 48 of 50 airline tasks (96%) have been solved by at least one agent, suggesting that the individual tasks are solvable but no single agent can solve them all consistently.[9]
Key Performance Trends
Several patterns emerge from the leaderboard data:
- Anthropic leads in retail: Claude models hold the top four retail positions among original τ-bench results, several of them achieved with Anthropic's own prompt addenda to the agent policy.[10][17]
- Chinese models competitive in airline: Zhipu AI's GLM-4.5 models and MiniMax's M1 models perform comparably to or better than some Claude variants in the airline domain.[11]
- Reasoning models mixed: OpenAI's reasoning models (o1, o3-mini, o4-mini) do not consistently outperform their non-reasoning counterparts (GPT-4.1, GPT-4o) on this benchmark, suggesting that chain-of-thought reasoning alone is insufficient for multi-turn agent tasks.
- Cost-performance tradeoffs: On the airline domain, the Pareto frontier includes Gemini 2.0 Flash (28% accuracy, $0.31 total run cost), DeepSeek V3 (44%, $5.43), and o4-mini High (56%, $11.36) on HAL's TAU-bench Airline leaderboard; HAL notes that some reported costs are overstated.[9]
- Domain gap persists: The gap between retail and airline performance is consistent across models. Airline tasks involve more complex policies, multi-leg trips, and more subtle edge cases.
Failure Analysis
Common failure modes identified:
- Policy Violations: Agents bypass or misinterpret domain rules
- Context Loss: Information forgotten in long conversations
- User Misunderstanding: Incorrect interpretation of user intent
- API Misuse: Incorrect tool selection or parameter usage
- State Confusion: Losing track of transaction state
τ³-bench: Task Corrections
In February 2026, as part of the τ³-bench release, the τ-bench team audited and corrected over 50 tasks across both domains (27 airline fixes, 26 retail fixes).[8] The corrections addressed five categories of issues identified through community feedback and the τ-Bench Verified research program:[8]
| Issue Category | Description | Examples |
|---|---|---|
| Incorrect expected actions | The annotated goal state was wrong | Compensation offered to ineligible passengers; invalid PayPal refunds |
| Ambiguous user instructions | The user instruction allowed multiple valid interpretations | Economy vs. basic economy confusion; "similar" vs. "same" item specifications |
| Impossible constraints | The task setup made the intended solution unreachable | Required payment methods absent from user profiles; location contradictions |
| Missing fallback behaviors | No guidance for what the agent should do when the intended path fails | No defined action when product searches return no results |
| Policy loophole prevention | Tasks that could be "solved" by exploiting policy gaps | Cancel-and-rebook exploits instead of proper modification refusals; cabin upgrade workarounds |
The impact of these corrections varied by domain. In the airline domain, pass^1 scores increased by 14 to 20 points across models, and pass^4 improvements were even larger (up to 22 points for some models). In the retail domain, the changes were more modest, with pass^1 shifts ranging from -0.4 to +5.5 points. The retail corrections primarily reduced evaluation variance rather than uniformly boosting scores.[8]
How do you run τ-bench?
Setup and Configuration
τ-bench is open-source under the MIT license and available on GitHub. The original repository now warns that its airline and retail tasks are outdated and points users to τ³-bench in the sierra-research/tau2-bench repository; the original code can still be installed with:[2]
git clone https://github.com/sierra-research/tau-bench
cd tau-bench
pip install -e .
API keys must be set as environment variables for the model providers being evaluated: OPENAI_API_KEY, ANTHROPIC_API_KEY, GOOGLE_API_KEY, MISTRAL_API_KEY.[2]
Running Evaluations
The benchmark is run through a command-line interface:
python run.py --agent-strategy tool-calling --env retail --model gpt-4o --model-provider openai --user-model gpt-4o --user-model-provider openai --user-strategy llm --max-concurrency 10
Key configuration options include:
| Parameter | Options | Description |
|---|---|---|
| --agent-strategy | tool-calling, react, act, few-shot | How the agent structures its reasoning and actions |
| --env | retail, airline | Which domain to evaluate |
| --model | Various | The model powering the agent |
| --user-model | Various | The model powering the user simulator |
| --user-strategy | llm, react, verify, reflection | How the user simulator generates responses |
| --max-concurrency | Integer | Number of parallel evaluations |
| --task-ids | Comma-separated | Run specific tasks by ID |
Supported Models
τ-bench routes model calls through LiteLLM, so --model-provider and --user-model-provider accept any LiteLLM provider. The README documents API keys for OpenAI, Anthropic, Google, Mistral and AnyScale, the providers whose models (GPT-4o, Claude 3, Gemini 1.5, Mistral Large, Mixtral and Llama 3 70B) were tested in the original paper.[1][2]
Technical Features
- Concurrent Processing: Parallel API request handling through the
--max-concurrencyflag, allowing multiple tasks to be evaluated simultaneously. - Historical Trajectories: The repository stores historical interaction trajectories, which can be replayed for analysis without re-running expensive API calls.
- Error Analysis: The
auto_error_identification.pyscript automatically classifies failures by fault assignment and fault type.[2] - Configurable Tasks: Specific tasks can be selected with the
--task-idsflag for targeted debugging. - Extensible Framework: New domains can be added by implementing the environment interface with a database, tool set, and policy document.
Impact and Adoption
Industry Adoption
τ-bench has become one of the standard benchmarks for evaluating AI agents in the industry:
- Anthropic: Has embraced τ-bench as a key benchmark for Claude model development. Claude 3.7 Sonnet's launch announcement highlighted its top performance on τ-bench, and Anthropic has incorporated pass^k metrics into their model evaluation process.[4][17] The company has used self-reflection and longer chain-of-thought prompting to improve consistency on the benchmark.
- OpenAI: Has used τ-bench to evaluate GPT-4.1, GPT-4.5, and the o-series reasoning models. OpenAI reported GPT-5 results on the successor τ²-bench, and used the benchmark for GPT-OSS model evaluation.[14]
- Sierra AI: Maintains the benchmark and its successors (τ²-bench and τ³-bench) and hosts the official leaderboard at taubench.com.[7]
- AI startups: Companies like Scaled Cognition have adopted τ-bench to evaluate their agent foundation models.
- Princeton HAL: The Princeton-led Holistic Agent Leaderboard (HAL) team independently reproduces τ-bench results, providing verified scores for the airline domain leaderboard.[9]
- Research Labs: Standard benchmark for agent papers.
Academic Influence
Within one year of release, τ-bench has had significant academic impact:
- The paper was accepted at ICLR 2025 as a poster presentation.[12]
- Been cited in numerous agent evaluation papers.
- Inspired domain-specific variants (for example MedAgentBench).
- Become standard for multi-turn agent evaluation.
- Influenced new evaluation methodologies.
- The pass^k metric has been adopted beyond τ-bench as a standard reliability measure for agent evaluation.
- It has become a standard reference point alongside WebArena and SWE-bench as representing a new class of rigorous agent benchmarks.
Researchers found that naive ReAct-style agents often break down during complex multi-step sequences, leading to the development of enhanced approaches including hierarchical architectures that maintain goals and memory throughout multi-turn conversations.
Derivative Benchmarks
τ²-bench (Tau-squared-bench)
Released in June 2025 by Sierra, with co-authors at the University of Toronto and the Vector Institute (arXiv:2506.07982), τ²-bench extends the τ-bench framework to a telecom domain with a critical new challenge: dual-control environments.[6] In the original τ-bench, only the agent uses tools. In τ²-bench, both the agent and the user can take actions in a shared environment, modeled as a Decentralized Partially Observable Markov Decision Process (Dec-POMDP).[6]
Key features of τ²-bench:
| Feature | Description |
|---|---|
| Telecom domain | Mobile phone technical support scenarios (no service, mobile data and MMS issues) |
| Dual-control | Both agent and user have tools; the user must perform actions on their end (restart their phone, toggle airplane mode) |
| Compositional task generator | Programmatically creates diverse, verifiable tasks from atomic components |
| Reliable user simulator | Tightly coupled with the environment to ensure consistent behavior |
| Fine-grained error analysis | Separates errors from reasoning vs. communication/coordination |
| Coordination metrics | Measuring agent-user collaboration |
| Enhanced complexity | More sophisticated interactions |
Performance drops significantly in τ²-bench compared to τ-bench. GPT-4.1, which achieves 74% pass^1 in retail and 56% in airline, drops to 34% in the telecom domain.[6] This gap highlights the difficulty of guiding users through actions rather than performing all actions autonomously.
τ³-bench
τ³-bench (2026) is the current version of the benchmark, maintained in the sierra-research/tau2-bench repository. Besides the airline and retail task fixes described above, it adds a banking domain in which agents retrieve and reason over a knowledge base of about 700 documents (τ-knowledge) and a real-time voice evaluation modality (τ-voice), both introduced in March 2026.[2][7][8]
MedAgentBench
Inspired directly by τ-bench, MedAgentBench adapts the framework to the medical domain. It features:
- Electronic Medical Record (EMR) environment
- FHIR API integration
- Physician-written scenarios
- Clinical task evaluation
The authors cited τ-bench as effective for testing general agent capabilities while noting the absence of a standardized medical agent benchmark, prompting creation of the domain-specific variant.
LegalAgentBench
Another domain-specific adaptation that emerged for evaluating AI agents in legal applications, inspired by τ-bench's framework for policy-compliant agent evaluation.
Limitations and Criticisms
Methodological Limitations
| Limitation | Description | Impact |
|---|---|---|
| Limited domains | Only two domains (retail and airline) in the original benchmark | Raises questions about generalization to other settings |
| Simulated users | LLM-based users may not capture the full range of human behavior | May underestimate difficulty with real, unpredictable users |
| English only | No multilingual support | Limits applicability to non-English customer service settings |
| Static task set | Fixed set of 165 tasks | Risk of overfitting as models are evaluated repeatedly |
| Binary scoring | No partial credit for partially correct solutions | May not capture agents that get "almost right" |
| Text only | No visual, voice, or document-based interactions in the original benchmark (τ³-bench later added voice and a document knowledge base) | Misses multimodal aspects of real customer service |
Evaluation Concerns
- Evaluation Brittleness: Binary success/failure may miss partial success.
- User model bias: LLM-simulated users may behave more predictably and cooperatively than real humans, potentially inflating scores.
- Policy simplification: The policy documents in τ-bench, while non-trivial, are simpler than the policy manuals used by actual airlines and retailers, which can run to hundreds of pages.
- Sim2Real gap: Research on the gap between simulated and real user interactions has raised questions about how well τ-bench performance predicts real-world agent performance.
- Self-reported scores: Many leaderboard entries are self-reported by model providers rather than independently verified, creating potential for selection bias.
- Benchmark saturation: In the airline domain, 48 of 50 tasks have been solved by at least one agent, suggesting the individual tasks may be approaching saturation even though no single agent solves them all.[9]
- Limited Error Types: May not cover all failure modes.
Future Directions
Planned and Anticipated Improvements
- Domain expansion: Healthcare, finance, and education domains would test generalization across different policy structures and tool sets; τ³-bench added a banking domain in March 2026.[7]
- Multimodal support: Adding images, documents, and voice interactions would better reflect real customer service environments.
- Human evaluation studies: Replacing LLM-simulated users with real humans would address the sim2real gap concern.
- Dynamic task generation: Procedurally generating new tasks would prevent overfitting to the fixed task set.
- Fine-grained metrics: Partial credit scoring could better differentiate agents that nearly solve a task from those that fail completely.
- Multilingual evaluation: Expanding beyond English would test agents in the global customer service settings where they are increasingly deployed; Sierra's τ-i18n extended τ-voice to six languages in October 2026.[7]
Open Research Questions
- Agent architecture design: What architectures best handle long-horizon, policy-constrained, multi-turn interactions, and can τ-bench-optimized architectures be developed?
- Training on τ-bench: Can agents be trained or fine-tuned specifically on τ-bench-style interactions to improve reliability?
- User modeling: How can user simulation be made more realistic without requiring human participants for every evaluation?
- Policy learning: Can agents learn to extract and follow policies from lengthy documents more reliably, including automatic policy extraction and compliance?
- Coordination in dual-control settings: How should agents guide users through actions in shared environments (as explored in τ²-bench)?
How does τ-bench differ from other agent benchmarks?
| Benchmark | Focus | Key Difference from τ-bench |
|---|---|---|
| SWE-bench | Software engineering tasks | Single-turn; no user interaction |
| AgentBench | Multi-environment agent evaluation | Tests multiple environments but single-turn interactions |
| WebArena | Web navigation and interaction | Focuses on browser-based tasks rather than conversational customer service |
| WebShop | E-commerce navigation | Earlier work by the same lead author; simpler single-turn shopping tasks |
| ALFWorld | Embodied agent tasks | Focuses on text-based embodied environments rather than customer service |
| InterCode | Interactive coding benchmark | Code-focused rather than customer service conversations |
| GAIA | General AI assistant tasks | Broader scope but less focus on multi-turn tool use and policy compliance |
| BFCL | Function calling accuracy | Tests tool use in isolation rather than within multi-turn conversations |
| τ²-bench | Dual-control conversational agents | Extends τ-bench with a telecom domain where both agent and user have tools |
| MT-Bench | Multi-turn conversation quality | Tests conversational ability but not tool use or policy compliance |
Continue reading
- ReAct (prompting)ReAct (short for Reasoning and Acting) is a prompting paradigm for large language models that interleaves verbal reasoning traces ("Thoughts") with task-specific actions executed against an external…Mentioned 8 times above
- Function callingFunction calling is a capability of large language models (LLMs) that lets a model decide, during generation, to invoke an external function or API and emit the function name plus its arguments as structured…Mentioned 8 times above
- Agent evaluationAgent evaluation is the systematic measurement of how well AI agents (LLM-based systems that plan and act over multiple steps using tools) perform on real-world tasks, using benchmarks, metrics, and testing…Mentioned 7 times above
- SWE-benchSWE-bench is an execution-based benchmark for evaluating whether a language-model system can resolve real software issues.Mentioned 4 times above
- AI AgentsAn AI agent is a software system that selects and performs actions in an environment in pursuit of an objective.Mentioned 3 times above
- AgentBenchAgentBench is a multi-dimensional benchmark for evaluating large language models (LLMs) as autonomous agents across eight distinct interactive environmentsMentioned 3 times above
More from See also
- Tool Use in LLMs
- Large Language Model
- Multi-turn Dialogue Systems
- Conversational Models
- Human-AI Interaction
More to read
Topics:AI Benchmarks
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32 ^33Yao, S., Shinn, N., Razavi, P., & Narasimhan, K. (2024). "τ-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains." arXiv:2406.12045. Retrieved from arxiv.org/...2406.12045
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Sierra Research. (2024). "Tau-bench: Code and Data." GitHub. Retrieved from github.com/...tau-bench
- ^1 ^2 ^3 ^4 ^5Sierra AI. (2024). "Benchmarking AI agents for the real-world." Sierra Blog. Retrieved from sierra.ai/...benchmarking-ai-agents
- ^Sierra AI. "τ-bench: Shaping the development and evaluation of agents." Sierra Blog. Retrieved from sierra.ai/...shaping-development-evaluation-agents
- Sierra. (2025). "τ²-bench: evaluating conversational agents in a dual-control environment." Retrieved from sierra.ai/...tau-squared-bench
- ^1 ^2 ^3Barres, V., Dong, H., Ray, S., Si, X., & Narasimhan, K. (2025). "τ²-Bench: Evaluating Conversational Agents in a Dual-Control Environment." arXiv:2506.07982. Retrieved from arxiv.org/...2506.07982
- ^1 ^2 ^3 ^4 ^5τ-bench Official Leaderboard. Retrieved from taubench.com
- ^1 ^2 ^3 ^4 ^5 ^6τ³-bench: Fixing Airline + Retail. Retrieved from taubench.com/...tau3-task-fixes
- ^1 ^2 ^3 ^4Princeton HAL: TAU-bench Airline Leaderboard. Retrieved from hal.cs.princeton.edu/taubench_airline
- ^1 ^2 ^3 ^4 ^5 ^6LLM-Stats: TAU-bench Retail Leaderboard. Retrieved from llm-stats.com/...tau-bench-retail
- ^1 ^2 ^3 ^4 ^5LLM-Stats: TAU-bench Airline Leaderboard. Retrieved from llm-stats.com/...tau-bench-airline
- ^1 ^2 ^3ICLR 2025 Poster: τ-bench. Retrieved from iclr.cc/...28170
- ^1 ^2Anthropic. (2024). "Introducing computer use, a new Claude 3.5 Sonnet." Retrieved from anthropic.com/...3-5-models-and-computer-use
- ^1 ^2OpenAI. (2025). "Introducing gpt-oss." Retrieved from openai.com/...introducing-gpt-oss
- Medium. (2025). "Claude 3.7 Sonnet Unveiled: Reviewing Anthropic's Most Advanced Reasoning Model." Retrieved from medium.com/...dvanced-reasoning-model-772b74331226
- ^Sierra. "Karthik Narasimhan." Sierra author page. Retrieved from sierra.ai/...karthik-narasimhan
- ^1 ^2 ^3Anthropic. (2025). "Claude 3.7 Sonnet and Claude Code." Retrieved from anthropic.com/...claude-3-7-sonnet
- ^1 ^2Anthropic. (2025). "Introducing Claude Sonnet 4.5." Retrieved from anthropic.com/...claude-sonnet-4-5
- ^Yao, S., Shinn, N., Razavi, P., & Narasimhan, K. (2025). "τ-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains." ICLR 2025 camera-ready version, OpenReview. Retrieved from openreview.net/forum
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
19 revisions · v19 · 6,848 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (150 claims, 24 sources fetched); 18 material + 35 minor fixed
Cite this page: AI Wiki. "τ-bench." aiwiki.ai, updated 28 Oct 2026, fact-checked 4 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/tau-bench