

Continuous Batching
Continuous batching is a scheduling technique for large language model (LLM) inference servers that inserts new requests into a running batch at the granularity of individual model iterations rather than waiting for all requests in a batch to complete before accepting new work. Also called iteration-level scheduling or in-flight batching (and occasionally, loosely, dynamic batching, a term that more often means request-level batching), the technique was formally described and evaluated in the paper "Orca: A Distributed Serving System for Transformer-Based Generative Models" by Yu et al., presented at USENIX OSDI 2022, which reported a "36.9x throughput improvement at the same level of latency" over NVIDIA FasterTransformer on a GPT-3 175B workload [1]. Systems that implement continuous batching, including vLLM, HuggingFace Text Generation Inference (TGI), NVIDIA TensorRT-LLM, and SGLang, have reported throughput gains over request-level baselines of up to 36.9x (Orca versus FasterTransformer) and up to 24x (vLLM versus HuggingFace Transformers), though such figures also reflect memory-management and kernel optimizations [1][3].
The Orca authors define the core idea as "iteration-level scheduling, a new scheduling mechanism that schedules execution at the granularity of iteration (instead of request)" [1]. In practice this means completed requests are released the instant they finish, and waiting requests are admitted to fill the freed slots, so the GPU batch stays close to full regardless of how much each request generates. As of 2026, continuous batching is the default scheduling model in every major open-source LLM serving stack.
What problem does static batching cause?
Transformer-based autoregressive language models generate output one token at a time. In order to produce a response of $N$ tokens, a model must execute $N$ sequential forward passes (ignoring speculative decoding), each of which takes the previously generated tokens as context. This sequential dependency means that the time to complete a request is directly proportional to the number of output tokens it generates.
The fundamental challenge for inference serving is that different requests produce different numbers of output tokens. A request asking for a short factual answer might finish in 20 tokens. A request asking the model to write a 500-word essay might require 600 or more tokens. An instruction-following request might involve a chain-of-thought that is unpredictable in length. The output length of any individual request cannot be known in advance; it depends on what the model generates, which in turn depends on the specific input and the model's learned behavior.
GPUs perform best when many operations are fused into a single large matrix multiplication. Serving a single request at a time is GPU-inefficient: the batch dimension of all matrix multiplications is 1, leaving most of the arithmetic units idle. Early inference systems addressed this by grouping multiple requests into a batch and processing them together in a single forward pass. When requests in the same batch each produce one token per step, a single GPU kernel handles all of them simultaneously, substantially improving hardware utilization.
Static batching
The simplest batching strategy, called static batching or request-level batching, waits until it has collected a full batch of requests and then runs that batch through the model until all requests in the batch complete. The batch is treated as an atomic unit: a new request cannot join the batch while it is running, and the batch does not release completed requests until every member has finished generating.
This approach has a severe efficiency problem rooted in the variable-length nature of language model outputs. In any realistic workload, some requests finish much earlier than others. If a batch of 16 requests has one request that needs 500 tokens and all others need 20 tokens, the 15 short requests finish in 20 iterations but sit idle occupying batch slots for the remaining 480 iterations while the long request completes. GPU memory allocated for the short requests' KV caches is held hostage. New requests waiting in the queue cannot be admitted even though 15 out of 16 batch slots are sitting idle.
The Orca paper [1] identified this inflexibility as the reason existing serving systems performed poorly on multi-iteration generation: "requests that have finished earlier than other requests in a batch cannot return to the client, while newly arrived requests have to wait until the current batch completely finishes." Output length distributions in chat workloads are typically skewed: many requests are short, but a long tail of requests produces very long outputs. Static batching, which must wait for the longest-running request in the batch before admitting new work, is especially harmed by this skew.
GPU underutilization measurement
Because no public request trace for generative language models existed, the Orca authors evaluated their system on a synthesized trace: input lengths drawn uniformly from 32 to 512 tokens, maximum generation lengths drawn uniformly from 1 to 128 tokens, and Poisson-distributed arrival times [1]. Under request-level scheduling, every request in a batch occupies its slot until the longest member finishes, so the cost of the idle slots grows with the spread of output lengths in the batch.
What did the Orca paper (OSDI 2022) introduce?
The paper "Orca: A Distributed Serving System for Transformer-Based Generative Models" by Gyeong-In Yu, Joo Seong Jeong, Geon-Woo Kim, Soojeong Kim, and Byung-Gon Chun was published at USENIX OSDI (Operating Systems Design and Implementation) 2022 [1]. OSDI is one of the top venues in systems research, with acceptance rates typically below 20%. The work came from Seoul National University and FriendliAI, which supported the research and employed several of its authors [1].
Orca's central contribution was the observation that the natural scheduling granularity for autoregressive decoding is the iteration, not the request. At every iteration, the model executes one forward pass and produces one new token for each sequence in the batch. From the hardware's perspective, what matters is that the batch dimension is large. Whether two sequences in that batch started at different times is irrelevant to the GPU; it sees the same matrix multiplications either way.
The authors proposed iteration-level scheduling, which the paper describes as "a new scheduling mechanism that schedules execution at the granularity of iteration (instead of request)" [1]: after every forward pass, the scheduler checks whether any sequences in the batch have completed (i.e., generated an end-of-sequence token or reached the maximum length). Completed sequences are immediately removed from the batch, freeing their slots. New requests waiting in the queue are immediately inserted to fill those slots, up to the maximum batch size the GPU can accommodate. The batch composition changes at every iteration, but the batch size remains at or near maximum throughout the run.
The Orca paper also introduced selective batching, described as a mechanism "which applies batching only to a selected set of operations," recognizing that not all operations in a transformer forward pass support variable-length inputs equally [1]. Attention operations are the most complex because the attention computation for each sequence depends on that sequence's own KV cache, which grows to different lengths for different sequences. The paper proposed handling this by treating the self-attention layers differently from the feed-forward layers: feed-forward layers can be naively batched across all sequences simultaneously (since they operate per-token), while attention layers require more careful handling of variable-length KV sequences. In the paper's terms, selective batching splits the batch and processes each request individually for the attention operation while applying batching to the other operations of the transformer block [1].
Evaluation in the Orca paper showed 36.9x higher throughput at the same level of latency compared to a static batching baseline (NVIDIA FasterTransformer) on a GPT-3 175B workload [1]. Concretely, to match a median normalized latency of 190 ms on the 175B model, FasterTransformer sustained 0.185 requests per second while Orca sustained 6.81 requests per second, a 36.9x gain [1]. These numbers apply to workloads with high request arrival rates and variable output lengths; workloads with uniform short outputs see more modest gains. The paper evaluated synthesized GPT-3 configurations scaling from 13B up to 341B parameters [1].
How does continuous batching work?
Iteration-level scheduling
The core loop of a continuous batching inference server operates as follows:
- Maintain a queue of waiting requests.
- At each iteration, assemble a batch from currently running sequences plus any new requests that fit within the available compute and memory budget.
- Execute one forward pass of the model over the entire batch, producing one new token per sequence.
- For each sequence in the batch, append the new token to its generated output.
- Check each sequence for completion: if a sequence has generated an end-of-sequence token or reached its maximum output length, mark it as finished.
- Remove completed sequences from the batch and release their resources.
- Admit new requests from the queue to fill vacated slots.
- Repeat from step 2.
The key difference from static batching is steps 5 through 7. In static batching, these steps only happen after all sequences in the batch have completed. In continuous batching, they happen at every single iteration.
Because the batch is modified between iterations, each iteration may process a slightly different set of sequences. The sequences from the previous iteration that have not yet completed carry forward their KV caches (already computed and cached), so only the new token needs to be processed for continuing sequences. New sequences joining the batch at step 7 must have their entire input prompt processed (the prefill phase) before they can join the main decoding loop.
Prefill and decode phases
Autoregressive generation has two distinct phases with different computational profiles:
Prefill (prompt processing): The model ingests the entire input prompt in a single forward pass, computing KV cache entries for every token in the prompt simultaneously. This phase is compute-bound: it involves large matrix multiplications where the sequence dimension equals the prompt length. A long prompt of 2,048 tokens produces 2,048 KV entries per layer in a single iteration. Prefill is fast per token but requires a lot of compute in aggregate.
Decode (token generation): After prefill, the model generates one new token per iteration. Each decoding iteration involves a forward pass over just the single new token, but the attention computation must attend over the full KV cache accumulated so far. The decoding phase is memory-bandwidth-bound rather than compute-bound: the bottleneck is loading KV cache data from GPU HBM.
Continuous batching must manage both phases simultaneously. New requests entering the batch need to run prefill; existing requests already in the decode phase need to run decode. In simple implementations, prefill and decode are handled in the same forward pass: the prefill request's tokens and the decode requests' single new tokens are concatenated and processed together. This works but can cause conflicts: a large prefill can dominate computation in an iteration and increase the time-to-first-token for other decode requests that happen to be in the same batch.
Chunked prefill
Chunked prefill is an extension to continuous batching that addresses the prefill-decode interference problem. Instead of processing an entire prompt in one iteration, chunked prefill breaks the prompt into fixed-size chunks (e.g., 512 or 1,024 tokens per chunk) and processes one chunk per iteration [4]. This keeps the compute load of any single iteration bounded, preventing long prefills from stalling the decode phase.
With chunked prefill, new requests enter the batch in a partially computed state, contributing only a chunk's worth of prefill compute per iteration until their prompt is fully processed, at which point they transition to the decode phase. The scheduler interleaves prefill chunks and decode tokens within each iteration, maintaining more consistent latency for already-running requests while still admitting new requests efficiently [9].
vLLM versions from 0.4 onward implement chunked prefill as a configurable option. The chunk size is a tunable parameter that trades off prefill throughput (larger chunks finish faster) against time-to-first-token stability (smaller chunks are less disruptive to concurrent decode requests).
Memory management for continuous batching
Continuous batching imposes specific requirements on memory management. Because the number of tokens each request will generate is unknown, the serving system cannot pre-allocate a fixed block of GPU memory per request. Allocating the maximum possible context length for every request would be prohibitively wasteful.
In early implementations of continuous batching, including the Orca paper's prototype, memory management was conservative: Orca's scheduler reserved KV cache slots for each request's maximum token count (max_tokens) in advance and admitted a new request only if that reservation fit in the memory allotted to the KV cache [1]. This approach was conservative and left GPU memory underutilized.
The introduction of PagedAttention by Kwon et al. (SOSP 2023) solved this problem by applying virtual memory concepts to KV cache allocation [2]. PagedAttention divides GPU memory into fixed-size physical blocks and maintains a per-sequence logical-to-physical block mapping. KV cache blocks are allocated on demand as tokens are generated, and released immediately when a sequence completes. This allows the maximum possible number of sequences to fit in GPU memory at any given time, complementing continuous batching's goal of keeping the batch full. The vLLM team reported that "existing systems waste 60% - 80% of memory due to fragmentation and over-reservation," whereas PagedAttention's paged allocation results in "near-optimal memory usage, with a mere waste of under 4%" [3].
The combination of continuous batching (for iteration-level scheduling) and PagedAttention (for efficient memory management) is what powers the high throughput of modern serving systems like vLLM. The two techniques are orthogonal and complementary: continuous batching determines when requests enter and leave the batch, while PagedAttention determines how memory is allocated and shared among the requests currently in the batch.
How does continuous batching differ from static and dynamic batching?
The terms static batching, dynamic batching, and continuous batching are sometimes used interchangeably or inconsistently in the literature. The following table clarifies the distinctions as used in most systems research:
| Property | Static batching | Dynamic batching | Continuous batching |
|---|---|---|---|
| Scheduling granularity | Request (entire batch runs until all complete) | Request with variable wait window | Iteration (every forward pass) |
| New request admission | Only between batches | Only between batches, but batches assembled dynamically | At every iteration |
| Handling of variable output lengths | Batch waits for longest request | Batch waits for longest request | Completed requests immediately released |
| GPU slot waste | High (proportional to length skew) | Reduced vs static (larger batches) | Minimal |
| Implementation complexity | Low | Low to moderate | Moderate to high |
| Reported throughput improvement | Baseline | Workload-dependent | Up to 24x (vLLM vs HF Transformers) to 36.9x (Orca vs FasterTransformer) [1][3] |
| Latency for short requests | Can be delayed by long co-batch members | Can be delayed by long co-batch members | Nearly optimal: released as soon as done |
Dynamic batching, as implemented in early serving frameworks like NVIDIA Triton Inference Server and TensorFlow Serving, refers to assembling a batch dynamically as requests arrive within a configurable time window or until a target batch size is reached. The key distinction from continuous batching is that dynamic batching still treats the assembled batch as an atomic unit once execution begins: no new requests are admitted until the entire batch finishes. Dynamic batching improves throughput over single-request serving by achieving larger matrix multiplications, but it still suffers from the idle-slot problem for long-tailed output distributions.
Continuous batching's defining characteristic is that the batch composition can change between every pair of consecutive model iterations. This is what enables close to 100% batch slot utilization regardless of output length variance.
How large are the performance gains?
The throughput improvements from continuous batching relative to static batching depend heavily on the workload characteristics, particularly the variance in output lengths. The following table summarizes reported gains from key papers and systems:
| Source | Baseline | Workload | Improvement |
|---|---|---|---|
| Orca paper (Yu et al., OSDI 2022) | FasterTransformer (request-level) | GPT-3 175B, variable-length outputs | 36.9x throughput [1] |
| vLLM blog post (Kwon et al., 2023) | HuggingFace Transformers | LLaMA-7B (A10G) and LLaMA-13B (A100), ShareGPT lengths | up to 24x throughput [3] |
| vLLM blog post (Kwon et al., 2023) | HuggingFace TGI | LLaMA-7B (A10G) and LLaMA-13B (A100), ShareGPT lengths | up to 3.5x throughput [3] |
| NVIDIA TensorRT-LLM launch blog (2023) | TensorRT-LLM without in-flight batching | Real-world LLM requests, H100 | At least 2x throughput (in-flight batching plus kernel optimizations) [23] |
The vLLM team summarized its headline result as: vLLM "achieves up to 24x higher throughput compared to HF and up to 3.5x higher throughput than TGI" [3]. It is important to note that these figures are not purely from continuous batching alone. Modern systems combine continuous batching with PagedAttention, optimized attention kernels (Flash Attention, FlashInfer), quantization, and hardware-specific tuning. Isolating the contribution of continuous batching alone is difficult because it is almost always deployed together with these other optimizations.
The Orca paper's 36.9x figure is one of the largest reported and reflects a comparison against an unoptimized static batching baseline without any of the memory management improvements that came later. The PagedAttention paper's comparison with its Orca reimplementation (vLLM sustained 1.7x to 2.7x higher request rates than an oracle version of Orca, and 2.7x to 8x higher than a max-reservation version, on ShareGPT) isolates the additional gain from PagedAttention's memory efficiency on top of iteration-level scheduling [2]. The PagedAttention paper summarizes this overall effect as a 2x to 4x throughput improvement over the previous state of the art (FasterTransformer and Orca) at the same level of latency [2].
In workloads with uniform output lengths (all requests produce the same number of tokens), continuous batching provides little throughput benefit over static batching because there is no idle-slot problem to solve. The gain is specific to the variable-length case, which describes virtually all production LLM deployments.
Which inference systems use continuous batching?
vLLM
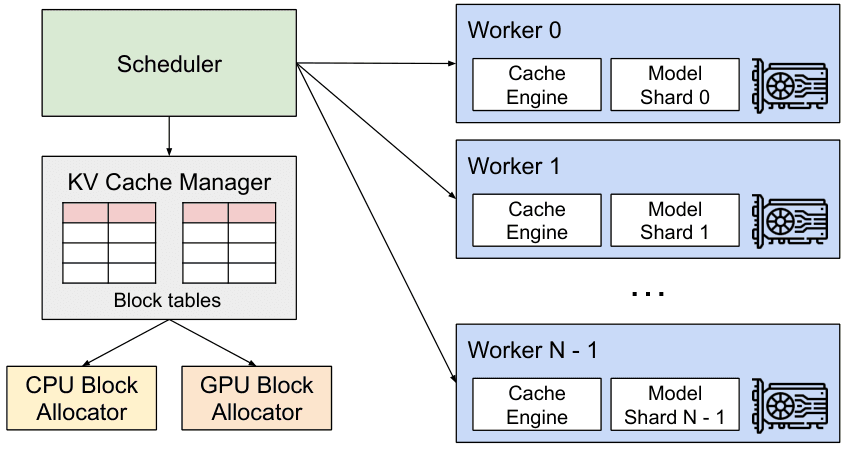
vLLM, developed at UC Berkeley and released in June 2023 [3], is the most widely used open-source LLM serving framework, and it was still shipping releases roughly every two weeks in mid-2026, reaching v0.26.0 on July 27, 2026 and v0.32.0 on October 18, 2026 [22]. It implements continuous batching as its default scheduling strategy, combined with PagedAttention for memory management [2]. vLLM's scheduler maintains a running batch that is updated at every iteration: completed sequences are removed, preempted sequences are recomputed later (the legacy V0 engine could also swap them to CPU memory), and new sequences are admitted from the waiting queue [17].
vLLM's implementation of continuous batching is more sophisticated than the original Orca description in several respects. The scheduler handles sequence groups (multiple parallel completions from one request), supports chunked prefill for controlling time-to-first-token, and integrates with speculative decoding pipelines where accepted tokens advance sequences by multiple positions per iteration. vLLM also supports prefix caching via Automatic Prefix Caching (APC), which allows the prefill of repeated prompt prefixes to be skipped by reusing previously computed KV cache blocks.
The vLLM V1 architecture (alpha released in January 2025) refactored the scheduler to reduce Python overhead in the control path and enable CUDAGraph capture for faster iteration dispatch, while preserving the continuous batching model.
The V1 alpha was released on January 27, 2025, and V1 became the default engine in vLLM v0.8.0 in March 2025 [11][17]. Removal of the legacy V0 engine then followed the schedule set out in the project's deprecation RFC: feature work on V0 was frozen at v0.9.0, deletion of V0 code began with v0.10.0 in July 2025, and v0.11.0, released on October 2, 2025, completed the removal of AsyncLLMEngine, LLMEngine, MQLLMEngine, and every V0 attention backend, leaving V1 as the only engine in the codebase [20][21]. V1 replaces the V0 separation of prefill and decode phases with a single unified scheduler that treats prompt tokens and generated output tokens uniformly, tracking each request with a simple {request_id: num_tokens} token budget so that chunked prefills, prefix caching, and speculative decoding all share one scheduling path [11]. With this design vLLM reported up to 1.7x higher throughput than V0, and its prefix caching causes less than a 1% throughput decrease even at a 0% cache hit rate, allowing it to be enabled by default [11]. In V1 chunked prefill is on by default and preemption under memory pressure uses recomputation rather than KV cache swapping, which the simplified V1 architecture no longer requires [17]. A 2025 engineering write-up describing the V1 internals notes that each engine step runs scheduling, a single forward pass that flattens the batch into one sequence, and postprocessing, with captured CUDA graphs replayed at run time to cut kernel-launch overhead [12].
Text Generation Inference (TGI)
HuggingFace's Text Generation Inference server batched requests at the iteration level from its early 2023 releases (its README first called the feature "dynamic batching"), and by May 2023 its router documentation described the scheduler as continuous batching [6]. TGI calls its implementation "continuous batching" explicitly in documentation and uses the same iteration-level scheduling model: requests are added to the running batch as slots become available, and completed requests are released immediately without waiting for batch-mates [6].
TGI targets tight integration with HuggingFace Hub model weights and the Transformers library ecosystem. It supports a range of model architectures and provides a REST API compatible with the OpenAI API format. Since version 0.9 (July 2023), TGI's flash-attention model implementations have used PagedAttention to manage KV cache memory [6]. In TGI's architecture this scheduling is coordinated by a high-performance Rust router that handles request validation, queuing, and batching before forwarding work to the inference server over gRPC [6]. The router intertwines prefill and decode steps and filters away finished requests rather than running static batches [6].
TGI's router documentation frames the benefit qualitatively: "a 2x latency slowdown for 10x more users on the same hardware is an acceptable tradeoff" [6]. Hugging Face used TGI in production for Hugging Chat, its Inference API and Inference Endpoints, but the project has since entered maintenance mode (accepting only minor bug fixes and documentation changes) and its GitHub repository was archived on March 21, 2026; Hugging Face now recommends vLLM and SGLang, along with local engines such as llama.cpp and MLX [6].
NVIDIA TensorRT-LLM
NVIDIA's TensorRT-LLM library provides highly optimized inference on NVIDIA hardware (particularly A100, H100, and H200 GPUs) and implements iteration-level scheduling under the name "in-flight batching" in its documentation [7]. NVIDIA describes the mechanism as follows: "rather than waiting for the whole batch to finish before moving on to the next set of requests, the TensorRT-LLM runtime immediately evicts finished sequences from the batch. It then begins executing new requests while other requests are still in flight" [23]. TensorRT-LLM's executor API (added in TensorRT-LLM v0.9, 2024) provides fine-grained control over in-flight batching behavior, including configurable maximum batch sizes, KV cache size limits, and chunked context (equivalent to chunked prefill) [7].
TensorRT-LLM combines in-flight batching with NVIDIA-specific optimizations: FP8 quantization on H100 Tensor Cores, INT8 KV cache quantization, XQA kernels optimized for multi-query and grouped-query attention in the generation phase, and, until the TensorRT engine backend was removed in the 1.3 release line, TensorRT's engine compilation pipeline that fused operations at the graph level [14]. The combination of in-flight batching and these hardware optimizations produces state-of-the-art throughput on NVIDIA hardware.
NVIDIA also provides a higher-level serving framework, Triton Inference Server, which can host TensorRT-LLM backends and add request queuing, load balancing, and multi-model management on top of TensorRT-LLM's in-flight batching.
With the TensorRT-LLM 1.0 release on September 24, 2025, NVIDIA promoted a new PyTorch-native backend to be the default LLM backend and changed the default backend of the trtllm-serve command to PyTorch [14]. The PyTorch backend's PyExecutor runs scheduling, model forward steps, and KV cache management in Python without an ahead-of-time engine-compilation step [27]. Release candidates for version 1.3 from July 2026 onward removed the TensorRT engine backend entirely, leaving PyTorch as the sole execution backend [14].
SGLang
SGLang, developed by researchers at Stanford, UC Berkeley, and other institutions, implements continuous batching as part of its runtime and extends it with RadixAttention, which uses a radix tree (trie) data structure to manage the KV cache [8]. RadixAttention enables automatic prefix reuse across all requests without requiring explicit configuration: any two requests sharing a common prefix will automatically share the corresponding KV cache blocks [8]. This allows continuous batching to coexist with aggressive prefix sharing in workloads involving repeated system prompts, few-shot examples, or multi-turn conversation history.
SGLang's runtime also implements chunked prefill [15] and batches requests across multiple concurrent programs (structured generation pipelines) [8]. The first version of the SGLang paper reported speedups of up to 5x on common LLM tasks, and the revised version reports up to 6.4x higher throughput than state-of-the-art inference systems across agent, reasoning, few-shot, JSON-decoding, RAG and multi-turn chat workloads [8].
SGLang joined the PyTorch ecosystem on March 19, 2025, and is hosted by LMSYS, a non-profit open-source organization [25]. By early 2025 its developers reported wide industry use: xAI used it to serve Grok 3 and Microsoft Azure used it to serve DeepSeek R1 on AMD GPUs, and its supporting institutions included AMD, NVIDIA, and xAI [15]. Using prefill-decode disaggregation together with large-scale expert parallelism on 96 NVIDIA H100 GPUs, an SGLang DeepSeek deployment reported about 52,300 input tokens per second and 22,300 output tokens per second per node for 2,000-token inputs, which the authors described as the first open-source result approaching the throughput in DeepSeek's own report at that scale [24].
Triton Inference Server
NVIDIA's Triton Inference Server added a "dynamic batching" feature long before the Orca paper, but this earlier dynamic batching was request-level, not iteration-level. Triton assembled batches from queued requests and dispatched them atomically. After the Orca paper and the vLLM/TGI releases demonstrated the superiority of iteration-level scheduling, NVIDIA added in-flight batching support to Triton when using TensorRT-LLM backends [7].
Ollama
Ollama, a lightweight local LLM serving tool, began adding support for parallel request handling in version 0.1.33 (2024). Ollama's parallel inference uses a simpler batching model than production systems and does not implement full iteration-level scheduling for all backend configurations, but it demonstrates the adoption of continuous batching ideas even in consumer-facing tools. The degree of concurrency is controlled by the OLLAMA_NUM_PARALLEL setting, which defaults to 1 in current releases, with additional requests queued in first-in, first-out order up to OLLAMA_MAX_QUEUE [18].
LMDeploy
Shanghai AI Laboratory's LMDeploy framework implements continuous batching in its TurboMind engine, which targets deployment of InternLM and other models. TurboMind uses iteration-level scheduling combined with a paged KV cache. LMDeploy reports throughput competitive with vLLM on supported model architectures. LMDeploy documents this feature as "persistent batch (a.k.a. continuous batching)" alongside a blocked KV cache and dynamic split-and-fuse, and reports up to 1.8x higher request throughput than vLLM on supported models [19].
What changed in 2025-2026?
By 2025 and 2026, continuous batching had become a settled baseline that every major serving stack assumes, and the frontier of systems work shifted toward coordinating it across many GPUs and separating the prefill and decode phases. NVIDIA announced Dynamo at GTC 2025 (March 18, 2025) as an open-source, datacenter-scale distributed inference framework and the successor to Triton Inference Server [13]. Dynamo is positioned as an orchestration layer above existing inference engines rather than a replacement for them: it can drive vLLM, SGLang, and TensorRT-LLM workers, adding disaggregated prefill and decode, a KV-cache-aware "smart router" that uses a radix tree to steer requests toward GPUs holding relevant cache, a GPU and SLO planner that scales capacity to meet service-level objectives, a distributed KV cache manager that offloads cold cache to CPU memory or storage, and the NIXL low-latency transfer library [13]. NVIDIA reported that Dynamo can serve up to 30x more requests when running DeepSeek-R1 671B on a GB200 NVL72 Blackwell system [13].
The disaggregation approach pioneered by DistServe and Mooncake also moved into mainstream open-source engines. Moonshot AI's Mooncake, the KVCache-centric disaggregated architecture behind the Kimi service, was published in 2024 (arXiv 2407.00079) and reported up to a 525% throughput increase in long-context simulated scenarios while still meeting latency SLOs; it received a Best Paper Award at USENIX FAST 2025, and its transfer engine was integrated into vLLM in December 2024 for disaggregated prefilling and KV cache transfer [16]. As of 2026, vLLM ships an experimental disaggregated-prefilling path that runs separate prefill and decode instances connected by a pluggable KV connector (with backends such as NIXL, LMCache, and Mooncake), reflecting how prefill-decode disaggregation has become a standard production option layered on top of per-pool continuous batching [26].
How does continuous batching combine with PagedAttention?
Continuous batching and PagedAttention address different aspects of the same throughput problem and are highly complementary.
Continuous batching solves the scheduling problem: how to keep the batch as full as possible given that requests complete at different times. Without continuous batching, even a system with perfect memory management would suffer from idle batch slots as short requests complete and wait for long ones.
PagedAttention solves the memory management problem: how to allocate GPU memory for KV caches without fragmentation or over-reservation [2]. Without PagedAttention, even a system with iteration-level scheduling would be constrained by how many requests can fit in GPU memory, because each request would need to reserve memory for its worst-case output length.
Together, they create a two-layer optimization:
- PagedAttention maximizes the number of sequences that can reside in GPU memory simultaneously, by eliminating wasted space from pre-allocation and fragmentation.
- Continuous batching maximizes GPU compute utilization by ensuring that as many of those in-memory sequences as possible are actively generating tokens at every iteration.
The vLLM system demonstrated this synergy empirically. Compared to Orca (iteration-level scheduling without PagedAttention), vLLM (iteration-level scheduling with PagedAttention) sustains 1.7x to 2.7x higher request rates than Orca (Oracle) and 2.7x to 8x higher than Orca (Max) at similar latency on ShareGPT [2]. The additional gain comes from PagedAttention's ability to pack more concurrent sequences into the same amount of GPU memory, giving the continuous batching scheduler more sequences to work with.
Chunked prefill extensions
As mentioned above, chunked prefill is a natural extension of continuous batching that addresses the interference between prefill (processing long input prompts) and decode (generating tokens one by one). Without chunked prefill, a request with a very long prompt would monopolize the GPU for an entire iteration, increasing the latency of all concurrently decoding requests by the duration of that prefill.
Chunked prefill was proposed in the SARATHI paper (Agrawal et al., 2023, arXiv 2308.16369), refined in its follow-up Sarathi-Serve [9], and subsequently implemented in vLLM, SGLang, and TensorRT-LLM [4]. The core idea is to divide the prefill phase into chunks of at most $C$ tokens (the chunk size) and process one chunk per iteration alongside the normal decode tokens [4]. This caps the per-iteration overhead from any single prefill at $C$ tokens, maintaining more predictable iteration latency.
The full Sarathi-Serve evaluation reports up to 2.6x higher serving capacity for Mistral-7B on a single A100, 3.7x for Yi-34B on two A100 GPUs, and up to 5.6x for Falcon-180B served with pipeline parallelism, all relative to vLLM, by adding new requests to a batch without pausing ongoing decodes (which the authors call stall-free batching) [9].
Setting the chunk size $C$ involves a tradeoff:
- Larger $C$ means prefill completes faster (fewer iterations needed to process a long prompt), improving TTFT for the incoming request.
- Smaller $C$ means less per-iteration overhead from prefill, improving decode latency stability for concurrently running requests.
In practice, chunk sizes of 512 to 2,048 tokens are commonly used. vLLM exposes this as the max_num_batched_tokens parameter.
Prefill-decode disaggregation
A more aggressive architectural response to the prefill-decode interference problem is prefill-decode disaggregation, sometimes called disaggregated serving. In this approach, dedicated prefill machines (or GPU pools) handle only the prompt processing phase, and completed KV caches are transferred over a high-bandwidth interconnect (InfiniBand, NVLink) to dedicated decode machines that handle token generation. Continuous batching applies within each pool independently.
Disaggregated serving eliminates the fundamental tension between prefill and decode by running them on entirely separate hardware, but at the cost of added system complexity and the latency and bandwidth cost of KV cache transfer. Projects including DistServe (Zhong et al., 2024) [5], Mooncake (Qin et al., 2024, arXiv 2407.00079) [16], and Splitwise (Patel et al., 2024) [10] have demonstrated disaggregated serving at scale.
Interaction with speculative decoding
Speculative Decoding is a technique that uses a smaller, faster draft model to propose multiple candidate tokens per step, which are then verified in parallel by the larger target model. When the verification accepts $k$ tokens in a single iteration, a sequence advances by $k$ token positions instead of one. This directly interacts with continuous batching in two ways.
First, sequences that accept multiple speculative tokens in one iteration effectively "sprint" ahead of sequences using standard decoding. This means different sequences in the same continuous batch can be at very different positions in their generation, making KV cache management more complex.
Second, speculative tokens that are rejected must be rolled back: the sequence's position and KV cache must be reset to the last accepted token. In a PagedAttention-based system, this means releasing blocks allocated for rejected positions. The implementation must handle this efficiently to avoid overhead that negates speculative decoding's gains.
vLLM's speculative decoding implementation (added in 2024) maintains compatibility with continuous batching by handling acceptance and rejection at the block manager level, treating rejected speculative tokens as if the sequence had simply not generated them. The scheduler continues to operate at the iteration level regardless of whether speculation is active for individual sequences.
What are the limitations of continuous batching?
Prefill latency spikes
Without chunked prefill, a single large prefill can spike iteration time substantially. If a request with a 4,096-token prompt enters the running batch, the iteration that processes its prefill can take many times as long as a standard decode iteration, because the whole prompt is processed in one compute-bound forward pass. All other requests in the batch experience a corresponding latency spike. This is the primary motivation for chunked prefill.
Head-of-line blocking in memory pressure
When GPU memory is nearly full, the scheduler may be forced to pause admission of new requests even though some batch slots are technically available. This creates a form of head-of-line blocking: the front of the request queue cannot be admitted even if the batch has room, because there is not enough free memory for its KV cache. The scheduler must balance admission control against memory pressure, sometimes preempting running sequences to make room. Preemption, whether by recomputation (as in vLLM V1) or by swapping KV cache to CPU memory (as in older systems), adds latency for the preempted request.
Difficulty with very long sequences
Requests with extremely long context (100K tokens or more) are challenging for continuous batching systems. A single very long sequence consumes enormous amounts of KV cache memory, limiting how many other sequences can run concurrently. The throughput benefit of continuous batching is reduced when most of the batch budget is consumed by a few very long sequences.
Context-length extension techniques, including ring attention, sequence parallelism, and KV cache compression methods, address this at the model architecture level rather than the scheduling level.
Tensor parallelism coordination
Large models deployed with tensor parallelism (splitting the model's weight matrices across multiple GPUs) require all GPUs to participate in every forward pass. This means the continuous batching scheduler must coordinate across all tensor-parallel ranks simultaneously: every rank must agree on which sequences are in the batch at each iteration. This is straightforward in synchronous setups but adds coordination overhead.
Pipeline parallelism incompatibility
Pipeline parallelism (distributing model layers across GPUs in a pipeline) is more difficult to combine with continuous batching than tensor parallelism. In a pipeline, different layers of the model are on different GPUs, and data flows from one stage to the next. Changing the batch composition between iterations requires careful synchronization to ensure all pipeline stages are updated consistently. Naive continuous batching with pipeline parallelism can lead to "bubble" inefficiencies at pipeline stage boundaries when batch compositions change. Sarathi-Serve addresses this by forming more uniform batches that reduce the imbalance between iterations, which it reports cuts pipeline bubbles and contributes to its up-to-5.6x serving-capacity gain on Falcon-180B with pipeline parallelism [9]. Research on pipeline-parallel continuous batching (including work on micro-batching and online scheduling within pipeline stages) is an active area.
Token budget interactions
Many deployment scenarios impose per-request or per-user token budgets (maximum input plus output tokens). Enforcing these budgets correctly in a continuous batching system requires the scheduler to track per-sequence token counts and terminate sequences that exceed their budget, which adds bookkeeping complexity. Production serving systems handle this via per-sequence termination conditions in the scheduler.
Relationship to other scheduling techniques
Continuous batching is one of several scheduling innovations for LLM inference. The following table places it in context:
| Technique | What it optimizes | How it interacts with continuous batching |
|---|---|---|
| Continuous batching | Batch slot utilization over time | Foundation; all other techniques build on or extend it |
| PagedAttention | GPU memory fragmentation | Orthogonal; maximizes number of sequences in memory |
| Chunked prefill | Prefill-decode latency interference | Extension to continuous batching scheduler |
| Speculative decoding | Per-sequence tokens-per-second | Requires custom handling in continuous batch scheduler |
| Prefix caching (APC, RadixAttention) | Redundant prefill computation | Implemented within the continuous batching memory layer |
| Disaggregated serving | Prefill-decode resource contention | Alternative architecture that avoids prefill-decode sharing |
| Multi-query / grouped-query attention | Attention KV cache size | Reduces memory pressure, indirectly benefits batching |
Continue reading
- vLLMvLLM is an open-source inference and serving engine for large language models. It is software for running already trained models, either through a Python interface for offline work or through a network server…Mentioned 33 times above
- KV CacheKV cache, short for key-value cache, is transient model state used during Transformer generation.Mentioned 32 times above
- InferenceIn machine learning, inference is the execution of a trained model to produce an output from an input.Mentioned 22 times above
- PagedAttentionPagedAttention is a KV-cache memory management algorithm for serving large language models that applies the virtual-memory paging technique used by operating systems to the GPU, eliminating memory…Mentioned 21 times above
- SGLangSGLang (short for Structured Generation Language) is a high-performance, open-source serving framework for large language models and multimodal models, originally developed at UC Berkeley's Sky Computing Lab…Mentioned 10 times above
- Speculative DecodingSpeculative decoding is a lossless inference acceleration technique for autoregressive transformer models in which a small, fast draft model proposes several future tokens at once and the larger target model…Mentioned 8 times above
More from See also
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16Yu, G., Jeong, J. S., Kim, G., Kim, S., & Chun, B. (2022). Orca: A Distributed Serving System for Transformer-Based Generative Models. *Proceedings of the 16th USENIX Symposium on Operating Systems Design and Implementation (OSDI 2022)*, 521-538. usenix.org/...yu
- ^1 ^2 ^3 ^4 ^5 ^6Kwon, W., Li, Z., Zhuang, S., Sheng, Y., Zheng, L., Yu, C. H., Gonzalez, J. E., Zhang, H., & Stoica, I. (2023). Efficient Memory Management for Large Language Model Serving with PagedAttention. *Proceedings of the 29th ACM Symposium on Operating Systems Principles (SOSP 2023)*. dl.acm.org/...3600006.3613165
- ^1 ^2 ^3 ^4 ^5 ^6 ^7vLLM Team. (2023). vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention. vLLM Blog. blog.vllm.ai/...vllm
- ^1 ^2 ^3Agrawal, A., Panwar, A., Mohan, J., Kwatra, N., Gulavani, B. S., & Ramjee, R. (2023). SARATHI: Efficient LLM Inference by Piggybacking Decodes with Chunked Prefills. arXiv:2308.16369. arxiv.org/...2308.16369
- ^Zhong, Y., Liu, S., Chen, J., Hu, J., Zhu, Y., Liu, X., Jin, X., & Zhang, H. (2024). DistServe: Disaggregating Prefill and Decoding for Goodput-optimized Large Language Model Serving. *USENIX OSDI 2024*. arxiv.org/...2401.09670
- ^1 ^2 ^3 ^4 ^5 ^6 ^7HuggingFace. (2023). Text Generation Inference. github.com/...text-generation-inference
- ^1 ^2 ^3NVIDIA. (2024). The Batch Manager in TensorRT-LLM. TensorRT-LLM documentation (archived November 19, 2024). web.archive.org/...batch-manager
- ^1 ^2 ^3 ^4Zheng, L., Yin, L., Xie, Z., Huang, J., Sun, C., Yu, C. H., Cao, S., Kozyrakis, C., Stoica, I., Gonzalez, J. E., Barrett, C., & Sheng, Y. (2024). SGLang: Efficient Execution of Structured Language Model Programs. arXiv:2312.07104. arxiv.org/...2312.07104
- ^1 ^2 ^3 ^4Agrawal, A., Kedia, N., Panwar, A., Mohan, J., Kwatra, N., Gulavani, B. S., Tumanov, A., & Ramjee, R. (2024). Taming Throughput-Latency Tradeoff in LLM Inference with Sarathi-Serve. *USENIX OSDI 2024*. arxiv.org/...2403.02310
- ^Patel, P., Choukse, E., Zhang, C., Shah, A., Goiri, I., Maleki, S., & Bianchini, R. (2024). Splitwise: Efficient Generative LLM Inference Using Phase Splitting. *ISCA 2024*. arxiv.org/...2311.18677
- ^1 ^2 ^3vLLM Team. (2025). vLLM V1: A Major Upgrade to vLLM's Core Architecture. vLLM Blog, January 27, 2025. blog.vllm.ai/...v1-alpha-release
- ^Gordic, A., & vLLM Team. (2025). Inside vLLM: Anatomy of a High-Throughput LLM Inference System. vLLM Blog, September 5, 2025. blog.vllm.ai/...anatomy-of-vllm
- ^1 ^2 ^3NVIDIA. (2025). NVIDIA Dynamo: A Low-Latency Distributed Inference Framework for Scaling Reasoning AI Models. NVIDIA Technical Blog, March 18, 2025. developer.nvidia.com/...caling-reasoning-ai-models
- ^1 ^2 ^3NVIDIA. (2025). TensorRT-LLM Release Notes (v1.0). nvidia.github.io/...release-notes
- ^1 ^2SGLang Team / PyTorch Foundation. (2025). SGLang Joins PyTorch Ecosystem: Efficient LLM Serving Engine. PyTorch Blog, March 19, 2025. pytorch.org/...sglang-joins-pytorch
- ^1 ^2Qin, R., Li, Z., He, W., Zhang, M., Wu, Y., Zheng, W., & Xu, X. (2024). Mooncake: A KVCache-centric Disaggregated Architecture for LLM Serving. arXiv:2407.00079. arxiv.org/...2407.00079
- ^1 ^2 ^3vLLM Team. (2025). vLLM V1 User Guide. vLLM Documentation. docs.vllm.ai/...v1_guide
- ^Ollama. (2024). FAQ: Handling Concurrent Requests (OLLAMA_NUM_PARALLEL, OLLAMA_MAX_QUEUE). docs.ollama.com/faq
- ^InternLM. (2024). LMDeploy: TurboMind Persistent Batch and Architecture. github.com/...lmdeploy
- ^vLLM Team. (2025). RFC: Deprecating vLLM V0. GitHub issue #18571. github.com/...18571
- ^vLLM Team. (2025). Release v0.11.0, 2 October 2025. GitHub Releases. github.com/...v0.11.0
- ^vLLM Team. (2026). Releases. GitHub. github.com/...releases
- ^1 ^2Vaidya, N., Comly, N., DeLaere, J., Patel, A., & Oh, F. (2023). NVIDIA TensorRT-LLM Supercharges Large Language Model Inference on NVIDIA H100 GPUs. NVIDIA Technical Blog, September 9, 2023. developer.nvidia.com/...erence-on-nvidia-h100-gpus
- ^SGLang Team. (2025). Deploying DeepSeek with PD Disaggregation and Large-Scale Expert Parallelism on 96 H100 GPUs. LMSYS Blog, May 5, 2025. lmsys.org/...2025-05-05-large-scale-ep
- ^SGLang Project. (2026). sgl-project/sglang. GitHub. github.com/...sglang
- ^vLLM Team. (2026). Disaggregated Prefilling (experimental). vLLM Documentation. docs.vllm.ai/...disagg_prefill
- ^NVIDIA. (2026). Architecture Overview (PyTorch backend). TensorRT-LLM documentation. nvidia.github.io/...arch_overview
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
8 revisions · v8 · 6,869 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (120 claims, 33 sources fetched); 14 material + 25 minor fixed
Cite this page: AI Wiki. "Continuous Batching." aiwiki.ai, updated 1 Aug 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/continuous_batching