

PagedAttention
PagedAttention is a KV-cache memory management algorithm for serving large language models that applies the virtual-memory paging technique used by operating systems to the GPU, eliminating memory fragmentation and raising serving throughput by 2 to 4 times compared with prior systems.[1][3] It was introduced by Woosuk Kwon and colleagues at UC Berkeley, Stanford University, and UC San Diego in 2023, and it is the foundational technique behind vLLM, one of the most widely deployed open-source LLM serving systems.[1] By storing the key-value (KV) cache in small fixed-size blocks that can sit in non-contiguous GPU memory, PagedAttention drives KV-cache utilization from roughly 20 to 38 percent in earlier systems up to over 96 percent, which lets a server batch 2 to 4 times more concurrent requests under the same memory budget.[1][3]
The work was published as "Efficient Memory Management for Large Language Model Serving with PagedAttention" at the 29th ACM Symposium on Operating Systems Principles (SOSP 2023).[1] Its arXiv identifier is 2309.06180.[2] The paper frames the core idea in a single sentence: it proposes "PagedAttention, an attention algorithm inspired by the classical virtual memory and paging techniques in operating systems," and on top of it builds vLLM, a serving system that achieves "(1) near-zero waste in KV cache memory and (2) flexible sharing of KV cache within and across requests to further reduce memory usage."[2]
What problem does PagedAttention solve?
To understand why PagedAttention matters, it helps to understand how autoregressive language model inference works. When a transformer processes a sequence of tokens, the self-attention mechanism computes key and value vectors for every token at every layer. During autoregressive generation, the model produces one new token per step, but it needs access to the keys and values from all previous tokens to compute attention over the full context. Recomputing these vectors from scratch at every step would be prohibitively slow, so serving systems store them in a structure called the KV cache.[1]
The KV cache grows as generation proceeds. For a sequence of length $T$ with $L$ transformer layers, $H$ attention heads, and head dimension $d$, the cache holds $2 \times L \times T \times H \times d$ floating-point values (one tensor each for keys and values). On the 13B-parameter OPT model at FP16 precision, the KV cache of a single token takes 800 KB, so one request at OPT's maximum length of 2,048 tokens can need as much as 1.6 GB of GPU memory.[1] In the paper's example of a 13B-parameter model on a 40 GB NVIDIA A100, about 65% of GPU memory holds the model weights and close to 30% holds the KV cache, and the authors note that even if all available memory went to KV cache, only a few tens of requests could fit.[1]
Prior to PagedAttention, serving systems handled KV cache memory in a static, pre-allocating fashion. When a new request arrived, the system reserved a contiguous block of GPU memory large enough to hold the KV cache for that request's maximum possible output length.[1] This created three distinct forms of waste:
Reserved but unused slots. Slots for tokens a request would generate later were held for the request's whole lifetime, so memory that would eventually be used sat idle and could not serve other requests in the meantime.[1]
Internal fragmentation. Because the output length cannot be known in advance, systems pre-allocated a chunk sized for the maximum possible sequence length (for example 2,048 tokens), and the slots beyond the request's actual length were never used.[1]
External fragmentation. As requests completed and freed their allocations, the freed regions were scattered across the address space. A new request requiring a large contiguous allocation might find that there is technically enough free memory in aggregate, but none of the free regions are large enough individually. This is classic external fragmentation.[1]
The original PagedAttention paper measured the consequence: in existing systems, only 20.4% to 38.2% of allocated KV cache memory actually stored useful token states.[1] Between 60% and 80% of that memory was wasted. This waste directly limited the number of requests that could run concurrently, which in turn limited throughput.[1]
How does PagedAttention borrow from OS virtual memory?
The solution PagedAttention applies is borrowed directly from how operating systems manage RAM. In a modern OS, physical RAM is divided into fixed-size pages (typically 4 KB). When a process needs memory, it does not receive a large contiguous physical allocation. Instead, it receives virtual address space that the OS maps onto physical pages wherever they happen to be free. A page table maintained per-process records which virtual pages map to which physical pages. Pages for the same process can be scattered throughout physical RAM, but the process sees a clean contiguous virtual address space.[1]
This design solves both internal and external fragmentation. Internal fragmentation is bounded to at most one page's worth of wasted space (the partially filled last page). External fragmentation is eliminated because any free physical page can satisfy any request; there is no need for the free pages to be adjacent.[1]
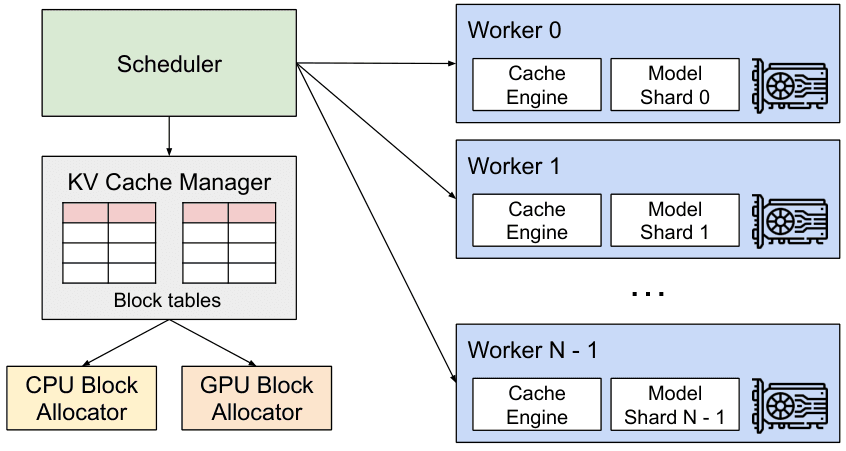
PagedAttention applies this exact idea to GPU memory for KV cache. The KV cache for a sequence is divided into fixed-size logical blocks. Each block stores the keys and values for a fixed number of consecutive tokens (the block size, defaulting to 16 tokens in the reference implementation). The system maintains a block table per sequence, mapping each logical block index to a physical block anywhere in the GPU's memory pool. The physical blocks for a single sequence do not need to be contiguous.[1]
The mapping between the two domains is direct: a logical KV block corresponds to a virtual memory page, a physical KV block corresponds to a physical memory frame, and the per-sequence block table plays the role of an OS page table.[1] During inference, attention is computed across this paged layout using a custom GPU kernel that follows each sequence's block table to gather the relevant key and value data. The paper and implementation include specialized CUDA kernels for this block-based attention computation.[1] The default kernel layout assigns one thread block per attention head per sequence, with 32-thread warps iterating over logical blocks via the block table.[4]
How does block-based KV cache allocation work?
The block manager in vLLM maintains a global pool of physical KV cache blocks. When a new request begins, the block manager allocates physical blocks on demand as tokens are generated. Only one physical block at a time is open for writing for any given sequence; previous blocks are treated as read-only once they are full.[1]
This on-demand allocation means that a sequence using 80 tokens occupies only the memory for those 80 tokens, not a pre-reserved slab sized for the maximum context length. A request that completes early frees its physical blocks immediately, making them available for new requests without any compaction or defragmentation step. Internal fragmentation is bounded to at most block_size - 1 tokens per sequence (the partially filled last block), compared to the entire maximum-length pre-allocation in earlier designs.[1]
External fragmentation is eliminated because any free physical block is interchangeable with any other. The block table handles the address translation, so no contiguity constraint exists.[1]
The tradeoff in choosing block size involves a balance between two effects. Smaller blocks reduce internal fragmentation but increase the size of block tables and add more indirection overhead in attention kernels. Larger blocks amortize the table overhead but waste more memory on partially filled trailing blocks. The paper evaluates block sizes from 1 to 256 tokens on the ShareGPT and Alpaca traces: on ShareGPT, block sizes from 16 to 128 perform best, while on Alpaca 16 and 32 work well and larger blocks degrade performance because sequences become shorter than the block. vLLM sets its default block size to 16.[1]
The memory layout for the key cache in vLLM's CUDA kernels is [num_blocks, num_kv_heads, head_size/x, block_size, x], where x is a hardware-dependent vectorization factor. The value cache layout is [num_blocks, num_kv_heads, head_size, block_size]. These specific layouts are chosen to allow coalesced memory access within the attention kernel: neighboring threads read adjacent memory addresses, maximizing memory bandwidth utilization.[4]
How does copy-on-write enable prefix sharing?
Beyond eliminating fragmentation, the block table abstraction enables another optimization: sharing physical blocks across multiple sequences. If two sequences share an identical prefix of tokens, their block tables can point to the same physical blocks for that prefix. The shared physical blocks hold the KV cache data computed once for the common prefix, and both sequences read from them without duplication.[1]
This sharing is managed through reference counting. Each physical block tracks how many sequences' block tables point to it. As long as multiple sequences reference a block, it is read-only. When a sequence needs to write a new token into a shared block (or perform any modification), the system applies copy-on-write semantics: it allocates a new physical block, copies the contents of the shared block into the new block, and updates the requesting sequence's block table to point to the new copy. The original shared block remains unmodified, so other sequences still referencing it are unaffected.[1]
This mechanism is directly useful in several inference scenarios:
Parallel sampling. A single prompt generating $n$ output sequences in parallel (for best-of-$n$ selection) would traditionally require $n$ separate copies of the prompt's KV cache. With copy-on-write, all $n$ sequences share the same physical blocks for the prompt. Independent physical blocks are allocated only as the sequences diverge in their generated tokens. The paper measures memory savings of 6.1% to 9.8% from this sharing on parallel sampling workloads.[1]
Beam search. Beam search maintains $k$ candidate sequences at each step, keeping the top-$k$ by score. These candidates share not just the prompt but also portions of the decoded sequence history where beams have not yet diverged. With copy-on-write, beams can share physical blocks as long as they point to the same token history, and new blocks are allocated only when beams diverge. Memory savings from beam search sharing range from 37.6% to 55.2% in the paper's evaluation.[1]
Shared system prompts. Many production deployments prepend the same system prompt or few-shot examples to every user request. With block sharing, the KV cache for that common prefix is computed once and shared across all concurrent requests using it. This is essentially automatic prefix caching at the block level, and it became the foundation for vLLM's later Automatic Prefix Caching (APC) feature, which extends block sharing to use a hash of block contents to identify reusable blocks from a global cache.[5]
How does PagedAttention enable iteration-level scheduling?
PagedAttention's memory efficiency enables a scheduler that works at the iteration level rather than the request level. At every decoding step, vLLM's scheduler decides which sequences to include in the next forward pass. Because physical memory blocks are allocated and freed on demand, the scheduler can add new sequences mid-generation whenever free blocks become available and remove completed sequences immediately when they finish.[1]
The scheduler maintains three queues:
- Waiting: requests that have arrived but not yet started prefill.
- Running: sequences currently generating tokens.
- Swapped: sequences whose KV cache blocks have been temporarily evicted.
When the GPU memory pool runs low, the scheduler must preempt some running sequences to make room for new ones. vLLM uses first-come-first-served (FCFS) ordering; the most recently admitted requests are preempted first, preserving progress on requests that have already generated significant output. Preemption operates on entire sequence groups at once rather than individual sequences, because sequences within a group (for example, multiple parallel samples from one request) may share physical blocks.[1]
Two recovery strategies are available after preemption:
Swapping. The preempted sequence's physical KV cache blocks are serialized to CPU DRAM over PCIe and released on the GPU. When the sequence is re-admitted, the blocks are copied back from CPU to GPU. This is efficient for larger block sizes where the PCIe transfer cost is amortized over more data, but it adds latency proportional to the amount of data swapped and the PCIe bandwidth available.[1]
Recomputation. The preempted sequence's KV cache blocks are simply discarded. When the sequence is re-admitted, the prefill phase is re-run from the beginning to regenerate the KV cache. Recomputation is more efficient at small block sizes, and for medium block sizes from 16 to 64 tokens the two methods give comparable end-to-end performance. The paper reports that recomputation overhead is never higher than 20% of swapping's latency.[1]
How much faster is PagedAttention?
The paper evaluates vLLM against two primary baselines: Orca and FasterTransformer. Orca is a prior iteration-level scheduling system without PagedAttention's memory management. FasterTransformer is NVIDIA's high-performance transformer inference library.[1]
Evaluations use OPT and LLaMA models ranging from 13B to 175B parameters, tested on ShareGPT and Alpaca prompt datasets. The ShareGPT dataset has much longer sequences (8.4 times longer input and 5.8 times longer output than Alpaca), making KV cache memory pressure more acute.[1]
Throughput comparison (ShareGPT dataset, normalized request rate)
| System | vs. FasterTransformer | vs. Orca (Oracle) | vs. Orca (Max) |
|---|---|---|---|
| vLLM (PagedAttention) | up to 22x | 1.7x to 2.7x | 2.7x to 8x |
"Oracle" refers to Orca with perfect foreknowledge of output lengths to eliminate over-reservation. The fact that vLLM outperforms even the oracle variant by 1.7x to 2.7x shows that the gains come from more than just eliminating over-reservation; the paged allocation and sharing provide additional benefits.[1]
Memory efficiency comparison
| System | KV cache utilization | Memory waste |
|---|---|---|
| Orca variants (Max, Pow2, Oracle) | 20.4% to 38.2% | 60% to 80% |
| vLLM (PagedAttention) | over 96% | under 4% |
Memory savings from block sharing
| Scenario | Memory savings |
|---|---|
| Parallel sampling | 6.1% to 9.8% (Alpaca); 16.2% to 30.5% (ShareGPT) |
| Beam search | 37.6% to 55.2% (Alpaca); 44.3% to 66.3% (ShareGPT) |
| Shared prefix (LLaMA-13B, WMT16 translation) | No memory figure reported; 1.67x (one-shot prefix) and 3.58x (five-shot prefix) higher throughput than Orca (Oracle) |
Comparison with HuggingFace Transformers
The vLLM blog post reports even larger gains relative to unoptimized inference code. Compared to HuggingFace Transformers running on the same hardware:[3]
- Single completion tasks: 14x to 24x higher throughput
- Three parallel completions: 8.5x to 15x higher throughput
These larger multipliers reflect the baseline inefficiency of HuggingFace Transformers for serving use cases, rather than the isolated gain from PagedAttention specifically.[3]
How does PagedAttention differ from naive attention serving?
The table below summarizes the conceptual differences between naive KV cache management (as used in early serving systems) and PagedAttention:
| Property | Naive KV cache | PagedAttention |
|---|---|---|
| Memory allocation | Pre-allocated contiguous slab per request | On-demand fixed-size blocks, any location |
| Internal fragmentation | Up to full max-length reservation | At most block_size - 1 tokens |
| External fragmentation | Yes, grows as requests complete | None (any free block fills any request) |
| Memory utilization | 20% to 38% | Over 96% |
| Prefix sharing | Not supported | Supported via block table aliasing |
| Copy-on-write | Not applicable | Supported via reference counting |
| Maximum concurrent batch | Limited by fragmentation | Near-optimal packing |
| Kernel complexity | Simple contiguous tensor access | Block table indirection, custom CUDA kernels |
| Per-kernel overhead | Baseline | Approximately 20% to 26% higher |
The per-kernel overhead is real: looking up block table entries and accessing non-contiguous memory is slower than a simple contiguous tensor read. However, the overhead is far outweighed by the ability to run 2 to 4 times more requests concurrently.[1] Throughput, which is what matters for a serving system under load, improves substantially even though individual kernel latency is slightly higher.[1]
Where is PagedAttention used?
vLLM
vLLM is the system that introduced PagedAttention and remains its primary home. Released by UC Berkeley researchers in June 2023, vLLM quickly became one of the most widely used open-source LLM serving frameworks. PagedAttention is the core of its memory management layer. Subsequent vLLM development has extended PagedAttention with Automatic Prefix Caching (APC), which uses content hashes to identify and reuse blocks across requests without explicit prefix matching;[5] chunked prefill, which breaks long prefill sequences into smaller chunks to reduce time-to-first-token variance; and speculative decoding, which uses a smaller draft model to propose multiple tokens for verification by the main model.
vLLM later added support for a large catalog of model architectures and multiple attention kernel backends, including Flash Attention, FlashInfer, and Triton-based kernels. At the time of the 2023 SOSP paper, the vLLM engine was written in about 8,500 lines of Python and 2,000 lines of C++ and CUDA.[1]
TensorRT-LLM
NVIDIA's TensorRT-LLM inference framework adopted a blocked KV cache design that is similar in spirit to PagedAttention. Alongside a contiguous KV cache option, TensorRT-LLM offers a paged KV cache that decomposes the cache into blocks, which a cache manager allocates to requests from a pool and recycles when required.[7] The internal memory layout and kernel implementation differ from vLLM's design, and TensorRT-LLM incorporates additional NVIDIA-specific optimizations such as INT8 and FP8 KV caches and XQA kernels for multi-query and grouped-query attention.[7] TensorRT-LLM is typically used when squeezing maximum performance from NVIDIA hardware, particularly for production deployments on A100 and H100 GPUs.
SGLang
SGLang is a serving framework developed by researchers at Stanford, UC Berkeley and other institutions that takes the prefix caching idea further with a data structure called RadixAttention.[6] Where PagedAttention achieves prefix sharing by aliasing block tables when the serving system knows requests share a prefix, RadixAttention organizes the entire KV cache as a radix tree (trie) indexed by token sequences.[6] Any request whose token prefix matches a prefix already in the tree can immediately reuse that portion of the KV cache, with no need for the operator to configure explicit prefix groups.[6] The SGLang paper reports up to 6.4x higher throughput than existing systems, including vLLM, across agent, reasoning, few-shot and other workloads; the authors note they compared against an earlier vLLM version because RadixAttention had since been partially integrated into vLLM as an experimental feature.[6]
Text Generation Inference (TGI)
HuggingFace's Text Generation Inference server adopted paged memory management as well; its feature list cites optimized inference code using Flash Attention and Paged Attention.[11] Hugging Face has since placed TGI in maintenance mode, accepting only minor bug fixes, documentation improvements and lightweight maintenance tasks.[11]
LMDeploy
LMDeploy, developed by the MMRazor and MMDeploy teams in the InternLM ecosystem, uses a blocked KV cache in its TurboMind inference engine, targeting deployment of models like InternLM.[12] It follows the same conceptual model of non-contiguous physical blocks with logical-to-physical mapping.
What are the limitations of PagedAttention?
PagedAttention is not without costs and constraints.
Attention kernel overhead. The custom attention kernels that gather KV data from non-contiguous blocks are slower per operation than kernels operating on contiguous tensors. The paper measures approximately 20% to 26% kernel-level overhead.[1] At batch size 1 (low-concurrency scenarios), this overhead is not offset by memory gains, and a system like Flash Attention using contiguous memory may have lower latency. PagedAttention's advantage is in high-concurrency, high-throughput scenarios.[1]
Block table management complexity. The system must maintain per-sequence block tables and a global block allocator. Reference counting for copy-on-write adds additional bookkeeping. This complexity is manageable in practice but adds implementation overhead compared to simple contiguous allocation.
PCIe bandwidth for swapping. When the scheduler preempts sequences by swapping their KV blocks to CPU memory, the PCIe link between the GPU and host RAM becomes a bottleneck. PCIe 4.0 x16 provides roughly 32 GB/s of bandwidth in each direction, but a large swap event can still add hundreds of milliseconds of latency for a request waiting to be readmitted. Recomputation avoids this but burns GPU compute instead.
Internal fragmentation from block granularity. The block size is a fixed parameter for the entire serving instance. If most requests produce short sequences and the block size is large, internal fragmentation re-emerges. Choosing an appropriate block size for a deployment's workload characteristics matters.
Distributed inference complexity. PagedAttention was originally designed for single-GPU or tensor-parallel setups. Pipeline parallelism across nodes introduces additional complexity because different stages must coordinate block table state. vLLM's distributed implementation uses Megatron-LM-style tensor parallelism, where each GPU holds a slice of each physical block, but pipeline-parallel block management is more involved.
Interaction with speculative decoding. Speculative decoding generates multiple candidate tokens using a draft model and verifies them with the main model. Managing block allocation for speculative tokens that may be rejected requires care; blocks allocated for rejected tokens must be rolled back or discarded efficiently.
A later line of work, including the vAttention system, also questions whether software-level paging is strictly necessary, arguing that low-level GPU virtual memory APIs can deliver dynamic KV allocation while preserving the contiguous virtual layout that simpler attention kernels expect.[10]
Variants and improvements
Automatic Prefix Caching (APC)
vLLM's APC feature, added after the initial PagedAttention paper, extends block sharing to work automatically without explicit prefix groups. When a physical block is filled and becomes read-only, vLLM hashes its contents along with its position-dependent prefix hash. New requests with matching prefixes find their logical blocks remapped to existing physical blocks from the hash table, skipping recomputation.[5] This turns PagedAttention's copy-on-write mechanism into a general-purpose KV cache that persists across requests.[5]
RadixAttention (SGLang)
SGLang's RadixAttention organizes the KV cache as a radix tree where each edge represents a sequence of tokens and each node represents a point where multiple prefixes share a common ancestor. This structure makes prefix matching for new requests an efficient tree traversal, avoiding the per-block hashing of vLLM's APC.[6] RadixAttention is particularly effective for workloads with deep, branching prefix structures such as multi-turn conversations, few-shot examples, or retrieval-augmented generation with shared retrieved contexts.[6]
FlashInfer paged attention kernels
FlashInfer is an attention kernel library whose PageAttention operators are implemented as block-sparse attention kernels, with the page size setting the block's column count; at a page size of 1 it supports vector-sparsity, which SGLang uses.[8] FlashInfer 0.2 integrated Flash Attention 3 templates and a JIT compiler that generates specialized kernels for attention variants, reducing the need to maintain a separate CUDA kernel for every attention configuration.[8] vLLM also offers FlashInfer as an optional attention backend.
Chunked prefill
Chunked prefill divides long input sequences into smaller chunks processed in separate iterations. Combined with PagedAttention, this reduces peak memory pressure during the prefill phase, which would otherwise require allocating the full KV cache for a long prompt in one step.[9] The cited analysis describes a tunable tradeoff: a smaller chunk size reduces peak memory during prefill but may increase latency, while a smaller block size reduces persistent memory overhead but adds more page operations.[9] The two techniques are orthogonal: PagedAttention manages spatial fragmentation in memory while chunked prefill manages temporal concentration of compute.[9]
PagedEviction
PagedEviction (arXiv 2509.04377) extends PagedAttention with a structured pruning strategy that selectively evicts KV cache blocks for less important tokens when memory pressure is high, rather than evicting entire sequences. This allows longer context windows to fit in fixed GPU memory at the cost of some approximation in attention over evicted tokens.
vLLM V1 architecture
The vLLM V1 refactor (alpha released January 27, 2025)[13] redesigned the runtime architecture to separate the scheduler from the workers more cleanly, enable CUDAGraph capture for PagedAttention-based decoding, and improve compatibility with chunked prefill and speculative decoding. The V1 architecture maintains PagedAttention as its core memory abstraction while improving scheduling throughput and reducing Python overhead in the control plane.
Continue reading
- KV CacheKV cache, short for key-value cache, is transient model state used during Transformer generation.Mentioned 36 times above
- vLLMvLLM is an open-source inference and serving engine for large language models. It is software for running already trained models, either through a Python interface for offline work or through a network server…Mentioned 31 times above
- SGLangSGLang (short for Structured Generation Language) is a high-performance, open-source serving framework for large language models and multimodal models, originally developed at UC Berkeley's Sky Computing Lab…Mentioned 6 times above
- TensorRTTensorRT is NVIDIA's software development kit (SDK) for high-performance deep learning inference on NVIDIA GPUs.Mentioned 5 times above
- Flash AttentionFlashAttention is a family of exact, input/output-aware algorithms and GPU kernels for scaled dot-product attention.Mentioned 4 times above
- Speculative DecodingSpeculative decoding is a lossless inference acceleration technique for autoregressive transformer models in which a small, fast draft model proposes several future tokens at once and the larger target model…Mentioned 4 times above
More from See also
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32 ^33 ^34 ^35 ^36 ^37 ^38Kwon, W., Li, Z., Zhuang, S., Sheng, Y., Zheng, L., Yu, C. H., Gonzalez, J. E., Zhang, H., & Stoica, I. (2023). Efficient Memory Management for Large Language Model Serving with PagedAttention. *Proceedings of the 29th Symposium on Operating Systems Principles (SOSP 2023)*. dl.acm.org/...3600006.3613165
- ^1 ^2Kwon et al. (2023). Efficient Memory Management for Large Language Model Serving with PagedAttention. arXiv preprint arXiv:2309.06180. arxiv.org/...2309.06180
- ^1 ^2 ^3 ^4vLLM Team. (2023). vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention. vLLM Blog. blog.vllm.ai/...vllm
- ^1 ^2vLLM Project. (2024). Paged Attention design documentation. docs.vllm.ai/...paged_attention
- ^1 ^2 ^3 ^4vLLM Project. (2024). Automatic Prefix Caching documentation. docs.vllm.ai/...automatic_prefix_caching
- ^1 ^2 ^3 ^4 ^5 ^6Zheng, L., Yin, L., Xie, Z., Huang, J., Sun, C., Yu, C. H., Cao, S., Kozyrakis, C., Stoica, I., Gonzalez, J. E., Barrett, C., & Sheng, Y. (2024). SGLang: Efficient Execution of Structured Language Model Programs. arXiv:2312.07104. arxiv.org/...2312.07104
- ^1 ^2NVIDIA. Multi-Head, Multi-Query, and Group-Query Attention. TensorRT-LLM documentation. nvidia.github.io/...gpt-attention
- ^1 ^2FlashInfer Team. (2024). FlashInfer 0.2: Efficient and Customizable Kernels for LLM Inference Serving. flashinfer.ai/...flashinfer-v02-release
- ^1 ^2 ^3Sengopal, K. (2024). Paged Attention and Chunked Prefill for LLM Inference. sengopal.me/...d-chunked-prefill-for-llm-inference
- ^Prabhu, R., Nayak, A., Mohan, J., Ramjee, R., & Panwar, A. (2024). vAttention: Dynamic Memory Management for Serving LLMs without PagedAttention. arXiv:2405.04437. arxiv.org/...2405.04437
- ^1 ^2Hugging Face. text-generation-inference (README). GitHub. github.com/...text-generation-inference
- ^InternLM. LMDeploy (README). GitHub. github.com/...lmdeploy
- ^vLLM Team. (2025). vLLM V1: A Major Upgrade to vLLM's Core Architecture. vLLM Blog. blog.vllm.ai/...v1-alpha-release
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
8 revisions · v8 · 4,221 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (95 claims, 17 sources fetched); 7 material + 21 minor fixed
Cite this page: AI Wiki. "PagedAttention." aiwiki.ai, updated 21 Jun 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/paged_attention