

Data labeling
Data labeling (also called data annotation) is the process of attaching meaningful tags, labels, or metadata to raw data so that machine learning algorithms can learn from it. The labeled data serves as the ground truth during supervised learning and the human preference signal during RLHF, and the work has grown into a multi-billion-dollar industry: the global data collection and labeling market was valued at about $3.77 billion in 2024 and is projected to reach $17.1 billion by 2030, a roughly 28% compound annual growth rate.[10] Without labeled data, most modern AI systems, from image recognition models to large language models, cannot be trained or aligned effectively.
Data labeling spans every major data modality: images, text, audio, video, and 3D point clouds. The work ranges from drawing rectangles around objects in photographs to rating which of two chatbot responses sounds more helpful. As frontier AI labs have shifted from passively training on web text to actively modeling expert workflows, the industry has moved upmarket from cheap crowd work toward high-cost expert annotation, and specialist firms such as Scale AI, Surge AI, Mercor, and Turing have reached, or been valued in reported funding talks at, multi-billion-dollar valuations on the strength of that demand.[19][20][21]
What is data labeling and why is it needed?
At its core, data labeling converts unstructured or semi-structured data into a format that statistical models can consume. A raw photograph, for example, contains pixel values but no information about what those pixels represent. A human annotator examines the photograph and marks relevant objects ("car," "pedestrian," "traffic light"), producing structured annotations that a computer vision model can use during training.
The purpose of labeling extends beyond initial model training. Labeled data is also used to evaluate model performance on held-out test sets, to fine-tune pre-trained models on domain-specific tasks, and to generate the preference comparisons needed for reinforcement learning from human feedback (RLHF). In production systems, newly collected data is often labeled on a rolling basis so that models can be retrained as distributions shift over time.
What are the types of data labeling?
Image annotation
Object detection and image classification are among the most common computer vision tasks, and each requires a different style of annotation.
| Annotation type | Description | Typical use case |
|---|---|---|
| Bounding box | A rectangle drawn tightly around an object, defined by corner coordinates (x_min, y_min, x_max, y_max) | Object detection in autonomous vehicles, retail inventory |
| Polygon | A multi-vertex outline tracing the precise boundary of an object | Instance-level annotation where object shape matters |
| Semantic segmentation | Every pixel in the image is assigned to a class (e.g., road, sidewalk, sky) | Self-driving cars, robotics, medical imaging |
| Instance segmentation | Like semantic segmentation, but separate instances of the same class receive distinct labels | Counting overlapping objects, warehouse logistics |
| Keypoint | Specific landmark points placed on an object to capture its pose or structure | Pose estimation, facial landmark detection, gesture recognition |
| Cuboid (3D bounding box) | A three-dimensional box placed around an object in a 2D or 3D scene | LiDAR data for autonomous driving, robotics |
| Polyline | A series of connected line segments tracing linear features | Lane markings on roads, power lines, cracks in infrastructure |
Bounding boxes are the fastest to produce and remain the default for many object detection pipelines. Semantic and instance segmentation require pixel-level precision and cost more per image but yield richer training signals. Keypoints are standard for human pose estimation tasks, where the annotator places points on joints (shoulders, elbows, wrists, knees) to define a skeletal structure.
Text annotation
Text annotation supports natural language processing (NLP) tasks. The main varieties include:
| Annotation type | Description | Typical use case |
|---|---|---|
| Named entity recognition (NER) | Identifying and classifying entities (people, organizations, locations, dates, monetary values) within text | Information extraction, knowledge graph construction |
| Sentiment analysis | Tagging text with positive, negative, or neutral sentiment labels | Customer feedback analysis, brand monitoring |
| Text classification | Assigning entire documents or passages to predefined categories | Spam detection, topic categorization, content moderation |
| Relation extraction | Labeling the relationships between identified entities | Biomedical literature mining, legal document analysis |
| Coreference resolution | Linking different mentions that refer to the same entity | Dialogue systems, document summarization |
| Part-of-speech tagging | Labeling each word with its grammatical role (noun, verb, adjective) | Parsing, grammar checking, linguistic research |
For NER, an annotator might read the sentence "Apple announced a $3 billion bond offering in London" and tag "Apple" as an organization, "$3 billion" as a monetary value, and "London" as a location. Sentiment annotation often uses Likert-scale ratings (1 to 5) or binary positive/negative labels.
Audio and speech annotation
Audio annotation prepares data for speech recognition, speaker identification, and sound event detection.
| Annotation type | Description | Typical use case |
|---|---|---|
| Transcription | Converting spoken language into written text with timestamps | Voice assistants, meeting transcription |
| Speaker diarization | Segmenting an audio recording by speaker and labeling each segment ("Speaker A," "Speaker B") | Call center analytics, podcast indexing |
| Sound event detection | Tagging non-speech audio events (glass breaking, dog barking, siren) | Surveillance, environmental monitoring |
| Emotion and intent labeling | Classifying the emotional tone or intent behind a spoken utterance | Customer service routing, voice-based UX research |
| Phonetic annotation | Labeling individual phonemes or prosodic features | Linguistics research, text-to-speech training |
Speaker diarization answers the question "who spoke when?" and is useful in multi-party conversations. AssemblyAI's documentation recommends at least 30 seconds of continuous speech per speaker for best results.
Video annotation
Video annotation extends image annotation across time. Annotators may label individual frames or track objects across a sequence of frames using interpolation, where the tool automatically estimates object positions between manually annotated keyframes. Video annotation is central to training models for autonomous driving, sports analytics, and security surveillance.
Annotation platforms and tools
A variety of open-source and commercial platforms exist for managing labeling workflows. The table below compares several widely used options.
| Platform | Type | Supported data | Notable features | License / pricing |
|---|---|---|---|---|
| Label Studio | Open-source / Enterprise | Images, text, audio, video, time series | Configurable templates, REST API, ML backend integration, Python SDK | Apache 2.0 (community); paid Enterprise and Cloud tiers from HumanSignal |
| Labelbox | Commercial | Images, video, text, geospatial, documents | Model-assisted labeling, active learning, API-first design, Alignerr expert marketplace | Paid tiers; founded 2018, raised $189M+ |
| Scale AI | Commercial (managed service) | Images, video, text, LiDAR, documents, RLHF data | Managed human workforce, quality control, government and defense contracts, data engine for LLM evaluation | Enterprise pricing; founded 2016 by Alexandr Wang, valued at ~$29B after Meta's June 2025 investment |
| Amazon SageMaker Ground Truth | Cloud service | Images, video, text, 3D point clouds | Automated labeling via active learning (AWS claimed savings of up to 70%), private or vendor workforces; its Mechanical Turk workforce option (500,000+ workers at its 2018 launch) ended when MTurk closed on September 30, 2026 | Pay-per-object pricing; closed to new customers since July 30, 2026 |
| Prodigy | Commercial (local) | Text, images, audio, video | Built by Explosion AI (makers of spaCy), runs entirely on local machines, scriptable recipes, active learning, LLM integration via spacy-llm | One-time license fee; data never leaves the user's machine |
| CVAT | Open-source | Images, video | Originally developed by Intel, now maintained by CVAT.ai Corporation; bounding boxes, polygons, cuboids, keyframes with interpolation, AI-assisted annotation via OpenVINO | MIT license |
| Encord | Commercial | Images, video, DICOM (medical) | Automated labeling, quality metrics, ontology management, HIPAA-compliant workflows | Paid tiers |
| V7 | Commercial | Images, video, documents | Auto-annotation with foundation models, pixel-accurate masks, dataset management | Paid tiers |
| SuperAnnotate | Commercial | Images, video, text, audio | Workforce management, quality assurance dashboards, model-assisted tools | Paid tiers |
| Snorkel AI | Commercial (programmatic labeling) | Text, tabular, images | Weak supervision via labeling functions, data programming paradigm, originated from Stanford research | Enterprise pricing |
Scale AI
Scale AI was founded in 2016 by Alexandr Wang and Lucy Guo through Y Combinator.[18] Wang, who was 19 at the time, had dropped out of MIT after previously working as an engineer at Quora.[18] The company provides data labeling services, model evaluation, and data infrastructure for AI development.
In May 2024, Scale AI raised $1 billion in a Series F round led by Accel, with participation from Amazon, Meta, NVIDIA, Intel Capital, and others.[6][7] The round valued the company at approximately $13.8 billion, nearly double its previous valuation.[6][7] Scale's annual recurring revenue tripled in 2023, and Reuters reported that the company generated roughly $870 million in revenue in 2024 (a Scale spokesperson later told CNBC the figure was close to $1 billion).[20][27]
In June 2025, Meta Platforms agreed to invest $14.3 billion for a 49% non-voting stake in Scale AI, which Scale said valued the company at more than $29 billion.[19][24] As part of the transaction, founder and CEO Alexandr Wang left to lead Meta's new superintelligence effort, and Scale's board named chief strategy officer Jason Droege interim CEO while the company continued to operate independently.[19][24] On July 30, 2026, Scale appointed Francis deSouza, then chief operating officer of Google Cloud, as CEO effective August 10, 2026.[25] The deal unsettled Scale's customers. Within days, Reuters reported that Google, which had planned to pay Scale about $200 million in 2025, planned to cut ties and that Microsoft was also looking to pull back; xAI was later reported to have paused its work too, amid concerns that a part-owner competitor could gain visibility into rivals' training pipelines.[22][27] Bloomberg reported that OpenAI was phasing out its Scale work, but an OpenAI spokesperson said the company had been winding it down over the previous six to 12 months and that the decision was not influenced by the Meta deal.[22][26]
Scale AI's clients have included major AI labs, the U.S. Department of Defense, and Fortune 500 companies; by November 2025, OpenAI, Google, and xAI were no longer listed as customers on Scale's website, while Meta was.[18][27] The company is known for its managed workforce model, where it handles recruiting, training, and quality control for annotators rather than leaving those tasks to the customer.
Surge AI
Surge AI is a data-labeling company founded in 2020 by Edwin Chen, a former engineer at Google, Facebook, and Twitter, who started the firm out of dissatisfaction with the quality of crowdsourced annotation.[20] Surge specializes in expert, RLHF-grade human feedback for frontier labs rather than competing on low-cost, high-volume work. By 2024 it had reportedly reached roughly $1.2 billion in annualized revenue, surpassing Scale AI's $870 million for the same year, with growth driven by a small group of about a dozen frontier labs including OpenAI, Google, Anthropic, Microsoft, and Meta.[20] In mid-2025, after the Meta-Scale deal unsettled Scale's customers, Surge began its first external fundraise, seeking up to $1 billion at a valuation reported between $15 billion and $25 billion.[20]
Mercor
Mercor is an AI-training and talent-marketplace startup founded in 2022 (incorporated 2023) by Thiel Fellows Brendan Foody, Adarsh Hiremath, and Surya Midha. It matches domain experts (including PhDs, doctors, lawyers, and software engineers) with AI labs that need high-quality human data and model evaluation. As of late 2025 the company managed more than 30,000 contractors paid an average of more than $85 per hour, and disclosed roughly $450 million in annualized run-rate revenue.[21] Mercor raised a $350 million Series C in October 2025 led by Felicis, valuing the company at about $10 billion, up roughly fivefold from its $2 billion Series B in February 2025.[21]
Turing
Turing, founded in 2018 by Jonathan Siddharth and Vijay Krishnan, began as a remote-engineering talent platform and pivoted into supplying coding-focused training data and human feedback to AI labs, including OpenAI. Its "Turing AGI Advancement" arm collaborates with frontier labs after researchers found that code in training datasets improves model reasoning. In March 2025, Turing raised a $111 million Series E led by Khazanah Nasional, doubling its valuation to $2.2 billion.[21] Turing's own announcement materials described the company as "an index bet on AGI."
Label Studio
Label Studio is an open-source data labeling tool released under the Apache 2.0 license.[12] It was created by Heartex (later rebranded to HumanSignal) and supports a wider range of data types than most alternatives, including images, text, audio, video, HTML, and time-series data.[12] Its template system lets teams define custom labeling interfaces using XML-like configuration.[12] HumanSignal offers a managed cloud Starter tier listed at $99 per month as of November 2026[30] and a self-hosted Enterprise tier with SSO, role-based access control, and audit logs.
CVAT
CVAT (Computer Vision Annotation Tool) was originally developed by Intel for internal use and later open-sourced under the MIT license.[13] Intel later moved it under the OpenCV umbrella, and in 2022 it became the core product of an independent company, CVAT.ai Corporation, which now maintains it.[13][31] CVAT specializes in image and video annotation, with built-in support for bounding boxes, polygons, polylines, cuboids, and keypoints.[13] Its interpolation feature lets annotators label objects in a few keyframes and have the tool fill in intermediate frames automatically.[13] CVAT integrates with Intel's OpenVINO toolkit for AI-assisted annotation.[13]
Prodigy
Prodigy is a commercial annotation tool built by Explosion AI, the company behind the spaCy NLP library.[14] Unlike cloud-based platforms, Prodigy runs entirely on the user's local machine, and no data is sent to third-party servers.[14] This makes it suitable for sensitive or regulated data. Prodigy's design emphasizes efficiency: it uses active learning to surface the most informative examples and presents binary decision interfaces (accept/reject) that allow annotators to work quickly.[14] In 2023, Prodigy added LLM integration through the spacy-llm library, enabling users to combine model predictions with human review.
How does RLHF and preference labeling work?
Reinforcement learning from human feedback (RLHF) has become a standard technique for aligning large language models with human preferences.[1] The data labeling requirements for RLHF differ from traditional annotation tasks, and the payoff can be large: in the OpenAI InstructGPT study, "outputs from the 1.3B parameter InstructGPT model are preferred to outputs from the 175B GPT-3, despite having 100x fewer parameters," a result the authors obtained by fine-tuning on human demonstrations and human preference rankings rather than by adding scale.[1]
How RLHF data collection works
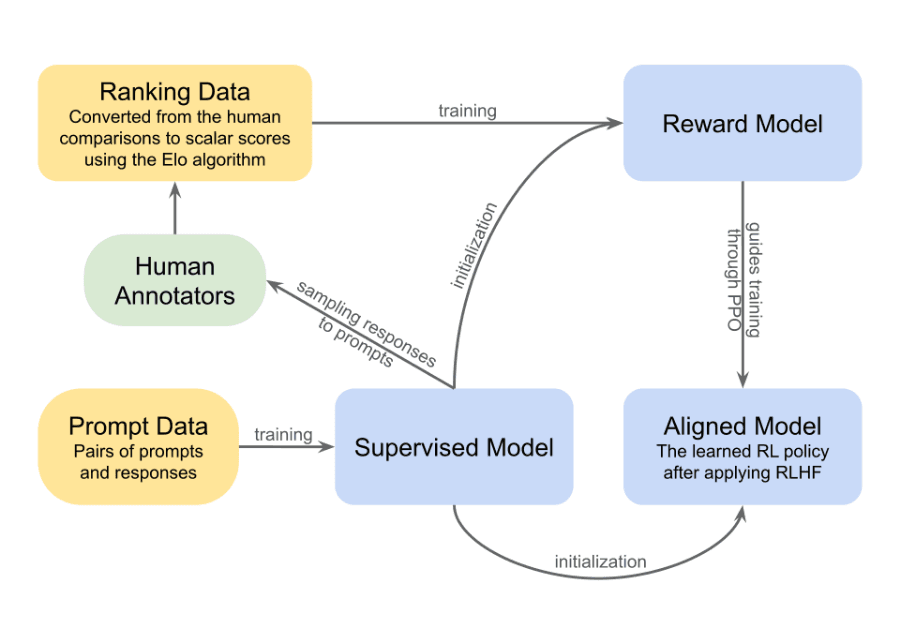
The RLHF pipeline typically involves three stages of data:
- Demonstration data. Human annotators write high-quality responses to prompts, producing examples that are used to fine-tune a base language model through supervised learning.[1]
- Comparison data. The fine-tuned model generates two or more candidate responses for a given prompt. Human evaluators then rank these responses, indicating which one is better. In the InstructGPT study, labelers ranked between 4 and 9 responses per prompt, and each ranking was expanded into pairwise comparisons (a prompt, two responses, and a preference) for training.[1]
- Reward model training. The comparison data trains a reward model that predicts how a human would score any given response. This reward model then guides the language model's optimization through reinforcement learning (typically using Proximal Policy Optimization, or PPO).[1]
OpenAI's InstructGPT paper (2022) described this pipeline in detail.[1] The process requires both human-generated text (for stage 1) and human preference judgments (for stage 2). Annotators often use Likert-scale ratings or pairwise ranking interfaces.
Challenges in preference labeling
Preference labeling introduces unique difficulties. Different evaluators may have varying interpretations of quality, helpfulness, or safety. A response that one evaluator considers helpful might strike another as verbose. These disagreements make inter-annotator agreement harder to achieve than in more objective tasks like bounding box annotation. To manage this, RLHF annotation teams use detailed rubrics, calibration sessions, and regular audits of annotator consistency.
The cost of RLHF annotation is also higher than standard labeling. Because evaluators must read and compare full text responses (sometimes multiple paragraphs long), throughput is lower and per-example costs can reach $50 to $100 for complex tasks involving domain expertise.
Why is data labeling shifting to expert annotation?
For years, the labeling industry optimized for volume and low cost, distributing simple tasks to large pools of crowd workers. The rise of post-training methods (instruction tuning, RLHF, and reasoning data) has inverted that priority: frontier labs increasingly need correct, expert-grade feedback on hard problems rather than millions of cheap labels. The venture firm SignalFire summarized the shift by arguing that "AI is moving from passively mirroring the internet to actively modeling expert workflows," with post-training behaviors "encoded and shaped, not by the internet at large, but by curated, high-quality feedback from subject matter experts."[23]
The business outcomes reflect this. Surge AI charges premium rates for coding answers graded by software engineers and medical data labeled by doctors, and reached an estimated $1.2 billion in 2024 revenue while staying lean.[20] Mercor said its domain-expert contractors earned more than $85 per hour on average, far above crowd-work rates, and reached a $10 billion valuation in under three years.[21] Turing supplies code-and-reasoning data graded by professional engineers.[21] The common thread is a move from "how many labels per dollar" toward "how good is the judgment behind each label," with expert annotators, AI-assisted pre-labeling, and tight quality loops replacing high-volume crowd pipelines for the hardest tasks.
Crowd-sourced vs. expert labeling
Organizations that need labeled data face a choice between crowd-sourced annotators and domain experts. Each approach has trade-offs.
Crowd-sourced labeling
Platforms like Amazon Mechanical Turk (MTurk), launched in 2005, pioneered the use of distributed online workers for annotation at scale.[17] By January 2011, MTurk had over 500,000 registered workers from more than 190 countries.[17] Work was distributed as Human Intelligence Tasks (HITs), and requesters paid per completed task.[17] Amazon stopped accepting new MTurk customers on July 30, 2026 and closed the service on September 30, 2026.[28][29]
Crowd-sourced labeling is the cheapest option per unit. Hourly rates for offshore annotators typically range from $4 to $12, and simple tasks (image classification, sentiment tagging) can be completed quickly. However, quality control is a persistent challenge. A 2018 academic study found that the median hourly wage for MTurk workers was approximately $2 per hour, which raises questions about worker motivation and attention to detail.[3] Many requesters compensate by collecting multiple annotations per item and using majority voting to determine the final label.
Expert labeling
For tasks requiring specialized knowledge, expert annotators produce higher-quality labels but at significantly greater cost. Medical imaging annotation, where a radiologist must identify tumors or anatomical structures in DICOM images, can cost $50 to $100 per hour. Legal document annotation, genomics data, and financial compliance labeling similarly demand trained professionals. Marketplaces such as Mercor that recruit PhDs, physicians, and engineers for AI-training work pay these experts more than $85 per hour on average, according to Mercor.[21]
Managed labeling services (offered by companies like Scale AI, Surge AI, Appen, and Sama) sit between pure crowd-sourcing and in-house expert teams. These services typically charge $6 to $12 per hour for general tasks and handle annotator recruitment, training, and quality assurance on behalf of the client.
Comparison
| Factor | Crowd-sourced | Expert | Managed service |
|---|---|---|---|
| Cost per hour | $2 to $12 | $25 to $100+ | $6 to $40 |
| Quality (typical) | Variable; requires QA layers | High; fewer errors | Moderate to high |
| Speed to scale | Fast (large worker pool) | Slow (limited supply) | Moderate |
| Best for | Simple, high-volume tasks | Domain-specific, high-stakes tasks | Teams without in-house annotation infrastructure |
| Drawbacks | Inconsistent quality, ethical concerns about low pay | Expensive, hard to recruit | Vendor lock-in, less control |
How is annotation quality measured?
Label quality directly affects model performance. A model trained on noisy labels will learn noisy patterns. Several techniques are used to measure and maintain annotation quality.
Inter-annotator agreement
Inter-annotator agreement (IAA) measures how consistently different annotators label the same data. The most common metric is Cohen's kappa, which accounts for agreement that would occur by chance:[5]
K = (Pr(a) - Pr(e)) / (1 - Pr(e))
where Pr(a) is the observed agreement between annotators and Pr(e) is the probability of agreement expected by chance.[5] Kappa values are typically interpreted using the Landis and Koch scale:[4]
| Kappa value | Interpretation |
|---|---|
| 0.81 to 1.00 | Almost perfect agreement |
| 0.61 to 0.80 | Substantial agreement |
| 0.41 to 0.60 | Moderate agreement |
| 0.21 to 0.40 | Fair agreement |
| 0.00 to 0.20 | Slight agreement |
| Below 0.00 | Poor agreement |
For tasks with more than two annotators, Fleiss' kappa generalizes the metric. Krippendorff's alpha is another option that handles missing data and works across different measurement scales (nominal, ordinal, interval, ratio).
Low IAA scores often indicate ambiguous labeling guidelines rather than poor annotator performance. When agreement drops below acceptable thresholds, teams typically revise their annotation instructions, add more examples to the guidelines, or hold calibration sessions.
Gold standard sets
Gold standard items are data points with known correct labels, verified by senior annotators or domain experts. These items are inserted randomly into each annotator's queue at a rate of roughly 5% to 10%. The annotator does not know which items are gold standards. If an annotator's accuracy on gold items falls below a threshold (often 90% to 95%), their work is flagged for review or they are removed from the task.
This approach provides ongoing quality signals without requiring every annotation to be checked. It also helps identify annotators who are rushing through tasks or misunderstanding the guidelines.
Consensus and adjudication
Many labeling pipelines collect two or three independent annotations per item and resolve disagreements through majority voting or a dedicated adjudicator. The adjudicator (usually a senior annotator or subject matter expert) reviews disputed items and selects the correct label. While this approach improves accuracy, it multiplies cost proportionally.
Active learning for efficient labeling
Active learning is a machine learning technique that reduces the amount of labeled data needed to reach a target level of model performance. Instead of labeling data points at random, active learning selects the examples that are most informative for the model.
How active learning works
The process runs in a loop:
- Train a model on the currently labeled dataset.
- Use the model to score unlabeled data points by informativeness (e.g., how uncertain the model is about each one).
- Send the highest-scoring points to human annotators for labeling.
- Add the newly labeled data to the training set and retrain.
- Repeat until performance reaches the desired level.
Selection strategies
Several strategies exist for choosing which examples to label next:
| Strategy | How it works | When to use |
|---|---|---|
| Uncertainty sampling | Select examples where the model is least confident in its prediction | General-purpose; works well with most classifiers |
| Query by committee | Train multiple models and select examples where they disagree most | When ensemble methods are feasible |
| Density-weighted sampling | Combine uncertainty with data density so that selected points are both uncertain and representative | When the unlabeled pool has uneven distributions |
| Expected model change | Select examples that would cause the largest update to model parameters if labeled | Computationally expensive but effective for small budgets |
Efficiency gains
When applied effectively, active learning can substantially reduce the number of labels needed compared with random sampling, though reported savings vary widely by task and dataset. Amazon SageMaker Ground Truth used active learning to automatically label high-confidence examples and route only uncertain ones to human annotators, which AWS said could reduce labeling costs by up to 70%; AWS closed the service to new customers on July 30, 2026.[8][28]
Synthetic data as an alternative
Synthetic data refers to artificially generated data that mimics the statistical properties of real-world data. It can supplement or partially replace manually labeled data in some training scenarios.
Advantages
Synthetic data generation eliminates manual annotation costs after the initial setup. Once a generation pipeline is built (using 3D rendering engines, generative adversarial networks, or diffusion models), producing additional labeled examples costs almost nothing per unit. Synthetic data also avoids privacy concerns, since no real individuals appear in the generated examples. This is especially valuable in healthcare and finance, where real data is subject to strict regulations.
Gartner has forecast that by 2030, synthetic data will be more widely used for AI training than real-world datasets.[16]
Limitations
Synthetic data can introduce distribution gaps. Models trained exclusively on synthetic examples sometimes fail when encountering real-world data that differs from the generated distribution. For this reason, synthetic data works best as a supplement to real labeled data, not a full replacement. Benchmarking against real-world test sets remains necessary to validate performance.
Simulation environments (such as those used for training autonomous driving models) can generate millions of labeled frames, but the visual fidelity and scenario diversity of these simulations must be carefully managed to avoid training models on unrealistic conditions.
Can LLMs label their own training data?
The rise of large language models has opened new possibilities for automating parts of the labeling process. Rather than relying solely on human annotators, teams can use LLMs to generate initial labels that humans then review and correct.
Performance of LLMs as annotators
A study by Refuel AI found that GPT-4 achieved 88.4% agreement with ground truth labels across a range of text classification datasets, compared to 86.2% for skilled human annotators on the same tasks.[9] These results suggest that LLMs can match or exceed skilled human annotators for certain text labeling tasks, though expert-level performance on specialized domains still requires human oversight.
Weak supervision and data programming
Weak supervision, pioneered by the Snorkel project at Stanford University (started in 2015), takes a programmatic approach to labeling.[2] Instead of annotating examples one by one, users write labeling functions: simple programs that apply heuristic rules, keyword matches, or external knowledge bases to assign noisy labels.[2] Snorkel's system then combines the outputs of many labeling functions, automatically learning each function's accuracy and correcting for correlations between them.[2]
This approach is much faster than manual annotation. In evaluations, subject matter experts using Snorkel built models 2.8 times faster and achieved 45.5% higher predictive performance compared to seven hours of hand labeling alone.[2]
Human-in-the-loop workflows
The most effective modern labeling pipelines combine LLM predictions with human review. A common pattern:
- An LLM generates labels for the full dataset.
- A confidence score is computed for each label.
- High-confidence labels are accepted automatically.
- Low-confidence or ambiguous labels are routed to human annotators.
This hybrid approach lets teams accept most confident labels automatically and reserve human effort for the difficult cases.
How much does data labeling cost?
Data labeling costs vary widely depending on task complexity, annotator expertise, data modality, and quality requirements.
Cost ranges by task type
| Task type | Cost per annotation | Notes |
|---|---|---|
| Image classification (binary) | $0.01 to $0.05 | Simple yes/no or category assignment |
| Bounding box annotation | $0.05 to $0.50 | Depends on number of objects per image |
| Semantic segmentation | $0.50 to $7.00 | Pixel-level labeling is labor-intensive |
| Text classification | $0.02 to $0.10 | Sentiment, topic, spam detection |
| Named entity recognition | $0.10 to $1.00 | Varies with entity density and domain |
| Audio transcription | $0.50 to $3.00 per minute | Higher for noisy audio or specialized vocabulary |
| RLHF preference comparison | $1.00 to $100 per example | Depends on response length and required expertise |
| Medical image annotation | $2.00 to $50.00 | Requires trained radiologists or pathologists |
Total project costs
A typical computer vision model might require 100,000 labeled images. At $0.50 to $5.00 per annotation, the direct labeling cost alone ranges from $50,000 to $500,000. This does not include project management, quality assurance overhead, tool licensing, or iteration costs when labeling guidelines change mid-project.
Market size
The global data collection and labeling market was valued at approximately $3.77 billion in 2024, according to Grand View Research, and is projected to reach $17.1 billion by 2030 at a compound annual growth rate of about 28%.[10] Estimates vary by scope: Mordor Intelligence puts the narrower data labeling market at around $2.6 billion in 2026, growing at roughly 22% annually, while Grand View's broader "data labeling solution and services" segment was valued near $18.6 billion in 2024.[10] Across definitions, the analysts agree on the direction: growth is driven by AI adoption in autonomous vehicles, healthcare, and financial services, and above all by the rising demand for human feedback data to train and align large language models.[10]
What are the ethical concerns of data labeling?
Data labeling work raises several ethical questions. Much of the labor is performed by workers in lower-income countries who are paid per task at rates that can fall below local minimum wages. The 2018 study of Amazon Mechanical Turk found a median hourly wage of roughly $2 per hour for workers on the platform.[3] Time magazine reported in 2023 on Kenyan workers who labeled harmful content for OpenAI's safety filters at wages of less than $2 per hour.[11]
Annotators who label content moderation data (violent images, hate speech, graphic material) are exposed to psychologically distressing material.[11] Some companies have introduced wellness programs and content rotation policies to mitigate harm, but standards vary across the industry.
Bias in labeled data is another concern. If annotators bring systematic biases to their labeling decisions (for example, associating certain names with particular demographics), those biases will be encoded in the training data and reproduced by the model. Careful guideline design, diverse annotator pools, and bias auditing of completed datasets are standard mitigation strategies.
Future directions
Several trends are shaping the evolution of data labeling:
- Foundation model pre-labeling. Models like Meta's Segment Anything Model (SAM) can pre-segment images with zero-shot accuracy, leaving human annotators to verify and correct rather than draw from scratch.[15] This accelerates image annotation workflows considerably.
- Continuous labeling in MLOps. Labeling is increasingly treated as an ongoing part of the ML lifecycle rather than a one-time task. Errors and distribution shifts detected in production feed back into the labeling pipeline, creating a continuous loop of improvement.
- Multimodal annotation. As multimodal AI models become more common, annotation tasks increasingly span multiple data types simultaneously (for example, labeling both the visual content and the spoken dialogue in a video).
- Regulatory requirements. The EU AI Act and similar regulations may require documentation of training data provenance and labeling procedures, creating new compliance demands for labeling workflows.
- Self-supervised and semi-supervised alternatives. Techniques like self-supervised learning and semi-supervised learning reduce (but do not eliminate) dependence on labeled data by leveraging large amounts of unlabeled data during pre-training.
Continue reading
- LabelIn machine learning, a label is the target output value associated with a single training example: the correct answer that a supervised learning model is trained to predict.Mentioned 32 times above
- Reinforcement Learning from Human Feedback (RLHF)Reinforcement learning from human feedback (RLHF) is a family of methods in which judgments supplied by people are converted into a reward signal and a policy is optimized with reinforcement learning against…Mentioned 13 times above
- Active LearningActive learning is a subfield of machine learning in which the learning algorithm interactively chooses which data points it wants labeledMentioned 10 times above
- Scale AIScale AI is a San Francisco-based artificial intelligence company founded in 2016 by Alexandr Wang and Lucy Guo.Mentioned 9 times above
- Supervised LearningSupervised learning is a machine learning paradigm in which a model is fitted to examples that pair an input with an observed target.Mentioned 4 times above
- Computer VisionComputer vision is the study of computational methods that extract, estimate, or generate useful representations from visual measurements.Mentioned 4 times above
More from See also
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6Ouyang, L., et al. "Training language models to follow instructions with human feedback." *Advances in Neural Information Processing Systems* 35 (2022). (InstructGPT paper) arxiv.org/...2203.02155
- ^1 ^2 ^3 ^4Ratner, A., et al. "Snorkel: Rapid Training Data Creation with Weak Supervision." *Proceedings of the VLDB Endowment* 11, no. 3 (2017).
- ^1 ^2Hara, K., et al. "A Data-Driven Analysis of Workers' Earnings on Amazon Mechanical Turk." *Proceedings of the 2018 CHI Conference on Human Factors in Computing Systems* (2018).
- ^Landis, J. R., and Koch, G. G. "The Measurement of Observer Agreement for Categorical Data." *Biometrics* 33, no. 1 (1977): 159-174.
- ^1 ^2Cohen, J. "A Coefficient of Agreement for Nominal Scales." *Educational and Psychological Measurement* 20, no. 1 (1960): 37-46.
- ^1 ^2Fortune. "Exclusive: Scale AI secures $1B funding at $14B valuation." May 21, 2024.
- ^1 ^2CNBC. "Amazon, Meta back Scale AI in $1 billion funding deal that values firm at $14 billion." May 21, 2024.
- ^Amazon Web Services. "Amazon SageMaker Ground Truth: Build Highly Accurate Datasets and Reduce Labeling Costs by up to 70%." AWS Blog.
- ^Refuel AI. "LLMs can structure data as well as humans, but 100x faster." Technical report, June 14, 2023. refuel.ai/...llm-labeling-technical-report
- ^1 ^2 ^3 ^4Grand View Research. "Data Collection And Labeling Market Size Report, 2030." (2025); Mordor Intelligence. "Data Labeling Market Size, Competitive Landscape 2025-2031."
- ^1 ^2Perrigo, B. "Exclusive: OpenAI Used Kenyan Workers on Less Than $2 Per Hour to Make ChatGPT Less Toxic." *Time*, January 18, 2023. time.com/...openai-chatgpt-kenya-workers
- ^1 ^2 ^3Label Studio documentation. labelstud.io.
- ^1 ^2 ^3 ^4 ^5CVAT documentation. cvat.ai.
- ^1 ^2 ^3Explosion AI. "Prodigy: A new tool for radically efficient machine teaching." explosion.ai.
- ^Kirillov, A., et al. "Segment Anything." *Proceedings of the IEEE/CVF International Conference on Computer Vision* (2023).
- ^Gartner. "Is Synthetic Data the Future of AI?" Press release, June 22, 2022. gartner.com/...-is-synthetic-data-the-future-of-ai
- ^1 ^2 ^3Wikipedia. "Amazon Mechanical Turk." Accessed March 2026.
- ^1 ^2 ^3Wikipedia. "Scale AI." Accessed March 2026.
- ^1 ^2 ^3CNBC. "Scale AI's Alexandr Wang confirms departure for Meta as part of $14.3 billion deal." June 12, 2025. cnbc.com/...-exit-for-meta-part-of-14-billion-deal
- ^1 ^2 ^3 ^4 ^5 ^6Sacra. "Surge AI revenue, funding & news." (2025); Reuters reporting on Surge AI fundraise, July 2025.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7CNBC. "AI startup Mercor now valued at $10 billion with new $350 million funding round." October 27, 2025. cnbc.com/...ai-hiring-startup-mercor-funding; TechCrunch. "Mercor quintuples valuation to $10B with $350M Series C." October 27, 2025. techcrunch.com/...uation-to-10b-with-350m-series-c; TechCrunch. "Turing, a key coding provider for OpenAI and other LLM producers, raises $111M at a $2.2B valuation." March 6, 2025. techcrunch.com/...-raises-111m-at-a-2-2b-valuation
- ^1 ^2Fortune. "OpenAI is phasing out Scale AI work following startup's Meta deal." June 19, 2025; TechCrunch. "Google reportedly plans to cut ties with Scale AI." June 14, 2025.
- ^SignalFire. "Why expert data is becoming the new fuel for AI models." (2025). signalfire.com/...t-data-is-new-fuel-for-ai-models
- ^1 ^2Scale AI. "Scale AI Announces Next Phase of Company's Evolution." June 12, 2025. scale.com/...unces-next-phase-of-company-evolution
- ^Scale AI. "Scale AI Appoints Francis deSouza as CEO to Lead Next Phase of Company's Growth." July 30, 2026. scale.com/...scale-appoints-new-ceo
- ^CNBC. "OpenAI is winding down its work with Scale AI, whose founder is joining Meta." June 18, 2025. cnbc.com/...-with-scale-ai-founder-is-joining-meta
- ^1 ^2 ^3CNBC. "Scale AI's life after Meta deal has been rocky, but CFO insists it's not a 'zombie company'." November 4, 2025. cnbc.com/...as-been-rocky-cfo-insists-not-a-zombie
- ^1 ^2The Decoder. "Amazon sunsets Mechanical Turk, the original 'Artificial Artificial Intelligence'." July 6, 2026. the-decoder.com/...ificial-artificial-intelligence
- ^The Next Web. "Amazon is closing Mechanical Turk, the human workforce it sold as AI." August 26, 2026. thenextweb.com/...ical-turk-closing-september-2026
- ^HumanSignal. "Pricing." Retrieved November 2026. humansignal.com/pricing
- ^CVAT.ai. "CVAT celebrates seven-year anniversary." cvat.ai/...cvat-celebrates-seven-year-anniversary
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
9 revisions · v9 · 5,877 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (120 claims, 38 sources fetched); 8 material + 29 minor fixed
Cite this page: AI Wiki. "Data labeling." aiwiki.ai, updated 28 Oct 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/data_labeling