

Diffusion Language Models
Diffusion language models (DLMs, sometimes written dLLMs at frontier scale) are text generators that synthesize a sequence by iteratively denoising or unmasking many tokens in parallel, rather than predicting one token at a time left to right the way conventional autoregressive models do. They are a family of generative models for text that reverse a stochastic corruption process: where large language models such as the gpt family or llama 3 are causal systems that factor the joint probability of a sequence into a product of left-to-right conditionals, diffusion language models instead start from a fully corrupted or masked sequence and iteratively denoise it, refining many positions in parallel at each step. The approach inherits its mathematical scaffolding from the continuous-space diffusion models used for images, such as ddpm, adapted to either continuous word-embedding spaces or to discrete token spaces with absorbing or uniform corruption.[1][2][3]
The motivation for studying diffusion language models has shifted over time. Early work in 2021 and 2022 was driven by the desire for controllable generation and for an alternative to the strict left-to-right factorization of autoregressive models. By 2024 the focus had moved to closing the likelihood gap with autoregressive baselines and to the demonstration that masked discrete diffusion is a competitive paradigm at scale. In 2025 the field reached a scale milestone with LLaDA, an 8 billion parameter masked diffusion model trained from scratch that its authors describe as competitive with LLaMA3 8B, and a commercial milestone with Mercury from Inception Labs, which the company billed as the first commercial-scale diffusion-based language model. Additional 2025 releases including Block Diffusion (BD3-LM) from Cornell, Dream 7B from the University of Hong Kong and Huawei Noah's Ark Lab, ByteDance's high-speed Seed Diffusion, and Google DeepMind's experimental Gemini Diffusion consolidated the case that diffusion can serve as a credible substitute for next-token prediction in many production settings. By late 2025 and early 2026 the line had reached the mixture-of-experts regime with LLaDA-MoE and the 100-billion-parameter LLaDA 2.0 family from Ant Group, and a second commercial generation with Mercury 2, billed by Inception Labs as the first reasoning-capable diffusion model.[1][4][5][6] In 2026 the adaptation line reached NVIDIA, whose open-weight Nemotron-Labs-TwoTower (June 2026) freezes a pretrained 30-billion-parameter autoregressive backbone as a context tower and trains a second copy of it as a diffusion denoiser, and block diffusion found a second job as the draft model inside speculative decoding for autoregressive models through DFlash and DSpark.[20][26][29] Google released an open-weight text diffusion model, DiffusionGemma, in June 2026, and in the autumn of 2026 Inception shipped Mercury 2.5 (September 8), which it called, to its knowledge, the largest diffusion language model ever trained, and Mercury 3 (October 19), which it says is more than 40 times larger than Mercury 1.[52][55][60]
This article surveys the technical foundations of diffusion language models, traces the principal research lines from D3PM (2021) through Diffusion-LM (2022), SEDD (2024), MDLM and MD4 (2024), the autoregressive-to-diffusion adaptation line (DiffuLLaMA, 2024), LLaDA and LLaDA 1.5 (2025), Block Diffusion (2025), Mercury and Mercury 2 (2025 to 2026), Dream 7B (2025), Seed Diffusion (2025), Gemini Diffusion (2025), the mixture-of-experts scaling work of LLaDA-MoE and LLaDA 2.0 (2025) and its LLaDA 2.1, LLaDA 2.2 and LLaDA MoE v2 successors (2026), Radical Numerics' RND1 (2025), Google's DiffusionGemma (2026), Mercury 2.5 and Mercury 3 (2026), NVIDIA's TwoTower and Nemotron-Labs-Diffusion releases (2026), and the block-diffusion draft models DFlash and DSpark (2026), and discusses the speed and quality trade-offs that distinguish them from autoregressive systems built on the transformer architecture.
The principal systems surveyed below are summarized in the following catalog. Speed figures are vendor- or author-reported and are measured on different hardware and workloads, so they are not directly comparable; they are reproduced here with their attributions.
| System | Origin | Year | Type | Open weights | Headline claim (as reported) |
|---|---|---|---|---|---|
| Diffusion-LM | Stanford | 2022 | Continuous (embedding) | Yes | Early continuous diffusion LM; fine-grained controllable generation[2] |
| Plaid | Stanford | 2023 | Continuous (embedding) | Yes | Plaid 1B beats GPT-2 124M in likelihood (author-reported)[8] |
| SEDD | Stanford | 2024 | Discrete (score entropy) | Yes | ICML 2024 Best Paper; near GPT-2 perplexity[3] |
| MDLM / MD4 | Cornell / Google DeepMind | 2024 | Discrete (masked) | Yes | Simplified masked-diffusion recipe at GPT-2 scale[9][10] |
| DiffuGPT / DiffuLLaMA | HKU et al. | 2024 | Discrete (masked, AR-adapted) | Yes | Converts GPT-2/LLaMA to diffusion with under 200B tokens[13] |
| LLaDA 8B | Renmin University / Ant Group | 2025 | Discrete (masked) | Yes | Competitive with llama 3 8B (author-reported); NeurIPS 2025 Oral[4][67] |
| LLaDA 1.5 | Renmin University / Ant Group | 2025 | Discrete (masked) + VRPO | Yes | Adds preference-optimization alignment to LLaDA[14] |
| LLaDA-MoE | Ant Group / Renmin University | 2025 | Discrete (masked) MoE | Yes | Billed as the first open-source MoE dLLM; 7B total / 1.4B active[15][46] |
| LLaDA 2.0 | Ant Group (InclusionAI) | 2025 | Discrete (masked) MoE | Yes | Scales dLLMs to 100B total parameters[16] |
| Block Diffusion (BD3-LM) | Cornell | 2025 | Hybrid (block) | Yes | ICLR 2025 Oral; interpolates AR and diffusion[6] |
| Dream 7B | HKU / Huawei Noah's Ark | 2025 | Discrete (masked, AR-init) | Yes | Billed by its authors as the most powerful open dLLM at release (April 2025)[12][57] |
| Seed Diffusion | ByteDance Seed | 2025 | Discrete (masked) | No | ~2,146 tok/s on H20 for code (author-reported)[17] |
| RND1 | Radical Numerics | 2025 | Discrete (masked MoE, AR-converted) | Yes | 30B total / 3B active, converted from Qwen3-30B-A3B (author-reported)[62] |
| Mercury Coder | Inception Labs | 2025 | Commercial (discrete diffusion; details undisclosed) | No | ~1,109 tok/s on H100 (Artificial Analysis figure reported by Inception)[5][7] |
| Gemini Diffusion | Google DeepMind | 2025 | Experimental demo (block) | No | ~1,479 tok/s plus 0.84 s overhead; benchmarked against Gemini 2.0 Flash-Lite (vendor-reported)[18] |
| Mercury 2 | Inception Labs | 2026 | Commercial, reasoning | No | ~1,009 tok/s on Blackwell; reasoning dLLM (vendor-reported)[19] |
| LLaDA 2.1 | Ant Group (InclusionAI) | 2026 | Discrete (masked) MoE + token editing | Yes | 16B mini / 100B flash; 892 TPS on HumanEval+ for the 100B model (author-reported)[34] |
| DFlash / DFlash 2 | z-lab / Inco AI | 2026 | Block-diffusion draft model | Yes | Lossless speculative drafting; "over 6x" acceleration claimed (author-reported)[26][27] |
| DiffusionGemma | Google DeepMind | 2026 | Block diffusion (AR encoder + bidirectional decoder) MoE | Yes | 25.2B total / 3.8B active; "up to 4x faster" generation on dedicated GPUs (Google-reported)[60][61] |
| Nemotron-Labs-TwoTower | NVIDIA | 2026 | Hybrid (block); frozen AR context tower + trained diffusion denoiser | Yes | 30B-A3B backbone; 98.7% of AR quality at 2.42x throughput (NVIDIA-reported)[20][22] |
| Nemotron-Labs-Diffusion | NVIDIA | 2026 | Tri-mode (AR, diffusion, self-speculation) | Yes | 3B/8B/14B; 8B decodes 6x more tokens per forward pass than Qwen3-8B (NVIDIA-reported)[24] |
| LLaDA 2.2 | Ant Group (InclusionAI) | 2026 | Discrete (masked) MoE + Levenshtein editing | Yes | Agent-oriented; 128K context; 519 TPS on SWE-bench Verified (author-reported)[35] |
| LLaDA MoE v2 | Renmin University / Ant Group | 2026 | Discrete (masked) MoE, from scratch | Yes | 30B-A3B trained on 23.5T tokens; approaches Qwen3 on several benchmarks (author-reported)[47][48] |
| Mercury 2.5 | Inception Labs | 2026 | Commercial, reasoning | No | 1,107 tok/s; "largest diffusion language model ever trained" (vendor claim)[52] |
| Mercury 3 | Inception Labs | 2026 | Commercial, reasoning | No | 1,068 tok/s; 1M context; over 40x Mercury 1's parameters (vendor-reported)[55][56] |
How do diffusion language models work?
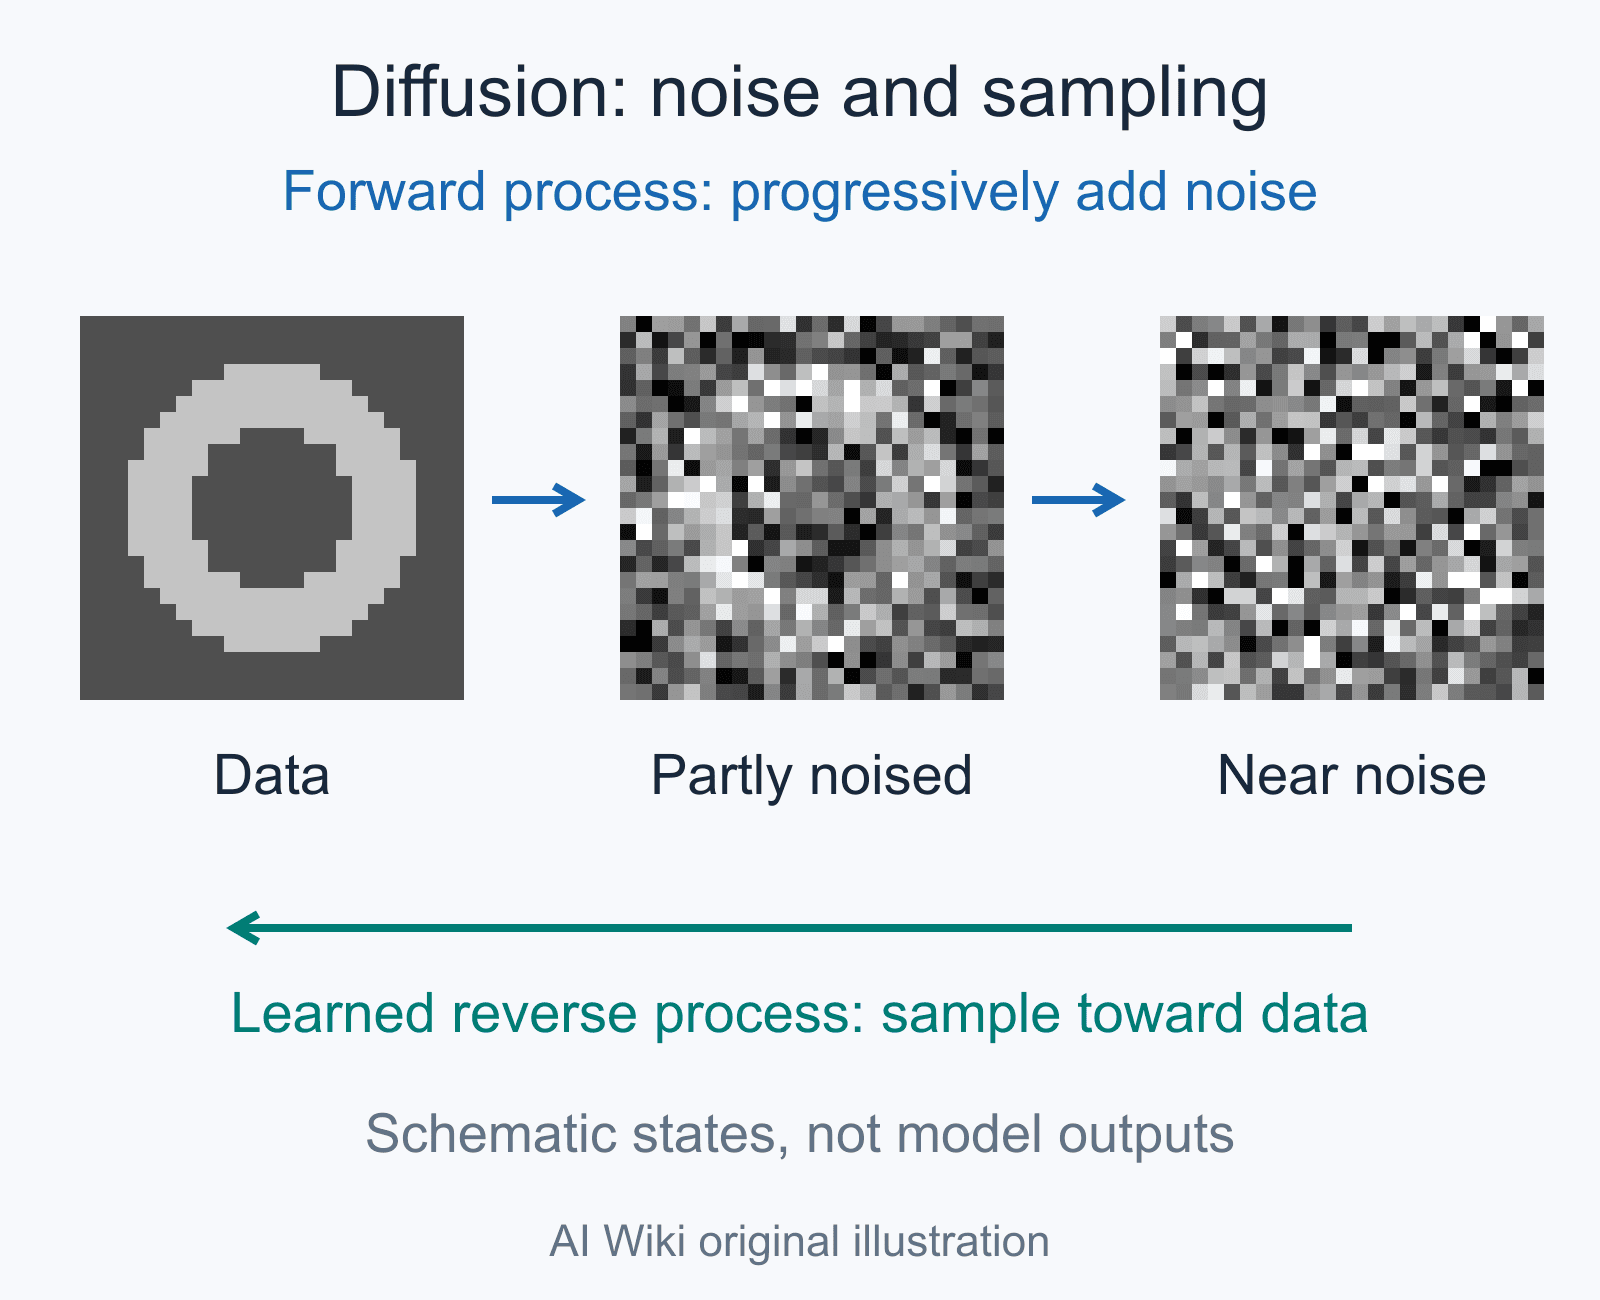
A diffusion language model is defined by a forward corruption process that gradually destroys a clean text sequence and a learned reverse process that undoes the corruption. In discrete masked diffusion, the dominant modern form, the forward process progressively replaces real tokens with a special mask symbol until the sequence is fully masked, and a transformer is trained to predict the original tokens at masked positions given the partially masked sequence. Generation runs the reverse process: starting from an all-mask sequence, the model fills in tokens over a chosen number of denoising steps, unmasking many positions per step rather than emitting a single token per forward pass.[1][9] Because the network attends to the full sequence at every step without a causal mask, the same model can in principle revise any position at any step, which is what gives diffusion language models their parallel, order-agnostic character. The number of denoising steps is a tunable knob that trades latency against quality, a control surface that left-to-right decoding does not naturally expose.
Why use diffusion for text generation?
Two structural motivations drive interest in diffusion for language. The first is parallel decoding. An autoregressive transformer must produce tokens one at a time, paying the cost of a full forward pass through the model for each emitted token; this is the central bottleneck of long-form decoding and the reason why systems such as flash attention or speculative decoding receive so much engineering attention. A diffusion language model can in principle update every position in a sequence at every denoising step. Sampling is therefore a function of the number of denoising steps and the per-step cost, not of the sequence length, which allows trade-offs between latency and quality that the autoregressive paradigm does not naturally expose. Mercury Coder Mini, for example, reports throughput of approximately 1,109 tokens per second on NVIDIA H100 GPUs (an Artificial Analysis measurement of Inception's API), and Inception describes its Mercury Coder models as up to 10x faster on average than speed-optimized frontier models of comparable quality.[5][7]
The second motivation is controllability. Because a diffusion sampler maintains a representation of the entire sequence at every step, classifier-guided or gradient-based control can be applied to that representation in much the way it is applied to images in continuous diffusion. Diffusion-LM, an early and widely cited continuous diffusion model for text, was introduced specifically to demonstrate fine-grained controllable generation, and subsequent work has explored infilling, length control, and global constraints that are awkward to express in left-to-right decoding.[2]
A third, more recent motivation is bidirectional reasoning. Autoregressive models are notoriously susceptible to the so-called reversal curse: a model that learns "A is B" during pretraining does not reliably answer the reverse question "B is A?" without explicit data. Because a masked diffusion model does not assume a fixed token ordering during training, it can produce predictions in arbitrary orders. On the LLaDA paper's poem completion task, LLaDA 8B Instruct scores 51.8 in the forward direction and 45.6 in the reversal direction, while gpt 4o drops from 82.7 forward to 34.3 reversal; LLaDA therefore trails GPT-4o going forward but beats it in reverse, and the authors attribute its balanced scores to treating tokens uniformly, without a left-to-right inductive bias.[4]
Continuous diffusion: Diffusion-LM and Plaid
Diffusion on discrete text had already appeared in 2021: D3PM (described below), which generalizes the multinomial diffusion model of Hoogeboom et al., reported character-level text generation and LM1B results.[1] The best-known early continuous approach is Diffusion-LM by Xiang Lisa Li, John Thickstun, Ishaan Gulrajani, Percy Liang, and Tatsunori B. Hashimoto, posted to arXiv in May 2022 and published at NeurIPS 2022.[2] Diffusion-LM adapts the Gaussian diffusion machinery developed for images to text by embedding discrete tokens into a continuous space, running the forward Gaussian corruption process on those embeddings, and learning a denoising network that reverses it. A learned rounding step maps the final denoised vectors back to tokens. The principal experimental result was on six fine-grained controllable generation tasks, where Diffusion-LM significantly outperformed gpt-2 based plug-and-play and fine-tuning baselines by applying classifier guidance directly to the continuous latent variables. It also functioned as a proof of concept that continuous diffusion in embedding space can produce fluent, fixed-length text.[2]
The continuous embedding approach was scaled and refined by Plaid (Likelihood-Based Diffusion Language Models) from Ishaan Gulrajani and Tatsunori B. Hashimoto, presented at NeurIPS 2023. The authors set out to close the likelihood gap with autoregressive models, introduced training recipes oriented around maximum likelihood rather than denoising quality alone, studied compute-optimal scaling, and released Plaid 1B, which they report outperforms GPT-2 124M in likelihood on benchmark datasets.[8] The large diffusion language models of 2024-2026 described below (MDLM, LLaDA, Dream, Mercury) are discrete rather than continuous, operating directly on tokenizer vocabularies.
Discrete diffusion: D3PM and the absorbing-state objective
The discrete diffusion line begins with D3PM, short for "Structured Denoising Diffusion Models in Discrete State-Spaces," published at NeurIPS 2021 by Jacob Austin, Daniel D. Johnson, Jonathan Ho, Daniel Tarlow, and Rianne van den Berg.[1] D3PM generalizes the DDPM forward process from Gaussian noise on continuous tensors to Markov transition matrices on discrete tokens. Instead of adding noise to coordinates, the forward chain probabilistically swaps tokens for other tokens, including a designated "mask" token. By selecting different transition matrices, D3PM unifies several corruption strategies: uniform random replacement, swap to nearest-neighbor tokens in an embedding space, and absorbing-state replacement in which any token can be replaced by a special mask symbol but the mask itself never reverts.[1]
The absorbing-state variant is particularly important because it draws a formal connection between diffusion and masked language modeling. As Austin et al. observe, when the forward process only ever masks tokens, the reverse process is exactly trained to predict masked positions, which is the BERT-style objective up to a choice of masking schedule. The connection clarifies that bert and its descendants can be viewed as one-step approximations to absorbing-state diffusion, and conversely that masked diffusion models generalize masked language models by iterating the denoising step many times to support generation.[1] D3PM also showed that autoregressive models emerge from a deterministic left-to-right masking schedule, placing the three paradigms (autoregressive, masked, diffusion) on a single spectrum.
Score Entropy Discrete Diffusion (SEDD)
A second major step came in 2024 with SEDD, "Discrete Diffusion Modeling by Estimating the Ratios of the Data Distribution," by Aaron Lou, Chenlin Meng, and Stefano Ermon, which received the Best Paper award at ICML 2024.[3] SEDD addresses a longstanding theoretical obstacle: standard score matching, which is the workhorse loss for continuous diffusion, does not naturally apply to discrete spaces because there is no gradient of the log density to estimate.
Lou et al. introduced a new loss called score entropy that extends score matching to discrete spaces by estimating ratios of the data distribution rather than gradients of its logarithm. The score entropy loss provides a principled and computationally tractable training objective for discrete diffusion models with general (not just absorbing) corruption processes. Empirically, SEDD reduced perplexity by 25 to 75 percent relative to prior discrete diffusion baselines at comparable scales, and obtained roughly six to eight times better unconditional generative perplexity than an unannealed gpt-2. The authors describe SEDD as competitive with autoregressive models at comparable sizes, "in particular outperforming GPT-2," and report that it can match its own quality with 32 times fewer network evaluations.[3]
The Masked Diffusion framework: MDLM and MD4
Building on D3PM's absorbing-state insight and SEDD's tractable training, two NeurIPS 2024 papers refined the masked diffusion framework into something close to a unified recipe. The first, MDLM (Simple and Effective Masked Diffusion Language Models) by Subham Sekhar Sahoo, Marianne Arriola, Yair Schiff, Aaron Gokaslan, Edgar Marroquin, Justin T. Chiu, Alexander Rush, and Volodymyr Kuleshov, presents a substitution-based parameterization that reduces the absorbing-state diffusion variational bound to a mixture of standard masked language modeling cross-entropy losses with appropriate weights.[9] The MDLM paper also derives a Rao-Blackwellized objective that further reduces variance during training. With these simplifications and modern engineering practices, the authors report a new state of the art among diffusion models on language modeling benchmarks and perplexity that approaches that of autoregressive models.[9]
The second, MD4 (Simplified and Generalized Masked Diffusion for Discrete Data) by Jiaxin Shi, Kehang Han, Zhe Wang, Arnaud Doucet, and Michalis K. Titsias, generalizes the same family. MD4 shows that the continuous-time variational objective for masked diffusion is a simple weighted integral of cross-entropy losses, supports state-dependent masking schedules, and reports state-of-the-art discrete diffusion results that exceed autoregressive likelihood on pixel-level image modeling and surpass prior diffusion language models on four out of five zero-shot language tasks at GPT-2 scale.[10] Together MDLM and MD4 cemented masked diffusion as the dominant practical instantiation of discrete diffusion for text, and provided the simplified training recipes that LLaDA, Mercury, and Dream all build upon.
Adapting autoregressive models: DiffuGPT and DiffuLLaMA
Training a large diffusion language model from scratch is expensive, so a parallel research line asks whether an existing pretrained autoregressive checkpoint can be cheaply converted into a diffusion model. The reference result is DiffuGPT and DiffuLLaMA, presented in "Scaling Diffusion Language Models via Adaptation from Autoregressive Models" by Shansan Gong, Shivam Agarwal, Yizhe Zhang, Jiacheng Ye, Lin Zheng, Mukai Li, Chenxin An, Peilin Zhao, Wei Bi, Jiawei Han, Hao Peng, and Lingpeng Kong, submitted in October 2024 and accepted at ICLR 2025.[13] The work converts gpt-2 and LLaMA base models, spanning parameter sizes from 127M to 7B, into masked diffusion models using fewer than 200 billion tokens of continued training; DiffuLLaMA in particular was adapted from LLaMA-2 7B on a mixture of SlimPajama and Starcoder data. The authors report that the resulting models outperform earlier diffusion language models and are competitive with their autoregressive counterparts, while acquiring diffusion-native abilities such as filling in the middle of a sequence without reordering the prompt. The AR-adaptation idea was influential: Dream 7B and the later LLaDA 2.0 family both initialize from autoregressive checkpoints rather than training the diffusion model from a random start.[13]
LLaDA: an 8B diffusion model trained from scratch
In February 2025 came LLaDA, "Large Language Diffusion Models," by Shen Nie, Fengqi Zhu, Zebin You, Xiaolu Zhang, Jingyang Ou, Jun Hu, Jun Zhou, Yankai Lin, Ji-Rong Wen, and Chongxuan Li from the Gaoling School of Artificial Intelligence at Renmin University of China and Ant Group; the paper was posted to arXiv on February 14, 2025 and presented as an oral at NeurIPS 2025.[4][67] LLaDA is a masked discrete diffusion model whose architecture is a standard decoder-only transformer without causal masking, trained with a forward masking process and a reverse generation process that predicts masked tokens. The training and SFT pipeline closely mirrors a conventional large language model recipe, with diffusion appearing only in the loss and at sampling time.
LLaDA 8B was pretrained from scratch on 2.3 trillion tokens using approximately 0.13 million H800 GPU-hours and then fine-tuned on 4.5 million SFT pairs; the authors trained 1B and 8B variants and released the 8B Base and Instruct checkpoints. They describe the 8B base model as "overall competitive" with LLaMA3 8B Base: it leads on math and Chinese benchmarks and trails on others such as BBH, ARC-C, HellaSwag and MBPP. On MMLU LLaDA 8B scores 65.9 versus 65.4 for LLaMA3 8B Base; on GSM8K it scores 70.3 versus 48.7; on MATH it scores 31.4 versus 16.0; and on HumanEval it scores 35.4 versus 34.8.[4] After supervised fine-tuning the model exhibits competitive multi-turn dialogue, instruction following, and the previously discussed reversal-curse behavior. The headline contribution of LLaDA is not any single benchmark number but the evidence that the diffusion paradigm scales: the authors describe the work as scaling language diffusion "to an unprecedented" size of 8B for a model trained from scratch (DiffuLLaMA had reached 7B four months earlier, but by adapting LLaMA 2 rather than training from scratch).[4][13] The authors state that "LLaDA 8B is competitive with strong LLMs like LLaMA3 8B in in-context learning and, after SFT, exhibits impressive instruction-following abilities in case studies such as multi-turn dialogue."[4] Follow-up work from the same group extended LLaDA to vision-language inputs (LLaDA-V, May 2025, which adds a vision encoder and MLP connector to LLaDA) and to preference alignment (LLaDA 1.5, below).[45][14]
The LLaDA family: LLaDA 1.5, LLaDA-MoE, and LLaDA 2.0
The original LLaDA was aligned with supervised fine-tuning only, and the same group released a series of successors that added preference optimization, sparse mixture-of-experts architectures, and frontier-scale parameter counts.
LLaDA 1.5, "Variance-Reduced Preference Optimization for Large Language Diffusion Models" by Fengqi Zhu and colleagues (posted to arXiv in May 2025 and published at ACL 2026), addresses the difficulty of applying preference-based alignment to diffusion models. Because a diffusion model's likelihood is only available through a high-variance evidence-lower-bound (ELBO) estimate, naive Direct Preference Optimization is unstable. The authors introduce VRPO (Variance-Reduced Preference Optimization), a framework that analyzes the bias and variance of the preference loss and applies unbiased variance-reduction strategies including optimal Monte Carlo budget allocation and antithetic sampling. LLaDA 1.5 improves over the supervised-fine-tuning-only LLaDA baseline by reported margins of +4.7 on GSM8K, +3.0 on HumanEval, +1.8 on MBPP, +4.0 on IFEval, and +4.3 on Arena-Hard.[14]
LLaDA-MoE, "A Sparse MoE Diffusion Language Model" by Fengqi Zhu and colleagues from Ant Group and Renmin University (submitted September 2025), is described on its model card as the first open-source mixture-of-experts diffusion large language model, pretrained from scratch; its weights were published on Hugging Face on September 10, 2025.[46] It was pretrained on approximately 20 trillion tokens and uses a learned router to activate only about 1.4 billion of its roughly 7 billion total parameters per token, which keeps inference cost low while preserving the capacity of a larger model. The authors report state-of-the-art results among diffusion language models, surpassing LLaDA, LLaDA 1.5, and Dream, with the instruct-tuned variant described as comparable to Qwen2.5-3B-Instruct.[15]
LLaDA 2.0, "Scaling Up Diffusion Language Models to 100B" from the InclusionAI team at Ant Group (weights published on Hugging Face on November 25, 2025; technical report posted to arXiv on December 10, 2025), pushes the mixture-of-experts line to frontier scale by converting a pretrained autoregressive model into a diffusion model with a three-phase block-level training schedule. The release includes two instruction-tuned MoE variants: LLaDA 2.0-mini at 16 billion total parameters and LLaDA 2.0-flash at 100 billion total parameters with only about 6.1 billion activated per token. The authors report that LLaDA 2.0-flash outperforms open-source dense models of similar scale while reducing computational cost; at 100 billion total parameters it is, together with its 100B LLaDA 2.1 and LLaDA 2.2 flash successors, the largest of the open-weight diffusion language models described in this article.[16][32][33] The flash model card gives the split as 100 billion total and 6.1 billion activated parameters, continually trained from the autoregressive Ling 2.0 series.[33]
The InclusionAI team kept shipping through 2026. LLaDA 2.1, "Speeding Up Text Diffusion via Token Editing" (arXiv, February 9, 2026), adds token-to-token editing to the mask-to-token decoding scheme so that tokens already placed can be revised in later steps, exposed as a Speedy Mode (a low unmasking threshold, with editing repairing the output) and a Quality Mode (conservative thresholds); the paper also describes what it calls the first large-scale reinforcement learning framework tailored to diffusion LLMs and releases LLaDA2.1-Mini (16B) and LLaDA2.1-Flash (100B), reporting 892 tokens per second on HumanEval+ for the 100B model.[34] LLaDA2.0-Uni (April 22, 2026) put the 16B mini backbone behind a SigLIP-VQ discrete visual tokenizer and a diffusion image decoder for unified multimodal understanding and generation.[37] LLaDA 2.2 (LLaDA2.2-flash on July 16, 2026, LLaDA2.2-mini on September 5, 2026) is billed as the series' first agent-oriented release: it adds DELETE and INSERT control tokens ("Levenshtein editing") so that parallel decoding can change sequence structure, extends context to 128K tokens, bounds mixture-of-experts activation per diffusion block ("Block Routing"), and trains editing with an agentic reinforcement-learning objective the card calls L-EBPO. The flash card reports 49.28 on SWE-bench Verified with the Claude Code scaffold at 519 tokens per second, against 61.20 for the autoregressive Ling-2.6-flash it is compared with at 303.2 tokens per second; the mini variant keeps the 16B, 256-expert (8 active) LLaDA2.0-mini architecture.[35][36] All LLaDA 2.x weights are Apache-2.0 releases on Hugging Face.[33][35][36] The same backbone has been reused for applications: LLaDA-UI (arXiv, September 9, 2026) aligns a native-resolution vision encoder with LLaDA2.0-mini-base to build a 16.7-billion-parameter block-diffusion GUI agent, which its authors report outperforms Qwen2.5-VL-7B and surpasses Qwen3-VL-8B on four of six GUI benchmarks.[49]
The Renmin University group behind the original LLaDA returned to from-scratch training with LLaDA MoE v2 (arXiv 2608.03457, August 4, 2026). The paper fits scaling laws for mixture-of-experts diffusion models and reports that they differ quantitatively from autoregressive trends (the optimal batch size grows faster with compute, the optimal learning rate decays faster, and the optimal token budget grows slightly faster than activated model size). Guided by those fits, the authors trained a 30B-A3B model from scratch on 23.5 trillion tokens, about 65 percent of Qwen3's pretraining budget by their count, and report that it approaches Qwen3 on several knowledge, reasoning and coding benchmarks and, after supervised fine-tuning alone, beats SDAR Chat on seven of eight reasoning and coding benchmarks.[47] Base and Instruct checkpoints were published under Apache-2.0 on Hugging Face (GSAI-ML) on August 17-18, 2026.[48]
Mercury: Inception Labs' commercial diffusion language model
Where LLaDA established the research case for diffusion at scale, Mercury from Inception Labs established the commercial case. Inception Labs was founded by three researchers with deep credentials in diffusion modeling and language: Stanford professor Stefano Ermon (co-author of the SEDD paper), UCLA professor Aditya Grover, and Cornell professor Volodymyr Kuleshov (co-author of MDLM and Block Diffusion). The company launched Mercury Coder, billed as the first commercial-scale diffusion-based large language model, on February 26, 2025.[5][11] The $50M financing round led by Menlo Ventures, with participation from Andrew Ng and Andrej Karpathy, came later: Inception announced it on November 6, 2025 (the blog index dates Stefano Ermon's post November 7), in a post that described the round as "recently closed" and shipped an upgraded Mercury model at the same time, priced at $0.25 per million input tokens and $1.00 per million output tokens.[42] In its launch announcement, the company described it under the headline "Introducing Mercury, the World's First Commercial-Scale Diffusion Large Language Model," and stated that "our models run at over 1000 tokens/sec on NVIDIA H100s, a speed previously possible only using custom chips."[5]
Mercury Coder ships in Mini and Small variants. According to the technical report "Mercury: Ultra-Fast Language Models Based on Diffusion," Mercury Coder Mini achieves approximately 1,109 tokens per second on NVIDIA H100 GPUs, while Mercury Coder Small achieves approximately 737 tokens per second, in both cases roughly an order of magnitude faster than speed-optimized autoregressive frontier models of comparable quality.[7] These throughput figures come from Artificial Analysis measurements of Inception's API, and the report says Mercury Coder Small performs on par with speed-optimized models such as Claude 3.5 Haiku and Gemini 2.0 Flash while being much faster. On the Copilot Arena coding leaderboard, the report says, Mercury Coder Mini was tied for second place on quality, ahead of GPT-4o Mini, Gemini 1.5 Flash and GPT-4o, and had the lowest latency of the models listed.[7] Mercury and Mercury Coder became available through Amazon Bedrock Marketplace and Amazon SageMaker JumpStart on August 27, 2025, and Mercury was also offered on Azure AI Foundry.[50][51]
The Mercury report describes the underlying model as a transformer trained to predict multiple tokens in parallel with a weighted denoising diffusion loss; it says its methods extend the score-entropy work of Lou, Meng and Ermon (SEDD), that the models were trained on the order of trillions of tokens, and that they support a 32,768-token context out of the box (up to 128K with context extension). Serving relies on a proprietary inference engine with custom kernels. The report does not give parameter counts. Its design goal is to remove the strict sequential bottleneck of next-token prediction and exploit parallelism on existing GPU hardware.[7]
On February 24, 2026, Inception Labs announced Mercury 2, which it describes as the first reasoning-capable diffusion large language model. According to the company's launch materials, Mercury 2 generates output through parallel refinement rather than sequential decoding, runs at approximately 1,009 tokens per second on NVIDIA Blackwell GPUs, supports a 128K-token context window, and offers tunable reasoning. Inception positions it as more than 5 times faster (">5x" in the launch post) than leading speed-optimized autoregressive models while remaining competitive in quality, and prices it at $0.25 per million input tokens and $0.75 per million output tokens through an OpenAI-API-compatible endpoint. As with the first generation, the company does not disclose parameter counts. These figures are vendor-reported and have not been independently benchmarked here.[19]
Through the summer of 2026 Mercury 2 was extended rather than replaced. Inception's blog lists Mercury Edit 2, a next-edit-prediction diffusion model for coding assistants, on March 30, 2026 (its authors, Kenan Hasanaliyev and Reece Shuttleworth, report edits accepted 48 percent more often than the previous model's); Mercury 2 availability on Azure AI Foundry on June 24, 2026; and a July 29, 2026 update that raised the free allowance on new API keys from 10 million to 100 million tokens, reported lower time-to-first-token and more reliable tool calling, and added Baseten as a host.[38][39][40] On August 31, 2026, OpenRouter listed Mercury 2.5 (Preview) with a 260,000-token context at $0.04 per million input tokens and $0.15 per million output tokens.[41] Inception formally released Mercury 2.5 on September 8, 2026, in a post by CEO Stefano Ermon calling it "the most capable diffusion LLM on the market" and, "to our knowledge," "the largest diffusion language model ever trained" (no parameter count was given). The company reports a 40 percent increase in intelligence over Mercury 2, quality comparable to cost-optimized models such as GPT-5.6 Luna (Low), Gemini 3.5 Flash-Lite and Claude Haiku 4.5, 1,107 tokens per second on NVIDIA GPUs and a 260K context, at list prices of $0.20 and $0.75 per million input and output tokens (the OpenRouter figures match its 80 percent launch discount).[52] A voice-tuned variant previewed alongside it, Mercury Voice, became generally available for enterprise customers on September 29, 2026; Inception reports a median time to first answer token under 320 milliseconds on its customer-service test set.[53] On October 15, 2026, Inception announced that TIME had named Mercury 2 to its Best Inventions of 2026 list in the artificial intelligence category.[54]
On October 19, 2026, Inception released Mercury 3, which it calls "the most capable diffusion-based LLM released to date." The company says Mercury 3 has more than 40 times the total parameters of Mercury 1 (again without a parameter count), runs at 1,068 tokens per second on NVIDIA GPUs, supports a 1-million-token context, and is on par with or better than speed-optimized models such as GPT-6 Luna and Claude Haiku 5.5 while running 4 to 8 times faster; list prices are $0.20 and $0.70 per million input and output tokens, halved at launch. It is offered through Inception's API, OpenRouter, Baseten and Vercel.[55] Interesting Engineering's launch report presents these figures as the company's claims.[56] With the Mercury 3 launch, Inception closed Mercury 2 and Mercury 2.5 to new users; its models page says existing customers with usage before October 19, 2026 keep access until November 15, 2026, and enterprise customers remain supported under their agreements.[68]
Block Diffusion (BD3-LM, 2025)
Pure diffusion models suffer from two limitations relative to autoregressive systems: they cannot easily generate variable-length sequences, and they cannot reuse KV cache the way a standard transformer decoder can. Block Diffusion (BD3-LM, "Block Discrete Denoising Diffusion Language Models") was proposed to address both. The paper, by Marianne Arriola, Aaron Gokaslan, Justin T. Chiu, Zhihan Yang, Zhixuan Qi, Jiaqi Han, Subham Sekhar Sahoo, and Volodymyr Kuleshov, was accepted as an Oral at ICLR 2025.[6]
The core idea is to partition a token sequence into blocks and to model the joint distribution as an autoregressive product over blocks, with each block generated by a discrete diffusion process internally. When the block size equals the full sequence length, BD3-LM degenerates into a standard masked diffusion model; when the block size equals one, it degenerates into a standard autoregressive transformer. Intermediate block sizes interpolate smoothly between the two regimes, trading off sample efficiency (favored by autoregressive) against parallelism and controllability (favored by diffusion). The authors show that BD3-LM supports flexible-length generation, KV caching, and parallel sampling within each block, achieves state-of-the-art perplexity among diffusion language models, and effectively bridges the autoregressive and diffusion paradigms with a single architecture.[6] Block-wise generation became common in later large diffusion models: LLaDA 2.0 is trained with a block-level schedule, and Gemini Diffusion, DiffusionGemma and TwoTower all generate block by block.[16][18][21][61]
TwoTower: decoupled context and denoiser towers (NVIDIA, 2026)
Where Block Diffusion changed the factorization, NVIDIA's TwoTower changed the network. The paper "Nemotron-Labs-TwoTower: Diffusion Language Modeling with Pretrained Autoregressive Context" (arXiv 2606.26493, first version June 25, 2026, revised June 29) by Fitsum Reda, John Kamalu, Roger Waleffe, Mostofa Patwary, Mohammad Shoeybi, and Bryan Catanzaro starts from an observation the authors credit to Arriola et al.'s E2D2 (NeurIPS 2025): a diffusion language model does two different jobs at every denoising step, representing the clean tokens it already has and denoising the corrupted ones, and asking one decoder to do both "pulls the same set of weights in different directions."[20][21][23] E2D2 split the jobs into an encoder and a lightweight decoder but trained both with tied weights at up to 1.7 billion parameters; TwoTower asks whether a full split holds at 30 billion parameters on a hybrid Mamba-attention-MoE backbone.[21][23]
The recipe takes two copies of a pretrained autoregressive model. The context tower is the original network, frozen, run causally over the prompt and every committed token, so it keeps the backbone's KV cache and Mamba states and its full autoregressive ability. The denoiser tower is the second copy, trained with a masked-diffusion objective to fill a block of S masked positions in parallel, with bidirectional attention inside the block and cross-attention to the context tower's cache at the same layer index (layer i of the denoiser reads layer i of the context tower, rather than only a final hidden state). Mamba-2 layers in the denoiser are seeded from the context tower's state at the block boundary, and the denoiser is told the current noise level through adaptive layer normalization borrowed from image diffusion transformers, an addition of about 1.5 million parameters. Generation is block-autoregressive in the BD3-LM sense: the denoiser refines one block, the block is committed, the context tower advances its caches, and the next block starts.[21][22]
The released instantiation uses Nemotron 3 Nano 30B-A3B (52 layers: 23 Mamba-2, 6 self-attention, 23 mixture-of-experts), which NVIDIA pretrained on 25 trillion tokens. Only the denoiser is trained, in three stages on the backbone's own data blends (block size 32, then 32, then 16), and NVIDIA reports that at the default operating point (confidence-unmasking threshold 0.8, block size 16, BF16 on two H100 GPUs) the model retains 98.7 percent of the autoregressive baseline's aggregate benchmark quality at 2.42 times its wall-clock generation throughput. Per task, the model card lists MMLU 78.24 against 78.56 for the AR baseline, GSM8K 90.14 against 92.49, and HumanEval 75.58 against 79.27, so the cost lands mostly on code and math.[21][22] Two ablations carry the paper's argument for the design: tying the towers under a joint AR-plus-diffusion loss was "substantially worse" in both decoding modes than freezing the context tower and training a separate denoiser, and sampling with blocks larger than the training block collapses generative tasks (HumanEval falls from 76.40 at block size 16 to 19.85 at 64) while smaller blocks hold quality but cost throughput.[21]
The weights were published on Hugging Face as nvidia/Nemotron-Labs-TwoTower-30B-A3B-Base-BF16, a base checkpoint of roughly 60 billion parameters in total (both towers), under what the card calls the NVIDIA Nemotron Open Model License and marks "ready for commercial use"; the repository was created on April 11, 2026, and its commit log shows the rename from Nemotron-TwoTower to Nemotron-Labs-TwoTower on July 1, 2026, with the old repository id now redirecting to the new one.[22][44] Full diffusion decoding needs two 80 GB GPUs because both towers stay resident, although the sequence-length-dependent cache memory is the same as the backbone's.[21][22] NVIDIA's own token accounting is inconsistent: the abstract and results give about 2.1 trillion training tokens for the denoiser, while the training section says "roughly 1.4T tokens" across its two phases, and the documents do not reconcile the two. The card also reports "2 shared experts" and about 3 billion active parameters per tower where NVIDIA's Nemotron 3 Nano cards say one shared expert and 3.5 billion active.[21][22] As of September 6, 2026, the Hugging Face API reported 817 downloads and 142 likes for the repository; on October 31, 2026 it reported 742 downloads (Hugging Face's rolling 30-day count) and 149 likes, and NVIDIA's Hugging Face organization still listed only the base checkpoint, so the paper's stated plan to add post-trained TwoTower models had not yet been carried out.[21][44]
TwoTower sits at the intersection of two lines this article traces: it is an AR-to-diffusion adaptation like DiffuLLaMA, Dream 7B, and LLaDA 2.0, but leaves the pretrained network untouched and adds a second one instead of continuing to train it, and it is block diffusion like BD3-LM, but with the prefix represented by a separate frozen model rather than the same weights under a different attention mask. The paper reports no speculative-decoding experiments but notes that the context tower's retained LM head makes it usable as a verifier. None of the NVIDIA-reported numbers above had been independently reproduced as of this writing.[21]
Nemotron-Labs-Diffusion: one network, three decoding modes (NVIDIA, 2026)
A separate NVIDIA group (Yonggan Fu and 25 co-authors, with Pavlo Molchanov as last author) took the opposite architectural bet in Nemotron-Labs-Diffusion (arXiv 2607.05722, July 7, 2026): one dense network trained with a joint AR-diffusion objective that switches between autoregressive decoding, diffusion parallel decoding, and a third "self-speculation" mode, in which the diffusion pass drafts and the AR pass verifies with a shared KV cache, by changing only the attention pattern at inference time.[24][25] The family spans 3B, 8B, and 14B parameters in base, instruct, and vision-language variants, released on Hugging Face under the NVIDIA Nemotron Open Model License with code at NVlabs/Nemotron-Labs-Diffusion; the 8B repository was created on March 18, 2026, months before the paper.[25] The abstract reports that the 8B model decodes 6x more tokens per forward pass than Qwen3-8B at comparable accuracy, which it translates into 4x higher throughput on SPEED-Bench with SGLang on a GB200 GPU, and the model card gives 850 tokens per second at concurrency 1 on GB200 against 253 for AR decoding (1,015 with custom CUDA kernels).[24][25] Where TwoTower doubles the weight footprint to protect the autoregressive model, Nemotron-Labs-Diffusion shares one set of weights and accepts that the two objectives must be balanced in training; the authors argue they are complementary, with diffusion improving "lookahead planning" and AR supplying "left-to-right linguistic priors."[24]
Block diffusion as a draft model: DFlash and DSpark (2026)
A second, and by download counts a large, use of block diffusion in 2026 is not as a standalone generator but as the drafter inside speculative decoding for autoregressive models. DFlash ("Block Diffusion for Flash Speculative Decoding," by Jian Chen, Yesheng Liang, and Zhijian Liu; arXiv 2602.06036, February 5, 2026; accepted at ICML 2026) trains a lightweight block-diffusion model that proposes an entire block of draft tokens in a single forward pass, conditioned on context features extracted from the target model, which the target then verifies in one pass. The abstract claims "over 6x lossless acceleration" across a range of models and tasks and up to 2.5x the speedup of EAGLE-3.[26] The code repository (z-lab/dflash on GitHub, MIT license, created January 4, 2026) lists public drafters for Qwen, Gemma 4, MiniMax, Kimi, GPT-OSS, Llama 3.1, and GLM models, with backends for SGLang, vLLM, llama.cpp, and MLX.[43] DFlash 2 (Inco AI, August 18, 2026; Inco's post says its team released the original DFlash) keeps the top candidates at every draft position and adds a lightweight selector that traces one coherent path through them, plus two-tap dynamic convolutions to stop draft quality decaying toward the end of the block. Inco reports 16 to 25 percent more accepted output per verification pass for about 1 percent added cycle latency, and its Qwen3.8-27B drafter card lists 2.67x to 3.43x throughput over autoregressive decoding at concurrency 1 on an H200 with SGLang, ahead of Qwen3.8's built-in MTP heads and a community DSpark drafter on the same five tasks. The post also says DFlash drafters had been downloaded more than 3.5 million times on Hugging Face as of August 2026 and that Meta, Poolside, Xiaomi, and NVIDIA ship official DFlash drafters with their own models; those are the company's claims.[27][28]
DSpark ("Confidence-Scheduled Speculative Decoding with Semi-Autoregressive Generation," by Xin Cheng and 32 co-authors including Wenfeng Liang; arXiv 2607.05147, July 6, 2026) addresses the weakness of purely parallel drafters, whose acceptance decays along the block because drafted tokens do not condition on one another. DSpark pairs a parallel backbone with a lightweight sequential module to model intra-block dependencies, and schedules the verification length per request from estimated prefix-survival probabilities and the serving engine's throughput profile. The paper reports deployment inside the DeepSeek-V4 serving system under live traffic, where DSpark raised per-user generation speed by 60 to 85 percent at matched throughput against the production MTP-1 baseline.[29] NVIDIA published an official DSpark checkpoint for Nemotron 3.5 Lightning (nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4-DSpark: 967 million parameters, OpenMDW-1.1 license, Hugging Face release date August 11, 2026 per the card).[30]
NVIDIA's Jetson team put both drafters into an edge deployment guide on September 4, 2026 ("Frontier Reasoning Reaches the Edge: How to Deploy and Optimize Models on NVIDIA Jetson," by Khalil BenKhaled, Aditya Sahu, and Chitoku Yato). The post describes DFlash as using "a separate diffusion-based draft model to propose a block of tokens in parallel" and DSpark as building on DFlash "by correcting drafts and stopping weak proposals early," and reports that on NVIDIA Jetson NVFP4 quantization plus speculative decoding gave up to 6.28x decode throughput over BF16: Nemotron 3.5 Lightning was fastest with DSpark (123.01 to 138.02 output tokens per second across four SpeedBench categories) and Qwen3.8-27B with DFlash 2 (27.69 to 34.44 tokens per second), served through vLLM's speculative-config interface with 5 and 7 speculative tokens respectively.[31] For diffusion language modeling the significance is indirect: block-diffusion networks now ship in mainstream inference engines even where the model users talk to remains autoregressive.
Dream 7B and the open-weights frontier
On April 2, 2025, Jiacheng Ye, Zhihui Xie, Lin Zheng, Jiahui Gao, Zirui Wu, Xin Jiang, Zhenguo Li, and Lingpeng Kong from the University of Hong Kong and Huawei Noah's Ark Lab released Dream 7B with open Base and Instruct weights, calling it "the most powerful open diffusion large language model to date"; the technical report, "Dream 7B: Diffusion Large Language Models," followed on arXiv on August 21, 2025.[57][12] Dream 7B is a 7 billion parameter discrete diffusion language model that, like LLaDA, follows the masked diffusion recipe. Two training tricks were emphasized in the report: AR-based LLM initialization, in which the diffusion model is initialized from a pretrained autoregressive checkpoint (Qwen2.5 7B, with 580 billion tokens of further training according to the release post) and then continued under the masked diffusion objective, and context-adaptive token-level noise rescheduling, which adjusts the per-token corruption rate based on local context to stabilize training.
The authors report that Dream 7B consistently outperforms previous open diffusion language models on general, mathematical, and coding benchmarks while remaining competitive with autoregressive llama-class models of similar scale. A companion release on July 15, 2025, Dream-Coder 7B, was adapted from Qwen2.5-Coder 7B with 322 billion training tokens; its authors report that the Instruct variant attains 21.4 percent pass@1 on LiveCodeBench (2410-2505 problems).[58] Both Dream 7B and Dream-Coder 7B were released with open weights on Hugging Face, making them among the most capable open diffusion language models available at the time of release and providing a public counterpart to the closed-source Mercury family.[12]
Gemini Diffusion
In May 2025 Google DeepMind unveiled Gemini Diffusion, an experimental text diffusion model that generates output by refining noise step by step and that "generates entire blocks of tokens at once" rather than predicting tokens sequentially. DeepMind reports that the model corrects errors during generation for more consistent outputs and that it excels at editing tasks in the context of mathematics and code. The model page reports a sampling speed of 1,479 tokens per second excluding a 0.84-second overhead, averaged across the reported evaluations, and Google's May 20, 2025 announcement says the demo "generates content significantly faster than our fastest model so far, while matching its coding performance." DeepMind's comparison is against Gemini 2.0 Flash-Lite: Gemini Diffusion scores 89.6 percent on HumanEval (90.2 for Flash-Lite), 76.0 percent on MBPP (75.8), 30.9 percent on LiveCodeBench v6 (28.5) and 23.3 percent on AIME 2025 (20.0), but trails on SWE-Bench Verified (22.9 against 28.5, in a non-agentic single-turn evaluation), GPQA Diamond (40.4 against 56.5), BIG-Bench Extra Hard (15.0 against 21.0) and Global MMLU Lite (69.1 against 79.0).[18] Access was through a waitlist, and all of these figures are vendor-reported.[18] When re-checked on October 31, 2026, the model page still listed the same speed and benchmark table and said Gemini Diffusion "is currently available as an experimental demo to help develop and refine future models."[18]
DiffusionGemma (Google DeepMind, 2026)
Google followed Gemini Diffusion with an open-weight model on June 10, 2026. DiffusionGemma, announced by Brendan O'Donoghue and Sebastian Flennerhag, is built on the Gemma 4 26B A4B mixture-of-experts backbone and, in Google's words, on "cutting-edge Gemini Diffusion research."[60] The model card lists 25.2 billion total and 3.8 billion active parameters (8 of 128 experts plus one shared expert) and describes an encoder-decoder arrangement: an autoregressive encoder caches the prompt, a decoder with bidirectional attention denoises a 256-token "canvas" while cross-attending to that cache, and each finished canvas is appended to the cache before the next one starts, a block-autoregressive scheme of the same family as BD3-LM.[61] Google reports up to 4x faster generation on dedicated GPUs, more than 1,000 tokens per second on one H100 and more than 700 on a GeForce RTX 5090, and the card describes 15-20 tokens finalized per forward pass. The weights are released under Apache 2.0 as an experimental model; Google says autoregressive Gemma 4 models "remain the standard for high-quality production outputs."[60][61] Its sampler, benchmarks and serving support are covered in the dedicated DiffusionGemma article.
Seed Diffusion
Seed Diffusion is a high-speed discrete diffusion language model from ByteDance's Seed team, announced on July 31, 2025 and described in the technical report "Seed Diffusion: A Large-Scale Diffusion Language Model with High-Speed Inference" (arXiv, August 4, 2025).[59] The report focuses on structured code generation as a proving ground for the discrete diffusion approach and emphasizes inference speed: the Seed Diffusion Preview is reported to reach approximately 2,146 tokens per second on NVIDIA H20 GPUs, which the team's announcement describes as 5.4 times faster than autoregressive models of similar scale and the report describes as significantly faster than the contemporary Mercury and Gemini Diffusion systems, while noting that direct comparison is difficult because those systems were measured on different hardware and workloads.[59][17] The team attributes this throughput to a two-stage diffusion training procedure, constrained-order learning, and on-policy learning of an efficient parallel decoding order, and claims state-of-the-art results on the speed-quality Pareto frontier for code models. The model is available as an online demo; ByteDance Seed's Hugging Face organization listed no Seed Diffusion weights when checked on October 31, 2026, and the speed figures are author-reported.[17]
RND1 (Radical Numerics, 2025)
On October 9, 2025, Radical Numerics released RND1-Base, an experimental 30-billion-parameter sparse mixture-of-experts diffusion model with 3 billion active parameters, converted from the autoregressive Qwen3-30B-A3B and continually pretrained for 500 billion tokens. The company called it "the largest and most capable open-source DLM to date" and released the weights, training recipe and inference code; Ant Group's 100-billion-parameter LLaDA 2.0 weights followed seven weeks later.[62][33]
How do diffusion language models compare to autoregressive models?
The diffusion-versus-autoregressive comparison has three dimensions worth separating: speed, quality, and reasoning.
Speed. Diffusion models can in principle generate many tokens per forward pass. In practice the number of denoising steps determines the actual latency: in the Mercury report's Artificial Analysis table, Mercury Coder Mini runs at 1,109 tokens per second on H100, while the speed-optimized autoregressive APIs it is compared with run at 59 to 201 tokens per second.[7] Open research checkpoints such as LLaDA and Dream were initially slow in practice because bidirectional attention prevents standard KV caching; training-free methods such as Fast-dLLM (ICLR 2026), which adds an approximate block-wise KV cache and confidence-aware parallel decoding, report up to 27.6x throughput gains on those models.[65] The gap also narrows when speculative decoding or other autoregressive acceleration techniques are applied to baseline systems. The advantage is largest for short to medium outputs and shrinks for very long generations, where the per-step transformer cost grows with sequence length.
Quality. As of early 2026, the best open and closed diffusion language models are competitive with comparably sized autoregressive models on standard academic benchmarks. LLaDA 8B matches or exceeds llama 3 8B on MMLU, GSM8K, MATH, and HumanEval.[4] Inception reports that Mercury Coder Small performs on par with Claude 3.5 Haiku and Gemini 2.0 Flash on coding benchmarks with up to 10x higher throughput.[7] Dream 7B is broadly competitive with llama-class 7B baselines.[12] As of October 2026, vendors position their strongest diffusion models against speed-optimized tiers rather than flagship systems: Inception compares Mercury 3 with GPT-6 Luna and Claude Haiku 5.5, and Google says autoregressive Gemma 4 remains its choice for highest-quality output.[55][60] Public comparisons with flagship gpt-4-class or Claude-class systems for general chat, complex reasoning, or agentic workflows still favor autoregressive models.
Reasoning. Diffusion models exhibit some characteristic strengths and weaknesses on reasoning workloads. The bidirectional nature of masked diffusion gives them an advantage on reversal-style tasks and on global-constraint problems; LLaDA's reversal-curse experiments are one example.[4] On chain-of-thought style reasoning, however, diffusion models do not naturally produce a single causal trace, which complicates the application of standard inference-time scaling techniques developed for autoregressive reasoning models. Research has attacked the problem from two directions. Diffusion-of-Thought (DoT; NeurIPS 2024) fine-tunes diffusion language models, including Plaid, to let chain-of-thought reasoning steps "diffuse over time" and reports a small diffusion model beating a much larger autoregressive one on multi-digit multiplication, boolean logic and grade-school math.[63] d1 (NeurIPS 2025) adapts reinforcement learning to masked diffusion models with diffu-GRPO, which it describes as the first integration of policy-gradient methods with masked dLLMs, and reports that it consistently improves on its base model, LLaDA-8B-Instruct, on math and planning benchmarks.[64] Reasoning models comparable to OpenAI's o-series or DeepSeek-R1 remain autoregressive in the public record. Vendors began contesting that gap in 2026: Inception bills Mercury 2 as a reasoning diffusion model with tunable reasoning, LLaDA 2.1 describes a large-scale reinforcement learning framework for diffusion LLMs, and LLaDA 2.2 trains agentic tool use with block-level policy optimization, but none of these has been benchmarked here against frontier reasoning systems.[19][34][35]
What open problems remain for diffusion language models?
Several open problems remain unresolved as of 2026.
The first is scaling. For most of 2025 the dense LLaDA 8B was the largest publicly verified diffusion language model trained from scratch. The mixture-of-experts line has since pushed the public ceiling higher: LLaDA-MoE was pretrained from scratch on roughly 20 trillion tokens, and LLaDA 2.0-flash reaches 100 billion total parameters (about 6.1 billion activated) by converting an autoregressive checkpoint.[15][16] Whether the diffusion paradigm continues to scale in the same way as autoregressive models into the hundreds of billions of dense parameters, and whether it produces similar emergent capabilities, remains empirically open. In 2026 the from-scratch line grew again with LLaDA MoE v2 (30B total, 3B active, 23.5 trillion tokens), and Inception, without disclosing parameter counts, describes Mercury 2.5 as, to its knowledge, the largest diffusion language model ever trained and Mercury 3 as more than 40 times larger than Mercury 1.[47][52][55] TwoTower adds a different data point: the adaptation route reached a 30-billion-parameter hybrid MoE backbone in 2026 while training only the denoiser on about 2.1 trillion tokens, a fraction of the backbone's 25 trillion, which suggests that the cost of reaching a given diffusion scale can be set by the price of an existing autoregressive checkpoint rather than by from-scratch pretraining.[21]
The second is prompting and inference-time control. Autoregressive models accept a prompt by simply prepending it to the decoded context. Masked diffusion models must instead condition by leaving prompt tokens unmasked throughout the denoising process, a technique sometimes called prefix conditioning. This works for standard chat but raises subtle questions about caching, batching, and tool use that the field is still actively investigating; approximate KV caches such as Fast-dLLM's and block-wise designs with an autoregressive prefix (BD3-LM, TwoTower, DiffusionGemma) are the main 2025-2026 answers to the caching problem.[9][12][65][6][61]
The third is reasoning. As discussed above, diffusion reasoning work (DoT, d1, LLaDA 2.1's RL framework) and Inception's reasoning-tuned Mercury models exist, but as of October 2026 no diffusion model has been shown in public benchmarks to match frontier autoregressive reasoning models, and inference-time scaling recipes for diffusion remain less settled than for autoregressive decoding.[63][64][34][19]
The fourth is multimodality. LLaDA-V extends LLaDA to vision-language tasks, LLaDA2.0-Uni adds discrete visual tokens and an image decoder for unified understanding and generation, LLaDA-UI builds a GUI agent on the same backbone, and DiffusionGemma accepts images and sampled video frames; none of these supports audio input, and native multimodal diffusion remains an active research direction.[45][37][49][61]
The fifth is alignment and safety. Reinforcement learning from human feedback and preference optimization assume tractable sequence likelihoods, which masked diffusion models provide only through high-variance ELBO estimates. VRPO (LLaDA 1.5), diffu-GRPO (d1), LLaDA 2.1's RL framework and LLaDA 2.2's L-EBPO are adaptations of that toolkit; whether diffusion ultimately needs its own alignment methods is still open.[14][64][34][35]
What is the adoption status of diffusion language models in 2025-2026?
By mid-2026 the diffusion language modeling paradigm has moved from research curiosity to a recognized alternative to autoregressive transformer decoders, but it has not displaced them. The research community has produced strong open-weights releases (LLaDA, LLaDA-MoE, LLaDA 2.0, Dream 7B, MDLM, MD4), an ICML 2024 Best Paper (SEDD), and an ICLR 2025 Oral (Block Diffusion). The commercial frontier is led by Inception Labs' Mercury family, which reached its Mercury 3 generation in October 2026 and is now sold through Inception's API, OpenRouter, Baseten and Vercel (earlier Mercury models were also listed on Amazon Bedrock Marketplace and Azure AI Foundry), alongside Google DeepMind's experimental Gemini Diffusion and ByteDance's high-speed Seed Diffusion.[17][18][50][51][55] Masked discrete diffusion has also spread beyond text: NVIDIA's GenMol (ICML 2025) uses a single masked discrete diffusion model over molecular fragment sequences for drug-discovery tasks.[66]
As of October 2026 the picture has four new features. First, open weights at the 30B-to-100B scale come from several labs: Radical Numerics' RND1 (30B, October 2025), NVIDIA's Nemotron-Labs-TwoTower (roughly 60 billion parameters across its two towers, under the Nemotron Open Model License) and the Renmin University group's LLaDA MoE v2 (30B) sit alongside Ant Group's LLaDA 2.x line, with NVIDIA's smaller 3B-to-14B Nemotron-Labs-Diffusion family beside them,[62][47] whose LLaDA2.2-flash (100B) and LLaDA2.2-mini (16B) arrived in July and September 2026 with 128K context and agentic tool use.[22][25][35][36] Second, block diffusion is in production inference stacks as a draft model: DFlash and DSpark drafters run in vLLM, SGLang, and llama.cpp, NVIDIA ships an official DSpark checkpoint for Nemotron 3.5 Lightning and recommends both methods for Jetson deployments, and Inco AI claims more than 3.5 million Hugging Face downloads of DFlash drafters.[27][30][31] Third, Inception remains the most visible commercial dLLM vendor: it moved from Mercury 2 to Mercury 2.5 (September 8, 2026), Mercury Voice (September 29) and Mercury 3 (October 19), while Gemini Diffusion is still an experimental demo and the Seed Diffusion arXiv report was still at its first version on October 31, 2026.[17][18][52][53][55] Fourth, Google entered open weights with DiffusionGemma in June 2026, and the Renmin University group showed with LLaDA MoE v2 that from-scratch MoE diffusion training continues at the 30B scale.[60][47] What no vendor has yet shown is an open diffusion model at TwoTower's scale that beats its own autoregressive backbone on quality: TwoTower gives up 1.3 percent of aggregate quality for 2.42x throughput, and LLaDA2.2-flash trails the autoregressive Ling-2.6-flash it is compared with by about 12 points on SWE-bench Verified at 1.7 times the tokens per second.[22][35]
Whether diffusion will eventually replace autoregressive generation as the dominant paradigm for large language models depends on whether the speed advantages continue to compound at frontier scale, whether reasoning workflows can be made diffusion-native, and whether multimodal integration matures. As of 2026, the most plausible outcome is hybrid: block diffusion architectures and Mercury-style commercial systems suggest that the future may well consist of models that combine the parallelism of diffusion with the cache-friendly structure of autoregressive decoding, rather than a winner-take-all replacement of one paradigm by the other.[6][7] TwoTower and Nemotron-Labs-Diffusion, both hybrids by construction, and the drafter role of DFlash and DSpark, in which diffusion serves an autoregressive model rather than replacing it, are the 2026 evidence for that reading.[21][24][26]
Continue reading
- Autoregressive ModelAn autoregressive model predicts each element of a sequence from the elements that precede it, feeding its own earlier outputs back in as context for every later prediction.Mentioned 73 times above
- Diffusion modelA diffusion model is a generative model that learns to transform samples from a simple reference distribution into samples resembling a data distribution by reversing a gradual corruption process.Mentioned 42 times above
- GPTGPT, short for Generative Pre-trained Transformer, is the name of a model family developed by OpenAI.Mentioned 20 times above
- DenoisingDenoising is the process of removing unwanted noise from data to recover a cleaner underlying signalMentioned 15 times above
- Llama 3Llama 3 is a family of open-weight large language models developed by Meta. Meta released the original Llama 3 checkpoints on April 18, 2024, in 8-billion-parameter and 70-billion-parameter sizes.Mentioned 4 times above
- Causal Language ModelA causal language model (CLM), also called an autoregressive language model or a decoder-only language model, is a language model that predicts the next token in a sequence using only the tokens that precede…Mentioned 4 times above
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Austin, Jacob; Johnson, Daniel D.; Ho, Jonathan; Tarlow, Daniel; van den Berg, Rianne. "Structured Denoising Diffusion Models in Discrete State-Spaces." arXiv:2107.03006, NeurIPS 2021. arxiv.org/...2107.03006 Accessed 2026-05-31.
- ^1 ^2 ^3 ^4 ^5Li, Xiang Lisa; Thickstun, John; Gulrajani, Ishaan; Liang, Percy; Hashimoto, Tatsunori B. "Diffusion-LM Improves Controllable Text Generation." arXiv:2205.14217, NeurIPS 2022. arxiv.org/...2205.14217 Accessed 2026-05-31.
- ^1 ^2 ^3 ^4Lou, Aaron; Meng, Chenlin; Ermon, Stefano. "Discrete Diffusion Modeling by Estimating the Ratios of the Data Distribution." arXiv:2310.16834, ICML 2024 (Oral, Best Paper). arxiv.org/...2310.16834 Accessed 2026-05-31.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Nie, Shen; Zhu, Fengqi; You, Zebin; Zhang, Xiaolu; Ou, Jingyang; Hu, Jun; Zhou, Jun; Lin, Yankai; Wen, Ji-Rong; Li, Chongxuan. "Large Language Diffusion Models." arXiv:2502.09992, v1 February 14, 2025, v3 October 18, 2025; NeurIPS 2025 (Oral). arxiv.org/...2502.09992 Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5Inception Labs. "Introducing Mercury, the World's First Commercial-Scale Diffusion Large Language Model." Inception Labs Blog, February 26, 2025. inceptionlabs.ai/...introducing-mercury Accessed 2026-05-31.
- ^1 ^2 ^3 ^4 ^5 ^6Arriola, Marianne; Gokaslan, Aaron; Chiu, Justin T.; Yang, Zhihan; Qi, Zhixuan; Han, Jiaqi; Sahoo, Subham Sekhar; Kuleshov, Volodymyr. "Block Diffusion: Interpolating Between Autoregressive and Diffusion Language Models." arXiv:2503.09573, ICLR 2025 Oral. arxiv.org/...2503.09573 Accessed 2026-05-31.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Inception Labs et al. "Mercury: Ultra-Fast Language Models Based on Diffusion." arXiv:2506.17298, 2025. arxiv.org/...2506.17298 Accessed 2026-05-31.
- ^1 ^2Gulrajani, Ishaan; Hashimoto, Tatsunori B. "Likelihood-Based Diffusion Language Models." arXiv:2305.18619, NeurIPS 2023 (Plaid). arxiv.org/...2305.18619 Accessed 2026-05-31.
- ^1 ^2 ^3 ^4 ^5Sahoo, Subham Sekhar; Arriola, Marianne; Schiff, Yair; Gokaslan, Aaron; Marroquin, Edgar; Chiu, Justin T.; Rush, Alexander; Kuleshov, Volodymyr. "Simple and Effective Masked Diffusion Language Models." arXiv:2406.07524, NeurIPS 2024. arxiv.org/...2406.07524 Accessed 2026-05-31.
- ^1 ^2Shi, Jiaxin; Han, Kehang; Wang, Zhe; Doucet, Arnaud; Titsias, Michalis K. "Simplified and Generalized Masked Diffusion for Discrete Data." arXiv:2406.04329, NeurIPS 2024 (MD4). arxiv.org/...2406.04329 Accessed 2026-05-31.
- ^Maginative. "Inception Labs Launches Mercury, the First Commercial Diffusion-Based Language Model." Maginative, February 2025. maginative.com/...l-diffusion-based-language-model Accessed 2026-05-31.
- ^1 ^2 ^3 ^4 ^5Ye, Jiacheng; Xie, Zhihui; Zheng, Lin; Gao, Jiahui; Wu, Zirui; Jiang, Xin; Li, Zhenguo; Kong, Lingpeng. "Dream 7B: Diffusion Large Language Models." arXiv:2508.15487, August 21, 2025 (technical report for the model released April 2, 2025). arxiv.org/...2508.15487 Accessed 2026-05-31.
- ^1 ^2 ^3 ^4Gong, Shansan; Agarwal, Shivam; Zhang, Yizhe; Ye, Jiacheng; Zheng, Lin; Li, Mukai; An, Chenxin; Zhao, Peilin; Bi, Wei; Han, Jiawei; Peng, Hao; Kong, Lingpeng. "Scaling Diffusion Language Models via Adaptation from Autoregressive Models." arXiv:2410.17891, ICLR 2025 (DiffuGPT and DiffuLLaMA). arxiv.org/...2410.17891 Accessed 2026-05-31.
- ^1 ^2 ^3 ^4Zhu, Fengqi; Wang, Rongzhen; Nie, Shen; Zhang, Xiaolu; Wu, Chunwei; Hu, Jun; Zhou, Jun; Chen, Jianfei; Lin, Yankai; Wen, Ji-Rong; Li, Chongxuan. "LLaDA 1.5: Variance-Reduced Preference Optimization for Large Language Diffusion Models." arXiv:2505.19223, May 2025; published in Proceedings of ACL 2026 (Volume 1: Long Papers), pages 11425-11460. arxiv.org/...2505.19223 and aclanthology.org/2026.acl-long.524 Accessed 2026-10-31.
- ^1 ^2 ^3Zhu, Fengqi; You, Zebin; Xing, Yipeng; Huang, Zenan; Liu, Lin; et al. "LLaDA-MoE: A Sparse MoE Diffusion Language Model." arXiv:2509.24389, September 2025. arxiv.org/...2509.24389 Accessed 2026-05-31.
- ^1 ^2 ^3 ^4InclusionAI (Ant Group). "LLaDA2.0: Scaling Up Diffusion Language Models to 100B." arXiv:2512.15745, December 2025. arxiv.org/...2512.15745 Accessed 2026-05-31.
- ^1 ^2 ^3 ^4 ^5ByteDance Seed. "Seed Diffusion: A Large-Scale Diffusion Language Model with High-Speed Inference." arXiv:2508.02193, August 2025. arxiv.org/...2508.02193 Accessed 2026-05-31.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Google DeepMind. "Gemini Diffusion." DeepMind model page and Google blog announcement, May 2025. deepmind.google/...gemini-diffusion and blog.google/...gemini-diffusion Accessed 2026-05-31.
- ^1 ^2 ^3 ^4Inception Labs. "Introducing Mercury 2" and "Inception Launches Mercury 2, the Fastest Reasoning LLM." Inception Labs Blog and Business Wire press release, February 2026. inceptionlabs.ai/...introducing-mercury-2 and businesswire.com/...matically-Lower-Inference-Cost Accessed 2026-05-31.
- ^1 ^2 ^3Reda, Fitsum; Kamalu, John; Waleffe, Roger; Patwary, Mostofa; Shoeybi, Mohammad; Catanzaro, Bryan. "Nemotron-Labs-TwoTower: Diffusion Language Modeling with Pretrained Autoregressive Context." arXiv:2606.26493, v1 June 25, 2026, v2 June 29, 2026. arxiv.org/...2606.26493 Accessed 2026-09-06.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12Reda, Fitsum et al. "Nemotron-Labs-TwoTower: Diffusion Language Modeling with Pretrained Autoregressive Context." arXiv:2606.26493v2 HTML full text (Sections 1-4, Tables 1-4), June 29, 2026. arxiv.org/...2606.26493v2 Accessed 2026-09-06.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8NVIDIA. "nvidia/Nemotron-Labs-TwoTower-30B-A3B-Base-BF16" model card. Hugging Face, last modified July 1, 2026. huggingface.co/...-Labs-TwoTower-30B-A3B-Base-BF16 Accessed 2026-09-06.
- ^1 ^2Arriola, Marianne; Schiff, Yair; Phung, Hao; Gokaslan, Aaron; Kuleshov, Volodymyr. "Encoder-Decoder Diffusion Language Models for Efficient Training and Inference." arXiv:2510.22852, NeurIPS 2025 (E2D2), October 26, 2025. arxiv.org/...2510.22852 Accessed 2026-09-06.
- ^1 ^2 ^3 ^4 ^5Fu, Yonggan; Whalen, Lexington; Garg, Abhinav; et al.; Molchanov, Pavlo. "Nemotron-Labs-Diffusion: A Tri-Mode Language Model Unifying Autoregressive, Diffusion, and Self-Speculation Decoding." arXiv:2607.05722, July 7, 2026. arxiv.org/...2607.05722 Accessed 2026-09-06.
- ^1 ^2 ^3 ^4NVIDIA. "nvidia/Nemotron-Labs-Diffusion-8B" model card and Hugging Face API record (repository created March 18, 2026). huggingface.co/...Nemotron-Labs-Diffusion-8B Accessed 2026-09-06.
- ^1 ^2 ^3 ^4Chen, Jian; Liang, Yesheng; Liu, Zhijian. "DFlash: Block Diffusion for Flash Speculative Decoding." arXiv:2602.06036, v1 February 5, 2026, v2 May 28, 2026 (ICML 2026). arxiv.org/...2602.06036 Accessed 2026-09-06.
- ^1 ^2 ^3Inco AI. "DFlash 2: Keep Drafting Parallel." Inco AI blog, August 18, 2026. inco.ai/...dflash2 Accessed 2026-09-06.
- ^Inco AI. "incoai/Qwen3.8-27B-DFlash2" model card (evaluation tables). Hugging Face, created August 18, 2026. huggingface.co/...Qwen3.8-27B-DFlash2 Accessed 2026-09-06.
- ^1 ^2Cheng, Xin; Yu, Xingkai; Shao, Chenze; et al.; Liang, Wenfeng. "DSpark: Confidence-Scheduled Speculative Decoding with Semi-Autoregressive Generation." arXiv:2607.05147, July 6, 2026. arxiv.org/...2607.05147 Accessed 2026-09-06.
- ^1 ^2NVIDIA. "nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4-DSpark" model card. Hugging Face, release date August 11, 2026 per the card. huggingface.co/...5-Lightning-30B-A3B-NVFP4-DSpark Accessed 2026-09-06.
- ^1 ^2BenKhaled, Khalil; Sahu, Aditya; Yato, Chitoku. "Frontier Reasoning Reaches the Edge: How to Deploy and Optimize Models on NVIDIA Jetson." NVIDIA Technical Blog, September 4, 2026. developer.nvidia.com/...ze-models-on-nvidia-jetson Accessed 2026-09-06.
- ^Bie, Tiwei; Cao, Maosong; Chen, Kun; et al. "LLaDA2.0: Scaling Up Diffusion Language Models to 100B." arXiv:2512.15745, v1 December 10, 2025, v2 December 24, 2025. arxiv.org/...2512.15745 Accessed 2026-09-06.
- ^1 ^2 ^3 ^4InclusionAI (Ant Group). "inclusionAI/LLaDA2.0-flash" model card. Hugging Face, repository created November 25, 2025. huggingface.co/...LLaDA2.0-flash Accessed 2026-09-06.
- ^1 ^2 ^3 ^4 ^5Bie, Tiwei; Cao, Maosong; Cao, Xiang; et al. "LLaDA2.1: Speeding Up Text Diffusion via Token Editing." arXiv:2602.08676, v1 February 9, 2026, v3 February 13, 2026. arxiv.org/...2602.08676 Accessed 2026-09-06.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7InclusionAI (Ant Group). "inclusionAI/LLaDA2.2-flash" model card. Hugging Face, repository created July 16, 2026. huggingface.co/...LLaDA2.2-flash Accessed 2026-09-06.
- ^1 ^2 ^3InclusionAI (Ant Group). "inclusionAI/LLaDA2.2-mini" model card. Hugging Face, repository created September 5, 2026. huggingface.co/...LLaDA2.2-mini Accessed 2026-09-06.
- ^1 ^2Inclusion AI; Bie, Tiwei; Chen, Haoxing; et al. "LLaDA2.0-Uni: Unifying Multimodal Understanding and Generation with Diffusion Large Language Model." arXiv:2604.20796, April 22, 2026. arxiv.org/...2604.20796 Accessed 2026-09-06.
- ^Inception Labs. Blog index (post dates for "Introducing Mercury 2," February 24, 2026; "Introducing Mercury Edit 2," March 30, 2026; "Mercury 2 on Azure Foundry," June 24, 2026; "More builders. More throughput. Better Mercury 2.," July 29, 2026; "Mercury 2 for Search," August 11, 2026). inceptionlabs.ai/blog Accessed 2026-09-06.
- ^Hasanaliyev, Kenan; Shuttleworth, Reece. "Introducing Mercury Edit 2." Inception Labs blog, March 30, 2026. inceptionlabs.ai/...introducing-mercury-edit-2 Accessed 2026-09-06.
- ^Inception Team. "More builders. More throughput. Better Mercury 2." Inception Labs blog, July 29, 2026. inceptionlabs.ai/...mercury-2-10x-free-tokens Accessed 2026-09-06.
- ^OpenRouter. Model listing "inception/mercury-2.5-preview" (created August 31, 2026; context 260,000; pricing per token) via the OpenRouter models API. openrouter.ai/...mercury-2.5-preview Accessed 2026-09-06.
- ^Ermon, Stefano. "The Next Step for dLLMs: Scaling up Mercury." Inception Labs blog, November 7, 2025. inceptionlabs.ai/...mercury-refreshed Accessed 2026-09-06.
- ^z-lab. "DFlash: Block Diffusion for Flash Speculative Decoding" repository README and GitHub API record (created January 4, 2026, MIT license). github.com/...dflash Accessed 2026-09-06.
- ^1 ^2Hugging Face API. Model record and commit history for nvidia/Nemotron-Labs-TwoTower-30B-A3B-Base-BF16 (created April 11, 2026; commits "Update to Nemotron-Labs-TwoTower" and "add -Labs to model name" on July 1, 2026; 817 downloads and 142 likes on September 6, 2026). huggingface.co/...main Accessed 2026-09-06.
- ^1 ^2You, Zebin; Nie, Shen; Zhang, Xiaolu; Hu, Jun; Zhou, Jun; Lu, Zhiwu; Wen, Ji-Rong; Li, Chongxuan. "LLaDA-V: Large Language Diffusion Models with Visual Instruction Tuning." arXiv:2505.16933, May 22, 2025. arxiv.org/...2505.16933 Accessed 2026-10-31.
- ^1 ^2InclusionAI (Ant Group). "inclusionAI/LLaDA-MoE-7B-A1B-Instruct" model card. Hugging Face, repository created September 10, 2025. huggingface.co/...LLaDA-MoE-7B-A1B-Instruct Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5Zhu, Fengqi; Xu, Shaoxuan; Ou, Jingyang; You, Zebin; et al.; Li, Chongxuan; Wen, Ji-Rong. "LLaDA MoE v2: Scaling Mixture-of-Experts Diffusion Language Models." arXiv:2608.03457, August 4, 2026. arxiv.org/...2608.03457 Accessed 2026-10-31.
- ^1 ^2GSAI-ML. "GSAI-ML/LLaDA-MoE-v2-30B-A3B-Base" and "GSAI-ML/LLaDA-MoE-v2-30B-A3B-Instruct" model cards (Apache-2.0; repositories created August 17 and 18, 2026). Hugging Face. huggingface.co/...LLaDA-MoE-v2-30B-A3B-Base Accessed 2026-10-31.
- ^1 ^2Gu, Zhangxuan; Chen, Haoxing; Qin, Qi; et al.; Lan, Zhenzhong. "LLaDA-UI: Bringing Block-wise Diffusion to Vision-Language GUI Agents." arXiv:2609.13287, September 9, 2026. arxiv.org/...2609.13287 Accessed 2026-10-31.
- ^1 ^2Vijeaswaran, Niithiyn; Liu, John; Evans, Jonathan; Talluri, Rohit; Warner, Breanne. "Mercury foundation models from Inception Labs are now available in Amazon Bedrock Marketplace and Amazon SageMaker JumpStart." AWS Machine Learning Blog, August 27, 2025. aws.amazon.com/...e-and-amazon-sagemaker-jumpstart Accessed 2026-10-31.
- ^1 ^2Inception Labs. "Mercury Diffusion LLM Now Available on Azure AI Foundry." Inception Labs blog. inceptionlabs.ai/...mercury-azure-foundry Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5Ermon, Stefano. "Introducing Mercury 2.5." Inception Labs blog, September 8, 2026. inceptionlabs.ai/...introducing-mercury-2-5 Accessed 2026-10-31.
- ^1 ^2Trabelsi, Firas; Miraoui, Yanis; Khanna, Samar; Zhao, Xinyu; Gunasekaran, Gokul; Liu, Emily; Hasanaliyev, Kenan. "Introducing Mercury Voice." Inception Labs blog, September 29, 2026. inceptionlabs.ai/...introducing-mercury-voice Accessed 2026-10-31.
- ^Inception Team. "Mercury 2 Named to TIME's Best Inventions of 2026." Inception Labs blog, October 15, 2026. inceptionlabs.ai/...time-s-best-inventions-of-2026 Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Inception Team. "Diffusion at Scale: Introducing Mercury 3." Inception Labs blog, October 19, 2026. inceptionlabs.ai/...introducing-mercury-3 Accessed 2026-10-31.
- ^1 ^2Walter, Neetika. "Mercury 3 claims to outperform GPT-6 Luna, Claude Haiku 5.5 at 8 times the speed." Interesting Engineering, October 19, 2026. interestingengineering.com/...model-8-times-faster Accessed 2026-10-31.
- ^1 ^2Ye, Jiacheng; Xie, Zhihui; Zheng, Lin; Gao, Jiahui; Wu, Zirui; Jiang, Xin; Li, Zhenguo; Kong, Lingpeng. "Dream 7B." HKU NLP Group blog, April 2, 2025. hkunlp.github.io/...dream Accessed 2026-10-31.
- ^HKU NLP Group. "Dream-Coder 7B." HKU NLP Group blog, July 15, 2025. hkunlp.github.io/...dream-coder Accessed 2026-10-31.
- ^1 ^2ByteDance Seed. Seed Diffusion Preview release announcement. ByteDance Seed blog, July 31, 2025. seed.bytedance.com/...146-tokens-s-inference-speed Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5 ^6O'Donoghue, Brendan; Flennerhag, Sebastian. "DiffusionGemma: 4x faster text generation." Google blog, June 10, 2026. blog.google/...fusion-gemma-faster-text-generation Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5 ^6Google DeepMind. "google/diffusiongemma-26B-A4B-it" model card (Apache-2.0). Hugging Face, 2026. huggingface.co/...diffusiongemma-26B-A4B-it Accessed 2026-10-31.
- ^1 ^2 ^3Chandrasegaran, Keshigeyan; Thomas, Armin W.; et al. "RND1: simple, scalable AR-to-diffusion conversion." Radical Numerics blog, October 9, 2025. radicalnumerics.ai/...rnd1 Accessed 2026-10-31.
- ^1 ^2Ye, Jiacheng; Gong, Shansan; Chen, Liheng; Zheng, Lin; Gao, Jiahui; Shi, Han; Wu, Chuan; Jiang, Xin; Li, Zhenguo; Bi, Wei; Kong, Lingpeng. "Diffusion of Thoughts: Chain-of-Thought Reasoning in Diffusion Language Models." arXiv:2402.07754, NeurIPS 2024. arxiv.org/...2402.07754 Accessed 2026-10-31.
- ^1 ^2 ^3Zhao, Siyan; Gupta, Devaansh; Zheng, Qinqing; Grover, Aditya. "d1: Scaling Reasoning in Diffusion Large Language Models via Reinforcement Learning." arXiv:2504.12216, NeurIPS 2025. arxiv.org/...2504.12216 Accessed 2026-10-31.
- ^1 ^2Wu, Chengyue; Zhang, Hao; Xue, Shuchen; Liu, Zhijian; Diao, Shizhe; Zhu, Ligeng; Luo, Ping; Han, Song; Xie, Enze. "Fast-dLLM: Training-free Acceleration of Diffusion LLM by Enabling KV Cache and Parallel Decoding." arXiv:2505.22618, ICLR 2026. arxiv.org/...2505.22618 Accessed 2026-10-31.
- ^Lee, Seul; Kreis, Karsten; Veccham, Srimukh Prasad; Liu, Meng; Reidenbach, Danny; Peng, Yuxing; Paliwal, Saee; Nie, Weili; Vahdat, Arash. "GenMol: A Drug Discovery Generalist with Discrete Diffusion." arXiv:2501.06158, ICML 2025. arxiv.org/...2501.06158 Accessed 2026-10-31.
- ^1 ^2NeurIPS 2025. "Large Language Diffusion Models" (Oral). NeurIPS virtual conference site. neurips.cc/...118609 Accessed 2026-10-31.
- ^Inception Labs. "Our Models" (models page, Mercury 2 and Mercury 2.5 availability notice). inceptionlabs.ai/models Accessed 2026-10-31.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
9 revisions by 1 contributor · v9 · 11,281 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independently verified 2026-10-31 against the cited papers (D3PM, SEDD, MDLM, MD4, LLaDA family, Dream, Seed Diffusion, RND1, DiffusionGemma), Inception's Mercury reports, blog and models page, Google's Gemini Diffusion pages and Hugging Face records; 11 verifier defects fixed before stamping.
Cite this page: AI Wiki. "Diffusion Language Models." aiwiki.ai, updated 31 Oct 2026, fact-checked 31 Oct 2026. CC BY 4.0. https://aiwiki.ai/wiki/diffusion_language_models