

GDPval
GDPval is a benchmark released by OpenAI on September 25, 2025 that measures how well frontier AI models can produce the actual deliverables of professional knowledge work, scored by experts against work done by experienced humans.[1] It is built around 1,320 real tasks gathered from working professionals across 44 occupations in the nine U.S. industries that each contribute more than five percent of Gross Domestic Product, and OpenAI open-sourced a 220-task "gold" subset (five tasks per occupation) so that outside groups can reproduce it.[1][2] The paper describes GDPval as "a benchmark evaluating AI model capabilities on real-world economically valuable tasks" that "covers the majority of U.S. Bureau of Labor Statistics Work Activities for 44 occupations across the top 9 sectors contributing to U.S. GDP."[2]
Unlike academic tests of reasoning or recall, each GDPval task is a finished work product (a legal brief, a tax return, a project schedule, a customer support reply, a nursing care plan, a financial model) and the evaluation asks whether a model's output is as good as or better than the version produced by a human industry expert. Outputs are graded by occupational experts in blind pairwise comparisons against the human deliverables, and the headline metric is a win rate against those baselines. The first paper, posted to arXiv on October 5, 2025 as 2510.04374 and led by Tejal Patwardhan with eighteen co-authors at OpenAI, reported that the strongest model tested (Claude Opus 4.1) matched or beat industry experts on 47.6 percent of the gold subset, while GPT-5 (high reasoning) reached 39.0 percent and GPT-4o reached 12.5 percent.[2] OpenAI argued that frontier model performance had more than doubled between GPT-4o (spring 2024) and GPT-5 (summer 2025), and that frontier models could complete GDPval tasks roughly a hundred times faster and a hundred times cheaper than the experts, figures OpenAI said reflect pure model inference time and API billing rates and leave out the human oversight, iteration and integration needed in real workplaces.[1][2]
The benchmark is the most visible product of OpenAI's economic research arm, which Chief Economist Aaron "Ronnie" Chatterji joined in 2024 with a remit to ground claims about AI capability in measurable economic value.[5] GDPval was framed as a corrective to saturated knowledge benchmarks like MMLU and GPQA, where top models were scoring close to the ceiling and the scores stopped discriminating between systems. The choice to weight tasks by GDP, draw occupations from Bureau of Labor Statistics wage and employment data, and recruit graders with an average of fourteen years of professional experience was meant to anchor the score in something a labor economist would recognize.[2] Within months the leaderboard had become a fixture of model release announcements, and Artificial Analysis built an independent reimplementation called GDPval-AA that became a widely reported Elo leaderboard for frontier model deliverable quality in 2026.[10]
What is GDPval and why did OpenAI build it?
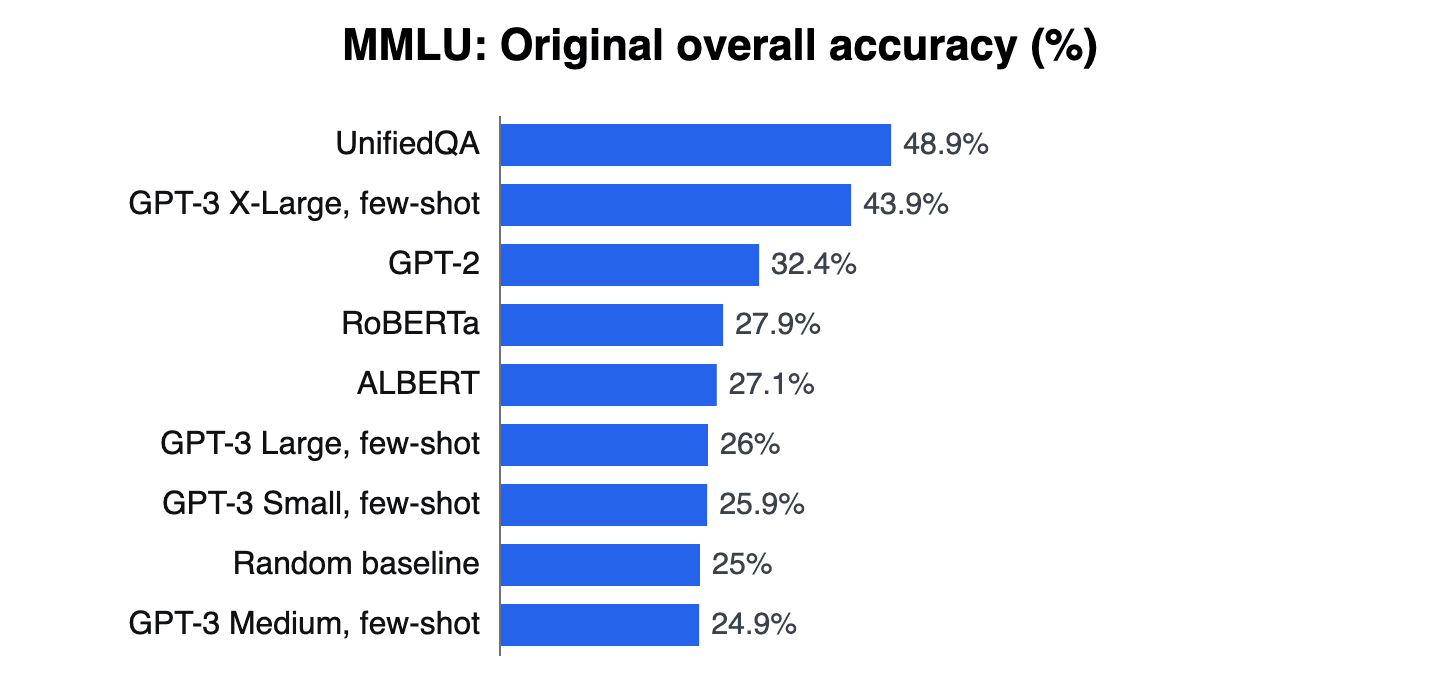
By the second half of 2025, the dominant complaint about AI evaluation was that the most-cited benchmarks no longer measured anything useful. MMLU was effectively saturated. Humanity's Last Exam had been launched specifically to give frontier models headroom, and ARC-AGI-2 was holding up but only as a test of abstract puzzle solving. None of these scores answered the question that policymakers, investors and labor economists were actually asking, which was whether the models were getting good enough to do the kind of work that people get paid for.
Sam Altman had been making variants of that claim for years, but the empirical basis was thin. The most cited piece of work was Eloundou et al.'s 2023 "GPTs are GPTs" paper, which used BLS occupational task data and asked annotators to estimate task exposure to large language models.[20] It was a useful framing exercise but it relied on subjective labeling rather than head-to-head comparison of model outputs against expert outputs.
OpenAI's economic research team, organized under Chatterji after his appointment as Chief Economist in 2024, set out to build something more direct.[5] The plan was to commission real work products from real professionals, ask current frontier models to produce the same deliverables under the same instructions, and have other professionals from the same occupations score the results blind. The benchmark would be expensive to build, because it required paying experts to design tasks and paying more experts to grade outputs, but the payoff was a number that could be defended in front of a Senate committee.
Tejal Patwardhan, the paper's lead author, had previously co-authored SWE-Lancer, OpenAI's benchmark of real freelance software engineering tasks, which the GDPval paper cites as a domain-specific predecessor.[2] Patwardhan's co-authors include Rachel Dias, Elizabeth Proehl, Grace Kim, Michele Wang, Olivia Watkins, Simon Posada Fishman, Marwan Aljubeh, Phoebe Thacker, Laurance Fauconnet, Natalie S. Kim, Patrick Chao, Samuel Miserendino, Gildas Chabot, David Li, Michael Sharman, Alexandra Barr, Amelia Glaese and Jerry Tworek.[2] Chatterji is among those thanked in the paper's acknowledgments.[2]
The choice to call the benchmark "GDPval" was deliberate. OpenAI said it chose the name because it "started with the concept of Gross Domestic Product (GDP) as a key economic indicator and drew tasks from the key occupations in the industries that contribute most to GDP."[1] Pegging the occupation selection to nine industries that each contribute more than five percent of U.S. GDP ensured that the benchmark would, at the time of release, cover sectors representing roughly 75 percent of measured U.S. GDP, even though the specific occupations sampled within those sectors only captured the higher-paying knowledge-work corner of each.[1]
How does GDPval work?
The paper describes GDPval as a measurement of how well a model can produce the deliverables that an experienced professional would hand to a client or a manager. According to the authors, "tasks are constructed from the representative work of industry professionals with an average of 14 years of experience."[2] Every task includes three things: a written request, a set of reference files (about two thirds of tasks include at least one reference file), and a deliverable that the human author actually produced. Tasks took the human authors about seven hours on average to complete, and 67.7 percent of tasks required interaction with at least one reference file.[2]
The deliverables are not simple text strings. They include Excel workbooks with named sheets and formulas, Word documents in specific formats, multi-form PDF tax returns, slide decks, CAD-adjacent diagrams, and audio or video clips. The dataset stores both the prompt and the reference and deliverable files in Parquet plus the original formats. The 220-task open-sourced "gold" subset comes to 2.29 GB on disk because the reference files alone are large.[4] In the gold subset's tax task, for example, the 15 reference files are a couple's 2024 W-2s, 1099 forms, mortgage-interest, childcare and student-loan statements and an intake questionnaire, the instruction asks for a Form 1040 in PDF with every schedule required for e-filing, and the human deliverable is the completed return.[4] The model has to read the references, decide which numbers go where, and produce a file that matches the format of the human's submission closely enough for an experienced preparer to grade them side by side.
How are GDPval tasks collected and quality-controlled?
OpenAI hired professional contributors through a vetting process that required at least four years of professional experience in their occupation, with the average across all contributors landing at fourteen years.[2] Contributors were asked to submit a representative work product, the written instructions a colleague or manager would have given them to produce it, and any reference materials a person seeing the task fresh would need. OpenAI's research team then reviewed each submission for completeness, redacted personal information about clients and colleagues, and rejected tasks that depended on tools or data that could not be made available to a model in a self-contained evaluation.
For multi-step tasks, the team checked that all relevant context was packaged into the request and references. Tasks requiring proprietary software tools were out of scope.[2] All 1,320 tasks then went through an iterative pipeline of automated model-based screening and at least three stages of human review: a generalist check against project requirements, an occupation-specific review that confirmed another member of the occupation could complete the task with the provided context, and a final reviewer feedback loop. Each task received an average of five human reviews, with a minimum of three.[2]
How are GDPval outputs graded?
Grading is done by occupational experts working blind. For each task, the grader sees the request, the reference files, and two unlabeled deliverables. One of the deliverables is the original human's work and the other is the model's. The grader picks one as better, marks them as tied, or picks the other. For the headline results each model was sampled three times per prompt and three different graders graded each sample, giving nine comparisons per prompt per model, and each comparison took more than an hour on average. Inter-rater agreement among humans was 71 percent. OpenAI also built an automated grader using a frontier model and reported 66 percent agreement with humans, which is enough to make the automated grader useful for tracking but not to replace expert grading.[2]
The paper says its experts were "well compensated for their time and experience" but does not give rates. The grading rubric instructed evaluators to consider correctness, completeness, formatting fidelity, presentation quality and any explicit requirements stated in the task prompt. They were not told which deliverable was AI-generated, but the paper cautions that blinding was imperfect: OpenAI outputs often used em dashes, Claude outputs often used first-person phrasing and Grok occasionally referred to itself by name, so graders may have inferred a file's origin even though filenames were scrubbed.[2]
The automated grader is based on GPT-5-high prompted with the same task description, references and deliverables, and asked to produce a structured judgment matching the human rubric. The 66 percent figure (65.7 percent over three sweeps, against 70.8 percent human inter-rater agreement) is an expected-agreement score in which each grade is 0, 0.5 or 1, so a win-versus-tie disagreement counts as half agreement.[2] The paper reports that agreement is lower when the grader assesses outputs from capable OpenAI models, consistent with models favoring their own responses, and highest for less capable models. OpenAI offers the automated grader at evals.openai.com as an "experimental research service" that it says is not yet as reliable as expert graders; the paper marks 12 of the 220 gold tasks as ungradable by it.[1][2]
What do the GDPval metrics mean?
The headline number is GDPval-Win, the percentage of tasks where the model's deliverable is rated as good as or better than the human's (wins and ties both count).[2] A secondary metric, GDPval-AA (the "AA" stands for Artificial Analysis), was introduced by Artificial Analysis as an Elo-style aggregate computed from blind pairwise model-versus-model comparisons using the Bradley-Terry rating system, originally anchored at GPT-5.1 (Non-Reasoning) = 1,000; the GDPval-AA v2.1 scale introduced in September 2026 instead pins DeepSeek V4.1 Flash (max) at 1,600.[10][11] GDPval-AA is what most public leaderboards now report, because it scales to many models without re-running grading against a fixed human baseline for each new release.
OpenAI's own headline figures, including 47.6 percent for Claude Opus 4.1 and later launch-post numbers, are "wins or ties" rates; OpenAI's launch chart also shows the wins-only share separately (43.6 percent for Claude Opus 4.1).[1][2] Epoch AI's GDPval page, which draws on the public leaderboard, defaults to a win-rate metric and offers wins-plus-ties in a dropdown.[12]
Which occupations and industries does GDPval cover?
The nine industries were selected because each contributes more than five percent of U.S. GDP, using Federal Reserve Bank of St. Louis data on value added by industry in Q2 2024.[2] Within each industry, the five highest-earning predominantly knowledge-work occupations were chosen using May 2024 BLS Occupational Employment and Wage Statistics, with knowledge-work classification done from O*NET task descriptions.[2] The result is 44 occupations rather than 45 because Retail Trade contributes four.[2] The 44 occupations together represented roughly $3 trillion in annual U.S. wages at the time of release.
| Industry (NAICS sector) | Approximate share of U.S. GDP | Occupations sampled |
|---|---|---|
| Real Estate and Rental and Leasing | 13.8% | 5 |
| Government | 11.3% | 5 |
| Manufacturing | 10.0% | 5 |
| Professional, Scientific and Technical Services | 8.1% | 5 |
| Health Care and Social Assistance | 7.6% | 5 |
| Finance and Insurance | 7.4% | 5 |
| Retail Trade | 6.3% | 4 |
| Wholesale Trade | 5.8% | 5 |
| Information | 5.4% | 5 |
Representative occupations include Software Developers, Lawyers, Accountants and Auditors, Registered Nurses, Financial Managers, Project Management Specialists, Compliance Officers, Property Managers, Industrial Engineers, Real Estate Agents, Customer Service Representatives, Editors, Audio and Video Technicians, and Child, Family, and School Social Workers. Each occupation contributes 30 tasks in the full set and 5 tasks in the open gold subset.[2]
OpenAI validated this selection against the Acemoglu and Autor (2011) task-content framework.[21] Tasks classified as digital correlated positively with non-routine cognitive content and negatively with routine and manual content, which is what you would expect from a benchmark aimed at knowledge work.
What do GDPval tasks look like?
The gold subset, released openly through Hugging Face, illustrates the range of work GDPval covers.[4] A few representative examples from the gold subset:[4]
- Accountants and Auditors: A mid-level tax preparer completes a 2024 Form 1040 for a married couple. The 15 reference files include W-2s, 1099-INT, 1099-B and 1099-DIV forms, a mortgage interest statement, a childcare statement and a client intake questionnaire; the deliverable is the return in PDF with the schedules and forms required for e-filing.
- Software Developers: Build a self-contained backend for a website contact form as a Node.js 18 AWS Lambda function deployed through Terraform and exposed through API Gateway, validating Google reCAPTCHA and sending mail through Amazon SES. There are no reference files; the deliverable is the Terraform configuration and Lambda code.
- Real Estate Brokers: Prepare a Comparative Market Analysis for an investor selling a four-bedroom duplex in Adairsville, Georgia, using an attached CMA template, with 5-10 comparable sales, 3-5 active or pending listings, a low, mid and high valuation range, and list-price and days-on-market graphs, delivered as a PDF.
- Customer Service Representatives: A senior representative at a financial services contact center builds a roughly 10-page PDF training deck on spotting elder abuse and financial exploitation during calls, tying in the Senior Safe Act and FINRA Rule 2165, plus a second PDF of three fictional mutual fund accounts with built-in red flags.
- Compliance Officers: A bank investigator follows up a law-enforcement tip about possible money laundering through two spa businesses, analyzes an attached transaction spreadsheet and produces an annotated spreadsheet and a Suspicious Activity Report.
- Manufacturing: In an example from OpenAI's announcement, a manufacturing engineer designs a jig that lets one person run the reel-in and reel-out test on a cable spooling truck and submits a PDF concept design built from 3D-model snapshots.[1]
Each occupation contributes 30 such tasks in the full set and five in the gold subset. The full set is held back partly to prevent overfitting and partly because OpenAI uses the unreleased 1,100 tasks for its internal model evaluations.
How is GDPval scored?
GDPval-Win
GDPval-Win is the original metric and remains the easiest to interpret. For a given model, it is the share of tasks in which expert graders judge the model's deliverable to be at least as good as the matched human deliverable. Wins and ties both count, with ties usually contributing half a point. A score of 50 percent means the model is, on average, indistinguishable from an industry expert on the gold subset.
This framing has the advantage of being immediately legible to a non-technical audience. The disadvantage is that the human baseline is fixed: every new model is graded against the same set of human deliverables, and as models pass the human level the metric compresses near 50 percent. OpenAI acknowledged this in the paper and indicated that future versions of GDPval would expand the human baseline pool.[2]
GDPval-AA Elo
Artificial Analysis introduced GDPval-AA in late 2025 to address the saturation problem.[10] Instead of scoring against a fixed human baseline, GDPval-AA runs models head-to-head on the same task and used a frontier model as the blind grader (Gemini 3 Pro at launch, then Gemini 3.1 Pro Preview; since GDPval-AA v2 in mid-2026, a panel of three frontier LLM judges). The pairwise wins, losses and ties are fed into a Bradley-Terry maximum-likelihood Elo fit, with confidence intervals from 1,000 bootstrap resamples and the entire scale anchored at GPT-5.1 (Non-Reasoning) = 1,000.[10]
Models are evaluated inside Stirrup, an open-source agentic harness that gives them shell access, a web fetch tool that returns markdown, a Brave-API web search, an image viewer for vision-capable models and a finish action. Each model gets up to 100 turns per task and Stirrup summarizes the context window once it crosses 70 percent of capacity. The benchmark uses all 220 tasks of OpenAI's public gold subset; the 100-turn limit was raised to 250 in GDPval-AA v2 in mid-2026.[11]
GDPval-AA became a common score in frontier model launch announcements, partly because it produces a single number that scales smoothly across hundreds of models and partly because Artificial Analysis built it into its Intelligence Index from v4.0 (January 2026) through v4.3.2; it was removed in v5.0 in late 2026 and is now a standalone evaluation.[11] While it was in the index, GDPval-AA scores were normalized as clamp((Elo - 500) / 2000) and frozen at the time of model addition, so the index value is stable even as later evaluations change the underlying Elo.[11]
How do AI models perform on GDPval?
The paper compared a year of frontier model releases on the gold subset using the human-baseline GDPval-Win metric. The numbers below come from OpenAI's announcement and the v1 arXiv paper.[1][2]
| Model | Release | GDPval-Win on gold subset |
|---|---|---|
| GPT-4o | May 2024 | 12.5% |
| Gemini 2.5 Pro | March 2025 | 25.5% (OpenAI launch chart)[1] |
| o4-mini | April 2025 | 29.1% |
| o3 | April 2025 | 35.2% |
| Grok 4 | July 2025 | 24.3% (OpenAI launch chart)[1] |
| GPT-5 (high reasoning) | August 2025 | 39.0% (OpenAI's launch chart shows 38.8% for GPT-5 high; TechCrunch reported 40.6%)[1][6] |
| Claude Opus 4.1 | August 2025 | 47.6% |
OpenAI presented the chart as evidence that the year-on-year improvement on real economic tasks was approximately linear and that the gap between frontier models and human experts was closing fast; the paper states that "frontier model performance on GDPval is improving roughly linearly over time, and that the current best frontier models are approaching industry experts in deliverable quality."[2] The paper also reported a few more granular findings: increasing reasoning effort improved scores, providing additional task context improved scores, and giving the model a simple agentic scaffold improved scores.[2]
By mid-2026 the leaderboard had moved well past human-expert parity in raw win rate on the gold subset, which is part of why GDPval-AA Elo became the default reporting metric. The Artificial Analysis GDPval-AA leaderboard as archived on May 4, 2026 is shown below; individual Elo values drift by a few points as ratings are refit.[24]
| Rank | Model | GDPval-AA Elo |
|---|---|---|
| 1 | GPT-5.5 (xhigh reasoning) | 1,771 |
| 2 | GPT-5.5 (high reasoning) | 1,754 |
| 3 | Claude Opus 4.7 (Adaptive Reasoning, Max Effort) | 1,753 |
| 4 | Claude Opus 4.7 (Non-reasoning, High Effort) | 1,688 |
| 5 | Claude Sonnet 4.6 (Adaptive Reasoning, Max Effort) | 1,675 |
| 6 | GPT-5.4 (xhigh) | 1,674 |
| 7 | GPT-5.5 (medium) | 1,656 |
| 8 | Claude Opus 4.6 (Adaptive Reasoning, Max Effort) | 1,619 |
| 9 | Claude Sonnet 4.6 (Non-reasoning, High Effort) | 1,591 |
| 10 | Claude Opus 4.6 (Non-reasoning, High Effort) | 1,591 |
OpenAI reported that GPT-5.5 beat or tied industry experts on 84.9 percent of GDPval tasks at its April 2026 launch.[18] It was not the first model past parity on OpenAI's metric: OpenAI had described GPT-5.2 Thinking, at 70.9 percent in December 2025, as its first model performing at or above human expert level.[25] In the May 2026 snapshot no Gemini model reached the GDPval-AA top ten, and the best-placed Chinese models, Xiaomi's MiMo-V2.5-Pro (1,572) and DeepSeek V4 Pro (1,558), sat roughly 200 points below the leaders.[24] As of November 2026 Artificial Analysis runs GDPval-AA v2.1, whose re-anchored scale is not comparable with the table above; Claude Opus 5.5 (Max) led at 1,866, followed by Kimi K3.1 Pro (1,858) and Meta's Muse Wonder Full (Max) (1,857).[10]
How much faster and cheaper are models than human experts on GDPval?
Alongside the win-rate numbers, OpenAI used GDPval to make a cost-and-speed argument that became one of the most quoted findings of 2025. On the gold subset, the company reported that frontier models could complete the tasks roughly 100 times faster and 100 times cheaper than the human industry experts, while cautioning that these figures reflect pure model inference time and API billing rates and leave out human oversight, iteration and integration.[1][2] The faster figure is straightforward: a task that takes a human seven hours can be produced by a model in a few minutes of wall-clock time. The cheaper figure depends on the specific task and on which model is being compared against which professional, but the overall message was that the marginal economic cost of producing a GDPval deliverable had collapsed.
The paper's appendix gives the naive ratios: GPT-5 was about 90 times faster and 474 times cheaper than the human experts, against 327 times faster and 5,172 times cheaper for GPT-4o, with human cost estimated from median BLS wages (an average of 404 minutes and $361 per gold-subset task).[2]
The speed and cost numbers come with two important caveats that GDPval does not measure. First, the model output still has to be reviewed by someone competent before it can be used, and review is not free. Once the paper adds expert review time (about 109 minutes and $86 per task) and the cost of redoing failed work, GPT-5's advantage shrinks to roughly 1.1 to 1.4 times faster and 1.2 to 1.6 times cheaper.[2] Second, the cost numbers exclude integration, data preparation and the capital costs of building the workflows in which a model produces a deliverable; in industry deployments these costs typically dwarf the variable cost of API calls.
What are the criticisms and limitations of GDPval?
GDPval was the most influential AI economic benchmark of 2025-2026, and it attracted criticism from several directions.
The most common methodological complaint was that 66 percent automated-grader agreement against 71 percent human inter-rater agreement is not as close to parity as the headline numbers suggest.[15] The five-point gap is small in absolute terms but big enough that automated grading produces a measurably noisier signal, and most public leaderboards rely on automated grading to scale.
A second line of critique focused on what the benchmark actually measures. GDPval scores a single, isolated deliverable. Real knowledge work involves building context, negotiating scope, getting feedback, revising, and being accountable for downstream consequences. A model that produces a well-formatted nursing care plan in five minutes does not thereby replace a registered nurse. Celia Ford's Transformer News piece pointed out that automating the entry-level pieces of knowledge work could remove the apprenticeship pathway through which people become senior, even if every individual deliverable is fine.[9]
A third critique took aim at the "100x faster, 100x cheaper" framing. The claim is true in the narrow sense that running an OpenAI API call costs less than an hour of a senior accountant's time. It is misleading in the broader sense that it ignores integration costs, oversight overhead, organizational change management, and the cost of being wrong. A paper posted to ResearchGate under the title "Critical Analysis: The Fundamental Flaws in OpenAI's GDPval Evaluation Framework" also challenged the benchmark's design.[17]
A fourth concern is that the 44 occupations, while large compared to other AI benchmarks, still cover only the higher-paying knowledge-work jobs in nine sectors. Construction, transportation, agriculture, hospitality and personal services are absent. The benchmark also under-samples occupations where the work is fundamentally interpersonal, like therapy, teaching or sales, because these tasks are hard to package as graded deliverables.
Finally, several reviewers pointed out that the gold subset only contains 220 tasks (5 per occupation) out of 1,320, and that the agent harness used internally at OpenAI was not open-sourced with the data.[14] Independent reproductions therefore rely on the smaller gold subset and on third-party harnesses like Stirrup, which produce different numbers from the OpenAI internal pipeline.[10] This is the gap that GDPval-AA was designed to fill, but it also means that two leaderboards quoting GDPval scores may be measuring meaningfully different things.
Does GDPval show how close AI is to AGI?
A distinct strand of commentary emerged around how GDPval scores were being used to argue about progress toward artificial general intelligence. Some commentators read "GPT-5 is at 39 percent on GDPval" as "GPT-5 has automated 39 percent of the U.S. knowledge-work economy." Commentators pushed back on this reading. The benchmark measures whether a model can produce a deliverable as good as a human's, on a one-shot task with packaged context. It does not measure whether a model can find the work, scope it, navigate the office politics around it, integrate it into a larger production pipeline, or be held legally and reputationally accountable for its consequences. The gap between "can produce the artifact" and "can do the job" is large, especially in regulated occupations where signing a tax return or a discharge plan carries personal liability.
A related complaint is that GDPval rewards looking right rather than being right. Critics argued that human experts under time pressure tend to weight surface features (formatting, structure, presence of expected sections) more heavily than they weight substantive correctness. A GDPval task that requires a 2,000-word legal brief can be "won" by a model that produces a clean brief that misstates a precedent in paragraph fourteen. The grader, working through a backlog of pairwise comparisons in a few hours, may not catch the misstatement. This is the sort of failure mode that a more interactive evaluation (where a model has to defend its output, revise based on feedback or face a senior reviewer) would surface, and it is not part of GDPval-v0.
How was GDPval received?
The September 25, 2025 release got broad press coverage. TechCrunch led with the framing that GPT-5 "stacks up to humans in a wide range of jobs," Axios emphasized that "AI is catching up to human work," and the Marketing AI Institute drove the "100x faster and cheaper" line into general circulation.[6][7][8] OpenAI's announcement said that "When AI complements workers in this way it can translate into significant economic growth."[1] Chatterji later cited GDPval's "quite a steep curve of improvement" on MIT Sloan Management Review's podcast, describing AI as "a real complement for people with deep expertise."[23]
The academic reception was more mixed. AI safety researchers welcomed the move toward economically grounded evaluation but cautioned that GDPval was not measuring autonomy, planning, or long-horizon decision making, all of which the International AI Safety Report had identified as the capabilities most relevant to systemic risk.
Industry adoption was rapid and almost universal. Within months OpenAI was reporting GDPval in its own launches (GPT-5.2 in December 2025, GPT-5.5 in April 2026), and GDPval-AA results became common in other developers' launch materials.[18][25] Artificial Analysis added GDPval-AA to its Intelligence Index v4.0 in early 2026 as a replacement for the by-then-saturated MMLU-Pro, AIME 2025 and LiveCodeBench, a change DeepLearning.AI's The Batch summed up as "saturated benchmarks need to be replaced by more meaningful measures."[11][26] Artificial Analysis later upgraded the evaluation to GDPval-AA v2 (mid-2026, with a three-judge LLM panel and a 250-turn limit) and v2.1 (September 2026), and removed it from Intelligence Index v5.0 in late 2026, keeping it as a standalone evaluation.[11]
Developer communities had a more skeptical reaction. The LessWrong piece on GPT-5.5 by Zvi Mowshowitz noted that OpenAI's GDPval results and the GDPval-AA scores disagreed on whether Claude Opus 4.7 trailed GPT-5.4, and that win rates against a human "stop being a great metric in the 80s."[19] Pranil Dasika argued on Medium that the automated grader's 66 percent agreement mattered more for enterprise deployment than the roughly 48 percent headline win rate.[15]
OpenAI itself acknowledged the limits in its announcement, calling GDPval "an early step that doesn't reflect the full nuance of many economic tasks" and noting that the one-shot evaluation does not capture cases where a model needs to build context or improve through multiple drafts.[1] They committed to expanding the benchmark to more occupations, more interactive tasks and richer multimodal deliverables.
Has GDPval been updated since launch?
As of May 2026, OpenAI had not released a formally numbered "GDPval v2." The paper describes the September 2025 release as "the first version of GDPval" and says future iterations will add breadth, realism and interactivity.[2] Subsequent additions and variants include the following.
| Variant | Released by | Description |
|---|---|---|
| GDPval-v0 | OpenAI, Sep 25 2025 | Original 1,320-task release; 220-task gold subset open-sourced.[1] |
| GDPval-AA | Artificial Analysis, late 2025 | Independent agentic reimplementation of the gold subset using the Stirrup harness; produces an Elo leaderboard via Bradley-Terry fits.[10] |
| GDPval-AA v2 and v2.1 | Artificial Analysis, June and September 2026 | Upgraded sandbox, panel of three LLM judges and 250-turn limit; v2.1 fits ratings with a Crowd-BT model and pins DeepSeek V4.1 Flash (max) at 1,600.[11] |
| GDPval Inspect | Inspect Evals repository (UKGovernmentBEIS), 2026 | Community-contributed Inspect implementation of the 220-task gold subset; outputs are scored by submitting them to OpenAI's automated grader.[13] |
OpenAI has signaled an interest in expanding the underlying dataset to add more interactive multi-turn tasks, occupations outside the original nine industries, and richer rubrics that capture quality dimensions other than "is this as good as the human's version." A formal v2 release had not been announced as of the article's writing.
How does GDPval compare with other benchmarks?
GDPval is part of a small but growing family of benchmarks that try to measure economic or professional value rather than raw cognitive capability. The table below sketches the most-cited cousins.
| Benchmark | Released | Domain | Headline metric | Compared with GDPval |
|---|---|---|---|---|
| SWE-bench | Princeton, Oct 2023 | Real GitHub issues in 12 Python repos | Patch resolution rate | Narrower (software only) but more verifiable; resolution is automated via test suites. |
| RE-Bench (METR) | METR, late 2024 | ML research engineering tasks | Performance vs. human researchers | Focused on a single occupation; uses long agentic time budgets. |
| REALCODE | 2024 | Real codebase tasks | Code edit success | Code-focused, narrower scope than GDPval. |
| Humanity's Last Exam | CAIS, Jan 2025 | Cross-domain expert questions | Answer accuracy | Tests reasoning depth, not deliverable production. |
| ARC-AGI-2 | ARC Prize, Mar 2025 | Abstract puzzle grids | Solve rate | Tests fluid intelligence on synthetic tasks. |
| MMLU | Hendrycks et al., 2020 | Multiple-choice academic | Accuracy | Saturated; tests recall not work product. |
| GDPval | OpenAI, Sep 2025 | 44 BLS knowledge-work occupations | Win rate against human expert deliverables | Anchored to GDP and BLS wages; produces real artifacts. |
GDPval's distinguishing feature in this group is the explicit GDP weighting and the human-baseline framing. SWE-bench tells you whether your model can fix a Python bug. RE-Bench tells you whether it can replicate ML research. GDPval tells you, in dollar-weighted terms, how much of the U.S. knowledge-work economy your model can plausibly produce a passable artifact for. None of these benchmarks measures whether the artifact would actually solve the underlying business problem, which is the open question the next generation of evaluations is trying to answer.
How does GDPval connect to the International AI Safety Report?
The International AI Safety Report 2026, published in February 2026, cites the GDPval paper as an example of recent benchmarks that measure AI performance on economically valuable tasks, in a passage noting that conventional evaluations often overestimate AI systems' practical utility in real-world settings.[27]
The benchmark also sits inside the broader set of AI safety and automation discussions that have shaped policy through 2026.
Continue reading
- OpenAIOpenAI is an American artificial intelligence research and deployment organization.Mentioned 46 times above
- GPT-5GPT-5 is a family of proprietary large language models released by OpenAI on August 7, 2025.Mentioned 22 times above
- Gemini 3Gemini 3 is the third major generation of the Gemini family of multimodal models from Google DeepMind, launched on November 18, 2025 with Gemini 3 Pro as the flagship and described by Google as "our most…Mentioned 4 times above
- MMLUMMLU, short for Massive Multitask Language Understanding, is an English-language AI benchmark for evaluating broad academic and professional knowledge through four-option multiple-choice questions.Mentioned 4 times above
- Claude Opus 4.7Claude Opus 4.7 is a hybrid reasoning large language model released by Anthropic on April 16, 2026 as the company's most capable generally available model at launch.Mentioned 3 times above
- International AI Safety ReportThe International AI Safety Report is the first independent, government-mandated scientific assessment of the capabilities, risks, and safety of general-purpose artificial intelligence, written by an…Mentioned 3 times above
More from See also
- GPT-5.4
- Claude Opus 4.5
- DeepSeek-R1
- SWE-bench
- Humanity's Last Exam
- ARC-AGI-2
- GPQA
- Large Language Model
- America's AI Action Plan
- BLS
- Sam Altman
Topics:AI BenchmarksAI Research
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16OpenAI. "Measuring the performance of our models on real-world tasks." September 25, 2025. openai.com/...gdpval
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31Patwardhan, Tejal, Rachel Dias, Elizabeth Proehl, Grace Kim, Michele Wang, Olivia Watkins, Simon Posada Fishman, Marwan Aljubeh, Phoebe Thacker, Laurance Fauconnet, Natalie S. Kim, Patrick Chao, Samuel Miserendino, Gildas Chabot, David Li, Michael Sharman, Alexandra Barr, Amelia Glaese, and Jerry Tworek. "GDPval: Evaluating AI Model Performance on Real-World Economically Valuable Tasks." arXiv:2510.04374, October 5, 2025. arxiv.org/...2510.04374
- OpenAI. "GDPval Technical Report." cdn.openai.com/...GDPval.pdf
- ^1 ^2 ^3 ^4Hugging Face. "openai/gdpval Dataset Card." huggingface.co/...gdpval
- ^1 ^2OpenAI. "Dr. Ronnie Chatterji named OpenAI's first Chief Economist." openai.com/...openai-chief-economist-announcement
- ^1 ^2Wiggers, Kyle. "OpenAI says GPT-5 stacks up to humans in a wide range of jobs." TechCrunch, September 25, 2025. techcrunch.com/...o-humans-in-a-wide-range-of-jobs
- ^Axios. "OpenAI's new GDPval benchmark shows AI catching up to human work." September 25, 2025. axios.com/...chatgpt-gdp-val-ai-study
- ^Marketing AI Institute. "OpenAI's New Benchmark Shows AI Does Knowledge Work 100X Faster and Cheaper Than Experts." marketingaiinstitute.com/...openai-gdpval
- ^Ford, Celia. "OpenAI's GDPval benchmark measures when AI can do your job." Transformer News, October 2, 2025. transformernews.ai/...openai-gdpval-ai-jobs-work
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Artificial Analysis. "GDPval-AA Leaderboard." artificialanalysis.ai/...gdpval-aa
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Artificial Analysis. "Intelligence Benchmarking Methodology." artificialanalysis.ai/...intelligence-benchmarking
- ^Epoch AI. "GDPval." epoch.ai/...gdpval
- ^UK Government BEIS. "GDPval Inspect Evaluation." ukgovernmentbeis.github.io/...gdpval
- ^Aurora, Aman. "GDPVAL: Evaluating AI Model Performance on Real-World Economically Valuable Tasks." December 15, 2025. amaarora.github.io/...2025-12-15-gdpval-review
- ^1 ^2Dasika, Pranil. "OpenAI's GDPval: Why the 66% Automated Grading Problem Matters More Than the 48% Win Rate." Medium. medium.com/...re-than-the-48-win-rate-a5e542508196
- Innovative Human Capital. "The GDP Benchmark: A New Frontier for Measuring AI Capabilities in Professional Knowledge Work." innovativehumancapital.com/...ional-knowledge-work
- ^ResearchGate. "Critical Analysis: The Fundamental Flaws in OpenAI's GDPval Evaluation Framework." researchgate.net/...'s_GDPval_Evaluation_Framework
- ^1 ^2MarkTechPost. "OpenAI Releases GPT-5.5, a Fully Retrained Agentic Model That Scores 82.7% on Terminal-Bench 2.0 and 84.9% on GDPval." April 23, 2026. marktechpost.com/...l-bench-2-0-and-84-9-on-gdpval
- ^Mowshowitz, Zvi. "GPT-5.5: Capabilities and Reactions." LessWrong. lesswrong.com/...gpt-5-5-capabilities-and-reactions
- ^Eloundou, Tyna, Sam Manning, Pamela Mishkin, and Daniel Rock. "GPTs are GPTs: An Early Look at the Labor Market Impact Potential of Large Language Models." 2023.
- ^Acemoglu, Daron, and David Autor. "Skills, Tasks and Technologies: Implications for Employment and Earnings." Handbook of Labor Economics, 2011.
- OpenAI Forum. "Thinking Machines & AI Economics: How Reasoning AI Is Rewriting the Future of Work, Science, and Strategy." 2025. forum.openai.com/...ai-economics-in-the-forum-2025
- ^MIT Sloan Management Review. "Science, Innovation, and Economic Growth: OpenAI's Ronnie Chatterji." sloanreview.mit.edu/...th-openais-ronnie-chatterji
- ^1 ^2Artificial Analysis. "GDPval-AA Leaderboard." Archived May 4, 2026. web.archive.org/...gdpval-aa
- ^1 ^2OpenAI. "Introducing GPT-5.2." December 11, 2025. web.archive.org/...introducing-gpt-5-2
- ^DeepLearning.AI. "Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Tests." The Batch, January 30, 2026. deeplearning.ai/...hmarks-to-harder-business-tests
- ^Bengio, Yoshua, et al. "International AI Safety Report 2026." February 2026. arXiv:2602.21012. arxiv.org/...2602.21012
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
6 revisions · v6 · 5,972 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (150 claims, 34 sources fetched); 37 material + 30 minor fixed
Cite this page: AI Wiki. "GDPval." aiwiki.ai, updated 27 Jun 2026, fact-checked 4 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/gdpval