

Grouped-Query Attention
Grouped-query attention (GQA) is an attention mechanism for transformer language models that partitions the query heads into a small number of groups, where every query head in a group shares one key projection and one value projection. It was introduced by Joshua Ainslie, James Lee-Thorp, Michiel de Jong, Yury Zemlyanskiy, Federico Lebron, and Sumit Sanghai of Google Research in a paper submitted to arXiv on May 22, 2023 and published at EMNLP 2023, and it sits between multi-head attention (a separate key/value head for every query head) and multi-query attention (a single shared key/value head). [1] GQA cuts the size of the key/value (KV) cache by a factor of H/G (the number of query heads divided by the number of groups), which speeds up autoregressive inference while keeping output quality close to standard multi-head attention. The paper's stated result is that "uptrained GQA achieves quality close to multi-head attention with comparable speed to MQA." [1] Model developers adopted it quickly: Meta used it in the two largest Llama 2 configurations (34B and 70B) and in every Llama 3 size, and it is documented in the technical reports or configuration files of Mistral 7B, Qwen2 and Qwen3, Gemma 2 and Gemma 3, and OpenAI's gpt-oss, among others. [4][5][6][7][14][16][17][20]
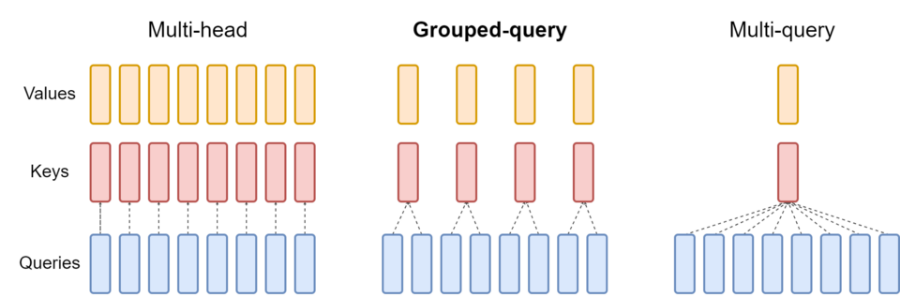
The core idea interpolates between the two extremes of the attention design space: full multi-head attention, which maintains independent K/V heads for every query head, and multi-query attention, which collapses all K/V heads into one. By sitting between these extremes, GQA achieves a large reduction in the size of the KV cache with only a small degradation in model quality. [1]
What problem does GQA solve?
The KV Cache Bottleneck
During the autoregressive decoding phase of transformer inference, a model generates one token at a time. At each step, the model must compute attention over every token in the context window. To avoid recomputing the key and value projections of all previous tokens at every step, practical inference systems maintain a KV cache, a stored buffer of the K and V tensors for each layer and each prior token. [2]
The memory cost of the KV cache grows as:
For a large model serving long contexts at scale, this can reach tens of gigabytes. Llama 2 13B, for example, uses standard multi-head attention with 40 layers and 40 key/value heads of dimension 128. [11] Plugging those values into the formula at a 4,096-token context with batch size 8 and 16-bit storage gives about 26.8 GB (25 GiB) for the KV cache alone. Beyond raw memory, the decoding step is memory-bandwidth-bound: for each new token, the accelerator must read the entire KV cache from memory to compute a single attention query. The ratio of computation to memory access is low, so throughput is limited by how fast the hardware can move data rather than by floating-point throughput. Noam Shazeer framed this directly in the multi-query attention paper, writing that incremental inference "is often slow, due to the memory-bandwidth cost of repeatedly loading the large 'keys' and 'values' tensors." [2]
Reducing the number of K/V heads directly reduces both the memory footprint and the bandwidth requirement, making the decoding step faster without changing the arithmetic of the attention computation itself. [2]
Multi-Head Attention
The original transformer architecture described by Vaswani et al. (2017) uses Multi-Head Attention (MHA). [3] In MHA, an input hidden state of dimension $d_{\text{model}}$ is linearly projected into $h$ separate query, key, and value vectors, each of dimension $d_k = d_{\text{model}} / h$. Attention scores are computed independently in each of the $h$ heads, and the results are concatenated and projected back to $d_{\text{model}}$. [3]
MHA is expressive because each head attends to different parts of the context using its own key and value projections. The KV cache size scales linearly with $h$: for a model with $h$ heads, $L$ layers, head dimension $d_k$, sequence length $T$, and batch size $B$, the cache requires $2 \cdot h \cdot d_k \cdot L \cdot T \cdot B$ elements (times bytes per element for a concrete figure).
Multi-Query Attention
In November 2019, Noam Shazeer proposed Multi-Query Attention (MQA) in the paper "Fast Transformer Decoding: One Write-Head is All You Need" (arXiv:1911.02150). MQA retains $h$ independent query projections but uses only a single shared key head and a single shared value head across all query heads. In Shazeer's description, multi-query attention "is identical except that the different heads share a single set of keys and values." [2]
The impact on memory is large. Compared to MHA, MQA reduces the number of K/V elements by a factor of $h$: for a model with 32 attention heads, the KV cache shrinks by about 97%. In the paper's own experiments (a 211-million-parameter encoder-decoder model on WMT 2014 English-German, measured on one TPUv2 with a batch of 1,024 sequences), amortized decoder inference time fell from 46 microseconds per token for the multi-head baseline to 3.8 microseconds for the multi-query model, while a training step took 433 ms versus 425 ms. [2] Shazeer reported that the resulting models "can indeed be much faster to decode, and incur only minor quality degradation from the baseline." [2]
MQA has costs that later work documented. The GQA paper notes that MQA "can lead to quality degradation and training instability." In its appendix, T5-Large models trained with multi-query attention from scratch suffered frequent loss spikes during pre-training and diverged immediately when fine-tuned on long-input tasks. [1] The same paper showed that an existing multi-head checkpoint can be converted to MQA cheaply, by uptraining with about 5% of the original pre-training compute, which is the starting point for GQA. [1]
What does the GQA paper (May 2023) propose?
The paper "GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints" (arXiv:2305.13245) by Joshua Ainslie, James Lee-Thorp, Michiel de Jong, Yury Zemlyanskiy, Federico Lebron, and Sumit Sanghai of Google Research was submitted to arXiv on May 22, 2023 and published in the Proceedings of EMNLP 2023 (pages 4895-4901); the third and latest arXiv version is dated December 23, 2023. [1] The first three authors are marked as equal contributors, and de Jong is listed with the University of Southern California, with the work done at Google Research. [1]
The paper makes two related contributions, stated in its abstract as: "(1) propose a recipe for uptraining existing multi-head language model checkpoints into models with MQA using 5% of original pre-training compute, and (2) introduce grouped-query attention (GQA), a generalization of multi-query attention which uses an intermediate (more than one, less than number of query heads) number of key-value heads." [1] The first contribution is a practical uptraining procedure for converting existing MHA checkpoints to either MQA or GQA format without requiring full retraining. The second introduces GQA itself. The authors also note in their related-work section that "Rabe (2023) independently developed GQA with public implementation," referring to a memory-efficient attention module in Google's Flaxformer library. [1]
Uptraining Procedure
Converting a pre-trained MHA model requires transforming the K/V projection matrices from $H$ independent heads down to $G$ grouped heads (where $G < H$). In the authors' words, "the projection matrices for key and value heads are mean pooled into single projection matrices": all the original K heads assigned to a given group are averaged element-wise to produce the single K head for that group, and the same is done for V heads. [1] In an ablation on T5-Large converted to MQA, mean pooling worked best, followed by keeping only the first head and then random initialization; the authors explain the ordering by "the degree to which information is preserved from the pre-trained model." [1]
After this structural conversion, the model is further pre-trained ("uptrained") for a small proportion $\alpha$ of its original training steps, using the same pre-training recipe and data. The main experiments use $\alpha = 0.05$, and the paper reports that "for $\alpha$ = 0.05, training took approximately 600 TPUv3 chip-days" for T5-XXL. [1] An ablation over $\alpha$ (Figure 5 of the paper) found that GQA "already achieves reasonable performance after conversion while MQA requires uptraining to be useful," and that both "gain from 5% uptraining with diminishing returns from 10%." [1]
Experimental Setup
All models are based on the T5.1.1 encoder-decoder architecture, implemented in JAX, Flax and Flaxformer. The main comparison covers multi-head T5 Large and T5-XXL, plus T5-XXL checkpoints uptrained to MQA and to GQA with 8 groups. GQA and MQA were applied to decoder self-attention and cross-attention but not to encoder self-attention, because encoder representations are computed in parallel and memory bandwidth "is therefore generally not the primary bottleneck." [1] Evaluation used five summarization datasets (CNN/Daily Mail, arXiv, PubMed, MediaSum, Multi-News), WMT 2014 English-to-German translation, and TriviaQA question answering. Timing is reported as time per sample per TPUv4 chip, measured on 8 TPUs with the largest batch size that fits up to 32 per TPU. [1]
How does GQA work?
Query Head Grouping
GQA divides the $H$ query heads into $G$ equally sized groups. All query heads within a group share a single key projection and a single value projection. The notation GQA-$G$ denotes grouped-query attention with $G$ groups. [1]
The two limiting cases recover existing methods:
- GQA-1: All query heads share one K/V pair, equivalent to MQA.
- GQA-$H$: Each query head has its own K/V pair, equivalent to standard MHA. [1]
For an intermediate value of $G$, GQA has $G$ K/V heads instead of 1 (as in MQA) or $H$ (as in MHA). The KV cache is reduced by a factor of $H / G$ relative to MHA. [1]
Attention Computation
At inference time, for each group $g$ ($g = 1, \ldots, G$), the query heads in that group attend to the shared K/V pair for that group. If there are $H/G$ query heads per group, the attention scores for those heads are computed as:
where $K_g$ and $V_g$ are the shared key and value matrices for group $g$. The outputs of all $H$ heads are then concatenated and linearly projected as in standard MHA. [1] With contiguous grouping, the FlashAttention library's documentation gives a concrete example: if Q has 6 heads and K and V have 2, query heads 0, 1 and 2 attend to K/V head 0, and query heads 3, 4 and 5 attend to K/V head 1. [36]
The arithmetic of training and prefill (the first forward pass over the prompt) is almost unchanged, apart from the smaller K and V projections. The benefit of GQA appears primarily at the decode step, where the number of K/V entries that must be loaded from the KV cache is reduced by a factor of $H / G$. NVIDIA's July 2026 kernel measurements illustrate the split: varying the number of query heads per K/V head from 1 (MHA) to 64 (MQA) changed prefill runtime by under 1%, while decode runtime fell roughly 2x each time the number of K/V heads was halved. [10]
KV Cache Reduction
For a model with $H$ query heads, $G$ K/V groups, $d_k$ head dimension, $L$ layers, sequence length $T$, batch size $B$, and 2 bytes per element (float16):
- MHA: $2 \cdot H \cdot d_k \cdot L \cdot T \cdot B \cdot 2$ bytes
- GQA-$G$: $2 \cdot G \cdot d_k \cdot L \cdot T \cdot B \cdot 2$ bytes
- MQA: $2 \cdot 1 \cdot d_k \cdot L \cdot T \cdot B \cdot 2$ bytes
The reduction factor of GQA over MHA is $H / G$. For Llama 3.1 8B with 32 query heads and 8 K/V heads, the KV cache is 4x smaller than it would be with MHA. [5]
How does GQA differ from MHA and MQA?
Quality and Speed Tradeoffs
The GQA paper's main result is that GQA-8-XXL (a T5-XXL model uptrained with 8 K/V groups) comes close to MHA-XXL in quality while running at near-MQA speed. The paper summarizes this as: "GQA achieves significant additional quality gains, achieving performance close to MHA-XXL with speed close to MQA." [1] Selected results from Table 1 of the paper (the "Average" column averages all seven tasks, mixing ROUGE-1 for the summarization sets, BLEU for WMT and F1 for TriviaQA):
| Model | Inference time per sample (T_infer) | Average | WMT (BLEU) | TriviaQA (F1) |
|---|---|---|---|---|
| MHA-Large | 0.37 | 46.0 | 27.7 | 78.2 |
| MHA-XXL | 1.51 | 47.2 | 28.4 | 81.9 |
| MQA-XXL | 0.24 | 46.6 | 28.5 | 81.3 |
| GQA-8-XXL | 0.28 | 47.1 | 28.4 | 81.6 |
MHA-XXL has the best average but is about 6x slower than MQA-XXL. GQA-8-XXL is 0.1 points below MHA-XXL on the average while being only slightly slower than MQA-XXL. [1] The uptrained MQA-XXL model also beat MHA-Large on both quality and speed, which the authors describe as a favorable tradeoff in its own right. [1]
The authors list several limits on these results: the experiments cover only encoder-decoder models, ROUGE is "a flawed evaluation that does not tell the whole story," and because of limited compute they did not compare the uptrained XXL GQA model against one trained from scratch. They expected GQA to have "a stronger advantage over MQA" in decoder-only models, which lack a separate cross-attention. [1]
Architectural Comparison Table
| Property | MHA | GQA-$G$ | MQA |
|---|---|---|---|
| K/V heads | $H$ | $G$ (where $1 < G < H$) | 1 |
| KV cache size | baseline | $G/H$ of MHA | $1/H$ of MHA |
| Decode bandwidth for K/V | highest | $G/H$ of MHA | lowest |
| Model quality | best | close to MHA | degraded |
| Introduced | Vaswani et al. (2017) | Ainslie et al. (2023) | Shazeer (2019) |
With 32-64 query heads and 8 K/V heads, a configuration used by Llama 3 8B and 70B, Mistral 7B, Qwen2.5-72B and several Qwen3 models, GQA reduces the KV cache to 25% or 12.5% of the MHA baseline. [5][6][13][14]
Performance Tradeoffs
How many groups should GQA use?
Figure 6 of the GQA paper plots inference time per sample for GQA-XXL as the number of groups rises from 1 (MQA) to 64 (MHA), at input length 2,048 and output length 512. Going from 1 to 8 groups adds modest inference overhead, with the cost increasing faster as the model approaches MHA. The authors explain that for larger models the KV cache is a smaller share of the memory-bandwidth overhead while the key-value reduction is sharper because there are more heads, and conclude: "We selected 8 groups as a favorable middle ground." [1]
Released models do not all follow that choice. Among the models in the adoption tables below, 8 K/V heads is the most common value (Llama 3, Mistral 7B, Mixtral 8x7B, Qwen2.5-14B and 72B, Qwen3 dense models, Yi-34B, gpt-oss), but Gemma 2 keeps two query heads per K/V head (for example 16 query and 8 K/V heads in the 9B model), Qwen3's MoE models use 4 K/V heads, and Qwen3.5's full-attention layers use 2. [5][6][14][15][16][19][20][21]
Two 2025-2026 analyses argue for fewer K/V heads than the 2023 default:
- Context-length-aware sizing. Chen et al. ("Cost-Optimal Grouped-Query Attention for Long-Context Modeling," EMNLP 2025) analyse how context length, model size, GQA configuration and loss interact. They conclude that "commonly used GQA configurations are highly suboptimal for long-context scenarios," that long-context models "should use fewer attention heads while scaling up the model size," and that configurations chosen by their recipe "can reduce both memory usage and FLOPs by more than 50% compared to Llama-3's GQA, with no degradation in model capabilities." [34]
- Hardware guidance. In a July 31, 2026 post on attention co-design, NVIDIA argues that the number of query heads sharing each K/V head should be chosen for decode efficiency and pushed high: in NVIDIA's analysis, decode arithmetic intensity scales roughly as twice that ratio, and measured decode runtime falls about 2x each time the K/V head count is halved, while prefill runtime stays essentially flat (varying the ratio from 1, MHA, to 64, MQA, changed prefill runtime by under 1%). The same post notes the parallelism consequence: tensor parallelism should stay at or below the K/V head count to avoid duplicating the KV cache across GPUs, so models with very few K/V heads, such as NVIDIA's Nemotron 3 with two, are scaled with attention data parallelism or KV parallelism instead. [10]
Quality evidence from model developers
Developers who trained GQA models from scratch have published ablations that do not all agree on the size of the quality cost:
| Study | Setup | Reported result |
|---|---|---|
| Llama 2 paper (Meta, July 2023) | 30B models trained on 150B tokens; FFN widened 1.3x (GQA) or 1.33x (MQA) to match parameters | GQA "performs comparably to the MHA baseline on most evaluation tasks and is better than the MQA variant on average" [4] |
| Gemma 2 report (Google, July 2024) | Two instances of the 9B model, MHA versus GQA | Average over 4 benchmarks: 50.3 (MHA) versus 50.8 (GQA); "overall few changes in performance" [16] |
| DeepSeek-V2 report (DeepSeek-AI, May 2024) | 7B dense models trained on 1.33T tokens, parameters aligned by adjusting layer count | MMLU 45.2 (MHA), 41.2 (GQA, 8 groups), 37.9 (MQA); "MHA demonstrates significant advantages over GQA and MQA on hard benchmarks" [8] |
Training vs. Inference Overhead
During training, GQA has nearly the same computational cost as MHA when the full sequence is processed in parallel; only the K/V projection matrices are smaller, by a factor of $H/G$. The uptraining procedure adds compute when converting an MHA checkpoint (about 5% of the original pre-training in the paper's setup), but a model designed with GQA from the start needs no conversion. [1]
At inference time, the benefit is concentrated in the decode phase and grows with sequence length and batch size. A worked example: with MHA (32 heads, head dimension 128), a single layer at sequence length 8,192 holds 32 x 128 x 8,192 x 2 (K and V) x 2 bytes (bfloat16) = about 134 MB of K/V per sequence, all of which is read at every decode step. With 8 K/V heads instead of 32, the same layer holds about 33.5 MB, a 4x reduction in the bytes that must be loaded. NVIDIA's measurements show decode runtime tracking this reduction closely at long KV lengths, falling about 2x per halving of the K/V head count. [10]
Memory vs. Quality Frontier
The standard GQA recipe assigns neighbouring query heads to the same group. Research on MHA-to-GQA conversion has looked at smarter grouping. Chen et al.'s AsymGQA (2024, presented at the ICML 2024 ES-FoMo-II workshop) groups heads using activation similarity and allows groups of unequal size; when converting LLaMA-2-7B to GQA, the authors report "an accuracy increase of 7.5% on MMLU compared to neighbour grouping." [33] The authors also report that naive mean-pooled merging "can cause a significant quality degradation even after fine-tuning" in their setting. [33]
Which models use GQA?
LLaMA 2
LLaMA 2, which Meta released on July 18, 2023, uses GQA only in its larger configurations. The paper's model table says the bigger models, 34B and 70B, use GQA "for improved inference scalability," while the 7B and 13B models use standard MHA (their released configurations have 32 and 40 K/V heads respectively, equal to their query heads). Meta trained the 34B model but delayed its release "due to a lack of time to sufficiently red team," so among the released checkpoints only the 70B model uses GQA. [4][11] The 70B checkpoint has 64 query heads and 8 K/V heads (GQA-8), an 8x reduction relative to MHA with the same head count. [11]
The paper gives two reasons for choosing GQA over MQA for the 34B and 70B models: its 30B ablation (see the table above), and serving practicalities. Meta hosted its largest models on 8 A100 GPUs with tensor parallelism, and with MQA "sharding for MQA cannot be done across heads anymore, given the number of heads is lower than the number of GPUs," forcing either duplicated KV values on every GPU or batch-dimension sharding. [4] The Llama 2 technical report cites the GQA paper as the source of the technique. [4]
LLaMA 3
LLaMA 3, released by Meta starting in April 2024, extends GQA to all model sizes. The Llama 3 report states that the family uses "grouped query attention (GQA; Ainslie et al. (2023)) with 8 key-value heads to improve inference speed and to reduce the size of key-value caches during decoding." [5] Table 3 of the report lists the attention configuration of the 8B, 70B and 405B models (the 405B model was released as part of Llama 3.1 in July 2024): [5]
| Model | Query heads | K/V heads | KV cache reduction vs. MHA |
|---|---|---|---|
| Llama 3 8B | 32 | 8 | 4x |
| Llama 3 70B | 64 | 8 | 8x |
| Llama 3 405B | 128 | 8 | 16x |
All three sizes are GQA-8 (8 K/V groups); the differing reduction factors come from the differing query-head counts. The report also notes that GQA helps its context-parallel training, since the K and V tensors that must be communicated are much smaller than the Q tensor. [5]
Mistral 7B
Mistral 7B, released by Mistral AI on September 27, 2023 and described in an October 2023 paper (arXiv:2310.06825, Jiang et al.), uses GQA alongside sliding window attention (SWA). The paper states that the model "leverages grouped-query attention (GQA) for faster inference, coupled with sliding window attention (SWA) to effectively handle sequences of arbitrary length with a reduced inference cost." [6] Its architecture table lists 32 query heads and 8 K/V heads, the same ratio as Llama 3 8B, and the paper says GQA reduces "the memory requirement during decoding, allowing for higher batch sizes hence higher throughput." [6]
The pairing of GQA with sliding window attention was notable because both techniques address the same bottleneck (KV cache memory and bandwidth) from different angles. [6] The open-weight Mixtral 8x7B mixture-of-experts model kept the 32-query, 8-K/V-head layout. [21] Mistral did not keep GQA across its whole line, though: the configuration of Mistral Large 3 (December 2025) specifies multi-head latent attention parameters (a 512-dimensional KV latent and a 1,536-dimensional query latent) rather than a reduced K/V head count. [22]
Qwen
Qwen, Alibaba's open-weight model family, first used GQA in Qwen1.5-32B, released on April 2, 2024; the Qwen team wrote that apart from size there was "almost nothing different in model architecture except for the inclusion grouped query attention (GQA)." [12] The smaller Qwen1.5 models such as Qwen1.5-7B kept MHA (32 query and 32 K/V heads). [12] With Qwen2 (technical report July 2024), GQA became standard across the family: the technical report states "We adopt Grouped Query Attention (GQA, Ainslie et al., 2023) instead of conventional multi-head attention (MHA)," noting that GQA "optimizes KV cache usage during inference, significantly enhancing throughput." [7]
| Model | Query heads | K/V heads | Source |
|---|---|---|---|
| Qwen2-0.5B | 14 | 2 | Qwen2 report [7] |
| Qwen2-7B | 28 | 4 | Qwen2 report [7] |
| Qwen2-72B | 64 | 8 | Qwen2 report [7] |
| Qwen2.5-14B | 40 | 8 | config.json [13] |
| Qwen2.5-72B | 64 | 8 | config.json [13] |
| Qwen3-0.6B and 1.7B | 16 | 8 | Qwen3 report [14] |
| Qwen3-8B | 32 | 8 | Qwen3 report [14] |
| Qwen3-32B | 64 | 8 | Qwen3 report [14] |
| Qwen3-30B-A3B (MoE) | 32 | 4 | Qwen3 report [14] |
| Qwen3-235B-A22B (MoE) | 64 | 4 | Qwen3 report [14] |
| Qwen3.5-397B-A17B (full-attention layers) | 32 | 2 | model card [15] |
The Qwen3 report (May 2025) lists GQA among the dense models' architectural components, says the MoE models "share the same fundamental architecture," and gives the head counts above for all eight models. [14] Qwen3.5 (February 2026) is a hybrid: its 60-layer flagship stacks three Gated DeltaNet linear-attention layers for every gated softmax-attention layer, and those attention layers use 32 query heads and 2 K/V heads. [15]
Other Models
The following open-weight models document GQA (or, where noted, not) in a technical report or in the num_attention_heads and num_key_value_heads fields of their released configuration files:
| Model (developer, release) | Query heads | K/V heads | Notes | Source |
|---|---|---|---|---|
| Gemma 2 2B / 9B / 27B (Google, 2024) | 8 / 16 / 32 | 4 / 8 / 16 | All sizes use GQA with "num_groups = 2" | [16] |
| Gemma 3 (Google, March 2025) | not listed | not listed | Report states the models "use a Grouped-Query Attention (GQA)" | [17] |
| Phi-3-mini (Microsoft, 2024) | 32 | 32 | Standard MHA, not GQA | [18] |
| Phi-3-small / Phi-3-medium (Microsoft, 2024) | 32 / 40 | 8 / 10 | GQA | [18] |
| Phi-4 14B / Phi-4-mini (Microsoft, 2024-2025) | 40 / 24 | 10 / 8 | GQA | [18] |
| Yi-6B / Yi-34B (01.AI, 2023-2024) | 32 / 56 | 4 / 8 | Yi paper: GQA in both sizes | [19] |
| gpt-oss-120b and 20b (OpenAI, August 2025) | 64 | 8 | Model card: GQA "with 8 key-value heads" | [20] |
| GLM-4.5 (Zhipu AI, July 2025) | 96 | 8 | GQA | [27] |
| MiniMax M2 (MiniMax, October 2025) | 48 | 8 | GQA | [28] |
| Nemotron 3 (NVIDIA) | not listed | 2 | Cited by NVIDIA as a GQA model with two K/V heads | [10] |
How does GQA compare to Multi-Head Latent Attention?
Multi-head Latent Attention (MLA), introduced in the DeepSeek-V2 technical report (May 2024) and used in DeepSeek V3 (December 2024), takes a different approach to the KV cache bottleneck. [8] The MLA article covers its mechanism in detail; this section summarizes the comparison with GQA.
How MLA Works
Instead of reducing the number of K/V heads (as GQA does), MLA compresses keys and values jointly into a low-rank latent vector using a learned down-projection, and caches that latent plus a small decoupled key that carries the rotary position embedding. Full per-head keys and values are produced from the latent by learned up-projections; at inference time, these up-projections can be absorbed into the query and output projections so that K and V never need to be materialized. [8]
DeepSeek-V2 gives the cache per token as $(d_c + d_h^R) \cdot l$ elements, where $d_c$ is the KV compression dimension, $d_h^R$ the decoupled key dimension and $l$ the number of layers. With $d_c = 4 d_h$ and $d_h^R = d_h / 2$, this equals the cache of GQA "with only 2.25 groups." [8]
Comparison Table
| Property | GQA | MLA (DeepSeek) |
|---|---|---|
| Cache compression method | Reduce number of K/V heads | Joint low-rank compression of K and V |
| KV cache per token per layer (elements) | $2 \cdot G \cdot d_h$ | $d_c + d_h^R$ (576 in DeepSeek-V3) |
| Example vs. MHA with the same heads | 8x for 64 query heads and 8 groups | about 57x for DeepSeek-V3's 128 heads of dimension 128 |
| Extra compute at decode | None (K/V used directly) | Up-projections, normally absorbed into Q and output projections |
| Kernel support | Standard attention kernels (FlashAttention, FlashInfer) | Dedicated kernels such as FlashMLA |
| Quality vs. MHA (DeepSeek-V2 ablations) | Below MHA in DeepSeek's 7B dense test | Above MHA in DeepSeek's MoE tests |
| Introduced | Ainslie et al. (2023) | DeepSeek-V2 technical report (2024) |
The DeepSeek-V3 figures come from its configuration (128 attention heads, 128-dimensional heads, a 512-dimensional KV latent and a 64-dimensional rotary key): 576 cached elements per token per layer, against 32,768 for MHA with the same heads and 2,048 for a GQA layout with 8 K/V heads of the same dimension, so MLA's cache is about 3.6x smaller than that GQA layout. [23]
Tradeoffs
On quality, DeepSeek's own ablations favour MLA. In the DeepSeek-V2 report, MoE models with MLA scored higher than otherwise identical MoE models with MHA at two scales while needing 14% (small) and 4% (large) of MHA's KV cache, whereas a 7B dense GQA model trailed MHA. [8] Other developers' ablations (Llama 2, Gemma 2) found GQA close to MHA, so the size of the GQA quality gap depends on the setup. [4][16]
MLA is more complex to implement. Getting the cache savings requires the decoupled rotary key and the absorbed formulation, and efficient decoding uses dedicated kernels. [8] GQA works with standard attention kernels: the K/V heads can be shared or expanded to match the number of query heads, at which point an ordinary scaled dot-product attention kernel handles the rest. [9][35]
GQA and MLA in recent model families
Both designs remain in use in open-weight models released in 2025-2026. The table records what each model's own configuration or model card specifies, as of October 2026:
| Model (release) | Attention design | Source |
|---|---|---|
| Qwen3 (April 2025) | GQA (4 or 8 K/V heads) | [14] |
| Kimi K2 (July 2025) | MLA (512-dimensional KV latent, 64 heads) | [24] |
| GLM-4.5 (July 2025) | GQA (96 query, 8 K/V heads) | [27] |
| gpt-oss (August 2025) | GQA (64 query, 8 K/V heads), alternating banded-window and dense layers | [20] |
| MiniMax M2 (October 2025) | GQA (48 query, 8 K/V heads) | [28] |
| Mistral Large 3 (December 2025) | MLA (512-dimensional KV latent, 128 heads) | [22] |
| GLM-5 (February 2026) | MLA parameters (512-dimensional KV latent) with DeepSeek Sparse Attention | [25] |
| Qwen3.5 (February 2026) | Gated DeltaNet hybrid; GQA (32 query, 2 K/V heads) in every fourth layer | [15] |
| Kimi K3 (July 2026) | Kimi Delta Attention (linear) layers interleaved with latent-attention layers (512-dimensional KV latent) in 24 of 93 layers | [26] |
Converting between GQA and MLA
Because most deployed models were trained with MHA or GQA, several 2025 papers propose converting them to MLA after pre-training, in the same spirit as the GQA paper's MHA-to-GQA uptraining:
- TransMLA (Meng et al., Peking University, February 2025) argues that "MLA provides superior expressive power compared to GQA with the same KV cache overhead" and presents a framework that converts GQA-based models such as LLaMA, Qwen, Gemma and Mistral/Mixtral into MLA models compatible with DeepSeek's codebase. The authors report that compressing 93% of the KV cache of LLaMA-2-7B gave a 10.6x speedup at an 8K context length, and that about 6B tokens of fine-tuning recovered comparable benchmark performance. [29]
- MHA2MLA (Ji et al., Fudan University and others, February 2025; accepted to ACL 2025) combines partial removal of rotary embeddings with a joint SVD of the pre-trained key and value weights. The authors report recovering performance with 0.6% to 1% of the original data and cutting Llama2-7B's KV cache by 92.19% with a 1% drop in LongBench performance. [30]
- X-EcoMLA (AMD, March 2025) upcycles pre-trained attention into a hybrid MLA variant with post-training distillation. For Llama3.2-1B-Instruct, a GQA model, the authors report that 6.4x KV compression matched the baseline's average score using 3.6B training tokens and 70 GPU hours on AMD MI300, and 10.6x compression lost less than 0.1% of average score with 7B tokens and 140 GPU hours. [31]
A related line of work redesigns the grouped and latent families together. Zadouri, Strauss and Tri Dao ("Hardware-Efficient Attention for Fast Decoding," May 2025) propose Grouped-Tied Attention, which ties key and value states and "matches Grouped-Query Attention (GQA) quality while using roughly half the KV cache," and Grouped Latent Attention, which matches MLA quality and "is easier to shard"; they report their GLA kernel is up to 2x faster than FlashMLA in a speculative-decoding setting. [32]
How is GQA implemented?
PyTorch
PyTorch 2.5 added an enable_gqa argument to torch.nn.functional.scaled_dot_product_attention. When it is set to True, the function accepts key and value tensors with fewer heads than the query; the documentation's reference implementation repeats the K/V heads along the head dimension to match the query heads. The function expects tensors laid out as (batch, heads, sequence, head_dim). [35]
import torch.nn.functional as F

def gqa_attention(q, k, v):
    # q: (batch, num_heads, seq, head_dim); k, v: (batch, num_kv_heads, seq, head_dim)
    return F.scaled_dot_product_attention(q, k, v, is_causal=True, enable_gqa=True)

def gqa_attention_explicit(q, k, v):
    # Equivalent result, but materializes expanded copies of K and V
    repeat_factor = q.size(1) // k.size(1)
    k_expanded = k.repeat_interleave(repeat_factor, dim=1)
    v_expanded = v.repeat_interleave(repeat_factor, dim=1)
    return F.scaled_dot_product_attention(q, k_expanded, v_expanded, is_causal=True)
The explicit repeat_interleave form allocates expanded copies of K and V, which costs memory and bandwidth; fused kernels avoid that copy by indexing the shared head directly.
FlashAttention
Flash Attention supports GQA natively from FlashAttention-2 (paper published July 2023). The FlashAttention-2 paper explains that "instead of having to duplicate the key and value heads for the computation, we implicitly manipulate the indices into the head to perform the same computation," with the gradients for K and V summed across the implicitly duplicated heads in the backward pass. [9] In the flash-attn library, flash_attn_func "supports multi-query and grouped-query attention (MQA/GQA) by passing in KV with fewer heads than Q," and requires the number of query heads to be divisible by the number of K/V heads. [36] Flash Attention 3, the Hopper-specific successor, is covered in its own article.
FlashInfer, a kernel library for LLM serving, announced in February 2024 that it uses tensor-core prefill kernels for GQA decode attention, because the higher operational intensity of GQA makes CUDA-core decode kernels compute-bound; it reported "up to 2-3x speedup for Grouped-Query Attention on A100 & H100, compared to vLLM implementation." [37]
Transformers Library
Hugging Face Transformers exposes GQA through the num_key_value_heads configuration field. The Llama configuration documentation states that if num_key_value_heads=num_attention_heads the model uses MHA, if num_key_value_heads=1 it uses MQA, and otherwise GQA is used; it also repeats the GQA paper's advice to construct each group's key and value head "by meanpooling all the original heads within that group" when converting a multi-head checkpoint. [38] This is the field that the configuration-based rows in the tables above are read from.
TensorRT-LLM, Transformer Engine and vLLM
NVIDIA TensorRT-LLM documents MHA, MQA and GQA support in its attention backends, configured through a num_kv_heads argument, and offers an "XQA" optimization specifically for MQA/GQA in the generation phase. [39] NVIDIA's Transformer Engine library uses a num_gqa_groups parameter, documented with the same convention as the paper (GQA-1 is MQA, GQA-H is MHA). [40] In vLLM, the fused QKV projection layer shards K/V heads across tensor-parallel ranks; when the tensor-parallel size is at least the number of K/V heads, each GPU holds one K/V head, and when it exceeds the number of K/V heads, each K/V head is replicated across several GPUs. [41]
Relationship to the Broader Attention Design Space
GQA is one point in a design space defined by (1) the number of query heads and (2) the number of K/V heads. The case where both are equal corresponds to MHA; one K/V head corresponds to MQA; GQA fills the space between. [1]
Other attention variants occupy different parts of the design space or introduce additional dimensions:
Sliding Window Attention (SWA), used in Mistral 7B, limits each query to a fixed-size window of past tokens rather than the entire context. SWA reduces the KV cache by capping the number of stored positions rather than by reducing the number of K/V heads. GQA and SWA are orthogonal and can be combined, as Mistral 7B demonstrates. [6] Shazeer made the same point about MQA in 2019, training "local" variants to show that local attention and multi-query attention are orthogonal. [2]
Sparse Attention mechanisms, such as those used in Longformer and BigBird, selectively compute attention over a sparse subset of token pairs. This reduces the attention computation (which is quadratic in sequence length for dense attention) but does not address the K/V head count that GQA targets.
Tensor Parallelism Compatibility: The number of K/V heads interacts with tensor parallelism. The GQA paper notes that standard sharding "replicates the single key and value head by the number of model partitions" under MQA, and that "GQA removes the waste from such partitioning." [1] Tensor parallelism splits heads across GPUs, so each GPU holds K/V heads divided by the tensor-parallel degree. With 8 K/V heads and 8-way tensor parallelism, each GPU holds exactly one K/V head; with more GPUs than K/V heads, serving systems such as vLLM replicate K/V heads, which duplicates the KV cache. [41] NVIDIA's 2026 guidance is to keep the tensor-parallel degree at or below the number of K/V heads and to scale attention for models with very few K/V heads with attention data parallelism or KV parallelism. [10]
Head Dimension: The GQA paper fixes the head dimension and varies only the number of K/V heads. [1] Released GQA models use different head sizes: 128 in Llama 3 and Qwen3, 256 in Gemma 2's 2B and 9B models and in Qwen3.5's attention layers, and 64 in gpt-oss. [5][14][15][16][20] NVIDIA's 2026 analysis finds that head dimension does not change arithmetic intensity but must suit the hardware, recommending 128 or 256. [10]
Limitations
Quality gap. GQA is a compromise: at a fixed parameter budget, fewer K/V heads can cost quality. DeepSeek's 7B dense ablation found MHA clearly ahead of GQA-8 on hard benchmarks, while Meta's and Google's ablations found little difference. [4][8][16] The original paper did not compare uptrained GQA with GQA trained from scratch, and the AsymGQA authors report that naive mean-pooled conversion can lose quality even after fine-tuning. [1][33]
Prefill is not accelerated. The bandwidth savings apply to the decode phase. During prefill, the full prompt is processed in parallel and the computation is compute-bound; NVIDIA measured under 1% change in prefill runtime across the full range from MHA to MQA. [10] GQA therefore does little for time to first token on long prompts, though it still shrinks the cache those prompts produce.
Does not bound cache growth. GQA shrinks every cache entry by the same factor but the cache still grows linearly with context length. Complementary techniques such as sparse attention, sliding-window attention (as in Mistral 7B), hybrid architectures in which only some layers keep a global KV cache (as in Qwen3.5 and Nemotron 3), and KV cache eviction policies address that growth. [6][10][15]
Tensor parallelism constraints. When a model has fewer K/V heads than the tensor-parallel degree, the K/V heads must be replicated, duplicating the cache, or attention must be parallelized another way. [10][41] This is why NVIDIA pairs models with two K/V heads with attention data parallelism or KV parallelism. [10]
Orthogonal to KV cache quantization. GQA reduces the number of cache entries but not the precision of each entry. KV cache quantization (storing K/V in 8-bit or 4-bit formats) is a separate technique that can be combined with it; the GQA paper itself lists quantization among other methods that reduce memory-bandwidth overhead. [1]
Continue reading
- KV CacheKV cache, short for key-value cache, is transient model state used during Transformer generation.Mentioned 32 times above
- Llama 3Llama 3 is a family of open-weight large language models developed by Meta. Meta released the original Llama 3 checkpoints on April 18, 2024, in 8-billion-parameter and 70-billion-parameter sizes.Mentioned 13 times above
- Multi-Query Attention (MQA)Multi-Query Attention (MQA) is a variant of the multi-head attention mechanism used in transformer neural networks in which all query heads share a single key head and a single value head, rather than each…Mentioned 10 times above
- Mistral 7BMistral 7B is a 7.3-billion-parameter, decoder-only large language model released by mistral ai on September 27, 2023, under the Apache 2.0 license.Mentioned 8 times above
- Llama 2Llama 2 is a family of open-weight large language models developed by Meta AI. Meta released pretrained and dialogue-tuned checkpoints with 7 billion, 13 billion, and 70 billion parameters on July 18, 2023.Mentioned 7 times above
- Tensor ParallelismTensor parallelism (TP) is a distributed training technique that splits the individual weight matrices of a neural network layer across multiple devices, so that each device computes a partial result that is…Mentioned 7 times above
More from See also
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30Ainslie, J., Lee-Thorp, J., de Jong, M., Zemlyanskiy, Y., Lebron, F., and Sanghai, S. (2023). GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints. *Proceedings of EMNLP 2023*, pages 4895-4901. arXiv:2305.13245. aclanthology.org/2023.emnlp-main.298
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Shazeer, N. (2019). Fast Transformer Decoding: One Write-Head is All You Need. arXiv:1911.02150.
- ^1 ^2Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., and Polosukhin, I. (2017). Attention Is All You Need. *Advances in Neural Information Processing Systems 30*.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Touvron, H., et al. (2023). Llama 2: Open Foundation and Fine-Tuned Chat Models. arXiv:2307.09288.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Dubey, A., et al. (2024). The Llama 3 Herd of Models. arXiv:2407.21783.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Jiang, A. Q., et al. (2023). Mistral 7B. arXiv:2310.06825.
- ^1 ^2 ^3 ^4 ^5Qwen Team (2024). Qwen2 Technical Report. arXiv:2407.10671.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7DeepSeek-AI (2024). DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model. arXiv:2405.04434.
- ^1 ^2Dao, T. (2023). FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning. arXiv:2307.08691.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10Bhatia, N., Jain, S., Pampana, S. K., Borkar, R., and Darvish Rouhani, B. (2026). Co-Designing AI Model Attention for Fast, Interactive Long-Context Inference. NVIDIA Developer Blog, July 31, 2026. developer.nvidia.com/...ive-long-context-inference
- ^1 ^2 ^3Llama 2 model configurations (config.json) for Llama-2-7b-hf, Llama-2-13b-hf and Llama-2-70b-hf, as published in the public NousResearch mirrors of Meta's Hugging Face checkpoints (the official meta-llama repositories are access-gated). huggingface.co/...config.json ; huggingface.co/...config.json
- ^1 ^2Qwen Team (2024). Qwen1.5-32B: Fitting the Capstone of the Qwen1.5 Language Model Series. Qwen blog, April 2, 2024. qwenlm.github.io/...qwen1.5-32b ; Qwen1.5-7B configuration: huggingface.co/...config.json
- ^1 ^2 ^3Qwen2.5-14B and Qwen2.5-72B model configurations (config.json). huggingface.co/...config.json ; huggingface.co/...config.json
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11Yang, A., et al. (2025). Qwen3 Technical Report. arXiv:2505.09388.
- ^1 ^2 ^3 ^4 ^5 ^6Qwen Team (2026). Qwen3.5-397B-A17B model card and configuration. Hugging Face, February 2026. huggingface.co/...Qwen3.5-397B-A17B
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Gemma Team (2024). Gemma 2: Improving Open Language Models at a Practical Size. arXiv:2408.00118.
- ^1 ^2Gemma Team (2025). Gemma 3 Technical Report. arXiv:2503.19786.
- ^1 ^2 ^3Microsoft Phi model configurations (config.json): Phi-3-mini-4k-instruct, Phi-3-small-8k-instruct, Phi-3-medium-4k-instruct, phi-4 and Phi-4-mini-instruct. huggingface.co/...config.json ; huggingface.co/...config.json ; huggingface.co/...config.json ; huggingface.co/...config.json ; huggingface.co/...config.json
- ^1 ^201.AI (2024). Yi: Open Foundation Models by 01.AI. arXiv:2403.04652. Configurations: huggingface.co/...config.json ; huggingface.co/...config.json
- ^1 ^2 ^3 ^4 ^5OpenAI (2025). gpt-oss-120b & gpt-oss-20b Model Card. arXiv:2508.10925.
- ^1 ^2Mixtral-8x7B-v0.1 model configuration (config.json). huggingface.co/...config.json
- ^1 ^2Mistral-Large-3-675B-Instruct-2512 model parameters (params.json). Hugging Face. huggingface.co/...params.json
- ^DeepSeek-V3 model configuration (config.json). huggingface.co/...config.json
- ^Kimi-K2-Instruct model configuration (config.json). huggingface.co/...config.json
- ^GLM-5 model card and configuration (config.json). huggingface.co/...GLM-5
- ^Kimi-K3 model configuration (config.json). huggingface.co/...config.json
- ^1 ^2GLM-4.5 model configuration (config.json). huggingface.co/...config.json
- ^1 ^2MiniMax-M2 model configuration (config.json). huggingface.co/...config.json
- ^Meng, F., Tang, P., Tang, X., Yao, Z., Sun, X., and Zhang, M. (2025). TransMLA: Multi-Head Latent Attention Is All You Need. arXiv:2502.07864.
- ^Ji, T., Guo, B., Wu, Y., Guo, Q., Shen, L., Chen, Z., Qiu, X., Zhang, Q., and Gui, T. (2025). Towards Economical Inference: Enabling DeepSeek's Multi-Head Latent Attention in Any Transformer-based LLMs. ACL 2025. arXiv:2502.14837.
- ^Li, G., Rezagholizadeh, M., Yang, M., Appia, V., and Barsoum, E. (2025). X-EcoMLA: Upcycling Pre-Trained Attention into MLA for Efficient and Extreme KV Compression. arXiv:2503.11132.
- ^Zadouri, T., Strauss, H., and Dao, T. (2025). Hardware-Efficient Attention for Fast Decoding. arXiv:2505.21487.
- ^1 ^2 ^3Chen, Y., Zhang, C., Gao, X., Mullins, R. D., Constantinides, G. A., and Zhao, Y. (2024). Optimised Grouped-Query Attention Mechanism for Transformers. ICML 2024 ES-FoMo-II Workshop. arXiv:2406.14963.
- ^Chen, Y., Wu, Y., Song, C., Thai, Z. L., Shen, X., Han, X., Liu, Z., and Sun, M. (2025). Cost-Optimal Grouped-Query Attention for Long-Context Modeling. EMNLP 2025. arXiv:2503.09579.
- ^1 ^2PyTorch documentation (version 2.5). torch.nn.functional.scaled_dot_product_attention. docs.pytorch.org/...l.scaled_dot_product_attention
- ^1 ^2Dao-AILab. flash-attention README (flash_attn_func documentation). GitHub. github.com/...flash-attention
- ^FlashInfer team (2024). Accelerating Self-Attentions for LLM Serving with FlashInfer. FlashInfer blog, February 2, 2024. flashinfer.ai/...introduce-flashinfer
- ^Hugging Face Transformers. LlamaConfig documentation (num_key_value_heads), configuration_llama.py, v4.46.0. github.com/...configuration_llama.py
- ^NVIDIA TensorRT-LLM documentation. Multi-Head, Multi-Query, and Group-Query Attention. github.com/...attention.md
- ^NVIDIA Transformer Engine. MultiheadAttention (num_gqa_groups), multi_head_attention.py. github.com/...multi_head_attention.py
- ^1 ^2 ^3vLLM project. QKVParallelLinear, vllm/model_executor/layers/linear.py. github.com/...linear.py
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
13 revisions · v13 · 7,297 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independently verified 2026-10-31 (see v12 stamp); v13 fixes the Kimi K3 release month (July 16, 2026) per the kimi_k3 article and Moonshot's release.
Cite this page: AI Wiki. "Grouped-Query Attention." aiwiki.ai, updated 31 Oct 2026, fact-checked 31 Oct 2026. CC BY 4.0. https://aiwiki.ai/wiki/grouped_query_attention