

Multi-head Latent Attention
Multi-head Latent Attention (MLA) is an attention mechanism for transformer models that compresses the keys and values of all attention heads into one shared low-rank latent vector, so that only this vector, plus a small key that carries position information, has to be kept in the key-value cache during generation.[1] DeepSeek-AI introduced it in May 2024 as part of the DeepSeek-V2 model, to address the memory bottleneck that limits inference throughput and context length in large language models.[1] In the words of the DeepSeek-V2 paper, "MLA guarantees efficient inference through significantly compressing the Key-Value (KV) cache into a latent vector."[1] With DeepSeek-V2's settings, an MLA layer caches 576 elements per token, against 32,768 for standard multi-head attention with the same 128 heads of dimension 128, and in DeepSeek's ablations MLA models scored higher than otherwise identical multi-head attention models on most of the benchmarks tested.[1]
Unlike earlier approaches such as Multi-Query Attention (MQA) or Grouped-Query Attention (GQA), which shrink the cache by sharing key and value heads, MLA uses low-rank joint compression of keys and values into a compact latent representation.[1] The DeepSeek-V2 paper's headline figures are whole-model comparisons with the dense DeepSeek 67B, which itself used GQA: a 93.3% smaller KV cache, 5.76 times the maximum generation throughput and a 42.5% training-cost saving. The paper attributes the deployed model's smaller cache to "MLA and these optimizations", meaning FP8 weights and KV cache quantization to about 6 bits per element, and credits the training saving to the sparse DeepSeekMoE feed-forward layers, so none of the three numbers measures MLA alone.[1][45]
As of October 2026, published configuration files show MLA in DeepSeek's V2 and V3 families (including DeepSeek-R1, V3.1, V3.2-Exp and V3.2), in Moonshot's Kimi K2, K2.5 and K2.6 and the full-attention layers of Kimi K3, in Z AI's GLM-5 line, in InclusionAI's Ling 2.5 and Ling 3.0-flash, in Mistral Large 3 and Mistral Large 4, in Sarvam AI's 105B model and in Meituan's LongCat-Flash.[36][37][38][46][52][53][54][55] DeepSeek layered fine-grained sparsity on top of MLA in DeepSeek-V3.2-Exp (September 2025), then dropped MLA in DeepSeek V4 (April 2026), replacing it with a hybrid of Compressed Sparse Attention and Heavily Compressed Attention that compresses the key-value cache along the sequence rather than into a per-token latent vector.[26][27][32]
What problem does MLA solve?
The development of MLA emerged from DeepSeek-AI's effort to create economical large-scale language models. In autoregressive text generation, a model generates output one token at a time, with each newly generated token being added to the input sequence for the next step. Traditional multi-head attention mechanisms store full-dimensional key and value matrices for every attention head at every sequence position, creating enormous memory requirements that scale linearly with context length.[2]
The DeepSeek-V2 paper's contribution list states that "Huazuo Gao and Wangding Zeng have made key innovations in the research of the MLA architecture," and the authors thank Jianlin Su, first author of the RoFormer paper that introduced rotary position embeddings, "for his helpful discussion on position embedding."[1][14]
Why is the KV cache a bottleneck?
In the original Transformer architecture, introduced in the paper "Attention Is All You Need", the model relies on a mechanism called Multi-head Attention (MHA).[3] For each token in an input sequence, the model computes three vectors: a Query (Q), a Key (K), and a Value (V). The attention score between any two tokens is calculated based on the similarity of their Q and K vectors, enabling the model to capture complex, long-range dependencies. The computational complexity of this operation is quadratic with respect to the sequence length, , where N is the sequence length and d is the model dimension.[4]
A naive implementation would require recomputing the K and V vectors for all previous tokens at every single generation step. To avoid this redundant computation, a technique called KV caching is used. The K and V vectors for all tokens in the context are computed once and stored in memory (the KV cache). For each new token, the model only needs to compute its own K and V vectors and append them to the cache.[4]
While this dramatically speeds up inference, it introduces a new bottleneck: memory. Multi-head attention has to cache elements for each token, where is the number of heads, the head dimension and the number of layers, and the DeepSeek-V2 paper calls this heavy cache "a large bottleneck that limits the maximum batch size and sequence length."[1] With 128 heads of dimension 128, as in DeepSeek-V2, that is 32,768 values per token per layer; for a 60-layer model at an 8K context it comes to about 32 GB for a single sequence in 16-bit precision. This limits the batch sizes that can be processed simultaneously, directly constraining inference speed and making long-context applications expensive.[10] The size of the KV cache grows linearly with the sequence length and the number of attention heads, and for modern LLMs with billions of parameters, many attention heads, and very long context windows (for example 128,000 tokens or more), the KV cache can quickly exceed the capacity of a single GPU.[5]
How do MQA and GQA reduce the cache?
To address the KV cache problem, several variants of MHA were developed as performance-for-efficiency trade-offs:
-
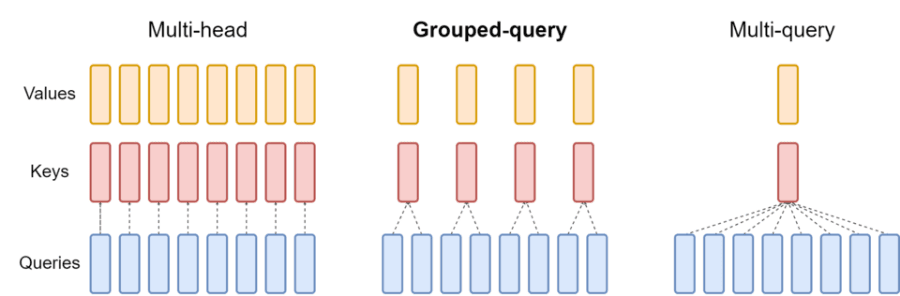
Multi-Query Attention (MQA): This approach uses the standard number of Query heads but shares a single Key and a single Value head across all of them, drastically reducing memory usage.[6] This limits the model's expressive capacity and can lead to degradation in model quality.[7]
-
Grouped-Query Attention (GQA): GQA offers a compromise between MHA and MQA. It divides the Query heads into several groups and shares a single Key and Value head within each group. This reduces the KV cache size significantly compared to MHA while often preserving more model quality than MQA.[8]
Both methods give up some modeling capacity compared with full multi-head attention.[7] In DeepSeek's own ablation of 7B dense models trained on 1.33T tokens, the MHA model beat an 8-group GQA model and an MQA model on all four hard benchmarks tested, for example 45.2 against 41.2 and 37.9 on MMLU.[1] Multi-head Latent Attention (MLA) was developed to strike a better balance between memory efficiency and model quality. It compresses the key/value space into a latent vector rather than sharing actual keys, preserving distinct per-head keys and values.[1][9]
Comparison of attention mechanisms
The table below summarizes the differences between standard multi-head attention and its memory-saving variants. Cache sizes are per token per layer, counted in elements; the capability labels are the ones the DeepSeek-V2 paper gives in its Table 1.[1]
| Attention mechanism | Key/value sharing strategy | KV cache per token per layer | Relative memory | Capability (DeepSeek-V2 Table 1) |
|---|---|---|---|---|
| Standard Multi-Head Attention (MHA) | Separate K and V for each head (no sharing) | 100% (baseline) | Strong | |
| Multi-Query Attention (MQA) | One shared K and V across all heads | (about 3% if n_h=32) | Weak | |
| Grouped-Query Attention (GQA) | K and V shared within groups of heads | (12.5% with 8 heads per group) | Moderate | |
| Multi-Head Latent Attention (MLA) | No direct sharing; per-head K and V are reconstructed from one cached latent vector | 1.8% at DeepSeek-V2's settings (576 of 32,768) | Stronger |
Notes: = number of heads; = number of key-value groups; = KV compression dimension; = dimension of the decoupled rotary key. Actual savings depend on model settings. The capability labels are DeepSeek's summary of its own ablations (a 7B dense comparison of MHA, GQA and MQA, and MoE comparisons of MLA with MHA), not an independent benchmark.[1]
How does MLA work?
Core mechanism
The core idea behind MLA is to use low-rank approximation to compress the information needed for the Key and Value vectors.[9] MLA introduces a shared down-projection matrix and separate up-projection matrices, where the compressed latent dimension is much smaller than the full K and V dimensions combined.[1] The mechanism can be described in three phases:
-
Compression phase (down-projection to latent space): Instead of directly projecting the input hidden state to the full-sized K and V vectors, MLA first projects it into a much smaller, low-dimensional "latent vector."
-
Caching phase: Only the compressed latent vectors (and a small decoupled rotary key) are stored in memory, not full keys and values. Since the latent dimension is significantly smaller than the full K and V dimensions combined, the memory required for the cache is drastically reduced.
-
Use during attention: In the simplest description, the cached latent vector is "decompressed" back into full-sized K and V vectors for each head using separate up-projection matrices. In practice, DeepSeek folds the up-projections into the query and output projections, so that attention runs directly against the cached latents (see "Weight absorption" below).[1]
This workflow trades extra computation (more matrix multiplications for the down- and up-projections) for reduced memory traffic (loading a much smaller cache from memory).[5][4] Decoding-time attention is usually limited by memory bandwidth rather than by arithmetic throughput, which makes this a favorable trade on GPUs.[11]
Mathematical formulation
Preliminaries: standard multi-head attention
Given an input hidden state for a token at timestep t, where d is the model dimension, standard MHA computes the Query (), Key (), and Value () vectors using projection matrices :
Here, is the number of heads and is the dimension per head. The resulting vectors are then reshaped into separate heads, and the attention output is calculated using the scaled dot-product attention formula.[3] During inference all keys and values are cached, so MHA stores elements per token.[1]
MLA formulation
MLA replaces the per-head key and value projections with a low-rank factorization that passes through a shared latent representation.[1] It introduces a down-projection matrix and up-projection matrices , where is the KV compression dimension and .[1]
1. Latent KV compression: The hidden state is first projected into a compressed latent vector :
This small vector is what gets stored in the KV cache. The same compressed vector is used for all heads' keys and values, so without position handling only elements per token would need to be cached.[1]
2. Key and value reconstruction: The content parts of the keys and values are produced from the latent by the up-projections:
Each of these -dimensional vectors is split into per-head vectors . Because every head has its own slice of and , heads still get distinct keys and values even though they share one cached latent.[1] The paper adds that during inference " can be absorbed into , and can be absorbed into ," so the keys and values never need to be computed explicitly.[1]
3. Query compression: To reduce activation memory during training, DeepSeek-V2 also compresses the queries, "even if it cannot reduce the KV cache":[1]
where , , and . The smaller DeepSeek-V2-Lite does not compress its queries.[1]
In DeepSeek-V2, hyperparameters include , , , , and a decoupled per-head dimension ; DeepSeek-V3 uses the same values.[1][12] Per layer, the 32,768 key and value elements that MHA with these heads would cache (16,384 of each) are replaced by 576: the 512-dimensional latent plus the 64-dimensional decoupled key, about 57 times fewer. Because low-rank compression changes the output scale of a layer, DeepSeek-V2 adds RMSNorm layers after the compressed latent vectors and multiplies additional scaling factors at these width bottlenecks "to ensure stable training," and DeepSeek-V3 keeps both.[1][12]
During DeepSeek-V2's training, "MLA is also optimized based on an improved version of FlashAttention-2."[1][13]
| Parameter | DeepSeek-V2-Lite | DeepSeek-V2 | DeepSeek-V3 |
|---|---|---|---|
| Layers | 27 | 60 | 61 |
| KV compression dimension | 512 | 512 | 512 |
| Query compression dimension | none (queries not compressed) | 1,536 | 1,536 |
| Number of attention heads | 16 | 128 | 128 |
| Head dimension | 128 | 128 | 128 |
| Decoupled RoPE dimension | 64 | 64 | 64 |
| MHA cache per token per layer () | 4,096 | 32,768 | 32,768 |
| MLA cache per token per layer () | 576 | 576 | 576 |
| Cache reduction against MHA with the same heads | 85.9% | 98.2% | 98.2% |
Sources: DeepSeek-V2 and V3 reports and the released configuration files.[1][12][46] Measured across all 61 layers in BF16, DeepSeek-V3's MLA cache is 70.272 KB per token, against 327.680 KB for Qwen-2.5 72B and 516.096 KB for LLaMA-3.1 405B, both GQA models, according to a DeepSeek paper presented at ISCA 2025.[48]
How does MLA stay compatible with RoPE?
A critical technical challenge MLA solves is compatibility with Rotary Position Embeddings (RoPE), a widely used positional encoding that applies rotation matrices to queries and keys.[1][14] RoPE works by rotating the Query and Key vectors according to their position in the sequence, which makes the dot product between them depend on relative position.[15]
DeepSeek-V2 follows DeepSeek 67B in using RoPE, but the paper states that "RoPE is incompatible with low-rank KV compression." If RoPE were applied to the keys , would be "coupled with a position-sensitive RoPE matrix" and could no longer be absorbed into , "since a RoPE matrix related to the currently generating token will lie between and and matrix multiplication does not obey a commutative law"; the keys for all prefix tokens would then have to be recomputed during inference.[1] A direct application of RoPE after the up-projection would require decompressing the entire KV cache at every generation step, defeating the purpose of the compression.[16]
To solve this, the DeepSeek-V2 paper introduced decoupled RoPE.[1] This technique splits the Q and K heads into two parts: one part that carries positional information (the "rope" part) and one that does not (the "nope" part).[7] In practice, an additional set of query vectors and one shared key are maintained solely for the purpose of applying RoPE, while the cached latent itself remains unrotated.[1]
The model maintains additional multi-head query vectors and a shared key specifically for positional information. These receive RoPE transformations while compressed components remain position-independent.[1] The solution uses additional multi-head queries and a shared key :
where and . Final queries and keys are formed by concatenation:
Attention is then computed with a scaled denominator, and the head outputs are combined by the output projection :
The decoupled key also has to be cached, so the total KV cache per token becomes elements.[1] The shared RoPE key is broadcast to all attention heads, adding only 64 dimensions to the cache per token in DeepSeek-V2.[1] This allows the weight matrices for the non-RoPE components to be absorbed during inference, so full key matrices never have to be materialized.
The positional rotations are applied only to the designated "rope" part of the vectors, so positional information does not interfere with the compression. One consequence is that MLA is not a drop-in replacement for MHA: changing the attention mechanism also required changing how positions are encoded. When DeepSeek-V2's context was extended from 4K to 128K tokens with YaRN, YaRN "was specifically applied to the decoupled shared key as it is responsible for carrying RoPE."[1]
Some later models drop RoPE from their MLA layers altogether. Moonshot's Kimi Linear applies "NoPE to all full attention (MLA) layers," leaving position information to its linear-attention layers, and notes that NoPE "enables their conversion to the highly-efficient pure Multi-Query Attention (MQA) during inference"; Kimi K3's configuration sets mla_use_nope to true, and Mistral Large 4's parameters mark one layer in every four as having no RoPE.[29][36][53]
Weight absorption optimization
During inference, MLA avoids reconstructing per-head keys and values. Appendix C of the DeepSeek-V2 paper states that "due to the associative law of matrix multiplication, we can absorb into , and into ," so keys and values do not have to be computed for each query.[1] For head , with the head's slice of , the content part of the attention score can be rewritten as
The transformed query has dimensions, so the score is a dot product against the cached latent itself, and because , the product can be precomputed. On the output side, head 's contribution through is , so the value up-projection folds into the output projection and the attention weights are applied to the latent vectors directly.[1]
DeepSeek's later reports call the two ways of running MLA its "MHA mode" and "MQA mode." In the MHA mode, per-head keys and values are materialized; in the MQA mode, every query head attends over the same cached entries, with "each latent vector (the key-value entry of MLA)" shared "across all query heads of the query token." For DeepSeek-V3.1-Terminus, DeepSeek used the MHA mode for training and prefilling and the MQA mode for decoding.[26] In FlashMLA's decoding kernel, each cached entry is 576 values wide when used as a key (latent plus rotary key), its first 512 values serve as the value, and DeepSeek's write-up notes that "in MLA, K and V are the same with different names."[49]
How much faster is MLA?
Computational efficiency
The DeepSeek-V2 paper reports its efficiency gains as whole-model comparisons with the dense DeepSeek 67B: DeepSeek-V2, a 236B-parameter MoE model, "saves 42.5% of training costs, reduces the KV cache by 93.3%, and boosts the maximum generation throughput to 5.76 times."[1] Three things separate those numbers from MLA by itself:
- DeepSeek 67B was not a multi-head attention baseline. Its configuration specifies 95 layers with 64 query heads and 8 key-value heads, that is, grouped-query attention.[45]
- The deployed DeepSeek-V2 also ran with FP8 parameters and with KV cache quantization that compresses "each element in its KV cache into 6 bits on average," and the paper says the smaller cache comes from "MLA and these optimizations."[1]
- The throughput and training figures also reflect the switch from dense feed-forward layers to DeepSeekMoE.[1]
By element count, the measure the paper's Table 1 uses "regardless of the storage precision," DeepSeek-V2 caches 34,560 elements per token (576 in each of its 60 layers), against 194,560 for DeepSeek 67B (2 x 8 key-value heads x 128 dimensions x 95 layers), about 82% fewer. The paper's Figure 1 plots the cache in kilobytes per token, and the 93.3% figure matches a comparison of a 6-bit DeepSeek-V2 cache against a 16-bit DeepSeek 67B cache, although the paper does not show the calculation.[1][45]
DeepSeek measured generation throughput using the prompt and generation length distribution of its deployed DeepSeek 67B service. On a single node with 8 H800 GPUs, DeepSeek-V2 exceeded 50K tokens per second of generation throughput, 5.76 times DeepSeek 67B's maximum, and its prompt input throughput exceeded 100K tokens per second.[1] DeepSeek-V3, released in December 2024, kept the same MLA dimensions.[12]
MLA against MHA in DeepSeek's ablations
The DeepSeek-V2 paper's direct comparison of the two mechanisms uses MoE models that are identical except for attention. The two small models have about 16B total parameters and were trained on 1.33T tokens; the two large ones have about 250B and were trained on 420B tokens.[1]
| Model | Total parameters | KV cache per token (elements) | BBH | MMLU | C-Eval | CMMLU |
|---|---|---|---|---|---|---|
| Small MoE with MHA | 15.8B | 110.6K | 37.9 | 48.7 | 51.6 | 52.3 |
| Small MoE with MLA | 15.7B | 15.6K | 39.0 | 50.0 | 50.9 | 53.4 |
| Large MoE with MHA | 250.8B | 860.2K | 46.6 | 57.5 | 57.9 | 60.7 |
| Large MoE with MLA | 247.4B | 34.6K | 50.7 | 59.0 | 59.2 | 62.5 |
MLA scored higher in seven of the eight comparisons (the exception is C-Eval at the small scale) while using 14% (small) and 4% (large) of MHA's KV cache.[1] These are DeepSeek's own results at two scales; the paper does not include a matched-cache comparison of MLA against GQA.
DeepSeek-V2 against DeepSeek 67B
The whole-model comparison mixes MLA with DeepSeekMoE, more training data and other changes:[1]
| Metric | DeepSeek 67B | DeepSeek-V2 | Improvement |
|---|---|---|---|
| MMLU score | 71.3 | 78.5 | +7.2 points |
| BBH score | 68.7 | 78.9 | +10.2 points |
| Generation throughput | not stated in the paper | 50,000+ tps | 5.76x |
| Training GPU hours/trillion tokens | 300,600 | 172,800 | 42.5% reduction |
| Activated parameters | 67B | 21B | 68.7% reduction |
Beyond DeepSeek's own models, inference engines have measured MLA's effect. Red Hat, whose Neural Magic team led the MLA implementation in vLLM, reported that on an 8x NVIDIA H200 setup generation throughput rose by 3.4x with MLA and by 40% with FP8 kernel optimizations, measured against vLLM v0.7.0; on H100 GPUs under tensor parallelism 8 with pipeline parallelism 2 the same comparison gave a 2.8x boost from MLA and a 26% improvement from the FP8 kernels. The same post reports token capacity on that 8x H200 setup expanding from 54,560 to 512,000 tokens, with batch size growing from 13 to 128. It also notes a trade-off: at low queries per second, MHA "currently outperforms MLA" on time to first token, while MLA delivers better time per output token under sustained load.[41]
Arithmetic intensity
A decoding step of ordinary attention reads the whole KV cache to produce one output per head, so it is usually limited by memory bandwidth. MLA's absorbed form changes the ratio because all query heads read the same cached latent. In its April 2025 write-up on the FlashMLA kernel, DeepSeek estimates the decoding kernel's compute-to-memory ratio at about FLOPs per byte, where is the number of query heads and the number of query tokens per request.[49] On an NVIDIA H800 SXM5, which the write-up puts at 3.35 TB/s of memory bandwidth and a practical peak of about 865 TFLOPS after clock throttling, the kernel becomes compute-bound once reaches 128. Because DeepSeek's decoding instances do not use tensor parallelism, is 128, so DeepSeek optimized the kernel for the compute-bound case, reaching up to 660 TFLOPS.[49]
Training efficiency
DeepSeek-V2 required 172.8K H800 GPU hours per trillion training tokens, compared with 300.6K for DeepSeek 67B, a 42.5% reduction.[1] The paper attributes this saving to sparsity ("sparse DeepSeek-V2 can save 42.5% training costs compared with dense DeepSeek 67B"), since DeepSeek-V2 activates fewer parameters and needs fewer FLOPs per token, rather than to MLA.[1]
DeepSeek-V3, with 671B parameters, used 2.788 million H800 GPU hours for its full training, which DeepSeek priced at $5.576 million assuming a rental price of $2 per GPU hour. The report notes that this covers only the official training run, "excluding the costs associated with prior research and ablation experiments on architectures, algorithms, or data."[12] Among its memory-saving techniques, the V3 report lists recomputing "all RMSNorm operations and MLA up-projections during back-propagation" instead of storing their outputs.[12]
How does MLA compare to MHA, MQA, and GQA?
Evolution from multi-head attention
The lineage from Multi-Head Attention to MLA spans seven years of transformer optimization research:[4]
-
2017: Multi-Head Attention (MHA) established the standard with separate key-value heads for each query head[3]
-
2019: Multi-Query Attention (MQA) reduced memory by using a single shared KV head across all queries[6]
-
2023: Grouped-Query Attention (GQA) interpolated between MHA and MQA by grouping query heads[8]
-
2024: Multi-head Latent Attention (MLA) uses low-rank compression while maintaining distinct per-head keys and values[1]
-
2025: DeepSeek Sparse Attention (DSA) layers fine-grained sparsity on top of MLA[26]
-
2025-2026: Hybrid architectures interleave MLA layers with linear attention layers, as in Moonshot's Kimi Linear (October 2025) and Kimi K3 and InclusionAI's Ling 2.5[25][29][36][38]
-
2026: DeepSeek V4 replaces MLA with attention that compresses the cache along the sequence dimension (CSA and HCA)[27]
| Mechanism | Cache size per token per layer | Cache size formula (all layers) | Capability (DeepSeek-V2 Table 1) | Example models |
|---|---|---|---|---|
| MHA | Strong | GPT-2, GPT-3 | ||
| MQA | Weak | PaLM, Falcon-7B[63][64] | ||
| GQA | Moderate | LLaMA 2 (34B and 70B), Llama 3, Mistral 7B, MiniMax M2[39][66][67][68] | ||
| MLA | Stronger | DeepSeek-V2, DeepSeek-V3, Kimi K2, Mistral Large 3 | ||
| MLA + DSA | for every token, plus an indexer key; attention reads only the selected entries | same as MLA, plus the indexer cache | DeepSeek reports parity with V3.1-Terminus | DeepSeek-V3.2-Exp, DeepSeek-V3.2, GLM-5, Mistral Large 4 |
Note: = number of heads; = number of groups; = number of layers; = head dimension; = compressed latent dimension; = decoupled RoPE dimension. The approximation holds for DeepSeek-V2's choice of and .[1] DSA does not shrink what is stored per token: vLLM's implementation keeps the full MLA cache and a separate key cache for the indexer, and each query attends to a selected subset of entries (2,048 in DeepSeek-V3.2's configuration).[17][46]
Comparison with grouped-query attention
With DeepSeek-V2's settings ( and ), MLA's cache equals that of GQA with only 2.25 groups, and the paper states that "its performance is stronger than MHA."[1] For comparison, many GQA models use 8 key-value heads, among them Llama 3 and DeepSeek's own previous model, DeepSeek 67B.[45][67]
The TransMLA authors prove that, for a fixed KV-cache budget, any GQA layer can be rewritten as an MLA layer but not the reverse, so that "MLA provides superior expressive power compared to GQA with the same KV cache overhead."[5] The key difference lies in the mechanism:
-
GQA: Forces multiple query heads to share identical key-value representations, limiting the diversity of attention patterns
-
MLA: Uses low-rank compression to preserve distinct keys and values per head reconstructed from a shared compressed representation
The trade-offs depend on the regime. MLA adds projection work, and in its absorbed decoding form it can become compute-bound rather than memory-bound once enough query heads share each cached entry.[49] Red Hat's vLLM measurements found MLA ahead under sustained, high-throughput load but MHA ahead on time to first token at low request rates.[41]
Which models use MLA?
DeepSeek model family
DeepSeek-AI used MLA in every flagship release from DeepSeek-V2 through the V3 line, then ended that run with DeepSeek-V4:
DeepSeek-V2 (May 2024)[1]
-
236B total parameters, 21B activated per token
-
128K token context window
-
Trained on 8.1 trillion tokens
-
Introduced MLA; the 15.7B-parameter DeepSeek-V2-Lite released with it also uses MLA
DeepSeek-V3 (December 2024)[12]
-
671B total parameters, 37B activated per token
-
61 transformer layers; every layer after the first three uses an MoE layer with 256 routed experts plus one shared expert
-
Trained on 14.8 trillion tokens
-
Official training run priced at $5.576 million (2.788M H800 GPU hours at an assumed $2 per hour), excluding prior research and ablations
-
DeepSeek reports chat performance "comparable to leading closed-source models, including GPT-4o and Claude-3.5-Sonnet," on a series of benchmarks
DeepSeek-R1 (January 2025)[47]
-
Reasoning model whose released configuration has the same architecture and MLA dimensions as DeepSeek-V3[46]
-
Trained with large-scale reinforcement learning; DeepSeek reports that reasoning abilities "can be incentivized through pure reinforcement learning (RL)"
DeepSeek-V3.1 (August 2025)
- Same attention configuration as DeepSeek-V3 ( 512, 1,536, 128 heads, 64 rotary dimensions)[46]
DeepSeek-V3.2-Exp (September 2025)[26]
-
First DeepSeek release to layer DeepSeek Sparse Attention (DSA) on top of MLA
-
DSA selects a sparse subset of tokens per query using a learned indexer, and is implemented on the MQA mode of MLA so each latent KV entry is shared across all query heads of the query token, aligning with the kernel-level requirement that KV entries be reused across queries for high throughput
-
Maintains benchmark parity with V3.1-Terminus. DeepSeek shipped it with what its launch note called an API price cut of "50%+": on the deepseek-chat and deepseek-reasoner endpoints the list price per million output tokens went from $1.68 under V3.1-Terminus to $0.42 under V3.2-Exp, and cache-miss input from $0.56 to $0.28[42][43]
-
Establishes that fine-grained sparsity and latent compression are complementary rather than competing techniques
DeepSeek-V3.2 (December 2025)[51]
- Keeps the V3.2-Exp design: the released configuration carries the same MLA dimensions plus the DSA indexer, with
index_topkset to 2,048[46]
DeepSeek-V4 (April 2026)[27][28][32]
-
The first DeepSeek flagship since DeepSeek-V2 that does not use MLA. Attention is a hybrid of Compressed Sparse Attention (CSA) and Heavily Compressed Attention (HCA), and the V4 technical report's section on designs inherited from DeepSeek-V3 lists only DeepSeekMoE and Multi-Token Prediction. MLA is not mentioned anywhere in the report
-
CSA and HCA compress along the sequence dimension, folding every m tokens into a single entry (m is 4 for CSA layers and 128 for HCA layers in the released checkpoints), then run core attention in MQA mode with each compressed entry serving as both key and value. MLA's low-rank joint compression of keys and values into a per-token latent vector is absent from both paths
-
The published config.json for DeepSeek-V4-Pro and DeepSeek-V4-Flash carries none of
kv_lora_rank,qk_nope_head_dim, orv_head_dim, the three key-value parameters that appear in the V2, V3, and V3.2 configs, and setsnum_key_value_headsto 1. The low-rank query projection (q_lora_rank) and the 64 rotary dimensions (qk_rope_head_dim) do carry over; in the V2 paper, query compression was described as a way to cut activation memory during training and explicitly as something that "cannot reduce the KV cache," so it is not the part of MLA that defines the mechanism -
DeepSeek reports that at a one-million-token context, DeepSeek-V4-Pro needs only 27% of the single-token inference FLOPs and 10% of the KV cache of DeepSeek-V3.2
The DeepSeek-V4.1-Flash report (September 2026) places MLA within a broader framework: KV cache costs can be cut along "three multiplicative dimensions": the size of each entry, where GQA reduces the number of KV heads and MLA shares a small latent across heads; the sequence dimension (CSA and HCA); and the layer dimension, where layers reuse other layers' caches.[33]
Adoption beyond DeepSeek
After DeepSeek-V3's release, MLA spread across the open-weight ecosystem during 2025 and 2026, mostly among Chinese labs at first and later at Mistral AI and Sarvam AI. Sebastian Raschka's survey of ten open-weight releases from January and February 2026 groups Kimi K2.5, GLM-5 and Ling 2.5 together as the models that adopted MLA in that window, and singles out GLM-5 as the one that also took DeepSeek Sparse Attention.[25] Published configuration files make the test concrete: a checkpoint that uses MLA carries kv_lora_rank (the KV compression dimension ), usually alongside qk_nope_head_dim, qk_rope_head_dim and v_head_dim, while a checkpoint that uses GQA carries none of them.
| Model | Developer | Released | kv_lora_rank () | q_lora_rank () | qk_rope_head_dim () | Attention heads | Notes |
|---|---|---|---|---|---|---|---|
| DeepSeek-V2 | DeepSeek | May 2024 | 512 | 1,536 | 64 | 128 | 60 layers[46] |
| DeepSeek-V2-Lite | DeepSeek | May 2024 | 512 | none | 64 | 16 | 27 layers[46] |
| MiniCPM3-4B | OpenBMB | September 2024 | 256 | 768 | 32 | 40 | Dense model, 62 layers[56] |
| DeepSeek-V3, R1, V3.1 | DeepSeek | Dec 2024 to Aug 2025 | 512 | 1,536 | 64 | 128 | 61 layers[46] |
| Moonlight-16B-A3B | Moonshot AI | February 2025 | 512 | none | 64 | 16 | "Same architecture as DeepSeek-V3"[57] |
| Kimi K2 | Moonshot AI | July 2025 | 512 | 1,536 | 64 | 64 | DeepseekV3ForCausalLM[36] |
| LongCat-Flash | Meituan | August 2025 | 512 | 1,536 | 64 | 64 | 560B MoE[55] |
| DeepSeek-V3.2-Exp, V3.2 | DeepSeek | Sep and Dec 2025 | 512 | 1,536 | 64 | 128 | Plus DSA indexer, top-k 2,048[46] |
| Kimi Linear 48B-A3B | Moonshot AI | October 2025 | 512 | none | 64 | 32 | MLA in 7 of 27 layers, without RoPE[65] |
| Mistral Large 3 | Mistral AI | December 2025 | 512 | 1,536 | 64 | 128 | 61 layers[52] |
| Kimi K2.5, K2.6 | Moonshot AI | Jan and Apr 2026 | 512 | 1,536 | 64 | 64 | 262,144-token context[36] |
| GLM-5, 5.1, 5.3 | Z AI | Feb, Apr and Aug 2026 | 512 | 2,048 | 64 | 64 | Plus DSA indexer, top-k 2,048[37] |
| Ling 2.5 1T | InclusionAI | February 2026 | 512 | 1,536 | 64 | 64 | Hybrid with linear attention[38] |
| Sarvam 105B | Sarvam AI | March 2026 | 512 | not set (q_head_dim 192) | 64 | 64 | 32 layers[54] |
| Kimi K3 | Moonshot AI | July 2026 | 512 | 1,536 | 64 | 96 | MLA in 24 of 93 layers, without RoPE[36] |
| Ling 3.0-flash | InclusionAI | 2026 | 512 | none | 64 | 32 | Hybrid with Kimi Delta Attention[38] |
| Mistral Large 4 | Mistral AI | October 2026 (weights) | 512 | none | 64 | 64 | Plus sparse-attention indexer, top-k 2,048[53] |
Moonshot Kimi: Kimi K2 (2025) declares DeepseekV3ForCausalLM as its architecture and sets kv_lora_rank to 512, alongside a sparse mixture-of-experts backbone of 384 experts with 8 activated per token and a 131,072-token context. Kimi K2.5 and K2.6 keep the same MLA and expert configuration and double the context to 262,144 tokens. Kimi K3 switches its text stack to Moonshot's own KimiLinearForCausalLM, which makes 24 of its 93 layers (every fourth layer and the last) full-attention layers and fills the rest with Kimi Delta Attention; those full-attention layers still carry the MLA parameters, with mla_use_nope set to true, and the context reaches 1,048,576 tokens.[36] Moonshot's Kimi Linear paper, which introduced this hybrid, settled on a uniform 3:1 ratio, "repeating 3 KDA layers to 1 full MLA layer," and reports that, with an identical training recipe, it outperformed a full-MLA baseline while reducing KV cache usage "by up to 75%."[29]
Z AI GLM-5: GLM-5 (February 2026)[25] is the clearest non-DeepSeek adoption of the V3.2 recipe. Its architecture string is GlmMoeDsaForCausalLM, and its configuration carries both the MLA parameters and the lightning-indexer parameters of DSA, including index_topk set to 2,048, the same selection budget DeepSeek used in V3.2. Its MLA heads are wider than DeepSeek's, with qk_nope_head_dim of 192 and v_head_dim of 256. GLM-4.6 and GLM-4.7, the two Z AI releases that preceded GLM-5, both ran plain GQA with 8 key-value heads against 96 query heads. The MLA plus DSA pairing carried forward into GLM-5.1 and GLM-5.3; GLM-5.1 keeps GLM-5's max_position_embeddings of 202,752, while GLM-5.3's configuration raises it to 1,048,576.[37]
InclusionAI Ling 2.5: Ling 2.5 1T (February 2026) combines MLA with a recurrent linear-attention pathway, which Raschka identifies as Lightning Attention and places in the same hybrid family as Qwen3.5.[25] Its configuration shows both halves side by side, kv_lora_rank of 512 next to num_kv_heads_for_linear_attn. Ling 3.0-flash keeps the MLA half, with kv_lora_rank still at 512, but swaps the linear-attention half: num_kv_heads_for_linear_attn drops to 0 and a set of kda_ fields appears in place of Ling 2.5's configuration, alongside q_lora_rank set to null.[38]
Mistral AI: Mistral Large 3 (December 2025) uses DeepSeek-V3's attention dimensions exactly: its params.json lists 61 layers, 128 heads, kv_lora_rank 512, q_lora_rank 1,536 and 64 rotary dimensions.[52] Mistral Large 4, whose weights Mistral released in October 2026, keeps the 512-dimensional KV latent but drops query compression, adds an indexer with index_topk of 2,048, and removes RoPE from one layer in every four; its model card also describes the bundled speculative-decoding head as "3 dense MLA draft layers."[53]
Other adopters: OpenBMB's MiniCPM3-4B (September 2024) is an early non-DeepSeek example and a dense model rather than a mixture of experts, using a smaller 256-dimensional latent.[56] Meituan's LongCat-Flash (August 2025) carries the DeepSeek-V3 latent and query dimensions.[55] Sarvam AI's 105B model (March 2026) uses what its model card calls "an MLA-style attention stack," while its smaller 30B sibling uses GQA with 4 key-value heads.[25][54]
Models that did not adopt MLA: MiniMax M2 and M2.5 use plain Grouped-Query Attention, 8 key-value heads against 48 query heads, and carry none of the MLA parameters; Raschka describes M2.5 as "a fairly classic design: just plain Grouped Query Attention, no sliding window attention or other efficiency improvements."[25][39] Alibaba's Qwen3.8 line also stays off MLA. Its configuration sets layer_types so that every fourth layer is full attention, GQA with 4 key-value heads against 64 query heads, and the other three in each group are linear-attention (Gated DeltaNet) layers.[40]
Can an existing GQA model be converted to MLA?
Yes, with fine-tuning. Several 2025 papers convert pretrained MHA or GQA checkpoints to MLA instead of training from scratch.
TransMLA (Meng et al., Peking University and others), first posted to arXiv in February 2025 and accepted as a spotlight presentation at NeurIPS 2025, argues that "MLA provides superior expressive power compared to GQA with the same KV cache overhead" and converts GQA-based models (its abstract names LLaMA, Qwen, Gemma and Mistral/Mixtral) into checkpoints compatible with DeepSeek's codebase and its inference optimizations.[5] The conversion concentrates positional information into a small number of dimensions with a PCA-based technique called RoRoPE, improves on it with FreqFold, which exploits the similarity of adjacent RoPE frequencies, and balances the norms of keys and values before a joint PCA (BKV-PCA).[5]
The headline experiment used LLaMA-2-7B. The authors report that compressing 93% of its KV cache gave "a 10.6x speedup with an 8K context length" in vLLM, a figure measured on the smallest of three accelerators they tested (165.2 TFLOPS with 24 GB of memory) against the original model, and that 6B tokens of further training recovered most of the benchmark performance:[5]
| LLaMA-2-7B variant | Further training tokens | KV cache change | Average of six benchmarks | MMLU |
|---|---|---|---|---|
| Original model | none (2T pretraining tokens) | none | 59.85 | 41.43 |
| TransMLA, no fine-tuning | 0 | -68.75% | 58.20 | 39.90 |
| TransMLA, no fine-tuning | 0 | -92.97% | 43.26 | 28.93 |
| TransMLA | 500M | -68.75% | 59.82 | 40.87 |
| TransMLA | 6B | -92.97% | 58.68 | 40.82 |
The six benchmarks are MMLU, ARC, PIQA, HellaSwag, OpenBookQA and WinoGrande.[5]
MHA2MLA (Ji et al., Fudan University and others, February 2025; accepted to ACL 2025) combines partial removal of RoPE from the query and key dimensions that contribute least to attention scores with a joint SVD of the pretrained key and value weights.[21] The arXiv abstract reports recovering performance with 0.3% to 0.6% of the original training data and a 92.19% smaller Llama2-7B KV cache "with only a 0.5% drop in LongBench performance"; the revised October 2025 version gives 0.6% to 1% of the data and a 1% drop. The 92.19% figure combines MHA2MLA with 4-bit KV cache quantization.[21]
X-EcoMLA (AMD, March 2025) upcycles pretrained attention into a hybrid MLA variant with post-training distillation. For Llama3.2-1B-Instruct, the authors report that 6.4x KV compression matched the baseline's average score using 3.6B training tokens and 70 GPU hours on AMD MI300, and that 10.6x compression lost less than 0.1% of average score with 7B tokens and 140 GPU hours.[59]
MHA2MLA and vision-language extensions
A January 2026 follow-up from the MHA2MLA group, MHA2MLA-VLM, extends the conversion to vision-language models. It adds a "modality-adaptive partial-RoPE strategy" and a low-rank approximation that compresses the visual and textual KV spaces separately, and the authors report that on three VLMs it "restores original model performance with minimal supervised data" and works alongside KV quantization.[30]
Deployment and applications
Cloud platforms
Production deployments of MLA-based models span multiple cloud platforms:
-
Google Cloud Vertex AI: DeepSeek-V3.2 was offered as a managed Model-as-a-Service API (
deepseek-v3.2-maas, generally available from December 10, 2025) with a 163,840-token context limit, and the same Model Garden card can be self-deployed to a dedicated endpoint. Google's documentation marked the managed endpoint deprecated as of July 21, 2026, with retirement set for October 21, 2026, a date that had passed by 31 October 2026[18] -
Alibaba Cloud PAI: the Model Gallery offers "vLLM or BladeLLM accelerated deployment features, enabling you to deploy the DeepSeek-V3 and DeepSeek-R1 series models with a single click." BladeLLM is Alibaba Cloud PAI's own inference framework, and the third deployment mode the page lists runs without acceleration[34]
-
Fireworks AI: on-demand deployment of DeepSeek V3 onto dedicated GPUs. The model page states that the model "uses Multi-head Latent Attention (MLA) and a Multi-Token Prediction (MTP) objective to improve inference speed and training efficiency," and lists a 131,072-token maximum context[35]
Inference frameworks
Support for MLA in open-source inference engines arrived in stages:
-
SGLang: v0.3 (September 2024) added MLA optimizations "including weight absorption, grouped decoding kernels, FP8 batched MatMul, and FP8 KV cache quantization," which LMSYS reported gave 3x to 7x higher throughput than its baseline on H100 GPUs.[60] DeepSeek's V3 README recommends SGLang, cites those MLA optimizations, and lists day-one AMD GPU support through SGLang in BF16 and FP8.[61]
-
vLLM: v0.6.6 supported DeepSeek-V3 inference in FP8 and BF16 on NVIDIA and AMD GPUs; dedicated MLA support, led by Red Hat's Neural Magic team, arrived in v0.7.1 in early 2025.[61][41] For DeepSeek-V3.2-Exp, vLLM stores each token's FP8 MLA cache in 656 bytes (512 FP8 latent values, 16 bytes of scale factors, and the 64 rotary values left in BF16) and keeps a separate key cache for the DSA indexer.[17] A 2026 release added support for DeepSeek-V4's attention stack, which is not MLA.[28]
-
LightLLM: supports single-node and multi-node deployment of DeepSeek-V3 in FP8 and BF16, according to DeepSeek's README.[61]
As of 31 October 2026, vLLM's MLA attention backends include implementations built on FlashMLA, FlashInfer, CUTLASS, Triton and AMD's AITER, and SGLang ships FlashMLA, FlashInfer MLA, TensorRT-LLM MLA and CuTe DSL MLA backends.[62]
PyTorch implementations of MLA are available for study, such as the one in Sebastian Raschka's "LLMs-from-Scratch" repository, whose memory estimator shows a KV cache saving of about 75% over MHA for its example configuration.[19]
FlashMLA kernels
DeepSeek open-sourced FlashMLA on 24 February 2025 as the first release of its Open Source Week, describing it as an "Efficient MLA Decoding Kernel for Hopper GPUs" with BF16 support, a paged KV cache with block size 64, and "3000 GB/s memory-bound | BF16 580 TFLOPS compute-bound on H800."[50] FlashMLA exploits two structural properties of MLA: the shared compressed cache , which lets one cached entry serve as both key and value for all query heads, and the absorption of into the query, which lets attention scores be computed in the latent space.[1][49]
An April 2025 update delivered a 5% to 15% improvement on compute-bound workloads, reaching up to 660 TFLOPS on NVIDIA H800 SXM5 GPUs.[31] In September 2025 the library added the token-level sparse attention kernels behind DeepSeek Sparse Attention for DeepSeek-V3.2.[31] As of 31 October 2026, the README describes FlashMLA as "DeepSeek's library of optimized attention kernels, powering inference of the DeepSeek-V4.1 model on NVIDIA GPUs and Huawei Ascend NPUs," and its 30 September 2026 release removed support for the Hopper architecture and for DeepSeek V3, V3.2 and V4.0, directing users of those models to an earlier commit.[31] The FlashMLA article covers the kernels' history and formats in detail.
Production deployment patterns
DeepSeek's deployment of DeepSeek-V3 separates prefilling and decoding:[12]
Prefill operations (processing input prompts)
-
Minimum deployment unit of 4 nodes with 32 GPUs
-
The attention part uses 4-way tensor parallelism with sequence parallelism, combined with 8-way data parallelism
-
32-way expert parallelism for the MoE part
Decoding operations (generating output tokens)
-
Minimum deployment unit of 40 nodes with 320 GPUs
-
The attention part uses 4-way tensor parallelism with sequence parallelism, combined with 80-way data parallelism
-
320-way expert parallelism, with each GPU hosting one expert and 64 GPUs hosting redundant and shared experts
Limitations and challenges
Implementation complexity
MLA is harder to implement efficiently than GQA. Realizing the cache savings requires the decoupled rotary key, and fast decoding depends on the absorbed formulation and dedicated kernels.[1][49] DeepSeek itself runs MLA in two forms: the MHA mode for training and prefilling and the MQA mode for decoding, and for short-sequence prefilling under DSA it "specially implement[s] a masked MHA mode."[26] Red Hat's vLLM work found that MHA still gave better time to first token at low request rates.[41]
The decoupled RoPE mechanism adds mathematical and implementation complexity. Broadcasting operations for the shared RoPE key across all attention heads require efficient GPU kernels; without proper optimization, virtual replication can introduce performance overhead.[2]
Industry adoption
Attention design can be checked directly only where a model's weights and configuration files are published, which in practice means the open-weight releases. OpenAI's gpt-oss-120b, released with open weights in August 2025, runs Grouped-Query Attention with 8 key-value heads against 64 query heads and alternating sliding-window and full-attention layers, and carries none of MLA's kv_lora_rank, qk_nope_head_dim or v_head_dim fields.[44]
The TransMLA authors present their framework as a practical route for migrating GQA-based models onto the MLA structure, with direct compatibility with DeepSeek's codebase and its optimized kernels as part of the payoff.[5] Among open-weight labs the pattern through 2026 was concentration rather than convergence: Moonshot, Z AI, InclusionAI, Mistral AI and Sarvam AI shipped MLA in flagship or large models, MiniMax and Alibaba's Qwen line stayed with Grouped-Query Attention, and DeepSeek itself left MLA behind in V4.[27][36][37][38][39][40][52][53][54]
Quality considerations
Quality concerns center on the effects of lossy low-rank compression on specific capabilities. DeepSeek's published ablations compare MLA with MHA, and MHA with GQA and MQA, but not MLA directly with GQA at a matched cache size.[1] Other groups have since run such comparisons at small scale with their own proposals in the mix: the Tensor Product Attention paper (NeurIPS 2025), for example, trains MHA, MQA, GQA and MLA baselines of up to 1.5B parameters alongside its own method and reports that its T6 model matches or surpasses all of them.[58] There is a theoretical risk that important, fine-grained information could be lost during the down-projection to the latent space, and the latent dimension is a critical hyperparameter balancing compression ratio and information fidelity.[9][4]
Training and adoption challenges
MLA is an architectural feature that is normally incorporated during a model's pre-training. Converting an existing model pre-trained with MHA or GQA to MLA without further training causes a large drop in performance: in the TransMLA experiments, removing 92.97% of LLaMA-2-7B's KV cache without fine-tuning cut its six-benchmark average from 59.85 to 43.26.[5] This creates a "path dependency" for organizations with large investments in existing GQA-based models. Post-training conversion methods such as TransMLA, MHA2MLA, X-EcoMLA and the multimodal MHA2MLA-VLM are direct responses to this challenge.[5][21][30][59]
Theoretical foundations
Low-rank factorization
MLA's low-rank factorization approach builds on long-standing research into matrix compression and efficient neural architectures. The key assumption is that the key and value projections in transformer attention, while high-dimensional, can be well approximated through a compressed bottleneck without significant information loss.[1]
The technique is rooted in matrix approximation methods like singular value decomposition (SVD), where a matrix is approximated as with , , and .[9] Conversion methods use this directly: MHA2MLA initializes its latent projections from a joint SVD of pretrained key and value weights, and TransMLA from a joint PCA.[5][21]
Expressive power
The expressive power advantage stems from MLA's ability to reconstruct distinct keys and values for each attention head from the shared latent representation. While GQA forces heads to share identical KV matrices, MLA's per-head up-projection matrices and enable each head to extract different information from the compressed representation.[1]
The TransMLA paper formalizes this: it shows that GQA can always be represented by MLA with the same KV cache overhead, but that the converse does not hold, and that given the same cache size, expressiveness increases in the order GQA, MLA, MQA, with each transformable into the next in one direction only.[5]
Future directions
Hardware optimization
The DeepSeek-V3 technical report closes with suggestions to hardware vendors, most of them about communication and low-precision arithmetic rather than MLA specifically:[12]
-
Offloading communication tasks from the GPU's streaming multiprocessors to a dedicated co-processor
-
Higher FP8 GEMM accumulation precision in tensor cores
-
Native support for tile-wise and block-wise quantization
-
Fusing FP8 casting with memory transfers, or near-memory computing, for online quantization
-
Support for transposed GEMM operations
A 2025 DeepSeek paper presented at ISCA reflects further on hardware for these architectures and uses MLA's KV cache savings as one of its examples.[48]
Alternative and hybrid architectures
Alternative attention architectures continue to emerge alongside MLA:
-
Tensor Product Attention (TPA): factorizes queries, keys and values with contextual low-rank tensor decompositions; its authors show that MHA, MQA, and GQA "can be expressed as non-contextual variants of TPA"[58]
-
DeepSeek Sparse Attention (DSA): Layers fine-grained sparsity on top of MLA in DeepSeek-V3.2-Exp[26]
-
Compressed Sparse Attention (CSA) and Heavily Compressed Attention (HCA): What DeepSeek used in place of MLA in DeepSeek-V4. The DeepSeek-V4.1-Flash report treats them as acting on a different dimension of the same problem: GQA and MLA shrink the size of each cached entry, while CSA and HCA cut how many entries there are[27][33]
-
Kimi Linear: Moonshot's expressive linear-attention architecture, which interleaves three Kimi Delta Attention layers with one MLA layer[29]
-
Hybrid architectures: Several 2025-2026 open-weight models assign different attention mechanisms to different layers, among them Kimi K3, Ling 2.5 and Ling 3.0-flash, which pair MLA layers with linear attention, and Mistral Large 4, which pairs MLA with a sparse-attention indexer[36][38][53]
Subsequent works pair MLA with other efficiency techniques. MHA2MLA converts a pretrained MHA or GQA checkpoint to MLA with a small fine-tuning budget and can be combined with KV cache quantization.[21] DeepSeek Sparse Attention selects key-value entries on top of an MLA cache, and the V3.2-Exp report cites the Native Sparse Attention work for the kernel-level constraint that each entry be shared across multiple queries, which is why DSA runs in the MQA mode of MLA.[20][26]
Related concepts
The term "latent attention" is used in different contexts, and it is important to distinguish MLA from other mechanisms that use similar terminology.
Perceiver: Iterative latent attention
The Perceiver architecture, introduced by DeepMind, also uses a "latent array" and an attention bottleneck.[22] However, its purpose is fundamentally different. The Perceiver is designed to handle extremely high-dimensional and multi-modal inputs (such as images, audio, and point clouds) that are too large for a standard Transformer. It uses an asymmetric cross-attention mechanism where a small, fixed-size latent array iteratively "queries" the massive input data to distill it into a manageable representation.[22]
The bottleneck in the Perceiver serves to decouple the network's depth from the input's size, solving a problem at the input encoding stage. In contrast, MLA's latent vector is a mechanism for compressing the internal KV cache to improve inference efficiency for standard sequential data, addressing a bottleneck in the model's state management during generation.
Low-rank adaptation (LoRA)
Low-rank adaptation (LoRA) is a popular technique for parameter-efficient fine-tuning (PEFT) of large models. LoRA also uses low-rank matrix decomposition, but for a different purpose.[23] It freezes the large, pre-trained weight matrices of a model and injects small, trainable low-rank "adapter" matrices alongside them. During fine-tuning, only these small adapters are updated, dramatically reducing the number of trainable parameters.[24]
MLA, on the other hand, uses low-rank decomposition as a permanent, integral part of the model's core architecture to optimize inference, not as a temporary adapter for efficient training. The shared vocabulary shows up in configuration files: DeepSeek-style checkpoints name the compression dimensions kv_lora_rank and q_lora_rank even though no adapters are involved.[46]
Continue reading
- DeepSeekDeepSeek is a Chinese artificial intelligence company based in Hangzhou. It was founded in 2023 by Liang Wenfeng, who had previously co-founded the quantitative investment firm High-Flyer.Mentioned 172 times above
- LoRA (Low-Rank Adaptation)Low-Rank Adaptation, usually abbreviated LoRA, is a parameter-efficient fine-tuning method for adapting a pre-trained model.Mentioned 19 times above
- Mixture of Experts (MoE)A mixture of experts (MoE) is a machine-learning architecture that contains multiple component functions called experts and a gating or routing mechanism that determines how their outputs contribute to a…Mentioned 11 times above
- Grouped-Query AttentionGrouped-query attention (GQA) is an attention mechanism for transformer language models that partitions the query heads into a small number of groups, where every query head in a group shares one key…Mentioned 9 times above
- FlashMLAFlashMLA is an open-source library of attention kernels from DeepSeek, built around Multi-head Latent Attention (MLA), the attention variant DeepSeek uses to shrink the KV cache in its large language models.Mentioned 9 times above
- DeepSeek Sparse Attention (DSA)DeepSeek Sparse Attention (DSA) is a trainable, fine-grained sparse attention mechanism introduced by the Chinese AI company DeepSeek in its experimental model DeepSeek-V3.2-Exp, released on September 29, 2025.Mentioned 6 times above
More to read
Topics:Deep LearningMachine LearningModel ArchitectureNeural NetworksTransformer Models
See also
-
Attention mechanism
-
Attention (machine learning)
-
Transformer (machine learning)
-
Multi-head attention
-
Multi-query attention
-
Key-value cache
-
Perceiver
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32 ^33 ^34 ^35 ^36 ^37 ^38 ^39 ^40 ^41 ^42 ^43 ^44 ^45 ^46 ^47 ^48 ^49 ^50 ^51 ^52 ^53 ^54 ^55DeepSeek-AI et al. (2024). "DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model." arXiv:2405.04434.
- ^1 ^2Shekhar, S. "Understanding DeepSeek's Multi-Head Latent Attention (MLA)." Retrieved from shashankshekhar.com/blog/flashmla.
- ^1 ^2 ^3Vaswani, A. et al. (2017). "Attention Is All You Need." NeurIPS 2017.
- ^1 ^2 ^3 ^4 ^5Sinai, L. (February 2025). "DeepSeek's Multi-Head Latent Attention." liorsinai.github.io.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12Meng, F. et al. (February 2025). "TransMLA: Multi-Head Latent Attention Is All You Need." arXiv:2502.07864. Published at NeurIPS 2025 as "TransMLA: Migrating GQA Models to MLA with Full DeepSeek Compatibility and Speedup", decision "Accept (spotlight)". openreview.net/forum?id=TcVCu2PKb9.
- ^1 ^2Shazeer, N. (2019). "Fast Transformer Decoding: One Write-Head is All You Need." arXiv:1911.02150.
- ^1 ^2 ^3Banatt, P. "Understanding Multi-Head Latent Attention." planetbanatt.net/articles/mla.html.
- ^1 ^2Ainslie, J. et al. (2023). "GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints." EMNLP 2023.
- ^1 ^2 ^3 ^4Raschka, S. "Multi-Head Latent Attention (MLA)." LLM Architecture Gallery, sebastianraschka.com.
- ^Calmops. "Multi-Head Latent Attention MLA: DeepSeek's Memory Optimization." calmops.com/algorithms/multi-head-latent-attention-mla-deepseek.
- ^Aussie AI. "Multi-head Latent Attention (MLA)." aussieai.com/research/mla.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9DeepSeek-AI et al. (December 2024). "DeepSeek-V3 Technical Report." arXiv:2412.19437.
- ^Dao, T. (2023). "FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning." arXiv:2307.08691.
- ^1 ^2Su, J. et al. (2021). "RoFormer: Enhanced Transformer with Rotary Position Embedding." arXiv:2104.09864.
- ^PyImageSearch (October 2025). "KV Cache Optimization via Multi-Head Latent Attention." pyimagesearch.com.
- ^Vizuara. "Decoding Multi-Head Latent Attention (Part 2): Solving the RoPE Paradox." vizuara.substack.com.
- ^1 ^2vLLM Project (2025). "DeepSeek-V3.2-Exp in vLLM: Fine-Grained Sparse Attention in Action." blog.vllm.ai/2025/09/29/deepseek-v3-2.html.
- ^Google Cloud. "DeepSeek-V3.2." Vertex AI documentation. cloud.google.com/vertex-ai/generative-ai/docs/maas/deepseek/deepseek-v32.
- ^Raschka, S. "LLMs-from-Scratch" GitHub repository, MLA implementation.
- ^Yuan, J. et al. (February 2025). "Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse Attention." arXiv:2502.11089.
- ^1 ^2 ^3 ^4 ^5Ji, T., Guo, B., Wu, Y., Guo, Q., Shen, L., Chen, Z., Qiu, X., Zhang, Q., and Gui, T. (February 2025). "Towards Economical Inference: Enabling DeepSeek's Multi-Head Latent Attention in Any Transformer-based LLMs." ACL 2025. arXiv:2502.14837 (v2, October 2025).
- ^1 ^2Jaegle, A. et al. (2021). "Perceiver: General Perception with Iterative Attention." ICML 2021.
- ^Hu, E. et al. (2021). "LoRA: Low-Rank Adaptation of Large Language Models." arXiv:2106.09685.
- ^Hugging Face PEFT library documentation.
- ^1 ^2 ^3 ^4 ^5 ^6Raschka, S. (2026). "A Dream of Spring for Open-Weight LLMs: 10 Architectures from Jan-Feb 2026." magazine.sebastianraschka.com.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7DeepSeek-AI (September 2025). "DeepSeek-V3.2-Exp: Boosting Long-Context Efficiency with DeepSeek Sparse Attention." github.com/deepseek-ai/DeepSeek-V3.2-Exp/blob/main/DeepSeek_V3_2.pdf.
- ^1 ^2 ^3 ^4 ^5DeepSeek-AI (April 2026). "DeepSeek-V4: Towards Highly Efficient Million-Token Context Intelligence." arXiv:2606.19348.
- ^1 ^2vLLM Team (April 24, 2026). "DeepSeek V4 in vLLM: Efficient Long-context Attention." blog.vllm.ai/blog/2026-04-24-deepseek-v4.
- ^1 ^2 ^3 ^4Moonshot AI (October 2025). "Kimi Linear: An Expressive, Efficient Attention Architecture." arXiv:2510.26692.
- ^1 ^2Fan, X., Sun, Z., Ji, T., Shen, L., and Gui, T. (January 2026). "MHA2MLA-VLM: Enabling DeepSeek's Economical Multi-Head Latent Attention across Vision-Language Models." arXiv:2601.11464.
- ^1 ^2 ^3DeepSeek-AI. "FlashMLA: Efficient Multi-head Latent Attention Kernels." github.com/deepseek-ai/FlashMLA.
- ^1 ^2DeepSeek-AI. DeepSeek-V4-Pro and DeepSeek-V4-Flash model cards and config.json files. huggingface.co/deepseek-ai/DeepSeek-V4-Pro, huggingface.co/deepseek-ai/DeepSeek-V4-Flash.
- ^1 ^2DeepSeek-AI (September 2026). "DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression." huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash.
- ^Alibaba Cloud Data Intelligence (February 8, 2025). "One-Click Deployment of DeepSeek-V3 and DeepSeek-R1 Models." alibabacloud.com/blog/one-click-deployment-of-deepseek-v3-and-deepseek-r1-models_601973.
- ^Fireworks AI. "DeepSeek V3" model page. fireworks.ai/models/fireworks/deepseek-v3.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Moonshot AI. Kimi K2, K2.5, K2.6 and K3 config.json files on Hugging Face. huggingface.co/moonshotai/Kimi-K2-Instruct, huggingface.co/moonshotai/Kimi-K2.5, huggingface.co/moonshotai/Kimi-K2.6, huggingface.co/moonshotai/Kimi-K3.
- ^1 ^2 ^3 ^4Z AI. GLM-4.6, GLM-4.7, GLM-5, GLM-5.1 and GLM-5.3 config.json files on Hugging Face. huggingface.co/zai-org/GLM-4.7, huggingface.co/zai-org/GLM-5, huggingface.co/zai-org/GLM-5.3.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7InclusionAI. Ling-2.5-1T and Ling-3.0-flash config.json files on Hugging Face. huggingface.co/inclusionAI/Ling-2.5-1T, huggingface.co/inclusionAI/Ling-3.0-flash.
- ^1 ^2 ^3MiniMax. MiniMax-M2 and MiniMax-M2.5 config.json files on Hugging Face. huggingface.co/MiniMaxAI/MiniMax-M2, huggingface.co/MiniMaxAI/MiniMax-M2.5.
- ^1 ^2Alibaba Qwen. Qwen3.8-2.4T-A95B config.json on Hugging Face. huggingface.co/Qwen/Qwen3.8-2.4T-A95B.
- ^1 ^2 ^3 ^4Red Hat (February 4, 2025). "Enhancing DeepSeek models with MLA and FP8 optimizations in vLLM." redhat.com/en/blog/enhancing-deepseek-models-mla-and-fp8-optimizations-vllm.
- ^DeepSeek (September 29, 2025). "Introducing DeepSeek-V3.2-Exp." DeepSeek API Docs. api-docs.deepseek.com/news/news250929.
- ^DeepSeek. "Models & Pricing." DeepSeek API Docs, archived snapshots of September 22, 2025 (V3.1-Terminus) and October 4, 2025 (V3.2-Exp). web.archive.org/web/20250922123509/https://api-docs.deepseek.com/quick_start/pricing, web.archive.org/web/20251004112357/https://api-docs.deepseek.com/quick_start/pricing.
- ^OpenAI. gpt-oss-120b config.json on Hugging Face. huggingface.co/openai/gpt-oss-120b.
- ^1 ^2 ^3 ^4DeepSeek-AI. deepseek-llm-67b-base config.json on Hugging Face. huggingface.co/deepseek-ai/deepseek-llm-67b-base.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11DeepSeek-AI. DeepSeek-V2, DeepSeek-V2-Lite, DeepSeek-V3, DeepSeek-R1, DeepSeek-V3.1, DeepSeek-V3.2-Exp and DeepSeek-V3.2 config.json files on Hugging Face. huggingface.co/deepseek-ai.
- ^DeepSeek-AI (January 2025). "DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning." arXiv:2501.12948.
- ^1 ^2Zhao, C. et al. (May 2025). "Insights into DeepSeek-V3: Scaling Challenges and Reflections on Hardware for AI Architectures." ISCA '25 Industry Track. arXiv:2505.09343.
- ^1 ^2 ^3 ^4 ^5 ^6DeepSeek-AI (April 22, 2025). "A Deep-Dive Into the New Flash MLA Kernel." github.com/deepseek-ai/FlashMLA/blob/main/docs/20250422-new-kernel-deep-dive.md.
- ^DeepSeek-AI (February 2025). Open Source Week index, "Day 1 - FlashMLA." github.com/deepseek-ai/open-infra-index.
- ^DeepSeek-AI (December 2025). "DeepSeek-V3.2: Pushing the Frontier of Open Large Language Models." arXiv:2512.02556.
- ^1 ^2 ^3 ^4Mistral AI. Mistral-Large-3-675B-Instruct-2512 params.json and model card on Hugging Face. huggingface.co/mistralai/Mistral-Large-3-675B-Instruct-2512.
- ^1 ^2 ^3 ^4 ^5 ^6Mistral AI. Mistral-Large-4-1T-A52B model card, config.json and params.json on Hugging Face. huggingface.co/mistralai/Mistral-Large-4-1T-A52B.
- ^1 ^2 ^3 ^4Sarvam AI. sarvam-105b and sarvam-30b config.json files and sarvam-105b model card on Hugging Face. huggingface.co/sarvamai/sarvam-105b, huggingface.co/sarvamai/sarvam-30b.
- ^1 ^2 ^3Meituan LongCat Team. LongCat-Flash-Chat config.json and model card on Hugging Face, huggingface.co/meituan-longcat/LongCat-Flash-Chat; "LongCat-Flash Technical Report" (2025), arXiv:2509.01322.
- ^1 ^2OpenBMB. MiniCPM3-4B config.json on Hugging Face. huggingface.co/openbmb/MiniCPM3-4B.
- ^Moonshot AI. Moonlight-16B-A3B config.json and model card on Hugging Face. huggingface.co/moonshotai/Moonlight-16B-A3B.
- ^1 ^2Zhang, Y., Liu, Y., Yuan, H., Qin, Z., Yuan, Y., Gu, Q., and Yao, A. C. (2025). "Tensor Product Attention Is All You Need." NeurIPS 2025. arXiv:2501.06425.
- ^1 ^2Li, G., Rezagholizadeh, M., Yang, M., Appia, V., and Barsoum, E. (March 2025). "X-EcoMLA: Upcycling Pre-Trained Attention into MLA for Efficient and Extreme KV Compression." arXiv:2503.11132.
- ^LMSYS Org (September 4, 2024). "SGLang v0.3 Release: 7x Faster DeepSeek MLA, 1.5x Faster torch.compile, Multi-Image/Video LLaVA-OneVision." lmsys.org/blog/2024-09-04-sglang-v0-3/.
- ^1 ^2 ^3DeepSeek-AI. DeepSeek-V3 GitHub repository README, "How to Run Locally." github.com/deepseek-ai/DeepSeek-V3.
- ^vLLM project, MLA attention backends (github.com/vllm-project/vllm/tree/main/vllm/v1/attention/backends/mla), and SGLang project, attention backends (github.com/sgl-project/sglang/tree/main/python/sglang/srt/layers/attention). Accessed 31 October 2026.
- ^Chowdhery, A. et al. (2022). "PaLM: Scaling Language Modeling with Pathways." arXiv:2204.02311.
- ^Technology Innovation Institute. falcon-7b config.json on Hugging Face. huggingface.co/tiiuae/falcon-7b.
- ^Moonshot AI. Kimi-Linear-48B-A3B-Instruct config.json on Hugging Face. huggingface.co/moonshotai/Kimi-Linear-48B-A3B-Instruct.
- ^Touvron, H. et al. (2023). "Llama 2: Open Foundation and Fine-Tuned Chat Models." arXiv:2307.09288.
- ^1 ^2Grattafiori, A. et al. (2024). "The Llama 3 Herd of Models." arXiv:2407.21783.
- ^Jiang, A. Q. et al. (2023). "Mistral 7B." arXiv:2310.06825.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
14 revisions · v14 · 10,058 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independently verified 2026-10-31 against the DeepSeek-V2/V3/V3.2/V4 reports, DeepSeek ISCA 2025 paper, FlashMLA repo, TransMLA/MHA2MLA/X-EcoMLA/TPA papers, vLLM releases and the config.json of every adoption-table model; 7 verifier defects fixed and a duplicate reference removed before stamping.
Cite this page: AI Wiki. "Multi-head Latent Attention." aiwiki.ai, updated 31 Oct 2026, fact-checked 31 Oct 2026. CC BY 4.0. https://aiwiki.ai/wiki/multi-head_latent_attention