

Induction Heads
Induction heads are a circuit pattern in Transformer language models in which a small set of attention heads, typically spread across two layers, perform an in-context "match and copy" operation that completes patterns of the form [A][B] ... [A] -> [B].[1][2] In plain terms, when a token A has appeared earlier in the context followed by some token B, an induction head detects the second occurrence of A and raises the probability that the next token is B, letting the model continue a pattern it has just seen rather than relying only on what it memorized during pretraining.[1] Anthropic's 2022 paper In-context Learning and Induction Heads defines them directly: "'Induction heads' are attention heads that implement a simple algorithm to complete token sequences like [A][B] ... [A] -> [B]", and argues they "might constitute the mechanism for the majority of all 'in-context learning' in large transformer models".[1]
The mechanism was first characterized in late 2021 in Anthropic's A Mathematical Framework for Transformer Circuits[2] and elaborated in In-context Learning and Induction Heads by Catherine Olsson, Nelson Elhage, Neel Nanda, and 23 collaborators, which presents preliminary and indirect evidence that induction heads may be the mechanism behind most In-Context Learning in large language models.[1] The discovery is considered a foundational result in Mechanistic interpretability, in part because it ties a behavior visible in the loss curve (a sudden bump that coincides with the emergence of in-context learning) to a specific, decomposable circuit inside the network.[1] Induction heads scale: heads that satisfy the same prefix-matching and copying criteria appear in models ranging from small two-layer toy transformers up to a 40-layer, 13-billion-parameter model.[1]
What problem do induction heads solve?
Modern decoder-only transformers process text autoregressively, with each layer mixing information across positions through multi-head self-attention and applying token-wise nonlinear transformations through MLP blocks.[3] A long-standing puzzle for the field was that, in addition to the knowledge learned during pretraining, these models also display in-context learning: the ability to pick up patterns from a prompt and continue them without any weight updates.[4] Standard architectural descriptions did not by themselves explain how a fixed set of weights could implement such flexible context-conditioned behavior.
The mechanistic-interpretability program initiated by Chris Olah and colleagues at Anthropic approached this question by trying to reverse-engineer concrete circuits inside small transformer models, in the same spirit that the earlier Circuits thread had reverse-engineered vision networks.[2][5] The first concrete circuit they identified, in A Mathematical Framework for Transformer Circuits (December 22, 2021), was the induction head.[2] The paper showed that a two-layer attention-only transformer, which has no MLPs, can already learn an algorithm for completing repeated subsequences, and that this algorithm can be cleanly decomposed into two attention heads in different layers communicating through the residual stream.[2]
The follow-up paper In-context Learning and Induction Heads was first published in the Transformer Circuits Thread on March 8, 2022, and posted to arXiv as 2209.11895 on September 24, 2022.[1][6] It is a long, multi-part argument that the same circuit motif is responsible for the bulk of in-context learning capability not just in toy two-layer models but in the much larger transformers that constitute frontier language models.[1] The study analyzed 34 transformers over the course of training, including more than 50,000 attention-head ablations.[1]
The paper's author list includes 26 researchers, with Catherine Olsson, Nelson Elhage, Neel Nanda, Nicholas Joseph, Nova DasSarma, Tom Henighan, and Ben Mann among the first authors, and Chris Olah as the final author.[1] The work was produced almost entirely at Anthropic, with one of the lead authors, Neel Nanda, going on to become one of the most visible communicators of the mechanistic-interpretability approach through his open-source library TransformerLens and his subsequent role at Google DeepMind.[10]
How do induction heads work?
Behavioral definition
An induction head is most easily described by its behavior on a sequence in which a short pattern repeats. Given a sequence ending in token A that has appeared somewhere earlier in the context, an induction head:[1][2]
- Prefix matching. When the query position is at the second occurrence of A, the head's attention pattern places weight on the token immediately following the first occurrence of A. In other words, if the context is
... A B ... ... A, the head at the trailing position attends to the position of the earlier B. The paper describes this as the head attending "back to previous tokens that were followed by the current and/or recent tokens".[1] - Copying. The head's OV (output-value) circuit then increases the logit corresponding to the attended-to token. In the same example, this raises the predicted probability that the next token after the second A will again be B.[1]
Together these two behaviors implement the pattern [A][B] ... [A] -> [B].[1] The original paper operationalizes the test using repeated random tokens: random sequences of tokens are concatenated with themselves, so that prefix matching and copying can be detected as numerical scores even when the underlying tokens have no semantic meaning.[1] A head is classified as an induction head when it scores highly on both metrics.
The two-head mechanism
The minimal mechanism, identified in two-layer attention-only models, uses a pair of heads in two consecutive layers connected through the residual stream.[2]
The previous-token head is the first ingredient. It lives in the earlier layer and learns an attention pattern that simply attends from each position to the position immediately before it. Its OV circuit then writes a representation of the previous token into the residual stream at the current position. After this head fires, every token's residual stream carries information about what token preceded it.[2]
The induction head is the second ingredient and lives in the later layer. Its queries are computed from the residual stream at the current position, but, crucially, its keys are computed from the residual stream of earlier positions after the previous-token head has written to them. So the keys at an earlier position now encode the token at that position together with the token that came before it. The induction head's QK circuit learns to match the current token against the "what came before" component of earlier keys, which means it places attention on positions whose preceding token equals the current token. Its OV circuit then copies the value (the token identity) from the attended position back to the output, raising that token's logit.[1][2] As the paper puts it, this first head "copies information from the previous token into each token", which "makes it possible for the second attention head to attend to tokens based on what happened before them, rather than their own content".[1]
This pattern of one head's output feeding into another head's keys is what A Mathematical Framework for Transformer Circuits calls K-composition.[2] The same framework also defines Q-composition (where queries come from earlier heads' outputs) and V-composition (where values are routed through earlier heads). Induction heads are the canonical and most prominent example of K-composition discovered in real transformers.[2] The framework distinguishes this from V-composition, whose two-head paths can be treated as virtual attention heads that act like a single head; K- and Q-composition instead change the attention pattern itself and are not reducible in this way, which is why the induction circuit needs two layers.[2]
One useful way to picture the difference between a single-layer model and a two-layer model is that the single-layer model can only attend to tokens based on their own identity (or their position), since the keys at each position are computed directly from the embedding of the token at that position.[2] Adding a previous-token head in a second layer enriches the keys at each position with information about the preceding token, which is exactly the information an induction head needs to perform prefix matching. Anthropic's framework treats this as a general lesson about transformer expressivity: composing attention heads through the residual stream allows later heads to attend on the basis of computed features rather than raw token identity, and induction heads are the simplest behavior that requires this extra expressivity.[2]
QK and OV circuits
A central conceptual move in the Mathematical Framework paper is to decompose each attention head into two independent circuits, both expressible as low-rank bilinear forms on the residual stream.[2]
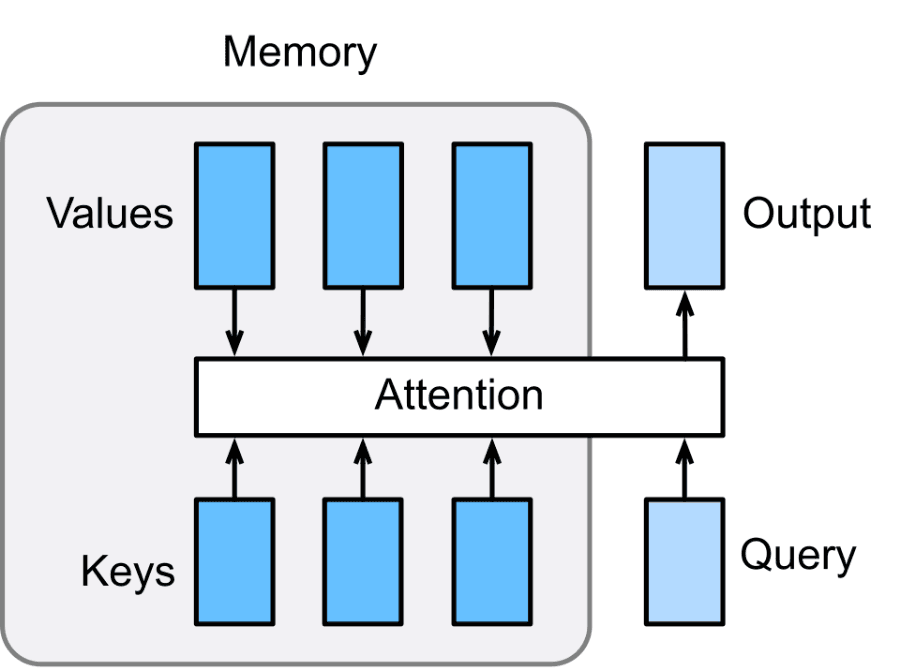
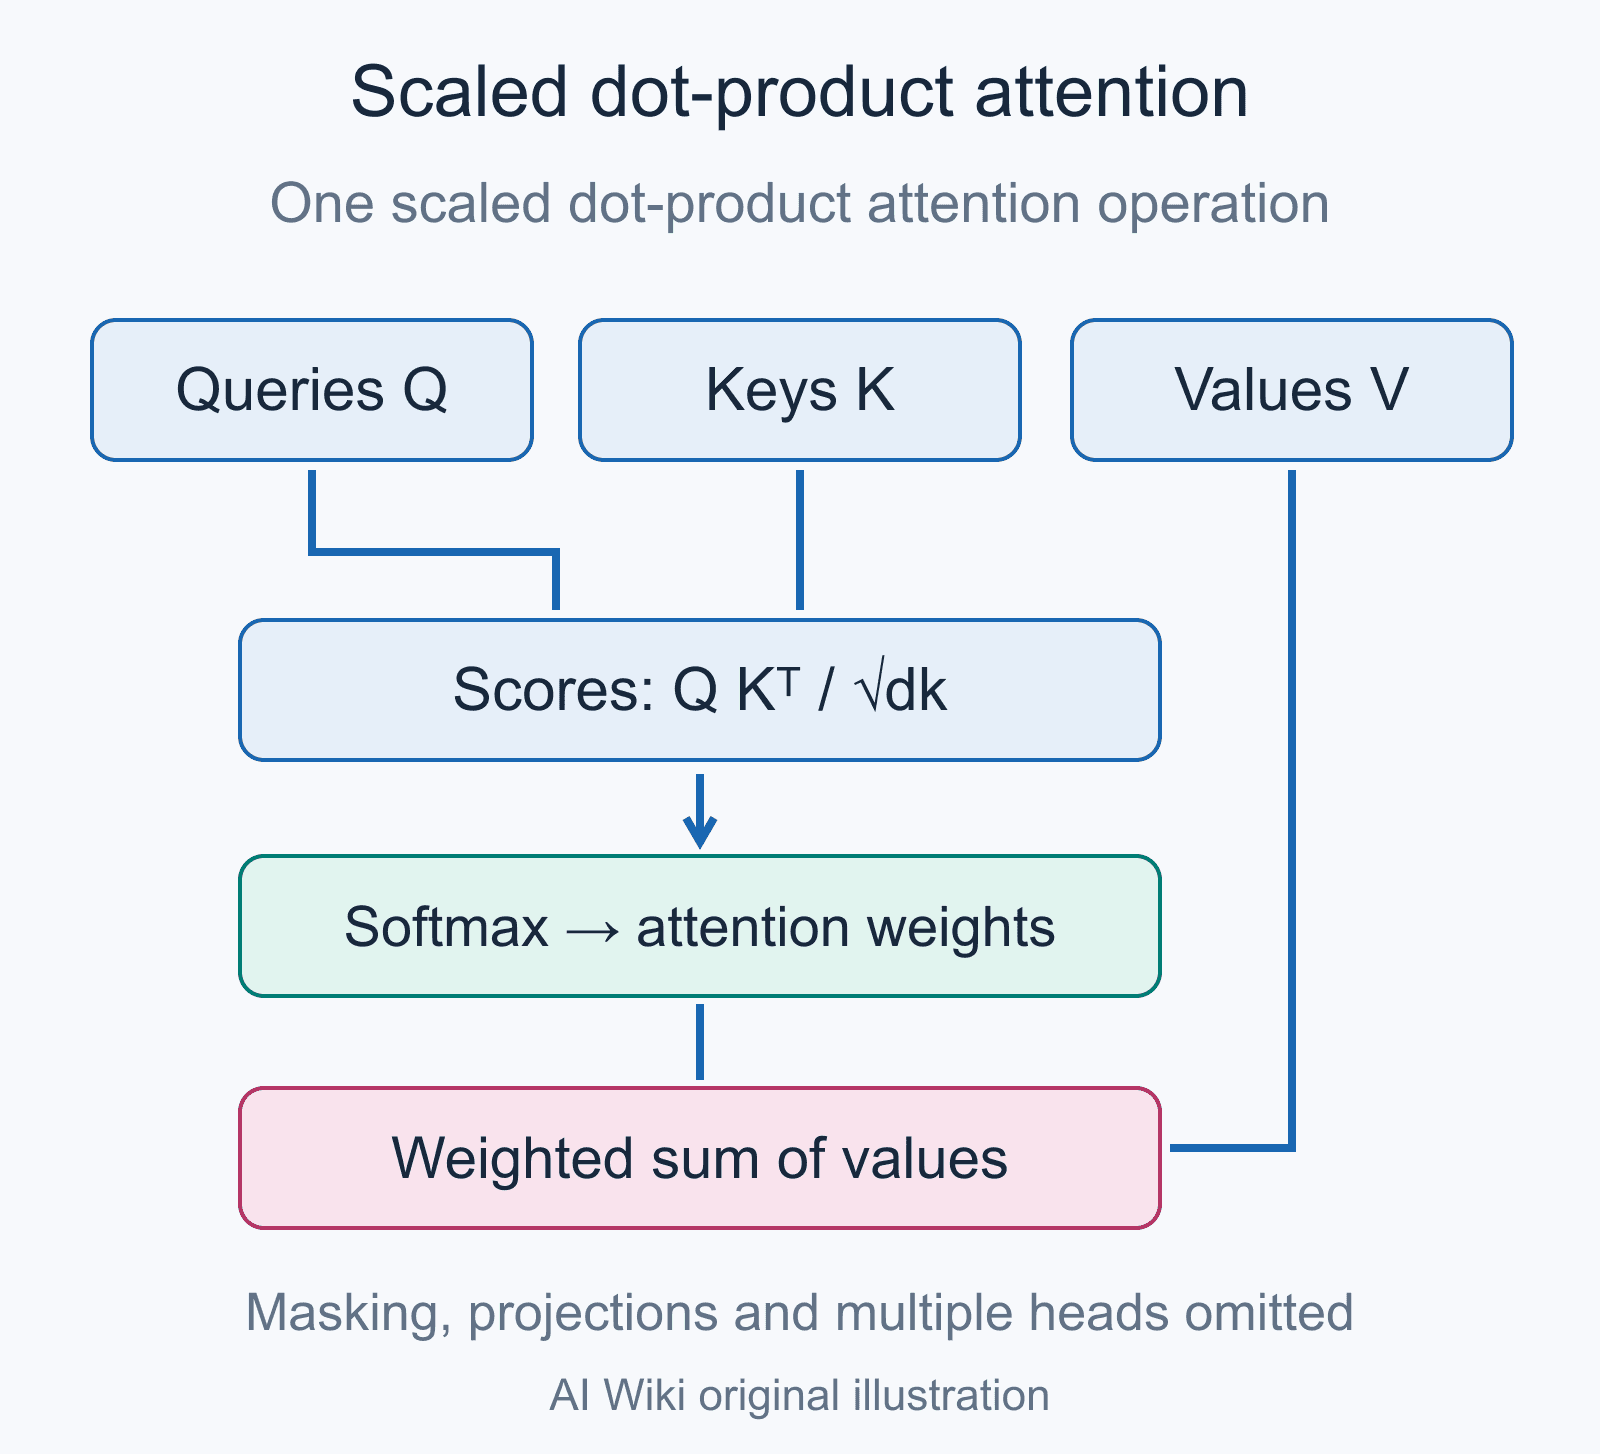
The QK circuit of a head is the matrix product W_Q^T W_K, projected through the embedding and any upstream head outputs. It determines where the head attends, based on the dot product between the query at the current position and the key at each previous position.[2]
The OV circuit of a head is the matrix product W_O W_V, projected through the embedding and any downstream contributions to the logits. It determines what is written to the residual stream when the head does attend, and hence how each attended token shifts the output distribution.[2]
For an induction head, both circuits do something distinctive. The QK circuit, after K-composition with the previous-token head, implements a prefix-matching pattern: it produces large attention scores at positions whose preceding token equals the query token.[1][2] The OV circuit implements a copying pattern: when the head attends to a token, it raises the logit of that token in the output. Together these two patterns yield the [A][B] ... [A] -> [B] behavior.[1]
The QK/OV split is more than a notational convenience: it makes head analysis tractable because each circuit is bilinear in the residual stream and can be studied as a low-rank linear operator.[2] In particular, when looking at induction heads, one can plot the QK circuit's attention pattern on repeated sequences and see prefix matching as a literal diagonal band off the main diagonal, and one can plot the OV circuit's effective contribution to the logits and see copying as a near-identity map from token embeddings to logit increments. These visualizations are the empirical signatures that the In-context Learning and Induction Heads paper uses to flag candidate induction heads in models from small attention-only toys up to a 13-billion-parameter transformer.[1]
Generalization beyond literal copying
A natural worry about the basic story is that it sounds too literal: real transformers do far more than copy verbatim subsequences. The In-context Learning and Induction Heads paper argues that this is mostly a matter of how strictly one reads the QK and OV circuits.[1] The paper distinguishes several relaxations:
- Translation-style induction. When the OV circuit maps token B not to B itself but to a related token B', the same kind of head can track the corresponding word in an earlier sentence written in another language; the paper shows a layer-7 head in its 40-layer model doing this across English, French, and German text.[1]
- Fuzzier matching. When the QK circuit attends to positions whose preceding context is similar, rather than literally equal, the same circuit handles paraphrased or partially varied repetitions.[1]
- Longer prefixes. Multi-head compositions can match on more than one preceding token, in effect approximating higher-order n-gram lookups rather than only matching against the single previous token.[1]
These generalizations form a continuous spectrum from literal copy heads to behaviors that look, at the level of model output, like reasoning. The argument in the paper is that the same QK/OV decomposition, generalized in these directions, accounts for a large share of what is described colloquially as in-context learning.[1]
How were induction heads discovered, and what is the induction bump?
Coincident emergence with in-context learning
The most striking empirical claim of In-context Learning and Induction Heads concerns the training dynamics of these circuits.[1] When the authors train transformers from scratch and track both the formation of induction heads and a quantitative measure of in-context learning, they find that the two emerge simultaneously, during a narrow window early in training. As the paper states, "induction heads develop at precisely the same point as a sudden sharp increase in in-context learning ability, visible as a bump in the training loss".[1] Anthropic refers to this window informally as the "induction bump" and the broader event as a "phase change", noting that it is one of very few clearly localized events in the otherwise smooth training-loss curves of language models.[1]
The paper operationalizes in-context learning capability with a simple metric: "the loss of the 500th token in the context minus the average loss of the 50th token in the context, averaged over dataset examples".[1] If a model has good in-context learning, its loss should decrease as the context grows because later tokens benefit from earlier ones, so this difference becomes large and negative. The induction-head formation is detected directly through the prefix-matching and copying scores on repeated random tokens.[1] In every multi-layer model studied, the two curves shift together: induction heads appear, prefix-matching and copying scores jump, in-context learning capability jumps, and the training loss briefly bumps.[1]
The same phenomenon shows up under perturbations. When the authors change the architecture in ways that move the timing of the loss bump, the formation of induction heads moves with it; in-context learning capability tracks the same shift.[1] This co-perturbation is one of the strongest pieces of correlational evidence for a causal link between the two phenomena.[1]
Subsequent work has refined this picture by studying what has to be true of the training data for induction heads to form. The 2024 paper What needs to go right for an induction head? by Aaditya Singh and collaborators studies induction-head emergence by training transformers on a synthetic few-shot task built from the Omniglot dataset, using an optogenetics-inspired framework that clamps subsets of activations throughout training.[22] It finds that induction heads are diverse and additive, and identifies three underlying subcircuits that interact to drive induction-head formation and produce the phase change; these subcircuits also explain data-dependent properties such as the timing of the phase change.[22]
What are the six lines of evidence?
The paper organizes its argument as six complementary lines of evidence that the induction-head circuit is the mechanistic source of much of in-context learning at scale.[1]
- Macroscopic co-occurrence. Induction heads form at the same point in training as the in-context learning bump (the phase change).[1]
- Macroscopic co-perturbation. Architectural changes that delay or accelerate one effect delay or accelerate the other in lockstep.[1]
- Direct ablation. Knocking out induction heads at test time in small models causes a large drop in in-context learning, as measured by the loss-difference metric.[1]
- Specific examples of generality. Induction-head-like behavior shows up in literal copying, translation, and a type of abstract pattern matching, suggesting that the underlying circuit motif is doing more than verbatim copying.[1]
- Mechanistic plausibility. The two-layer two-head construction is fully reverse-engineered in toy models, providing a concrete proof of concept that the QK and OV decomposition can implement the observed behavior.[1][2]
- Continuity across scale. Induction-head-like heads, defined by their prefix-matching and copying scores, are found in models from a few layers up through the largest transformers the authors examined, suggesting the same motif persists when MLPs and more layers are added.[1]
For small attention-only models the argument is causal: ablating the relevant heads removes the relevant behavior.[1] For larger models with MLPs and many more layers, the evidence is mostly correlational; the paper is explicit that it can only show consistent statistical signatures, not a fully reverse-engineered circuit at scale.[1]
Ablation studies
Ablation is the central tool used to make the causal case in small models.[1] The procedure is to remove an attention head from the model at test time and measure the change in the in-context learning score.[1] The paper describes two variants: a "full" ablation, which removes all of a head's contributions to model behavior, and a "pattern-preserving" ablation, which removes the head's contribution to later heads' output vectors but preserves its contribution to their attention patterns; the Model Analysis Table reports only pattern-preserving ablations.[1] In the small models, knocking out induction heads greatly decreases in-context learning, and almost all of the in-context learning in small attention-only models appears to come from induction heads; ablating most other heads actually increases the in-context learning score.[1]
The paper's evidence draws on 34 models and more than 50,000 attention-head ablations, but the ablations cover only the small models: the authors note they do not have ablations for their full-scale models, because the cost of a full set of ablations scales superlinearly with model size.[1]
The paper is explicit about how far this evidence reaches. In attention-only models the logits can be written as a sum of contributions from individual heads plus a direct path term that cannot contribute to in-context learning, so ablations are a principled way to measure each head's contribution; in models with MLPs, in-context learning could also come from interactions between MLP and attention layers.[1] Combined with the formation-time correlations and the architectural co-perturbation experiments, this is the strongest causal evidence the paper offers for small models.[1]
What variants and generalizations of induction heads exist?
The induction-head template has proven remarkably extensible. Researchers have built on it in two complementary directions: relaxing what counts as a "match" (so the same circuit can handle approximate or semantic repetition) and relaxing what counts as a "copy" (so the head can edit, translate, or otherwise transform the attended-to token rather than simply repeat it). Many subsequent interpretability findings can be read as decorations on the basic QK/OV decomposition that the induction-head paper introduced.
Fuzzy and semantic induction
The basic induction head matches identical tokens. Follow-up work has shown that a continuum of related circuits performs fuzzy matching, attending to context positions whose surrounding tokens are similar in some learned representation but not necessarily identical.[1][7] This explains how the same family of circuits can support paraphrased or inflected pattern completion in natural text rather than only literal repetition.
Subsequent research formalized parts of this picture under the heading of semantic induction heads: heads that, when attending to a "head" token, recall a semantically related "tail" token (linked by a syntactic dependency or a knowledge-graph relation) and raise its output logit; their formation correlates closely with the emergence of in-context learning.[7] These heads remain interpretable using the same QK/OV decomposition but operate on more abstract representations carried by the residual stream after MLPs and earlier attention layers have processed it.[7]
N-gram induction
A natural extension of the basic two-head construction allows the previous-token head, or chains of such heads, to write information about not just one but several preceding tokens into each position.[8] The induction head then prefix-matches against this longer context, effectively performing in-context n-gram lookup. This generalization has been explored both as an interpretability lens and as an inductive bias: one line of work explicitly hardcodes an n-gram induction layer into transformers as a drop-in replacement for parts of multi-head attention.[8]
Generalized induction heads
Other work has used the induction-head idea as a design template. Kim et al. propose the Generalized Induction-Head Model (GIM), an interpretable next-token predictor inspired by induction heads: a retrieval-based module that finds similar sequences in the context by combining exact n-gram matching with fuzzy matching based on a neural similarity metric.[9] The authors evaluate it on language modeling and on fMRI response prediction.[9]
Selective and structured induction
A more recent strand of theoretical work has analyzed selective induction heads: induction-like circuits that learn to choose, in context, which causal structure to use when completing a sequence.[20] Such heads can implement different match-and-copy rules conditional on properties of the prompt, providing a mechanistic story for tasks where the model must infer which kind of pattern is being demonstrated before completing it.[20] Related work has also shown that two-layer transformers can provably represent induction heads over arbitrary-order Markov chains, providing a theoretical underpinning for the n-gram-style generalizations that empirical work observes.[21]
What tools and datasets are used to study induction heads?
TransformerLens
The most widely used software for studying induction heads and related circuits is TransformerLens, an open-source library for mechanistic interpretability of GPT-style language models originally created by Neel Nanda.[10] TransformerLens exposes hook points on every internal activation, making it straightforward to capture attention patterns, intervene on specific heads, and run ablations. The library's introductory tutorial is built around reproducing induction-head behavior on small models, and the prefix-matching/copying metrics defined in the In-context Learning and Induction Heads paper are standard utilities in the library.[10]
TransformerLens has since become a de facto standard for circuit-level analyses, used in much of the academic mechanistic-interpretability literature and maintained by an open-source community.[10]
For users who want a hands-on introduction, the library's README links an introductory tutorial on the library and mechanistic interpretability, and lists a user-contributed notebook that partially replicates the induction-head phase change from In-context Learning and Induction Heads.[10] This pedagogical pipeline has made induction-head analysis one of the standard first projects for new students of mechanistic interpretability.[10]
Repeated random tokens and other probes
The repeated-random-tokens probe used in In-context Learning and Induction Heads is a deliberately stripped-down dataset: sequences of randomly sampled tokens concatenated with themselves so that the only useful pattern is the repetition.[1] Because the tokens are random, any head whose attention pattern correlates with the repeat structure can be flagged as performing prefix matching, and any head whose OV circuit reliably boosts the repeated token can be flagged as copying.[1]
While useful, this probe has known limitations: heads that perform sophisticated context processing on natural text may fall back to induction-like behavior only on stripped-down repeated sequences, which can produce false positives if one identifies induction heads from RRT scores alone.[11] Subsequent analyses have therefore complemented RRT scores with task-specific behavioral tests, attention-pattern visualizations, and head-by-head ablations on natural data.[11]
How do induction heads relate to other interpretability work?
Function vectors and task vectors
A line of research initiated by David Bau and collaborators identified function vectors: linear directions in transformer activation space that can be patched into a clean prompt to make the model perform a specific in-context task.[12] Function vectors are constructed by averaging the outputs of a small set of attention heads, identified via causal mediation analysis, that mediate in-context learning across many tasks.[12] Function-vector heads are distinct from induction heads but correlated with them: many function-vector heads start out as induction heads during training before transitioning to the function-vector mechanism, which suggests that induction is a precursor or building block for function-vector behavior.[13]
A closely related notion, task vectors, describes hidden-state representations that the model constructs from few-shot demonstrations and then uses to steer subsequent predictions.[14] Function vectors and task vectors are closely related constructs, and the finding that many function-vector heads begin as induction heads links the circuit-level description of induction to this more representational language.[12][13][14]
Attribution graphs and Claude
Anthropic's later interpretability work moved from circuits identified by hand to mechanized analyses based on sparse-coding decompositions and Attribution Graphs.[15][16] The 2025 paper On the Biology of a Large Language Model applies Attribution Graphs built from Cross-Layer Transcoders to study Claude 3.5 Haiku, including circuits for multi-hop reasoning, planning in poetry, and shared multilingual concepts.[15][16] This work emphasizes feature-level rather than head-level explanations; in its jailbreak case study, for example, the graphs suggest some output tokens are mainly produced by simple induction, copying, and grammar-based behavior.[15]
The same line of work connects to feature-level interpretability using Sparse autoencoder dictionaries, as developed in Towards Monosemanticity and Scaling Monosemanticity.[17][18] Where induction heads explain how the model routes information across positions, sparse autoencoders explain what the residual stream encodes at each position; both perspectives are needed to describe what a circuit actually does.
Logit lens and copy suppression
The induction-head picture has also influenced work on other interpretable attention heads. The Logit lens technique, which projects intermediate residual-stream activations through the unembedding to read out what the model would predict at each layer, is commonly used to diagnose copying and induction behavior at intermediate layers.[19] Closely related is the discovery of copy-suppression heads, which act as a counterweight to copy-like heads (including induction heads) by reducing the logits of tokens that other components are pushing to repeat; copy suppression by a single head in GPT-2 Small (L10H7) is one of several mechanisms behind self-repair when other heads are ablated, explaining 39% of that behavior in a narrow task.[19]
How common are induction heads across model scales?
A central practical claim of the original work is that induction-head-like circuits are not artefacts of toy models: they appear in transformers across orders of magnitude in scale.[1] The Anthropic paper found induction heads in models ranging from two-layer attention-only toys up to a 40-layer model with 13 billion parameters, and reported that the prefix-matching and copying scores remain reliable head-identification signals at scale.[1] Subsequent independent work has confirmed prefix-matching, copying, and induction-like patterns in a wide variety of public GPT-2, Pythia, and Llama checkpoints.[11][13]
The dominance of induction-style mechanisms at scale is, however, more nuanced than the basic story suggests. More recent analyses have shown that in models above roughly a billion parameters, ablating heads identified by classic induction scores while preserving heads identified by function-vector scores leaves few-shot in-context learning mostly intact, while ablating the function-vector heads (which still exhibit induction-like patterns) impairs it much more.[13] One interpretation is that induction is a precursor mechanism that, at scale, is partially absorbed into or supplemented by more abstract task-conditioned heads.[13] The basic motif, prefix-matching followed by output copying through a QK/OV decomposition, persists across this transition, even as the heads that implement it become more specialized.
The timing of induction-head formation is also sensitive to architecture: in In-context Learning and Induction Heads, a "smeared key" architectural change moves the phase change, and the formation of induction heads and in-context learning move with it.[1] Theoretical work has also analyzed the learning dynamics of a simplified two-layer induction construction on first-order Markov chains, illustrating how in-context representations emerge during training.[21]
Why do induction heads matter?
Induction heads occupy an unusual position in the Mechanistic interpretability literature: they are the first concrete circuit discovered inside a real language model that ties a mechanism to an emergent capability.[1][2] Several aspects of the result have shaped subsequent interpretability research.
First, induction heads gave the field a clean example of how a behavior identified at the loss-curve level (a bump in the training loss, a phase change in in-context learning ability) could be matched to a specific circuit at the parameter level.[1] This linkage between training dynamics and circuit-level mechanism remains a model for what mechanistic-interpretability arguments aspire to.[15]
Second, the QK/OV decomposition introduced alongside induction heads has become a default conceptual tool in interpretability writing.[2] Almost every subsequent attention-head case study, from the GPT-2 Small IOI (indirect object identification) circuit through the copy-suppression analyses, uses some form of the QK/OV split to organize its findings.[19]
Third, induction heads serve as the introductory example in essentially every modern mechanistic-interpretability tutorial.[10] TransformerLens's onboarding materials, Neel Nanda's introductory lectures, and many independent course notes all use the construction as the first nontrivial circuit students reverse-engineer.[10] The choice is pedagogically natural: induction heads sit at the boundary where toy theory meets real, scaling phenomena.
Finally, induction heads matter for AI safety because they provide an existence proof that one can locate, name, and intervene on the specific machinery responsible for a high-level capability.[1] If similar arguments can be made for capabilities related to deception, situational awareness, or other safety-relevant behaviors, the same toolkit of circuit identification, training-dynamics analysis, and ablation could allow more direct safety reasoning. The induction-head paper is frequently cited as a proof of concept that such arguments are at least possible.[1][15]
What are the limitations of the induction-head story?
Several caveats apply to the induction-head story, and the original paper is careful about them.[1] At larger scales the evidence for a causal link between induction heads and in-context learning is correlational rather than causal: it is consistent with multiple mechanisms, of which induction is the most parsimonious but not the only candidate.[1] The mechanistic two-head story is also explicitly minimal; real models implement induction-like behavior using compositions across more than two layers, multiple heads per role, and contributions from MLPs, none of which are captured by the basic construction.[11]
The behavioral definition based on repeated random tokens, while convenient, can both miss heads that perform context-rich induction only on natural text and falsely flag heads that exhibit copy-like behavior only as a fallback on degenerate inputs.[11] Several follow-up analyses have argued that the cleanest characterization of "induction" depends on the test distribution one uses, and that any single score should be treated as a coarse proxy rather than a definitive identifier.[11]
Finally, the relationship between induction heads and other mechanisms responsible for in-context learning is now understood to be more complex than originally proposed. As noted above, function-vector heads and task-vector representations partially decouple from classic induction signatures at scale, and parts of in-context learning that involve abstract pattern recognition or task inference may be carried by mechanisms that go well beyond simple prefix-matching and copying.[13]
ELI5: what is an induction head?
Imagine you are reading a sentence and you see the name "Dr. Lee" early on. Later you see "Dr." again and, before you even read the next word, you guess "Lee", because that is the word that followed "Dr." last time. An induction head is the little piece of a language model that does exactly this guess: it looks back for where the current word appeared before, sees what came next, and bets that the same thing will come next again.[1] It is made of two cooperating parts: one part tags every word with "the word before me was X", and the other part uses those tags to find a matching spot earlier in the text and copy whatever followed it.[1][2] This simple copy-the-pattern trick turns out to power a lot of what makes large language models seem to "learn" from the examples you put in a prompt.[1]
Related Work
| Concept | Relation to induction heads |
|---|---|
| In-Context Learning | The behavior that induction heads are hypothesized to implement at the circuit level. |
| Mechanistic interpretability | The broader research program that discovered induction heads as one of its first concrete circuits. |
| Attribution Graphs | A later interpretability framework that builds feature- and edge-level explanations for behaviors related to those induction heads explain at the head level. |
| Sparse autoencoder | A complementary tool for decomposing the residual stream into features that induction heads then route across positions. |
| Logit lens | A diagnostic technique often paired with induction-head analyses to read out how copying behavior builds up across layers. |
| Towards Monosemanticity | Anthropic's first sparse-feature decomposition of a language model, conceptually adjacent to the head-level decomposition that defines induction heads. |
| Scaling Monosemanticity | The follow-up that scales sparse-feature analysis to Claude 3 Sonnet, complementing head-level analyses with feature-level ones. |
| On the Biology of a Large Language Model | Applies attribution graphs to Claude 3.5 Haiku, explaining behaviors at the feature level rather than the attention-head level. |
Continue reading
- In-Context LearningIn-context learning (ICL) is the ability of a large language model to learn a new task at inference time by conditioning on a prompt that contains a few input-output examples (demonstrations)Mentioned 41 times above
- AttentionAttention is a family of operations in neural networks that computes an output by assigning data-dependent weights to a collection of representations and combining them.Mentioned 35 times above
- TransformersA Transformer is a deep learning architecture, introduced by eight Google researchers in the 2017 paper "Attention Is All You Need", that uses attention as the sole mechanism for modeling relationships between…Mentioned 12 times above
- AnthropicAnthropic is an American artificial intelligence (AI) safety and research company founded in 2021 by Dario Amodei, Daniela Amodei, and other former OpenAI researchers, best known for the Claude family of large…Mentioned 9 times above
- Mechanistic interpretabilityMechanistic interpretability (often abbreviated as mech interp or MI) is the field that reverse-engineers the internal computations of neural networks, particularly transformersMentioned 6 times above
- TransformerLensTransformerLens is an open-source Python library for the mechanistic interpretability of GPT-style language models.Mentioned 6 times above
More from See also
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32 ^33 ^34 ^35 ^36 ^37 ^38 ^39 ^40 ^41 ^42 ^43 ^44 ^45 ^46 ^47 ^48 ^49 ^50 ^51 ^52 ^53 ^54 ^55 ^56 ^57 ^58 ^59 ^60 ^61 ^62 ^63 ^64Catherine Olsson, Nelson Elhage, Neel Nanda et al., "In-context Learning and Induction Heads", Transformer Circuits Thread / arXiv:2209.11895, 2022-09-24. arxiv.org/...2209.11895. Accessed 2026-05-20.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23Nelson Elhage, Neel Nanda, Catherine Olsson et al., "A Mathematical Framework for Transformer Circuits", Anthropic / Transformer Circuits Thread, 2021-12-22. transformer-circuits.pub/...framework. Accessed 2026-05-20.
- ^Ashish Vaswani et al., "Attention Is All You Need", arXiv:1706.03762, 2017-06-12. arxiv.org/...1706.03762. Accessed 2026-05-20.
- ^Tom B. Brown et al., "Language Models are Few-Shot Learners", arXiv:2005.14165, 2020-05-28. arxiv.org/...2005.14165. Accessed 2026-05-20.
- ^Chris Olah et al., "Zoom In: An Introduction to Circuits", Distill, 2020-03-10. distill.pub/...zoom-in. Accessed 2026-05-20.
- ^Catherine Olsson et al., "In-context Learning and Induction Heads", Transformer Circuits Thread, 2022-03-08. transformer-circuits.pub/...ng-and-induction-heads. Accessed 2026-05-20.
- ^1 ^2 ^3Jie Ren et al., "Identifying Semantic Induction Heads to Understand In-Context Learning", arXiv:2402.13055, 2024-02-20. arxiv.org/...2402.13055. Accessed 2026-05-20.
- ^1 ^2Ilya Zisman et al., "N-Gram Induction Heads for In-Context RL: Improving Stability and Reducing Data Needs", arXiv:2411.01958, 2024-11-04. arxiv.org/...2411.01958. Accessed 2026-05-20.
- ^1 ^2Eunji Kim et al., "Interpretable Next-token Prediction via the Generalized Induction Head", arXiv:2411.00066, 2024-10-31. arxiv.org/...2411.00066. Accessed 2026-05-20.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Neel Nanda and contributors, "TransformerLens: A library for mechanistic interpretability of GPT-style language models", GitHub, 2022-08-26. github.com/...TransformerLens. Accessed 2026-05-20.
- ^1 ^2 ^3 ^4 ^5 ^6Alexandre Variengien, "Some common confusion about induction heads", LessWrong, 2023-03-28. lesswrong.com/...n-confusion-about-induction-heads. Accessed 2026-05-20.
- ^1 ^2 ^3Eric Todd, Millicent L. Li, Arnab Sen Sharma, Aaron Mueller, Byron C. Wallace, David Bau, "Function Vectors in Large Language Models", arXiv:2310.15213, 2023-10-23. arxiv.org/...2310.15213. Accessed 2026-05-20.
- ^1 ^2 ^3 ^4 ^5 ^6Kayo Yin et al., "Which Attention Heads Matter for In-Context Learning?", arXiv:2502.14010, 2025-02-19. arxiv.org/...2502.14010. Accessed 2026-05-20.
- ^1 ^2Roee Hendel, Mor Geva, Amir Globerson, "In-Context Learning Creates Task Vectors", arXiv:2310.15916, 2023-10-24. arxiv.org/...2310.15916. Accessed 2026-05-20.
- ^1 ^2 ^3 ^4 ^5Jack Lindsey et al., "On the Biology of a Large Language Model", Anthropic / Transformer Circuits Thread, 2025-03-27. transformer-circuits.pub/...biology. Accessed 2026-05-20.
- ^1 ^2Anthropic, "Circuit Tracing: Revealing Computational Graphs in Language Models", Transformer Circuits Thread, 2025-03-27. transformer-circuits.pub/...methods. Accessed 2026-05-20.
- ^Trenton Bricken et al., "Towards Monosemanticity: Decomposing Language Models With Dictionary Learning", Anthropic / Transformer Circuits Thread, 2023-10-04. transformer-circuits.pub/...monosemantic-features. Accessed 2026-05-20.
- ^Adly Templeton et al., "Scaling Monosemanticity: Extracting Interpretable Features from Claude 3 Sonnet", Anthropic / Transformer Circuits Thread, 2024-05-21. transformer-circuits.pub/...scaling-monosemanticity. Accessed 2026-05-20.
- ^1 ^2 ^3Callum McDougall, Arthur Conmy, Cody Rushing, Thomas McGrath, Neel Nanda, "Copy Suppression: Comprehensively Understanding an Attention Head", arXiv:2310.04625, 2023-10-06. arxiv.org/...2310.04625. Accessed 2026-05-20.
- ^1 ^2Francesco D'Angelo, Francesco Croce, Nicolas Flammarion, "Selective Induction Heads: How Transformers Select Causal Structures In Context", arXiv:2509.08184, 2025-09-09. arxiv.org/...2509.08184. Accessed 2026-05-20.
- ^1 ^2Chanakya Ekbote et al., "What One Cannot, Two Can: Two-Layer Transformers Provably Represent Induction Heads on Any-Order Markov Chains", arXiv:2508.07208, 2025-08-10. arxiv.org/...2508.07208. Accessed 2026-05-20.
- ^1 ^2Aaditya K. Singh et al., "What needs to go right for an induction head? A mechanistic study of in-context learning circuits and their formation", arXiv:2404.07129, 2024-04-10. arxiv.org/...2404.07129. Accessed 2026-05-20.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
6 revisions by 1 contributor · v6 · 5,658 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (95 claims, 17 sources fetched); 8 material + 18 minor fixed
Cite this page: AI Wiki. "Induction Heads." aiwiki.ai, updated 25 Jun 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/induction_heads