

Agent evaluation
Agent evaluation is the systematic measurement of how well AI agents (LLM-based systems that plan and act over multiple steps using tools) perform on real-world tasks, using benchmarks, metrics, and testing methodologies. It has two broad modes: outcome (or task-success) evaluation, which checks whether the agent reached the correct final state, and trajectory (or process) evaluation, which inspects the sequence of reasoning steps and tool calls the agent took to get there. The most common headline metric is the task success rate, scored either by deterministic code-based graders, by an LLM-as-a-judge, or by human reviewers, and the field's defining challenges are reproducibility, cost, partial credit, and reward hacking.[3][4]
As autonomous AI systems have evolved from simple chatbots into multi-step, tool-using agents capable of browsing the web, writing code, and operating computer interfaces, the need for rigorous evaluation frameworks has grown rapidly. Agent evaluation encompasses a broad range of approaches, from standardized academic benchmarks like SWE-bench and WebArena to enterprise-grade observability platforms that track cost, latency, and reliability in production.[1][2]
Unlike traditional language model evaluation, which typically measures performance on static question-answer pairs, agent evaluation must account for multi-turn interactions, tool use, environment manipulation, non-deterministic execution paths, and the compounding effects of errors over long task horizons.[3] The field draws on research in reinforcement learning, human-computer interaction, software engineering, and safety analysis. By May 2026, the discipline has matured into a distinct subfield with dedicated frameworks from frontier labs (Anthropic, OpenAI, Google DeepMind), national institutes (UK AISI, US AISI/CAISI), and independent organizations such as METR and Sierra.[4][5]
Why did agent evaluation become a distinct field?
The evaluation of AI agents has roots in earlier work on reinforcement learning environments such as Atari games and MuJoCo simulations, where agents were measured by cumulative reward. However, the rise of large language models (LLMs) as the backbone of agentic systems introduced new evaluation challenges. Early LLM benchmarks such as MMLU and HellaSwag focused on static knowledge and reasoning, but they could not capture whether a model could effectively use tools, navigate websites, or resolve real software engineering issues.
The first wave of agent-specific benchmarks used simplified or simulated environments. MiniWoB++ (2018) provided a collection of over 100 simplified web tasks for testing basic web manipulation skills. WebShop simulated an e-commerce environment with 1.18 million products and 12,087 crowd-sourced shopping instructions.[6] These early benchmarks demonstrated that LLMs could be evaluated as interactive agents rather than passive text generators, but their synthetic nature limited how well results generalized to real-world settings.
By late 2023 and into 2024, a second wave of more realistic benchmarks appeared. SWE-bench tested agents on real GitHub issues from popular Python repositories.[7] WebArena created self-hosted replicas of real websites for autonomous web navigation.[2] GAIA combined multi-modal reasoning with tool use across multiple difficulty levels.[8] AgentBench evaluated LLMs across eight distinct environments spanning operating systems, databases, knowledge graphs, and web browsing.[1] These benchmarks reflected a growing consensus that agent evaluation must test performance in realistic, multi-step scenarios rather than isolated capabilities.
The third wave, beginning in 2025, has focused on enterprise readiness, safety, and consistency. Benchmarks like CUB (Computer Use Benchmark), τ²-bench, and OSWorld-Verified have introduced domain-specific workflows, repeated-trial consistency metrics, and verified task sets.[9][10] The field has also seen the emergence of comprehensive evaluation frameworks from companies like Anthropic, which published detailed guidance on building agent evaluation pipelines that combine code-based graders, model-based graders, and human review.[4]
What does agent evaluation measure?
A comprehensive survey published in 2025 proposed a two-dimensional taxonomy for agent evaluation, organizing prior work by evaluation objectives (what to evaluate) and evaluation process (how to evaluate).[11]
What to evaluate
Agent evaluation targets four primary objectives:
| Dimension | Description | Example metrics |
|---|---|---|
| Agent behavior | Overall performance as perceived by a user, treating the agent as a black box | Task completion rate, output quality, latency, cost per task |
| Agent capabilities | Specific skills the agent demonstrates | Tool use accuracy, planning quality, memory retention, multi-agent collaboration |
| Reliability | Consistency and robustness across repeated executions and varied conditions | pass^k (all k trials succeed), robustness under input perturbations |
| Safety and alignment | Adherence to policies, avoidance of harm, fairness | Harm rate, policy violation rate, adversarial robustness, bias detection |
How to evaluate
The evaluation process involves several components:
- Interaction mode: Static evaluations present fixed inputs and check outputs, while dynamic evaluations involve multi-turn interactions where the environment changes based on agent actions.
- Evaluation data: Benchmarks range from synthetic task sets (MiniWoB++) to curated real-world datasets (SWE-bench, Mind2Web).
- Metric computation: Three primary approaches are used. Code-based graders apply deterministic rules and test cases, offering objectivity but limited flexibility. LLM-as-a-Judge methods leverage another language model to score subjective criteria. Human-in-the-loop evaluation provides gold-standard assessments but is expensive and slow.[12]
- Evaluation environments: These range from sandboxed simulations to real operating systems and live websites.
- Tooling infrastructure: Platforms like LangSmith, Braintrust, and AgentOps provide tracing, observability, and automated evaluation pipelines.
How do you measure agent success?
Task completion and success rate
The most fundamental metric in agent evaluation is the success rate (SR), also called the task completion rate. It measures the proportion of tasks that an agent completes correctly out of the total number attempted. Success is typically determined by checking whether the agent's actions produce the desired end state, such as a passing test suite in SWE-bench or the correct final webpage configuration in WebArena.[7][2]
Variants of success rate include:
| Metric | Definition | Use case |
|---|---|---|
| Success rate (SR) | Fraction of tasks completed correctly | General benchmark scoring |
| pass@k | Probability that at least one of k independent attempts succeeds | Measuring best-case capability |
| pass^k | Probability that all k independent attempts succeed | Measuring consistency and reliability |
| Partial credit | Graded score reflecting progress toward completion | Multi-step tasks where full success is rare |
| Progress rate | Fraction of subtasks or milestones completed | Long-horizon workflow evaluation |
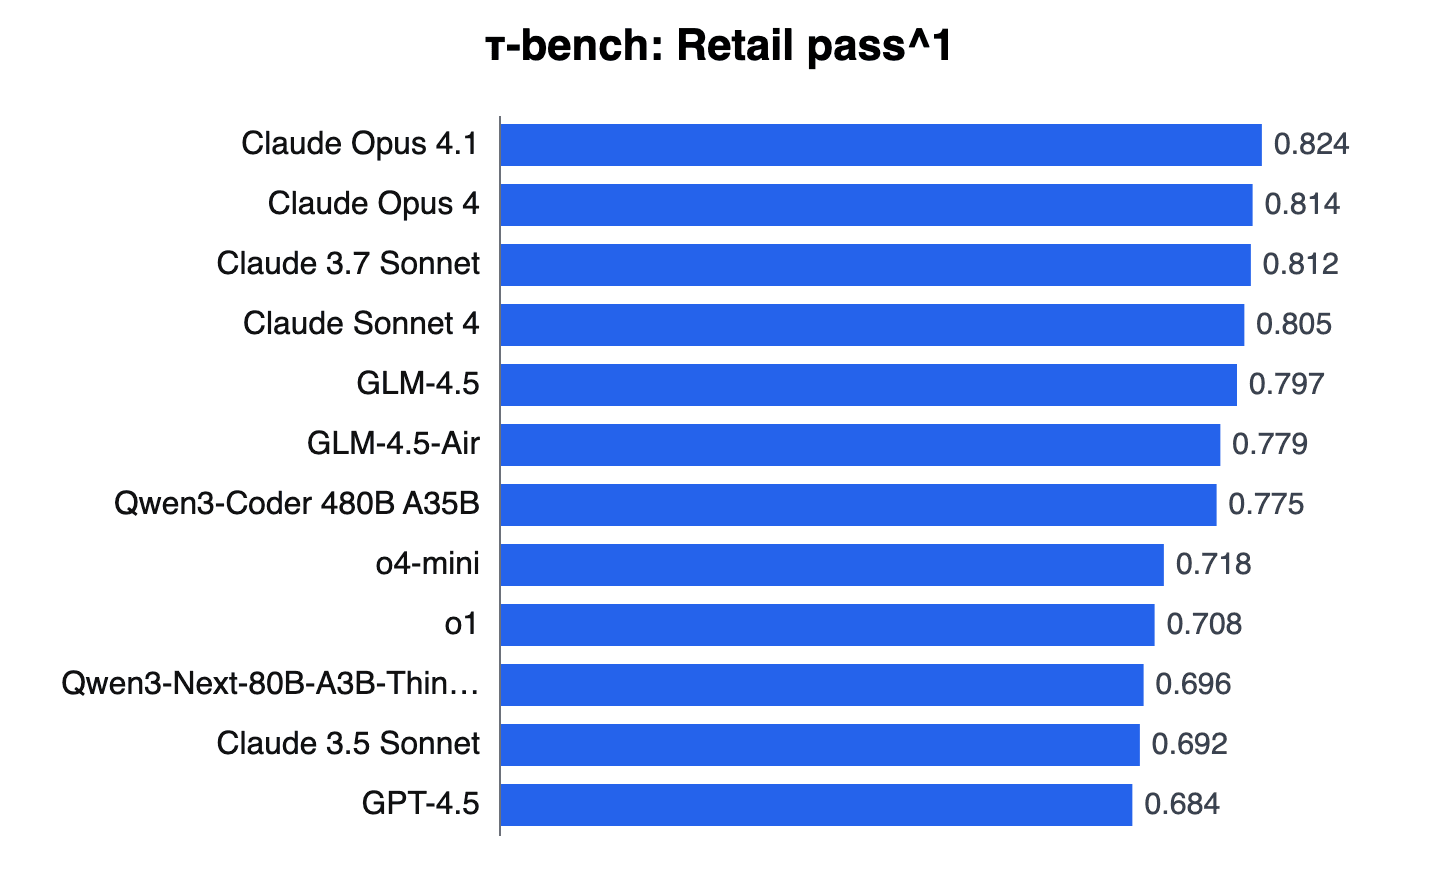
The distinction between pass@k and pass^k is particularly important for agent evaluation. As Anthropic has noted, pass@k approaches 100% as k increases (since the agent only needs to succeed once), while pass^k falls toward 0% (since every attempt must succeed). For production systems where reliability matters, pass^k is often the more relevant metric.[4] Sierra's τ-bench specifically uses pass^k to highlight the inconsistency of current agents: state-of-the-art models that achieve roughly 50% success on individual tasks can drop below 25% on pass^8 in retail customer service scenarios.[13]
Efficiency and cost metrics
As agents move from research prototypes to production systems, efficiency metrics have become essential:
- Token usage: The total number of tokens consumed per task, directly correlated with API costs.
- Latency: Time from task initiation to completion, measured as end-to-end request latency or time-to-first-token for streaming applications.
- Number of steps: How many actions, tool calls, or turns the agent requires to complete a task. Fewer steps generally indicate more efficient reasoning.
- Cost per task: The total monetary cost including API calls, infrastructure, and any human review. An agent achieving 95% task success but requiring 50 API calls per task may be economically unviable.
- Apply rate: Used in SWE-bench, this measures the fraction of generated patches that can be applied to the codebase without errors, regardless of whether they pass tests.
Safety and alignment metrics
Safety evaluation has become a distinct research area as agents gain the ability to take real-world actions:
- Harm rate: The proportion of tasks where the agent produces harmful, toxic, or dangerous outputs.[14]
- Policy compliance: Whether the agent adheres to specified business rules, access controls, and operational constraints.
- Adversarial robustness: Performance under deliberate attempts to manipulate the agent through prompt injection, jailbreaking, or adversarial inputs.[15]
- Risk awareness: The agent's ability to recognize and flag risky situations rather than blindly executing potentially harmful actions, as measured by benchmarks like R-Judge.[16]
Tool use metrics
For agents that interact with external tools and APIs:
- Tool selection accuracy: Whether the agent chooses the correct tool for a given subtask.
- Invocation accuracy: Whether tool calls include correct parameters and formatting.
- Parameter F1: The precision and recall of parameter values in tool calls compared to ground truth.
- Abstention rate: Whether the agent correctly declines to use a tool when no appropriate tool is available.[17]
What are the main agent benchmarks?
The most widely cited agent benchmarks each target a different environment: SWE-bench (2,294 real GitHub issues across 12 Python repositories) for software engineering, WebArena (812 tasks on self-hosted website replicas) for web navigation, GAIA (466 multi-step assistant questions) for general tool use, AgentBench (eight environments) for multi-domain capability, τ-bench for customer-service consistency, and OSWorld (369 desktop tasks across Ubuntu, Windows, and macOS) for computer use.[7][2][8][1][13][10] The sections below detail each, grouped by environment.
Software engineering benchmarks
SWE-bench
SWE-bench is one of the most widely cited agent benchmarks. Introduced by researchers at Princeton University in 2023, it evaluates AI coding agents on their ability to resolve real GitHub issues from 12 popular open-source Python repositories. The original dataset contains 2,294 issue-patch pairs, each requiring the agent to understand the issue description, locate relevant code, and generate a patch that passes the repository's test suite. The authors framed the goal directly in the paper's title, asking "Can Language Models Resolve Real-World GitHub Issues?", and reported that "the best-performing model, Claude 2, is able to solve a mere 1.96% of the issues" at release.[7]
SWE-bench has spawned several variants:
| Variant | Tasks | Description |
|---|---|---|
| SWE-bench (full) | 2,294 | Original dataset of Python GitHub issues |
| SWE-bench Verified | 500 | Hand-filtered subset validated for test harness correctness |
| SWE-bench Lite | 300 | Smaller subset for faster evaluation |
| SWE-bench++ | 11,100+ | Multi-language extension covering 11 programming languages |
| SWE-bench Live | Ongoing | Continuously updated with new issues to prevent data contamination |
| SWE-bench Pro | 1,865 | More challenging tasks requiring extended reasoning |
| SWE-bench Multimodal | 617 | JavaScript tasks that include visual inputs (screenshots, mockups) |
| SWE-bench Java Verified | 91 | First non-Python variant with Dockerized build/test harnesses |
By 2026, leading scores on SWE-bench Verified have effectively saturated. Anthropic reported 93.9% for the restricted-access Claude Mythos Preview in April 2026.[60] On Vals AI's independent leaderboard, which runs every model through the same mini-SWE-agent harness, the top score in May 2026 was 82.6% (GPT-5.5), ahead of Claude Opus 4.7 at 82.0% and GPT-5.3 Codex at 78.0%; as of September 2026, Claude Opus 5 led at 97.0%.[18] OpenAI stopped reporting Verified scores in February 2026 after an audit found that every frontier model it tested, including GPT-5.2, Claude Opus 4.5, and Gemini 3 Flash, could reproduce gold patches or verbatim problem-statement details for some Verified tasks, indicating data contamination; it recommended SWE-bench Pro instead.[59] The harder SWE-bench Pro still separates models more: Anthropic reported 77.8% on Pro for Claude Mythos Preview, against 93.9% on Verified.[60][19]
SWE-bench Live, released as a NeurIPS 2025 dataset paper by Microsoft Research, addresses contamination by adding 50 freshly verified, high-quality issues every month from public GitHub projects with creation dates after January 1, 2024.[20]
SWE-bench Multimodal, presented at ICLR 2025, extends the original benchmark to 617 JavaScript tasks drawn from 17 libraries used for diagramming, data visualization, syntax highlighting, and interactive mapping. Each instance includes at least one image (screenshot, UI mockup, or diagram), making it a test of cross-modal reasoning. When released, SWE-agent resolved only 12% of tasks, with the next best system at 6%.[21]
LiveCodeBench and InterCode
LiveCodeBench provides a continuously refreshed set of coding problems sourced from competitive programming platforms, addressing contamination concerns. InterCode tests agents on interactive coding tasks that require iterative debugging and execution within a sandboxed environment.
MLE-bench
MLE-bench, released by OpenAI in October 2024, evaluates agents on machine learning engineering work using 75 curated Kaggle competitions. Tasks span dataset preparation, model training, hyperparameter tuning, and experiment management. Human baselines are derived from the public Kaggle leaderboards. In the original paper, the best open-source agent scaffold (AIDE with OpenAI o1-preview) earned at least a bronze medal in 16.9% of competitions.[22]
Web agent benchmarks
WebArena
WebArena, introduced in 2023, provides a self-hosted environment for evaluating autonomous web browsing agents. It includes fully functional websites from four common domains (e-commerce, social forums, collaborative software development, and content management), plus tools such as a map and knowledge resources such as user manuals. The benchmark comprises 812 templated tasks instantiated from 241 templates, with an average of 3.3 variations per template.[2]
WebArena measures functional correctness, meaning whether agents achieve the intended final goal regardless of the specific path taken. Human performance on WebArena reaches 78.24%. AI agent performance has improved substantially since the benchmark's release: the original GPT-4 based agent achieved only 14.41% success, while by early 2025 IBM's CUGA (Computer Using Generalist Agent) reported a then state-of-the-art 61.7%, and in February 2026 Ant Group's OpAgent framework reported 71.6%.[2][24][64]
Extensions to WebArena include WebChoreArena, which adds 532 tasks focused on tedious, long-horizon workflows requiring extensive memory and calculation, and WebArena Verified, a 2025 audit project that revised all 812 tasks for offline, stack-agnostic evaluation with a 258-task "Hard" subset for fast focused runs.
MiniWoB++
MiniWoB++ (Mini World of Bits) is a collection of over 100 web interaction environments with simplified, synthetic web pages. Maintained by the Farama Foundation, it follows the Gymnasium API and uses Selenium WebDriver for browser interaction. Tasks include clicking buttons, filling forms, navigating dropdowns, and other basic web manipulation skills. While MiniWoB++ lacks the realism of later benchmarks, it remains valuable as a training ground and lightweight evaluation environment for early-stage agent development.
Mind2Web
Mind2Web, introduced at NeurIPS 2023 by the NLP group at Ohio State University, contains 2,350 tasks spanning 137 real websites across 31 domains. Unlike benchmarks that use simulated websites, Mind2Web evaluates agents on actual web pages collected from top-ranked sites. The benchmark tests three levels of generalization: cross-task (different tasks on the same website), cross-website (similar tasks on different websites in the same domain), and cross-domain (tasks on websites in entirely different domains). In the original paper, whole-task success was low: the best MindAct configuration (fine-tuned Flan-T5-Large) completed 7.1% of cross-task test tasks end to end, and MindAct with GPT-4, evaluated on a 50-task subset, reached a 36.2% step success rate but only 2.0% task success.[25]
VisualWebArena
VisualWebArena, presented at ACL 2024, contains 910 tasks across three web apps (a classifieds site, a shopping site, and a forum) that explicitly require visual understanding of images and spatial reasoning, not just navigation. Easy tasks involve basic visual identification, such as recognizing the presence of a cat in an image. In the original paper the best agent (GPT-4V with Set-of-Marks prompting) reached 16.4%, against human performance of 88.7%.[26]
BrowseComp
BrowseComp, released by OpenAI in April 2025, is an open-source benchmark of 1,266 challenging problems that require persistently navigating many websites to retrieve "entangled" information. All questions have a single, short, indisputable answer that does not change over time, which makes grading straightforward. GPT-4o without browsing scored near zero, while OpenAI's Deep Research agent solved roughly half of the problems.[27] A 2025 follow-up, BrowseComp-Plus, replaces the live web with a fixed, human-verified document corpus, removing the variability of opaque search APIs and enabling reproducible, component-focused evaluation of retrieval pipelines. On BrowseComp-Plus, GPT-5 paired with the Qwen3-Embedding-8B retriever achieves 70.1% accuracy versus 3.86% for the open-source Search-R1 model paired with a BM25 retriever.[28]
Operating system and desktop benchmarks
OSWorld
OSWorld, presented at NeurIPS 2024, is the first benchmark to evaluate multimodal agents on open-ended tasks within real computer environments. It includes 369 tasks involving real desktop applications across Ubuntu, Windows, and macOS, spanning tools like Chromium, GIMP, LibreOffice, Thunderbird, VLC, and Visual Studio Code. Tasks cover web browsing, desktop application use, OS file operations, and multi-application workflows.[10]
Human evaluators complete approximately 72.4% of OSWorld tasks. When the benchmark launched, the best AI agent achieved only 12.2% success. By December 2025, performance had improved dramatically: Simular reported that its Agent S3 framework, combined with Behavior Best-of-N selection across multiple runs, reached 72.6%, just above the human baseline.
OSWorld-Verified, released by the XLANG Lab in July 2025, is an in-place upgrade with refined task quality and infrastructure improvements: the environment was migrated from VMware/Docker to AWS with 50x parallelization, ambiguous tasks were rewritten, and several flaky web dependencies were stabilized.[9] By May 2026, Claude Mythos Preview led the OSWorld-Verified leaderboard at 79.6%, followed by GPT-5.5 at 78.7% and Claude Opus 4.7 at 78.0%, all exceeding the human baseline. As of October 29, 2026, BenchLM's aggregation of reported results listed Qwen3.8 Max at 86.1%, ahead of Claude Fable 5 and Claude Mythos 5 at 85%.[29]
OSUniverse and OSWorld-Human
Released in 2025, OSUniverse introduces graduated difficulty levels, automated validation with low error rates, and graph-based evaluation that awards partial credit for multi-step workflows. It supports multiple operating systems and uses Docker containers for simplified setup, making it more modular and accessible than OSWorld. OSWorld-Human (2025) supplements OSWorld with measurements of human action counts and time, enabling efficiency comparisons in addition to raw success.
Windows Agent Arena
Windows Agent Arena, introduced in late 2024 by Microsoft Research, is a reproducible Azure-hosted environment focused exclusively on Windows OS tasks, with custom execution-based evaluation scripts for each task. It complements OSWorld by giving Windows-specific tasks first-class treatment.
General assistant and reasoning benchmarks
GAIA
GAIA (General AI Assistants) was introduced in late 2023 by researchers from Meta AI, Hugging Face, and AutoGPT. It presents 466 human-annotated tasks requiring multi-step reasoning, tool use, web browsing, and multimodal interpretation. The GAIA paper framed the difficulty in stark human-versus-machine terms: "we show that human respondents obtain 92% vs. 15% for GPT-4 equipped with plugins", a gap the authors describe as conceptually simple for humans yet challenging for advanced AI.[8] Tasks are structured across three difficulty levels:[8]
| Level | Description | Typical requirements |
|---|---|---|
| Level 1 | Simple tasks | Single tool, basic reasoning |
| Level 2 | Intermediate tasks | Multiple tools, multi-step planning |
| Level 3 | Complex tasks | Extensive planning, numerous tools, advanced reasoning |
GAIA tasks have unambiguous, verifiable answers, making automated evaluation straightforward. The benchmark's official leaderboard is hosted on Hugging Face. In February 2025, OpenAI reported that Deep Research set a new state of the art on the validation set, with 67.36% accuracy at pass@1 and 72.57% with consensus voting over 64 samples (cons@64).[30] Scores then rose quickly: on the Hugging Face test-set leaderboard the top entry passed 90% in December 2025 and reached 94.35% in November 2026, with Level 3 still the hardest tier.[65]
AgentBench
AgentBench, published at ICLR 2024, evaluates LLMs as agents across eight distinct environments spanning three categories:[1]
| Category | Environments |
|---|---|
| Code-grounded | Operating system (OS), database (DB), knowledge graph (KG) |
| Game-grounded | Digital card game, lateral thinking puzzles |
| Web-grounded | House-holding, web shopping, web browsing (Mind2Web) |
The benchmark tested 29 LLMs and revealed a significant performance gap between commercial models (like GPT-4) and open-source alternatives. Key findings indicated that poor long-term reasoning, weak decision-making, and limited instruction-following ability were the primary obstacles to building effective LLM agents.
AgentBoard
AgentBoard, an oral presentation at NeurIPS 2024, introduced a fine-grained progress-rate metric that captures incremental advancement on partially observable, multi-turn tasks. The framework spans 9 distinct tasks covering embodied, web, tool use, and game environments, and ships with an interactive visualization toolkit for inspecting trajectories step-by-step rather than only checking final-state success.[31]
Function calling and tool use benchmarks
Berkeley Function-Calling Leaderboard (BFCL)
The BFCL, developed by UC Berkeley's Gorilla project, has become the standard benchmark for evaluating LLM function-calling capabilities. Now in version 4 (as of 2025), it evaluates models on serial and parallel function calls across Python, Java, JavaScript, and REST APIs using a novel Abstract Syntax Tree (AST) evaluation method.[17]
BFCL v4 added categories for web search, memory management, and format sensitivity, building on the multi-turn interactions introduced in v3. The benchmark assesses models on their ability to select correct functions, structure arguments properly, handle multiple parallel calls, and abstain when no appropriate function is available. Leading scores as of 2025 place Anthropic's Claude models and OpenAI's GPT models near the top, with overall accuracy scores ranging from roughly 59% to 70%.
ToolLLM and ToolBench
ToolLLM, presented at ICLR 2024, provides a comprehensive framework for training and evaluating LLMs on tool use. Its associated dataset, ToolBench, contains 16,464 RESTful APIs spanning 49 categories from RapidAPI Hub, along with 126,000+ instruction-solution path pairs. The benchmark evaluates agents on both single-tool and multi-tool scenarios, using a depth-first search based decision tree (DFSDT) approach to generate solution paths.[32]
The automated evaluator, ToolEval, measures both pass rate (whether the tool chain produces correct output) and solution path quality (whether the agent's reasoning process is sound). StableToolBench, a subsequent variant, addressed reproducibility concerns in the original benchmark.
AppWorld
AppWorld, awarded Best Resource Paper at ACL 2024, is an execution environment of 9 day-to-day apps operable via 457 APIs, populated with the simulated digital lives of roughly 100 people. The benchmark includes 750 natural agent tasks evaluated by state-based unit tests that check both task success and the absence of "collateral damage" (unintended state changes). GPT-4o solved approximately 49% of "normal" tasks and 30% of "challenge" tasks.[33]
Customer service and enterprise benchmarks
tau-bench and tau2-bench
τ-bench, developed by Sierra, is a simulation framework for evaluating customer service agents. It emulates multi-turn conversations between a simulated user (powered by an LLM) and an agent equipped with domain-specific API tools and policy guidelines. The benchmark covers realistic domains including airline customer service and retail support; a telecom domain was added later in τ²-bench.[13][34]
What distinguishes τ-bench from other benchmarks is its emphasis on consistency. Rather than measuring whether an agent can complete a task once, it uses pass^k to assess whether the agent succeeds across multiple independent trials. State-of-the-art models like GPT-4o achieve less than 50% success on individual tasks, and their consistency drops below 25% on pass^8 in retail scenarios. The benchmark expanded through τ²-bench (released June 2025) which introduced dual-control environments where both the user and the agent can take actions in a shared state, and τ³-bench, which adds knowledge retrieval and voice interactions. In the τ²-bench paper, Claude 3.7 Sonnet reached a pass^1 of 49% on the new telecom domain, while GPT-4.1 fell from 74% (retail) and 56% (airline) to 34% on telecom, and agents lost performance when moving from no-user to dual-control settings.[34]
TheAgentCompany
TheAgentCompany, developed at Carnegie Mellon University and posted to arXiv in December 2024, evaluates LLM agents on 175 diverse tasks situated inside a simulated software company. The environment includes a self-hosted GitLab, a self-hosted Plane (issue tracker), Rocket.Chat for communication, ownCloud for files, and simulated colleagues with which the agent must coordinate. The strongest agent, built on Gemini 2.5 Pro, completed 30.3% of tasks fully autonomously and scored 39.3% with partial credit (Claude 3.7 Sonnet followed at 26.3%), while open-weights models lagged at 7.4% or below. The benchmark paints a sobering picture of long-horizon workplace automation: a substantial share of consequential tasks remain out of reach.[35]
CUB (Computer Use Benchmark)
CUB, introduced by Theta Software in mid-2025, is a benchmark specifically designed for computer-use agents. It contains 106 end-to-end workflows across seven industries: consumer, construction, finance, healthcare, marketing, sales, and supply chain. Tasks were created in collaboration with domain experts (accountants, investment bankers, doctors) and involve synthetic versions of enterprise platforms like SAP and CapIQ.
CUB is particularly challenging because it requires graphical user interface interactions (clicking buttons, selecting menu items) in addition to typing or API calls. When first released, no tested agent framework exceeded 10% success, even with a granular scoring system that awarded partial credit.
GDPval
GDPval, released by OpenAI in September 2025, evaluates models on 1,320 specialized work tasks drawn from 44 occupations across the top nine sectors of the U.S. economy. Tasks include legal briefs, engineering blueprints, customer support conversations, and nursing care plans, and were created by professionals averaging 14 years of experience. The primary grading method is blind head-to-head human comparison between AI and expert deliverables. In the launch paper, the strongest model (Claude Opus 4.1) matched or beat the expert deliverable on 47.6% of gold-subset tasks; OpenAI later reported 84.9% (wins or ties) for GPT-5.5 in April 2026.[36][61]
Cybersecurity benchmarks
Cybench
Cybench, accepted as an ICLR 2025 oral, is a framework that packages 40 professional-level Capture-the-Flag (CTF) tasks from four recent competitions, broken down into subtasks for finer-grained evaluation. Agents are given a shell, the relevant starter files, and an environment in which they can execute commands. In the original paper, agents based on Claude 3.5 Sonnet, GPT-4o, OpenAI o1-preview, and Claude 3 Opus solved unguided tasks that took human red teams up to 11 minutes, but no agent could solve the hardest task in the suite (which took human teams nearly 25 hours).[37]
By 2026 these results had shifted dramatically. In May 2026 the UK AI Security Institute reported that a newer checkpoint of Claude Mythos Preview was the first model to complete both of its cyber ranges, the 32-step corporate-network simulation "The Last Ones" and the 7-step industrial-control simulation "Cooling Tower".[56][38] AISI also reported that it had estimated in February 2026 that the length of cyber tasks frontier models could complete at 80% reliability had been doubling about every 4.7 months since late 2024, and that Mythos Preview and GPT-5.5 had since exceeded that trend.[56]
CAIBench
CAIBench, posted to arXiv in late 2025, is a modular cybersecurity meta-benchmark that aggregates Jeopardy-style CTFs, attack-and-defense CTFs, cyber-range exercises, knowledge questions, and privacy assessments over 10,000+ instances. It is designed to test both offensive and defensive cyber capabilities in a single framework.[39]
Safety benchmarks
AgentHarm
AgentHarm, published at ICLR 2025, contains 110 explicitly malicious agent tasks (440 with augmentations) covering 11 harm categories including fraud, cybercrime, and harassment. The benchmark measures both whether models refuse harmful requests and whether jailbroken agents maintain their capabilities when attempting to complete multi-step harmful tasks. Findings included that several leading LLMs were surprisingly compliant with malicious agentic requests without jailbreaking, and that simple universal jailbreak templates could be adapted to coherent multi-step harmful agent behavior.[14]
R-Judge
R-Judge, published in Findings of EMNLP 2024, evaluates the safety risk awareness of LLM agents. It contains 569 records of multi-turn agent interactions covering 27 risk scenarios across 5 application categories and 10 risk types. Rather than testing whether agents cause harm directly, R-Judge assesses whether models can identify and flag safety risks in agent interaction records.[16]
ToolEmu
ToolEmu takes a different approach to safety evaluation by using an LLM to emulate tool execution and grade accidental safety violations. It covers 36 tools and 144 test cases in high-stakes scenarios where the user's intent is benign but the agent's actions could inadvertently cause harm. This sandbox-based approach allows safety evaluation without requiring actual tool infrastructure.[15]
AILuminate
AILuminate v1.0, from MLCommons (described in a February 2025 technical paper), is a 24,000-prompt safety benchmark that covers 12 hazard categories: violent crimes, nonviolent crimes, sex-related crimes, child sexual exploitation, indiscriminate weapons, suicide and self-harm, intellectual property, privacy, defamation, hate, sexual content, and specialized advice (election, financial, health, legal). It uses a tuned ensemble of safety evaluation models as graders and v1.0 launched with English prompts, with French, Simplified Chinese, and Hindi versions planned. AILuminate represents one of the first cross-industry attempts to establish a shared safety reporting standard for general-purpose chat systems.[40]
AdvBench and HarmBench
AdvBench is a widely used dataset of roughly 520 adversarial prompts that target categories like misinformation, illegal activity, and hate speech, frequently paired with the Greedy Coordinate Gradient (GCG) attack. HarmBench, presented at ICML 2024, extends adversarial evaluation to 510 unique harmful behaviors (text, contextual, and multimodal) with a standardized scoring pipeline. The HarmBench paper systematically compared 18 red-teaming methods against 33 LLMs and defenses, finding that no attack or defense was uniformly effective and that model size did not predict robustness.[41]
JailbreakBench
JailbreakBench, a NeurIPS 2024 Datasets and Benchmarks paper, is an open robustness benchmark for jailbreaking LLMs. Its JBB-Behaviors dataset contains 100 distinct misuse behaviors (55% original, 45% sourced from AdvBench and TDC/HarmBench) split into ten categories matching OpenAI's usage policies. JailbreakBench tracks both attack success rate and defense effectiveness across an open leaderboard.[42]
Cross-environment and mobile benchmarks
CRAB (Cross-environment Agent Benchmark)
CRAB, released in late 2024 by Camel-AI, evaluates agents across 120 tasks spanning Ubuntu and Android environments. It introduces graph-based fine-grained scoring with partial credit capability. The best model (GPT-4o) achieved only 14.17% completion ratio, highlighting the difficulty of cross-environment task completion.
Vibe-Eval
Vibe-Eval, released by Reka in 2024, is an open multimodal chat benchmark with 269 visual understanding prompts (100 marked "hard"), each with a gold-standard expert response. The hard set is constructed so that more than 50% of questions are answered incorrectly by every then-frontier model, providing headroom for years of progress.[43]
How do the major agent benchmarks compare?
| Benchmark | Year | Domain | Tasks | Environment | Key metric | Human baseline | Best AI (approx.) |
|---|---|---|---|---|---|---|---|
| MiniWoB++ | 2018 | Web (synthetic) | 100+ | Synthetic web pages | Task success rate | Near 100% | 95%+ |
| WebArena | 2023 | Web (realistic) | 812 | Self-hosted websites | Functional correctness | 78% | 71.6% (OpAgent, 2026) |
| Mind2Web | 2023 | Web (real) | 2,350 | Real websites | Task success / step success | N/A | 7.1% task SR (2023 paper) |
| SWE-bench Verified | 2023 | Software engineering | 500 | Real GitHub repos | pass@1 | N/A | 97.0% (Vals AI, Sept 2026; saturated, contaminated) |
| SWE-bench Pro | 2025 | Software engineering | 1,865 | Real GitHub repos | pass@1 | N/A | 77.8% (Mythos Preview, self-reported) |
| GAIA | 2023 | General assistant | 466 | Multi-modal, multi-tool | Accuracy | 92% | 94.35% (test set, Nov 2026) |
| AgentBench | 2023 | Multi-domain (8 envs) | Varies | Simulated environments | Overall score | N/A | Varies by env |
| ToolBench | 2023 | API/tool use | 16,464 APIs | Real APIs via RapidAPI | Pass rate | N/A | Varies |
| VisualWebArena | 2024 | Visual web | 910 | Self-hosted multimodal sites | Success rate | 89% | 16.4% (2024 paper) |
| AppWorld | 2024 | Apps and APIs | 750 | 9 simulated apps, 457 APIs | State-based unit tests | N/A | 49% normal |
| OSWorld | 2024 | Desktop OS | 369 | Real VMs (Ubuntu/Win/Mac) | Task success rate | 72.4% | 86.1% (OSWorld-Verified, Oct 2026) |
| BFCL v4 | 2024 | Function calling | 2,000+ | API simulation | Overall accuracy | N/A | ~70% |
| τ-bench | 2024 | Customer service | Multiple domains | Simulated conversations | pass^k | N/A | <50% (SR, 2024 paper) |
| MLE-bench | 2024 | ML engineering | 75 Kaggle | Real ML pipelines | Medal rate | Strong Kaggler | 16.9% bronze (2024 paper) |
| Cybench | 2024 | Cybersecurity | 40 CTFs | Sandboxed shells | Subtask completion | Expert teams | Saturating |
| TheAgentCompany | 2024 | Workplace tasks | 175 | Simulated company | Task success / partial | Full-time employee | 30% |
| BrowseComp | 2025 | Deep research | 1,266 | Live web | Exact-match accuracy | N/A | ~50% (Deep Research) |
| CUB | 2025 | Enterprise workflows | 106 | Synthetic enterprise platforms | Task success rate | N/A | <10% |
| AILuminate v1.0 | 2025 | Safety | 24,000 prompts | Static chat | Hazard category scores | N/A | N/A |
| GDPval | 2025 | Economic work | 1,320 | Real deliverables | Blind expert comparison | Expert quality | 84.9% (GPT-5.5, self-reported) |
| BrowseComp-Plus | 2025 | Deep research | Curated corpus | Fixed document corpus | Exact-match accuracy | N/A | 70.1% (GPT-5) |
Outcome vs trajectory: how is agent performance graded?
Outcome-based evaluation
The most common approach evaluates agents based on final outcomes. In SWE-bench, this means checking whether the generated patch passes the test suite. In WebArena, it means verifying whether the web page reached the desired state. Outcome-based evaluation is attractive because it is objective and mirrors what end users care about, but it can miss important failure modes. An agent might produce the correct result through unsafe or inefficient means, or it might fail on a task for reasons unrelated to its core capabilities (such as a flaky test or ambiguous task specification).
Process-based evaluation
Process-based (or trajectory-based) evaluation examines the steps an agent takes rather than just its final output. This includes analyzing tool call sequences, reasoning traces, and intermediate decisions. Metrics like Node F1 (for tool selection accuracy) and Edge F1 (for sequence accuracy) measure how well an agent's decision process aligns with reference trajectories.
Process evaluation is valuable for diagnosing failure modes and understanding agent behavior, but it risks penalizing valid alternative approaches. As Anthropic has emphasized, "grading what the agent produced, not the path it took" prevents unnecessarily punishing creative solutions.[4]
Side-effect evaluation
A growing area of methodology focuses on the side effects an agent leaves behind, not just whether the task itself was completed. AppWorld's state-based unit tests, for example, check both task success and the absence of unintended state changes ("collateral damage").[33] Similar approaches snapshot the sandbox before and after an agent run and diff the file system, database state, or browser DOM, scoring the agent on the precision of its actions. Side-effect evaluation is especially relevant for computer-use agents and enterprise agents that can mutate persistent state.
LLM-as-a-Judge
Using a separate large language model to evaluate agent outputs has become widespread, particularly for tasks where success is subjective or difficult to verify programmatically. The judge model receives the agent's transcript (including actions, tool calls, and outputs) along with a scoring rubric, and assigns scores based on quality criteria. The approach was popularized by Zheng et al.'s 2023 paper "Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena", which reported that "strong LLM judges like GPT-4 can match both controlled and crowdsourced human preferences well, achieving over 80% agreement, the same level of agreement between humans".[12]
The same paper documented three persistent failure modes that still shape LLM-as-judge practice today: position bias (judges favor whichever answer is shown first or last), verbosity bias (judges prefer longer answers regardless of correctness), and self-enhancement bias (judges favor outputs from the same model family). Pairwise judging with position swapping, length normalization, and using a different judge family from the system under test are the standard mitigations.[12]
A more advanced variant, Agent-as-a-Judge, uses a multi-agent setup where evaluator agents can themselves use tools and take actions to verify the primary agent's work. Mind2Web 2 introduced this approach for evaluating agentic search, where the evaluator agent actively checks whether retrieved information is correct and complete.
LLM-as-a-Judge approaches offer flexibility and can handle nuanced evaluation criteria, but they require careful calibration against human judgments and can introduce their own biases.
Pairwise vs absolute scoring
Two broad scoring paradigms exist for subjective evaluation. Absolute scoring asks a grader to assign a numerical score to each response on a Likert scale (often 1 to 5 or 1 to 10). Pairwise scoring presents two outputs side by side and asks the grader to pick the better one. Pairwise judging is generally more reliable for LLM judges because it sidesteps the calibration problem (judges anchor inconsistently on absolute scales) but it is more expensive at scale because the number of comparisons grows quadratically with the number of systems. Chatbot Arena's Elo-style aggregation and GDPval's blind head-to-head expert comparison are pairwise schemes; OpenAI Evals and most product-grade graders default to absolute scoring.[12][36]
Human evaluation
Human evaluation remains the gold standard for open-ended tasks and subjective quality assessments. Human evaluators review agent transcripts and rate performance on criteria like helpfulness, accuracy, safety, and efficiency. While expensive and slow, human evaluation serves as the ground truth for calibrating automated evaluation methods.
BrowserArena uses human judges for head-to-head agent comparisons on user-submitted tasks, providing a reference-free evaluation approach that does not require predefined ground-truth answers.
Multi-trial evaluation
Given the non-deterministic nature of LLM-based agents, running a single trial per task provides an unreliable estimate of performance. Multi-trial evaluation runs each task multiple times and reports aggregate statistics. The pass@k and pass^k metrics capture different aspects of multi-trial performance, and Anthropic recommends running multiple trials per task to get more consistent results.[4]
What tools and platforms run agent evaluations?
Academic and open-source frameworks
BrowserGym is a universal simulation environment developed by ServiceNow that unifies web-based benchmarks including MiniWoB++, WebArena, VisualWebArena, and WorkArena under a single Gymnasium-style API. It provides standardized observation and action spaces (HTML, accessibility tree, screenshot, set-of-mark), making it easier to compare agents across different web benchmarks. The companion AgentLab framework adds agent construction and analysis tools on top.[23][44]
Inspect is an open-source evaluation framework from the UK AI Security Institute (UK AISI) and Meridian Labs that supports a wide range of agent benchmarks including GAIA, BFCL, AgentHarm, SWE-bench, GDM CTF, and Cybench. It provides composable evaluation pipelines with support for multiple solvers and scorers, built-in tools (bash, Python, text editing, web search, web browsing, computer use), MCP and custom tool calling, and multi-agent primitives. As of 2025-2026, Inspect ships with more than 200 pre-built evaluations through the Inspect Evals repository.[45][46]
Inspect Sandboxing Toolkit is a 2025 AISI extension to Inspect that bundles plugins for spinning up secure containerized environments for evaluation runs, including Docker, Kubernetes, and isolated VM backends. Inspect Cyber, also from AISI, is a standardized framework specifically for agentic cyber evaluations, with a consistent two-file task configuration (one file for the evaluation, one for its infrastructure).[47][48]
Inspect Evals is the open-source community repository for the framework, launched in November 2024 in collaboration with Arcadia Impact and the Vector Institute; by then more than 50 contributors, including other AI safety institutes and frontier labs, had contributed to the Inspect framework itself.[46]
AgentBench Toolkit provides an integrated evaluation package supporting all eight AgentBench environments, with standardized APIs for running evaluations and collecting results.
Petri (Parallel Exploration Tool for Risky Interactions) is an open-source automated alignment auditing framework released by Anthropic in October 2025. Petri deploys an auditor agent that runs multi-turn conversations with a target model through simulated users and tools, then uses a judge model to score and summarize the transcripts. Applied to 14 frontier models with 111 seed instructions, Petri elicited a broad set of misaligned behaviors including autonomous deception, oversight subversion, whistleblowing, and cooperation with human misuse. Petri 2.0, released in January 2026, added realism mitigations against evaluation awareness and 70 new seed scenarios.[63]
Commercial platforms
Several commercial platforms offer agent evaluation and observability capabilities:
| Platform | Key features |
|---|---|
| LangSmith | Native LangChain integration, automatic tracing, minimal performance overhead |
| Braintrust | Unified evaluation/observability/optimization, AI-generated custom scorers |
| AgentOps | Session tracking, LLM call tracing, tool use monitoring, cost tracking |
| Langfuse | Open-source tracing and analytics, prompt management |
| Galileo | Agent metric dashboards, automated evaluation pipelines |
| Arize Phoenix | Open-source observability, online and offline evals, span-level tracing |
| Promptfoo | CLI and library for declarative evals, CI/CD integration, red-teaming and vulnerability scanning |
These platforms complement academic benchmarks by providing production-oriented evaluation capabilities including real-time monitoring, A/B testing, and trace-level debugging. Promptfoo, originally an independent open-source project, was acquired by OpenAI, which announced the deal in March 2026 and said it would keep building the open-source offering; it continues as an MIT-licensed CLI with support for multiple model providers.[62][50]
OpenAI's OpenAI Evals is an MIT-licensed Python framework with a registry of public benchmarks and a Completion Function Protocol for evaluating prompt chains and tool-using agents. The framework has since been complemented by an OpenAI Evals API and a Dashboard-hosted workflow for running, grading, and tuning evals as part of an iterative product loop.[51]
What makes agent evaluation so hard?
Reproducibility
Agent evaluation faces significant reproducibility challenges. LLM-based agents exhibit variability in execution paths, tool selection, and reasoning patterns due to non-deterministic sampling. This means that the same agent can produce different results on the same task across different runs. Long-horizon tasks amplify this problem because errors compound over multiple steps. Without standardized protocols for controlling randomness and reporting variance, benchmark results can be misleading.
Environment reproducibility is also a concern. Web-based benchmarks depend on external services that may change over time, and desktop benchmarks require specific virtual machine configurations. OSWorld-Verified and StableToolBench have addressed some of these issues by improving infrastructure reliability and standardizing evaluation environments.[9]
Data contamination
As LLMs are trained on increasingly large corpora of internet text, the risk of benchmark data appearing in training sets grows. This data contamination can inflate benchmark scores without reflecting genuine capability improvements. OpenAI publicly acknowledged this issue by stopping SWE-bench Verified reporting after finding contamination across frontier models, recommending SWE-bench Pro (which draws its public tasks from copyleft-licensed repositories and keeps its commercial set private) instead.[59][19]
Several strategies have been developed to combat contamination. SWE-bench Live provides a continuously updated stream of 50 new issues per month from public GitHub projects dated after January 2024.[20] LiveCodeBench refreshes its problem set regularly. SWE-bench Pro uses legal and architectural barriers, such as copyleft licenses and private commercial repositories, to deter inclusion in training corpora, while BrowseComp-Plus fixes the document corpus so that results do not depend on the live web.[19][28] Some benchmarks create fully synthetic tasks designed to fall outside internet-scale training corpora.
Cost and scalability
Running comprehensive agent evaluations is expensive. Each task may require multiple API calls, tool executions, and environment setups. Multi-trial evaluation (necessary for reliable results) multiplies these costs further. OSWorld evaluation, for example, requires provisioning and managing virtual machines for each task. SWE-bench requires building and running test suites for real software projects.
Failed attempts still incur costs, making reliability economically critical. An agent that requires many retries to succeed may be technically capable but financially impractical. Developing cost-bounded evaluation protocols that balance thoroughness with efficiency remains an active research challenge.
Task specification ambiguity
Defining clear, unambiguous success criteria for agent tasks is difficult. Anthropic reported in 2026 that low scores on capable models can reflect evaluation bugs rather than model limitations: Claude Opus 4.5 initially scored 42% on CORE-Bench until an Anthropic researcher found rigid grading that penalized "96.12" when expecting "96.124991...", ambiguous task specifications, and stochastic tasks that were impossible to reproduce exactly; after the fixes and a less constrained scaffold, its score rose to 95%.[4] The recommended mitigation is that two domain experts should be able to independently reach the same pass/fail verdict on every task.
Generalization
Most benchmarks test agents on a fixed set of tasks within specific domains. How well performance on these tasks predicts real-world capability remains an open question. Mind2Web explicitly tests three levels of generalization (cross-task, cross-website, cross-domain), but most benchmarks do not systematically evaluate generalization. An agent that achieves high scores on SWE-bench Python tasks may not transfer that performance to other programming languages, as the introduction of SWE-bench++ and SWE-bench Java has begun to reveal.
Reliability vs capability gap
A February 2026 paper from Princeton's Holistic Agent Leaderboard (HAL) team, "Towards a Science of AI Agent Reliability" (Rabanser et al., accepted at ICML 2026), found that reliability across 15 models and 12 metrics had improved only slightly even as accuracy climbed.[58] The HAL Reliability Dashboard reports consistency under repeated runs, robustness to perturbations, predictability of failures, and respect for safety constraints separately from raw accuracy. The conclusion is that "improving raw task performance is insufficient for building dependable AI agents", and that reliability requires targeted attention beyond capability scaling.[58]
Safety and alignment evaluation gaps
Current safety benchmarks like AgentHarm and R-Judge cover important failure modes, but the space of possible agent harms is vast and difficult to enumerate.[14][16] Agents operating in real environments can cause harm through subtle chains of actions that are difficult to predict or test for. The gap between synthetic safety benchmarks and real-world deployment risks remains a significant concern for the field. Automated auditing tools like Anthropic's Petri attempt to close part of this gap by using auditor agents to probe for misaligned behaviors at scale.[49]
Time horizons and the doubling-time framework
A distinct line of work, led by METR (Model Evaluation and Threat Research), reframes agent evaluation in terms of human-relatable task duration rather than benchmark-specific success rates. METR's flagship metric is the 50%-task-completion time horizon, defined as the task duration (measured by an expert human's completion time) at which an AI agent is predicted to succeed half the time. The team plots the time horizon of frontier models against their release date.[53]
The original METR paper, "Measuring AI Ability to Complete Long Tasks" (March 2025), found that the time horizon has been doubling roughly every seven months since 2019. Claude 3.7 Sonnet, the strongest model in that paper's evaluation, scored a 50% time horizon of about 50 minutes on METR's task suite. The headline implication, extrapolating the trend, was that "in under a decade, we will see AI agents that can independently complete a large fraction of software tasks that currently take humans days or weeks".[57]
In January 2026 METR released Time Horizon 1.1, which expanded the suite from 170 to 228 tasks (with long, 8+ hour tasks doubling from 14 to 31) and migrated the evaluation harness from METR's in-house Vivaria to AISI's Inspect framework. Under the updated estimator the headline hybrid trend remained 196 days (7 months), but the post-2023 doubling time tightened to 131 days (4.3 months) and the post-2024 doubling time tightened to 89 days, suggesting that progress has accelerated since 2023.[54] AISI's May 2026 cyber-capability post reported a February 2026 estimate that its 80%-reliability cyber time horizon had been doubling roughly every 4.7 months since late 2024, which AISI described as close to METR's software results (about 4.2 months at 80% reliability since late 2024).[56]
The METR framework has become an influential summary measure for policy and safety discussions, in part because it translates abstract benchmark percentages into "this model can do tasks that take humans X minutes". Critics caution that the metric is sensitive to task suite construction and that external validity (whether benchmark task durations match the real-world tasks that economically matter) remains an open question. The 2025 GDPval results, which target 1,320 real economic tasks, provide a complementary anchor.[36]
2025-2026 developments
The 18 months from late 2024 to mid-2026 saw the most concentrated changes in agent evaluation since the field's emergence.
Benchmark saturation and contamination
Several flagship benchmarks effectively saturated. By May 2026, the top self-reported score on SWE-bench Verified exceeded 93%, OSWorld-Verified scores exceeded 79% (above the human baseline), and the best GAIA test-set leaderboard entries exceeded 93%.[60][29][65] OpenAI's February 2026 audit found contamination on SWE-bench Verified across frontier models, prompting the field to migrate to SWE-bench Pro (1,865 long-horizon tasks, with public and held-out sets drawn from copyleft-licensed repositories and a commercial set from proprietary startup codebases) and SWE-bench Live (50 fresh issues per month).[59][19][20] The same dynamic played out on browsing benchmarks: BrowseComp gave way to BrowseComp-Plus, which fixes the document corpus to remove the variability of opaque search APIs.[28]
National-institute frameworks
The UK AI Security Institute released and operationalized Inspect as the de facto open evaluation harness across labs and governments. Inspect Evals (November 2024) collected community-contributed evaluations into a single repository, and 2025 saw the release of Inspect Sandboxing Toolkit and Inspect Cyber as agent-focused extensions.[46][47][48] METR migrated its time-horizon harness from Vivaria to Inspect in early 2026, consolidating a shared infrastructure across METR, AISI, and frontier labs.[54] The US AI Safety Institute was rebranded as the Center for AI Standards and Innovation (CAISI) inside NIST in June 2025 and continues to coordinate pre-deployment evaluation with Anthropic and OpenAI, with focus areas including generative AI risk management, synthetic content, evaluations, red teaming, and model safety and security.[55]
Automated red teaming and alignment auditing
Automated red teaming matured beyond static prompt sets. Anthropic's Petri (October 2025) and its January 2026 update Petri 2.0 use auditor agents to generate, run, and score multi-turn behavioral probes; the system identified deception, oversight subversion, and other failure modes across 14 frontier models with 111 seed instructions.[49] Other vendors followed: Promptfoo expanded its red-team module (and was acquired by OpenAI in March 2026), and HarmBench, AdvBench, and JailbreakBench remained reference datasets for comparing attacks and defenses.[50][41][42]
Enterprise and economic-task benchmarks
OpenAI's GDPval (September 2025) graded frontier-model outputs by blind head-to-head comparison with deliverables from experts who averaged 14 years of experience, across 44 occupations and 1,320 tasks. The best model in the launch paper (Claude Opus 4.1) matched or beat experts on 47.6% of gold-subset tasks, and OpenAI reported 84.9% for GPT-5.5 in April 2026.[36][61] Carnegie Mellon University's TheAgentCompany (December 2024) reported that the strongest agents could only autonomously complete 30% of 175 simulated software-company tasks, with partial credit reaching 40%, painting a more sobering picture of long-horizon workplace automation.[35] Sierra's τ²-bench (June 2025) and τ³-bench added dual-control environments and voice channels to customer-service evaluation, while keeping pass^k as the headline reliability metric.[34]
Reliability as a first-class metric
The HAL team at Princeton reported in 2026 that accuracy gains had not translated into proportional reliability gains across 15 evaluated models on 12 metrics covering consistency, robustness, predictability, and safety.[58] τ-bench's pass^k framing, ReliabilityBench's k-trial / ε-perturbation / λ-fault dimensions, and AppWorld's state-based collateral-damage tests all share this orientation. Anthropic's January 2026 guide "Demystifying evals for AI agents" pushed similar themes for product-grade evaluation, emphasizing balanced positive and negative cases, regular transcript reading, and monitoring for evaluation saturation rather than model saturation.[4]
Time-horizon acceleration
The most discussed result of the period was METR's January 2026 Time Horizon 1.1 update, which estimated a post-2024 doubling time of 89 days for the 50%-task-completion horizon, compared with 109 days for the same period under the original TH1 estimator.[54] AISI's May 2026 cyber-capability post cited a February 2026 estimate of a 4.7-month doubling time for autonomous cyber tasks and reported that Claude Mythos Preview and GPT-5.5 had since outpaced that trend.[56] Even with confidence intervals that span months, both numbers imply that benchmark difficulty levels considered cutting-edge in 2024 (such as long-horizon multi-application workflows) may be effectively solved within a year or two, sharpening the case for continuously refreshed, contamination-resistant evaluation infrastructure.
Leaderboards and tracking
Several public leaderboards track agent performance across major benchmarks:
- SWE-bench Leaderboard (swebench.com): Tracks performance on all SWE-bench variants, with separate rankings for Verified, Lite, and full datasets.
- GAIA Leaderboard (Hugging Face): Hosts the official GAIA rankings.
- HAL Reliability Dashboard (hal.cs.princeton.edu/reliability): Princeton's reliability-focused leaderboard.[58]
- BFCL Leaderboard (gorilla.cs.berkeley.edu): Ranks models on function-calling accuracy across multiple categories.
- OSWorld Leaderboard (os-world.github.io): Tracks multimodal agent performance on desktop computing tasks.
- OSWorld-Verified Leaderboard: The post-2025 verified leaderboard.[29]
- Epoch AI Benchmarks (epoch.ai): Aggregates results across multiple benchmarks and tracks progress over time.
- Scale Labs SWE-Bench Pro (labs.scale.com): Hosts the SWE-bench Pro leaderboard with public, held-out, and commercial splits.[19]
- METR Time Horizons (metr.org/time-horizons): Tracks frontier-model time horizons over time.[53]
- Artificial Analysis τ²-bench: Tracks Telecom and other τ²-bench domains.
These leaderboards play an important role in driving progress but also create incentive structures that can distort research priorities. Researchers may optimize for specific benchmark scores rather than general capability, and leaderboard positions can be gamed through task-specific fine-tuning or prompt engineering.
Best practices
Anthropic published a detailed guide on building agent evaluations in January 2026, synthesizing lessons learned from developing Claude's agent capabilities. Key recommendations include:[4]
- Start with real failures: Build initial evaluation sets from 20 to 50 tasks drawn from manual testing and observed real-world failures.
- Write unambiguous tasks: Each task should have a clear success criterion and a reference solution; two domain experts should reach the same pass/fail verdict.
- Run multiple trials: Because model outputs vary between runs, run several trials per task.
- Grade outcomes, not processes: Evaluate what the agent produced rather than the specific path it took.
- Use layered grading: Combine code-based graders (for objective criteria), model-based graders (for subjective criteria), and periodic human review.
- Read transcripts regularly: Manual review of agent transcripts reveals whether failures stem from the agent or from evaluation artifacts.
- Monitor for saturation: When agents reach near-100% on a benchmark, it becomes a regression suite rather than a capability test. Develop harder tasks to continue measuring progress.
- Balance positive and negative cases: Avoid one-sided evaluations that cause agents to over-optimize for a single behavior.
- Maintain evals as products: Like unit tests, evaluations require ongoing ownership, refactoring, and updates as the underlying agent evolves.
Future directions
The field of agent evaluation is evolving rapidly along several axes:
Holistic evaluation frameworks that assess multiple dimensions simultaneously (performance, safety, cost, reliability) rather than treating each dimension in isolation. The 2025 survey on LLM agent evaluation identified this as the top research priority.[11]
Enterprise-mimicking environments that replicate real business workflows, including role-based access controls, multi-user scenarios, and integration with enterprise software. CUB, TheAgentCompany, GDPval, and FieldWorkArena (from Fujitsu, focused on manufacturing and warehouse operations) represent early steps in this direction.[35][36]
Scalable automated evaluation techniques that reduce reliance on expensive human judges while maintaining evaluation quality. Agent-as-a-Judge, automated alignment auditing systems like Petri, and improved LLM-based grading methods are active areas of development.[49]
Efficient evaluation protocols that support iterative development cycles without prohibitive costs. This includes techniques for selecting representative task subsets, early stopping based on confidence intervals, and amortizing environment setup costs across multiple evaluations.
Real-time and continuous evaluation that goes beyond static benchmark snapshots to continuously monitor agent performance in production. This connects agent evaluation to the broader field of ML monitoring and observability.
Cross-modal and cross-environment evaluation that tests agents across different input modalities (text, vision, audio) and operating environments (web, desktop, mobile, voice) within unified frameworks. τ³-bench's addition of voice evaluation, CRAB's cross-platform testing, and BrowserGym's unification of web environments represent examples of this trend.[44]
Continue reading
- Benchmark (AI)In artificial intelligence and machine learning, a benchmark is a specified evaluation used to compare systems under common conditions.Mentioned 84 times above
- SWE-benchSWE-bench is an execution-based benchmark for evaluating whether a language-model system can resolve real software issues.Mentioned 42 times above
- OSWorldOSWorld is a benchmark for evaluating multimodal AI agents on open-ended tasks performed inside real computer environments.Mentioned 19 times above
- METRMETR (Model Evaluation and Threat Research) is a nonprofit research organization based in Berkeley, California, that develops scientific methods for measuring the autonomous capabilities of frontier AI systems…Mentioned 14 times above
- WebArenaWebArena is a realistic, self-hosted web environment and benchmark designed for developing and evaluating autonomous AI agents that perform tasks on the web.Mentioned 13 times above
- τ-benchτ-bench (Tau-bench), short for Tool-Agent-User Interaction Benchmark, is an AI benchmark that evaluates language agents' ability to complete complex tasks through realistic, multi-turn interactions with…Mentioned 13 times above
More from See also
- AI Agents
- SWE-bench Verified
- SWE-Bench Pro
- GAIA benchmark
- VisualWebArena
- AgentBench
- BrowseComp
- Berkeley Function Calling Leaderboard
- MLE-bench
- GDPval
- UK AI Security Institute
- US AI Safety Institute (Center for AI Standards and Innovation)
- AI coding agent
- AI browser agent
- Computer-use agent
- Large Language Model
- Prompt injection
- Jailbreak (artificial intelligence)
- Red teaming (artificial intelligence)
- Reinforcement learning
- Deep Research
References
- ^1 ^2 ^3 ^4Liu, X. et al., "AgentBench: Evaluating LLMs as Agents", ICLR 2024 / arXiv, 2023-08-07. arxiv.org/...2308.03688. Accessed 2026-05-24.
- ^1 ^2 ^3 ^4 ^5 ^6Zhou, S. et al., "WebArena: A Realistic Web Environment for Building Autonomous Agents", ICLR 2024 / arXiv, 2023-07-25. arxiv.org/...2307.13854. Accessed 2026-05-24.
- ^1 ^2"Evaluation and Benchmarking of LLM Agents: A Survey", arXiv, 2025-07-29. arxiv.org/...2507.21504. Accessed 2026-05-24.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Anthropic, "Demystifying evals for AI agents", Anthropic Engineering Blog, 2026-01-09. anthropic.com/...demystifying-evals-for-ai-agents. Accessed 2026-05-24.
- ^UK AI Security Institute, "Our 2025 year in review", AISI Work blog, 2025-12-19. aisi.gov.uk/...our-2025-year-in-review. Accessed 2026-05-24.
- ^Yao, S. et al., "WebShop: Towards Scalable Real-World Web Interaction with Grounded Language Agents", NeurIPS, 2022. arxiv.org/...2207.01206. Accessed 2026-05-24.
- ^1 ^2 ^3 ^4Jimenez, C. E. et al., "SWE-bench: Can Language Models Resolve Real-World GitHub Issues?", arXiv, 2023-10-10. arxiv.org/...2310.06770. Accessed 2026-05-24.
- ^1 ^2 ^3 ^4Mialon, G. et al., "GAIA: A Benchmark for General AI Assistants", arXiv, 2023-11-21. arxiv.org/...2311.12983. Accessed 2026-05-24.
- ^1 ^2 ^3XLANG Lab, "Introducing OSWorld-Verified", XLANG Lab blog, 2025-07. xlang.ai/...osworld-verified. Accessed 2026-05-24.
- ^1 ^2 ^3Xie, T. et al., "OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments", NeurIPS 2024 / arXiv, 2024-04-11. arxiv.org/...2404.07972. Accessed 2026-05-24.
- ^1 ^2Mohammadi, M. et al., "Evaluation and Benchmarking of LLM Agents: A Survey", arXiv, 2025-07-29. arxiv.org/...2507.21504. Accessed 2026-05-24.
- ^1 ^2 ^3 ^4Zheng, L. et al., "Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena", NeurIPS 2023. arxiv.org/...2306.05685. Accessed 2026-05-24.
- ^1 ^2 ^3Yao, S. et al., "tau-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains", Sierra / arXiv, 2024-06-17. arxiv.org/...2406.12045. Accessed 2026-05-24.
- ^1 ^2 ^3Andriushchenko, M. et al., "AgentHarm: A Benchmark for Measuring Harmfulness of LLM Agents", ICLR 2025 / arXiv, 2024-10-11. arxiv.org/...2410.09024. Accessed 2026-05-24.
- ^1 ^2Ruan, Y. et al., "Identifying the Risks of LM Agents with an LM-Emulated Sandbox", arXiv, 2023-09-25. arxiv.org/...2309.15817. Accessed 2026-05-24.
- ^1 ^2 ^3Yuan, T. et al., "R-Judge: Benchmarking Safety Risk Awareness for LLM Agents", EMNLP 2024 Findings / arXiv, 2024-01-18. arxiv.org/...2401.10019. Accessed 2026-05-24.
- ^1 ^2Yan, F. et al., "Berkeley Function-Calling Leaderboard", UC Berkeley Gorilla project, 2024. gorilla.cs.berkeley.edu/leaderboard. Accessed 2026-05-24.
- ^Vals AI, "SWE-bench Verified Leaderboard", 2026. vals.ai/...swebench. Accessed 2026-05-24.
- ^1 ^2 ^3 ^4 ^5Deng, X. et al., "SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?", Scale AI / arXiv, 2025-09-21. arxiv.org/...2509.16941. Accessed 2026-05-24.
- ^1 ^2 ^3Zhang, L. et al., "SWE-bench Goes Live!", NeurIPS 2025 Datasets and Benchmarks / arXiv, 2025-05-29. arxiv.org/...2505.23419. Accessed 2026-05-24.
- ^Yang, J. et al., "SWE-bench Multimodal: Do AI Systems Generalize to Visual Software Domains?", ICLR 2025 / arXiv, 2024-10-04. arxiv.org/...2410.03859. Accessed 2026-05-24.
- ^Chan, J. S. et al., "MLE-bench: Evaluating Machine Learning Agents on Machine Learning Engineering", OpenAI / arXiv, 2024-10-09. arxiv.org/...2410.07095. Accessed 2026-05-24.
- ^Drouin, A. et al., "WorkArena: How Capable Are Web Agents at Solving Common Knowledge Work Tasks?", arXiv, 2024-03-12. arxiv.org/...2403.07718. Accessed 2026-05-24.
- ^IBM Research, "Towards Enterprise-Ready Computer Using Generalist Agent", arXiv, 2025-03-03. arxiv.org/...2503.01861. Accessed 2026-05-24.
- ^Deng, X. et al., "Mind2Web: Towards a Generalist Agent for the Web", NeurIPS 2023 / arXiv, 2023-06-09. arxiv.org/...2306.06070. Accessed 2026-05-24.
- ^Koh, J. Y. et al., "VisualWebArena: Evaluating Multimodal Agents on Realistic Visual Web Tasks", ACL 2024 / arXiv, 2024-01-24. arxiv.org/...2401.13649. Accessed 2026-05-24.
- ^Wei, J. et al., "BrowseComp: A Simple Yet Challenging Benchmark for Browsing Agents", OpenAI, 2025-04-10. openai.com/...browsecomp. Accessed 2026-05-24.
- ^1 ^2 ^3Chen, Z. et al., "BrowseComp-Plus: A More Fair and Transparent Evaluation Benchmark of Deep-Research Agent", arXiv, 2025-08-08. arxiv.org/...2508.06600. Accessed 2026-05-24.
- ^1 ^2 ^3BenchLM, "OSWorld-Verified Benchmark 2026", BenchLM.ai. benchlm.ai/...osWorldVerified. Accessed 2026-05-24.
- ^OpenAI, "Introducing Deep Research", OpenAI blog, 2025-02-02. openai.com/...introducing-deep-research. Accessed 2026-05-24.
- ^Ma, C. et al., "AgentBoard: An Analytical Evaluation Board of Multi-turn LLM Agents", NeurIPS 2024 Oral / arXiv, 2024-01-24. arxiv.org/...2401.13178. Accessed 2026-05-24.
- ^Qin, Y. et al., "ToolLLM: Facilitating Large Language Models to Master 16000+ Real-world APIs", ICLR 2024 / arXiv, 2023-07-31. arxiv.org/...2307.16789. Accessed 2026-05-24.
- ^1 ^2Trivedi, H. et al., "AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents", ACL 2024 Best Resource Paper / arXiv, 2024-07-26. arxiv.org/...2407.18901. Accessed 2026-05-24.
- ^1 ^2 ^3Barres, V. et al., "tau-squared-bench: Evaluating Conversational Agents in a Dual-Control Environment", Sierra, University of Toronto and Vector Institute / arXiv, 2025-06-09. arxiv.org/...2506.07982. Accessed 2026-05-24.
- ^1 ^2 ^3Xu, F. et al., "TheAgentCompany: Benchmarking LLM Agents on Consequential Real World Tasks", Carnegie Mellon University / arXiv, 2024-12-18. arxiv.org/...2412.14161. Accessed 2026-05-24.
- ^1 ^2 ^3 ^4 ^5OpenAI, "GDPval: Evaluating AI Model Performance on Real-World Economically Valuable Tasks", OpenAI / arXiv, 2025-10-05. arxiv.org/...2510.04374. Accessed 2026-05-24.
- ^Zhang, A. et al., "Cybench: A Framework for Evaluating Cybersecurity Capabilities and Risks of Language Models", ICLR 2025 Oral / arXiv, 2024-08-15. arxiv.org/...2408.08926. Accessed 2026-05-24.
- ^UK AI Security Institute, "Our evaluation of OpenAI's GPT-5.5 cyber capabilities", AISI Work blog, 2026-04-30. aisi.gov.uk/...-openais-gpt-5-5-cyber-capabilities. Accessed 2026-05-24.
- ^Sanz-Gómez, M., Mayoral-Vilches, V. et al., "Cybersecurity AI Benchmark (CAIBench): A Meta-Benchmark for Evaluating Cybersecurity AI Agents", arXiv, 2025-10-28. arxiv.org/...2510.24317. Accessed 2026-05-24.
- ^MLCommons, "AILuminate: Introducing v1.0 of the AI Risk and Reliability Benchmark from MLCommons", arXiv, 2025-03-07. arxiv.org/...2503.05731. Accessed 2026-05-24.
- ^1 ^2Mazeika, M. et al., "HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal", ICML 2024 / arXiv, 2024-02-06. arxiv.org/...2402.04249. Accessed 2026-05-24.
- ^1 ^2Chao, P. et al., "JailbreakBench: An Open Robustness Benchmark for Jailbreaking Large Language Models", NeurIPS 2024 / arXiv, 2024-03-28. arxiv.org/...2404.01318. Accessed 2026-05-24.
- ^Padlewski, P. et al., "Vibe-Eval: A hard evaluation suite for measuring progress of multimodal language models", Reka, 2024-05-03. arxiv.org/...2405.02287. Accessed 2026-05-24.
- ^1 ^2Chezelles, T. L. et al., "The BrowserGym Ecosystem for Web Agent Research", ServiceNow Research, 2024. github.com/...BrowserGym. Accessed 2026-05-24.
- ^UK AI Security Institute, "Inspect: A framework for large language model evaluations", Inspect documentation, 2025. inspect.aisi.org.uk. Accessed 2026-05-24.
- ^1 ^2 ^3UK AI Security Institute, "Announcing Inspect Evals", AISI Work blog, 2024-11-13. aisi.gov.uk/...inspect-evals. Accessed 2026-05-24.
- ^1 ^2UK AI Security Institute, "The Inspect Sandboxing Toolkit: Scalable and secure AI agent evaluations", AISI Work blog, 2025. aisi.gov.uk/...ble-and-secure-ai-agent-evaluations. Accessed 2026-05-24.
- ^1 ^2UK AI Security Institute, "Inspect Cyber: A New Standard for Agentic Cyber Evaluations", AISI Work blog, 2025. aisi.gov.uk/...inspect-cyber. Accessed 2026-05-24.
- ^1 ^2 ^3Anthropic Alignment Science, "Petri: An open-source auditing tool to accelerate AI safety research", Anthropic, 2025-10-06. alignment.anthropic.com/...petri. Accessed 2026-05-24.
- ^1 ^2Promptfoo GitHub, "promptfoo: LLM evals and red teaming", Promptfoo, 2025-2026. github.com/...promptfoo. Accessed 2026-05-24.
- ^OpenAI, "OpenAI Evals framework", OpenAI GitHub, 2025-2026. github.com/...evals. Accessed 2026-05-24.
- Kapoor, S., Stroebl, B. et al., "Holistic Agent Leaderboard: The Missing Infrastructure for AI Agent Evaluation", Princeton University / arXiv, 2025-10-13. arxiv.org/...2510.11977. Accessed 2026-05-24.
- ^1 ^2Kwa, T. et al., "Measuring AI Ability to Complete Long Tasks", METR / arXiv, 2025-03-19. arxiv.org/...2503.14499. Accessed 2026-05-24.
- ^1 ^2 ^3METR, "Time Horizon 1.1", METR blog, 2026-01-29. metr.org/...2026-1-29-time-horizon-1-1. Accessed 2026-05-24.
- ^NIST, "U.S. AI Safety Institute Consortium Holds First Plenary Meeting", NIST News, 2025. nist.gov/...-plenary-meeting-reflect-progress-2024. Accessed 2026-05-24.
- ^1 ^2 ^3 ^4UK AI Security Institute, "How fast is autonomous AI cyber capability advancing?", AISI Work blog, 2026-05-13. aisi.gov.uk/...omous-ai-cyber-capability-advancing. Accessed 2026-11-03.
- ^METR, "Measuring AI Ability to Complete Long Tasks", METR blog, 2025-03-19. metr.org/...ring-ai-ability-to-complete-long-tasks. Accessed 2026-11-03.
- ^1 ^2 ^3 ^4Princeton HAL, "HAL Reliability Dashboard" (Rabanser, S., Kapoor, S. et al., "Towards a Science of AI Agent Reliability", ICML 2026 / arXiv 2602.16666, 2026-02-18). hal.cs.princeton.edu/reliability. Accessed 2026-11-03.
- ^1 ^2 ^3Glaese, M. and Watkins, O., "Why SWE-bench Verified no longer measures frontier coding capabilities", OpenAI, 2026-02-23. openai.com/...o-longer-evaluate-swe-bench-verified. Accessed 2026-11-03.
- ^1 ^2 ^3Anthropic, "Project Glasswing: Securing critical software for the AI era", Anthropic, 2026-04. anthropic.com/glasswing. Accessed 2026-11-03.
- ^1 ^2OpenAI, "Introducing GPT-5.5", OpenAI, 2026-04-23. openai.com/...introducing-gpt-5-5. Accessed 2026-11-03.
- ^Fernholz, T., "OpenAI acquires Promptfoo to secure its AI agents", TechCrunch, 2026-03-09. techcrunch.com/...romptfoo-to-secure-its-ai-agents. Accessed 2026-11-03.
- ^Anthropic Alignment Science, "Petri 2.0: New Scenarios, New Model Comparisons, and Improved Eval-Awareness Mitigations", Anthropic, 2026-01-22. alignment.anthropic.com/...petri-v2. Accessed 2026-11-03.
- ^Guo, Y. et al., "OpAgent: Operator Agent for Web Navigation", arXiv, 2026-02-14. arxiv.org/...2602.13559. Accessed 2026-11-03.
- ^1 ^2GAIA benchmark maintainers, "GAIA leaderboard results (results_public, 2023 test split)", Hugging Face, accessed 2026-11-04. huggingface.co/...results_public. Accessed 2026-11-04.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
8 revisions · v8 · 10,448 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (170 claims, 85 sources fetched); 18 material + 51 minor fixed
Cite this page: AI Wiki. "Agent evaluation." aiwiki.ai, updated 1 Oct 2026, fact-checked 4 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/agent_evaluation