

GAIA benchmark
GAIA (General AI Assistants) is a benchmark for evaluating general-purpose AI agents and assistants on real-world tasks that require reasoning, web browsing, file handling, and multimodal understanding.[1] Published in November 2023 by a team from Meta AI (FAIR), Hugging Face, and AutoGPT, GAIA was designed to expose a fundamental gap between human and AI capability on tasks that, in the authors' words, are "conceptually simple for humans yet challenging for most advanced AIs."[1] Its 466 curated questions span three difficulty levels and cover an unusually wide range of modalities and tool use.[1] The leaderboard is hosted on Hugging Face and has become one of the standard evaluations for agentic AI systems.[3] When the paper was accepted at ICLR 2024, the best available AI system, GPT-4 with plugins, scored only 15% overall against a human baseline of 92%, establishing GAIA as a benchmark that would take years rather than months to approach human performance.[1][2] By mid-2026, the leading systems on the leaderboard's hidden test set (not the public validation set) were posting overall scores above 93%, reaching 94.35% by November 2026, and the benchmark's authors had released a successor, GAIA2, designed to test the dynamic and asynchronous behaviors that the original GAIA could not.[3][19]
Background
By late 2023, the prevailing assumption among AI researchers was that the remaining gap between human and machine performance lay in specialized, high-difficulty domains: the bar exam, the USMLE medical licensing exam, the International Mathematics Olympiad. Benchmarks such as MMLU and BIG-Bench had driven rapid progress by posing questions that required graduate-level expertise, and models like GPT-4 and PaLM 2 were already matching or exceeding average human performance on many of them. The implicit expectation was that if AI could handle difficult professional tasks, it was well on its way to general intelligence.
Grégoire Mialon, Clémentine Fourrier, Thomas Wolf, Yann LeCun, Thomas Scialom, and Craig Swift argued that this framing had the problem backward.[1] Their central observation was that advanced models consistently failed at tasks any capable human adult handles without difficulty: looking up a recent news article, extracting a figure from a PDF, identifying an image, following a multi-step instruction that required combining information from several sources. The researchers targeted this class of task, difficult for AI but easy for humans, and they designed GAIA specifically to measure performance on it.[1]
The philosophical underpinning was that robustness matters more than peak performance. A system that scores above human level on an isolated chemistry multiple-choice question but fails to answer "who won the 2022 French Open" by browsing the web is not approaching general artificial intelligence. Genuine AI assistants, the authors argued, must handle the full breadth of tasks humans routinely perform, not just a narrow slice of carefully defined test items.[1]
A secondary motivation was benchmark integrity. MMLU, GSM8k, and related evaluations were already showing signs of saturation and data contamination: rapid improvements were as likely to reflect training data leakage as genuine capability gains. GAIA was designed from the start to resist contamination by requiring answers that could not be retrieved from a simple text search or a model's pre-training corpus, and by hiding the answers to the 300-question test set behind a submission-gated leaderboard.[1]
What is the GAIA paper, and when was it published?
The paper titled "GAIA: a benchmark for General AI Assistants" (arXiv:2311.12983) was submitted to arXiv on November 21, 2023 and later accepted at the International Conference on Learning Representations (ICLR) 2024.[1][2] The six authors were:
- Grégoire Mialon (Meta AI / FAIR)
- Clémentine Fourrier (Hugging Face)
- Craig Swift (AutoGPT)
- Thomas Wolf (Hugging Face, co-founder and Chief Science Officer)
- Yann LeCun (Meta AI, then Chief AI Scientist; he left Meta in November 2025)
- Thomas Scialom (Meta AI / GenAI)
The collaboration between Meta's Fundamental AI Research division and Hugging Face was notable. Yann LeCun's involvement as co-author lent the benchmark considerable visibility, given his prominence as one of the Turing Award winners credited with the deep learning revolution.
The abstract declared GAIA's ambition plainly: if the benchmark were solved, it would represent "a milestone in AI research."[1] The paper proposed four design principles that distinguished GAIA from prior work (the paper's own labels are real-world and challenging questions, easy interpretability, non-gameability, and simplicity of use):[1]
- Relevance and challenge: Questions must be rooted in the real world and require multiple tools or steps, while remaining conceptually simple enough for a non-expert human to solve.
- Interpretability: Answers must be short, factual, and unambiguous, enabling automatic evaluation without a judge model and making error analysis tractable.
- Robustness: Answers must not be trivially retrievable from text already indexed on the web, preventing training data shortcuts.
- Usability: The benchmark must be small enough to evaluate cheaply and completely, in contrast to MMLU's 15,000 items, and must support zero-shot prompting without special-purpose fine-tuning.
The paper demonstrated a stark finding: humans achieved 92% accuracy across all three difficulty levels, while GPT-4 with plugins, the strongest system available at the time, achieved only 15%.[1] Even this 15% figure overstated raw model capability because the plugins were selected manually by the researchers for each question, functioning as an oracle configuration. Without the oracle plugin selection, performance was substantially lower.[1]
How does GAIA build and score its questions?
Question design
All 466 questions were created by human annotators following structured guidelines developed by the paper's authors.[1] The creation process began with the authors drafting an initial set of example questions that embodied the benchmark's core properties. These examples were then shared with annotators alongside instructions for generating similar questions.
Each question had to satisfy several hard constraints:
- The answer must be a short factoid, typically a number, a proper noun, a date, or a brief phrase, enabling exact-match evaluation.
- The answer must not appear in plain text at the top of search results; annotators were required to verify that the answer was not trivially googleable.
- The information underlying the answer must be grounded in a reliable source: Wikipedia, a peer-reviewed paper on arXiv, GitHub, a published dataset, or an official government or organizational publication.
- The question must involve at least one step of genuine reasoning or synthesis beyond retrieval, such as numerical computation, temporal reasoning, counting, or comparison across sources.
- Where possible, the question should involve a file attachment, an image, an audio clip, or a document that the solver must interpret.
Annotators spent roughly two hours per question including design and validation.[1] Two new annotators then answered each question independently; if they and the original annotator reached the same answer, the question was validated. The validation pass found that 68% of questions were good as is, while the rest had to be corrected or removed.[1]
File and modality types
GAIA intentionally tests multimodal handling in addition to text reasoning.[1] Questions may be accompanied by:
- Images requiring visual analysis or identification
- PDF documents that must be read and cross-referenced
- Spreadsheets or CSV files requiring numerical processing
- Audio clips requiring transcription or content interpretation
- Videos requiring frame-level analysis or temporal reasoning
- Plain-text documents requiring extraction and synthesis
The distribution of file types is not uniform across difficulty levels: Level 1 questions often require no files, Level 2 questions frequently attach a PDF or image, and Level 3 questions may involve multiple heterogeneous files.
How are GAIA answers evaluated?
Scoring uses exact string matching applied to a normalized version of the model's final answer.[1][4] In the official scorer, string answers are compared after removing whitespace and punctuation and lowercasing, numeric answers after stripping "$", "%" and commas, and list answers element by element after splitting on commas or semicolons.[3] This approach was chosen because it is fully automatic and eliminates the need for a separate judge model, which itself introduces reliability concerns and cost.[1]
Models are evaluated in zero-shot mode: no few-shot examples of GAIA questions are provided in the prompt.[1] This was a deliberate choice to prevent overfitting to the benchmark's specific format and to measure the ability to follow natural-language instructions of the kind a real user would provide.
Refinements after launch
As the GAIA leaderboard matured through 2024 and 2025, evaluation practice around it changed more than the benchmark itself: the official scorer still applies the same quasi-exact-match normalization.[3] The Princeton HAL group began reporting the total API cost of each run alongside raw accuracy, plotting an accuracy-versus-cost frontier; some runs on the 165-question validation set cost more than $1,000 in total.[5]
What are the three difficulty levels in GAIA?
The 466 questions are divided into three levels based on the estimated complexity of the solution path.[1] The level assignments are not mechanical; the authors acknowledge they represent reasonable guidelines rather than strict algorithmic thresholds.[1]
Level 1
Level 1 questions "generally require no tools, or at most one tool but no more than 5 steps."[1] A typical Level 1 question might ask for a numerical fact that requires looking up a single webpage and performing a single arithmetic operation, or for a property of an image that requires visual analysis plus one lookup. The validation set contains 53 Level 1 questions; the test set contains 93.[1]
Human annotators achieved 93.9% accuracy on Level 1. The best AI system in the original paper (GPT-4 with oracle plugins) achieved 30.3%, a gap of more than 60 percentage points.[1]
Level 2
Level 2 questions "generally involve more steps, roughly between 5 and 10, and combining different tools is needed."[1] These questions require synthesizing information from multiple sources, performing multi-step calculations, interpreting file attachments in combination with web information, or executing a non-trivial sequence of operations. The validation set contains 86 Level 2 questions; the test set contains 159.[1][3]
Human annotators achieved 91.8% on Level 2. GPT-4 with oracle plugins scored 9.7%, a gap of more than 80 percentage points.[1]
Level 3
Level 3 questions are meant "for a near perfect general assistant, requiring to take arbitrarily long sequences of actions" and represent tasks that would challenge a highly capable human assistant working without time pressure.[1] The questions may require combining information across many sources, maintaining complex state over a long reasoning chain, performing iterative refinements, or handling multiple file formats in concert. The validation set contains 26 Level 3 questions; the test set contains 49.[1][3]
Human annotators achieved 87.3% on Level 3, reflecting the genuine difficulty even for humans. GPT-4 with oracle plugins scored 0%, meaning that at launch no AI system could reliably solve any Level 3 question.[1]
The authors were explicit that the level boundaries are approximate.[1] A question labeled Level 2 might technically require fewer than five steps if an unusually capable tool is available, or might demand ten steps on a less capable system. The labels convey expected difficulty for a typical 2023-era AI assistant, not a formal algorithmic classification.
How are the validation and test splits organized?
The 466 questions are divided into two public groups:[1][4]
| Split | Questions | Answers available |
|---|---|---|
| Validation (dev set) | 165 (166 in the paper) | Yes, publicly released |
| Test (leaderboard set) | 301 (300 in the paper) | No, withheld by organizers |
The validation set is fully open, including ground-truth answers and annotator metadata such as the reasoning traces used to derive each answer and the annotator's own notes.[4] This makes the validation set suitable for development, debugging, and ablation studies, but it also means the validation set answers are widely known and have been incorporated into many model training datasets, making it less reliable as a contamination-free evaluation signal.
The test set answers are held by the benchmark organizers. Teams submit model outputs to the Hugging Face leaderboard, which evaluates the outputs and returns per-level and overall scores.[3] The test set question texts and associated files are public, but the answers remain hidden, which provides substantially more resistance to data contamination.
Researchers and practitioners have increasingly treated test set performance as the more trustworthy signal, particularly for systems that may have been exposed to validation set answers during training or fine-tuning.
Who leads the GAIA leaderboard?
The GAIA leaderboard is hosted at Hugging Face (huggingface.co/spaces/gaia-benchmark/leaderboard) and has been active since the benchmark's release in late 2023.[3] A parallel leaderboard operated by Princeton University's HAL project (hal.cs.princeton.edu/gaia) tracks performance under standardized agentic scaffolding conditions to control for the large variance introduced by different agent frameworks.[5]
Progress from 2023 to 2026
At launch in November 2023, the best AI result was GPT-4 with plugins at 15% overall.[1] By mid-2024, purpose-built agent frameworks incorporating web search, code execution, and multi-step planning had pushed overall scores above 40% on the validation set. The following table summarizes major performance milestones; rows mix the public validation set and the hidden test set, as noted:
| Period | System | Overall | Level 1 | Level 2 | Level 3 |
|---|---|---|---|---|---|
| Nov 2023 | GPT-4 + plugins (oracle) | ~15% | 30.3% | 9.7% | 0% |
| Nov 2023 | AutoGPT (GPT-4) | ~5% | 14.4% | 0.4% | 0% |
| Nov 2023 | GPT-4 Turbo | ~7% | 13.0% | 5.5% | 0% |
| Jul 2024 | Hugging Face Transformers Agents (ReactCodeAgent) + GPT-4o | 44.2% (validation); 33.3% (test) | -- | -- | -- |
| Oct 2024 | Magentic-One (o1), Microsoft Research (test) | 37.87% | 54.84% | 32.70% | 22.45% |
| Feb 2025 | OpenAI Deep Research (pass@1, validation) | 67.36% | 74.29% | 69.06% | 47.6% |
| Mar 2025 | Manus (self-reported, validation) | not reported | 86.5% | 70.1% | 57.7% |
| Apr 2025 | Genspark (self-reported) | not reported | 87.8% | 72.7% | 58.8% |
| 2025 | h2oGPTe Agent | ~75% (test set) | 86% | 74.8% | 53% |
| Jan 2026 | Nemotron-ToolOrchestra (test) | 90.37% | 96.77% | 86.79% | 89.8% |
| Feb 2026 | openJiuwen-deepagent (test) | 91.69% | 98.92% | 88.68% | 87.76% |
| Mar 2026 | OPS-Agentic-Search (Alibaba Cloud, test) | 92.36% | 98.92% | 90.57% | 85.71% |
| Nov 2026 | Keen AgenticOS V1.1 (KeenData, test) | 94.35% | 97.85% | 93.71% | 89.80% |
Note: the HF leaderboard rows from h2oGPTe onward are scores on the hidden 301-question test set; the Transformers Agents, OpenAI Deep Research, Manus and Genspark figures are on the public validation set. The Princeton HAL leaderboard evaluates on the 165-question public validation set under controlled scaffolding.[3][5]
Top performers on the HF leaderboard (as of March 2026)
The following table shows the top test-set entries on the main Hugging Face leaderboard as of the end of March 2026:[3]
| Rank | Agent | Organization | Overall | Level 1 | Level 2 | Level 3 |
|---|---|---|---|---|---|---|
| 1 | OPS-Agentic-Search | Alibaba Cloud | 92.36% | 98.92% | 90.57% | 85.71% |
| 2 | openJiuwen-deepagent | openJiuwen | 91.69% | 98.92% | 88.68% | 87.76% |
| 3 | Lemon | LR AILab / Lenovo CTO Org | 91.36% | 96.77% | 89.31% | 87.76% |
| 4 | JoinAI_V2.2 | JoinAI-CMCC | 90.70% | 98.92% | 86.79% | 87.76% |
| 5 | Nemotron-ToolOrchestra-0107 | NVIDIA | 90.37% | 96.77% | 86.79% | 89.80% |
| 6 | JoinAI_V2.1 | JoinAI-CMCC | 90.03% | 98.92% | 86.79% | 83.67% |
| 7 | SU Zero / Shuqian Series Pro MAX | Suzhou AI Lab / Shuqian Tech | 90.03% | 98.92% | 86.79% | 83.67% |
| 8 | HALO V1217-1 | Microsoft AI Asia (Ads) | 89.37% | 96.77% | 86.79% | 83.67% |
| 9 | ShawnAgent_v3.1 | Independent | 89.37% | 96.77% | 86.79% | 83.67% |
Later entries pushed higher: Co-Sight Pro v1.0.1 (ZTE-AICloud) reached 93.02% in May 2026, CustomGPT.ai Research Lab v44 reached 93.36% in June 2026, and Keen AgenticOS V1.1 (KeenData) posted 94.35% on November 3, 2026, the top test-set score as of November 2026.[3]
Scores in this range reflect the use of multi-model orchestration: top systems in 2025 and 2026 typically route questions to specialized subagents backed by different frontier models (GPT-5, Gemini, Claude, DeepSeek), choose tools dynamically, and run verification steps before submitting a final answer.
Princeton HAL leaderboard (controlled conditions)
The Princeton HAL leaderboard evaluates agents under identical scaffolding (the HAL Generalist agent framework) to separate the contribution of the underlying model from the contribution of the agent wrapper.[5] As of early 2026, results under these controlled conditions, on the 165-question validation set, were as follows (in October 2026 HAL noted that some reported costs are overstated by up to 2x because trace spans were double-counted):[5]
| Rank | Model | Overall | Level 1 | Level 2 | Level 3 | Cost per run |
|---|---|---|---|---|---|---|
| 1 | Claude Sonnet 4.5 (Sept 2025) | 74.55% | 82.07% | 72.68% | 65.39% | $178.20 |
| 2 | Claude Sonnet 4.5 High (Sept 2025) | 70.91% | 77.36% | 74.42% | 46.15% | $179.86 |
| 3 | Claude Opus 4.1 High (Aug 2025) | 68.48% | 71.70% | 70.93% | 53.85% | $562.24 |
| 4 | Claude Opus 4 High (May 2025) | 64.85% | 71.70% | 67.44% | 42.31% | $665.89 |
| 5 | Claude 3.7 Sonnet High (Feb 2025) | 64.24% | 67.92% | 63.95% | 57.69% | $122.49 |
Anthropic models occupied the top six positions on the HAL leaderboard as of early 2026 under these standardized conditions, suggesting that instruction-following reliability and multi-step tool use are areas where Claude model generations have shown consistent improvement over time.[5]
Three tiers of GAIA scores
A practical insight that crystallized in 2025 and 2026 is that a single "GAIA score" is misleading because three categorically different evaluation regimes produce three different score ranges on the same 466 questions. The bare-model regime measures a frontier model with minimal scaffolding: GPT-5 Mini in this regime scored about 44.8% in a 2026 snapshot compiled by Rapid Claw.[13] The scaffolded regime fixes a generalist agent framework such as Princeton HAL's reference implementation and varies only the underlying model: Claude Sonnet 4.5 reached 74.6%.[5] The full-system regime allows arbitrary engineering, including multi-model orchestration, custom verifiers, and benchmark-specific tool routing: the leading 2026 entries pushed past 92%.[3] The gap between regimes routinely exceeds 30 percentage points on identical questions, so comparing two GAIA results requires asking which regime each was evaluated under.
OpenAI Deep Research, ChatGPT Agent, and Manus
Several systems that attracted particular attention in 2025 illustrated different strategies for tackling GAIA. OpenAI's Deep Research product, released in early 2025 as part of the ChatGPT Pro subscription, scored 67.36% on average (pass@1) on the GAIA validation set, or 72.57% with 64-sample consensus.[29] Its Level 1 performance of 74.3% and Level 2 performance of 69.1% were notably strong for a commercially available product not specifically fine-tuned for GAIA. The result demonstrated that capable web research agents could solve the majority of GAIA's easier questions without special-purpose engineering.
Manus launched in beta in March 2025 and reported GAIA validation scores of 86.5% on Level 1, 70.1% on Level 2, and 57.7% on Level 3.[15] The Manus result attracted wide coverage because it far exceeded what earlier general-purpose assistants had achieved, and it validated the GAIA benchmark as a meaningful signal for distinguishing capable agentic systems from less capable ones. Genspark subsequently reported 87.8% on Level 1, 72.7% on Level 2 and 58.8% on Level 3, edging past Manus at each level by a small margin.[15]
OpenAI launched ChatGPT Agent on July 17, 2025, combining the Operator action-taking remote browser, Deep Research's web synthesis, and ChatGPT's conversational interface into a single product.[23][24] OpenAI's headline benchmark results for ChatGPT Agent emphasized strong gains on Humanity's Last Exam (41.6% pass@1, roughly double the o3 score), FrontierMath (27.4% with tool access), and DSBench.[23][24] The launch post did not report a GAIA score for ChatGPT Agent.[23]
H2O.ai's h2oGPTe Agent was the first system to claim a grade-C performance (roughly 75%) on the harder test set rather than the more permissive validation set, a distinction the company highlighted explicitly because test set performance is considered a more reliable signal given that validation set answers are widely known.[11]
Hugging Face smolagents and open-source agents
In December 2024, Hugging Face released smolagents, a minimal open-source agent library designed to make tool-using agents accessible without heavy framework infrastructure.[25] Its predecessor, the Transformers Agents framework, had already reached 44.2% on the GAIA validation set with a GPT-4o-backed code agent in July 2024, ranking first overall at the time, and 33.3% on the test set.[32] In February 2025 a smolagents-based open reproduction of Deep Research reached 55.15% on the validation set using o1.[33]
How does GAIA compare to other agent benchmarks?
GAIA occupies a specific niche among agent benchmarks: it tests breadth of general assistant capability rather than depth in a single domain. The following comparison situates GAIA alongside three other prominent evaluations.
Comparison table
| Dimension | GAIA | WebArena | BrowseComp | Tau-bench |
|---|---|---|---|---|
| Paper / origin | Mialon et al., ICLR 2024 | Zhou et al., ICLR 2024 | Wei et al., OpenAI, Apr 2025 | Yao et al., Sierra AI, Jun 2024 |
| Primary focus | General assistant tasks: reasoning, files, multimodal, web | Autonomous web navigation across simulated websites | Hard information retrieval requiring deep web browsing | Tool-agent-user interaction in enterprise service domains |
| Number of tasks | 466 (166 dev + 300 test) | 812 long-horizon web tasks | 1,266 challenging browsing problems | Retail + airline domains (multi-turn) |
| Modalities | Text, image, PDF, audio, video, spreadsheet | Browser / web interface only | Browser / web interface only | Text + tool APIs |
| Answer format | Short factoid, exact match | Functional correctness of web state | Short factoid, exact match | Database state match |
| Human baseline | 92% | ~78% | Not reported | N/A |
| Best AI score at launch | 15% (GPT-4 + plugins) | 14.41% (GPT-4 agent) | 1.9% (GPT-4o with browsing) | <50% (GPT-4o) |
| Best AI score 2025-2026 | ~94% (test set, Nov 2026)[3] | ~68% (Claude Mythos Preview)[13] | 86.9% (Claude Mythos Preview, Apr 2026)[31] | ~99% on tau2-bench telecom (Claude Opus 4.6) |
| Framework sensitivity | High (~30 point scaffold effect) | Moderate | Low | Moderate |
| Contamination risk | Validation set high; test set low | Moderate (confirmed answer leakage Apr 2026) | Low | Low |
WebArena
WebArena (arXiv:2307.13854, ICLR 2024) evaluates agents on 812 long-horizon web navigation tasks across five realistic simulated websites: an e-commerce platform, a social forum, a collaborative software development site, a content management system, and a map application.[7] Tasks require an agent to interpret a natural language instruction and then complete it entirely through browser interactions, without any privileged API access.[7]
WebArena tests a different capability profile than GAIA: it emphasizes sequential browser control and multi-page navigation rather than multimodal file handling or numerical reasoning. The original best result was 14.41% (GPT-4 agent), and the human baseline was 78.24%.[7] By 2025, specialized browser-control agents had pushed performance above 60%, with the best results in early 2026 reaching around 68%.
The key distinction is that WebArena is primarily a web interaction benchmark: the information needed to complete most tasks is available on the simulated websites, and success depends on correctly navigating menus, forms, and links. GAIA questions require working with the open internet and diverse file types, and many questions require synthesis across multiple heterogeneous sources rather than navigation of a single coherent website.
BrowseComp
BrowseComp was released by OpenAI in April 2025 (arXiv:2504.12516) and contains 1,266 questions designed to measure an agent's ability to locate hard-to-find information on the live internet.[8][17] Questions were verified to require multiple search iterations, to have answers not available on the first pages of search results, and to be genuinely difficult enough that an experienced human researcher could not solve them in ten minutes.[8]
BrowseComp is substantially harder than GAIA on the specific capability of deep web research: while GAIA Level 3 questions are the hardest general-assistant questions in the benchmark, BrowseComp questions are designed so that even Deep Research, which scored 67.36% on the GAIA validation set, achieved only 51.5% on BrowseComp at launch.[8][17][29] The benchmark is specialized: it measures information-retrieval depth rather than the full range of file handling, numerical reasoning, and multimodal analysis that GAIA covers. A system could theoretically score very well on BrowseComp and poorly on GAIA's file-heavy Level 2 questions, or vice versa.
The baseline AI performance on BrowseComp was near zero at launch: GPT-4o with browsing achieved 1.9%, highlighting that standard browsing capability and advanced research capability are very different things.[8][17]
Tau-bench
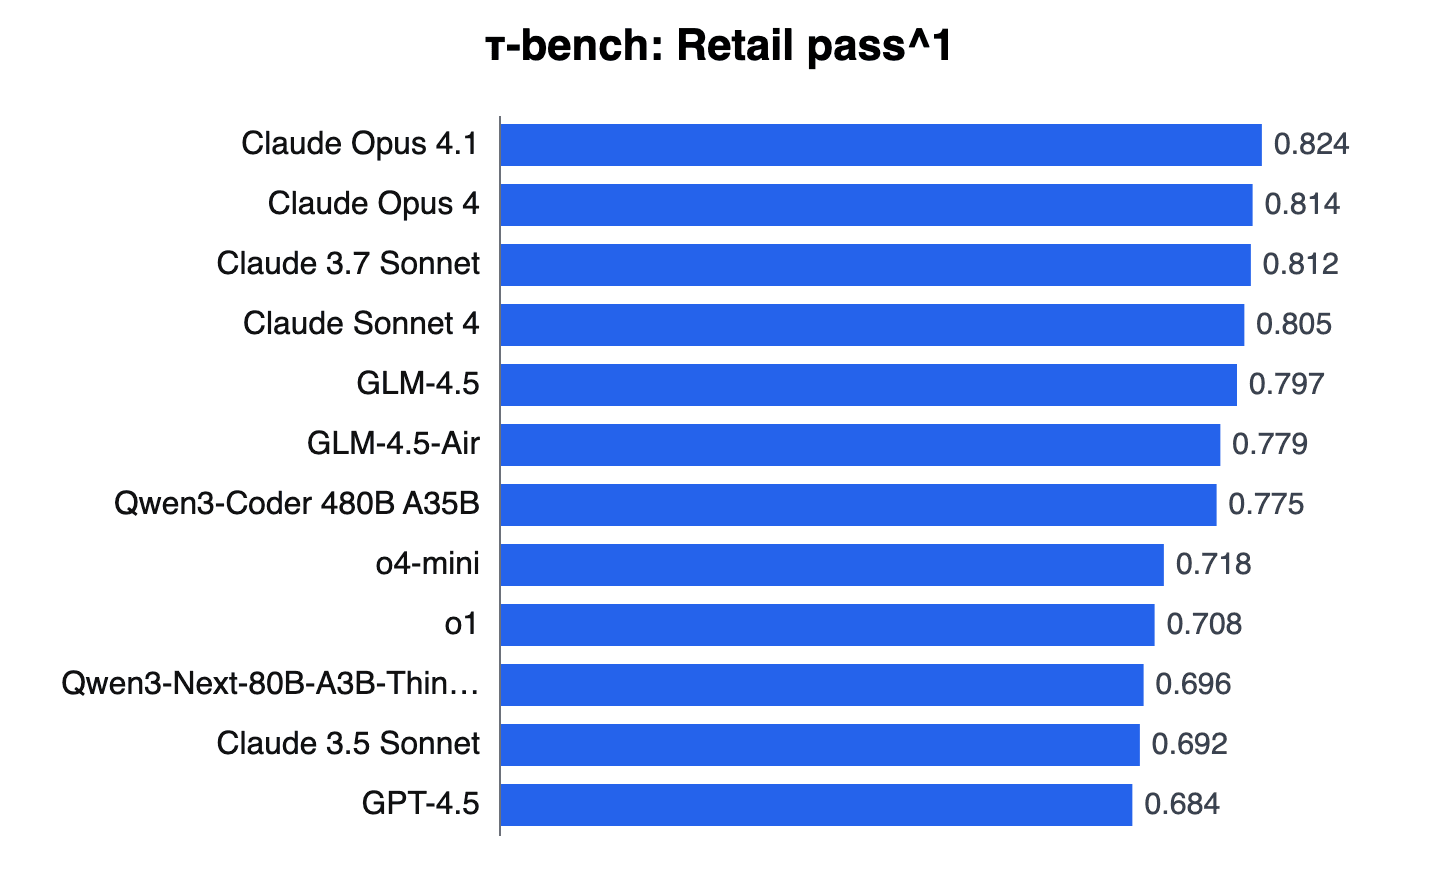
Tau-bench (tau-bench, arXiv:2406.12045) was published by Sierra AI in June 2024 and measures a fundamentally different dimension: the ability of an AI agent to interact with a simulated human user while following domain-specific policies and using designated tool APIs.[9][18] The benchmark simulates customer service interactions in retail and airline domains, where an agent must complete a user's request by calling the right tools, adhering to complex policy rules (such as return windows and cancellation fees), and maintaining coherence across a multi-turn conversation.[9]
The core metric is pass^k, which asks: out of k independent runs of the same task, how many does the agent complete correctly?[9] This measures reliability and consistency, not just peak accuracy on a single attempt. GPT-4o, a strong baseline, scores below 50% on individual tasks and less than 25% on pass^8 in the retail domain, meaning that even when the agent succeeds on a given task in isolation, it fails to do so reliably across multiple independent attempts.[9]
Tau-bench is narrower in scope than GAIA (enterprise service rather than general assistant tasks) but more demanding on the reliability axis. A GAIA question is answered once; a Tau-bench task must be completed reliably across repeated trials. The two benchmarks are complementary: GAIA is a better measure of breadth and tool diversity, while Tau-bench is a better measure of policy adherence and operational reliability in constrained domains.
SWE-bench
SWE-bench measures AI performance on a different kind of task: resolving real GitHub issues in open-source Python repositories by modifying code and passing hidden test suites. While GAIA tests a general assistant on diverse real-world tasks, SWE-bench tests a software engineering agent on a specific, technically deep task type. The two benchmarks are not in competition; practitioners typically use both to separately evaluate general assistant capability and coding agent capability.
Has GAIA been saturated?
By early 2026, GAIA had reached a state that commentators described as effective saturation.[13] The top test-set scores hovered at 92.36% overall, with Level 1 at 98.92% and Level 2 above 90%.[3] Level 3, originally designed as the impossible-for-AI tier, had moved to between 85% and 90% for the leading systems.[3] The remaining headroom was small enough that further improvements were as likely to reflect quirks of evaluation harness behavior, retry policies, or validation set contamination as they were to reflect underlying capability gains.
Several observations crystallized as the benchmark approached saturation. The question-level error patterns of the leading systems were no longer correlated with question difficulty as judged by the original level labels: top systems missed roughly the same questions across submissions, and those questions tended to be ones with ambiguous ground truth, unstable web sources, or unusual answer formatting that defeated the exact-match scorer. Cost-normalized leaderboards, including the Princeton HAL accuracy-versus-cost view, became more informative than raw accuracy for practitioners deciding on a production architecture.[5] Together, these factors motivated the GAIA team to release the successor benchmark, GAIA2, in September 2025.[19][20]
What is GAIA2, and how does it differ from GAIA?
In September 2025, Thomas Scialom, Grégoire Mialon, and collaborators at Meta and Hugging Face released GAIA2, the successor benchmark designed to address the limitations of the original.[19][20] The associated paper, "Gaia2: Benchmarking LLM Agents on Dynamic and Asynchronous Environments" (arXiv:2602.11964), was published in early 2026 and presented at ICLR 2026.[19] GAIA2 is hosted within Meta's open-source Agents Research Environments (ARE) platform, which provides the execution sandbox for both running and developing the benchmark.[20][22]
Design changes from GAIA
GAIA2 differs from the original in five fundamental ways. First, it replaces static questions over the open web with a closed sandbox environment that mocks the apps a smartphone user would interact with daily: email, calendar, messaging, contacts, a shopping app, a file system, and a chat interface to the agent itself.[19][20] This removes the dependence on live web pages that can change or disappear.
Second, GAIA2 introduces asynchronous events that occur in the environment regardless of agent actions.[19] New emails arrive, calendar invitations appear, contacts update their availability, and the agent must handle these dynamic events while completing its primary task.[19] The original GAIA evaluated an agent's ability to find an answer; GAIA2 evaluates its ability to operate in a world that does not pause to wait for it.
Third, each scenario in GAIA2 is paired with a write-action verifier rather than relying on exact-match on a final answer string.[19][20] The verifier checks every state-changing action the agent takes (such as sending an email or creating a calendar event) against oracle annotations.[19] This makes GAIA2 directly usable for Reinforcement Learning from Verifiable Rewards (RLVR), allowing developers to train agents against the benchmark rather than only evaluating them on it.[19]
Fourth, GAIA2 substantially expands scale: 1,120 human-annotated scenarios in the full benchmark, with a 160-scenario subset called GAIA2-mini for rapid iteration.[19][20] This is roughly 2.4 times the size of the original GAIA's 466-question pool.
Fifth, GAIA2 explicitly tests multi-agent collaboration in some scenarios, where the evaluation agent must communicate with other simulated agents to complete its task.[19] This dimension was absent from the original GAIA and reflects the increased prominence of multi-agent systems in 2025-era agentic AI.
Initial GAIA2 leaderboard
The initial GAIA2 leaderboard, published with the September 2025 release, showed scores far lower than late-stage GAIA scores, restoring the kind of dynamic range the original GAIA had at launch.[20][21] GPT-5 with high reasoning reached the strongest overall score of approximately 42% pass@1, well below human performance estimates.[19][20] Claude 4 Sonnet traded accuracy and speed for cost, while Kimi K2 led the open-source category at approximately 21% pass@1.[19] The pattern of results echoed the original GAIA launch, where even the best AI systems scored a fraction of human performance.
A particularly informative finding was that all leading models failed disproportionately on time-sensitive tasks where the environment evolved during the agent's response.[19][20] The asynchronous design successfully exposed a capability gap that the original GAIA, with its static questions, had been unable to measure.
Adoption and licensing
GAIA2 is released under a Creative Commons BY 4.0 license, and the ARE execution platform is under an MIT license.[20][22] The combination is permissive: developers can use both for commercial and research purposes without restriction. Within weeks of release, the GAIA2 maintainers had added results for further models, including DeepSeek V3.1 Terminus, Qwen3 235B in thinking mode and GPT-OSS 120B.[21] The original GAIA leaderboard remains active and continues to receive submissions, primarily for backward comparison purposes, while GAIA2 is treated as the more meaningful current evaluation for serious agentic AI work.[3]
Limitations
Validation set contamination
The 166 validation questions and their answers are publicly available and have been widely scraped, discussed, and incorporated into model training pipelines.[4] By 2025, models reporting impressive validation set scores faced reasonable suspicion of having been exposed to the answers during training or fine-tuning, even without deliberate benchmark overfitting. The authors acknowledged this risk in the original paper, but the open nature of the validation set is inherent to its usefulness as a development tool.[1] The test set provides a more reliable signal, and it is where most leaderboard submissions go: by November 2026 the public results file listed about 4,100 test-set entries against fewer than 100 validation-set entries.[3]
Framework effect
GAIA scores depend heavily on the agent scaffolding used to run the underlying model.[5] The same model can produce results that differ by 20 to 30 percentage points depending on whether it is wrapped in a simple tool-use loop, a sophisticated multi-agent planner, or a purpose-built GAIA-optimized framework.[5] This makes model-to-model comparisons using different scaffolding nearly meaningless. The Princeton HAL leaderboard was created precisely to address this by holding scaffolding constant, but most public leaderboard entries still use proprietary, heterogeneous frameworks.[5]
The practical implication is that a vendor claiming a state-of-the-art GAIA score may be reporting the combined effect of a strong model and an aggressive scaffolding effort, while a competitor's headline number may reflect a weaker scaffold around a stronger model. Without controlled comparison, the public leaderboard rewards engineering investment in the harness more than capability of the underlying model.
Static evaluation
GAIA questions were written in 2023. Some questions reference websites, documents, or facts that may have changed or become unavailable.[1] The benchmark relies on live web access for many questions, meaning that a question about the contents of a webpage could become unanswerable if the page is modified or removed. The organizers periodically review and replace problematic questions, but this maintenance burden is ongoing.
Reward hacking
In April 2026, researchers from UC Berkeley's Center for Responsible, Decentralized Intelligence demonstrated that automated scanning agents could exploit evaluation harness weaknesses to achieve near-perfect scores on multiple major agent benchmarks including GAIA without solving the underlying tasks. On GAIA, a submit-your-answers leaderboard with no sandboxed execution, their agent scored about 98% on the 165 validation questions by exploiting the publicly available answers and collisions in the answer normalizer.[30]
Narrow human baseline
The 92% human baseline was established with a population of annotators most commonly aged 26 to 35 (39%), 57% male, with 61% holding bachelor's degrees and 43% holding advanced degrees.[1] This demographic is not representative of the general human population, and the performance gap between AI and a broader population baseline might be somewhat smaller. The benchmark is also limited to English, which restricts its applicability as a measure of general AI assistant capability across languages.[1]
Coverage gaps
GAIA does not evaluate some capabilities that are important for real-world AI assistants, including multi-turn dialogue, long-horizon memory across sessions, tasks that require modifying state in external systems, and tasks that require negotiation or persuasion. All questions have unique, deterministic answers, which excludes the open-ended generation and subjective judgment tasks that occupy a large fraction of real assistant workloads.[1] GAIA2 explicitly addresses several of these gaps through its asynchronous environment and write-action verifiers, but the original GAIA is structurally unable to measure them.[19]
Industry impact
Establishing a common signal
Before GAIA, there was no widely accepted benchmark for evaluating general-purpose AI assistants on diverse, real-world tasks. MMLU tested knowledge but not tool use. AgentBench tested agents in closed environments that did not reflect open web interaction. GAIA filled this gap and quickly became the de facto standard for AI assistant evaluation, particularly as agentic AI systems became a competitive product category in 2024 and 2025.[12][14]
Major announcements in the agentic AI space began routinely citing GAIA scores. OpenAI reported Deep Research results on GAIA alongside its launch.[29] Manus made GAIA a centerpiece of its technical evaluation.[15] H2O.ai announced its leaderboard position as a marketing milestone.[10][11] The benchmark's adoption as a standard signal validated the research team's original design choices: short factoid answers, a held-out test set, and three difficulty levels proved tractable enough to evaluate quickly but rich enough to differentiate systems meaningfully.
Shifting benchmark philosophy
GAIA influenced the design of subsequent benchmarks by demonstrating that a small, curated set of hard questions could be more informative than a large set of easy ones. The 466 questions in GAIA provide more diagnostic signal than the 15,000 items in MMLU because each GAIA question requires a unique tool-use path that is harder to game through data contamination or prompt engineering.[1]
The benchmark also contributed to a broader recognition in the research community that AI evaluation needed to move beyond static knowledge tests toward dynamic, tool-grounded assessments. BrowseComp, released in 2025, cited GAIA among earlier information-retrieval benchmarks that recent models had saturated and set out to make web research harder.[8] Tau-bench extended the GAIA philosophy of "tasks humans do routinely" into enterprise service contexts.[9] GAIA2 took the next logical step by replacing static question answering with execution in a dynamic environment, completing the trajectory from "can the model retrieve an answer" to "can the agent operate in a live world" that the original GAIA had begun.[19]
Influence on agent development
The GAIA leaderboard created competitive pressure that accelerated investment in agent capabilities. The large performance gap between Level 1 and Level 3 at launch (30.3% vs. 0% for the best 2023 system) gave developers a clear roadmap: first solve the easy cases, then improve multi-step planning, then tackle long-horizon reasoning.[1] Progress on GAIA through 2024 and 2025 tracked closely with the development of more sophisticated agent frameworks incorporating persistent memory, better tool orchestration, and multi-agent delegation.
The benchmark's emphasis on multimodal file handling also pushed agent developers to build more robust PDF parsing, image understanding, and spreadsheet processing capabilities. Many real-world AI assistant tasks involve structured or semi-structured files, and GAIA's inclusion of these modalities made clear that a text-only agent would be fundamentally limited.
A second-order effect was the standardization of evaluation harnesses. The HAL Generalist framework from Princeton, the Inspect Evals harness from the UK AI Security Institute, and Hugging Face's smolagents reference scaffolds all emerged in part as reactions to GAIA's high framework sensitivity, providing reproducible ways to run a model on the benchmark and gradually reducing scaffold-driven variance in published comparisons.[5][28]
Continue reading
- Benchmark (AI)In artificial intelligence and machine learning, a benchmark is a specified evaluation used to compare systems under common conditions.Mentioned 44 times above
- Hugging FaceHugging Face is an artificial intelligence company and collaboration platform for machine learning.Mentioned 13 times above
- τ-benchτ-bench (Tau-bench), short for Tool-Agent-User Interaction Benchmark, is an AI benchmark that evaluates language agents' ability to complete complex tasks through realistic, multi-turn interactions with…Mentioned 8 times above
- Deep ResearchDeep Research is a category of AI agent products that perform multi-step web research to produce comprehensive, citation-backed analytical reportsMentioned 8 times above
- WebArenaWebArena is a realistic, self-hosted web environment and benchmark designed for developing and evaluating autonomous AI agents that perform tasks on the web.Mentioned 5 times above
- Agentic AIAgentic AI is an umbrella term for artificial intelligence systems that pursue a user-specified objective through a sequence of decisions and actions.Mentioned 5 times above
More from See also
More to read
Topics:AI AgentsAI Benchmarks
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32 ^33 ^34 ^35 ^36 ^37 ^38 ^39 ^40 ^41Mialon, G., Fourrier, C., Swift, C., Wolf, T., LeCun, Y., and Scialom, T. "GAIA: a benchmark for General AI Assistants." arXiv:2311.12983, November 21, 2023. arxiv.org/...2311.12983
- ^1 ^2GAIA benchmark paper, ICLR 2024 proceedings. proceedings.iclr.cc/...3e405ec-Abstract-Conference
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17GAIA Leaderboard, Hugging Face. huggingface.co/...leaderboard
- ^1 ^2 ^3 ^4GAIA dataset, Hugging Face. huggingface.co/...GAIA
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12HAL GAIA Leaderboard, Princeton University. hal.cs.princeton.edu/gaia
- ar5iv HTML rendering of GAIA paper. ar5iv.labs.arxiv.org/...2311.12983
- ^1 ^2 ^3Zhou, S. et al. "WebArena: A Realistic Web Environment for Building Autonomous Agents." arXiv:2307.13854, 2023. arxiv.org/...2307.13854
- ^1 ^2 ^3 ^4 ^5Wei, J. et al. "BrowseComp: A Simple Yet Challenging Benchmark for Browsing Agents." arXiv:2504.12516, April 2025. arxiv.org/...2504.12516
- ^1 ^2 ^3 ^4 ^5Yao, S. et al. "tau-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains." arXiv:2406.12045, June 2024. arxiv.org/...2406.12045
- ^H2O.ai. "H2O.ai Tops GAIA Leaderboard: A New Era of AI Agents." 2024. h2o.ai/...h2o-ai-tops-gaia-leaderboard
- ^1 ^2H2O.ai. "H2O.ai Tops the General AI Assistant (GAIA) Test." 2025. h2o.ai/...h2o-ai-tops-the-general-ai-assistant-test
- ^Arduin.io. "GAIA benchmark overview." arduin.io/...gaia-overview
- ^1 ^2 ^3Rapid Claw. "AI Agent Benchmarks 2026: SWE-bench, GAIA, and Beyond." rapidclaw.dev/...ai-agent-benchmarks-2026
- ^VentureBeat. "The GAIA benchmark: Next-gen AI faces off against real-world challenges." venturebeat.com/...f-against-real-world-challenges
- ^1 ^2 ^3Charly Wargnier (@DataChaz). X post on Genspark vs. Manus vs. OpenAI DeepResearch on GAIA, April 2025. x.com/...1915329740183044407
- IBM Research. "Introducing CUGA: The enterprise-ready configurable generalist agent." research.ibm.com/...cuga-agent-framework
- ^1 ^2 ^3OpenAI. "BrowseComp: a benchmark for browsing agents." openai.com/...browsecomp
- ^Sierra AI. "tau-Bench: Benchmarking AI agents for the real-world." sierra.ai/...benchmarking-ai-agents
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17Froger, R. et al. "Gaia2: Benchmarking LLM Agents on Dynamic and Asynchronous Environments." arXiv:2602.11964, early 2026. arxiv.org/...2602.11964
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10Hugging Face. "Gaia2 and ARE: Empowering the community to study agents." Hugging Face blog, September 2025. huggingface.co/...gaia2
- ^1 ^2Hugging Face. "Gaia2 Leaderboard Update: New Models and New Observations." huggingface.co/...gaia2-new-models-evaluation
- ^1 ^2Meta Agents Research Environments documentation. facebookresearch.github.io/...benchmarking
- ^1 ^2 ^3OpenAI. "Introducing ChatGPT agent: bridging research and action." July 17, 2025. openai.com/...introducing-chatgpt-agent
- ^1 ^2TechCrunch. "OpenAI launches a general purpose agent in ChatGPT." July 17, 2025. techcrunch.com/...general-purpose-agent-in-chatgpt
- ^Hugging Face. "smolagents: a smol library to build agents." Hugging Face blog, December 2024. huggingface.co/...smolagents
- Steel.dev GAIA Leaderboard. leaderboard.steel.dev/...gaia
- BenchLM GAIA snapshot. benchlm.ai/...gaia
- ^UK AI Security Institute. "GAIA evaluation in Inspect Evals." ukgovernmentbeis.github.io/...gaia
- ^1 ^2 ^3OpenAI. "Introducing deep research." February 2, 2025. openai.com/...introducing-deep-research
- ^Wang, H., Mang, Q., Cheung, A., Sen, K., and Song, D. "How We Broke Top AI Agent Benchmarks: And What Comes Next." Berkeley RDI, April 2026. rdi.berkeley.edu/...trustworthy-benchmarks-cont
- ^Anthropic. "Project Glasswing." April 2026. anthropic.com/glasswing
- ^Roucher, A. and Petrov, S. "Our Transformers Code Agent beats the GAIA benchmark." Hugging Face blog, July 1, 2024. huggingface.co/...beating-gaia
- ^Hugging Face. "Open-source DeepResearch: Freeing our search agents." Hugging Face blog, February 2025. huggingface.co/...open-deep-research
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
8 revisions · v8 · 6,763 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (170 claims, 31 sources fetched); 22 material + 28 minor fixed
Cite this page: AI Wiki. "GAIA benchmark." aiwiki.ai, updated 22 Jun 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/gaia_benchmark