

AIME 2025
| AIME 2025 | |
|---|---|
| Overview | |
| Full name | American Invitational Mathematics Examination 2025 |
| Abbreviation | AIME 2025 |
| Description | A challenging mathematical reasoning benchmark based on the American Invitational Mathematics Examination 2025 problems, testing olympiad-level mathematical reasoning with complex multi-step problem solving |
| AIME I date | 2025-02-06 |
| AIME II date | 2025-02-12 |
| Latest version | 1.0 |
| Authors | Mathematical Association of America |
| Organization | Mathematical Association of America (MAA), Art of Problem Solving (AoPS) |
| Technical Details | |
| Type | Mathematical Reasoning, Olympiad Mathematics |
| Modality | Text |
| Task format | Open-ended problem solving (integer answer 000 to 999) |
| Number of tasks | 30 (15 from AIME I, 15 from AIME II) |
| Total examples | 30 |
| Evaluation metric | Exact match, pass@1, cons@8, cons@64, avg@n |
| Domains | Algebra, Geometry, Number Theory, Combinatorics, Probability |
| Languages | English |
| Performance | |
| Human performance | 26.67% to 40% (4 to 6 problems correct per 15) |
| Baseline | ~20% (non-reasoning models) |
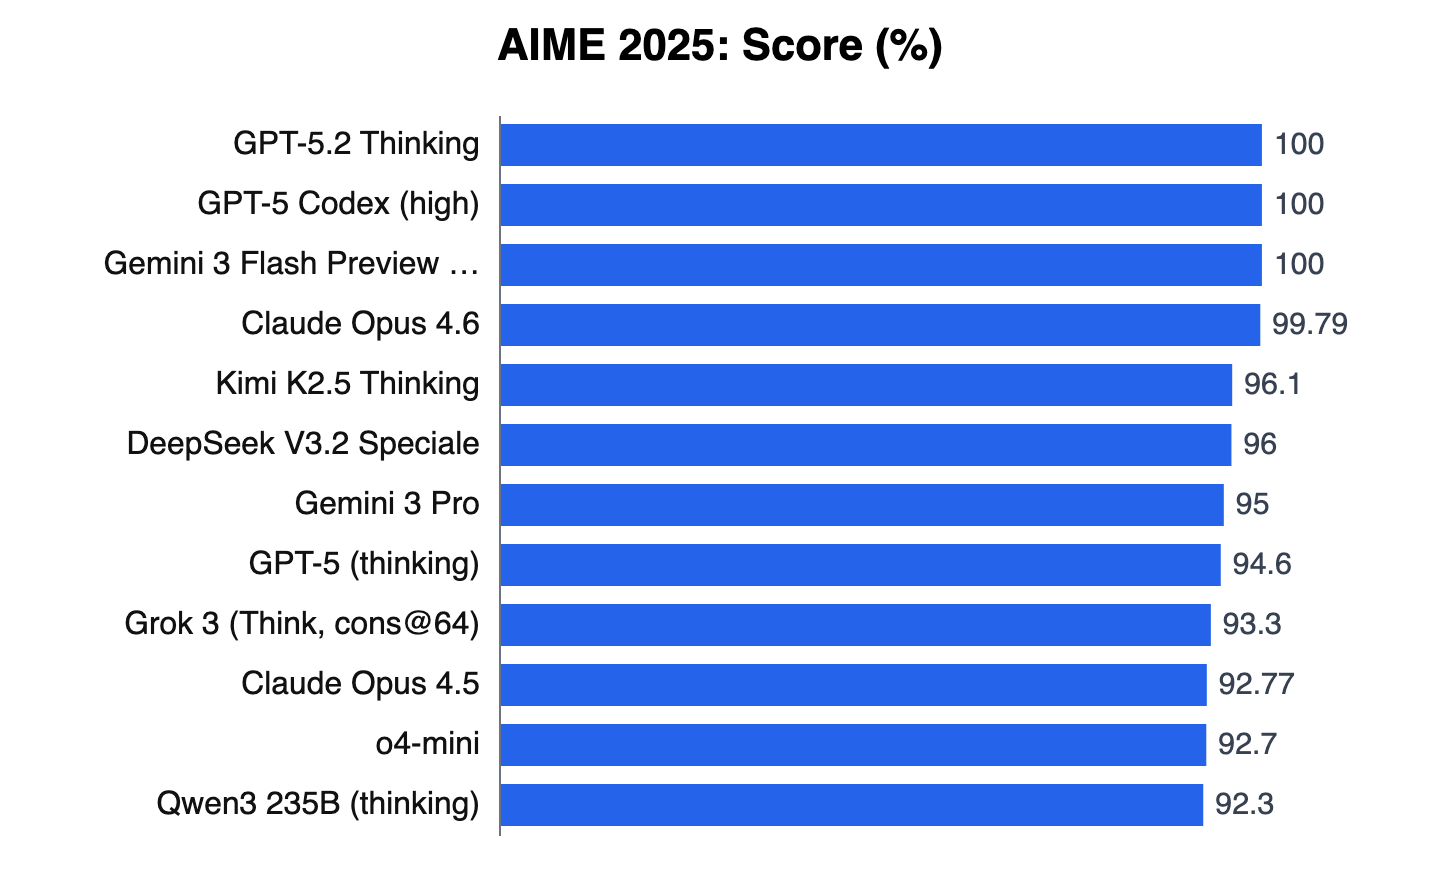
| SOTA score (no tools) | 100% (GPT-5.2 Thinking and other frontier models); Claude Opus 4.6 99.79%[1][2] |
| SOTA score (with Python) | 100% (numerous models since late 2025) |
| SOTA model | Multiple models tied at the ceiling |
| SOTA date | 2026-05 |
| Saturated | Yes, effectively saturated at the frontier |
| Resources | |
| Website | Official MAA AIME page |
| AoPS Wiki (AIME I) | 2025 AIME I problems |
| AoPS Wiki (AIME II) | 2025 AIME II problems |
| Dataset (HF) | MathArena/aime_2025 |
| Live leaderboard | MathArena, Artificial Analysis |
| Successor | AIME 2026 |
| Predecessor | AIME 2024 |
AIME 2025 is a 30-problem mathematical reasoning AI benchmark built from the 2025 American Invitational Mathematics Examination, a high school olympiad track contest run by the Mathematical Association of America (MAA).[3] It became one of the most-cited reasoning tests of 2025 because nearly every frontier model released before February 2025 had a strong claim to never having seen the problems, and by May 2026 it is effectively saturated: top systems from OpenAI, Anthropic, Google DeepMind, Moonshot AI, DeepSeek, and xAI score within about one problem of a perfect 30 out of 30.[8] The 2025 edition was administered in two sittings: AIME I on Thursday, February 6, 2025, and AIME II on Wednesday, February 12, 2025.[4][5] Each paper contains 15 problems with integer answers in the range 000 to 999, giving 30 problems in total. Within hours of each test window closing, research labs and independent evaluators began running frontier language models on the fresh problems, turning the contest into one of the most closely watched mathematical reasoning benchmarks of 2025 and 2026.[6]
The benchmark gained traction quickly because it offered something rare: a hard, well calibrated set of problems that nearly every major model released before February 2025 had a strong claim to never having seen. That made it a useful counterpoint to AIME 2024, where contamination of pretraining corpora became a serious concern after researchers showed model scores fell by 10 to 20 points compared with held out 2025 problems.[7]
By mid 2026, AIME 2025 has reached a different stage of its lifecycle. The benchmark is effectively saturated at the frontier: by May 2026, models from OpenAI, Anthropic, Google DeepMind, Moonshot AI, DeepSeek, and xAI score within about one problem of a perfect 30 out of 30, often within statistical noise of one another.[8] The contest that once separated reasoning models from non reasoning ones is now used mostly as a regression sanity check rather than as a frontier ranking tool. Even so, the leaderboard has become an artefact of how a benchmark goes from useful to saturated in roughly fifteen months.
What is AIME 2025?
AIME 2025 evaluates how well a large language model can carry out structured multi step mathematical reasoning under tight constraints. Problems require pre calculus mathematics across algebra, geometry, number theory, combinatorics, and probability, and increase in difficulty across each 15 problem set. There is no partial credit; the model either produces the correct integer or it does not.
For humans, AIME is the gateway between the AMC 10 / AMC 12 and the USA Math Olympiad. Typical AIME qualifiers solve about 4 to 6 of the 15 problems per paper, putting human performance between 26.67% and 40% on a single sitting. A non reasoning model that knows textbook techniques but cannot reason carefully tends to land around 20%. The qualifying floor for the United States of America Mathematical Olympiad (USAMO) is set against the AIME each year, and the same problem distribution that gates a few hundred students into a national olympiad now gates frontier model releases into a press cycle.[3]
Why did it become the math benchmark of 2025?
For most of 2024, the math benchmark of choice was AIME 2024 paired with MATH 500 and GSM8K. By late 2024, the top reasoning models from OpenAI and DeepSeek were posting scores above 80% on AIME 2024 and above 95% on MATH 500, and the field needed something that was not yet partly memorized. AIME 2025 fit the brief: it was hard, it shared the same answer format that researchers had already built tooling around, and the training cutoffs of leading models (including DeepSeek R1, o3 mini, and Claude 3.7 Sonnet) all sat before February 6, 2025.[9]
The other useful thing about AIME 2025 was political. The contest is run by the MAA, an independent organization, rather than by any of the labs being evaluated, which made it harder for any one company to cherry pick the questions where their model did well. Because every paper is graded by the MAA's own answer key, scoring is mechanical and disputes are limited to whether a sample produced the correct boxed integer.
How did AIME 2025 become saturated?
Saturation arrived faster than most observers expected. In February 2025, o3 mini high was the leader at 86.5% pass@1.[10] By April, o3 and o4 mini had pushed the frontier past 90%.[10] By the August 2025 launch of GPT-5, OpenAI reported 94.6% without tools for GPT-5 with thinking (99.6% with Python).[11] By November 2025, Anthropic's Claude Opus 4.5 was reporting 92.77% closed book and 100% with Python.[12] In February 2026, Anthropic reported Claude Opus 4.6 at 99.79% (avg@5) closed book, while explicitly flagging that this score may be contamination-inflated.[13] By Q1 2026, major reasoning launches from xAI, Moonshot AI, DeepSeek, and Anthropic that reported AIME 2025 were at or near the ceiling. The result is that AIME 2025 has shifted from a frontier ranker to a smoke test: a model that fails to score above 90% in 2026 is, almost by definition, not a reasoning model.
Exam structure and dataset
The 30 problem dataset combines both AIME papers and is the version most leaderboards report against. Some early evaluations reported only the 15 problems from AIME I because they were run on February 7, before AIME II was administered.[14]
| Item | AIME I | AIME II |
|---|---|---|
| Date administered | February 6, 2025 | February 12, 2025 |
| Number of problems | 15 | 15 |
| Time limit (humans) | 3 hours | 3 hours |
| Answer format | Integer 000 to 999 | Integer 000 to 999 |
| Calculator policy | None permitted | None permitted |
The MAA publishes the official problems and answer keys after each sitting. The Art of Problem Solving community then writes up multiple solutions per problem, which is one of the ways the problems eventually leak into web crawls.[4][5]
Coverage by mathematical domain
| Domain | Example topics |
|---|---|
| Algebra | Polynomial and functional equations, inequalities, sequences |
| Geometry | Euclidean and coordinate geometry, transformations, 3D solids |
| Number theory | Divisibility, modular arithmetic, Diophantine equations |
| Combinatorics and probability | Counting, expected values, generating functions |
| Trigonometry / complex numbers | Identities, roots of unity |
Problem level topic breakdown
A useful way to read AIME 2025 model failures is by topic. The two papers cover a fairly standard distribution, with later problems weighted toward combinatorics, geometry, and synthesis problems that combine two or more subareas. The table below summarizes which topics appear at which problem positions.
| Problem position | AIME I 2025 topic | AIME II 2025 topic |
|---|---|---|
| 1 | Number bases and factors | Triangles and areas |
| 2 | Areas and similar triangles | Polynomial factoring |
| 3 | Counting and arrangements | Counting and cases |
| 4 | Lattice points and quadratic formula | Logarithms and factoring |
| 5 | Divisibility rules | Circumcircles and inscribed angles |
| 6 | Cyclic quadrilaterals and tangents | Tangent circles and Pythagorean theorem |
| 7 | Probability and counting | Factors and inclusion exclusion |
| 8 | Complex numbers and circles | Greedy algorithms |
| 9 | Quadratics and symmetry | Trigonometry and tangents |
| 10 | Piecewise functions and graphing | Counting polygons and diagonals |
| 11 | Coordinate geometry | Bracketed inequalities |
| 12 | 3D surfaces and areas | Congruent triangles and law of cosines |
| 13 | Expected value and regions | Recursive sequences and modular arithmetic |
| 14 | Inequalities and cyclic quadrilaterals | Symmetry and equilateral triangles |
| 15 | Modular arithmetic | Polynomials and quadratics |
The two papers are roughly matched in difficulty, although MathArena's per problem accuracy logs show AIME II Problem 14 (a symmetry argument over equilateral triangles) and AIME I Problem 13 (an expected value calculation over a partitioned region) as the two questions on which weaker reasoning models lose the most points.[8]
How is AIME 2025 evaluated?
Different evaluators have settled on different protocols, which is part of why scores in different press releases sometimes look inconsistent.
Common metrics
| Metric | What it measures | Typical use |
|---|---|---|
| pass@1 | Single sample exact match accuracy | Default leaderboards |
| cons@8 | Majority vote across 8 samples | Reduces variance on a 30 problem set |
| cons@64 | Majority vote across 64 samples | Used in o1 and Grok 3 announcements |
| pass@k | At least one of k samples is correct | Ablations, not headline numbers |
| avg@n | Pass@1 averaged across n independent runs | Used by MathArena (n=4) and Artificial Analysis (n=10) |
Because the dataset has only 30 problems, single run pass@1 numbers are noisy. Two independent average of 5 runs can differ by 5 to 10 percentage points on the same model, which has pushed evaluators toward consistency metrics or pass@1 averaged over many runs (often 16, 32, or 50). It also explains why frontier models tend to bunch within a percentage point or two of each other; the noise is comparable to the gap. The MathArena project explicitly samples each problem four times and averages, in part to give a tighter confidence interval without exhausting model API budgets.[15]
Closed book versus tool use
The headline AIME 2025 number is usually reported closed book: the model produces a chain of thought and a final integer using only its own weights. A second mode, called tool augmented or code interpreter mode, allows the model to call out to a Python interpreter during reasoning. Tool augmented numbers tend to be 5 to 7 points higher and have pushed several frontier models to 100% on AIME 2025. By mid 2026, distinguishing the two modes has become less meaningful at the top of the leaderboard because both saturate, but the distinction still matters for mid tier and open weight models where tool use can move scores from the mid 70s into the high 80s.
Sampling settings used in research papers
| Parameter | Common setting |
|---|---|
| Temperature | 0.0 to 0.6 (often averaged) |
| Samples per question | 8, 16, 32, or 64 |
| Maximum tokens | 16K to 64K |
| Top p | 0.95 |
| Prompt format | "Please reason step by step, and put your final answer within \boxed{}" |
The \boxed{} answer convention comes from the MATH dataset, and DeepSeek documents this exact template in its DeepSeek-V3.2 report.[23] A model that ignores the \boxed{} requirement, or that emits the answer outside the box, is sometimes counted as a parse failure rather than a wrong answer, which is one reason small infrastructure differences across evaluators can swing a score by a point or two.
Reasoning budget caps
A subtler issue in 2026 is how to bound test time compute. A reasoning model that is allowed to think for 64K tokens will outscore the same model capped at 8K tokens on the harder AIME 2025 problems, sometimes by 5 to 10 points. Different leaderboards take different positions. Artificial Analysis publishes scores at the lab's default reasoning budget, while other leaderboards such as MathArena use their own settings.[15] The result is that a single model can have three different scores depending on which leaderboard is reporting it, and the gap can exceed the gap between competing labs at the same budget.
Model performance
The tables below collect publicly reported AIME 2025 results from model release blogs, third party leaderboards (Artificial Analysis, MathArena, Vellum, llm-stats, BenchLM), and arXiv reports. Because methodology varies across sources, scores within a few points should be treated as tied.
Closed book (no tool use) leaderboard, mid-2026 snapshot
| Model | Score (%) | Method | Organization | Released |
|---|---|---|---|---|
| GPT-5.2 Thinking | 100 | pass@1 | OpenAI | 2025-12[1] |
| GPT-5 Codex (high) | 100 | pass@1 | OpenAI | 2026[16] |
| Claude Opus 4.6 | 99.79 | avg@5, adaptive thinking | Anthropic | 2026-02[13] |
| GPT-5 (thinking) | 94.6 | pass@1 | OpenAI | 2025-08[11] |
| Gemini 3 Flash Preview (reasoning) | 100 | pass@1 | Google DeepMind | 2026[16] |
| Gemini 3 Pro | 95.0 | pass@1 (no tools) | Google DeepMind | 2025-11[17] |
| Kimi K2.5 Thinking | 96.1 | avg@32, 96K budget | Moonshot AI | 2026[19] |
| Kimi K2.6 | ~96 (on AIME 2026, comparable scale) | pass@1 | Moonshot AI | 2026-04[20] |
| DeepSeek V3.2 Speciale | 96.0 | pass@1 | DeepSeek | 2025-12[23] |
| Grok 4 | 91.7 | pass@1 (no tools) | xAI | 2025-07[24] |
| GPT-5 (no thinking) | 61.9 | pass@1 | OpenAI | 2025-08[11] |
| Grok 3 (Think, cons@64) | 93.3 | cons@64 | xAI | 2025-02[25] |
| o4-mini | 92.7 | pass@1 | OpenAI | 2025-04[10] |
| Claude Opus 4.5 | 92.77 | pass@1 | Anthropic | 2025-11[12] |
| Qwen3 235B (thinking) | 92.3 | pass@1 | Alibaba | 2025 |
| o3 | 88.9 | pass@1 | OpenAI | 2025-04[10] |
| DeepSeek R1 0528 | 87.5 | pass@1 | DeepSeek | 2025-05[26] |
| Claude Sonnet 4.5 | 87 | pass@1 | Anthropic | 2025-09 |
| Gemini 2.5 Pro | 86.7 | pass@1 | Google DeepMind | 2025-03 |
| o3-mini (high) | 86.5 | pass@1 | OpenAI | 2025-01 |
| Qwen3 235B A22B (original, thinking mode) | 81.5 | pass@1 | Alibaba | 2025-04 |
| Claude Opus 4 | 75.5 | pass@1 | Anthropic | 2025-05 |
| DeepSeek R1 (original) | 70.0 | pass@1 | DeepSeek | 2025-01[26] |
| o1 | 79.2 | pass@1 | OpenAI | 2024-12[10] |
| Claude 3.7 Sonnet | 52.7 | pass@1 (third-party) | Anthropic | 2025-02[9] |
| Gemini 2.0 Flash | ~45 | pass@1 | Google DeepMind | 2025-01 |
| Non reasoning baseline | ~20 | pass@1 | Various | n/a |
Tool augmented (Python interpreter) leaderboard
With access to a Python interpreter during reasoning, several models reach the ceiling of the dataset:
| Model | Score (%) | Source |
|---|---|---|
| GPT-5 Pro with Python | 100.0 | OpenAI launch blog[11] |
| Claude Opus 4.5 with Python | 100.0 | Anthropic system card[12] |
| Claude Sonnet 4.5 with Python | 100.0 | Anthropic launch announcement[32] |
| Gemini 3 Pro with code execution | 100.0 | Google launch material[17] |
| o4-mini with Python | 99.5 | OpenAI o3 / o4-mini blog[10] |
| o3 with Python | 98.4 | OpenAI o3 / o4-mini blog[10] |
Specific stories worth knowing
The Grok 3 launch was the first instance where AIME 2025 scores caused a public dispute over evaluation honesty. xAI headlined 93.3% for Grok 3 (Think), but that figure used cons@64, while OpenAI's chart for o3 mini reported pass@1. On apples to apples pass@1, Grok 3 Reasoning Beta sat below o3 mini high.[25] The episode was a useful reminder that the headline number depends on which metric a lab chooses.
DeepSeek's path was its own story. The original R1 from January 2025 scored 70.0% pass@1 by DeepSeek's later count, well below o3 mini.[26] The R1-0528 update from May 2025 jumped to 87.5%. DeepSeek credited deeper reasoning (average tokens per AIME question rose from about 12K to about 23K) along with post-training optimizations.[26] By December 2025, the DeepSeek V3.2 Speciale variant pushed open weight performance to 96%, matching the IMO 2025 gold medal benchmark on a separate set of problems with 35/42 points at the International Mathematical Olympiad.[23]
Claude 3.7 Sonnet, released the same month as AIME 2025, came in low at 52.7% in third-party testing.[9] Anthropic's strategy at the time emphasized coding and agentic tasks. The gap closed with Claude 4 Opus (75.5%), Claude Sonnet 4.5 (87%), Claude Opus 4.5 (92.77%), Claude Opus 4.6 (99.79% with contamination caveat), and Claude Opus 4.7 (released April 2026) later in 2025 and into 2026.[12][13][28] The contamination caveat, first attached to Claude Opus 4.5's score and repeated for Claude Opus 4.6's near-perfect result, is itself a milestone: the lab publicly conceded that on AIME 2025 the headline number had become unreliable enough that the model card should disclose the risk rather than hide it.
The Kimi family from Moonshot AI is the 2026 chapter of the AIME story. Kimi K2.5 Thinking, released early in 2026, posted 96.1% on a tight average@32 run with a 96K thinking budget.[19] Kimi K2.6, released on April 20, 2026, primarily pushed the coding and agentic frontier; its model card reports 96.4% on AIME 2026 and no AIME 2025 score.[20] Zhipu's GLM-5 (744B-parameter MoE, 92.7% on AIME 2026 I) and GLM-5.1 (March 27, 2026) round out the picture from Chinese open weight labs, although both report AIME 2026 rather than AIME 2025 results.[21][22] The implication is that the open weight ecosystem has now drawn level with closed frontier labs on AIME 2025 specifically, even if more general capability benchmarks remain a step behind.
Open weight progression on AIME 2025
How does AIME 2025 differ from AIME 2024?
Researchers use the gap between AIME 2024 and AIME 2025 scores as a rough contamination indicator: a model that scores noticeably higher on the older paper is suspected of having seen those problems during training. MathArena, which has evaluated more than 50 LLMs, reported that most models scored 10 to 20 points higher on AIME 2024 than their AIME 2025 results and human-difficulty calibration would predict.[15]
| Aspect | AIME 2024 | AIME 2025 |
|---|---|---|
| Frontier score (early 2025) | High 80s to mid 90s | Mid 70s to high 80s |
| Frontier score (mid 2026) | Effectively 100% across the board | At or near 100% for top tier |
| Estimated contamination | Substantial for many models | Limited, some leakage |
| Saturation (late 2025) | Effectively saturated | Approaching saturation |
| Saturation (mid 2026) | Saturated | Saturated for the frontier |
By 2026, the difference between the two contests has become largely vestigial at the top of the leaderboard. Frontier models score at the ceiling on both. The contamination signal that once made AIME 2025 the more credible benchmark of the two is now most useful for diagnosing mid tier and open weight models, where the gap between AIME 2024 and AIME 2025 still shows up. For frontier model releases, evaluators have rotated toward AIME 2026 (administered in February 2026), HMMT 2026, the Putnam 2025, and MathArena Apex, all of which retain the post training cutoff property that AIME 2025 had in early 2025.[29]
How the gap shifted across 2025 and 2026
| Model class | AIME 2024 score | AIME 2025 score | Gap |
|---|---|---|---|
| Frontier closed weight (mid 2026) | ~99-100 | ~99-100 | <1 |
| Frontier open weight (mid 2026) | ~98-100 | ~95-100 | 0-3 |
| Mid tier closed weight (mid 2026) | ~95 | ~88 | 5-7 |
| Open weight 7B class | ~85 | ~70 | 12-15 |
| Pre 2025 reasoning models | High 80s | Low 70s | 10-20 |
The pattern across rows is consistent with the contamination story: the larger and more recent the model, the smaller the AIME 2024 to 2025 gap, because newer training corpora include AIME 2025 solutions and newer models are large enough that the marginal effect of memorized problems is small.
Is AIME 2025 contaminated?
Even AIME 2025 has not been completely clean. MathArena's authors listed 8 of the 30 problems with possibly similar versions already on the public web (Quora, math.stackexchange, and similar sites), and Dimitris Papailiopoulos found an essentially identical version of Problem 1 on Quora.[6][15] That kept some risk that pre February 2025 training data still contained partial solutions or similar formulations.
The response from the evaluation community has been to move toward live benchmarks: instead of evaluating on a fixed test set indefinitely, evaluators score models only on competitions held after the model's training cutoff. The MathArena project, run by researchers at ETH Zurich's SRI Lab and INSAIT, formalized this approach with continual evaluation across AIME, HMMT, the Putnam, and the IMO.[15] Its authors describe the core idea plainly: "By evaluating models as soon as new problems are released, we effectively eliminate the risk of contamination," the same paper that reports "strong signs of contamination in AIME 2024."[15] A separate effort at vals.ai ran the same idea with a public leaderboard.
The practical workflow most labs adopted for AIME 2025 was to fetch the official problem PDFs the morning after each sitting, run frozen pre announcement checkpoints, and publish results within 48 to 72 hours, before the problems could plausibly enter any retraining cycle.
What contamination actually looks like at the model level
Contamination is not a single phenomenon. It comes in at least three flavors that affect AIME 2025 differently:
- Direct memorization. The model produces the answer with a chain of thought that is verbatim or near verbatim from an Art of Problem Solving solution thread. This is rare for AIME 2025 because the solutions were not yet on the web during most training cutoffs, but it is endemic on AIME 2024.
- Distributional contamination. The model has not seen the exact problem, but has seen many problems by the same authors, in the same year's contest style, or scraped from official answer keys. Evidence for this on AIME 2025 is weak but not zero.
- Tool augmented leakage. The model is allowed to retrieve from the web or to call a code interpreter and finds the official solution online. Frontier evaluators block this by running tool augmented evaluations in sandboxed environments without internet access.
MathArena's contamination audit on AIME 2025 includes a per problem table indicating which of the 30 problems were flagged as potentially leaked.
Anthropic's contamination disclosure on Claude Opus 4.6
A specific episode worth flagging is the February 2026 release of Claude Opus 4.6. Its system card reported 99.79% on AIME 2025 (avg@5, adaptive thinking, max effort) but added that "we have some concerns that contamination may have inflated this score," repeating a caveat first attached to Claude Opus 4.5 and a rare acknowledgment from a frontier lab that a flagship benchmark number should not be read at face value.[13] The disclosure is now widely cited as the cleanest signal that AIME 2025 has crossed from a useful frontier benchmark into a number that primarily measures saturation effects rather than reasoning capability.
Limitations
AIME 2025 is useful, not perfect. Several limitations are worth keeping in mind:
- Thirty problems is enough to separate weak from strong models, but not enough to rank similar frontier models with confidence; pass@1 variance on a single run can swing 5 to 10 points.
- Answer only scoring means a model can guess the correct integer for the wrong reasons, especially in combinatorics where the answer space is small.
- All problems and reasoning are in English, limiting usefulness for multilingual evaluation.
- Problems do not require calculus or graduate level mathematics, so scores say almost nothing about research math. For that, evaluators look at FrontierMath, the USAMO, or the IMO grand challenge.
- Test time compute is a confounder: two models with the same final score can be using radically different amounts of compute per problem.
- Saturation has eliminated the benchmark's discriminative power at the frontier. By 2026, any model that fails AIME 2025 is unambiguously below the reasoning bar, but passing it no longer establishes that a model is at the frontier.
- Differences in reasoning budget caps can swing scores by 5 to 10 points even when methodology is otherwise identical, which is a continuing source of noise across leaderboards.
- The benchmark is also licensed CC BY-NC-SA 4.0 on Hugging Face, which restricts some commercial reuse of the curated MathArena release even though the underlying MAA problems are widely reproduced.[14]
Impact on AI development
AIME 2025 has shaped how frontier labs talk about reasoning. By mid 2025, the AIME 2025 number had become a near required disclosure in any major reasoning model release, alongside GPQA Diamond, HumanEval, and the MMLU. The reproducible lift from longer reasoning chains helped popularize the test time compute paradigm that defines o3, DeepSeek R1, and their successors. cons@k metrics pushed multi sample voting into product features in Claude, Gemini, and ChatGPT. The contamination story reinforced the case for held out evaluation sets and motivated continual benchmarks like MathArena.[15] Open source projects (DeepSeek R1 Distill, OpenThinker, AM Thinking, and various Qwen and Llama based distillations) have used AIME 2025 as their primary external yardstick for reasoning capability transfer.
What replaced AIME 2025 at the frontier
By 2026, the practical replacement for AIME 2025 at the top of leaderboards has been a portfolio rather than a single benchmark:
- AIME 2026, administered in February 2026, is the natural successor for any model released after early 2026.[29] Model cards report Kimi K2.6 at 96.4%, GLM-5 at 95.4%, and GPT-5.4 (xhigh) at 99.2%.[20][22]
- HMMT 2026, the Harvard MIT Math Tournament from February 2026, gives a parallel data point at a similar difficulty.
- The Putnam 2025, an undergraduate competition with proof style problems graded by an LLM judge, separates models that AIME 2025 cannot.
- MathArena Apex, an aggregated leaderboard that selects 2025 competition problems on which at least one frontier model failed, has become the headline metric for reasoning research.[31]
- The IMO 2025 grand challenge, where DeepSeek V3.2 Speciale and a handful of other systems reached gold medal performance (35/42 points), is the current frontier marker for olympiad mathematics.[23]
The shift to a portfolio rather than a single contest matters because it reduces the risk that any one paper becomes the proxy for math reasoning the way AIME 2024 once did. AIME 2025 in this story is the inflection point: it was the last single contest whose pass@1 score was treated as a credible standalone reasoning benchmark, and the move to portfolios was a direct response to its saturation.
Cost and compute considerations
A separate impact has been on how much compute labs spend on a single benchmark run. By mid 2026, a single AIME 2025 evaluation at a 32-sample budget can cost between five and twenty US dollars in API tokens for a frontier model, and substantially more for tool augmented runs with extended thinking. That cost has not been a barrier for established labs, but it has shaped the design of cheaper continuous evaluation pipelines, where models are sampled four times rather than thirty two and the resulting confidence intervals are wider but the cost is order of magnitude lower.
Recent developments (April-May 2026)
The April to May 2026 window has been mostly about open weight catch up rather than new frontier movement on AIME 2025 itself:
- April 20, 2026: Moonshot AI released Kimi K2.6, a 1T-parameter MoE focused on coding and agentic capabilities; it reported 96.4% on AIME 2026 rather than an AIME 2025 score.[20]
- April 16, 2026: Anthropic released Claude Opus 4.7, the successor to Opus 4.6; its announcement did not report an AIME 2025 score.[28]
- February 19, 2026: Google DeepMind launched Gemini 3.1 Pro in preview. Google's published evaluation table for the model does not include AIME 2025.[18]
- March 27, 2026: Zhipu released GLM-5.1, an incremental upgrade over GLM-5 that improved coding and reasoning without materially shifting the AIME 2025 ceiling.[22]
- May 2026: Artificial Analysis's AIME 2025 page, by then a legacy benchmark it had dropped from its Intelligence Index in January 2026, listed GPT-5.2 (xhigh), GPT-5 Codex (high), and Gemini 3 Flash Preview (reasoning) tied at the ceiling.[16] The leaderboard has effectively become a multi-way tie at the top, with discrimination between frontier systems now occurring on AIME 2026, MathArena Apex, and the IMO and Putnam evaluations.
Related benchmarks
- AIME 2024: predecessor, now widely considered contaminated for most pre 2025 models.
- MATH: 12,500 problem dataset spanning multiple difficulty levels.
- GSM8K: grade school math word problems, effectively saturated.
- GPQA Diamond: PhD level science multiple choice questions.
- HMMT: Harvard MIT Math Tournament problems, run alongside AIME 2025 in MathArena.
- USAMO: USA Math Olympiad, proof based and substantially harder than AIME.
- FrontierMath: research level mathematics designed to remain unsaturated.
Continue reading
- Reasoning modelsReasoning models are large language models that are post-trained or configured to spend additional inference-time computation on intermediate steps before returning an answer.Mentioned 5 times above
- GSOGSO (short for Global Software Optimization in the project page subtitle, and Challenging Software Optimization Tasks for Evaluating SWE-Agents in the paper title) is an artificial intelligence benchmark for…Listed in See also
- Vimgolfvimgolf-gym is an OpenAI Gym style customizable environment and benchmark built around VimGolf, the long running keystroke counting puzzle game for Vim.Listed in See also
- WeirdMLWeirdML is a benchmark for evaluating how well large language models can do hands on machine learning engineering.Listed in See also
- AA-LCRAA-LCR (Artificial Analysis Long Context Reasoning) is a benchmark for large language models that evaluates the ability to reason across multiple real-world documents totalling approximately 100,000 tokens per…Listed in See also
- ERQAERQA (Embodied Reasoning Question Answering) is a multimodal benchmark released by Google DeepMind in March 2025 to evaluate the embodied reasoning capabilities of vision-language models (VLMs) on robotics…Listed in See also
More from See also
More to read
Topics:AI Benchmarks
References
- ^1 ^2Vellum AI. "GPT-5.2 Benchmarks (Explained)." vellum.ai/blog/gpt-5-2-benchmarks.
- ^Anthropic. "Claude Opus 4.6 System Card." February 2026. anthropic.com.
- ^1 ^2Mathematical Association of America. "AIME (American Invitational Mathematics Examination)." maa.org/maa-invitational-competitions.
- ^1 ^2Art of Problem Solving. "2025 AIME I." artofproblemsolving.com/wiki/index.php/2025_AIME_I.
- ^1 ^2Art of Problem Solving. "2025 AIME II." artofproblemsolving.com/wiki/index.php/2025_AIME_II.
- ^1 ^2Papailiopoulos, D. "AIME I 2025: A Cautionary Tale About Math Benchmarks and Data Contamination." x.com/DimitrisPapail/status/1888325914603516214, February 2025.
- ^Balunovic, M., Jovanovic, N., et al. "MathArena: Evaluating LLMs on Uncontaminated Math Competitions." arXiv:2505.23281, 2025.
- ^1 ^2 ^3MathArena. "AIME 2025 dataset and leaderboard." matharena.ai/?comp=aime--aime_2025.
- ^1 ^2 ^3 ^4IntuitionLabs. "AIME 2025 Benchmark: An Analysis of AI Math Reasoning." intuitionlabs.ai.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7OpenAI. "Introducing OpenAI o3 and o4-mini." April 2025. openai.com/index/introducing-o3-and-o4-mini.
- ^1 ^2 ^3 ^4OpenAI. "Introducing GPT-5." August 2025. openai.com/index/introducing-gpt-5.
- ^1 ^2 ^3 ^4Anthropic. "Claude Opus 4.5 system card." November 2025. anthropic.com/claude-opus-4-5-system-card.
- ^1 ^2 ^3 ^4Anthropic. "Claude Opus 4.6 System Card." February 2026. anthropic.com.
- ^1 ^2Hugging Face. "MathArena/aime_2025 Dataset." huggingface.co/datasets/MathArena/aime_2025.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Balunovic, M., Jovanovic, N., et al. "MathArena: Evaluating LLMs on Uncontaminated Math Competitions." arXiv:2505.23281, 2025. arxiv.org/abs/2505.23281.
- ^1 ^2 ^3Artificial Analysis. "AIME 2025 Benchmark Leaderboard." artificialanalysis.ai/evaluations/aime-2025.
- ^1 ^2Google DeepMind. "Gemini 3 Pro launch notes." 2025. blog.google.
- ^Google. "Gemini 3.1 Pro: A smarter model for your most complex tasks." February 2026. blog.google/innovation-and-ai/models-and-research/gemini-models/gemini-3-1-pro/.
- ^1 ^2 ^3Moonshot AI. "Kimi K2.5 Thinking technical report." 2026. moonshot.ai.
- ^1 ^2 ^3 ^4Moonshot AI. "Kimi K2.6 model card." April 20, 2026. huggingface.co/moonshotai/Kimi-K2.6.
- ^Zhipu AI. "GLM-5 release." 2026. huggingface.co/zai-org/GLM-5.
- ^1 ^2 ^3Zhipu AI. "GLM-5.1 release." March 27, 2026. huggingface.co/zai-org/GLM-5.1.
- ^1 ^2 ^3 ^4 ^5DeepSeek AI. "DeepSeek-V3.2: Pushing the Frontier of Open Large Language Models." arXiv:2512.02556, December 2025.
- ^xAI. "Grok 4 Heavy benchmark report." 2025. x.ai.
- ^1 ^2xAI. "Grok 3 Beta: The Age of Reasoning Agents." February 2025. x.ai.
- ^1 ^2 ^3 ^4 ^5 ^6DeepSeek AI. "DeepSeek-R1-0528 model card." Hugging Face, May 2025.
- DeepSeek AI. "DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning." arXiv:2501.12948, January 2025.
- ^1 ^2Anthropic. "Claude Opus 4.7 release announcement." April 2026. anthropic.com/claude/opus.
- ^1 ^2Hugging Face. "MathArena/aime_2026 Dataset." huggingface.co/datasets/MathArena/aime_2026.
- MathArena. "AIME 2025 contamination audit." matharena.ai.
- ^MathArena. "Apex aggregated reasoning leaderboard." matharena.ai/?comp=apex--apex_2025.
- ^Anthropic. "Introducing Claude Sonnet 4.5." September 2025. anthropic.com/news/claude-sonnet-4-5.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
13 revisions · v13 · 5,621 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (150 claims, 34 sources fetched); 28 material + 21 minor fixed
Cite this page: AI Wiki. "AIME 2025." aiwiki.ai, updated 28 Oct 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/aime_2025