

AIME 2024
AIME 2024 is an AI benchmark of 30 problems drawn from the 2024 American Invitational Mathematics Examination that has become the standard yardstick for measuring the mathematical reasoning of large language models such as OpenAI o1, o3, and DeepSeek R1.[1][3] Each problem has an integer answer between 0 and 999, the competition was originally written by the Mathematical Association of America for top high school mathematicians in the United States, and the 30 questions combine the 15 problems of AIME I with the 15 of AIME II.[1][2] Because the answer space is small, the questions resist guessing, and the problems demand layered reasoning, AIME 2024 became one of the most cited tests of mathematical reasoning ability for reasoning models released in late 2024 and 2025.[3] By 2026 the benchmark is widely considered saturated: most frontier reasoning models score above 90% and leaderboards such as BenchLM now display it for reference only rather than ranking on it.[15][29]
| AIME 2024 | |
|---|---|
| Overview | |
| Full name | American Invitational Mathematics Examination 2024 |
| Abbreviation | AIME 2024 |
| Description | A challenging mathematical reasoning benchmark based on the American Invitational Mathematics Examination 2024 problems, designed to evaluate AI models' ability to solve complex high school mathematics problems requiring multi-step reasoning |
| Release date | 2024-02-01 |
| Latest version | 1.0 |
| Benchmark updated | 2024-02-07 |
| Authors | Mathematical Association of America |
| Organization | Mathematical Association of America (MAA), Art of Problem Solving (AoPS) |
| Technical Details | |
| Type | Mathematical Reasoning, Problem Solving |
| Modality | Text |
| Task format | Open-ended problem solving |
| Number of tasks | 30 (15 from AIME I + 15 from AIME II) |
| Total examples | 30 |
| Evaluation metric | Exact Match, Pass@1, Cons@N |
| Domains | Algebra, Geometry, Number Theory, Combinatorics, Probability |
| Languages | English |
| Performance | |
| Human performance | ~33% (median 2024 AIME score was 5 of 15) |
| Baseline | ~12% (GPT-4o pass@1) |
| SOTA score | 95.8% (Grok 3 Mini, cons@64) |
| SOTA model | Grok 3 Mini (xAI) |
| SOTA date | 2025-02-17 |
| Saturated | Yes (top reasoning models exceed 90%) |
| Resources | |
| Website | Official website |
| GitHub | Repository |
| Dataset | Download |
| Predecessor | AIME 2023 |
| Successor | AIME 2025 |
What is AIME 2024 and what is it used for?
The AIME 2024 benchmark is built on the 2024 cycle of the American Invitational Mathematics Examination, an invitational round of the AMC competition series. For the 2024 cycle, AIME invitations went to at least the top 2.5% of AMC 10 scorers and at least the top 5% of AMC 12 scorers; for 2027 the MAA switched to fixed score thresholds.[1] Strong AIME performance is the gateway to the USA Mathematical Olympiad (USAMO) and USA Junior Mathematical Olympiad (USAJMO), and the index used for those competitions combines AMC and AIME scores.
The AIME 2024 problems were administered in two sittings: AIME I on January 31 to February 1, 2024, and AIME II on February 7, 2024.[2] Each sitting contains 15 problems and runs for three hours, scored 1 point per correct answer with no penalty for wrong or blank answers, so a perfect score is 15 per form and 30 across both.[2] After the contest closed, the problems and full solutions were posted publicly through the Art of Problem Solving wiki and other community archives, which is exactly why AIME 2024 became a popular target for AI researchers, and also why later contamination concerns emerged.[12]
The machine-readable benchmark most often used in papers is the Hugging Face dataset published by Maxwell Jia, which packages the 30 official problems with reference answers in JSON Lines format.[11] Several alternative packagings exist, including HuggingFaceH4/aime_2024 and math-ai/aime24, but they all wrap the same 30 MAA problems. Some early evaluations, including OpenAI's blog post for o1, reported results as the average number of problems solved per 15-problem exam (for example 11.1/15) rather than out of all 30 problems, which is one source of confusion when comparing scores across papers.[3]
A note on the problem 12 erratum
The official MAA answer for AIME I 2024 Problem 12 was listed as 384 in the official MAA answer portal right after the contest, although the correct answer is 385, as the Areteem Institute noted on February 2, 2024.[20] The Maxwell-Jia dataset uses 385.[11] Any evaluation script that copied the early 384 key would mark correct answers to this problem as wrong.
Why did AIME 2024 become an LLM benchmark?
A few features made AIME 2024 the right shape for evaluating reasoning models:
- Integer answers from 0 to 999: the model either writes the correct integer or it does not, which makes grading cheap and reproducible.
- No partial credit, no negative marking: a clean exact-match metric.
- Hard but bounded math: every problem is solvable from a high school curriculum, but the later items demand creative combinations of algebra, number theory, geometry, and combinatorics. That is the level where pre-2024 base models like GPT-4o consistently failed and where chain-of-thought training started to pay off.[3]
- Small, well-known dataset: only 30 problems, easy to run and inspect.
- Public reference solutions: makes detailed error analysis straightforward, not just final accuracy.
Technical specifications
Problem format
Each AIME 2024 problem requires the model to output a single integer between 000 and 999. Problems are presented as plain text and may include LaTeX. Common task patterns include:
- Counting and probability questions where the answer is the numerator plus denominator of a reduced fraction.
- Geometry problems where the answer is some integer length, area, or sum of unknowns.
- Number theory problems asking for a specific residue, sum of digits, or count of solutions.
- Algebra problems where the answer is a coefficient, a polynomial value at a point, or the sum m+n where the original answer is m/n.
The difficulty curve is steep. Problems 1 to 5 are typically tractable for an experienced AMC solver. Problems 11 to 15 frequently require nonobvious construction or clever invariants and are roughly USAMO entry difficulty. Problem 15 on AIME I 2024, for example, required setting up surface-area equations with Vieta's relations on a degree-three polynomial.[20]
How is AIME 2024 scored for LLMs?
The benchmark is run in several ways depending on the paper:
| Evaluation method | Description | Implementation |
|---|---|---|
| Exact match | Model output must equal the ground truth integer | Final answer extracted from \boxed{} or last line of model output |
| Pass@1 (greedy) | Single deterministic attempt | Temperature 0, no sampling |
| Pass@1 (averaged) | Average correctness across many samples | Common setup is 64 samples per problem with temperature 0.6 and top-p 0.95 |
| Cons@N (consensus) | Majority vote over N samples | Often N=64; reduces variance from sampling |
| Best-of-N | Re-rank N samples with a learned scorer | Used by OpenAI for the 93% o1 result with N=1000 |
| Tool-augmented | Model can call a Python interpreter | Pushes scores to ~99-100% on frontier models |
DeepSeek's R1 paper, for example, fixes temperature to 0.6, top-p to 0.95, and reports pass@1 averaged over 64 sampled responses, which is now a common reference setup.[6] Models are usually prompted with something close to: "Please reason step by step, and put your final answer within \boxed{}."
Because there are only 30 problems, single-run scores have high variance. A model that gets 24 right one run and 21 right the next has shifted by 10 percentage points without any change in capability. That is why most credible scores either average over many seeds or report cons@N.
Tool-augmented evaluations
By 2025 it became standard to publish two AIME numbers for any model that supports tool use: pure reasoning (no tools) and with a Python interpreter. Giving a frontier reasoning model a Python sandbox typically pushes AIME accuracy to ~99-100%: OpenAI reported 99.5% pass@1 for o4-mini and Anthropic reported 100% for Claude Opus 4.5 on AIME 2025 with Python.[4][30] At OpenAI's GPT-5 launch, the "Pro" variant with parallel test-time compute and tool use reportedly solved 100% of the AIME 2025 set, and similar numbers are routine on the older 2024 problems. These open-book results have shifted attention away from AIME as a pure reasoning yardstick and toward benchmarks like FrontierMath, HMMT, and USAMO 2025 where tool use is either disallowed or not enough.[29]
Performance analysis
Which models report AIME 2024 scores?
The table below collects widely-cited AIME 2024 scores from primary sources. Where scores were originally reported as problems solved per 15-problem exam (as in OpenAI's September 2024 blog post), that is noted in the methodology column.
| Model | AIME 2024 score | Methodology | Source / date |
|---|---|---|---|
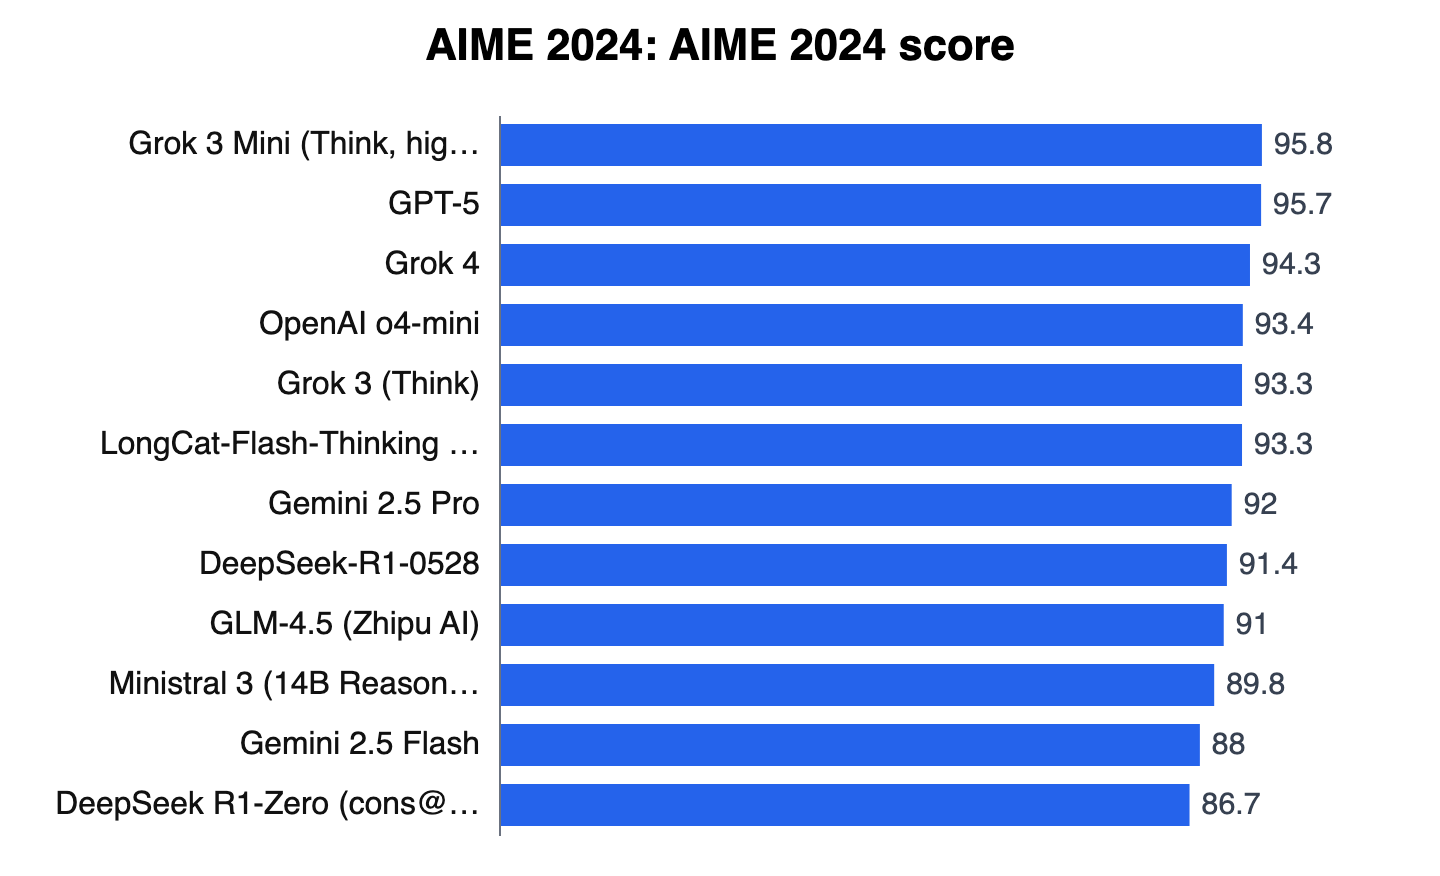
| GPT-5 | 95.7% | independent evaluation | Artificial Analysis (via Price Per Token), 2026[25] |
| Grok 3 Mini (Think, high) | 95.8% | cons@64, test-time compute scaling | xAI, February 2025[9] |
| Grok 4 | 94.3% | independent evaluation | Artificial Analysis (via Price Per Token), 2026[25] |
| OpenAI o4-mini | 93.4% | pass@1, no tools | OpenAI, April 2025[4] |
| Grok 3 (Think) | 93.3% | cons@64 | xAI, February 2025[9] |
| LongCat-Flash-Thinking (Meituan) | 93.3% | self-reported | Meituan, 2025[15] |
| OpenAI o1 (re-ranked) | 93% (13.9/15) | re-ranking 1000 samples, average per 15-problem exam | OpenAI, September 2024[3] |
| Gemini 2.5 Pro | 92.0% | pass@1 | Google DeepMind, March 2025[10] |
| OpenAI o3 | 91.6% (96.7% in the December 2024 preview announcement) | pass@1 | OpenAI, April 2025[4][26] |
| DeepSeek-R1-0528 | 91.4% | pass@1 | DeepSeek, May 2025[23] |
| GLM-4.5 (Zhipu AI) | 91.0% | self-reported | Zhipu AI, 2025[15] |
| Ministral 3 (14B Reasoning) | 89.8% | self-reported | Mistral AI, 2025[15] |
| Gemini 2.5 Flash | 88.0% | pass@1 | Google, 2025[15] |
| OpenAI o3-mini (high) | 87.3% (83.6% in the January 2025 launch post) | pass@1 | OpenAI, April 2025[4][5] |
| DeepSeek R1-Zero (cons@64) | 86.7% | majority vote over 64 samples | DeepSeek, January 2025[6] |
| DeepSeek R1 Distill Llama 70B | 86.7% | cons@64 (70.0% pass@1) | DeepSeek, 2025[15] |
| Qwen3-235B-A22B | 85.7% | self-reported | Alibaba, 2025[15] |
| OpenAI o1-pro | 86.0% | pass@1 | OpenAI, 2025[15] |
| OpenAI o1 (cons@64) | 83% (12.5/15) | consensus among 64 samples | OpenAI, September 2024[3] |
| Claude 3.7 Sonnet (extended thinking) | 80.0% | parallel extended thinking, 64K token budget | Anthropic, February 2025[7] |
| DeepSeek R1 | 79.8% | pass@1 averaged over 64 samples | DeepSeek paper, January 2025[6] |
| QwQ-32B (Alibaba) | 79.5% | pass@1 averaged | Alibaba, March 2025[16] |
| OpenAI o1 (single sample) | 74.4% | pass@1 (11.1/15 per exam in the blog post) | OpenAI, September 2024[3] |
| Gemini 2.0 Flash Thinking | 73.3% | pass@1 (Exp 01-21 version) | Google, January 2025[18] |
| OpenAI o1-mini | 63.6% | pass@1 averaged | DeepSeek paper / OpenAI[6] |
| Grok 3 (base, non-reasoning) | 52.2% | pass@1 | xAI, February 2025[9] |
| Gemini 2.0 Flash (experimental) | 35.5% | pass@1 | Google, December 2024[18] |
| Claude 3.7 Sonnet (standard mode) | 23.3% | pass@1, no extended thinking | Anthropic, February 2025[7] |
| Gemini 1.5 Pro | 19.3% | pass@1 | Google, 2024[18] |
| GPT-4o | ~12% (1.8/15) | average per 15-problem exam | OpenAI, September 2024[3] |
| Claude 3.5 Sonnet | 10.0% (16.0% for the October 2024 version) | single run, June 2024 version | UK AI Security Institute Inspect Evals; DeepSeek paper[17][6] |
A few notes on this table:
- The 93% o1 number that OpenAI publicized in September 2024 used best-of-1000 with a learned re-ranker, not a single sample. OpenAI's own report states that "o1 averaged 74% (11.1/15) with a single sample per problem, 83% (12.5/15) with consensus among 64 samples, and 93% (13.9/15) when re-ranking 1000 samples with a learned scoring function" on the 2024 AIME exams, scored per 15-problem exam, so press coverage that cited 93% as a single-shot score conflated three very different methodologies.[3]
- The DeepSeek R1 paper reports 79.8% pass@1 averaged over 64 samples, slightly above OpenAI o1-1217's 79.2% on the same setup, which is the headline that pushed R1 into the news cycle in January 2025.[6]
- Grok 3 Mini's 95.8% sits at the top of public AIME 2024 leaderboards through 2025, but it relies on cons@64 with very large test-time compute. At pass@1 the figures from xAI's own announcement are noticeably lower.[9]
- In Artificial Analysis's independent runs, GPT-5 (95.7%), Grok 4 (94.3%) and o4-mini (94.0%) sit within two points of each other near the ceiling, with o3 at 90.3%, which is one of the strongest single signals that the benchmark has effectively saturated.[25]
- With a Python interpreter enabled, o4-mini and Claude Opus 4.5 report 99.5% and 100% respectively on AIME 2025, so the table above intentionally excludes tool-augmented runs to keep comparisons apples-to-apples.[4][30]
How do reasoning models differ from base models on AIME 2024?
The most striking pattern in the table is the gap between reasoning-trained models and conventional chat models. GPT-4o and Claude 3.5 Sonnet score roughly 9 to 16% on AIME 2024, depending on version and harness.[6] Models trained with reinforcement learning on chains of thought, including OpenAI o1, DeepSeek R1, and Claude 3.7 Sonnet with extended thinking, jumped to 70-90%+. The same Claude 3.7 Sonnet weights score 23.3% in standard mode, 61.3% with a 64K-token extended thinking budget, and 80.0% with parallel test-time compute, which is the cleanest demonstration of how much of the gain comes from inference-time reasoning rather than raw capability.[7][8] OpenAI's o1 blog also reports a roughly log-linear scaling relationship between accuracy and test-time compute on AIME, a pattern most labs have since adopted in their evaluation reports.[3] Reading OpenAI's o1 compute charts, Toby Ord estimated that 100x more test-time compute lifts AIME accuracy from roughly 20% to 80%, while 100x more RL training compute only moves it from about 33% to 66%, indicating inference scaling is the larger lever on this dataset.[27]
Open-source progress
AIME 2024 has been the headline number for nearly every open-weight reasoning model release in 2025-2026. The fast-moving open-weight stack of late 2025 - DeepSeek-R1-0528 at 91.4%, Qwen3-235B-A22B at 85.7%, GLM-4.5 at 91.0%, MiniMax M1 at 86.0%, LongCat-Flash-Thinking at 93.3%, and the Ministral 3 reasoning family - has effectively closed the AIME 2024 gap with proprietary frontier models, even if it has not closed the gap on more contamination-resistant benchmarks like AIME 2025 or FrontierMath.[15][23] DeepSeek's R1-0528 release notes list AIME 2024 rising from 79.8% to 91.4%, and highlight AIME 2025 rising from 70% to 87.5% as the average reasoning length per AIME question nearly doubled from about 12K to 23K tokens.[23]
Human comparison
Separating model scores from human performance is messier than people often present. AIME is taken only by AMC qualifiers, so the typical AIME taker is already strong:
- The official MAA statistics for 2024 give an AIME I mean score of 5.89 (median 5) and an AIME II mean of 5.45 (median 5) out of 15 problems.[2]
- The median 2024 AIME score was therefore 5 problems out of 15 (about 33%), with means of roughly 36-39%.
- USAMO qualification typically requires a USAMO index where the AIME contribution is 9 or higher.
- The very top scorers, perfect or near-perfect, are a tiny tail of the distribution, on the order of a few hundred students nationally per year.
When OpenAI said o1's 93% (13.9/15) result "places it among the top 500 students nationally," that comparison rested on a best-of-1000 re-ranked score expressed per 15-problem exam, not a single-sample score on the combined 30-problem dataset most papers use today.[3]
Mathematical domains covered
The AIME 2024 benchmark tests proficiency across the standard secondary math contest domains:
| Domain | Example topics | Approximate share of problems |
|---|---|---|
| Algebra | Polynomial equations, systems, inequalities, sequences | ~27% |
| Geometry | Euclidean geometry, coordinate geometry, transformations | ~27% |
| Number theory | Divisibility, modular arithmetic, primes, Diophantine | ~20% |
| Combinatorics | Counting, probability, recursion | ~20% |
| Complex numbers | Roots of unity, complex algebra | ~6% |
Topic boundaries are fuzzy. A typical AIME 12 problem might mix coordinate geometry with number theory and a touch of combinatorics, and many problems are deliberately built so that the obvious approach is intractable and a clever observation cuts the work down. The published Areteem and AoPS solution sets for AIME I 2024 cover precisely these blended patterns: AIME I Problem 3 is a game-theory/modular arithmetic mash-up, Problem 10 mixes circle geometry with Stewart's theorem, Problem 14 is a 3D volume calculation, and Problem 15 reduces to applying Vieta's formulas to an unknown polynomial.[20]
Limitations and considerations
Is AIME 2024 contaminated?
Data contamination is the largest caveat hanging over AIME 2024 as a benchmark. The 2024 problems were posted in full, with detailed solutions, on the Art of Problem Solving wiki and elsewhere within hours of the contest. By the time models were trained or fine-tuned in late 2024 and 2025, those pages were almost certainly part of the public web crawls feeding pretraining and instruction tuning datasets.
Researchers building MathArena, a contamination-resistant evaluation framework, found strong signs of contamination on AIME 2024.[12] They report finding "strong signs of contamination in AIME 2024": most models scored 10-20% above the level their results on the newer AIME 2025 would predict, and QwQ-32B-Preview outperformed its expected human-aligned performance by nearly 60%, the most extreme contamination signal in the paper.[12]
A separate 2025 study, VAR-MATH, released VAR-AIME24, which turns the fixed numeric constants in each AIME 2024 problem into symbolic parameters and requires a model to solve several instantiations, to test whether models actually solve the problem or recall the answer. Under its strict metric, frontier models such as o4-mini-high, DeepSeek-R1-0528 and Qwen3-235B-A22B drop about 13-15 points, while small RL-tuned 7B and 32B models lose roughly 27-73% of their original score, suggesting they were memorizing surface form more than reasoning to a solution.[28]
The usual remedy now is to evaluate on AIME 2025, which is administered after the cutoff for most current models, in addition to AIME 2024. When a model that scored 90% on AIME 2024 drops to 75% on AIME 2025, that gap is a useful contamination signal even if neither score is perfectly clean.[12]
Statistical noise
Thirty problems is a small sample. A single problem worth 1 of 30 is 3.3% of the score. A model that solves 24 problems correctly scores 80%, but its true skill could plausibly produce anywhere between 22 and 26 on a different draw of similarly hard problems. Confidence intervals on AIME 2024 scores are wide, which is part of why pass@1 averaged over 64 samples and cons@64 are now the standard reporting modes.[6][17] A 2025 Stanford study of inference-time scaling found that spreading samples across several temperatures adds about 7.3 points over single-temperature test-time scaling, averaged over four small Qwen3 models and five benchmarks including AIME 2024 and AIME 2025: yet another non-capability lever that can shift headline AIME numbers.[24]
Limited coverage
AIME 2024 only tests one style of math: short-answer, integer-output, contest-flavored problems. It says nothing about whether a model can write a real proof, formalize an argument in Lean, or do open-ended exploration of a research-style question. Benchmarks like the USAMO, Putnam competitions, FrontierMath, and Humanity's Last Exam are designed to fill those gaps.
Saturation and benchmark deprecation
By 2026 some public leaderboards had stopped using AIME 2024 in their rankings. BenchLM, for example, shows AIME 2024 scores "for reference" but does not rank on them, and its weighted math score draws instead on newer sets such as AIME 2026, HMMT February 2026, USAMO 2026 and FrontierMath.[29] Lab reports moved the same way: Anthropic's Claude Opus 4.5 system card reports AIME 2025 (92.77% without tools, 100% with Python) and does not report AIME 2024.[30]
How does AIME 2024 differ from AIME 2025?
AIME 2024 and AIME 2025 share an identical structure, 30 integer-answer problems split across two forms, but they differ in the one dimension that matters most for benchmarking: training-data exposure. The 2024 problems had been on the public web for more than a year before most 2025-2026 models finished pretraining, while the 2025 problems were released in February 2025, after the knowledge cutoff of many of those models.[12] In practice this means AIME 2024 scores tend to run higher and less reliable, and a large drop from AIME 2024 to AIME 2025 for the same model is read as a contamination signal rather than a genuine difference in problem difficulty.[12] Most 2025-2026 model cards now report both numbers side by side for this reason.
Related benchmarks
AIME 2024 sits inside a broader ecosystem of mathematical reasoning benchmarks that AI researchers run alongside it:
- AIME 2025: the follow-up benchmark using the 2025 contest problems, less affected by training data contamination.
- MATH: the original 12,500-problem dataset of high school competition math, now considered partially saturated by frontier reasoning models.
- MATH-500: a 500-problem subset of MATH commonly reported alongside AIME.
- GSM8K: 8,000 grade school word problems, long since saturated by capable LLMs.
- GPQA Diamond: graduate-level science questions including mathematics.
- HMMT: the Harvard-MIT Mathematics Tournament, also used in MathArena.
- FrontierMath: research-level math problems designed to be much harder and more contamination resistant.
- Putnam: undergraduate competition mathematics, used for college-level evaluations.
- USAMO 2025: proof-based competition for the very top US math students, now a fresh evaluation target as well.
- MathArena: an evaluation framework that uses competitions held after each model's release to control for contamination.
Impact and significance
AIME 2024 is probably the single benchmark most responsible for the 2024-2025 reasoning model wave entering public consciousness. The September 2024 OpenAI o1 announcement leaned on AIME 2024 as its headline reasoning result, which set the framing that DeepSeek directly attacked four months later when R1 matched o1's score at a fraction of the inference cost.[3][6] Anthropic, Google, and xAI followed with their own reasoning launches, and AIME 2024 was on every comparison chart.[7][9][10]
The benchmark also accelerated two reporting habits. First, test-time compute became a first-class axis: almost every 2025 reasoning model release included a chart of accuracy against thinking budget, with AIME 2024 the most common dataset for that x-axis.[3][16] Second, cons@N and best-of-N now appear alongside pass@1 in most releases, since 30 problems and large test-time budgets together make any single number too noisy. For education, contamination concerns mean current AIME 2024 scores probably overstate how well frontier models reason on truly novel contest problems, and the more sobering AIME 2025 numbers tend to support that.[12] In 2026 the benchmark functions less as a frontier yardstick than as a baseline floor for new reasoning models.[15]
Continue reading
- Benchmark (AI)In artificial intelligence and machine learning, a benchmark is a specified evaluation used to compare systems under common conditions.Mentioned 22 times above
- Test-time computeTest-time compute (also called inference-time compute scaling or test-time scaling) is the practice of allocating additional computation while a large language model answers a queryMentioned 7 times above
- MathArenaMathArena is a public, continuously updated leaderboard and evaluation platform that measures the performance of large language models on mathematics competition problems released after each model's training…Mentioned 3 times above
- Chain-of-ThoughtChain-of-thought (CoT) is a sequence of intermediate steps that a language model generates before its final answer.Listed in See also
- Mathematical reasoning in AIin AIListed in See also
- DeepSeek-R1DeepSeek-R1 is an open-weight reasoning model and large language model family developed by the Chinese artificial intelligence laboratory DeepSeek. The original model was released on January 20, 2025.Mentioned 10 times above
More from See also
More to read
Topics:AI Benchmarks
References
- ^1 ^2 ^3Mathematical Association of America. "MAA Invitational Competitions." maa.org/maa-invitational-competitions
- ^1 ^2 ^3 ^4Wikipedia. "American Invitational Mathematics Examination." en.wikipedia.org/...tional_Mathematics_Examination
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13OpenAI. "Learning to reason with LLMs." September 12, 2024. openai.com/...learning-to-reason-with-llms
- ^1 ^2 ^3 ^4 ^5OpenAI. "Introducing OpenAI o3 and o4-mini." April 16, 2025. openai.com/...introducing-o3-and-o4-mini
- ^OpenAI. "OpenAI o3-mini." January 31, 2025. openai.com/...openai-o3-mini
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9DeepSeek-AI et al. "DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning." arXiv:2501.12948. January 2025. arxiv.org/...2501.12948v1
- ^1 ^2 ^3 ^4Anthropic. "Claude 3.7 Sonnet and Claude Code." February 24, 2025. anthropic.com/...claude-3-7-sonnet
- ^Anthropic. "Claude's extended thinking." 2025. anthropic.com/...visible-extended-thinking
- ^1 ^2 ^3 ^4 ^5xAI. "Grok 3 Beta: The Age of Reasoning Agents." February 17, 2025. x.ai/...grok-3
- ^1 ^2Google DeepMind. "Gemini 2.5: Our newest Gemini model with thinking." March 25, 2025. blog.google/...i-model-thinking-updates-march-2025
- ^1 ^2Maxwell-Jia. "AIME 2024 dataset." Hugging Face. huggingface.co/...AIME_2024
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Balunović et al. "MathArena: Evaluating LLMs on Uncontaminated Math Competitions." arXiv:2505.23281. arxiv.org/...2505.23281v2
- Vellum AI. "Analysis: OpenAI o1 vs DeepSeek R1." vellum.ai/...analysis-openai-o1-vs-deepseek-r1
- Vellum AI. "Claude 3.7 Sonnet vs OpenAI o1 vs DeepSeek R1." vellum.ai/...-7-sonnet-vs-openai-o1-vs-deepseek-r1
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10llm-stats.com. "AIME 2024 Benchmark Leaderboard." llm-stats.com/...aime-2024
- ^1 ^2Alibaba Cloud. "Alibaba Cloud Unveils QwQ-32B." alibabacloud.com/...utting-edge-performance_602039
- ^1 ^2UK AI Security Institute. "Inspect Evals: AIME 2024." ukgovernmentbeis.github.io/...aime2024
- ^1 ^2 ^3DataCamp. "Gemini 2.0 Flash Thinking Experimental: A Guide With Examples." datacamp.com/...gemini-2-0-flash-experimental
- CodeSOTA. "AIME 2024 Leaderboard." codesota.com/...aime-2024
- ^1 ^2 ^3Areteem Institute. "2024 AIME I Answer Key Released." February 2024. areteem.org/...2024-aime-i-answer-key-released
- Anthropic. "Introducing Claude Opus 4.5." November 2025. anthropic.com/...claude-opus-4-5
- LM Council. "AI Model Benchmarks May 2026." lmcouncil.ai/benchmarks
- ^1 ^2 ^3DeepSeek-AI. "DeepSeek-R1-0528 release notes." Hugging Face, May 2025. huggingface.co/...DeepSeek-R1-0528
- ^Wu, Mirhoseini and Tambe. "On the Role of Temperature Sampling in Test-Time Scaling." arXiv:2510.02611. October 2025. arxiv.org/...2510.02611
- ^1 ^2 ^3Price Per Token. "AIME 2024 Leaderboard" (data from Artificial Analysis). Accessed November 2026. pricepertoken.com/...aime
- ^TechCrunch. "OpenAI announces new o3 models." December 20, 2024. techcrunch.com/...openai-announces-new-o3-model
- ^Toby Ord. "How Well Does RL Scale?" October 20, 2025. tobyord.com/...how-well-does-rl-scale
- ^Yao, Cheng and Tan. "VAR-MATH: Probing True Mathematical Reasoning in LLMs via Symbolic Multi-Instance Benchmarks." arXiv:2507.12885. July 2025. arxiv.org/...2507.12885
- ^1 ^2 ^3BenchLM. "AIME 2024." Accessed November 2026. benchlm.ai/...aime2024
- ^1 ^2 ^3Anthropic. "Claude Opus 4.5 System Card." November 2025. assets.anthropic.com/...e-Opus-4-5-System-Card.pdf
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
9 revisions · v9 · 4,329 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (150 claims, 34 sources fetched); 21 material + 16 minor fixed
Cite this page: AI Wiki. "AIME 2024." aiwiki.ai, updated 28 Oct 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/aime_2024