

CharXiv
CharXiv
| CharXiv | |
|---|---|
| Overview | |
| Full name | Charting Gaps in Realistic Chart Understanding in Multimodal LLMs |
| Abbreviation | CharXiv |
| Description | An evaluation suite for assessing chart understanding capabilities in multimodal large language models, built from real charts in arXiv papers |
| Release date | 2024-06-26 (arXiv preprint), 2024-07-24 (v1.0 evaluation pipeline) |
| Latest version | 1.0 |
| Benchmark updated | Leaderboard updated 2024-12-25; adopted by frontier labs in 2025-04 |
| Authors | Zirui Wang, Mengzhou Xia, Luxi He, Howard Chen, Yitao Liu, Richard Zhu, Kaiqu Liang, Xindi Wu, Haotian Liu, Sadhika Malladi, Alexis Chevalier, Sanjeev Arora, Danqi Chen |
| Organization | Princeton Language and Intelligence (PLI), Princeton University; University of Wisconsin-Madison; The University of Hong Kong |
| Conference | NeurIPS 2024 Datasets and Benchmarks Track; spotlight at NeurIPS 2024 Multimodal Algorithmic Reasoning Workshop |
| Technical Details | |
| Type | Chart Understanding, Visual Reasoning, Multimodal Evaluation |
| Modality | Vision, Text |
| Task format | Open-vocabulary short-answer question answering |
| Number of question types | 2 (descriptive and reasoning) |
| Total examples | 2,323 charts; 1,000 validation charts with 5,000 questions; remaining 1,323 charts in held-out test split |
| Evaluation metric | Accuracy graded by GPT-4o (LLM-as-judge) |
| Domains | Scientific charts from arXiv preprints (2020-2023) in eight subjects: computer science, economics, electrical engineering and systems science, mathematics, physics, quantitative biology, quantitative finance and statistics |
| Languages | English |
| Performance | |
| Human performance | 80.5% reasoning, 92.1% descriptive |
| Best proprietary (paper) | GPT-4o, 47.1% reasoning |
| Best open-source (paper) | InternVL Chat V1.5, 29.2% reasoning |
| Leaderboard top (Dec 2024) | Claude 3.5 Sonnet, 60.2% reasoning, 84.3% descriptive |
| Saturated | Near ceiling: self-reported frontier scores exceed the 80.5% human reasoning baseline (as of November 2026) |
| Resources | |
| Website | charxiv.github.io |
| Paper | arXiv:2406.18521 |
| GitHub | princeton-nlp/CharXiv |
| Dataset | Hugging Face: princeton-nlp/CharXiv |
| License | CC BY-SA 4.0 (annotations), Apache 2.0 (code), original chart copyrights retained by paper authors |
CharXiv is a benchmark for evaluating chart understanding in multimodal large language models (MLLMs), built by researchers at Princeton Language and Intelligence with collaborators at the University of Wisconsin-Madison and the University of Hong Kong[1][2]. The paper, "CharXiv: Charting Gaps in Realistic Chart Understanding in Multimodal LLMs" by Wang et al., was posted to arXiv as 2406.18521 on 26 June 2024 and accepted at the NeurIPS 2024 Datasets and Benchmarks Track on 10 October 2024, with a spotlight at the NeurIPS 2024 Multimodal Algorithmic Reasoning Workshop[2][3].
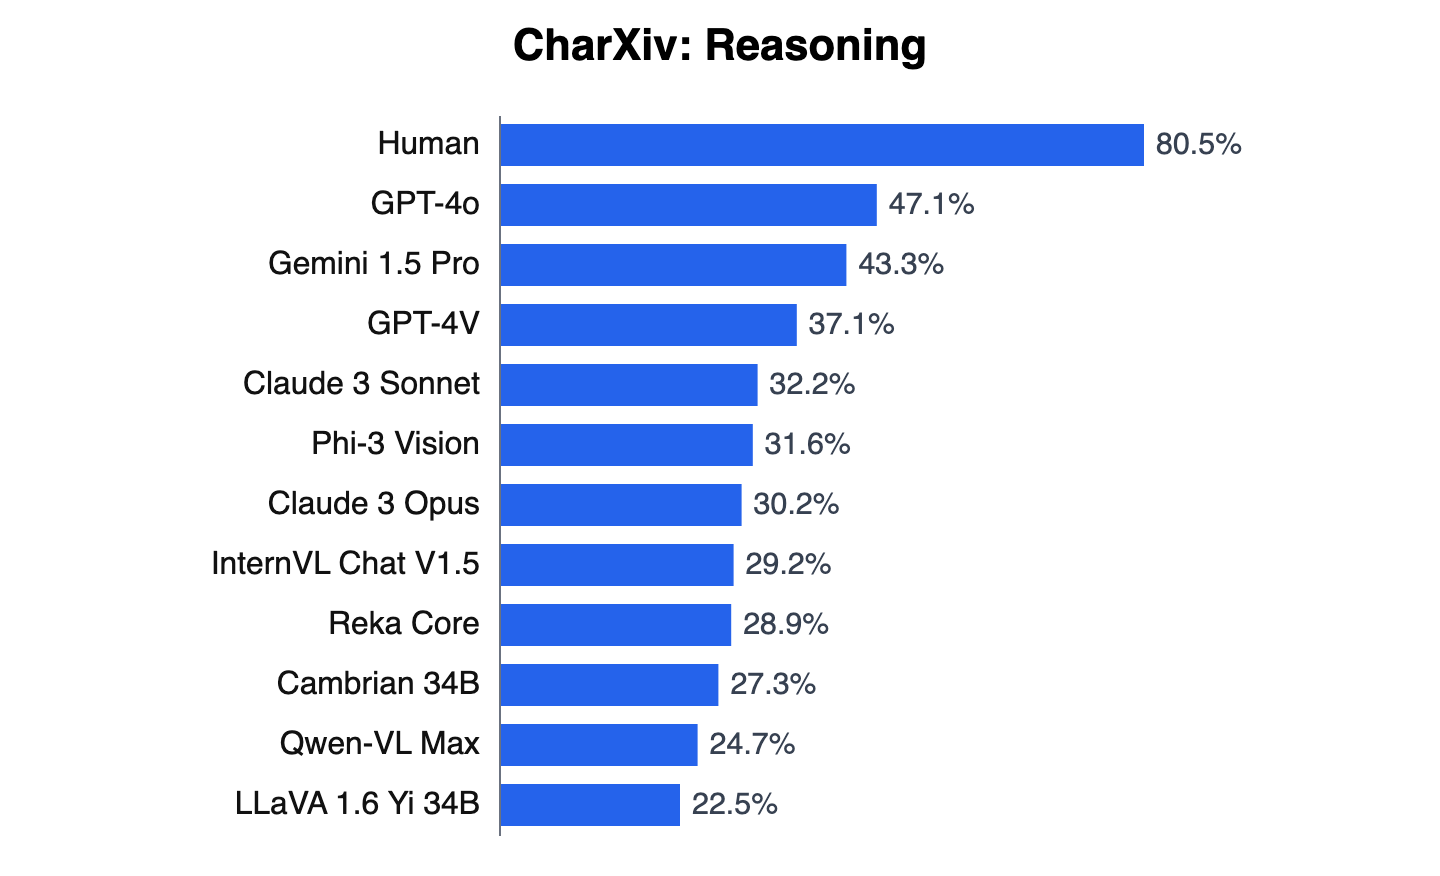
The benchmark uses 2,323 charts handpicked from real arXiv papers, pairing each chart with four descriptive questions plus one reasoning question. Answers are open-ended short text and grading is done with GPT-4o as judge. The paper reported that GPT-4o, the strongest proprietary model at submission, reached only 47.1% on reasoning while the strongest open-source model, InternVL Chat V1.5, reached 29.2%, both far below human accuracy of 80.5%[1][4].
Background
Chart understanding requires reading text, decoding spatial layouts, parsing legends and axes, and combining numbers across regions of an image. Earlier benchmarks such as FigureQA, DVQA and PlotQA used synthetic charts and templated questions, while ChartQA drew real charts from only four websites with limited visual diversity, so models could memorize patterns and post high scores without genuine visual reasoning ability[1]. The CharXiv authors argue this leads to an over-optimistic measure of progress, and the paper shows that simple stress tests with slightly different charts or questions can drop accuracy by up to 34.5% on those benchmarks[1]. CharXiv was designed as a corrective: scale, diversity and visual messiness are baked in by sourcing charts from real scientific papers rather than generating them.
The paper has thirteen authors led by Zirui Wang and including Mengzhou Xia, Haotian Liu (known for LLaVA, based at Wisconsin during the project), Sanjeev Arora and Danqi Chen. Most authors are based at Princeton's PLI lab[3][5].
Dataset construction
Source charts
All charts come from arXiv preprints posted between January 2020 and September 2023 in eight subjects (computer science, economics, electrical engineering and systems science, mathematics, physics, quantitative biology, quantitative finance and statistics), each contributing roughly 12 to 13% of the charts[1][6]. The team converted figures from arXiv vector files to raster images with widths between roughly 399 and 1,024 pixels, then ran a manual review to discard unreadable or ambiguous charts. Each chart's metadata records the paper ID, primary arXiv category and figure index[6]. A single CharXiv chart can be a bar plot, multi-axis line graph, scatter plot with regression overlays, heatmap, ROC or precision-recall curve, confusion matrix, or multi-panel composite (up to 120 subplots in the extreme), which distinguishes it from previous chart QA datasets where multi-panel composition was rare[6].
Splits
The benchmark splits 2,323 charts into a 1,000-chart validation set and a 1,323-chart held-out test set[1][6]. Each chart carries four descriptive questions and one reasoning question, so the validation set contains 5,000 questions. Test answers are stored as null to prevent leakage; practitioners are expected to evaluate on the validation set themselves, and the authors report test-set results using the privately held answers[1][8].
| Split | Charts | Descriptive questions | Reasoning questions | Answers public |
|---|---|---|---|---|
| Validation | 1,000 | 4,000 | 1,000 | Yes |
| Test | 1,323 | ~5,292 | ~1,323 | No (held out) |
| Total | 2,323 | ~9,292 | ~2,323 | Mixed |
Descriptive questions are drawn from 19 templates (one of the four per chart is deliberately unanswerable), while each reasoning question was written by a graduate-student annotator who could choose, modify or replace GPT-4V-generated sample questions: 59.3% of reasoning questions are human-written, 21.4% GPT-inspired and 19.3% GPT-generated. All question-answer pairs are validated by humans[1].
Question taxonomy
CharXiv's two question types break down further into named categories the leaderboard reports as subscores[7].
Descriptive questions (4 per chart)
Descriptive questions test whether a model reads the chart correctly without arithmetic or interpretation beyond the visible content. The five subscore categories:
| Code | Subcategory | What it tests |
|---|---|---|
| INEX | Information Extraction | Locating a specific value, label or annotation |
| ENUM | Enumeration | Listing labels (e.g., legend labels) or computing differences between labeled ticks |
| PATT | Pattern Recognition | Recognizing shapes (monotonic increase, oscillation, peak) |
| CNTG | Counting | Counting lines, legend labels or subplots |
| COMP | Compositionality | Counting the total number of labeled ticks across all axes |
Compositionality is the hardest descriptive subcategory: even Claude 3.5 Sonnet drops to 48.66% on COMP while scoring above 80% on the others[7].
Reasoning questions (1 per chart)
Reasoning questions require synthesizing information across chart elements; the paper designs them to need only visual and numerical reasoning, not domain-specific knowledge. They are organized by answer type:
| Code | Subcategory | What it tests |
|---|---|---|
| TC | Text-in-Chart | The answer is a piece of text found in the chart |
| TG | Text-in-General | The answer is an easily verifiable phrase not necessarily in the chart |
| NC | Number-in-Chart | The answer is a numerical value written on the chart |
| NG | Number-in-General | The answer is an exact numerical value, not necessarily in the chart, to a specified precision |
The four types are unevenly distributed: text-in-chart accounts for 45% of reasoning questions, number-in-general 23.2%, number-in-chart 22.0% and text-in-general 9.9%[1]. Number-in-General is the hardest category for almost every system tested[1][7].
Evaluation methodology
The official pipeline (v1.0, released 24 July 2024) is a three-step Python flow on the validation split[8]: generate.py calls the model with each chart-question pair and writes responses; evaluate.py calls the OpenAI API and asks GPT-4o to judge each response; get_stats.py aggregates the overall, descriptive and reasoning scores shown on the leaderboard. The choice of GPT-4o as judge is deliberate: exact-string matching is too strict for open-vocabulary answers, and a strong LLM judge correlates better with human grading[8]. The leaderboard reports descriptive and reasoning subscores separately, plus per-category breakdowns within each[7].
Results
Original paper results
The team evaluated 34 vision-language models covering proprietary APIs, generalist open models and chart-specific systems. Headline numbers on the validation split:
| Model | Reasoning | Descriptive | Notes |
|---|---|---|---|
| Human | 80.5% | 92.1% | In-house human participants |
| GPT-4o | 47.1% | 84.45% | Best proprietary at submission |
| Gemini 1.5 Pro | 43.3% | 71.97% | Best Google model; added after initial release |
| GPT-4V | 37.1% | 79.92% | Earlier OpenAI model |
| Claude 3 Opus | 30.2% | 71.55% | Pre-3.5 Anthropic flagship |
| Claude 3 Sonnet | 32.2% | 73.65% | Mid-tier Claude 3 |
| Phi-3 Vision | 31.6% | 60.48% | Microsoft small open VLM; added after initial release |
| InternVL Chat V1.5 | 29.2% | 58.5% | Best open-source at submission |
| Reka Core | 28.9% | 55.6% | Reka flagship |
| Cambrian 34B | 27.3% | 59.73% | NYU open-source; added after initial release |
| Qwen-VL Max | 24.7% | 41.48% | Alibaba proprietary |
| LLaVA 1.6 Yi 34B | 22.5% | 51.05% | Open-source baseline |
A random baseline (GPT-4o sampling without seeing the chart) scores 10.8% on reasoning and 19.85% on descriptive, providing a sanity floor[7]. Two patterns stand out: the descriptive-reasoning gap is large for every model (GPT-4o was within 8 points of humans on descriptive but over 30 points behind on reasoning), and the proprietary-open gap was close to 18 points on reasoning at submission[1].
Updated leaderboard (December 2024)
Between July and December 2024 the team added newer systems to the leaderboard; selected entries are below (the leaderboard also lists, for example, OpenAI's o1 at 52.6% and Qwen2-VL 72B at 43.0% on reasoning)[7][8]:
| Model | Reasoning | Descriptive | Released |
|---|---|---|---|
| Claude 3.5 Sonnet | 60.2% | 84.3% | 2024-06 |
| InternVL Chat V2.0 Pro | 39.8% | 76.83% | 2024 |
| InternVL Chat V2.0 76B | 38.9% | 75.17% | 2024 |
| Gemini 1.5 Flash | 33.9% | n/a | 2024 |
| GPT-4o Mini | 34.1% | 74.92% | 2024-07 |
| InternVL Chat V2.0 26B | 33.4% | 62.4% | 2024 |
| MiniCPM-V2.6 (Upsize+CoT) | 31.0% | 57.05% | 2024 |
Claude 3.5 Sonnet's 60.2% on reasoning was a step change, 13 points above GPT-4o, although later entries such as o1 (52.6%) narrowed that gap. Newer InternVL V2 models narrowed the open-source gap to about 21 points behind Claude on reasoning, with much smaller gaps on descriptive questions where the open-source 76B model came within 9 points of Claude[7].
Adoption by frontier labs
In an update on 14 April 2025, the CharXiv team noted that the benchmark had been formally incorporated into the official evaluation suites of several frontier model releases, including GPT-4.1, Qwen2.5-VL, InternVL2.5 and Doubao 1.5 Pro[8]. These adoptions converted CharXiv from a third-party academic benchmark into part of the standard set vendors report at launch, alongside MMMU, MathVista and ChartQA. As of November 2026, the llm-stats tracker lists mostly self-reported CharXiv reasoning scores above 90% for several systems (the top entry, Claude Mythos Preview, at 93.2%), above the paper's 80.5% human baseline[9]; the highest entry on the official leaderboard is OpenAI's o3 (high) at 78.6%[7].
Failure modes and robustness
The paper's appendices catalogue common failures[1]: on descriptive questions, models fail to localize the right subplot when many are present, read the wrong chart element, make OCR mistakes, hallucinate, and miscount; on reasoning questions, the representative models rarely make OCR or instruction-following errors and instead make factual mistakes with or without chain-of-thought reasoning. The paper also shows that perturbing existing chart QA datasets with small changes drops accuracy by up to 34.5%, while CharXiv already includes this realistic variation by design[1][3].
Comparison with related benchmarks
| Benchmark | Charts | Source | Question style |
|---|---|---|---|
| ChartQA | 20,882 | Statista, Pew, OWID, OECD | Human-written plus machine-generated from summaries [10] |
| PlotQA | 224K | Synthetic from World Bank tables | Templated |
| FigureQA | 100K+ | Synthetic | Yes/no (templated) [11] |
| DVQA | 300K | Synthetic bar charts | Templated [12] |
| ChartBench | ~67K | Synthetic and web | Mixed |
| MultiChartQA | 1,370 | Mixed (incl. arXiv) | Multi-chart reasoning, 2,000 questions [13] |
| CharXiv | 2,323 | Real arXiv papers | Free-form short answers, hand-authored |
CharXiv has roughly a third of ChartQA's questions (11,615 versus about 32,700), but the charts are much harder: multi-panel layouts, log scales, error bars and dense legends are common. Compared to PlotQA or FigureQA, CharXiv is about two orders of magnitude smaller, but those datasets are fully synthetic and do not discriminate between strong models. The design choice was deliberate: prioritize realism and difficulty over volume[1].
License, reception, and limitations
Annotations are released under CC BY-SA 4.0, evaluation code under Apache 2.0, and chart images remain under the copyright of the original arXiv authors[8]. The dataset is hosted on Hugging Face at princeton-nlp/CharXiv along with raw responses and graded outputs for all 34 models in the paper, useful for fine-grained meta-analysis[6]. The authors request CharXiv be used for evaluation rather than training; the test split's hidden answers enforce this.
CharXiv was one of the more cited 2024 multimodal evaluation papers. Beyond the NeurIPS spotlight, the benchmark has been used in subsequent chart reasoning research including a follow-up paper from 24 October 2024 (arXiv 2410.18798) proposing training methods specifically targeting CharXiv-style charts[8].
Limitations: CharXiv is English-only; charts come only from arXiv preprints (spread evenly across eight academic subjects), so business, journalism and other non-academic charts are not represented; and the answer format is restricted to short text. Validation answers are public, so models could indirectly memorize them through web scraping; the test split guards against this but depends on labs honoring the held-out convention[1][6]. LLM-as-judge grading via GPT-4o also couples the benchmark to a specific model, though the team validates GPT-4o judgments against human grading on a sample.
Continue reading
- InternVLInternVL is a family of open-source multimodal large language models developed by the OpenGVLab research group at the Shanghai Artificial Intelligence Laboratory in collaboration with academic partners…Mentioned 7 times above
- Claude 3.5 SonnetClaude 3.5 Sonnet was a proprietary multimodal large language model developed by Anthropic.Mentioned 4 times above
- LLaVA (Large Language and Vision Assistant)LLaVA (Large Language and Vision Assistant) is an open-source family of multimodal large language models that connects a frozen vision encoder to a pre-trained large language model through a single learned…Mentioned twice above
- MMMUMMMU (Massive Multi-discipline Multimodal Understanding and Reasoning Benchmark) is a multimodal AI benchmark of 11,550 college-level questions that pairs text with images to test expert knowledge and…Listed in See also
- MathVistaMathVista is a benchmark for evaluating the mathematical reasoning capabilities of foundation models in visual contexts.Listed in See also
- Qwen-VLQwen-VL is the first family of open vision-language (multimodal) models from the Qwen team at Alibaba Cloud, able to take images, text, and bounding boxes as input and produce text and bounding boxes as output.Listed in See also
More from See also
- Chart understanding
- Multimodal large language models
- Visual reasoning
- Vision language model
- ChartQA
- DocVQA
- Princeton Language and Intelligence
Topics:AI BenchmarksData & Datasets
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15Wang, Z., Xia, M., He, L., Chen, H., Liu, Y., Zhu, R., Liang, K., Wu, X., Liu, H., Malladi, S., Chevalier, A., Arora, S., and Chen, D. (2024). "CharXiv: Charting Gaps in Realistic Chart Understanding in Multimodal LLMs." arXiv:2406.18521. arxiv.org/...2406.18521
- ^1 ^2NeurIPS 2024 Datasets and Benchmarks Track poster page: "CharXiv: Charting Gaps in Realistic Chart Understanding in Multimodal LLMs," neurips.cc/...97598
- ^1 ^2 ^3OpenReview discussion and acceptance record: openreview.net/forum
- ^NeurIPS 2024 Proceedings PDF: proceedings.neurips.cc/...and_Benchmarks_Track.pdf
- ^Princeton Language and Intelligence event listing for CharXiv: pli.princeton.edu/...understanding-multimodal-llms
- ^1 ^2 ^3 ^4 ^5 ^6Hugging Face dataset card for princeton-nlp/CharXiv: huggingface.co/...CharXiv
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Official CharXiv project site and leaderboard: charxiv.github.io (mirror at princeton-nlp.github.io/CharXiv)
- ^1 ^2 ^3 ^4 ^5 ^6 ^7CharXiv GitHub repository (princeton-nlp/CharXiv), README, news log and license: github.com/...CharXiv
- ^Independent CharXiv reasoning leaderboard tracker: llm-stats.com/...charxiv-r
- ^Masry, A., Do, X. L., Tan, J. Q., Joty, S., and Hoque, E. (2022). "ChartQA: A Benchmark for Question Answering about Charts with Visual and Logical Reasoning." arXiv:2203.10244. arxiv.org/...2203.10244
- ^Kahou, S. E., Michalski, V., Atkinson, A., Kadar, A., Trischler, A., and Bengio, Y. (2017). "FigureQA: An Annotated Figure Dataset for Visual Reasoning." arXiv:1710.07300. arxiv.org/...1710.07300
- ^Kafle, K., Price, B., Cohen, S., and Kanan, C. (2018). "DVQA: Understanding Data Visualizations via Question Answering." arXiv:1801.08163. arxiv.org/...1801.08163
- ^Zhu, Z., Jia, M., Zhang, Z., Li, L., and Jiang, M. (2024). "MultiChartQA: Benchmarking Vision-Language Models on Multi-Chart Problems." arXiv:2410.14179. arxiv.org/...2410.14179
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
6 revisions · v6 · 2,746 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (130 claims, 17 sources fetched); 17 material + 11 minor fixed
Cite this page: AI Wiki. "CharXiv." aiwiki.ai, updated 28 Oct 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/charxiv