

Gemini Robotics
Gemini Robotics is a family of robot foundation models developed by Google DeepMind that extends the Gemini multimodal model line into the physical world. The first two models in the family, Gemini Robotics and Gemini Robotics-ER (short for Embodied Reasoning), were announced on March 12, 2025 and were both built on top of the Gemini 2.0 base model.[1][2] Subsequent releases added an on-device variant in June 2025, the Gemini Robotics 1.5 generation in September 2025, and a refreshed reasoning model called Gemini Robotics-ER 1.6 in April 2026.[3][4][5][6] A second numbered generation, the three-model Gemini Robotics 2 family, was announced on July 30, 2026 and is the current generation.[26] In October 2026 Google also published robotics demonstrations for Gemini 4 Argon, its general-purpose frontier model, which is not branded as a Gemini Robotics model.[37][38]
The line is positioned as a general-purpose vision-language-action (VLA) and embodied reasoning stack that lets robots perceive, plan, and act across different tasks and embodiments. Google DeepMind describes three properties as central to the design: generality across novel situations, interactivity through ordinary language, and dexterity for fine manipulation.[1][2] Google DeepMind calls Gemini Robotics "our most advanced vision-language-action (VLA) model yet" and frames the family as the company bringing "AI into the physical world."[1] The models are intended to be used together, with the embodied reasoning model acting as a high-level planner that calls the action model and other tools, including Google Search and user-defined functions.[4][7]
Apptronik is the lead humanoid hardware partner for the program, and Google DeepMind has run a trusted tester program that included Agile Robots, Agility Robotics, Boston Dynamics, and Enchanted Tools at launch and grew to more than sixty organizations by late 2025.[1][18] Stanford's Jan Liphardt, quoted by MIT Technology Review, called the launch "one of the first few announcements of people applying generative AI and large language models to advanced robots," while IEEE Spectrum described it as two new foundation models to help robots reason.[10][11]
What is Gemini Robotics and where did it come from?
Robotics research has long struggled to produce policies that generalize beyond the narrow conditions they were trained on. Earlier efforts inside Google DeepMind, notably the RT-1 (2022) and RT-2 (2023) projects, trained transformer policies on large robot datasets; RT-2 layered action prediction on top of vision-language models and showed that internet-scale pretraining could improve a robot's response to novel objects and instructions.[46] Outside Google, the OpenVLA model from Stanford and the Pi-0 model from Physical Intelligence extended the same recipe with different choices about action representation and embodiment coverage.[44][45]
Gemini Robotics inherits this approach but starts from a much larger and more recent base. Carolina Parada, who leads robotics at Google DeepMind, described the team's strategy as broad task learning instead of single-task specialization, with the bet that generalization would emerge once the model had enough exposure to varied tasks.[13] The models are built on top of Gemini 2.0, which already encodes wide visual and linguistic context, and they add physical actions as an additional output modality alongside text.[1][14]
The project was designed in collaboration with hardware partners from the start. Apptronik, maker of the Apollo humanoid robot, is the lead humanoid partner, and Google DeepMind opened a trusted tester program for Gemini Robotics-ER on the same day as the public announcement.[2][15]
When was each Gemini Robotics model released?
The table below summarizes the major Gemini Robotics releases through July 2026.
| Date | Release | Notes |
|---|---|---|
| March 12, 2025 | Gemini Robotics and Gemini Robotics-ER announced | Built on Gemini 2.0; both models gated to trusted testers at launch[1][2] |
| March 25, 2025 | Technical report posted to arXiv | Paper number 2503.20020, titled "Gemini Robotics: Bringing AI into the Physical World"[16] |
| June 24, 2025 | Gemini Robotics On-Device released | First on-robot VLA in the family; first VLA from Google DeepMind opened to fine-tuning[3][17] |
| September 25, 2025 | Gemini Robotics 1.5 and Gemini Robotics-ER 1.5 announced | Two-model agentic stack; ER 1.5 made available in preview through the Gemini API and Google AI Studio[4][18] |
| April 14, 2026 | Gemini Robotics-ER 1.6 released | Improved spatial reasoning and instrument reading; deployed on Boston Dynamics Spot for industrial inspection[5][6][19] |
| July 29, 2026 | Gemini Robotics 2 safety technical report published | Introduced ASIMOV-Agentic, an agentic safety and uncertainty resolution benchmark released as an open dataset[30] |
| July 30, 2026 | Gemini Robotics 2 family announced | Three models (Gemini Robotics 2, Gemini Robotics ER 2, Gemini Robotics On-Device 2); first whole-body humanoid control in the family; ER 2 published to the Gemini API[26][27] |
What models are in the Gemini Robotics family?
The Gemini Robotics product page groups the models into three roles: a vision-language-action model that turns visual input and instructions into motor commands, a reasoning model that plans, and an on-device variant that runs locally on the robot.[20] The same role structure has been preserved across model generations, with the version numbers (1.5, 1.6, 2) tracking improvements within each role rather than separate product lines. Google also dropped the hyphen in the reasoning model's name with the second generation: releases through April 2026 are styled "Gemini Robotics-ER", the July 2026 model "Gemini Robotics ER 2".[5][26]
| Model | Type | First released | Role |
|---|---|---|---|
| Gemini Robotics | Vision-language-action | March 2025 | Cloud-served VLA that issues motor commands |
| Gemini Robotics-ER | Vision-language model | March 2025 | Embodied reasoning, perception, and planning layer |
| Gemini Robotics On-Device | Vision-language-action | June 2025 | Local VLA optimized for on-robot inference |
| Gemini Robotics 1.5 | Vision-language-action | September 2025 | Reasoning-augmented VLA that explains its actions before executing |
| Gemini Robotics-ER 1.5 | Vision-language model | September 2025 | High-level planner with tool calling and adjustable thinking budget |
| Gemini Robotics-ER 1.6 | Vision-language model | April 2026 | Refresh focused on spatial reasoning, multi-view understanding, and instrument reading |
| Gemini Robotics 2 | Vision-language-action | July 2026 | Whole-body VLA that drives full humanoids as well as bi-arm robots, hands, and grippers[26] |
| Gemini Robotics ER 2 | Vision-language model | July 2026 | Embodied reasoning agent built on Gemini 3.5 Flash; orchestrates VLAs, tracks video progress, and coordinates multiple robots[27][28] |
| Gemini Robotics On-Device 2 | Vision-language-action | July 2026 | Local VLA built on Google's on-device Gemma models plus Gemini Robotics 1.5 technology[29] |
The embodied reasoning models are vision-language models that emit pointing, object detection, success detection, and code rather than continuous joint commands. The vision-language-action models translate pixels and instructions into motor commands directly. In Google's deployment guidance, the two models are used together: the reasoning model produces a plan and calls the action model (or other tools) to execute each step.[4][7]
What changed in the Gemini Robotics 2 generation?
Main article: Gemini Robotics 2
Google DeepMind announced the second numbered generation on July 30, 2026 in a post written by Carolina Parada, keeping the three-role structure but replacing all three models at once.[26] The slogan attached to the release, "from feet to fingertips," points at the change the company considers most significant: earlier models in the family controlled a humanoid's upper body for tabletop work, while Gemini Robotics 2 drives the whole body.[26]
Four capabilities are new or substantially extended in this generation.
Intelligent whole-body control. The VLA model page describes Gemini Robotics 2 as controlling entire humanoid bodies and dynamically balancing the robot's center of gravity, so that a robot can step, squat, and bend rather than reach from a fixed stance.[31] Putting legs, torso, arms, and fingers under one policy lets the model trade balance against reach inside a single decision instead of handing control between a locomotion controller and a manipulation policy. In the launch demonstration, Apptronik's Apollo 2 humanoid is told to put a watering can into the green bin on the bottom shelf; it walks to the table, picks up the can, walks to the shelves, and places it.[26] Google DeepMind says its robots "have more to advance in movement speed."[26]
One checkpoint across embodiments and end effectors. The performance charts published with the launch show a single model checkpoint driving three configurations: Apollo 2 with SharpaWave hands, Apollo 2 with Inspire hands, and a Franka Duo with a Robotiq gripper.[26] This extends the cross-embodiment transfer of the 1.5 generation from different robots to different hands on the same robot: the same weights operate a five-fingered, 22-degree-of-freedom SharpaWave hand and a two-fingered parallel gripper.[26][31]
Multi-robot collaboration. Gemini Robotics ER 2 can coordinate more than one machine, with robots of different types communicating through a shared semantic understanding and handing sub-tasks to whichever body suits them; the published demonstration pairs an Apollo 2 humanoid with a Franka F3 Duo arm.[27] ER 2 also adds two time-oriented skills that support long missions: progress classification, which sorts each video frame into one of five completion bands, and moment finding, which locates the exact frame where a critical event occurs.[27]
Fast on-device adaptation. Gemini Robotics On-Device 2 inherits the motion transfer techniques of Gemini Robotics 1.5 and is natively multi-embodiment. Google DeepMind reports adapting it to new bi-arm bodies in a few hours, typically with fewer than 200 examples, on platforms as different as Dexmate, SO101, and Trossen.[26][29]
The launch also introduced ASIMOV-Agentic, a benchmark for agentic safety and uncertainty resolution, covered in the safety section below.[26][30]
The success rates for this generation are listed in the benchmarks table below. They are Google DeepMind's own figures, read from charts in the launch post, and the company states that each whole-body and gripper figure is an average across several tasks in a skill category while the multi-finger figures are per-task.[26] Its own caption says the model reaches medium to high success on whole-body and gripper tasks while multi-finger dexterous manipulation "remains challenging," and the 56-point gap between unscrewing a light bulb (92%) and screwing one in (36%) is the sharpest illustration of that.[26] SiliconANGLE's coverage singled out progress tracking as the practical advance, on the grounds that a robot that knows where it stopped can resume a task instead of restarting it.[33]
How does Gemini Robotics work?
Gemini Robotics models inherit the transformer architecture and the multimodal pretraining data of Gemini 2.0. The original VLA was then trained on robot action data, chiefly teleoperated demonstrations collected on real ALOHA 2 robots; the technical report lists greater use of simulation-generated data as future work. The report describes the embodied reasoning model, Gemini Robotics-ER, as extending Gemini 2.0's abilities in object detection, pointing, trajectory and grasp prediction, multi-view correspondence, and 3D bounding box prediction.[16]
Two-model planning and action
From the original announcement onward, Google DeepMind has framed the family as a two-model system. Gemini Robotics-ER handles perception and decision-making: it recognizes elements in the scene, estimates their size and location, predicts grasp points and trajectories, and emits code to execute the action. Gemini Robotics handles execution: it converts the visual context plus an instruction into the joint-level commands that drive the robot.[2][13] The 1.5 generation made this split explicit by giving Gemini Robotics-ER 1.5 native tool-calling abilities so it can call Gemini Robotics 1.5 (or any other VLA) the same way a language agent calls a function.[4][7]
Cloud backbone and on-robot decoder
According to the technical report, the Gemini Robotics VLA is split between a vision-language backbone hosted in the cloud and a small action decoder running on the robot's onboard computer. The team optimized the backbone latency from "seconds to under 160 ms" and reported an end-to-end latency from raw camera observation to a chunk of low-level joint commands of about 250 ms, supporting an effective control frequency of 50 Hz.[16] This split allows the system to use the full Gemini 2.0 weights for reasoning while still issuing high-frequency motor commands locally, an architecture choice that contrasts with fully on-device VLAs such as Gemini Robotics On-Device or with cloud-only approaches without a dedicated on-robot decoder.
The model emits actions in chunks rather than one step at a time. Action chunking lets the policy plan several timesteps of motion in advance, which Google DeepMind argues helps it produce smoother trajectories and tolerate the network round trip to the cloud backbone.[16]
Training data
The Gemini Robotics paper describes the training mix as "a large and diverse dataset consisting of action-labeled robot data as well as other multimodal data." The robot-data portion includes thousands of hours of expert teleoperated demonstrations collected over twelve months on ALOHA 2 robots. The multimodal portion includes web documents, code, images, audio, video, and embodied reasoning and visual question answering data inherited from Gemini 2.0 pretraining.[16] Ablation studies in the same paper found that training a Gemini Robotics specialist model from scratch, rather than fine-tuning the generalist checkpoint, dropped success rates on evaluation tasks to 0%, which the authors read as evidence that, besides model capacity, the representation learned from the diverse robot action data of generalist training is a key ingredient for specializing to hard tasks.[16]
Reasoning before acting
In the 1.5 generation, the VLA was given the ability to think in natural language before producing actions. Google DeepMind described this as helping the robot "assess and complete complex tasks more transparently," and noted that the model could explain its plan in natural language while moving.[4] On the planning side, Gemini Robotics-ER 1.5 added an adjustable thinking budget that lets developers trade response speed for reasoning depth, and explicit checks against payload limits and workspace constraints to filter physically infeasible plans.[7]
Cross-embodiment transfer
Google DeepMind has emphasized that a single Gemini Robotics model can drive multiple robot embodiments. In the 1.5 generation, Google DeepMind reported that tasks presented only to the bi-arm ALOHA 2 platform during training "also just work" on Apptronik's Apollo humanoid and the bi-arm Franka robot, and vice versa; the original March 2025 model had instead been specialized for Apollo.[1][4] In the on-device release, Google reported adapting the ALOHA-trained model to the Franka FR3 and Apollo, and separately that it could learn new tasks from as few as 50 to 100 demonstrations.[3][17]
On-device variant
Gemini Robotics On-Device is a smaller VLA designed to run locally on the robot's onboard compute, outside of any cloud connection. It is engineered for low-latency inference on bi-arm platforms, with general-purpose dexterity comparable to the cloud-served model on out-of-distribution and multi-step tasks.[3] InfoQ reported that the on-device model completed evaluation tasks successfully more than 60% of the time on average, against roughly 80% for the cloud variant, with stronger performance than other published on-device VLA baselines.[17] It was the first VLA Google DeepMind released for fine-tuning by external developers, distributed through the Gemini Robotics SDK with a MuJoCo physics simulator integration.[3][17]
What can Gemini Robotics do?
Google DeepMind's public materials describe three recurring properties for Gemini Robotics: generality, interactivity, and dexterity.[1][2]
| Capability | Description |
|---|---|
| Generality | Adapts to new objects, instructions, and environments. Google reported that Gemini Robotics more than doubles the score of other state-of-the-art VLA models on a comprehensive generalization benchmark.[1] |
| Interactivity | Responds to commands phrased in everyday conversational language across multiple languages, monitors the scene continuously, and can adjust mid-task when objects move.[1][2] |
| Dexterity | Performs multi-step manipulation including origami folding, packing snacks into a Ziploc bag, folding clothes, unzipping bags, and pouring salad dressing.[1][3] |
| Tool use | The 1.5 generation can call digital tools such as Google Search and other VLA models to retrieve information or execute sub-steps.[4][7] |
| Embodiment transfer | Adapts across ALOHA 2, the bi-arm Franka FR3, and humanoid platforms such as Apptronik's Apollo, often without per-robot training.[1][4] |
Gemini Robotics-ER, the reasoning model, contributes a different set of capabilities focused on perception and planning: 2D pointing and object detection grounded in size, weight, and affordance information, multi-view correspondence, success and failure detection from camera streams, and code generation that calls other tools to execute physical actions.[7][16]
Generalization axes
The Gemini Robotics technical report decomposes generalization into three axes that are evaluated separately, a structure the report takes from prior work on evaluating generalist robot policies.[16]
| Axis | Definition | Example |
|---|---|---|
| Visual generalization | Invariance to visual changes that do not affect the actions required to solve the task | New backgrounds, lighting changes, or distractor objects added to a familiar scene |
| Instruction generalization | Robustness to paraphrased or differently structured instructions | "Put the banana into the container" versus "Place the yellow fruit inside the clear box" |
| Action generalization | Ability to adapt or synthesize new motions for tasks the robot has not been trained on | Slam-dunking a new toy basketball, or grasping objects of an unseen shape |
Google reported that on a comprehensive generalization benchmark spanning these axes, Gemini Robotics more than doubled the average score of prior state-of-the-art VLA baselines, with gains on all three axes and non-zero performance even where baselines failed outright, such as instructions in a new language.[1][16]
Demonstrations
The demonstrations released with the original Gemini Robotics announcement included a robotic arm placing a banana into a clear container while the container was repositioned, folding glasses into a case, performing origami, and slam-dunking a small basketball into a net despite never having seen those specific objects in training.[1][10] Apollo, Apptronik's humanoid robot, was shown packing lunches, sorting laundry, and placing items in containers.[15]
For the 1.5 generation, Google DeepMind highlighted a multi-step waste sorting task in which the robot first looked up local recycling rules using Google Search, then identified each object visually, then placed it in the correct bin: a sequence that required tool use, planning, and physical manipulation in a single mission.[4]
Benchmarks
Google has published several headline benchmark numbers for the Gemini Robotics family. The numbers below are taken directly from Google DeepMind's announcements and the underlying technical reports.
| Model | Benchmark | Result | Source |
|---|---|---|---|
| Gemini Robotics (March 2025) | Comprehensive generalization benchmark | More than 2x average score over prior state-of-the-art VLAs | [1] |
| Gemini Robotics-ER (March 2025) | End-to-end robotic control | 2x to 3x success rate over Gemini 2.0 baseline | [1] |
| Gemini Robotics-ER 1.5 (September 2025) | 15 academic embodied reasoning benchmarks (ERQA, Point-Bench, RefSpatial, RoboSpatial-Pointing, Where2Place, BLINK, CV-Bench, EmbSpatial, MindCube, RoboSpatial-VQA, SAT, Cosmos-Reason1, Min Video Pairs, OpenEQA, VSI-Bench) | Highest aggregated score among models tested by Google | [4] |
| Gemini Robotics On-Device (June 2025) | Average task success across seven evaluation tasks | About 60% on-device, about 80% for cloud variant | [17] |
| Gemini Robotics-ER 1.6 (April 2026) | Instrument reading without agentic vision | 86% | [5] |
| Gemini Robotics-ER 1.6 (April 2026) | Instrument reading with agentic vision | 93% | [5] |
| Gemini Robotics models | ASIMOV semantic safety benchmark | Over 80% accuracy on hazardous-scenario questions, including bleach-and-vinegar mixing | [11][22] |
| Gemini Robotics 2 (July 2026) | General whole-body manipulation on Apollo 2 with Inspire hands, single checkpoint | 68.4% picking up from a table, 45.7% from the floor, 76.3% from a shelf | [26] |
| Gemini Robotics 2 (July 2026) | Multi-finger dexterity on Apollo 2 with SharpaWave hands | 92% unscrewing a bulb, 44% tying a trash bag, 40% ziplock, 36% screwing a bulb, 32% dustpan | [26] |
| Gemini Robotics 2 (July 2026) | Gripper dexterity on a Franka Duo | 74.2% general pick and place, 78.9% diverse tool kitting, 89.6% precise insertion | [26] |
| Gemini Robotics ER 2 (July 2026) | Video progress classification into five completion bands | 57.4% accuracy | [27] |
| Gemini Robotics ER 2 (July 2026) | Moment finding (locating the frame of a critical event) | 91.3% accuracy, 0.96 second mean absolute distance | [27] |
On the same instrument-reading evaluation, Google's chart puts Gemini Robotics-ER 1.5 at 23% and Gemini 3.0 Flash at 67%, against 86% for ER 1.6 alone and 93% with agentic vision.[5] Some press coverage, such as a Resultsense summary of an Ars Technica report, gave the agentic-vision figure as 98%, which does not match Google's published chart.[19]
Which robots and partners use Gemini Robotics?
Gemini Robotics is intentionally embodiment-flexible, but most public demonstrations have used a small set of hardware partners.
| Partner | Robot | Role |
|---|---|---|
| Google DeepMind in-house | ALOHA 2 (bi-arm research platform) | Primary training and evaluation platform[1][16] |
| Franka Robotics | Franka FR3 (bi-arm) | Cross-embodiment evaluation; on-device adaptation target[3][17] |
| Apptronik | Apollo (humanoid) | Lead humanoid partner; demonstrations of lunch packing, laundry sorting, and placing items in containers[15] |
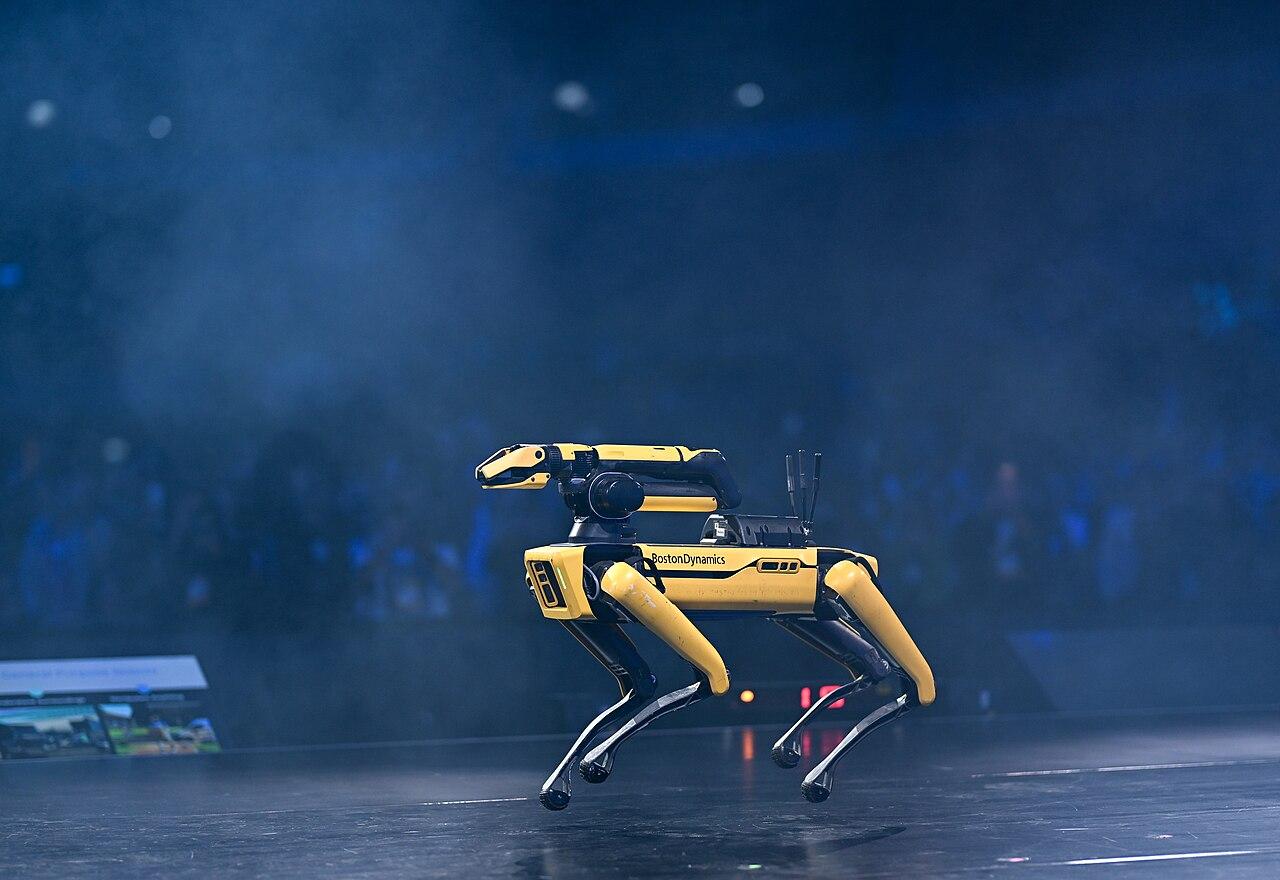
| Boston Dynamics | Spot (quadruped) | Industrial inspection, gauge reading, and autonomous navigation with Gemini Robotics-ER 1.6[6][19] |
| Agile Robots | Industrial bi-arm platforms | Trusted tester for Gemini Robotics-ER[2][8] |
| Agility Robotics | Digit (humanoid) | Trusted tester for Gemini Robotics-ER[2][8] |
| Enchanted Tools | Mirokai (mobile humanoid) | Trusted tester for Gemini Robotics-ER[2][8] |
InfoQ reported that the trusted tester program had grown to more than 60 participants by the September 2025 update, with Apptronik named as a continuing partner during that release.[18] By October 2026 the Gemini Robotics product page said Google was working with more than 100 trusted testers, "from enterprise automation leaders to cutting-edge robotics startups."[8] The July 2026 launch post thanks Apptronik, Boston Dynamics, and Agile Robots by name and widens the published hardware list: Apptronik's Apollo 2 humanoid with either SharpaWave or Inspire hands, a Franka Duo with a Robotiq gripper, a Franka F3 Duo in the multi-robot demonstration, and the Dexmate, SO101, and Trossen platforms for the on-device model.[26][27] A companion demonstration has Gemini Robotics ER 2 orchestrate a Boston Dynamics Spot's navigation and manipulation APIs to fetch a snack, with example code published on GitHub.[27]
Spot at Boston Dynamics
Boston Dynamics integrated Gemini Robotics into the Spot SDK by exposing a small set of "tools" (navigation between locations, image capture, object identification, grasping, and placement) that Gemini Robotics could call. The integration deliberately limits the model's capabilities to the existing API surface so that the model cannot invent new actions outside what Spot is sanctioned to do.[23] On top of this, the AIVI-Learning visual inspection product on Spot and the Orbit fleet manager incorporated Gemini Robotics-ER 1.6 to read analog gauges, thermometers, sight glasses, and digital displays during autonomous patrol.[6][19]
How does Google DeepMind handle Gemini Robotics safety?
Google DeepMind has framed Gemini Robotics as a robotics program with an explicit safety layer rather than a research demo. The company says its robotics models are reviewed through its Responsibility and Safety Council and evaluated against the ASIMOV benchmark suite for semantic and physical safety constraints.[1][22] In MIT Technology Review's launch coverage, the team described a constitutional approach inspired by Isaac Asimov's laws of robotics that produces a data-driven robot constitution to align behavior with human values.[10]
The Gemini Robotics 1.5 release upgraded the safety stack in three ways: it added a high-level semantic reasoning step that lets the planner think about safety before acting, aligned the planner's output with the existing Gemini Safety Policies, and triggered low-level on-board safety subsystems for collision avoidance.[4] An updated benchmark, ASIMOV v2, added broader tail coverage, new safety question types, and video modalities, and Google reported state-of-the-art results on it for Gemini Robotics-ER 1.5.[4]
For the April 2026 ER 1.6 release, Google reported better adherence to physical constraints (such as weight limits and liquid handling), a roughly 10-percentage-point improvement on video-based safety hazard identification compared to Gemini 3.0 Flash, and stronger compliance with Gemini safety policies on adversarial prompts.[5]
The Gemini Robotics 2 generation came with a separate safety technical report dated July 29, 2026 and a third ASIMOV benchmark, ASIMOV-Agentic, released as an open dataset on Hugging Face.[26][30] Where the earlier ASIMOV benchmarks scored a model's judgment about whether an instruction is safe, ASIMOV-Agentic scores the reasoning model's behavior as an orchestrator: whether it refuses unsafe tool calls to the VLA, shields the VLA from tasks that are infeasible or outside its training distribution, triggers protective stops during execution, and asks a human for help when a scene or an instruction is ambiguous.[26][30] Google DeepMind describes Gemini Robotics ER 2 as its safest robotics model so far on safety instruction following and human proximity benchmarks, and says the model halts a humanoid when a person comes too close and resumes on its own once the area is clear.[26][27] The report also records a trade-off that no model tested escaped: systems tuned to keep unnecessary stops below 5 percent missed more than 40 percent of genuine human-proximity hazards, which the authors read as an argument for keeping deterministic guardrails underneath the model.[30] The ER 2 model card separately prohibits use in safety-critical settings such as healthcare and transportation.[28]
How does Gemini Robotics compare with other robot foundation models?
Gemini Robotics sits in a small but growing category of robotics foundation models. The table below summarizes how it compares to the most widely discussed peers as of July 2026.
| Model | Developer | Released | Approach | Action representation | Notable embodiments |
|---|---|---|---|---|---|
| RT-1 | Google Research | 2022 | Transformer policy on real demonstrations | Discrete tokens | Everyday Robots mobile manipulator |
| RT-2 | Google DeepMind | 2023 | VLM (PaLI-X / PaLM-E) fine-tuned on robot data | Discrete tokens | Everyday Robots mobile manipulator[46] |
| OpenVLA | Stanford and partners | June 2024 | Open-source 7B VLA on Open X-Embodiment data | Discrete tokens | 22 embodiments via Open X-Embodiment |
| Pi-0 | Physical Intelligence | 2024 | Flow-matching VLA with continuous joint outputs at up to 50Hz | Continuous, flow-matching action chunks | Single-arm, dual-arm, and mobile manipulators[45] |
| GR00T N1 | NVIDIA | 2025 | Foundation VLA for humanoids | Continuous joint actions | Humanoid robots |
| Gemini Robotics 1.5 | Google DeepMind | September 2025 | VLA built on the Gemini 2.5 generation of Gemini with thinking before action[43] | Continuous joint actions | ALOHA 2, Franka FR3, Apptronik Apollo |
| Gemini Robotics 2 | Google DeepMind | July 2026 | Whole-body VLA driving legs, torso, arms, and fingers from one checkpoint, paired with a Gemini 3.5 Flash reasoning model | Continuous joint actions | Apptronik Apollo 2 with SharpaWave or Inspire hands, Franka Duo with a Robotiq gripper[26][28] |
In architecture terms, Pi-0 emphasizes diffusion-based continuous control and a hardware-agnostic, real-data philosophy, while OpenVLA and the RT line use discrete action tokens. Gemini Robotics shares Pi-0's continuous control philosophy but inherits the much larger Gemini 2.0 base, which gives it stronger world knowledge and tool-use behavior at the expense of fully open weights.[12] OpenVLA is open source and its authors reported that the 7-billion-parameter model outperformed the 55-billion-parameter RT-2-X by 16.5 points in absolute task success across 29 tasks, while Gemini Robotics is closed source and accessed through partner programs and the Gemini API.[44]
How can developers access Gemini Robotics?
Google DeepMind has staggered developer access across the family. The vision-language-action models have generally been gated to partner programs, while the embodied reasoning models have been the first to reach broader developer audiences.
| Model | Access route as of July 31, 2026 | Notes |
|---|---|---|
| Gemini Robotics (March 2025) | Trusted tester program only | Required signup form; available to a small set of partners[2][8] |
| Gemini Robotics-ER (March 2025) | Trusted tester program only | Same partner program as the VLA[2][8] |
| Gemini Robotics On-Device (June 2025) | Waitlist, then Gemini Robotics SDK | First VLA in the family released for fine-tuning, distributed with MuJoCo integration[3][17] |
| Gemini Robotics 1.5 (September 2025) | Select partners only | Continued partner-only distribution for the action model[4][18] |
| Gemini Robotics-ER 1.5 (September 2025) | Public preview through Gemini API and Google AI Studio | First Gemini Robotics model on the public Gemini API; the gemini-robotics-er-1.5-preview endpoint was shut down on April 30, 2026[4][7][32] |
| Gemini Robotics-ER 1.6 (April 2026) | Gemini API and Google AI Studio until its deprecation | Sample Colab notebooks and reference integrations published with the release; Google's deprecations page gives August 31, 2026 as the shutdown date of the gemini-robotics-er-1.6-preview endpoint, with gemini-robotics-er-2-preview as the named replacement[5][32] |
| Gemini Robotics 2 (July 2026) | Private preview, waitlist for early access | Action model remains partner-gated[26][31] |
| Gemini Robotics ER 2 (July 2026) | Publicly available through the Gemini API and Google AI Studio; private preview on the Gemini Enterprise Agent Platform | Endpoints gemini-robotics-er-2-preview and gemini-robotics-er-2-streaming-preview, both with a 131,072-token input limit and a 65,536-token output limit[26][27][35] |
| Gemini Robotics On-Device 2 (July 2026) | Trusted testers, waitlist for early access | Listed as "Trusted testers" on its model page[26][36] |
The embodied reasoning models are also the only ones in the family with published list pricing. As of November 2026, Google's Gemini Developer API pricing page lists gemini-robotics-er-2-preview on the paid tier at 1.00 US dollar per million input tokens (text, image, video, or audio) and 5.00 dollars per million output tokens including thinking tokens through December 31, 2026, rising to 2.00 and 10.00 dollars from January 1, 2027, with a free tier; context caching costs 0.10 dollars per million tokens plus 0.50 dollars per million tokens per hour of storage, doubling to 0.20 and 1.00 dollars in 2027. The streaming endpoint carries the same token rates.[34] At launch in July 2026 the ER 2 rates were 2.00 and 10.00 dollars, and the since-retired gemini-robotics-er-1.6-preview was listed at 1.00 dollar per million input tokens for text, image, and video (2.00 dollars for audio) and 5.00 dollars per million output tokens.[47]
Google's developer materials for Gemini 2.5 highlight related primitives that complement Gemini Robotics, including the Live API for real-time voice interaction with robots, function-calling for defining robot APIs as tools, and code-generation patterns for pick-and-place planning. These primitives are exposed through Google AI Studio, the Gemini API, and Vertex AI for any application built on Gemini 2.5, not just the dedicated robotics models.[25]
What is Gemini Robotics used for?
The public deployments of Gemini Robotics fall into several broad use cases.
| Use case | Examples | Models involved |
|---|---|---|
| Industrial inspection | Reading analog gauges, thermometers, sight glasses, and digital displays during autonomous patrol with Boston Dynamics Spot | Gemini Robotics-ER 1.6[6][19] |
| Household tasks | Sorting laundry, packing snacks into bags, folding garments, organizing shoes by handwritten instructions | Gemini Robotics, Gemini Robotics 1.5, Gemini Robotics On-Device, Gemini Robotics-ER 1.5 (Spot shoe demo)[1][3][23] |
| Multi-step agentic missions | Sorting trash and recycling using local rules looked up via Google Search, then physically placing each object in the correct bin | Gemini Robotics 1.5 + Gemini Robotics-ER 1.5[4] |
| Research demonstrations | Origami folding, slam-dunking small basketballs, drawing cards, pouring salad dressing | Gemini Robotics, Gemini Robotics On-Device[1][3][10] |
The combination of Gemini Robotics-ER and a vision-language-action model has been pitched as a generic agent loop for embodied tasks: the planner inspects the scene, decomposes the goal into sub-tasks, calls a VLA or external API for each step, and uses success detection to decide whether to retry or move on.[4][7]
How does Gemini 4 Argon relate to Gemini Robotics?
On October 13, 2026, the day Google opened Gemini 4 Argon to developers, enterprises and consumers, Kanishka Rao, a principal software engineer at Google, published "Gemini 4 Argon for Robotics" on the Google Developers Blog.[37][38] Argon is Google's general frontier model rather than a member of the Gemini Robotics family. The post calls it "a general-purpose physical reasoning model" that "can be applied across the entire robotics lifecycle," and developers reach it through the paid tier of the general Gemini API under the model code gemini-4-argon.[37][39] Neither the robotics post nor Google's Argon launch post presents Argon as a replacement for the Gemini Robotics models or explains how the two are meant to be combined. After the post, the Gemini Robotics product page still listed the three Gemini Robotics 2 models, and Google's robotics API guide names Gemini Robotics ER 2 as "the latest model in Gemini Robotics."[8][35]
The two also act on robots differently. The Gemini Robotics VLA models turn visual input and instructions into motor commands,[20] while the Gemini API lists text as Argon's only output type. In Google's examples Argon works through generated code, physics simulators and robot interfaces, such as a Spot manipulation "skill" or motion primitives sent to a robot server over HTTP.[37][39]
Google reports that Argon scores 87% on ERQA, the embodied reasoning benchmark it open-sourced as part of the original Gemini Robotics release, "using pure reasoning," and says the score is higher than that of every other frontier model.[37][42] The post groups its demonstrations into four areas.[37]
| Area | Demonstration in Google's post | Reported result |
|---|---|---|
| Robot control | Argon directs a Boston Dynamics Spot (12-DoF legs plus a 6-DoF arm) to pick up soda cans and drop them into a foot-pedal trash bin, first practicing the pedal step in an articulated MuJoCo digital twin of the bin | No success rate or trial count given |
| Robot control | Zero-shot control of a simple robot arm, using a calibrated wrist-camera grid and code-as-policies motion primitives, to stand a fallen mug upright and put a napkin inside | Task completed over several turns; no success rate given |
| Robot control | Steering robot hands inside the Gemini Omni video world model with timestamped prompts to arrange Scrabble tiles into "ARGON" | 33-step steered video rollout |
| Real2Sim | Building a MuJoCo twin of a real teleoperation episode, with assets and scene tuned in an iterative loop to match simulated visuals and fingertip contact events to the logged data | Qualitative |
| Real2Sim | Retargeting an egocentric human video onto a 76-DoF bimanual humanoid with 22-DoF five-fingered hands in MuJoCo | Qualitative |
| Real2Sim | Turning a pen-and-paper sketch of an Apollo 2 humanoid throwing a ball into a mujoco_warp scene and a whole-body throwing trajectory | All 6 target boxes knocked down in simulation |
| Physical understanding | Hindsight labeling of a 136-second ALOHA 2 episode of folding an origami fox | 6 subtasks, 17 contact-level primitives, and down-weighting of fumbles and retries |
| Physical understanding | Dense value function (task progress) for a 60-second bimanual ring-sorting episode from a human UMI gripper dataset | 28 segments labeled with positive, neutral or negative progress |
| Research and self-improvement | From one overhead RGB photo, a calibrated MuJoCo twin, a 77-task curriculum and more than 4,500 simulated episodes used to fine-tune a generalist VLA on a bimanual Franka FR3 setup | Real-robot success rate 56% to 75%; completion time 35 s to 24 s |
| Research and self-improvement | Pick and place on an SO-101 arm improved through trial and self-reflection | 58.9 s, then 22.9 s, then 17.4 s across three iterations |
| Research and self-improvement | One-prompt reproductions of robotics control papers as MuJoCo WebAssembly browser labs | 68 browser sandboxes |
The post does not name the VLA model that was fine-tuned on the simulated episodes.[37] Google's Argon launch post adds a hardware result from what it calls an internal test: Argon watched a raw video of a person playing cornhole, mapped the scene's spatial coordinates, calculated whole-body joint movements and wrote the simulation code, and when the result was transferred to Apptronik's Apollo humanoid the robot "quickly sank seven consecutive shots in a real-world trial." Google calls this a "Video-to-Sim-to-Real" pipeline and says it "compresses weeks of manual simulation modeling into a few hours."[38]
All of these figures are Google's own. MLQ.ai noted that the post gives no success rate, trial count or failure analysis for the Spot task and no independent replication of the simulation-data result, and argued that a model with text-only API output suits high-level planning, code generation, simulation and analysis better than a low-latency motor-control loop.[40] Humanoid Guide described the cornhole result as "an internal demonstration of one throwing task, rather than a general measure of robot competence."[41]
How was Gemini Robotics received?
Reception of the launch combined enthusiasm about scope with skepticism about real-world readiness. Stanford bioengineer Jan Liphardt told MIT Technology Review that the missing piece between cognition, large language models, and decision-making was an intermediate level of physical intelligence, and that Gemini Robotics was a credible attempt to fill that gap.[10] IEEE Spectrum noted that the dexterity demonstrations applied to specific high-quality training data rather than fully general skills, and that the embodied reasoning model's reliance on human-centric training data could produce suboptimal grasps for some robotic end effectors.[11]
MIT Technology Review's hands-on commentary observed that the demonstrations remained "quite slow and a little janky," while crediting the underlying generalization with a clear step up from prior systems.[10] Axios characterized the launch as the moment the humanoid robot industry started to converge with frontier AI labs, with Google DeepMind, Apptronik, Boston Dynamics, and Agility Robotics all named in the same announcement.[24]
Later coverage of Gemini Robotics-ER 1.6 focused on the Boston Dynamics Spot inspection deployment. Resultsense, summarizing Ars Technica, noted that the commercial test is whether the accuracy gains hold at operational scale, and that Boston Dynamics had not disclosed failure modes or comparisons against human inspectors.[19]
What are the limitations of Gemini Robotics?
Google DeepMind has acknowledged several limitations of the Gemini Robotics family in its own materials and in interviews. The cloud-served VLA depends on a network connection, which constrains deployments where bandwidth or latency is unreliable; the on-device model addresses this but trades some capability for size, with average task success closer to 60% than to the cloud variant's roughly 80% in Google's own evaluations.[3][17] Generalization gains depend heavily on the training data mix, and dexterous tasks such as origami folding require careful per-task data curation rather than emerging fully zero-shot.[11]
The reasoning model can hallucinate spatial properties or affordances, and the September 2025 release added explicit physical-feasibility checks to filter out plans the planner generated but the robot could not safely execute.[7] Demonstrations remain comparatively slow: MIT Technology Review described the launch videos as "quite slow and a little janky," and the July 2026 launch post itself says the robots "have more to advance in movement speed."[10][26]
Finally, Gemini Robotics models are largely closed: weights are not published, and access is gated through partner programs, the Gemini Robotics SDK trusted-tester waitlist, and the Gemini API for the embodied reasoning models. This contrasts with peers such as OpenVLA, whose weights and training data are public, and limits independent reproduction of Google's benchmark numbers.[12]
Continue reading
- Gemini (language model)Gemini is a family of natively multimodal large language models developed by Google DeepMind, first announced on December 6, 2023, that can reason across text, images, audio, video, and code within a single…Mentioned 194 times above
- RoboticsRobotics is the interdisciplinary study and engineering of robots: embodied machines whose mechanisms, sensors, computation, and actuators are organized to perform tasks in the physical world.Mentioned 172 times above
- Google DeepMindGoogle DeepMind is an artificial intelligence research and model-development organization at Google.Mentioned 32 times above
- Gemini Robotics 2Gemini Robotics 2 is a family of three robotics models announced by Google DeepMind on July 30, 2026: a vision-language-action (VLA) model of the same name, an embodied reasoning model called Gemini Robotics…Mentioned 15 times above
- ApptronikApptronik is an American robotics company headquartered in Austin, Texas, that designs and builds humanoid robots for commercial and industrial applications.Mentioned 14 times above
- Boston DynamicsBoston Dynamics is an American robotics company that develops mobile robots for industrial inspection, logistics, research, and material handling.Mentioned 12 times above
More from See also
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20Google DeepMind. "Gemini Robotics brings AI into the physical world." March 12, 2025. deepmind.google/...ings-ai-into-the-physical-world
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12Google. "Gemini Robotics and Gemini Robotics-ER are two new Gemini models designed for robotics." March 12, 2025. blog.google/...gemini-robotics
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11Google DeepMind. "Gemini Robotics On-Device brings AI to local robotic devices." June 24, 2025. deepmind.google/...ngs-ai-to-local-robotic-devices
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17Google DeepMind. "Gemini Robotics 1.5 brings AI agents into the physical world." September 25, 2025. deepmind.google/...-agents-into-the-physical-world
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Google DeepMind. "Gemini Robotics-ER 1.6: Powering real-world robotics tasks through enhanced embodied reasoning." April 14, 2026. deepmind.google/...gemini-robotics-er-1-6
- ^1 ^2 ^3 ^4 ^5Boston Dynamics. "Tools for Your To Do List with Spot and Gemini Robotics." bostondynamics.com/...ith-spot-and-gemini-robotics
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Kendra Byrne and Fei Xia. "Building the Next Generation of Physical Agents with Gemini Robotics-ER 1.5." Google Developers Blog, September 25, 2025. developers.googleblog.com/...gemini-robotics-er-15
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Google DeepMind. "Gemini Robotics product page." deepmind.google/...gemini-robotics
- Google. "How we built the new family of Gemini Robotics models." blog.google/...how-we-built-gemini-robotics
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Scott J. Mulligan. "Gemini Robotics uses Google's top language model to make robots more useful." MIT Technology Review, March 12, 2025. technologyreview.com/...to-make-robots-more-useful
- ^1 ^2 ^3 ^4Eliza Strickland and Evan Ackerman. "With Gemini Robotics, Google Aims for Smarter Robots." IEEE Spectrum, March 12, 2025. spectrum.ieee.org/gemini-robotics
- ^1 ^2Pebblous. "Three Teams, Three Robot Brains: A Head-to-Head Comparison of GR00T, Gemini, and Pi Architectures." blog.pebblous.ai/...en
- ^1 ^2Google. "How we built the new family of Gemini Robotics models." Google Blog. blog.google/...how-we-built-gemini-robotics
- ^Google DeepMind. "Gemini Robotics 1.5 model page." deepmind.google/...gemini-robotics (as of July 2026 this URL redirects to the Gemini Robotics 2 model page)
- ^1 ^2 ^3Interesting Engineering. "Apollo humanoid robot tackles unknown objects with Google DeepMind." interestingengineering.com/...pollo-humanoid-robot
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10Google DeepMind robotics team. "Gemini Robotics: Bringing AI into the Physical World." arXiv preprint 2503.20020, March 25, 2025. arxiv.org/...2503.20020
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Anthony Alford. "Google DeepMind Announces Robotics Foundation Model Gemini Robotics On-Device." InfoQ, July 2025. infoq.com/...google-gemini-robotics
- ^1 ^2 ^3 ^4Anthony Alford. "DeepMind Releases Gemini Robotics-ER 1.5 for Embodied Reasoning." InfoQ, September 2025. infoq.com/...deepmind-gemini-robotics
- ^1 ^2 ^3 ^4 ^5 ^6Eugenio Reyes. "Gemini Robotics-ER 1.6 hits 98% gauge-reading accuracy on Boston Dynamics Spot." Resultsense, April 16, 2026. resultsense.com/...-robotics-er-instrument-reading
- ^1 ^2Google DeepMind. "Gemini Robotics product family page." deepmind.google/...gemini-robotics
- Eugene Demaitre. "Gemini Robotics 1.5 enables agentic experiences, explains Google DeepMind." The Robot Report, September 25, 2025. therobotreport.com/...ces-explains-google-deepmind
- ^1 ^2Google DeepMind. "Responsibly advancing AI and robotics." deepmind.google/...sibly-advancing-ai-and-robotics
- ^1 ^2Boston Dynamics. "Tools for Your To Do List with Spot and Gemini Robotics." bostondynamics.com/...ith-spot-and-gemini-robotics
- ^Ina Fried. "New humanoid robots get smarter with Google's AI." Axios, March 12, 2025. axios.com/...gle-humanoid-robotics-gemini-deepmind
- ^Google for Developers. "Gemini 2.5 for robotics and embodied intelligence." developers.googleblog.com/...embodied-intelligence
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26Carolina Parada. "Gemini Robotics 2 brings whole body intelligence to robots." Google DeepMind, July 30, 2026. deepmind.google/...ole-body-intelligence-to-robots
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10Steven Hansen and Peng Xu. "Introducing Gemini Robotics ER 2." Google, The Keyword, July 30, 2026. blog.google/...gemini-robotics-er-2
- ^1 ^2 ^3Google DeepMind. "Gemini Robotics ER 2 model card." July 30, 2026. deepmind.google/...gemini-robotics-er-2
- ^1 ^2Google DeepMind. "Gemini Robotics On-Device 2 model card." July 30, 2026. deepmind.google/...gemini-robotics-on-device-2
- ^1 ^2 ^3 ^4 ^5Gemini Robotics Team, Google DeepMind. "Gemini Robotics 2: Safety Evaluations." July 29, 2026 (PDF). storage.googleapis.com/...ni-Robotics-2-Safety.pdf
- ^1 ^2 ^3Google DeepMind. "Gemini Robotics 2 model page." Accessed July 31, 2026. deepmind.google/...vla
- ^1 ^2Google. "Gemini API deprecations." Accessed October 15, 2026. ai.google.dev/...deprecations
- ^Maria Deutscher. "Google DeepMind debuts Gemini Robotics 2 model series for humanoid robots." SiliconANGLE, July 30, 2026. siliconangle.com/...2-model-series-humanoid-robots
- ^Google. "Gemini Developer API pricing." Accessed November 2, 2026. ai.google.dev/...pricing
- ^1 ^2Google. "Gemini Robotics ER." Gemini API documentation, last updated October 29, 2026. ai.google.dev/...robotics-overview
- ^Google DeepMind. "Gemini Robotics On-Device 2 model page." Accessed July 31, 2026. deepmind.google/...on-device
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Kanishka Rao. "Gemini 4 Argon for Robotics." Google Developers Blog, October 13, 2026. developers.googleblog.com/...-4-argon-for-robotics
- ^1 ^2 ^3Koray Kavukcuoglu. "Gemini 4 Argon: Built to solve your hardest problems." Google, The Keyword, October 13, 2026. blog.google/...introducing-gemini-4-argon
- ^1 ^2Google. "Gemini 4 Argon." Gemini API documentation. Accessed October 15, 2026. ai.google.dev/...gemini-4-argon
- ^MLQ.ai. "Google's Gemini 4 Argon turns robot video and sketches into simulation and control code." MLQ News, October 14, 2026. mlq.ai/...ketches-into-simulation-and-control-code
- ^Humanoid Guide. "Google demonstrates Gemini 4 Argon robotics on Apollo humanoid." October 14, 2026. humanoid.guide/...rgon-robotics-on-apollo-humanoid
- ^Google DeepMind. "Embodied Reasoning QA Evaluation Dataset (ERQA)." GitHub repository, embodiedreasoning/ERQA. github.com/...ERQA
- ^Gemini Robotics Team, Google DeepMind. "Gemini Robotics 1.5: Pushing the Frontier of Generalist Robots with Advanced Embodied Reasoning, Thinking, and Motion Transfer." arXiv preprint 2510.03342, October 2025. arxiv.org/...2510.03342
- ^1 ^2Moo Jin Kim et al. "OpenVLA: An Open-Source Vision-Language-Action Model." arXiv preprint 2406.09246, June 2024. arxiv.org/...2406.09246
- ^1 ^2Kevin Black et al. "pi0: A Vision-Language-Action Flow Model for General Robot Control." arXiv preprint 2410.24164, October 2024. arxiv.org/...2410.24164
- ^1 ^2Anthony Brohan et al. "RT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control." arXiv preprint 2307.15818, July 2023. arxiv.org/...2307.15818
- ^Google. "Gemini Developer API pricing." Internet Archive copy of July 31, 2026. web.archive.org/...pricing
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
10 revisions · v10 · 7,386 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (175 claims, 50 sources fetched); 7 material + 20 minor fixed
Cite this page: AI Wiki. "Gemini Robotics." aiwiki.ai, updated 28 Oct 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/gemini_robotics