

HotpotQA
HotpotQA is a large-scale, multi-hop question answering dataset of about 112,779 crowd-authored question-and-answer pairs over English Wikipedia, whose answers cannot be found in any single paragraph and instead require reasoning across two documents. Each example ships with sentence-level supporting facts that mark exactly which sentences justify the answer, which is why the project page describes it as "a question answering dataset featuring natural, multi-hop questions, with strong supervision for supporting facts to enable more explainable question answering systems." [1][2] It was introduced in HotpotQA: A Dataset for Diverse, Explainable Multi-hop Question Answering by Zhilin Yang, Peng Qi, Saizheng Zhang, Yoshua Bengio, William W. Cohen, Ruslan Salakhutdinov, and Christopher D. Manning, presented at EMNLP 2018 in Brussels and posted to arXiv on 25 September 2018 as 1809.09600. [1] It was the first large multi-hop reading-comprehension dataset where annotators wrote the questions themselves and marked the supporting sentences, and it became one of the standard testbeds for retrieval-augmented generation and tool-using language models.
The dataset is released under the same Creative Commons Attribution-ShareAlike 4.0 license as Wikipedia. [2] The official leaderboard, code, and downloads are hosted at hotpotqa.github.io.
Quick facts
| Field | Value |
|---|---|
| Released | 25 September 2018 (arXiv preprint); EMNLP, 31 October 2018 |
| Paper | Yang et al. 2018, arXiv:1809.09600 |
| Authors | Zhilin Yang, Peng Qi, Saizheng Zhang, Yoshua Bengio, William W. Cohen, Ruslan Salakhutdinov, Christopher D. Manning |
| Affiliations | Carnegie Mellon University, Stanford NLP Group, Universite de Montreal / Mila, Google AI |
| Total questions | ~112,779 (90,564 train, 7,405 dev, 7,405 distractor test, 7,405 fullwiki test) |
| Domain | English Wikipedia (introduction paragraphs) |
| Question types | Bridge questions (~80%), comparison questions (~20%) |
| Settings | Distractor (10 paragraphs) and Fullwiki (open domain over ~5M articles) |
| Metrics | Exact Match (EM) and F1 on Answer and Supporting Facts; Joint EM/F1 |
| License | Creative Commons Attribution-ShareAlike 4.0 |
| Leaderboard | hotpotqa.github.io |
What problem was HotpotQA built to solve?
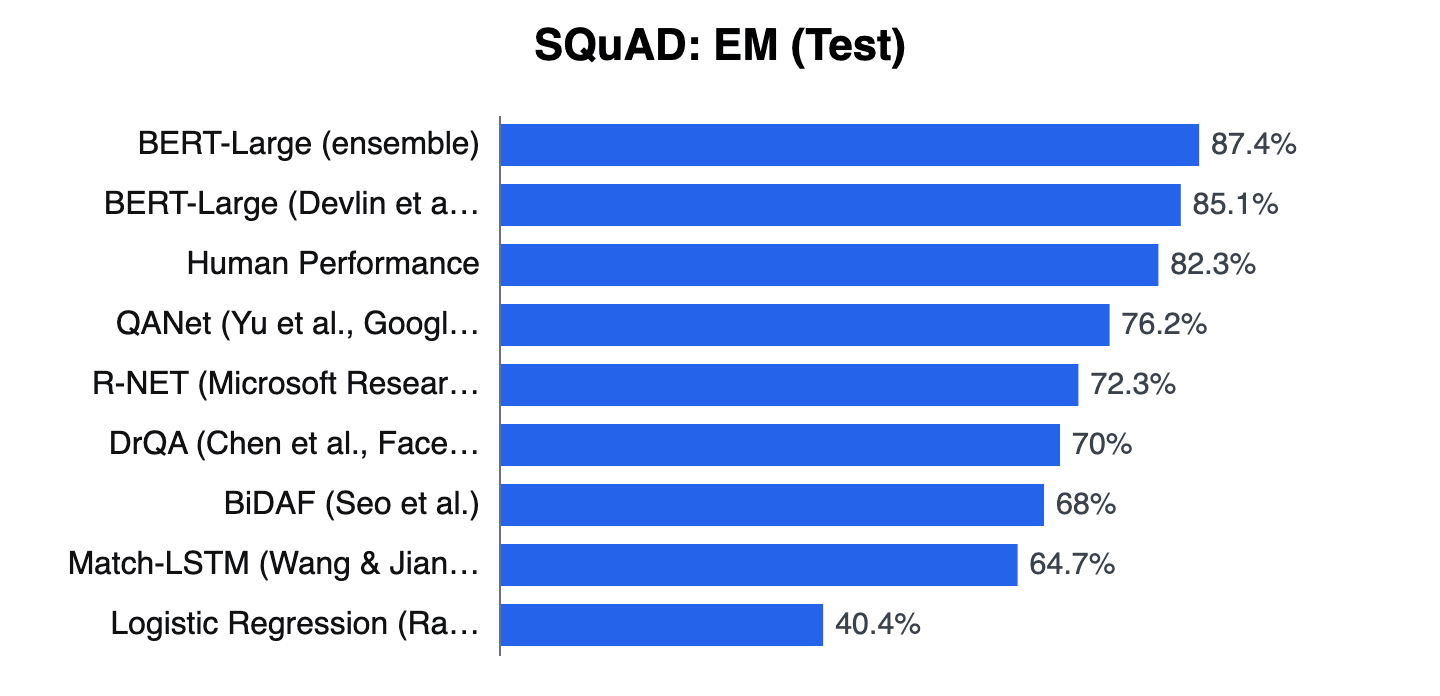
Before HotpotQA, the most influential reading-comprehension benchmark was the Stanford Question Answering Dataset, or SQuAD, released by Rajpurkar et al. in 2016. [3] SQuAD 1.1 contained 100,000 questions written against single Wikipedia paragraphs, and SQuAD 2.0 (Rajpurkar, Jia, and Liang, 2018) added 50,000 unanswerable questions. [3][4] By mid-2018 several systems had matched or exceeded the human exact-match score on SQuAD 1.1 (human F1 score fell only later in 2018), suggesting the format was close to saturated and was an incomplete proxy for reading comprehension. SQuAD answers are spans inside one paragraph, so a model can succeed by aligning the question to a single sentence and copying.
A second wave of datasets had begun to test reasoning across multiple documents. WikiHop, part of the QAngaroo collection (Welbl, Stenetorp, and Riedel, 2018), generated multi-hop questions automatically from Wikipedia and Wikidata triples and asked models to choose between candidate entities. [5] ComplexWebQuestions (Talmor and Berant, 2018) transformed Freebase queries into natural-language questions whose answer required composing facts from several web pages. [6] TriviaQA (Joshi et al. 2017) and SearchQA (Dunn et al. 2017) added long evidence chains, although their multi-hop content was incidental rather than required.
These earlier datasets had limitations. WikiHop questions were synthesized from knowledge-base templates, so the language was rigid and many questions could be answered by lexical overlap on a single document. None of them annotated which sentences a system needed to read. The HotpotQA authors set out to build a dataset that combined natural human-written language, true multi-hop dependency, sentence-level evidence supervision, and a freely licensed source corpus. The paper states its four design goals directly: the questions "require finding and reasoning over multiple supporting documents to answer"; they "are diverse and not constrained to any pre-existing knowledge bases or knowledge schemas"; the dataset provides "sentence-level supporting facts required for reasoning"; and it offers "a new type of factoid comparison questions." [1]
How was HotpotQA built?
The HotpotQA team built the dataset on Amazon Mechanical Turk during 2017 and 2018. The pipeline started from a hyperlink graph over the introduction paragraphs of English Wikipedia. The authors used the English Wikipedia dump of October 1, 2017 and kept only the lead paragraphs, since these contain a high concentration of factual sentences and are short enough for crowd workers to read quickly. [1] They sampled pairs of articles connected by hyperlinks, treating one article as the bridge entity that the question would route through.
For each pair, a worker saw the two paragraphs and was asked to write a question whose answer required information from both, plus the answer itself and the specific supporting sentences. To isolate likely single-hop questions, the authors moved questions from top contributors whose samples were mostly single-hop into a train-easy split, and questions that a baseline model answered with high confidence into train-medium; only the remaining hard examples were used for dev and test. Workers earned bonuses for productivity, and the ParlAI-based interface gave in-the-loop feedback and hints. [1]
HotpotQA contains two question types. Bridge questions, about 80 percent of the corpus, ask about an entity that links the two paragraphs. An example from the development set is "What government position was held by the woman who portrayed Corliss Archer in the film Kiss and Tell?" The first paragraph identifies the actress (Shirley Temple), and the second names her role as Chief of Protocol. [1] Comparison questions, about 20 percent of the corpus, contrast two entities on a shared attribute, for example "Were Scott Derrickson and Ed Wood of the same nationality?" These often have yes or no answers and require the model to extract a property from each paragraph and compare it. [1]
The authors also included yes-no questions (about 6 percent of all answers) and a small fraction of comparison questions whose answers are dates or numbers requiring arithmetic. All other answers are extractive spans. Each example is annotated with a small set of supporting sentences drawn from the gold paragraphs, about 2.4 on average in the development set. [1] The final release contains 90,564 training questions (split into 18,089 easy, 56,814 medium, and 15,661 hard examples), 7,405 development questions, and 7,405 hidden test questions for each of the two evaluation settings, for a public total of about 112,779 questions. [1]
Splits and statistics
| Split | Questions | Notes |
|---|---|---|
| Train | 90,564 | Easy (18,089), medium (56,814), and hard (15,661); gold paragraphs and supporting facts visible |
| Dev | 7,405 | All hard, gold supervision visible |
| Distractor test | 7,405 | Hidden answers; 10 paragraphs per question (2 gold, 8 distractors) |
| Fullwiki test | 7,405 | Hidden answers; system must retrieve from full Wikipedia |
| Question type | Share | Example pattern |
|---|---|---|
| Bridge | ~80% | First paragraph identifies an entity, second paragraph supplies the answer |
| Comparison | ~20% | Compare two entities on a shared attribute (often yes-no, date, or number) |
What are the two evaluation settings?
HotpotQA evaluates models in two regimes that share the same question set but differ in retrieval difficulty.
The distractor setting hands the system 10 paragraphs per question, and as the project page puts it, "a question-answering system reads 10 paragraphs to provide an answer (Ans) to a question." [2] Two of the 10 are the gold paragraphs containing the supporting facts; the other eight are distractors retrieved by a bigram TF-IDF query over the question against all Wikipedia introductions. [1] The model must read those 10 paragraphs, return the answer span (or yes / no), and predict which sentences are supporting facts. This setting isolates multi-hop reasoning and explanation from the open-domain retrieval problem.
The fullwiki setting is an open-domain task in which a system "must find the answer to a question in the scope of the entire Wikipedia." [2] The model receives only the question and must retrieve, read, and reason over the full corpus of about 5 million Wikipedia articles. The fullwiki setting is much harder because the gold paragraphs are buried in millions of distractors, and a retrieval miss on either of the two required paragraphs makes the question effectively unanswerable.
Four metrics are reported on each setting. Answer EM and Answer F1 measure exact-match accuracy and token-level F1 against the gold answer. Supporting Facts EM and F1 measure how accurately the model identifies the gold supporting sentences. Joint EM and Joint F1 require both the answer and all supporting facts to be correct in the same example. The leaderboard ranks systems primarily by Joint F1 inside each setting.
| Setting | Inputs | Difficulty | Metrics |
|---|---|---|---|
| Distractor | 10 paragraphs (2 gold + 8 IR distractors) | Reading and reasoning only | Ans EM/F1, Sup EM/F1, Joint EM/F1 |
| Fullwiki | Question + entire Wikipedia (~5M articles) | Retrieval and reasoning | Ans EM/F1, Sup EM/F1, Joint EM/F1 |
How well did the original baseline and humans do?
The original paper trained a baseline reader combining a recurrent question encoder, character-level embeddings, a self-attention layer, and a span pointer, with an auxiliary loss for predicting supporting facts. This model was a modified version of Clark and Gardner's 2018 simple-and-effective SQuAD reader, extended with supporting-fact heads.
On the distractor setting, the baseline reached 58.28 Answer F1 and 40.86 Joint F1 on the development set (58.99 Answer F1 and 41.37 Joint F1 on test), well below human performance. [1] On fullwiki the baseline retrieved with TF-IDF over Wikipedia introductions and dropped to 34.36 Answer F1 and 17.73 Joint F1 on dev (34.40 and 17.85 on test). [1] On a 1,000-example sample, the original crowd workers scored 83.60 Answer EM, 91.40 Answer F1, and 82.55 Joint F1 against answers from at least three additional workers (the baseline model scored 68.99 Answer F1 and 52.37 Joint F1 on the same sample), while the human upper bound, which scores each worker's answer against all the other workers' answers and keeps the maximum, reached 96.80 Answer EM, 98.77 Answer F1, 87.40 Supporting-Facts EM, and 96.37 Joint F1. [1] The large gap between the baseline and humans, especially on Joint F1, was the original motivation for the leaderboard.
How well do models perform on HotpotQA?
The HotpotQA leaderboard tracked steady progress for several years. Reference points below are taken from the official leaderboard at hotpotqa.github.io and the corresponding papers. [2]
In 2019 the first wave of strong systems appeared. DecompRC (Min, Zhong, Zettlemoyer, and Hajishirzi, 2019) decomposed each multi-hop question into single-hop sub-questions and answered each independently with a SQuAD-style reader, scoring 70.6 Answer F1 on distractor dev and 69.6 on test. [7] GoldEn Retriever (Qi, Lin, Mehr, Wang, and Manning, 2019) interleaved retrieval and reading and reached about 37.9 Answer EM on fullwiki. [8] Cognitive Graph QA (Ding, Zhou, Yang, and Tang, 2019) built a graph of entity nodes during reading and used a graph neural network to score answers, reaching 34.9 Joint F1 on the fullwiki test set. [9]
In 2020 systems built on BERT and its successors pushed numbers further. HGN, the Hierarchical Graph Network of Fang et al. (2020), tied paragraphs, sentences, entities, and answer candidates together with graph attention over a RoBERTa encoder, reaching 82.2 Answer F1 and 74.2 Joint F1 on distractor test. [10] Asai et al. (2020) introduced a learned path retriever that walked the Wikipedia hyperlink graph and reached 60.0 Answer EM on the fullwiki test set. [11] Longformer (Beltagy, Peters, and Cohan, 2020) showed that a long-context sparse-attention transformer, in a two-stage paragraph-selection-then-reading setup, came within about a point of graph-based systems (73.2 versus 74.2 Joint F1 on distractor test for HGN). [12]
Later systems combined dense retrieval with stronger readers. MDR, the Multi-hop Dense Retriever of Xiong et al. (2021), trained a recurrent dense encoder that issued the next query conditioned on retrieved evidence and pushed fullwiki to 62.3 Answer EM, 75.3 Answer F1, and 66.6 Joint F1 on test, the largest single jump in the open-domain setting. [13] Beam Retrieval (2023) reached 85.0 Answer F1 and 77.5 Joint F1 on the distractor test set, the top distractor entry on the official leaderboard as of November 2026. [2]
Large language models entered the leaderboard alongside fine-tuned systems. Press et al. 2022 introduced Self-Ask, in which GPT-3 asks itself sub-questions and answers them with a search tool, raising performance over standard chain-of-thought prompting on other multi-hop sets (2WikiMultiHopQA, MuSiQue, and Bamboogle) rather than HotpotQA. [23] ReAct (Yao et al. 2022) interleaved reasoning traces with Wikipedia search actions, scoring 27.4 EM with PaLM-540B, slightly below chain-of-thought (29.4), while a combination of ReAct with self-consistent chain-of-thought reached 35.1 EM. [24] IRCoT (Trivedi et al. 2023) interleaved retrieval with chain-of-thought steps using GPT-3 and code-davinci-002, reporting 49.3 Answer EM and 60.7 Answer F1 on 500 sampled development questions. [25]
GPT-4 and Claude evaluations have appeared in retrieval-augmented setups rather than as a single leaderboard number, since the questions and gold paragraphs are openly available and may overlap with training data. Retrieval-augmented methods such as Adaptive-RAG (2024) use HotpotQA as one of their multi-hop evaluation sets.
| System (Year) | Setting | Answer EM | Answer F1 | Joint F1 |
|---|---|---|---|---|
| Yang et al. baseline (2018) | distractor dev | 44.4 | 58.3 | 40.9 |
| Yang et al. baseline (2018) | fullwiki dev | 24.7 | 34.4 | 17.7 |
| DecompRC (2019) | distractor test | 55.2 | 69.6 | -- |
| GoldEn Retriever (2019) | fullwiki test | 37.9 | 48.6 | 39.1 |
| Cognitive Graph (2019) | fullwiki test | 37.1 | 48.9 | 34.9 |
| HGN-large (2020) | distractor test | 69.2 | 82.2 | 74.2 |
| Asai et al. path retriever (2020) | fullwiki test | 60.0 | 73.0 | 61.2 |
| Longformer-large (2020) | distractor test | 68.0 | 81.3 | 73.2 |
| MDR (2021) | fullwiki test | 62.3 | 75.3 | 66.6 |
| ReAct then CoT-SC, PaLM-540B (2022) | open, no fine-tune | 35.1 | -- | -- |
| IRCoT GPT-3 (2023) | open, no fine-tune | 49.3 | 60.7 | -- |
| Human (1,000-example sample) | dev/test sample | 83.6 | 91.4 | 82.6 |
| Human upper bound | distractor sample | 96.8 | 98.8 | 96.4 |
Numbers above are taken from the original papers and from the official leaderboard at hotpotqa.github.io, checked in November 2026. Verification dates and exact ranks shift over time, so the leaderboard remains the authoritative source for current scores. [2]
How is HotpotQA used for RAG and tool use?
HotpotQA became a default evaluation dataset for retrieval-augmented generation and tool-using language models. The questions are short and factual, with crisp ground-truth answers and small evidence sets, so they are cheap to evaluate. Each question is genuinely two-hop, which exposes whether a system can chain a second retrieval step rather than relying on a single best-paragraph match. The underlying corpus, Wikipedia, is the same corpus most retrieval systems use, so the dataset doubles as a test of multi-hop reasoning and a test of reading inside that corpus.
ReAct (Yao et al. 2022) used HotpotQA as its headline evaluation for tool-augmented prompting. [24] IRCoT (Trivedi et al. 2023) followed the same pattern. [25] Adaptive-RAG (Jeong et al. 2024) used HotpotQA as one of its multi-hop test beds. The dataset has functioned as a standard reference point, somewhat like SQuAD did for single-hop reading.
What are the main criticisms of HotpotQA?
HotpotQA has faced substantial scrutiny since its release.
The most cited critique is by Min, Wallace, Singh, Gardner, Hajishirzi, and Zettlemoyer (2019), Compositional Questions Do Not Necessitate Multi-hop Reasoning. [14] The paper showed that for a large share of HotpotQA bridge questions, a single-paragraph BERT reader given only one of the two gold paragraphs could produce the correct answer with reasonable accuracy. Their manual analysis of 100 bridge questions found that only 27% required multi-hop reasoning; most of the rest could be answered from one paragraph because the distractors were weak (35%) or the question contained redundant evidence (26%), and a single-paragraph BERT reader reached 67.08 F1. Chen and Durrett (2019) reached a similar conclusion: sentence-factored models that by design cannot do multi-hop reasoning still solved a large number of HotpotQA examples. [15] Min et al. also showed that adversarially chosen distractors cut single-paragraph BERT from 67.08 to 46.84 F1, though retraining on such distractors recovered most of the loss (60.10) [14]. Trivedi et al. (2020) estimated that only 18 of XLNet's 72 answer F1 points on HotpotQA came from genuine multifact reasoning. [16]
A second criticism is the gap between the distractor and fullwiki settings. The distractor setting is closer to a reading-comprehension task, while fullwiki is a retrieval-and-reading task whose primary bottleneck is recall over five million articles. Models that win the distractor leaderboard often do worse on fullwiki and vice versa, meaning the two settings measure different abilities under the same name.
A third issue is leaderboard saturation in the distractor setting. By 2023 the best distractor-setting system reached 85.0 Answer F1 [2], about six points below the 91.4 measured for crowd workers and well short of the 98.8 upper bound [1]. The fullwiki setting still has clear headroom against human performance.
What datasets followed HotpotQA?
Several later datasets were designed in part to address HotpotQA's weaknesses. 2WikiMultiHopQA (Ho, Nguyen, Sugawara, and Aizawa, 2020) generated 192,606 multi-hop questions from Wikipedia and Wikidata using templates and structured triples, with explicit reasoning paths on every example. [17] MuSiQue (Trivedi et al. 2022) built about 25,000 multi-hop questions by composing single-hop questions from existing datasets and removing reasoning shortcuts; previous strong models on HotpotQA dropped sharply on MuSiQue, supporting the claim that HotpotQA had latent shortcuts. [18]
IIRC (Ferguson et al. 2020) collected 13,441 questions where the supporting context is incomplete in the visible passage. [19] StrategyQA (Geva et al. 2021) covered 2,780 yes-no questions whose decomposition is implicit. [20] MultiRC (Khashabi et al. 2018), released a few months before HotpotQA, is a related multi-sentence reading-comprehension dataset of about 6,000 questions. [21]
Dense-retrieval and retrieval-augmented benchmarks have included HotpotQA inside larger evaluation suites. BEIR (Thakur et al. 2021) used HotpotQA as a multi-hop entry in its zero-shot retrieval suite. [27] KILT (Petroni et al. 2021) covered HotpotQA along with several other knowledge-intensive tasks under a unified Wikipedia snapshot. [28] MultiHop-RAG (Tang and Yang, 2024) built a news-article multi-hop benchmark for retrieval-augmented LLMs, citing HotpotQA among earlier multi-document QA datasets. [29]
Is HotpotQA open source?
Yes. HotpotQA is distributed under the Creative Commons Attribution-ShareAlike 4.0 license, the same license as Wikipedia content. [2] The training and development sets, including all answers and supporting-fact annotations, are publicly downloadable as JSON files from the project page. The test sets are released without answers; predictions must be submitted to the official evaluation server. The dataset, baseline models, evaluation script, and Wikipedia paragraph dump are hosted under the hotpotqa GitHub organization.
The primary author, Zhilin Yang, was a PhD student at Carnegie Mellon University under Ruslan Salakhutdinov and William W. Cohen at the time of release. He later founded the Chinese AI lab Moonshot AI, known for the Kimi family of long-context models. Peng Qi was a PhD student in the Stanford NLP Group under Christopher D. Manning, who together with Yoshua Bengio and Salakhutdinov advised the project across institutions.
Continue reading
- Question answeringQuestion answering (QA) is the task of producing an answer to a question, usually expressed in natural language.Mentioned 5 times above
- arXivarXiv is the free, open-access repository where nearly every consequential artificial intelligence paper of the deep learning era first appeared in public, often months before, or instead ofMentioned 3 times above
- Language ModelA language model is a model of patterns in language that assigns probabilities or comparable scores to linguistic sequences. Its units may be characters, words, subwords, bytes, or other tokens.Mentioned 3 times above
- EMNLPEMNLP, the Conference on Empirical Methods in Natural Language Processing, is an annual research conference that is one of the top-tier publication venues in natural language processing (NLP)Mentioned twice above
- Retrieval-Augmented GenerationRetrieval-augmented generation (RAG) is a family of methods that retrieves information from an external collection and conditions a generative model on that information when producing an output.Mentioned twice above
- SQuADSQuAD (the Stanford Question Answering Dataset) is a large-scale reading comprehension benchmark from Stanford University in which a model must answer a question by extracting the exact span of text that…Mentioned 8 times above
More to read
- Yang Zhilin
- TriviaQA
- Chain-of-Thought
- GPT-3
- TF-IDF (Term Frequency-Inverse Document Frequency)
- Longformer
Topics:AI BenchmarksArtificial IntelligenceData & DatasetsNatural Language Processing
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14Yang, Z., Qi, P., Zhang, S., Bengio, Y., Cohen, W. W., Salakhutdinov, R., and Manning, C. D. (2018). *HotpotQA: A Dataset for Diverse, Explainable Multi-hop Question Answering*. Proceedings of EMNLP 2018, pp. 2369-2380. arXiv:1809.09600. arxiv.org/...1809.09600
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9HotpotQA project page and leaderboard. hotpotqa.github.io.
- ^1 ^2Rajpurkar, P., Zhang, J., Lopyrev, K., and Liang, P. (2016). *SQuAD: 100,000+ Questions for Machine Comprehension of Text*. EMNLP.
- ^Rajpurkar, P., Jia, R., and Liang, P. (2018). *Know What You Don't Know: Unanswerable Questions for SQuAD*. ACL.
- ^Welbl, J., Stenetorp, P., and Riedel, S. (2018). *Constructing Datasets for Multi-hop Reading Comprehension Across Documents*. TACL.
- ^Talmor, A., and Berant, J. (2018). *The Web as a Knowledge-Base for Answering Complex Questions*. NAACL.
- ^Min, S., Zhong, V., Zettlemoyer, L., and Hajishirzi, H. (2019). *Multi-hop Reading Comprehension through Question Decomposition and Rescoring*. ACL. (DecompRC)
- ^Qi, P., Lin, X. V., Mehr, L., Wang, Z., and Manning, C. D. (2019). *Answering Complex Open-domain Questions Through Iterative Query Generation*. EMNLP. (GoldEn Retriever)
- ^Ding, M., Zhou, C., Yang, H., and Tang, J. (2019). *Cognitive Graph for Multi-Hop Reading Comprehension at Scale*. ACL.
- ^Fang, Y., Sun, S., Gan, Z., Pillai, R., Wang, S., and Liu, J. (2020). *Hierarchical Graph Network for Multi-hop Question Answering*. EMNLP.
- ^Asai, A., Hashimoto, K., Hajishirzi, H., Socher, R., and Xiong, C. (2020). *Learning to Retrieve Reasoning Paths over Wikipedia Graph for Question Answering*. ICLR.
- ^Beltagy, I., Peters, M. E., and Cohan, A. (2020). *Longformer: The Long-Document Transformer*. arXiv:2004.05150.
- ^Xiong, W., Li, X. L., Iyer, S., Du, J., Lewis, P., Wang, W. Y., Mehdad, Y., Yih, W., Riedel, S., Kiela, D., and Oguz, B. (2021). *Answering Complex Open-Domain Questions with Multi-Hop Dense Retrieval*. ICLR. (MDR)
- ^1 ^2Min, S., Wallace, E., Singh, S., Gardner, M., Hajishirzi, H., and Zettlemoyer, L. (2019). *Compositional Questions Do Not Necessitate Multi-hop Reasoning*. ACL.
- ^Chen, J., and Durrett, G. (2019). *Understanding Dataset Design Choices for Multi-hop Reasoning*. NAACL.
- ^Trivedi, H., Balasubramanian, N., Khot, T., and Sabharwal, A. (2020). *Is Multihop QA in DiRe Condition? Measuring and Reducing Disconnected Reasoning*. EMNLP.
- ^Ho, X., Nguyen, A., Sugawara, S., and Aizawa, A. (2020). *Constructing A Multi-hop QA Dataset for Comprehensive Evaluation of Reasoning Steps*. COLING. (2WikiMultiHopQA)
- ^Trivedi, H., Balasubramanian, N., Khot, T., and Sabharwal, A. (2022). *MuSiQue: Multihop Questions via Single-hop Question Composition*. TACL.
- ^Ferguson, J., Gardner, M., Hajishirzi, H., Khot, T., and Dasigi, P. (2020). *IIRC: A Dataset of Incomplete Information Reading Comprehension Questions*. EMNLP.
- ^Geva, M., Khashabi, D., Segal, E., Khot, T., Roth, D., and Berant, J. (2021). *Did Aristotle Use a Laptop? A Question Answering Benchmark with Implicit Reasoning Strategies*. TACL. (StrategyQA)
- ^Khashabi, D., Chaturvedi, S., Roth, M., Upadhyay, S., and Roth, D. (2018). *Looking Beyond the Surface: A Challenge Set for Reading Comprehension over Multiple Sentences*. NAACL. (MultiRC)
- Brown, T. B., et al. (2020). *Language Models are Few-Shot Learners*. NeurIPS. (GPT-3)
- ^Press, O., Zhang, M., Min, S., Schmidt, L., Smith, N. A., and Lewis, M. (2022). *Measuring and Narrowing the Compositionality Gap in Language Models*. arXiv:2210.03350. (Self-Ask)
- ^1 ^2Yao, S., Zhao, J., Yu, D., Du, N., Shafran, I., Narasimhan, K., and Cao, Y. (2022). *ReAct: Synergizing Reasoning and Acting in Language Models*. arXiv:2210.03629.
- ^1 ^2Trivedi, H., Balasubramanian, N., Khot, T., and Sabharwal, A. (2023). *Interleaving Retrieval with Chain-of-Thought Reasoning for Knowledge-Intensive Multi-Step Questions*. ACL. (IRCoT)
- Schick, T., Dwivedi-Yu, J., Dessi, R., Raileanu, R., Lomeli, M., Hambro, E., Zettlemoyer, L., Cancedda, N., and Scialom, T. (2023). *Toolformer: Language Models Can Teach Themselves to Use Tools*. arXiv:2302.04761.
- ^Thakur, N., Reimers, N., Ruckle, A., Srivastava, A., and Gurevych, I. (2021). *BEIR: A Heterogeneous Benchmark for Zero-shot Evaluation of Information Retrieval Models*. NeurIPS Datasets and Benchmarks.
- ^Petroni, F., et al. (2021). *KILT: a Benchmark for Knowledge Intensive Language Tasks*. NAACL.
- ^Tang, Y., and Yang, Y. (2024). *MultiHop-RAG: Benchmarking Retrieval-Augmented Generation for Multi-Hop Queries*. arXiv:2401.15391.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
5 revisions · v5 · 3,887 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (130 claims, 33 sources fetched); 27 material + 10 minor fixed
Cite this page: AI Wiki. "HotpotQA." aiwiki.ai, updated 23 Jun 2026, fact-checked 4 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/hotpotqa