

Implicit Bias
Implicit bias is an umbrella term that, in artificial intelligence and machine learning, refers to systematic tendencies operating below the surface of explicit design choices. It is used in three distinct senses: (1) unconscious human attitudes and stereotypes (the cognitive sense studied in social psychology) and how they enter AI systems, (2) data and algorithmic bias that cause machine learning models to produce discriminatory or unfair outputs, and (3) the implicit bias (also called implicit regularization) of gradient descent and related optimizers, the tendency of an optimization algorithm to converge to one particular solution among the many that fit the training data equally well. [1][6] These senses interact: human implicit biases shape the data that models learn from, the resulting models inherit and sometimes amplify those biases, and the mathematical implicit bias of the training algorithm determines which solution the model converges to.
This article covers all three meanings because they are commonly conflated and because, in artificial intelligence, they form a single causal chain from human cognition to data to optimization. Understanding the difference matters: the first two are about fairness and harm, while the third is a generalization-theory concept that helps explain why heavily overparameterized neural networks generalize at all.
Explain like I'm 5 (ELI5)
Imagine you are learning to draw animals by copying pictures from a book. If your book only has pictures of dogs, you might think all animals look like dogs. That is a kind of bias from your "training data." Now imagine that when you draw, your hand naturally makes smooth lines instead of jagged ones, even though nobody told you to. That is like the "implicit bias" of how you draw (the algorithm). Both kinds of bias affect what your final drawings look like. In AI, researchers try to make sure the training pictures are fair and represent everyone, and they also study why the drawing process itself tends to produce certain kinds of results.
What is cognitive implicit bias, and how does it enter AI?
Where did the concept of implicit bias come from?
The concept of implicit bias in psychology refers to unconscious attitudes, stereotypes, and associations that influence human judgment and behavior without deliberate intent. The term gained formal scientific grounding in the 1990s through the work of social psychologists Anthony Greenwald and Mahzarin Banaji. In a 1995 paper in Psychological Review, Greenwald and Banaji argued that the distinction between implicit (unconscious) and explicit (conscious) memory applies to social attitudes as well: people can hold automatic associations (for example, linking certain professions with a particular gender) that differ from their stated beliefs. [1] As they put it, "the signature of implicit cognition is that traces of past experience affect some performance, even though the influential earlier experience is not remembered in the usual sense, that is, it is unavailable to self-report or introspection." [1]
In 1998, Greenwald, Debbie McGhee, and Jordan Schwartz introduced the Implicit Association Test (IAT), a reaction-time measure that detects the strength of automatic associations between concepts (such as racial categories) and evaluative attributes (such as "pleasant" or "unpleasant"). [2] The IAT became one of the most widely used tools in social psychology. As of late 2023, more than 40 million IATs had been completed through the Project Implicit research website, roughly one IAT every 21 seconds, across more than 80 million launched study sessions. [15] How well the IAT predicts individual behavior is contested. Meta-analyses have found that IAT scores correlate with discriminatory behavior only weakly (average correlations of roughly 0.10 to 0.27, smaller in the more recent reviews such as Oswald et al. 2013 and Kurdi et al. 2018). [17][19] A 2019 meta-analysis of 492 studies by Forscher and colleagues found that procedures which changed scores on implicit measures produced only trivial changes in behavior. [18]
How does human implicit bias enter AI systems?
Human implicit biases affect AI systems through several pathways:
- Data collection decisions. Researchers and engineers choose what data to collect, how to label it, and which features to include. These decisions can reflect unconscious assumptions. For example, if a medical imaging dataset is collected primarily from hospitals in wealthier regions, the resulting model may perform poorly on populations from underrepresented areas.
- Labeling and annotation. Human annotators bring their own implicit associations to the labeling process. Studies have shown that image labeling tasks can reflect cultural and demographic biases of the annotators.
- Problem framing. The way a prediction task is defined, including the choice of target variable and success metrics, can embed human assumptions. Using arrest records as a proxy for criminal behavior, for example, conflates policing patterns with actual crime rates.
- Confirmation bias in model development. Model builders may unconsciously process results in ways that affirm pre-existing hypotheses, a phenomenon Google's machine learning documentation calls "experimenter's bias."
What is bias in data and algorithms?
What are the types of data bias?
Data bias occurs when the training data used for an ML model does not accurately represent the real-world population or phenomenon the model is intended to serve. Researchers have identified several distinct categories.
| Bias type | Definition | Example |
|---|---|---|
| Historical bias | Data reflects past inequalities or discrimination that existed during collection | A hiring dataset reflecting decades of gender imbalance in an industry |
| Representation bias | Training data under- or over-represents certain groups relative to the target population | A facial recognition dataset containing mostly light-skinned faces |
| Measurement bias | Features used are imperfect proxies for the concepts they are meant to capture | Using zip code as a proxy for socioeconomic status, which correlates with race |
| Aggregation bias | A single model is applied to a diverse population without accounting for subgroup differences | A diabetes prediction model trained without distinguishing between Type 1 and Type 2 diabetes across ethnic groups |
| Sampling bias | Data is collected using non-random methods that produce an unrepresentative sample | An online survey that excludes populations without internet access |
| Evaluation bias | Benchmark datasets or metrics used to assess model performance do not represent all groups equally | A benchmark for natural language understanding that contains text primarily from one dialect |
| Reporting bias | The frequency of events in the data does not match their real-world frequency because people tend to report unusual events | Social media data over-representing extreme opinions relative to the general population |
| Exclusion bias | Relevant data is removed during preprocessing, disproportionately affecting certain groups | Dropping records with missing income data, which may be more common among lower-income respondents |
How does the algorithm itself introduce bias?
Even when training data is balanced, the design of the algorithm itself can introduce or amplify bias. This can happen in several ways:
- Feature selection and weighting. If features that correlate with protected attributes (such as race, gender, or age) receive high weight in the model, the model may effectively discriminate against certain groups even without directly using the protected attribute. This is sometimes called "proxy discrimination."
- Objective function design. An optimization objective that maximizes overall accuracy may sacrifice performance on minority subgroups if doing so improves aggregate metrics.
- Feedback loops. When a model's predictions influence future data collection, biased predictions can become self-reinforcing. For example, if a predictive policing algorithm directs more officers to a neighborhood, more arrests occur there, producing data that further reinforces the model's prediction.
What are the notable real-world cases of AI bias?
Several widely studied examples illustrate how implicit and explicit biases manifest in deployed AI systems.
| System | Domain | Bias discovered | Year reported |
|---|---|---|---|
| COMPAS | Criminal justice | A 2016 ProPublica analysis of more than 7,000 Broward County defendants found Black defendants were almost twice as likely to be labeled higher risk without going on to reoffend (44.9%) as white defendants (23.5%) [5] | 2016 |
| Amazon recruiting tool | Hiring | The system, trained on 10 years of mostly male resumes, penalized resumes containing the word "women's" and downgraded graduates of two all-women's colleges; Amazon scrapped it [16] | 2018 |
| Gender Shades (commercial facial recognition) | Computer vision | Joy Buolamwini and Timnit Gebru found error rates of 0.8% for light-skinned males but up to 34.7% for dark-skinned females across systems from IBM, Microsoft, and Face++ [4] | 2018 |
| Google Photos auto-tagging | Image classification | The system labeled photos of Black individuals with an offensive animal category | 2015 |
| Word embeddings (Word2Vec, GloVe) | Natural language processing | Bolukbasi et al. showed that embeddings encoded stereotypical associations such as "man is to computer programmer as woman is to homemaker" [3] | 2016 |
| Healthcare risk prediction (Optum) | Healthcare | A widely used algorithm assigned lower risk scores to Black patients than to equally sick white patients because it used healthcare spending as a proxy for health needs; correcting it would raise the share of Black patients flagged for extra help from 17.7% to 46.5% [11] | 2019 |
The healthcare case studied by Obermeyer et al. (2019) is among the most cited. The authors concluded that "remedying this disparity would increase the percentage of Black patients receiving additional help from 17.7 to 46.5%," and that reformulating the algorithm to target health rather than cost reduced the measured bias by 84%. [11]
What is the implicit bias of gradient descent (implicit regularization)?
In a separate but related technical sense, "implicit bias" in deep learning refers to the tendency of optimization algorithms, especially gradient descent and its variants, to converge to particular solutions among the many that perfectly fit the training data. [6] This phenomenon is also called implicit regularization because it produces an effect similar to adding an explicit regularization penalty (such as L1 or L2 regularization) without the practitioner specifying one. [7]
Why does implicit bias matter for generalization?
Modern deep neural networks are heavily overparameterized: they have far more learnable parameters than training examples. Classical statistical theory predicts that such models should overfit severely and fail to generalize to unseen data. Yet in practice, gradient-descent-trained deep networks generalize well. The implicit bias of the optimization algorithm is widely believed to be a key explanation for this generalization puzzle. [7]
Behnam Neyshabur's 2017 work "Implicit Regularization in Deep Learning" formalized this observation, arguing that the optimization procedure itself biases models toward lower-complexity solutions that generalize better, even in overparameterized regimes. [7]
What are the key theoretical results on implicit bias?
Research on implicit bias in optimization has produced several foundational results.
How does gradient descent converge to the max-margin solution?
For linear classifiers trained with gradient descent on the logistic loss with linearly separable data, Daniel Soudry, Elad Hoffer, Mor Shpigel Nacson, Suriya Gunasekar, and Nathan Srebro proved in 2018 that the solution converges in direction to the maximum-margin (hard-margin SVM) solution. In their words, "we show the predictor converges to the direction of the max-margin (hard margin SVM) solution," and "this convergence is very slow, and only logarithmic in the convergence of the loss itself." [6] Concretely, the direction converges at a rate of order , where t is the number of iterations, and the result generalizes to any monotone decreasing loss function with an infimum at infinity, to multi-class problems, and to a single weight layer in a restricted deep-network setting. [6] This helps explain the benefit of continuing to minimize the cross-entropy loss even after the training error reaches zero.
For linear regression with squared error loss, gradient flow (the continuous-time limit of gradient descent) converges to the minimum L2-norm interpolator when started from zero (in general, to the interpolator closest to the initialization). In other words, among all solutions that fit the training data perfectly, gradient descent selects the one with the smallest Euclidean norm of parameters.
How do parameterization and initialization change the implicit bias?
The implicit bias changes depending on how the model is parameterized and initialized. Gunasekar et al. (2017) gave evidence that gradient descent on a factorized parameterization started near zero is biased toward minimum nuclear norm solutions, with the diagonal special case giving minimum-L1-norm predictors. Woodworth et al. (2020) showed that the scale of the initialization controls the transition: diagonal linear networks initialized near zero are biased toward sparse, minimum-L1-norm predictors (similar to Lasso), while large initialization gives the minimum-L2-norm (kernel regime) solution, the same one a standard linear model reaches from zero initialization. [20][21]
| Setting | Initialization | Implicit bias |
|---|---|---|
| Linear model (standard parameterization) | Any | Interpolator closest in L2 distance to the initialization (the minimum L2-norm solution when started from zero) [22] |
| Diagonal linear network ( reparameterization) | Small (near zero) | Minimum L1-norm solution (sparse, similar to Lasso) |
| Diagonal linear network | Large | Minimum L2-norm solution |
| Deep matrix factorization | Small | Low-rank solutions; bias toward low rank strengthens with depth |
| Single neuron with strictly monotonic activation (leaky ReLU, sigmoid), square loss | Any | Zero-loss solution closest in L2 distance to the initialization [22] |
| ReLU networks | Varies | Not expressible as any explicit function of the parameters, even for a single ReLU neuron with the square loss [22] |
These results demonstrate that architecture and initialization jointly determine the form of implicit regularization, which in turn affects which solution the optimizer finds.
What role does stochastic gradient descent play?
Stochastic gradient descent (SGD), which uses random mini-batches rather than the full dataset, introduces additional implicit regularization beyond what full-batch gradient descent provides. Smaller batch sizes produce noisier gradient estimates, which tend to drive the solution toward flatter minima in the loss surface. Flat minima are empirically associated with better generalization.
Other training hyperparameters also modulate implicit bias. Momentum, learning rate schedules, and weight decay all interact with the optimization trajectory to shape which solution the model converges to.
What are the recent developments?
Research from 2024 and 2025 has extended the theory in several directions:
- Connections between implicit bias and neural scaling laws suggest that norm growth during training is a key variable controlling how performance scales with model size and data.
- Studies of two-layer ReLU networks have revealed fine-grained structural biases, where hidden-layer weights align with class-average feature directions.
- Work on adversarial robustness has shown that the implicit bias of standard gradient descent can lead to non-robust solutions, motivating the study of alternative training procedures.
How does implicit bias differ from inductive bias?
Closely related to implicit bias is the concept of inductive bias (also called learning bias), which refers to the set of assumptions a learning algorithm uses to make predictions on inputs it has not seen during training. [14] While implicit bias of optimization describes the preference among solutions that fit the data equally well, inductive bias more broadly encompasses any prior assumption built into the model's architecture, algorithm, or representation.
What are the types of inductive bias?
| Type | Description | Example |
|---|---|---|
| Restriction bias (language bias) | Limits the hypothesis space the model can consider | Linear regression can only represent linear relationships |
| Preference bias (search bias) | Favors certain hypotheses over others within the hypothesis space | Decision trees prefer shorter trees (Occam's razor) |
| Relational bias | Assumes relationships between features | Convolutional neural networks assume local spatial correlations in images |
How does inductive bias vary by algorithm?
Different ML algorithms encode different inductive biases.
| Algorithm | Inductive bias |
|---|---|
| Linear regression | The relationship between input features and the target is linear |
| k-nearest neighbors | Nearby points in feature space belong to the same class (locality assumption) |
| Support vector machines | Classes are separated by wide margins in feature space |
| Convolutional neural networks | Translation invariance and local connectivity; patterns are equally meaningful regardless of spatial position |
| Recurrent neural networks | Sequential dependencies matter; recent inputs are more relevant than distant ones |
| Transformers | All positions can attend to all other positions (self-attention); no strict locality or ordering assumption |
| Decision trees | Axis-aligned splits in feature space; preference for shorter trees |
| Naive Bayes | Features are conditionally independent given the class label |
The choice of inductive bias determines what a model can and cannot learn efficiently. A well-matched inductive bias allows a model to generalize from limited data, while a poorly matched one leads to underfitting or failure to capture the true data structure.
How is bias measured? Fairness metrics
Quantifying bias requires formal metrics. Several widely used fairness definitions have been proposed, each capturing a different aspect of equitable treatment.
| Metric | Definition | Satisfied when |
|---|---|---|
| Demographic parity | The probability of receiving a positive prediction is equal across groups | for all groups a, b |
| Equalized odds | True positive rates and false positive rates are equal across groups | for |
| Equal opportunity | True positive rates are equal across groups (relaxation of equalized odds) | |
| Disparate impact ratio | Ratio of positive prediction rates between groups | (the "four-fifths rule" used in U.S. employment law) |
| Predictive parity | Positive predictive values are equal across groups | |
| Calibration | Predicted probabilities reflect true outcome rates equally across groups | Among all individuals assigned probability p, the fraction of positives is p, for all groups |
| Counterfactual fairness | The prediction would remain the same in a counterfactual world where the individual belonged to a different group | for every context x [23] |
Why can't all fairness metrics be satisfied at once?
An important theoretical finding, sometimes called the "impossibility theorem" of fairness (established independently by Chouldechova in 2017 and Kleinberg, Mullainathan, and Raghavan in 2016), shows that calibration and error-rate balance (equal false positive and false negative rates across groups) cannot all be satisfied simultaneously unless the base rates of the outcome are equal across groups. [8][9] This means that practitioners must make deliberate choices about which fairness criterion to prioritize, and these choices involve value judgments that go beyond technical optimization. [8]
How does implicit bias show up in word embeddings and language models?
Word embeddings are dense vector representations of words learned from large text corpora. Because these corpora reflect societal biases present in the text, the resulting embeddings encode those biases in their geometric structure.
What did Bolukbasi et al. (2016) find?
In an influential 2016 paper titled "Man is to Computer Programmer as Woman is to Homemaker? Debiasing Word Embeddings," Tolga Bolukbasi, Kai-Wei Chang, James Zou, Venkatesh Saligrama, and Adam Kalai demonstrated that a 300-dimensional Word2Vec embedding with a vocabulary of 3 million words and phrases, trained on Google News text, contained gender stereotypes. [3] Vector arithmetic showed, for example, that the analogy "man : computer_programmer :: woman : ?" resolved to "homemaker." The paper proposed a debiasing method based on identifying a "gender subspace" in the embedding space (via principal component analysis of gender-defining word pairs) and projecting non-gender-specific words away from that subspace. In a human evaluation, the share of generated analogies judged stereotypical fell from 19% before debiasing to 6% after. [3]
Why was early debiasing insufficient?
Subsequent research revealed that the Bolukbasi method was insufficient. Even after debiasing, the original bias could be partially recovered from the modified embeddings, and words with similar biases remained clustered together in the vector space. This led to more sophisticated debiasing approaches, including "Double-Hard Debias" and contextual debiasing methods applied to large language models such as BERT and GPT.
How does bias appear in large language models?
Large language models trained on internet text inherit and can amplify biases present in their training corpora. Studies have documented stereotypical associations in model outputs, disparities in toxicity detection across dialects, and differential performance on tasks involving different demographic groups. The scale of these models makes bias auditing and mitigation more challenging than in smaller embedding-based systems.
What strategies mitigate bias?
Bias mitigation techniques are typically categorized by the stage of the ML pipeline at which they intervene.
Pre-processing methods
Pre-processing techniques modify the training data before it reaches the model.
- Resampling and reweighting. Oversampling underrepresented groups, undersampling overrepresented ones, or assigning different weights to training instances to balance group representation.
- Fair representation learning. Transforming the data into a new feature space that retains task-relevant information while removing or reducing the influence of sensitive attributes. The "Learning Fair Representations" framework by Zemel et al. (2013) is a foundational example. [10]
- Data augmentation. Generating synthetic examples for underrepresented groups to balance the dataset.
- Label correction. Identifying and correcting biased labels in the training data.
In-processing methods
In-processing techniques modify the learning algorithm itself.
- Fairness constraints. Adding constraints to the optimization objective that enforce a chosen fairness metric during training, such as requiring demographic parity or equalized odds.
- Adversarial debiasing. Training a secondary adversarial network that attempts to predict the protected attribute from the model's internal representations; the main model is then penalized for making this prediction easy.
- Regularization penalties. Adding penalty terms to the loss function that penalize differences in predictions across groups.
Post-processing methods
Post-processing techniques adjust the model's predictions after training.
- Threshold adjustment. Using different classification thresholds for different groups to equalize a chosen fairness metric.
- Calibration. Adjusting predicted probabilities so that they are equally well-calibrated across groups.
- Output relabeling. Changing some predictions to satisfy fairness constraints, typically by flipping the predictions closest to the decision boundary.
How do the three approaches compare?
| Stage | Advantages | Disadvantages |
|---|---|---|
| Pre-processing | Model-agnostic; can be applied to any downstream model | May discard useful information; limited if bias is structural |
| In-processing | Directly optimizes for fairness during training; can achieve strong fairness guarantees | Requires access to training procedure; fairness-accuracy tradeoffs may be steep |
| Post-processing | Does not require retraining; can be applied to black-box models | Cannot fix biased internal representations; limited to adjusting outputs |
What software toolkits detect and mitigate bias?
Several open-source toolkits provide implementations of fairness metrics and mitigation algorithms.
| Toolkit | Developer | Key features |
|---|---|---|
| AI Fairness 360 (AIF360) | IBM Research | Over 70 fairness metrics, 10+ mitigation algorithms; available in Python and R [12] |
| Fairlearn | Microsoft | Group fairness metrics (MetricFrame) with matplotlib plotting (the former interactive dashboard is no longer part of Fairlearn), mitigation algorithms including Exponentiated Gradient and Grid Search; Python package |
| What-If Tool | Visual exploration of model behavior across groups; integrated with TensorBoard; strong for evaluation but limited mitigation algorithms | |
| Aequitas | University of Chicago | Bias audit toolkit focused on group fairness metrics; easy-to-use Python API |
| ML-fairness-gym | Simulation framework for studying long-term effects of fairness interventions in dynamic settings |
How is AI bias regulated?
Governments and international organizations have begun to address AI bias through regulation and policy frameworks.
What does the EU AI Act require?
The European Union's AI Act (Regulation (EU) 2024/1689) entered into force on August 1, 2024. It classifies AI systems by risk level and imposes the strictest requirements on "high-risk" systems used in areas such as employment, law enforcement, and access to essential services. Article 10 requires providers of high-risk AI systems to use training, validation, and testing datasets that are "relevant, sufficiently representative, and to the best extent possible, free of errors and complete," and to examine those datasets for "possible biases" and take mitigation measures. [13] Providers must implement data governance practices covering data collection, preparation, and bias detection, and systems that keep learning after deployment must be designed to reduce the risk of biased outputs feeding back into future training. The high-risk obligations were originally due to apply from August 2, 2026, but the AI Omnibus amendment (Regulation (EU) 2026/1744, in force since July 27, 2026) postponed them to December 2, 2027 for stand-alone high-risk systems listed in Annex III, such as employment and law enforcement uses, and to August 2, 2028 for AI embedded in regulated products. [13][24]
What is the United States approach?
The U.S. approach has been more fragmented. The White House Blueprint for an AI Bill of Rights (2022) outlined principles including protection against algorithmic discrimination, but it is non-binding. Executive Order 14110 on Safe, Secure, and Trustworthy AI (October 2023) directed federal agencies to address algorithmic discrimination, but Executive Order 14148 revoked it on January 20, 2025. [25] Several jurisdictions regulate AI in hiring: New York City's Local Law 144 requires a bias audit of automated employment decision tools within one year before use, and Illinois and Colorado have enacted laws addressing algorithmic discrimination in employment decisions. [26]
What other frameworks exist?
The OECD AI Principles (adopted 2019, updated 2024) recommend that AI systems be designed to respect human rights and democratic values, including fairness and non-discrimination. The UNESCO Recommendation on the Ethics of AI (2021) calls for member states to implement measures to prevent AI-driven discrimination.
How do the three senses of implicit bias connect?
The three meanings of implicit bias discussed in this article are not independent. They form a causal chain:
- Human implicit biases shape data collection, labeling, and problem formulation, introducing systematic distortions into training datasets. [1]
- Data and algorithmic biases in the ML pipeline propagate and sometimes amplify these distortions, producing models that discriminate against certain groups. [4][11]
- The implicit bias of the optimization algorithm determines which solution the model converges to among the many that fit the (biased) data. In some cases, the optimizer's implicit regularization can interact with data biases in ways that either mitigate or exacerbate unfair outcomes. [6]
For example, the implicit bias of gradient descent toward simpler solutions (lower-norm, lower-rank) can lead to models that rely on easily separable features, which in some cases are proxies for protected attributes. Conversely, explicit regularization strategies motivated by the theory of implicit bias (such as constraining model complexity) can sometimes reduce reliance on spurious correlations that produce unfair outcomes.
Understanding all three senses of implicit bias gives practitioners a more complete picture of where bias enters the ML pipeline and what tools are available to address it.
Continue reading
- BiasBias in artificial intelligence carries three distinct technical meanings: a learnable scalar parameter added inside a neuron, the systematic error component of an estimator (the "bias" in the bias-variance…Mentioned 98 times above
- RegularizationRegularization is any deliberate change to a learning problem or training algorithm intended to improve performance on data that were not used to fit the model.Mentioned 11 times above
- Fairness MetricA fairness metric is a quantitative, mathematical measure used to evaluate whether a machine learning model's predictions or decisions treat different demographic groups equitably.Mentioned 8 times above
- Fairness ConstraintA fairness constraint is an explicit mathematical condition imposed on a machine learning model during training, evaluation, or post-processing that forces its predictions to satisfy a specified group-fairness…Mentioned twice above
- Disparate ImpactDisparate impact is a legal and statistical concept describing situations where a seemingly neutral policy, practice, or algorithm produces disproportionately adverse outcomes for members of a protected class…Listed in See also
- OverfittingOverfitting is a failure of generalization: a fitted model or a model-selection procedure performs better on the observations used to develop it than on new observations from the population of interest.Listed in See also
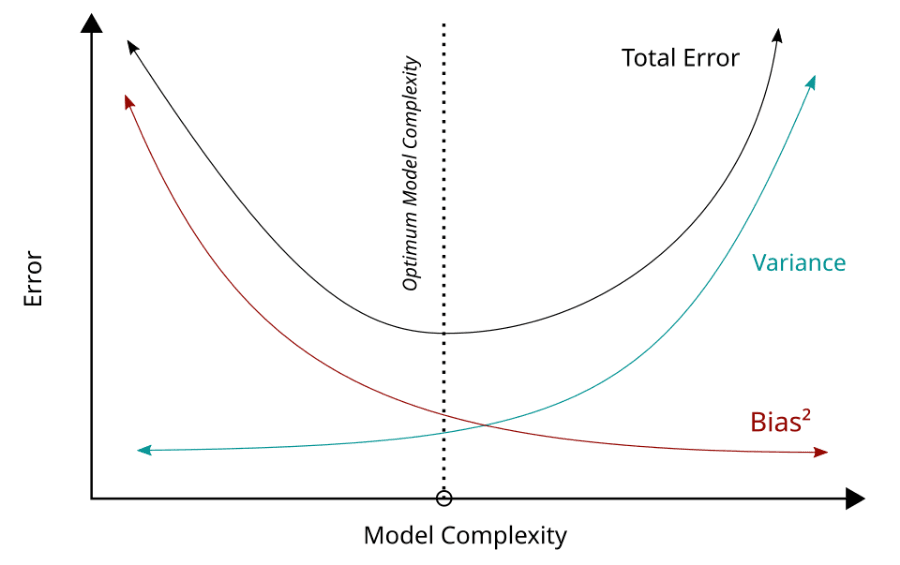
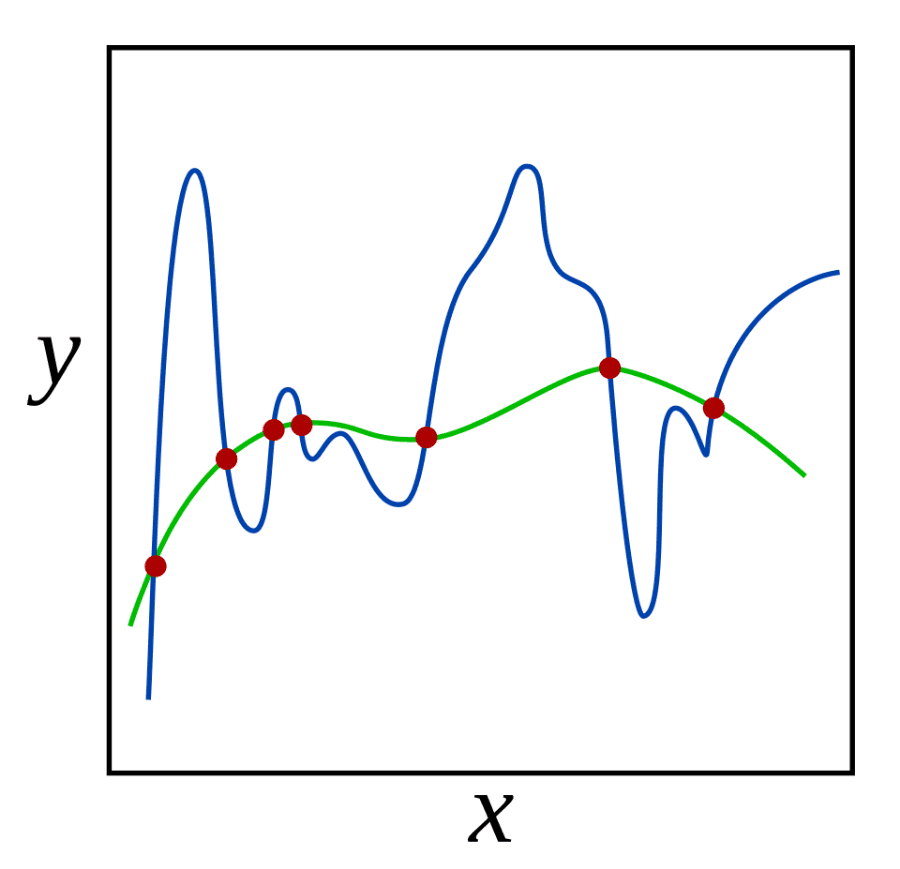
More from See also
More to read
Topics:AI EthicsMachine Learning
References
- ^1 ^2 ^3 ^4Greenwald, A. G., & Banaji, M. R. (1995). "Implicit social cognition: Attitudes, self-esteem, and stereotypes." *Psychological Review*, 102(1), 4-27.
- ^Greenwald, A. G., McGhee, D. E., & Schwartz, J. L. K. (1998). "Measuring individual differences in implicit cognition: The Implicit Association Test." *Journal of Personality and Social Psychology*, 74(6), 1464-1480.
- ^1 ^2 ^3Bolukbasi, T., Chang, K. W., Zou, J., Saligrama, V., & Kalai, A. (2016). "Man is to Computer Programmer as Woman is to Homemaker? Debiasing Word Embeddings." *Advances in Neural Information Processing Systems*, 29.
- ^1 ^2Buolamwini, J., & Gebru, T. (2018). "Gender Shades: Intersectional Accuracy Disparities in Commercial Gender Classification." *Proceedings of the Conference on Fairness, Accountability and Transparency*, 77-91.
- ^Angwin, J., Larson, J., Mattu, S., & Kirchner, L. (2016). "Machine Bias: There's software used across the country to predict future criminals. And it's biased against blacks." *ProPublica*.
- ^1 ^2 ^3 ^4 ^5Soudry, D., Hoffer, E., Nacson, M. S., Gunasekar, S., & Srebro, N. (2018). "The Implicit Bias of Gradient Descent on Separable Data." *Journal of Machine Learning Research*, 19(70), 1-57.
- ^1 ^2 ^3Neyshabur, B. (2017). "Implicit Regularization in Deep Learning." *arXiv preprint arXiv:1709.01953*.
- ^1 ^2Chouldechova, A. (2017). "Fair prediction with disparate impact: A study of bias in recidivism prediction instruments." *Big Data*, 5(2), 153-163.
- ^Kleinberg, J., Mullainathan, S., & Raghavan, M. (2017). "Inherent Trade-Offs in the Fair Determination of Risk Scores." *Proceedings of Innovations in Theoretical Computer Science (ITCS 2017)*. arXiv:1609.05807 (2016).
- ^Zemel, R., Wu, Y., Swersky, K., Pitassi, T., & Dwork, C. (2013). "Learning Fair Representations." *Proceedings of the 30th International Conference on Machine Learning (ICML)*, 325-333.
- ^1 ^2 ^3Obermeyer, Z., Powers, B., Vogeli, C., & Mullainathan, S. (2019). "Dissecting racial bias in an algorithm used to manage the health of populations." *Science*, 366(6464), 447-453.
- ^Bellamy, R. K. E., et al. (2019). "AI Fairness 360: An extensible toolkit for detecting and mitigating algorithmic bias." *IBM Journal of Research and Development*, 63(4/5), 4:1-4:15.
- ^1 ^2European Parliament and Council of the European Union. (2024). "Regulation (EU) 2024/1689 laying down harmonised rules on artificial intelligence (AI Act)," Article 10. *Official Journal of the European Union*.
- ^Mitchell, T. M. (1980). "The need for biases in learning generalizations." *CBM-TR 5-110*, Rutgers University. (Early formalization of inductive bias.)
- ^Ratliff, K. A., & Smith, C. T. (2024). "The Implicit Association Test." *Daedalus*, 153(1), 51-64. (Reports more than 40 million IATs completed at Project Implicit, roughly one every 21 seconds.)
- ^Dastin, J. (2018). "Amazon scraps secret AI recruiting tool that showed bias against women." *Reuters*.
- ^Greenwald, A. G., & Lai, C. K. (2020). "Implicit Social Cognition." *Annual Review of Psychology*, 71, 419-445.
- ^Forscher, P. S., Lai, C. K., Axt, J. R., Ebersole, C. R., Herman, M., Devine, P. G., & Nosek, B. A. (2019). "A meta-analysis of procedures to change implicit measures." *Journal of Personality and Social Psychology*, 117(3), 522-559.
- ^Oswald, F. L., Mitchell, G., Blanton, H., Jaccard, J., & Tetlock, P. E. (2013). "Predicting ethnic and racial discrimination: A meta-analysis of IAT criterion studies." *Journal of Personality and Social Psychology*, 105(2), 171-192.
- ^Gunasekar, S., Woodworth, B., Bhojanapalli, S., Neyshabur, B., & Srebro, N. (2017). "Implicit Regularization in Matrix Factorization." *Advances in Neural Information Processing Systems*, 30. arXiv:1705.09280.
- ^Woodworth, B., Gunasekar, S., Lee, J. D., Moroshko, E., Savarese, P., Golan, I., Soudry, D., & Srebro, N. (2020). "Kernel and Rich Regimes in Overparametrized Models." arXiv:2002.09277.
- ^1 ^2 ^3Vardi, G., & Shamir, O. (2021). "Implicit Regularization in ReLU Networks with the Square Loss." arXiv:2012.05156.
- ^Kusner, M. J., Loftus, J., Russell, C., & Silva, R. (2017). "Counterfactual Fairness." *Advances in Neural Information Processing Systems*, 30. arXiv:1703.06856.
- ^National Law Review. (2026). "EU Digital Omnibus on AI Enters into Force." natlawreview.com/...igital-omnibus-ai-enters-force
- ^Executive Office of the President. (2025). "Initial Rescissions of Harmful Executive Orders and Actions" (Executive Order 14148). *Federal Register*. federalregister.gov/...xecutive-orders-and-actions
- ^NYC Department of Consumer and Worker Protection. "Automated Employment Decision Tools (AEDT)." nyc.gov/...automated-employment-decision-tools.page
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
9 revisions · v9 · 5,177 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (85 claims, 27 sources fetched); 8 material + 20 minor fixed
Cite this page: AI Wiki. "Implicit Bias." aiwiki.ai, updated 27 Jun 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/implicit_bias