

NVIDIA Hopper
NVIDIA Hopper is the codename for NVIDIA's ninth-generation datacenter GPU microarchitecture, announced March 22, 2022 by CEO Jensen Huang at the GTC keynote.[1] Hopper succeeds the Ampere architecture used in the NVIDIA A100 and is the foundation for the NVIDIA H100, the NVIDIA H200, and the GH200 Grace Hopper Superchip.[2] The architecture is named after Rear Admiral Grace Hopper, the U.S. Navy computer scientist who developed the first compiler and helped create COBOL.[9]
Hopper was the workhorse of the generative AI boom from 2022 through 2024. Many frontier large language models trained during that period ran on H100 clusters, including Meta's Llama 3.1 405B. GPT-4 is not among them (it finished training in August 2022, before H100 was available), and Google trained its Gemini models on its own TPUs.[18][19][20] The architecture introduced fourth-generation Tensor Cores with the FP8 numerical format, the Transformer Engine for dynamic precision selection, fourth-generation NVLink at 900 GB/s, the NVLink Switch System for 256-GPU domains, and the Tensor Memory Accelerator for asynchronous data movement.[2] At launch NVIDIA quantified the generational gain as up to 9x faster training on a 395-billion-parameter Mixture-of-Experts model and up to 30x higher inference throughput on a Megatron 530B chatbot compared to A100.[17] Hopper was eventually succeeded by NVIDIA Blackwell in 2024, but the large installed base of H100 and H200 GPUs remained a major share of datacenter AI capacity into 2026.
When was Hopper announced?
NVIDIA announced Hopper on March 22, 2022 during the GTC spring keynote. Jensen Huang revealed the H100 GPU as the first product based on the new GH100 die, manufactured by TSMC on a custom 4N process node (a 5nm-class derivative tuned specifically for NVIDIA).[1] At launch NVIDIA said H100 would be available starting in the third quarter of 2022, in SXM5 and PCIe form factors.[17] Framing the launch, Huang said: "Data centers are becoming AI factories, processing and refining mountains of data to produce intelligence. NVIDIA H100 is the engine of the world's AI infrastructure that enterprises use to accelerate their AI-driven businesses."[17]
The codename follows NVIDIA's tradition of naming microarchitectures after pioneering scientists. Earlier generations included Tesla, Fermi, Kepler, Maxwell, Pascal, Volta, Turing, and Ampere. Hopper sits between Ampere (A100, 2020) and Blackwell (B100/B200, 2024).[9] The naming is paired with the Grace CPU, also developed by NVIDIA, which targets the Arm server market and combines with Hopper in the GH200 superchip module.[5]
Hopper arrived at the moment that demand for large language model training was beginning to explode. By late 2022, after the launch of ChatGPT, every major AI lab and hyperscaler was attempting to acquire as many H100s as possible. The chip was effectively allocated rather than sold for most of 2023 and 2024, with reported lead times stretching past a year at the peak.
What products are in the Hopper family?
The Hopper family covers SXM and PCIe accelerators, an export-restricted China variant, and a CPU+GPU superchip module.
| Product | Announced | Memory | Bandwidth | TDP | Form factor |
|---|---|---|---|---|---|
| H100 SXM5 | March 2022 | 80 GB HBM3 | 3.35 TB/s | 700 W | SXM5 module |
| H100 PCIe | 2022 | 80 GB HBM2e | 2 TB/s | 350 W | Dual-slot PCIe |
| H100 NVL | March 2023 | 188 GB total (94 GB per card, 2 cards) | 3.9 TB/s per GPU | 350 to 400 W per card | Dual PCIe with NVLink bridge |
| H800 | Late 2022 | 80 GB | 3.35 TB/s | 700 W | China-export variant with reduced NVLink |
| H200 SXM | November 13, 2023 | 141 GB HBM3e | 4.8 TB/s | 700 W | SXM5 module |
| H200 NVL | November 2024 | 141 GB HBM3e | 4.8 TB/s | 600 W | Dual-slot PCIe |
| GH200 (HBM3) | May 2023 production | 96 GB HBM3 + 480 GB LPDDR5X | 4 TB/s GPU | Up to 1000 W module | Superchip module |
| GH200 NVL2 | August 2023 | 282 GB HBM3e (2 superchips) | 10 TB/s combined | Module | Dual superchip |
| GH200 (HBM3e) | August 2023 announcement, Q2 2024 ship | 141 GB HBM3e usable (144 GB physical) + 480 GB LPDDR5X | 5 TB/s GPU | Up to 1000 W module | Superchip module |
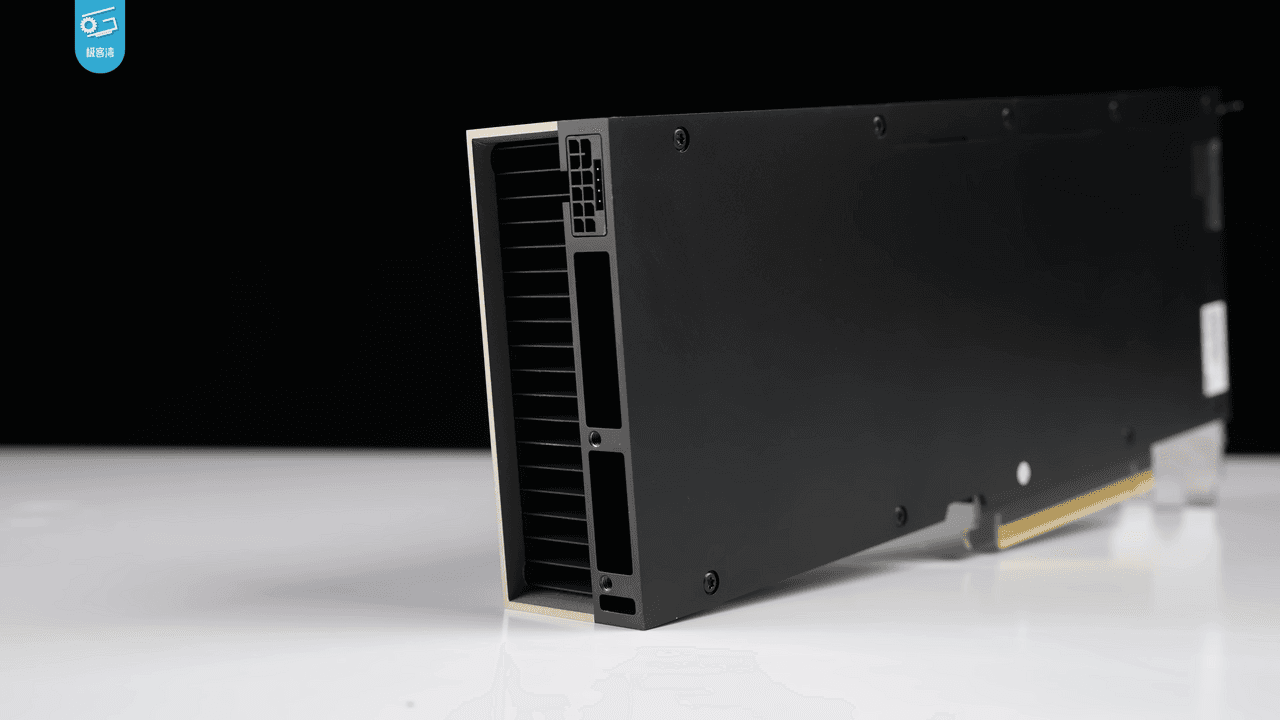
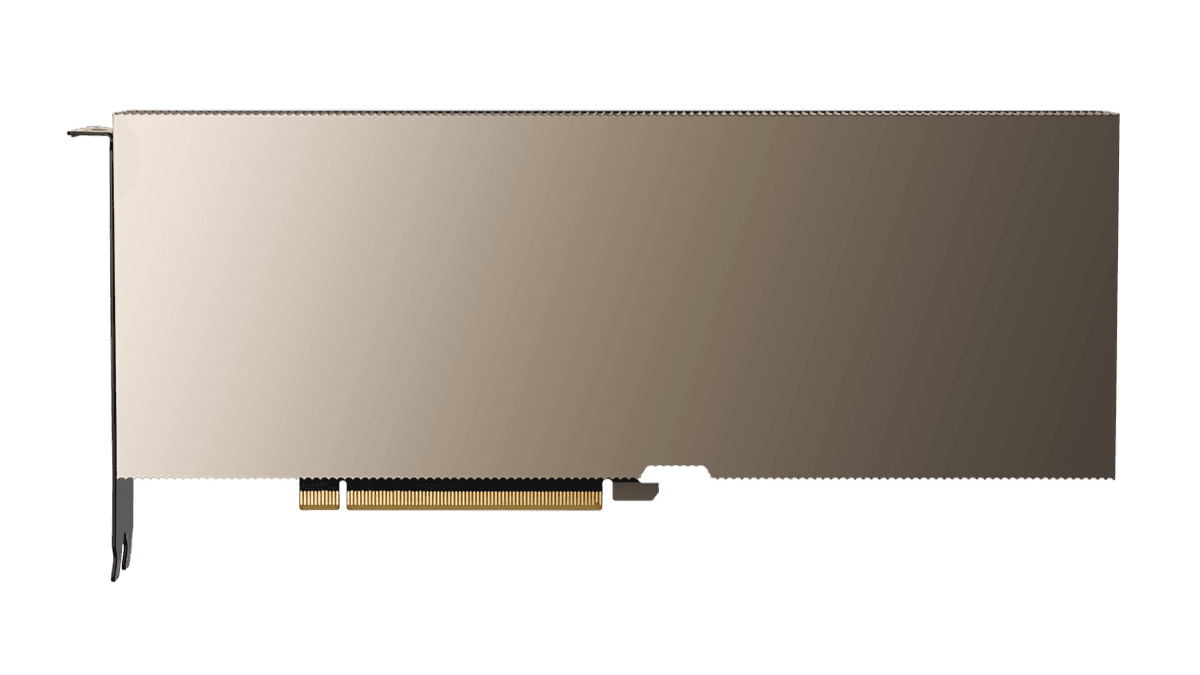
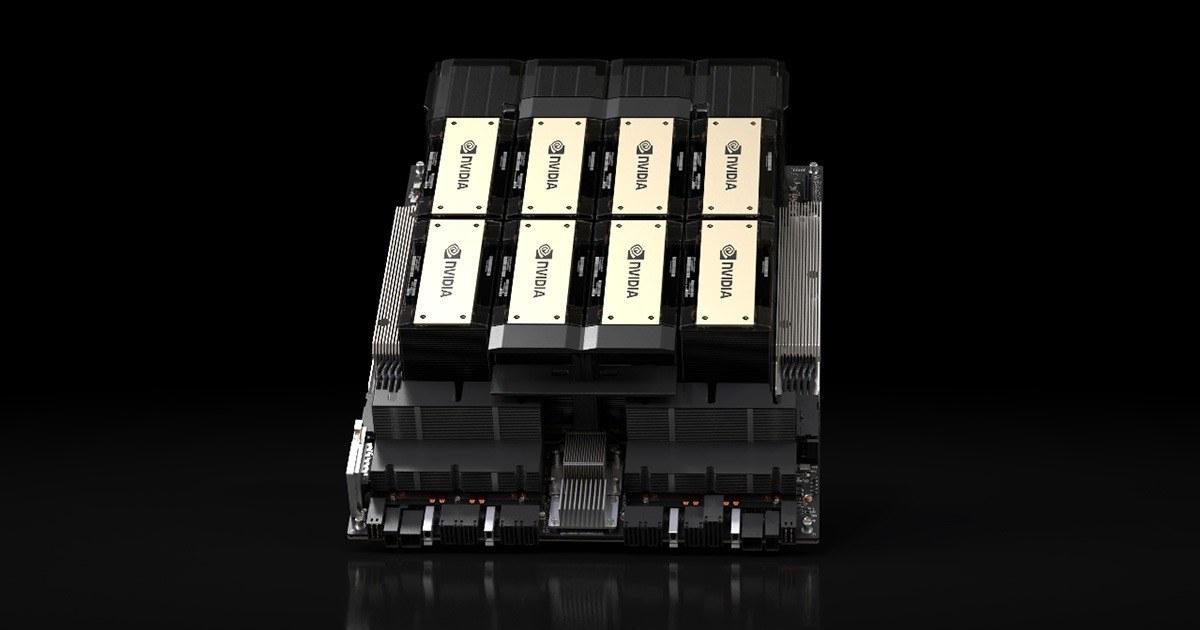
The H100 SXM5 was the volume part for AI training and shipped on the HGX H100 baseboard, which carries eight GPUs interconnected through fourth-generation NVLink and NVSwitch.[1] The H100 PCIe targeted enterprise servers that could not accept the higher 700 W power draw of SXM5. The H100 NVL, sometimes called the H100 NVL for Large Language Models, paired two PCIe cards over an NVLink bridge to deliver 188 GB of combined memory specifically for serving very large LLMs.[3]
The H800 was a stripped-down variant created in response to U.S. export controls in October 2022, with reduced NVLink bandwidth so it could be sold legally into China.[9] It was later joined by additional restricted SKUs as export rules evolved.
The H200, announced November 13, 2023 at SC23, used the same GH100 die as the H100 but added six 24 GB stacks of HBM3e memory in place of the five 16 GB HBM3 stacks on H100.[6][10] That single change boosted capacity by 76 percent and bandwidth by 43 percent without any other architectural change.[10] NVIDIA claimed roughly 1.9x the inference throughput on Llama 2 70B compared to H100 thanks to the larger working set and faster bandwidth.[6]
The GH200 Grace Hopper Superchip integrates a Grace CPU (72 Arm Neoverse V2 cores, up to 480 GB LPDDR5X) with a Hopper GPU on a single module connected by NVLink-Chip-to-Chip (NVLink-C2C) at 900 GB/s coherent bandwidth, roughly seven times faster than PCIe Gen 5.[5] The original GH200 used 96 GB of HBM3 on the GPU side; an updated GH200 announced in August 2023 moved to HBM3e, with 144 GB of physical (141 GB usable) GPU memory and 5 TB/s of bandwidth.[11]
Architecture and the GH100 die
Hopper is built around a single very large monolithic die called GH100, which set new records for transistor count and complexity in a datacenter GPU when it launched.[2] The GH100 packs 80 billion transistors on an 814 mm squared die manufactured on the TSMC 4N process.[1][2]
| Specification | GH100 full die | H100 SXM5 | H100 PCIe |
|---|---|---|---|
| Process node | TSMC 4N | TSMC 4N | TSMC 4N |
| Transistors | 80 billion | 80 billion | 80 billion |
| Die size | 814 mm squared | 814 mm squared | 814 mm squared |
| GPCs | 8 | 8 | 7 or 8 |
| Streaming Multiprocessors | 144 | 132 enabled | 114 enabled |
| FP32 CUDA cores | 18,432 | 16,896 | 14,592 |
| Fourth-gen Tensor Cores | 576 | 528 | 456 |
| L2 cache | 60 MB | 50 MB enabled | 50 MB enabled |
| HBM stacks | 6 (one disabled in shipping H100) | 5 active | 5 active |
| Memory controllers | 12 x 512-bit | 10 x 512-bit | 10 x 512-bit |
| Compute capability | 9.0 | 9.0 | 9.0 |
Each H100 SM contains 128 FP32 cores and four fourth-generation Tensor Cores. The Tensor Cores are the workhorse of the chip for AI workloads and provide more than ten times the deep learning throughput of the standard CUDA cores.[2] Hopper SMs include 256 KB of combined L1 cache and shared memory (configurable as up to 228 KB of shared memory), about 1.33 times the per-SM capacity of A100, and they expose a new Distributed Shared Memory (DSMEM) capability that lets SMs in the same Thread Block Cluster read each other's L1 directly.[2]
The full GH100 die has 60 MB of L2 cache, while shipping H100 products enable 50 MB.[2] The L2 is split into two physically separated halves, which has interesting bandwidth and latency consequences that ChipsAndCheese and academic microbenchmark papers have analyzed in detail.[14][15]
What makes Hopper different from Ampere?
Hopper is more than a process shrink of Ampere. It introduces several architectural features specifically designed for transformer-based workloads.
| Feature | Description |
|---|---|
| Fourth-generation Tensor Cores | New Tensor Core design with twice the per-clock throughput of A100's third-gen cores on equivalent precisions |
| FP8 (E4M3 and E5M2) | New 8-bit floating point formats with FP32 or FP16 accumulators, doubling throughput over FP16 |
| Transformer Engine | Software and hardware library that picks FP8 vs FP16 per layer using running statistics, often delivering 2x throughput on transformers without accuracy loss |
| Thread Block Clusters | New programming hierarchy above the thread block, letting up to 16 blocks (8 portable) cooperate across SMs in a GPC |
| Distributed Shared Memory | SMs in the same cluster can read each other's L1 directly, about 7x faster than going through global memory |
| Tensor Memory Accelerator (TMA) | Hardware unit that performs asynchronous bulk transfers of multidimensional tensors between global and shared memory |
| Asynchronous Transaction Barriers | Atomic synchronization primitive that counts both thread arrivals and bytes transferred |
| DPX instructions | New instructions that accelerate dynamic programming algorithms (Smith-Waterman, Floyd-Warshall) by up to 7x |
| Confidential Computing | Hardware-enforced trusted execution environment for encrypted GPU compute, the first on a server GPU |
| MIG 2.0 | Second-generation Multi-Instance GPU with up to 7 isolated instances, now supporting confidential computing per instance |
| Fourth-gen NVLink | 18 links per GPU at 25 GB/s in each direction (50 GB/s per link), 900 GB/s aggregate, 1.5x A100 |
| NVLink Switch System | NVLink Switch chips enable a single domain of up to 256 H100 GPUs across 32 nodes |
| Memory and L2 compression | HBM and L2 cache subsystems support data compression and decompression to optimize memory and cache usage (a capability carried over from A100) |
| PCIe Gen 5 | PCIe Gen 5 x16 host interface, doubling host bandwidth to 128 GB/s aggregate |
The Transformer Engine deserves special attention. It is implemented partly in silicon (the FP8 Tensor Cores) and partly in the open-source Transformer Engine library, which integrates with PyTorch, JAX, and frameworks like Megatron-LM.[8][16] The library tracks per-tensor scaling statistics during forward and backward passes and dynamically chooses between E4M3 (more mantissa bits, smaller range) for forward activations and E5M2 (more exponent bits, larger range) for gradients.[8] The result is that large transformer models can train in FP8 for most operations while keeping a small fraction in FP16 or FP32 to preserve numerical stability.[8] NVIDIA describes the Transformer Engine as using "software and custom NVIDIA fourth-generation Tensor Core technology" that automatically handles re-casting and scaling between FP8 and 16-bit precision in each layer.[8]
Thread Block Clusters and the Tensor Memory Accelerator together change how high-performance Hopper kernels are written. The TMA lets a single thread issue a multi-dimensional tile copy from HBM to shared memory while other warps continue computing, eliminating the traditional pattern of dedicating warps to address arithmetic and memory issue.[2] Combined with asynchronous transaction barriers, this enables the producer-consumer pipeline patterns that show up in libraries like CUTLASS 3.x and FlashAttention-3.
How fast is the H100?
The published H100 SXM5 performance numbers from the NVIDIA datasheet are reproduced below. These are peak theoretical throughputs and the FP8/FP16/BF16/TF32/INT8 figures include the structured 2:4 sparsity feature.[3]
| Precision | H100 SXM | H100 NVL (per GPU) | H200 SXM | H200 NVL |
|---|---|---|---|---|
| FP64 | 34 TFLOPS | 30 TFLOPS | 34 TFLOPS | 30 TFLOPS |
| FP64 Tensor Core | 67 TFLOPS | 60 TFLOPS | 67 TFLOPS | 60 TFLOPS |
| FP32 | 67 TFLOPS | 60 TFLOPS | 67 TFLOPS | 60 TFLOPS |
| TF32 Tensor Core (sparse) | 989 TFLOPS | 835 TFLOPS | 989 TFLOPS | 835 TFLOPS |
| BF16 Tensor Core (sparse) | 1,979 TFLOPS | 1,671 TFLOPS | 1,979 TFLOPS | 1,671 TFLOPS |
| FP16 Tensor Core (sparse) | 1,979 TFLOPS | 1,671 TFLOPS | 1,979 TFLOPS | 1,671 TFLOPS |
| FP8 Tensor Core (sparse) | 3,958 TFLOPS | 3,341 TFLOPS | 3,958 TFLOPS | 3,341 TFLOPS |
| INT8 Tensor Core (sparse) | 3,958 TOPS | 3,341 TOPS | 3,958 TOPS | 3,341 TOPS |
| GPU memory | 80 GB HBM3 | 94 GB HBM3 | 141 GB HBM3e | 141 GB HBM3e |
| Memory bandwidth | 3.35 TB/s | 3.9 TB/s | 4.8 TB/s | 4.8 TB/s |
| NVLink | 900 GB/s | 600 GB/s | 900 GB/s | 900 GB/s (2- or 4-way bridge) |
| Max TDP | 700 W | 350 to 400 W | 700 W | 600 W |
Sustained training throughput sits well below these peaks. Meta's Llama 3 paper reports 380 to 430 teraFLOP/s per GPU in BF16 across the Llama 3 405B pre-training configurations on 8,192 to 16,384 H100s, a BF16 model FLOPs utilization of 38 to 43 percent.[18]
How does Hopper compare with Ampere (A100)?
Hopper is roughly a generational leap over the A100, the previous datacenter flagship. The improvements come from three independent factors stacking together: more SMs, faster Tensor Cores per SM, and a new lower-precision format (FP8) that doubles arithmetic density.
| Specification | A100 SXM4 80GB | H100 SXM5 | Hopper improvement |
|---|---|---|---|
| Process | TSMC 7nm | TSMC 4N | One full node generation |
| Transistors | 54.2 billion | 80 billion | 1.48x |
| Die size | 826 mm squared | 814 mm squared | Slightly smaller |
| Streaming Multiprocessors | 108 | 132 | 1.22x |
| FP64 Tensor Core | 19.5 TFLOPS | 67 TFLOPS | 3.4x |
| TF32 Tensor (sparse) | 312 TFLOPS | 989 TFLOPS | 3.2x |
| BF16/FP16 Tensor (sparse) | 624 TFLOPS | 1,979 TFLOPS | 3.2x |
| FP8 Tensor (sparse) | not supported | 3,958 TFLOPS | New |
| Memory | 80 GB HBM2e | 80 GB HBM3 | Faster generation |
| Memory bandwidth | 2.0 TB/s | 3.35 TB/s | 1.68x |
| NVLink bandwidth | 600 GB/s | 900 GB/s | 1.5x |
| Max TDP | 400 W | 700 W | 1.75x |
NVIDIA's headline claims of 9x faster training and up to 30x faster LLM inference for H100 vs A100 depend on FP8 being usable for the workload and on the model being large enough to benefit from the larger memory capacity.[1][17] For HPC FP64 workloads the improvement is more modest, in the 3x to 4x range. For dense LLM inference of very large models, the combination of HBM3, larger L2, the Transformer Engine, and faster NVLink can produce more than 10x throughput improvements at equivalent latency.
How does Hopper compare with Blackwell?
Blackwell, introduced in March 2024, is Hopper's successor. Blackwell uses a dual-die package (two reticle-sized chips connected by a 10 TB/s die-to-die link) and adds support for FP4 and a refined FP8 implementation. It targets a roughly 2x to 4x performance improvement over Hopper on most LLM workloads, depending on whether FP4 is used.
| Specification | H100 SXM5 (Hopper) | B200 (Blackwell) |
|---|---|---|
| Transistors | 80 billion | 208 billion (dual die) |
| Process | TSMC 4N | TSMC 4NP |
| Memory | 80 GB HBM3 | 192 GB HBM3e |
| Memory bandwidth | 3.35 TB/s | 8 TB/s |
| FP8 Tensor (sparse) | 3,958 TFLOPS | ~9,000 TFLOPS |
| FP4 Tensor (sparse) | not supported | ~18,000 TFLOPS |
| NVLink | 900 GB/s (NVLink 4) | 1,800 GB/s (NVLink 5) |
| TDP | 700 W | 1,000 W |
Despite Blackwell's launch, Hopper continued to ship through 2025 while demand for AI compute exceeded supply and TSMC CoWoS advanced packaging capacity constrained Blackwell production, and H100 and H200 instances remained widely available in cloud catalogs into 2026.
Software stack
Hopper requires CUDA 11.8 or later for basic support and CUDA 12.x for full feature support including FP8 Tensor Cores, Thread Block Clusters, the TMA, and the DPX instructions.[2] The full software ecosystem includes:
| Component | Purpose |
|---|---|
| CUDA 12.x | Core programming model and runtime |
| cuDNN | Deep learning primitives library, FP8 support added |
| NCCL | Multi-GPU collective communications, scaled for NVLink Switch |
| TensorRT and TensorRT-LLM | Inference optimization and LLM serving |
| Transformer Engine | Open source library that orchestrates FP8 training and inference |
| Megatron-LM | Reference framework for very large transformer training |
| NeMo | NVIDIA's enterprise LLM toolkit |
| vLLM | Open source LLM inference server, Hopper-optimized |
| SGLang | High-throughput LLM inference engine |
| Triton Inference Server | Production inference serving framework |
| CUTLASS 3.x | Template library for high-performance Tensor Core kernels |
The Transformer Engine library is open source and lives at github.com/NVIDIA/TransformerEngine.[16] It integrates with PyTorch through te.LayerNormLinear, te.MultiheadAttention, and similar drop-in modules, and with JAX through Praxis. FlashAttention-3, released in 2024, was rewritten specifically to take advantage of Hopper TMA and asynchronous warp specialization, and pushed attention throughput on H100 to roughly 75 percent of FP16 Tensor Core peak.
Which models were trained on Hopper?
Hopper became the dominant training accelerator for frontier AI models from 2022 through 2024. Most training clusters are reported in approximate H100 counts, since the exact numbers are usually company-confidential.
| Model | Lab | Reported scale |
|---|---|---|
| GPT-4 | OpenAI | Not Hopper: training finished in August 2022, before H100 shipped; hardware not disclosed [19] |
| GPT-4o, o1 | OpenAI | H100 clusters, sizes not disclosed |
| Claude 3 family | Anthropic | Not disclosed by chip type |
| Gemini 1.5, Gemini Ultra | Not Hopper: Google TPUv4 (and TPUv5e for some Gemini 1.0 models) [20] | |
| Llama 2 | Meta | Not Hopper: A100-80GB only [21] |
| Llama 3 70B | Meta | H100 cluster, 24,000-GPU class |
| Llama 3.1 405B | Meta | Up to 16,384 H100 GPUs [18] |
| Mistral Large, Mixtral | Mistral AI | H100 |
| Grok 2 | xAI | H100 |
| DBRX | Databricks (Mosaic) | H100 |
The Llama 3.1 405B training run is the most thoroughly documented, since Meta published its technical report.[18] At 16,384 GPUs the run sustained 380 to 400 teraFLOP/s per H100 in BF16, and over a 54-day snapshot it saw roughly one unexpected interruption every three hours, with HBM3 and GPU faults accounting for about half of all failures.[12]
Datacenter deployment
Hopper ships in several reference platforms designed for different scales of deployment.
| Platform | Description |
|---|---|
| HGX H100 | Eight-GPU SXM5 baseboard with NVSwitch, the building block for most cloud and DGX systems |
| HGX H200 | Same baseboard architecture as HGX H100 but with H200 GPUs |
| DGX H100 | NVIDIA's reference 8-GPU server with dual Intel Sapphire Rapids CPUs, 2 TB system memory, and NVSwitch |
| DGX H200 | DGX with H200 GPUs |
| DGX SuperPOD | Modular cluster reference design built from 32 DGX H100 nodes (256 H100s) connected through NVLink Switch and InfiniBand |
| GH200 systems | Single-socket and dual-socket Grace Hopper systems from Supermicro, GIGABYTE, and others |
| MGX | NVIDIA's modular reference platform for partner-built Hopper servers |
Major cloud providers have all built large H100 fleets. AWS offers H100 through P5 instances (eight H100 SXM per instance). Microsoft Azure offers ND H100 v5 series. Google Cloud offers A3 instances. Oracle Cloud Infrastructure built one of the largest H100 superclusters for OpenAI's training. CoreWeave and Lambda Labs operate H100 clouds focused on AI workloads. By 2024 the secondary GPU cloud market had grown to hundreds of operators reselling H100 capacity.
How much does an H100 cost?
H100 supply was the binding constraint on AI development through 2023 and most of 2024. Industry reporting from Raymond James and others in late 2023 and early 2024 placed the per-GPU price for H100 SXM at roughly $25,000 to $30,000 with secondary market prices reportedly above $40,000. Complete DGX H100 systems were widely cited as costing $400,000 to $500,000.
Lead times for direct H100 orders from NVIDIA reached six months to over a year at the peak. Cloud provider allocation became a major business consideration; reports suggested that H100 access drove material revenue at AWS, Azure, GCP, and Oracle Cloud, and was a competitive differentiator for AI-focused clouds like CoreWeave. Several large AI labs disclosed multi-billion dollar H100 commitments. The supply constraint shifted upstream to TSMC's CoWoS advanced packaging capacity and to SK Hynix and Micron HBM3/HBM3e production, both of which became their own well-publicized bottlenecks.
Limitations
Hopper has several well-understood limitations that drove the design of Blackwell. The 700 W TDP per SXM5 module pushed datacenter power and cooling budgets well beyond those of earlier GPU servers. Even at lower densities, the power and thermal envelope of an HGX H100 server (eight 700 W GPUs, or 5.6 kW for the GPUs alone, before CPUs and networking) requires careful facility design.
The chip is monolithic and at 814 mm squared sits near the reticle limit of TSMC's lithography tools, which constrains how much further single-die scaling can go.[2] Blackwell's response was to move to a dual-die package. Memory capacity per GPU was a frequent bottleneck for serving very large models; H100's 80 GB forced the use of tensor parallelism across multiple GPUs even for inference of 70B-class models, which is why H200's jump to 141 GB and the GH200's 480 GB of CPU memory were so well received.[6]
HBM supply was the most-cited single constraint on H100 production. The chip uses five active stacks of HBM3 per GPU, and the total industry HBM3 output through 2023 and 2024 was insufficient to meet H100 demand, let alone leave headroom for the H200 and Blackwell ramp.
Finally, FP8 software tooling was immature in the first year after launch. Production training in FP8 only became routine in late 2023 and 2024 as the Transformer Engine library matured, FlashAttention-3 landed, and major training frameworks (Megatron-LM, NeMo, MosaicML/Composer) shipped robust FP8 paths.
Continue reading
- NvidiaNvidia Corporation is an American technology company that designs graphics processing units (GPUs) and is the world's dominant supplier of hardware for artificial intelligenceMentioned 23 times above
- Ampere (microarchitecture)Ampere is a graphics processing unit (GPU) microarchitecture from Nvidia, announced on May 14, 2020, as the successor to the Volta and Turing architectures.Mentioned 6 times above
- Jensen HuangJen-Hsun "Jensen" Huang (born 1963) is a Taiwan-born electrical engineer and business executive based in the United States.Mentioned twice above
- NVIDIA H100NVIDIA H100 (also called the H100 Tensor Core GPU) is a data-center graphics processing unit built by NVIDIA on the Hopper microarchitecture, fabricated with over 80 billion transistors on a custom TSMC 4N (4…Mentioned twice above
- NVIDIA A100The NVIDIA A100 Tensor Core GPU is a datacenter graphics processing unit that NVIDIA introduced on May 14, 2020 as the first product built on its Ampere architecture, and that became the dominant chip for…Linked in the introduction
- NVIDIA H200The NVIDIA H200 is a data center Tensor Core GPU for AI and high-performance computing that was the first GPU to ship with HBM3e memory, packing 141 GB at 4.8 TB/s on its SXM and NVL boards.Linked in the introduction
More to read
References
- ^1 ^2 ^3 ^4 ^5NVIDIA. "NVIDIA H100 Tensor Core GPU Architecture" whitepaper, March 2022. resources.nvidia.com/...nvidia-h100-tensor-c
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10NVIDIA Developer Blog. "NVIDIA Hopper Architecture In-Depth." developer.nvidia.com/...pper-architecture-in-depth
- ^1 ^2NVIDIA. "H100 Tensor Core GPU" product page and datasheet. nvidia.com/...h100
- NVIDIA. "H200 Tensor Core GPU" product page and datasheet. nvidia.com/...h200
- ^1 ^2NVIDIA. "GH200 Grace Hopper Superchip" product page. nvidia.com/...grace-hopper-superchip
- ^1 ^2 ^3NVIDIA Newsroom. "NVIDIA Supercharges Hopper, the World's Leading AI Computing Platform." November 13, 2023. nvidianews.nvidia.com/...ing-ai-computing-platform
- NVIDIA Investor Relations. "NVIDIA Grace Hopper Superchips Designed for Accelerated Generative AI Enter Full Production." May 28, 2023.
- ^1 ^2 ^3 ^4NVIDIA Blog. "H100 Transformer Engine Supercharges AI Training." blogs.nvidia.com/...h100-transformer-engine
- ^1 ^2 ^3Wikipedia. "Hopper (microarchitecture)." en.wikipedia.org/...Hopper_(microarchitecture)
- ^1 ^2Tom's Hardware. "Nvidia Announces H200 GPU: 141GB of HBM3e and 4.8 TB/s Bandwidth." November 13, 2023. tomshardware.com/...nvidia-h200-gpu-announced
- ^AnandTech. "NVIDIA Unveils Updated GH200 Grace Hopper Superchip with HBM3e Memory." August 8, 2023. Archived: web.archive.org/...ce-hopper-gpu-with-hbm3e-memory
- ^Tom's Hardware. "Faulty Nvidia H100 GPUs and HBM3 memory caused half of failures during Llama 3 training."
- Meta AI. "Introducing Llama 3.1: Our Most Capable Models to Date." ai.meta.com/...meta-llama-3-1
- ^ChipsAndCheese. "Nvidia's H100: Funny L2, and Tons of Bandwidth." chipsandcheese.com/...nny-l2-and-tons-of-bandwidth
- ^Luo et al., "Benchmarking and Dissecting the Nvidia Hopper GPU Architecture." arXiv:2402.13499. arxiv.org/...2402.13499v1
- ^1 ^2NVIDIA. Transformer Engine library on GitHub. github.com/...TransformerEngine
- ^1 ^2 ^3 ^4NVIDIA Newsroom. "NVIDIA Announces Hopper Architecture, the Next Generation of Accelerated Computing." March 22, 2022. nvidianews.nvidia.com/...-of-accelerated-computing
- ^1 ^2 ^3 ^4Llama Team, AI @ Meta. "The Llama 3 Herd of Models." arXiv:2407.21783. arxiv.org/...2407.21783
- ^1 ^2OpenAI. "GPT-4 Technical Report." arXiv:2303.08774. arxiv.org/...2303.08774
- ^1 ^2Gemini Team, Google. "Gemini 1.5: Unlocking multimodal understanding across millions of tokens of context." arXiv:2403.05530. arxiv.org/...2403.05530
- ^Touvron et al. "Llama 2: Open Foundation and Fine-Tuned Chat Models." arXiv:2307.09288. arxiv.org/...2307.09288
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
9 revisions · v9 · 4,007 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (130 claims, 19 sources fetched); 11 material + 16 minor fixed
Cite this page: AI Wiki. "NVIDIA Hopper." aiwiki.ai, updated 21 Jun 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/nvidia_hopper