

Test-Time Training (TTT)
Test-Time Training (TTT) is a family of machine learning techniques in which a model updates some of its own parameters at inference time, optimizing a self-supervised (or otherwise label-free) loss derived from the test input itself before producing the final prediction. The approach was introduced by Yu Sun and collaborators in the paper Test-Time Training with Self-Supervision for Generalization under Distribution Shifts (ICML 2020), where it was used to improve image-classifier robustness to corruptions and distribution shifts.[1] In 2024 the same lead author extended the idea into a sequence-modeling primitive, the TTT layer, whose hidden state is itself a small neural network trained by gradient descent as tokens stream in, giving an alternative to attention and to linear-state recurrences such as Mamba.[2] Subsequent work has applied TTT to abstract reasoning benchmarks such as ARC-AGI, to long-form video generation, and to in-context-learning regimes for large language models.[3][4] In 2025 and 2026 the line continued with large-chunk TTT layers, an "end-to-end" TTT recipe that turns a sliding-window Transformer into a long-context model by training on its context during inference, and reinforcement learning at test time for scientific discovery problems.[15][14][19]
Because TTT performs gradient updates per test instance (or per token), it sits between conventional supervised inference, which keeps weights frozen, and full continual learning, which adapts on labeled streaming data. In the original formulation the update signal comes from the test input under a self-supervised objective, with no test labels available.[1] TTT is therefore one way of spending extra inference-time computation: the extra FLOPs go into adapting weights rather than into longer chains of thought or more samples, a trade-off that 2025 long-context work argues explicitly for (see test-time compute).[18]
Terminology
Several similar-sounding terms are used for different things, and papers do not always use them consistently.
| Term | What changes at inference | Typical signal | Example source |
|---|---|---|---|
| Test-time training (TTT) | Model weights (all or a subset), per test instance or per token | Self-supervised loss on the test input (rotation prediction, masked reconstruction, next-token prediction), or a loss built from in-context demonstrations | Sun et al. 2020; Sun et al. 2024[1][2] |
| Test-time adaptation (TTA) | Model weights or the inputs, on unlabeled test data | Varies: entropy minimization, self-supervision, pseudo-labels | Liang et al. survey; Tent[12][20] |
| Test-time compute / test-time scaling | Usually nothing in the weights; more computation is spent per query | Search against verifiers, sampling, revising the output distribution, longer reasoning | Snell et al. 2024[21] |
| Test-time augmentation | Nothing; predictions on augmented copies of the input are aggregated | None (no learning) | Liang et al. survey[12] |
The Liang, He and Tan survey (IJCV 2025) treats test-time adaptation as the umbrella paradigm and divides it by the form of the test data into test-time domain adaptation (adapting on a whole unlabeled target set, also called source-free domain adaptation), test-time batch adaptation (adapting to one mini-batch or a single instance), and online test-time adaptation (adapting on a stream, reusing what was learned on earlier batches).[12] The single-instance case of test-time batch adaptation is what the survey calls test-time instance adaptation, "a.k.a., standard test-time training".[12] Tent (Wang et al., ICLR 2021) is a widely used example of fully test-time adaptation that does not need an auxiliary task: it minimizes the entropy of the model's predictions and updates only normalization statistics and channel-wise affine parameters, online, on each test batch.[20] Original TTT differs in that it requires the model to be trained jointly with the auxiliary task beforehand.[1]
Test-time compute is the broader idea of allocating more inference computation per query. Snell et al. (2024) studied two mechanisms, "searching against dense, process-based verifier reward models" and "updating the model's distribution over a response adaptively", neither of which changes the model's weights.[21] TTT is sometimes grouped with these methods because it also trades inference FLOPs for accuracy; the 2025 qTTT paper, for example, frames a few gradient steps on the context as "a better use of inference compute" than producing more thinking tokens for long-context tasks.[18] In ARC-AGI work the same technique is also called test-time fine-tuning (TTFT).[22]
History
Background and predecessors
Adapting a model to new distributions at inference time is a long-standing concern in machine learning, encompassing unsupervised domain adaptation, transductive learning, and online learning. Classical domain-adaptation methods typically require an unlabeled batch from the target distribution at training time, while transductive methods require all test inputs in advance. TTT departs from both: each test sample defines its own learning problem, and only the current sample (or a short stream) is used to update parameters before prediction.[1] The 2024 TTT-layers paper traces the idea of learning at test time back to local learning (Bottou and Vapnik), in which a model is trained on the neighbors of each test input before predicting, and to Vapnik's principle of transduction.[2] The conceptual move in TTT is to recast inference as a small training loop driven by a self-supervised task that is the same at training time and at test time, so that improvement on the auxiliary task is expected to transfer to the main task.
The 2019 to 2020 ICML paper
The original TTT paper, posted to arXiv in September 2019 and published in the Proceedings of the 37th ICML (2020, PMLR vol. 119, pp. 9229-9248), was authored by Yu Sun, Xiaolong Wang, Zhuang Liu, John Miller, Alexei A. Efros, and Moritz Hardt, with affiliations at UC Berkeley and UC San Diego.[1][5] The system trains a Y-shaped network with a shared feature extractor and two branches: a main branch for image classification and a self-supervised branch that predicts the rotation (0, 90, 180, or 270 degrees) applied to an input image, a task taken from Gidaris et al. (2018). At test time the shared feature extractor is fine-tuned to minimize the rotation-prediction loss on the current image, and the updated features are then used by the unchanged classification branch to predict a label.[1]
The paper reports two variants. Standard TTT updates the model independently for each test image and then discards the update, so the next image starts from the original weights. Online TTT keeps the accumulated updates across the test stream, so the model becomes progressively more specialized to the test distribution.[1] Both variants were evaluated on CIFAR-10-C and ImageNet-C (15 corruption types at five severity levels), on the VID-Robust video-frame dataset, and on the CIFAR-10.1 test set; on ImageNet-C the accuracy of online TTT was still rising at the end of the 50,000-image stream.[1]
TTT for vision after 2020
Subsequent work extended the original recipe to richer self-supervised objectives. Test-Time Training with Masked Autoencoders, by Yossi Gandelsman, Yu Sun, Xinlei Chen, and Alexei A. Efros (arXiv 2209.07522, NeurIPS 2022), replaces rotation prediction with the reconstruction objective of a Masked Autoencoder (MAE).[6] The authors argue that rotation prediction is often too hard to be helpful, whereas spatial autoencoding is a more general task, and they characterize the improvement theoretically in terms of the bias-variance tradeoff.[6] Test-Time Training on Video Streams (Renhao Wang, Yu Sun and co-authors, arXiv 2307.05014, 2023; published in the Journal of Machine Learning Research in 2025) carried online TTT over to real video: the model for each frame is initialized from the previous frame's model and trained on the current frame plus a small window of earlier frames. The authors report improvements of more than 2.2x and 1.5x over a fixed-model baseline for instance and panoptic segmentation, and found that online TTT beat an offline variant that trained on the entire video.[23]
In parallel, Sun and colleagues began treating TTT as a learning-to-learn problem. Learning to (Learn at Test Time) (arXiv 2310.13807, October 2023) describes an inner loop that learns on each instance with self-supervision and an outer loop that learns the self-supervised task itself; the authors show the inner loop is equivalent to linear attention when the inner learner is a linear model and to self-attention when it is a kernel estimator.[24]
Expansion to sequence modeling: TTT layers (2024)
In July 2024 Yu Sun, with co-authors Xinhao Li, Karan Dalal, Jiarui Xu, Arjun Vikram, Genghan Zhang, Yann Dubois, Xinlei Chen, Xiaolong Wang, Sanmi Koyejo, Tatsunori Hashimoto, and Carlos Guestrin, posted Learning to (Learn at Test Time): RNNs with Expressive Hidden States (arXiv 2407.04620), which generalized TTT from a per-image adaptation procedure into a generic sequence-modeling primitive.[2] The paper was published at ICML 2025 (PMLR vol. 267, pp. 57503-57522); the arXiv record was last revised in August 2025, with a note that "all experiments were completed in the first version."[32][2] The key reframe is that a recurrent neural network can be viewed as a sequence-to-sequence map whose hidden state compresses past context; the TTT layer makes that hidden state itself a small machine-learning model whose parameters are updated by self-supervised gradient descent on each incoming token.[2] Two instantiations are introduced: TTT-Linear (the hidden state is a linear model) and TTT-MLP (the hidden state is a two-layer multi-layer perceptron).[2]
Recent extensions (2024 to 2025)
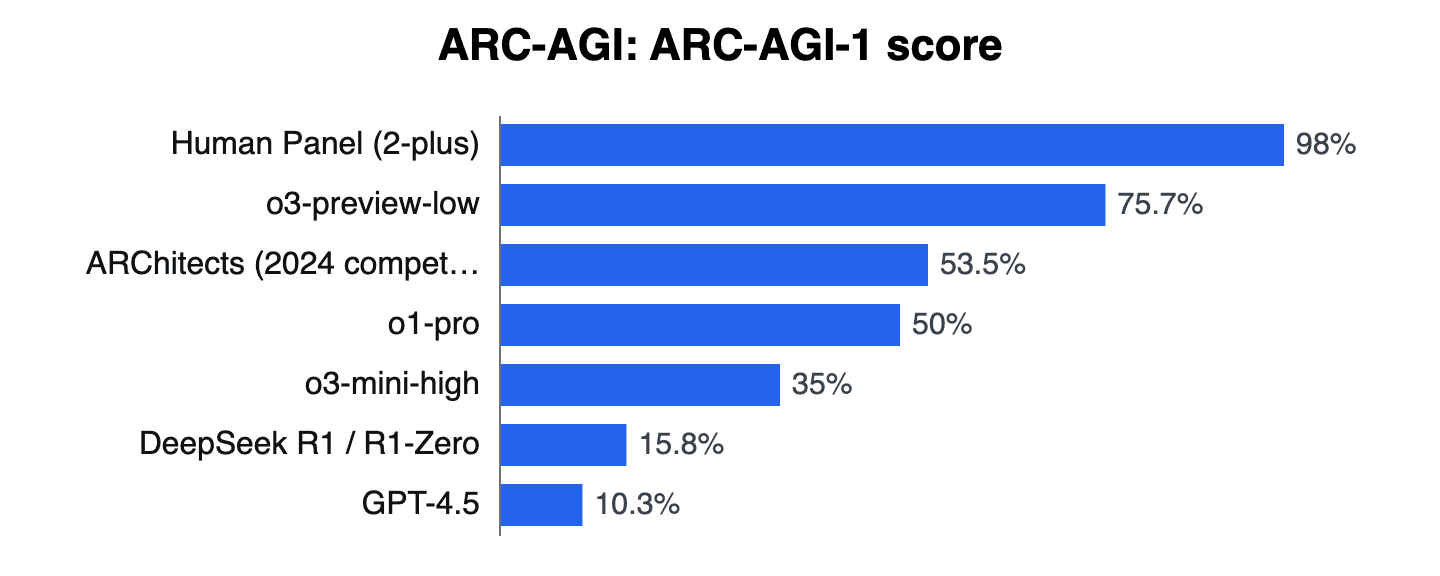
In November 2024 Ekin Akyürek, Mehul Damani, Adam Zweiger, Linlu Qiu, Han Guo, Jyothish Pari, Yoon Kim, and Jacob Andreas (MIT) released a paper first titled The Surprising Effectiveness of Test-Time Training for Abstract Reasoning, retitled in its March 2025 revision as The Surprising Effectiveness of Test-Time Training for Few-Shot Learning and published at ICML 2025. It applies a TTT recipe to 8 billion-parameter language models on the ARC-AGI benchmark and on BIG-Bench Hard.[3][33] The ARC Prize 2024 technical report gave the paper its second-place paper award and described TTT as "a dominant approach in LLM-based solutions for ARC-AGI", noting that the first-place Kaggle entry (the ARChitects, 53.5% on the private evaluation set) also used TTT and that the team MindsAI had pioneered TTT for ARC-AGI starting in 2023.[22]
In April 2025, Karan Dalal and collaborators from NVIDIA, Stanford, UC San Diego, UC Berkeley and UT Austin released One-Minute Video Generation with Test-Time Training (CVPR 2025), adding TTT layers to a pre-trained 5 billion-parameter diffusion transformer to generate one-minute Tom and Jerry cartoons from text storyboards.[4] These results expanded TTT's footprint from a robustness technique into a generic tool for long-context generation and few-shot reasoning.
Developments in 2025 and 2026
| Work | First posted | Venue (as of October 2026) | Idea |
|---|---|---|---|
| Titans (Behrouz, Zhong, Mirrokni, Google) | 31 Dec 2024 | NeurIPS 2025 | Neural long-term memory updated at test time by a "surprise"-driven gradient rule, combined with attention; see Titans[25] |
| Test-time regression (Wang, Shi, Fox) | Jan 2025 | arXiv preprint | Framework casting linear attention, state-space models, fast-weight programmers and softmax attention as regression solved over the input tokens at test time[17] |
| LaCT: Test-Time Training Done Right (Zhang et al., MIT and Adobe Research) | 29 May 2025 | ICLR 2026 | Update the fast weights on very large chunks (2K to 1M tokens) instead of 16 to 64 tokens[15] |
| MesaNet (von Oswald et al.) | 5 Jun 2025 | ICLR 2026 | Solves the in-context regression objective to optimality at every time step with a conjugate-gradient solver[16] |
| PERK (Chen, Romanou, Weiss, Bosselut) | 8 Jul 2025 | ICLR 2026 | Meta-learned encoding of long contexts into a LoRA adapter by test-time gradient updates[27] |
| TTT3R (Chen et al.) | 30 Sep 2025 | ICLR 2026 | Reframes recurrent 3D-reconstruction models as online learners and derives a closed-form learning rate for memory updates[28] |
| qTTT (Bansal et al.) | 15 Dec 2025 | ICLR 2026 | Few gradient steps on the query projections only, reusing the KV cache of a long context[18] |
| TTT-E2E (Tandon, Dalal, Li et al.) | 29 Dec 2025 | arXiv preprint | Sliding-window Transformer that keeps training on its context by next-token prediction; meta-learned initialization[14] |
| TTT-Discover (Yuksekgonul, Koceja, Li, Bianchi et al.) | 22 Jan 2026 | ICML 2026 | Reinforcement learning at test time on a single scientific or engineering problem[19] |
| TTT-NTP (Ouyang, Cai, Hu) | 19 Jun 2026 | Findings of EMNLP 2026 | Drop-in fast-weight adaptation for released LLM checkpoints, supervised by the model's own next contextual hidden state[26] |
Large-chunk TTT (LaCT). Tianyuan Zhang and co-authors at MIT and Adobe Research argue that earlier TTT layers ran at "extremely low FLOPs utilization (often below 5%)" because they updated fast weights every 16 or 64 tokens.[15] LaCT instead updates on chunks of 2,048 to 1 million tokens, treats the tokens within a chunk as an unordered set, and adds window attention to capture local structure inside each chunk. The authors report GPU utilization of up to 70% on NVIDIA A100s with a few dozen lines of PyTorch, nonlinear (SwiGLU) fast-weight states of up to 40% of model parameter size, and easy use of the Muon optimizer for the fast-weight update. They test it on novel view synthesis with up to 128 input images (about 1 million tokens), on language modeling (where they report performance competitive with DeltaNet), and on a 14 billion-parameter autoregressive video diffusion model handling sequences of up to 56,000 tokens.[15]
End-to-end TTT for long context (TTT-E2E). In December 2025 Arnuv Tandon, Karan Dalal, Xinhao Li, Daniel Koceja, Marcel Rød, Yu Sun and colleagues at the Astera Institute, NVIDIA, Stanford, UC Berkeley and UC San Diego proposed treating long-context language modeling "as a problem in continual learning rather than architecture design".[14] The model is a standard Transformer whose attention is restricted to a sliding window (8K tokens in the main runs); during inference it keeps training on the context it reads by ordinary next-token prediction, in mini-batches of 1K tokens, so that information beyond the window is compressed into its weights. Only the MLP layers of the last quarter of the blocks are updated, and those blocks get a second, frozen MLP as "safe" storage for pre-trained knowledge. The initialization for this test-time learning is meta-learned during training, which requires gradients of gradients.[14] For 3B-parameter models trained on 164B tokens, the authors report that TTT-E2E scales with context length in the same way as full attention while Mamba 2 and Gated DeltaNet do not, and that its constant per-token latency makes it 2.7x faster than full attention for prefill at 128K context on an H100. They also report two limitations: full attention "dramatically outperforms" TTT-E2E and the other efficient baselines on RULER needle-in-a-haystack retrieval, and training is 3.4x slower than full attention at 8K context (1.2x faster at 128K).[14]
Other directions. MesaNet, from Johannes von Oswald and colleagues, makes the earlier Mesa layer chunkwise parallel and numerically stable and reports lower perplexity and better long-context downstream results than previous RNNs at up to billion-parameter scale, at the cost of extra inference FLOPs.[16] The qTTT method of Rachit Bansal and co-authors performs one prefill to cache keys and values, then applies a few gradient updates only to the query projections on spans of the context; the authors report gains of 12.6 and 14.1 percentage points for Qwen3-4B averaged over subsets of LongBench-v2 and ZeroScrolls.[18] TTT-Discover, from Stanford, NVIDIA, the Astera Institute, UC San Diego and Together AI, runs reinforcement learning on one problem at a time with the open-weight gpt-oss-120b model through Thinking Machines' Tinker API; the authors report new best results on problems in mathematics (including Erdős' minimum overlap problem), a GPUMode kernel competition, past AtCoder contests and single-cell denoising, at "a cost of only a few hundred dollars per problem".[19] Google's Titans architecture, which adds a test-time-updated neural memory to attention, is covered on its own page.[25]
Technical Details
General recipe
The general TTT recipe involves three ingredients: a main task f trained at training time, a self-supervised auxiliary task g sharing some parameters with f, and an adaptation procedure A that takes the test input x, evaluates the auxiliary loss , and runs one or more steps of gradient descent on the shared parameters before evaluating f on x.[1] Because requires no labels, A can be applied at inference. The set of parameters updated is typically restricted to make adaptation cheap: in the original paper, only the shared feature-extractor weights are updated; in TTT layers, only the hidden state, which is itself a small set of model weights, is updated.[1][2]
The original rotation-prediction objective
In the ICML 2020 instantiation, the auxiliary task is image-rotation classification, a four-way classification problem. Training is multi-task: the main classification loss and the rotation loss are added and optimized jointly over all parameters (the paper calls this "joint training").[1] At test time, the method builds a batch containing only augmented copies of the single test image (random crop and horizontal flip, the same augmentations used in training), and updates the shared feature extractor by stochastic gradient descent on the rotation-prediction cross-entropy loss, with learning rate 0.001 and no weight decay or momentum. Standard TTT takes ten gradient steps per image; online TTT takes one step per new image.[1] The main branch's weights are not updated, so the classifier sees a slightly different feature vector at test time than it did at training. The paper reports that updating only the shared extractor or also the rotation branch made a negligible empirical difference.[1]
Two implementation choices follow from the single-image setting. The ResNets (26 layers for CIFAR-10, 18 for ImageNet) use Group Normalization rather than Batch Normalization, because a batch made of copies of one image gives inaccurate batch statistics; and the shared extractor ends after the second of three residual groups on CIFAR-10 and the third of four on ImageNet.[1] The paper estimates the cost of standard TTT at "2 × batch size × number of iterations" times that of a single forward pass, and notes preliminary results with one step at a higher learning rate that were "almost as good".[1] Its theoretical analysis proves, for main-task losses that are convex and smooth in the parameters, that one TTT gradient step on the auxiliary loss reduces the main-task loss when the gradients of the two losses are positively correlated. Empirically, across 75 corrupted test sets (15 corruption types at five levels), the improvement from TTT tracked the inner product between the two gradients, with linear correlation coefficients of 0.93 for standard and 0.89 for online TTT.[1]
TTT layers as a sequence-modeling primitive
In the 2024 TTT-layers formulation, each token in a sequence is processed by a layer whose internal state is the parameters of a small machine-learning model . For TTT-Linear, f is a linear model with a square weight matrix; for TTT-MLP, f is a two-layer MLP whose hidden dimension is four times the input dimension, with a GELU activation. For stability, f always includes a Layer Normalization and a residual connection, .[2] Three learnable projections produce a "training view" , a "label view" , and a "test view" per token. The inner-loop self-supervised reconstruction loss is
and the naive update rule is one step of online gradient descent on this loss, . The layer's output for position t is , the prediction of the updated inner model on the test view.[2]
The paper separates two nested learning problems. In the inner loop, only W is optimized, token by token, on each sequence (including test sequences). In the outer loop, which is ordinary training of the whole network, the projections are learned along with the rest of the network's parameters, so the self-supervised task itself is learned for the goal of next-token prediction rather than handcrafted; the inner-loop learning rate is also made learnable and input-dependent.[2] The subscripts K, V and Q deliberately echo the key, value and query projections of self-attention.[2]
This construction has two important properties. First, like a recurrence, it processes one token at a time, so the per-token cost is constant and the overall complexity is linear in sequence length. Second, because the hidden state is a parameterized function rather than a fixed-size vector, the layer can in principle store more information than the vector hidden states of LSTMs and of state-space models such as Mamba; the paper notes that TTT-Linear's hidden state is a matrix and TTT-MLP's is two matrices.[2]
Connection to linear attention and DeltaNet
A central theoretical result of the 2024 paper is that TTT-Linear reduces, under a particular set of choices, to linear attention. Theorem 1 states that when f is a linear model , the inner update uses batch gradient descent with learning rate 1/2, and the initial weights are zero, the layer produces the same output sequence as linear attention.[2] The paper's ablation table starts from this equivalence and adds components one at a time for a 125M-parameter model on the Pile at 2k context: perplexity moves from 15.91 for the original linear attention and 15.23 for the TTT-equivalent improved linear attention, through 15.27 with a learnable (slightly worse, but needed for stable training), to 14.05 after adding LayerNorm and the residual connection in f, 12.35 with mini-batch TTT, 11.99 with a learnable , and 11.09 with the Mamba backbone (which adds temporal convolutions). The authors identify mini-batch TTT as the largest single improvement.[2]
The 2025 revisions of the paper (April and August 2025) add that the closest prior work is DeltaNet, which is equivalent to TTT-Linear with an inner-loop mini-batch size of 1 and without the LayerNorm and residual connection; it also notes that Mamba 2 and Gated DeltaNet advanced matrix-hidden-state RNNs after the first version was released, and describes its own contribution as "a practical framework that can instantiate arbitrary neural networks as hidden states".[2] A TTT-Linear layer can thus be read either as an RNN that updates a parametric hidden state, or as a generalization of linear attention that supports other optimizers, non-linear inner models (TTT-MLP), and other self-supervised losses.[2] The 2025 test-time regression framework generalizes this view to a wider set of layers.[17]
Mini-batch TTT and dual form
The naive update cannot be parallelized across tokens, because depends on inside the gradient. Mini-batch TTT takes the gradients for all tokens in a mini-batch of size b with respect to the weights at the end of the previous mini-batch, so b gradients can be computed in parallel; b = 1 is online gradient descent and b equal to the sequence length is batch gradient descent. The paper uses b = 16 throughout and reports that b trades speed against quality.[2] A dual form computes the outputs within each mini-batch without materializing the intermediate weights and gradients, so the work maps onto matrix multiplications suited to GPU tensor cores and TPUs; the authors report that training with the dual form is more than 5x faster than with the primal form in their JAX implementation.[2] With these techniques and a forward kernel written in ThunderKittens, the paper reports that TTT-Linear's forward latency per token (1.3B models, batch size 16, NVIDIA A100) is lower than a Transformer's from 8k context and matches Mamba, and that TTT-Linear and Mamba have almost the same decode latency.[2]
TTT for in-context learning of language models
The MIT TTT-for-ARC paper applies a different style of TTT to an already-trained large language model. Given an ARC task that consists of several input-output example pairs and a held-out test query, the method constructs "leave-one-out" tasks from the given examples, augments them through invertible transformations such as rotations, flips and transposition (plus color permutations and shuffled example order), and uses these augmented tasks to fine-tune small task-specific LoRA adapters. Each ARC task gets its own adapter, trained for two epochs with batch size one or two and AdamW at a learning rate of 5e-5 (best for the 1B and 3B models) or 1e-4 (best for 8B); the LoRA rank is 128 with alpha 16, applied to the attention query and value projections, the MLP weights, and the output projection.[3] Predictions are made on transformed versions of the test input and combined by a hierarchical voting scheme. The authors report that the whole TTT and inference process takes about 12 hours for 100 validation tasks on one NVIDIA A100.[3] This is TTT in the sense that the model's parameters are updated from the test task alone (its few-shot demonstrations), using a loss built without external labels.
Variants and Implementations
| Variant | Year | Lead author(s) | Adaptation target | Update signal | Notes |
|---|---|---|---|---|---|
| Standard TTT (vision) | 2020 | Sun et al. | Shared encoder weights | Rotation-prediction loss on the test image | Resets weights per image[1] |
| Online TTT (vision) | 2020 | Sun et al. | Shared encoder weights | Rotation-prediction loss on streaming images | Accumulates updates across stream[1] |
| TTT-MAE | 2022 | Gandelsman et al. | ViT encoder and decoder, MAE setup | MAE reconstruction loss | Stronger auxiliary task, ViT backbone[6] |
| Online TTT on video streams | 2023 | Wang et al. | Per-frame model for segmentation and colorization | Self-supervised reconstruction on current and recent frames | Video frames in temporal order[23] |
| TTT-Linear | 2024 | Sun et al. | Inner linear-model hidden state | Per-token reconstruction loss | Linear-time language model layer[2] |
| TTT-MLP | 2024 | Sun et al. | Inner two-layer MLP hidden state | Per-token reconstruction loss | Higher capacity, more memory I/O[2] |
| TTT for ARC | 2024 | Akyürek et al. | Task-specific LoRA adapters | Loss on augmented few-shot examples | 53.0% pass@2 on the ARC public evaluation set with BARC's fine-tuned 8B model[3] |
| TTT-Video | 2025 | Dalal et al. | TTT-MLP layers added to a DiT | Inner-loop reconstruction during fine-tuning and inference | One-minute videos from storyboards[4] |
| LaCT | 2025 | Zhang et al. | Large nonlinear fast weights | Chunk-level updates over 2K to 1M tokens | Up to 70% GPU utilization reported[15] |
| TTT-E2E | 2025 | Tandon, Dalal, Li et al. | MLP layers in the last quarter of a sliding-window Transformer | Next-token prediction on the context | Meta-learned initialization[14] |
| TTT-Discover | 2026 | Yuksekgonul et al. | Rank-32 LoRA adapter on the LLM policy (via Tinker) | Reinforcement learning on one problem | gpt-oss-120b[19] |
Official open-source releases
The 2024 TTT-layers paper was accompanied by two official open-source repositories, and later papers from the same group have their own:
- ttt-lm-pytorch: a PyTorch implementation built on the Hugging Face Transformers library, distributed under the MIT license. Its README calls it "a naive implementation of TTT layers for tutorial purposes" and says the authors "do not recommend training" with it because it lacks systems optimization. A "ttt-1b style configuration" is provided via TTTConfig.[7]
- ttt-lm-jax: a JAX implementation tested on both GPUs and Cloud TPU VMs with Python 3.11, which the PyTorch README points to for training and for replicating the paper's results. Separate dependency lists for GPU and TPU are provided.[8][7]
Inference kernels and the speed benchmark for the TTT-layers paper are in a separate ttt-lm-kernels repository, and the video work and TTT-E2E were released through the same test-time-training GitHub organization.[7][29][30]
| Repository | Paper | Created | Stars | Forks | License |
|---|---|---|---|---|---|
| test-time-training/ttt-lm-pytorch | TTT layers (2024) | Jun 2024 | 1,407 | 79 | MIT |
| test-time-training/ttt-lm-jax | TTT layers (2024) | Jul 2024 | 463 | 36 | None listed |
| test-time-training/ttt-video-dit | One-minute video (2025) | Apr 2025 | 2,453 | 11 | MIT |
| test-time-training/e2e | TTT-E2E (2025) | Dec 2025 | 715 | 54 | None listed |
| a1600012888/LaCT | LaCT (2025) | May 2025 | 536 | 32 | MIT |
Star, fork and license figures are from the GitHub API as of 31 October 2026.[7][8][29][30][31]
Other implementations
Several independent or derivative implementations have appeared:
- Test-Time Training on Nearest Neighbors by Moritz Hardt and Yu Sun (arXiv 2305.18466, ICLR 2024) retrieves the nearest neighbors of each test input from a distributed index built on the Pile and fine-tunes the language model on their text using its standard training setup. The authors report that training on as few as 20 neighbors, each for one gradient iteration, substantially improves performance across more than 20 Pile language-modeling tasks and narrows the gap between a small GPT-2 and a GPT-Neo model more than ten times larger. Code is published as the
socialfoundations/tttlmrepository.[34][9] - Test-Time Model Adaptation for Image Reconstruction Using Self-supervised Adaptive Layers (TTT-AdaptNet; Yutian Zhao, Tianjing Zhang and Hui Ji, ECCV 2024) adapts a pre-trained unrolling network to each test sample in medical image reconstruction through added lightweight adaptive linear layers.[10]
- TTRL: Test-Time Reinforcement Learning (arXiv 2504.16084, 2025) trains LLMs with reinforcement learning on unlabeled test data, using majority voting over sampled answers as the reward; the authors report that it raised Qwen-2.5-Math-7B's pass@1 on AIME 2024 by about 211%.[11]
- Surveys such as Liang et al., A Comprehensive Survey on Test-Time Adaptation under Distribution Shifts (IJCV, 2025), place TTT within a taxonomy of test-time domain, batch and online adaptation.[12]
Results
Vision benchmarks (original TTT, 2020)
On CIFAR-10-C, which applies 15 corruption types at five severities to the CIFAR-10 test set, both TTT variants improved over a plain classifier by a large margin across all five levels and 15 corruption types (the joint-training baseline is the same network trained with the rotation task but kept fixed at test time). The standard version always improved over joint training; the online version often improved by more than 10% and never hurt by more than 0.2%.[1] On the original, uncorrupted CIFAR-10 test set, error was 8.9% for the plain ResNet-26 and 8.1% with joint training, and TTT improved it by a further 0.2%.[1] On ImageNet-C (level 5), standard TTT always improved over both baselines, while online TTT lost 0.1% on the original distribution but improved accuracy "by a factor of more than three" on many corruption types; its accuracy kept rising over the 50,000-image stream.[1]
| Benchmark (2020 paper) | Plain classifier | Joint training | Standard TTT | Online TTT |
|---|---|---|---|---|
| VID-Robust, accuracy (%) | 62.7 | 63.5 | 63.8 | 64.3 |
| CIFAR-10.1, error (%) | 17.4 | 16.7 | 15.9 | not reported |
The online variant also outperformed an unsupervised domain adaptation method given the entire unlabeled test set (UDA-SS) on 13 of 15 corruptions, and still improved on joint training when the corruption severity changed gradually along the stream.[1] On the seven CIFAR classes of VID-Robust, TTT did not improve the airplane class; the authors traced this to black margins that make rotation trivially predictable and to sky images whose rotation is ambiguous, concluding that the self-supervised task must be "both well defined and non-trivial".[1]
TTT-MAE, built on a ViT-Large MAE encoder with a ViT-Base classification head trained by probing, takes 20 SGD steps per test image on batches of 128 differently masked copies (75% masking). The authors report larger gains than rotation-based TTT on every ImageNet-C corruption relative to each method's own baseline, and improvements from 15.3% to 21.3% on ImageNet-A and from 31.3% to 38.9% on ImageNet-R.[6]
Language modeling on The Pile and Books3 (TTT layers, 2024)
The TTT-layers paper trains models of 125M, 350M, 760M and 1.3B parameters (Mamba at 130M to 1.4B) following the Chinchilla recipe used in the Mamba paper, on The Pile at 2k and 8k context and on Books3 at contexts from 1k to 32k.[2] At 2k context, TTT-Linear (with the Mamba backbone), Mamba, and a Transformer baseline have comparable performance "as the lines mostly overlap", while TTT-MLP performs slightly worse under large FLOP budgets: it has better perplexity than TTT-Linear at every model size, but "the extra cost in FLOPs offsets the advantage". At 8k context, both TTT-Linear and TTT-MLP "perform significantly better than Mamba", and the authors describe a widening advantage over Mamba as context grows.[2] At 32k on Books3, both TTT variants again perform better than Mamba; in the per-token analysis, the Transformer and TTT-Linear keep reducing perplexity as they condition on more tokens, while Mamba plateaus after 16k context.[2] The authors note that their scaling results do not cleanly fit a linear trend, even for the Transformer baseline.[2]
ARC-AGI (TTT for few-shot learning, 2024)
The ARC ablations use a randomly selected subset of 80 ARC validation tasks, where the authors report "up to 6x higher accuracy compared to fine-tuned baselines".[3] On the full ARC public evaluation set, TTT raised the authors' own fine-tuned Llama 3 8B model from 18.3% to 47.1% (pass@2), and applying their TTT pipeline to the fine-tuned 8B model released with BARC (Li et al.) reached 53.0%, which the paper describes as a 35% improvement over BARC's original TTT method.[3] Ensembling with BARC's program-synthesis component raised the score to 61.9%, which the authors describe as matching average human performance (60.2%) on the benchmark. Their ensemble scored 47.5% on the official ARC-AGI semi-private evaluation, a drop the authors attribute possibly to a larger distribution shift.[3] On BIG-Bench Hard in a 10-shot setting with Llama 3.1 8B, the same TTT recipe improves accuracy from 50.5% to 57.8%, a 7.3 point gain over standard few-shot prompting.[3]
Video generation (TTT-Video, 2025)
The TTT-Video work adds TTT-MLP layers into a pre-trained 5 billion-parameter diffusion transformer (CogVideoX 5B, originally limited to 3-second clips) and fine-tunes it on a dataset built from about seven hours of Tom and Jerry cartoons with human-annotated storyboards, organized into 3-second segments. Self-attention is kept local to each 3-second segment while the TTT layers run globally over the whole sequence of more than 300,000 tokens, and the TTT output passes through a learned tanh gate initialized so that its values start close to 0.1.[4] The authors report that training took the equivalent of 50 hours on 256 H100 GPUs, and they wrote a GPU kernel that shards the TTT-MLP hidden state across streaming multiprocessors on NVIDIA Hopper GPUs.[4]
In a blind human evaluation of 100 videos per method, TTT-MLP led the second-best method (sliding-window attention) by 34 Elo points on average, and led Mamba 2 by 55 points (1033 against 978) and Gated DeltaNet by 42 points.[4][13]
| Method (one-minute videos) | Text following | Motion naturalness | Aesthetics | Temporal consistency | Average Elo |
|---|---|---|---|---|---|
| Mamba 2 | 985 | 976 | 963 | 988 | 978 |
| Gated DeltaNet | 983 | 984 | 993 | 1004 | 991 |
| Sliding window attention | 1016 | 1000 | 1006 | 975 | 999 |
| TTT-MLP | 1014 | 1039 | 1037 | 1042 | 1033 |
The paper notes that the results still contain artifacts, "likely due to the limited capability of the pre-trained 5B model", and that its implementation's efficiency can be improved: for 63-second videos, TTT-MLP inference took 2.5x and training 3.8x as long as the local-attention baseline, compared with 11x and 12x for full attention and 1.8x for Gated DeltaNet.[4]
Comparison with other sequence-modeling approaches
| Approach | Hidden state | Per-token cost | Long-context behavior | Test-time adaptation |
|---|---|---|---|---|
| Transformer (self-attention) | Full KV cache, grows with t | Grows linearly with t (quadratic over the sequence) | Strong, but cost grows | No adaptation; weights frozen |
| RNN / LSTM | Fixed-size vector | Constant | Kaplan et al. found LSTMs did not use long context effectively, as cited in the TTT-layers paper[2] | No adaptation |
| Mamba / state-space models | Selective state | Constant | Perplexity plateaus after 16k tokens on Books in the TTT-layers paper's experiments[2] | No adaptation |
| Linear attention | Matrix accumulator | Constant per token | Equivalent to TTT-Linear with zero , batch GD and lr=1/2[2] | Accumulator update; one batch-GD step in the TTT view |
| TTT-Linear | Linear inner model trained at test time | Constant per token, plus inner-loop GD step | Keeps reducing perplexity beyond 16k on Books[2] | Yes, by inner-loop SSL update |
| TTT-MLP | Two-layer MLP inner model | Constant per token, more memory I/O | Outperforms TTT-Linear in long context in the paper's experiments[2] | Yes, by inner-loop SSL update |
| TTT-E2E | Updated MLP weights plus a sliding-window KV cache | Constant per token | Scales with context like full attention on language-modeling loss; weaker than full attention on needle-in-a-haystack[14] | Yes, by next-token prediction on the context |
The qualitative picture from the 2024 TTT-layers paper is that RNNs with fixed-size hidden states face a limit on how much context they can exploit, which becomes visible as context grows. Self-attention avoids that limit by keeping the entire context in a KV cache, at a per-token cost that grows with context length. TTT layers attempt a third path: keep the per-token cost constant by storing context inside a small parametric model, and increase that model's expressivity by making the inner state itself a neural network. The fact that TTT-Linear collapses to linear attention under a specific reduction makes the relationship to existing methods precise rather than merely analogical.[2]
Applications
Robustness to distribution shifts
The original use case for TTT remains adapting a deployed image classifier to corruptions or covariate shifts that were not present at training. Because the auxiliary task (rotation prediction or MAE reconstruction) does not require labels, the procedure can be applied wherever slower per-sample inference is acceptable. Online TTT, with its accumulated updates, suits deployments where the test distribution drifts gradually, the setting the 2020 paper simulated with slowly increasing noise.[1][6]
Long-context language modeling
The TTT-layer formulation suggests an alternative architecture for large language models in which the model's hidden state can absorb information from long contexts without paying quadratic attention cost. Empirically, TTT-Linear and TTT-MLP keep reducing perplexity beyond 16k tokens on Books3, where Mamba plateaus.[2] TTT-E2E applies the same idea to an otherwise standard Transformer, reaching 128K context with constant per-token prefill latency in the authors' experiments, though with weaker exact retrieval than full attention.[14] Methods such as qTTT and TTT-NTP instead add test-time updates to already released LLM checkpoints.[18][26] The PyTorch reference implementation of TTT layers is intended as a tutorial rather than for training.[7]
Few-shot reasoning and ARC-AGI
The MIT result on ARC-AGI drew wide attention to TTT as an approach to few-shot abstract reasoning. Each ARC task is presented as a handful of input-output pairs that already form a tiny supervised dataset, which suits the "learn at inference time" framing.[3] The ARC Prize 2024 technical report states that "all top LLM-based transduction approaches for ARC-AGI leverage TTT" and that no static-inference transduction solution scored above 11%; it predicted that TTT, or a derivative, "should become popular from 2026 onwards".[22]
Long-form video and other generative settings
The TTT-Video result extends TTT into generative modeling, applying TTT layers inside a pre-trained DiT to handle the very long sequences that one-minute videos require.[4] LaCT carries the approach to a 14B autoregressive video diffusion model and to novel view synthesis with about a million tokens of context, and TTT3R applies the TTT view to recurrent 3D reconstruction.[15][28]
Limitations
Despite the encouraging results, TTT carries several practical limitations.
First, inference-time cost. Performing a gradient-descent step (or many steps) per test sample or per token can multiply the FLOPs and wall-clock time of inference; the 2020 paper put standard TTT at "2 × batch size × number of iterations" times slower than a forward pass.[1] The TTT-layers paper introduces mini-batch TTT and a dual form to keep wall-clock time competitive with Mamba, but reports that TTT-MLP "still faces challenges in memory I/O"; its 2025 revision adds that such instantiations "can still require substantial wall-clock time".[2] LaCT's authors attribute the problem largely to small update mini-batches, which leave GPUs at low utilization.[15] The TTT-Video paper similarly reports that its implementation's efficiency can be improved, and TTT-E2E's training, which needs gradients of gradients, is 3.4x slower than full attention at 8K context.[4][14]
Second, auxiliary-task design. The framework is only as good as the self-supervised loss used in the inner loop. The 2020 paper's theory and experiments tie the benefit of TTT to positive gradient correlation between the auxiliary and main losses, and its VID-Robust airplane example shows no gain when rotation is trivial or ambiguous to predict.[1] The TTT-MAE authors argue that a self-supervised task "cannot be too easy or too hard, otherwise the test input will not provide useful signal".[6]
Third, recall versus compression. Methods that compress context into weights do not store every detail. TTT-E2E's authors report that Transformers with full attention "dramatically" outperform TTT-E2E and other efficient methods on needle-in-a-haystack retrieval, consistent with their stated aim of using long context "without having to recall every detail".[14]
Fourth, evaluation maturity. As of October 2026, the from-scratch language-modeling comparisons of TTT architectures in the TTT-layers, TTT-E2E and LaCT papers run from 125M to 3B parameters (methods that adapt already released checkpoints, such as qTTT and TTT-NTP, were tested on models of up to 8B), and the video and view-synthesis results are reported by the methods' own authors on their own benchmarks.[2][14][15] The behavior of TTT-style architectures at frontier-model scale and in instruction-tuned settings has not been shown in these papers.
Fifth, interaction with existing inference stacks. Updating weights per request or per token complicates batching, caching and serving systems built around frozen weights. The ARC Prize 2024 report judged that TTT is "harder to incorporate" into production systems than program synthesis and expected it would not be productionized "for a couple of years".[22] qTTT is designed around this constraint, updating only query projections so that the KV cache of the context can be reused.[18]
Related Work
TTT belongs to a broader family of inference-time adaptation techniques. In the Liang et al. taxonomy, test-time adaptation covers domain-level, batch-level and online adaptation, and standard TTT is the single-instance case of batch adaptation.[12] Methods such as Tent adapt without an auxiliary training task by minimizing prediction entropy.[20] Test-time augmentation averages predictions over augmented copies of the test input without changing weights, and the survey notes that such techniques "do not explicitly consider distribution shifts".[12]
Other adjacent fields include meta-learning (which trains models to be quickly adaptable from a few examples, and which the TTT-layers and TTT-E2E papers use for their outer loops), continual learning (which adapts on labeled streaming data), in-context learning (which adapts behavior without weight changes by conditioning on examples in the prompt), and online learning.[2][14] The TTT-for-ARC paper compares TTT with in-context learning and reports that gradient-based adaptation on the demonstrations outperforms few-shot prompting on both ARC and BIG-Bench Hard at the scales tested.[3]
Within sequence modeling, TTT layers are most directly comparable to selective state space models such as Mamba and Mamba 2, to linear attention variants such as DeltaNet and Gated DeltaNet, and to RWKV and xLSTM, which the TTT-layers paper lists among RNNs with matrix hidden states inherited from linear attention.[2] The relationship to linear attention is formal (Theorem 1 of the 2024 paper); the relationship to Mamba is empirical and shows up most clearly at long context.[2] The TTT-Video paper compares against Gated DeltaNet and sliding-window attention.[4] Google's Titans and its follow-ups place a test-time-updated memory alongside attention.[25]
Continue reading
- MambaMamba is a neural network architecture for sequence modeling that uses selective state space models (SSMs) to process sequential data in linear time with respect to sequence lengthMentioned 23 times above
- Linear AttentionLinear attention is a family of sub-quadratic attention mechanisms that replaces the softmax dot-product operation of standard Transformer self-attention with a feature-map-based factorizationMentioned 13 times above
- ARC-AGIARC-AGI (Abstraction and Reasoning Corpus for Artificial General Intelligence) is a family of AI benchmarks, created by Francois Chollet, that measures fluid intelligence: the ability to solve genuinely novel…Mentioned 10 times above
- Gated DeltaNetGated DeltaNet is a linear attention sequence model that augments the delta rule, a key-value error-correction update used in the earlier DeltaNet architectureMentioned 7 times above
- Mamba 2Mamba 2 is a state space model architecture introduced in the paper "Transformers are SSMs: Generalized Models and Efficient Algorithms Through Structured State Space Duality" by Tri Dao and Albert GuMentioned 5 times above
- LoRA (Low-Rank Adaptation)Low-Rank Adaptation, usually abbreviated LoRA, is a parameter-efficient fine-tuning method for adapting a pre-trained model.Mentioned 5 times above
More to read
- State space model (deep learning)
- Titans (neural architecture)
- Domain adaptation
- The Pile (dataset)
- Continual learning
- In-Context Learning
Topics:AI InferenceDeep LearningMachine LearningModel Architecture
See also
- Transformer
- Mamba and Mamba 2
- State space model (deep learning)
- Linear Attention
- Gated DeltaNet
- Titans (neural architecture)
- Recurrent Neural Network
- Self-supervised learning
- Masked Autoencoder
- Domain adaptation
- Continual learning
- Meta-Learning
- In-context learning
- LoRA
- ARC-AGI
- Test-time compute
- The Pile (dataset)
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27Sun, Yu; Wang, Xiaolong; Liu, Zhuang; Miller, John; Efros, Alexei A.; Hardt, Moritz, "Test-Time Training with Self-Supervision for Generalization under Distribution Shifts", arXiv preprint (ICML 2020), 2019-09-29 (revised 2020-07-01). arxiv.org/...1909.13231. Accessed 2026-05-20.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32 ^33 ^34 ^35 ^36 ^37 ^38Sun, Yu; Li, Xinhao; Dalal, Karan; Xu, Jiarui; Vikram, Arjun; Zhang, Genghan; Dubois, Yann; Chen, Xinlei; Wang, Xiaolong; Koyejo, Sanmi; Hashimoto, Tatsunori; Guestrin, Carlos, "Learning to (Learn at Test Time): RNNs with Expressive Hidden States", arXiv preprint, 2024-07-05. arxiv.org/...2407.04620. Accessed 2026-05-20.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11Akyurek, Ekin; Damani, Mehul; Zweiger, Adam; Qiu, Linlu; Guo, Han; Pari, Jyothish; Kim, Yoon; Andreas, Jacob, "The Surprising Effectiveness of Test-Time Training for Few-Shot Learning", arXiv preprint, 2024-11-11. arxiv.org/...2411.07279. Accessed 2026-05-20.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10Dalal, Karan; Koceja, Daniel; Hussein, Gashon; Xu, Jiarui; Zhao, Yue; Song, Youjin; Han, Shihao; Cheung, Ka Chun; Kautz, Jan; Guestrin, Carlos; Hashimoto, Tatsunori; Koyejo, Sanmi; Choi, Yejin; Sun, Yu; Wang, Xiaolong, "One-Minute Video Generation with Test-Time Training", arXiv preprint (CVPR 2025), 2025-04-07. arxiv.org/...2504.05298. Accessed 2026-05-20.
- ^Sun, Yu; Wang, Xiaolong; Liu, Zhuang; Miller, John; Efros, Alexei; Hardt, Moritz, "Test-Time Training with Self-Supervision for Generalization Under Distribution Shifts", Proceedings of the 37th International Conference on Machine Learning, PMLR vol. 119, 2020. proceedings.mlr.press/...sun20b. Accessed 2026-05-20.
- ^1 ^2 ^3 ^4 ^5 ^6Gandelsman, Yossi; Sun, Yu; Chen, Xinlei; Efros, Alexei A., "Test-Time Training with Masked Autoencoders", arXiv preprint (NeurIPS 2022), 2022-09-15. arxiv.org/...2209.07522. Accessed 2026-05-20.
- ^1 ^2 ^3 ^4 ^5test-time-training, "ttt-lm-pytorch: Official PyTorch implementation of Learning to (Learn at Test Time): RNNs with Expressive Hidden States", GitHub repository, 2024 (MIT License). github.com/...ttt-lm-pytorch. Accessed 2026-05-20.
- ^1 ^2test-time-training, "ttt-lm-jax: Official JAX implementation of Learning to (Learn at Test Time): RNNs with Expressive Hidden States", GitHub repository, 2024. github.com/...ttt-lm-jax. Accessed 2026-05-20.
- ^socialfoundations, "tttlm: Test-time-training on nearest neighbors for large language models", GitHub repository (ICLR 2024 companion code), 2024. github.com/...tttlm. Accessed 2026-05-20.
- ^Zhao, Yutian; Zhang, Tianjing; Ji, Hui, "TTT-AdaptNet: Test-time Model Adaptation for Image Reconstruction Using Self-supervised Adaptive Layers (ECCV 2024)", GitHub repository, 2024. github.com/...TTT-AdaptNet. Accessed 2026-05-20.
- ^Zuo, Yuxin et al., "TTRL: Test-Time Reinforcement Learning", arXiv preprint, 2025-04-22 (revised 2025-06-30). arxiv.org/...2504.16084. Accessed 2026-05-20.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Liang, Jian; He, Ran; Tan, Tieniu, "A Comprehensive Survey on Test-Time Adaptation under Distribution Shifts", International Journal of Computer Vision, 133(1):31-64, 2025 (preprint arXiv 2303.15361). arxiv.org/...2303.15361. Accessed 2026-05-20.
- ^test-time-training, "One-Minute Video Generation with Test-Time Training (project page)", 2025. test-time-training.github.io/video-dit. Accessed 2026-05-20.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12Tandon, Arnuv; Dalal, Karan; Li, Xinhao; Koceja, Daniel; Rød, Marcel; Buchanan, Sam; Wang, Xiaolong; Leskovec, Jure; Koyejo, Sanmi; Hashimoto, Tatsunori; Guestrin, Carlos; McCaleb, Jed; Choi, Yejin; Sun, Yu, "End-to-End Test-Time Training for Long Context", arXiv preprint, 2025-12-29 (revised 2025-12-31). arxiv.org/...2512.23675. Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Zhang, Tianyuan; Bi, Sai; Hong, Yicong; Zhang, Kai; Luan, Fujun; Yang, Songlin; Sunkavalli, Kalyan; Freeman, William T.; Tan, Hao, "Test-Time Training Done Right", arXiv preprint (ICLR 2026), 2025-05-29. arxiv.org/...2505.23884. Accessed 2026-10-31.
- ^1 ^2von Oswald, Johannes; Scherrer, Nino; Kobayashi, Seijin; Versari, Luca; Yang, Songlin; Mittal, Sarthak; Schlegel, Maximilian; Maile, Kaitlin; Schimpf, Yanick; Sieberling, Oliver; Meulemans, Alexander; Saurous, Rif A.; Lajoie, Guillaume; Frenkel, Charlotte; Pascanu, Razvan; Agüera y Arcas, Blaise; Sacramento, João, "MesaNet: Sequence Modeling by Locally Optimal Test-Time Training", arXiv preprint (ICLR 2026), 2025-06-05 (revised 2026-06-03). arxiv.org/...2506.05233. Accessed 2026-10-31.
- ^1 ^2Wang, Ke Alexander; Shi, Jiaxin; Fox, Emily B., "Test-time regression: a unifying framework for designing sequence models with associative memory", arXiv preprint, 2025-01-21 (revised 2025-05-02). arxiv.org/...2501.12352. Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5 ^6Bansal, Rachit; Zhang, Aston; Tiwari, Rishabh; Madaan, Lovish; Duvvuri, Sai Surya; Khatri, Devvrit; Brandfonbrener, David; Alvarez-Melis, David; Bhargava, Prajjwal; Kale, Mihir Sanjay; Jelassi, Samy, "Let's (not) just put things in Context: Test-Time Training for Long-Context LLMs", arXiv preprint (ICLR 2026), 2025-12-15. arxiv.org/...2512.13898. Accessed 2026-10-31.
- ^1 ^2 ^3 ^4Yuksekgonul, Mert; Koceja, Daniel; Li, Xinhao; Bianchi, Federico; McCaleb, Jed; Wang, Xiaolong; Kautz, Jan; Choi, Yejin; Zou, James; Guestrin, Carlos; Sun, Yu, "Learning to Discover at Test Time", arXiv preprint (ICML 2026), 2026-01-22 (revised 2026-02-05). arxiv.org/...2601.16175. Accessed 2026-10-31.
- ^1 ^2 ^3Wang, Dequan; Shelhamer, Evan; Liu, Shaoteng; Olshausen, Bruno; Darrell, Trevor, "Tent: Fully Test-time Adaptation by Entropy Minimization", arXiv preprint (ICLR 2021), 2020-06-18. arxiv.org/...2006.10726. Accessed 2026-10-31.
- ^1 ^2Snell, Charlie; Lee, Jaehoon; Xu, Kelvin; Kumar, Aviral, "Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model Parameters", arXiv preprint, 2024-08-06. arxiv.org/...2408.03314. Accessed 2026-10-31.
- ^1 ^2 ^3 ^4Chollet, François; Knoop, Mike; Kamradt, Gregory; Landers, Bryan, "ARC Prize 2024: Technical Report", arXiv preprint, 2024-12-05 (revised 2025-01-08). arxiv.org/...2412.04604. Accessed 2026-10-31.
- ^1 ^2Wang, Renhao; Sun, Yu; Tandon, Arnuv; Gandelsman, Yossi; Chen, Xinlei; Efros, Alexei A.; Wang, Xiaolong, "Test-Time Training on Video Streams", arXiv preprint (Journal of Machine Learning Research 26, 2025), 2023-07-11 (revised 2025-01-04). arxiv.org/...2307.05014. Accessed 2026-10-31.
- ^Sun, Yu; Li, Xinhao; Dalal, Karan; Hsu, Chloe; Koyejo, Sanmi; Guestrin, Carlos; Wang, Xiaolong; Hashimoto, Tatsunori; Chen, Xinlei, "Learning to (Learn at Test Time)", arXiv preprint, 2023-10-20 (revised 2024-01-07). arxiv.org/...2310.13807. Accessed 2026-10-31.
- ^1 ^2 ^3Behrouz, Ali; Zhong, Peilin; Mirrokni, Vahab, "Titans: Learning to Memorize at Test Time", arXiv preprint (NeurIPS 2025), 2024-12-31. arxiv.org/...2501.00663. Accessed 2026-10-31.
- ^1 ^2Ouyang, Xuan; Cai, Zefan; Hu, Junjie, "Test-Time Training with Next-Token Prediction", arXiv preprint (Findings of EMNLP 2026), 2026-06-19 (revised 2026-08-30). arxiv.org/...2606.21803. Accessed 2026-10-31.
- ^Chen, Zeming; Romanou, Angelika; Weiss, Gail; Bosselut, Antoine, "PERK: Long-Context Reasoning as Test-Time Learning", arXiv preprint (ICLR 2026), 2025-07-08 (revised 2026-08-31). arxiv.org/...2507.06415. Accessed 2026-10-31.
- ^1 ^2Chen, Xingyu; Chen, Yue; Xiu, Yuliang; Geiger, Andreas; Chen, Anpei, "TTT3R: 3D Reconstruction as Test-Time Training", arXiv preprint (ICLR 2026), 2025-09-30 (revised 2026-03-03). arxiv.org/...2509.26645. Accessed 2026-10-31.
- ^1 ^2test-time-training, "ttt-video-dit: Official PyTorch implementation of One-Minute Video Generation with Test-Time Training", GitHub repository, 2025 (MIT License). github.com/...ttt-video-dit. Accessed 2026-10-31.
- ^1 ^2test-time-training, "e2e: Official JAX implementation of End-to-End Test-Time Training for Long Context", GitHub repository, 2025. github.com/...e2e. Accessed 2026-10-31.
- ^Zhang, Tianyuan (a1600012888), "LaCT: Code release for paper Test-Time Training Done Right", GitHub repository, 2025 (MIT License). github.com/...LaCT. Accessed 2026-10-31.
- ^Sun, Yu et al., "Learning to (Learn at Test Time): RNNs with Expressive Hidden States", Proceedings of the 42nd International Conference on Machine Learning, PMLR vol. 267, pp. 57503-57522, 2025. proceedings.mlr.press/...sun25h. Accessed 2026-10-31.
- ^Akyürek, Ekin et al., "The Surprising Effectiveness of Test-Time Training for Few-Shot Learning", Proceedings of the 42nd International Conference on Machine Learning, PMLR vol. 267, pp. 942-963, 2025. proceedings.mlr.press/...akyurek25a. Accessed 2026-10-31.
- ^Hardt, Moritz; Sun, Yu, "Test-Time Training on Nearest Neighbors for Large Language Models", arXiv preprint (ICLR 2024), 2023-05-29 (revised 2024-02-02). arxiv.org/...2305.18466. Accessed 2026-10-31.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
8 revisions by 1 contributor · v8 · 8,306 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independently verified 2026-10-31 against the TTT (ICML 2020), TTT-MAE, TTT-layers, ARC, video-TTT, TTT-E2E, LaCT and other cited papers (arXiv, PMLR, OpenReview, Crossref) and GitHub API; 17 verifier defects (5 material, mostly missing venues) fixed before stamping.
Cite this page: AI Wiki. "Test-Time Training (TTT)." aiwiki.ai, updated 31 Oct 2026, fact-checked 31 Oct 2026. CC BY 4.0. https://aiwiki.ai/wiki/test_time_training