

Hugging Face Transformers
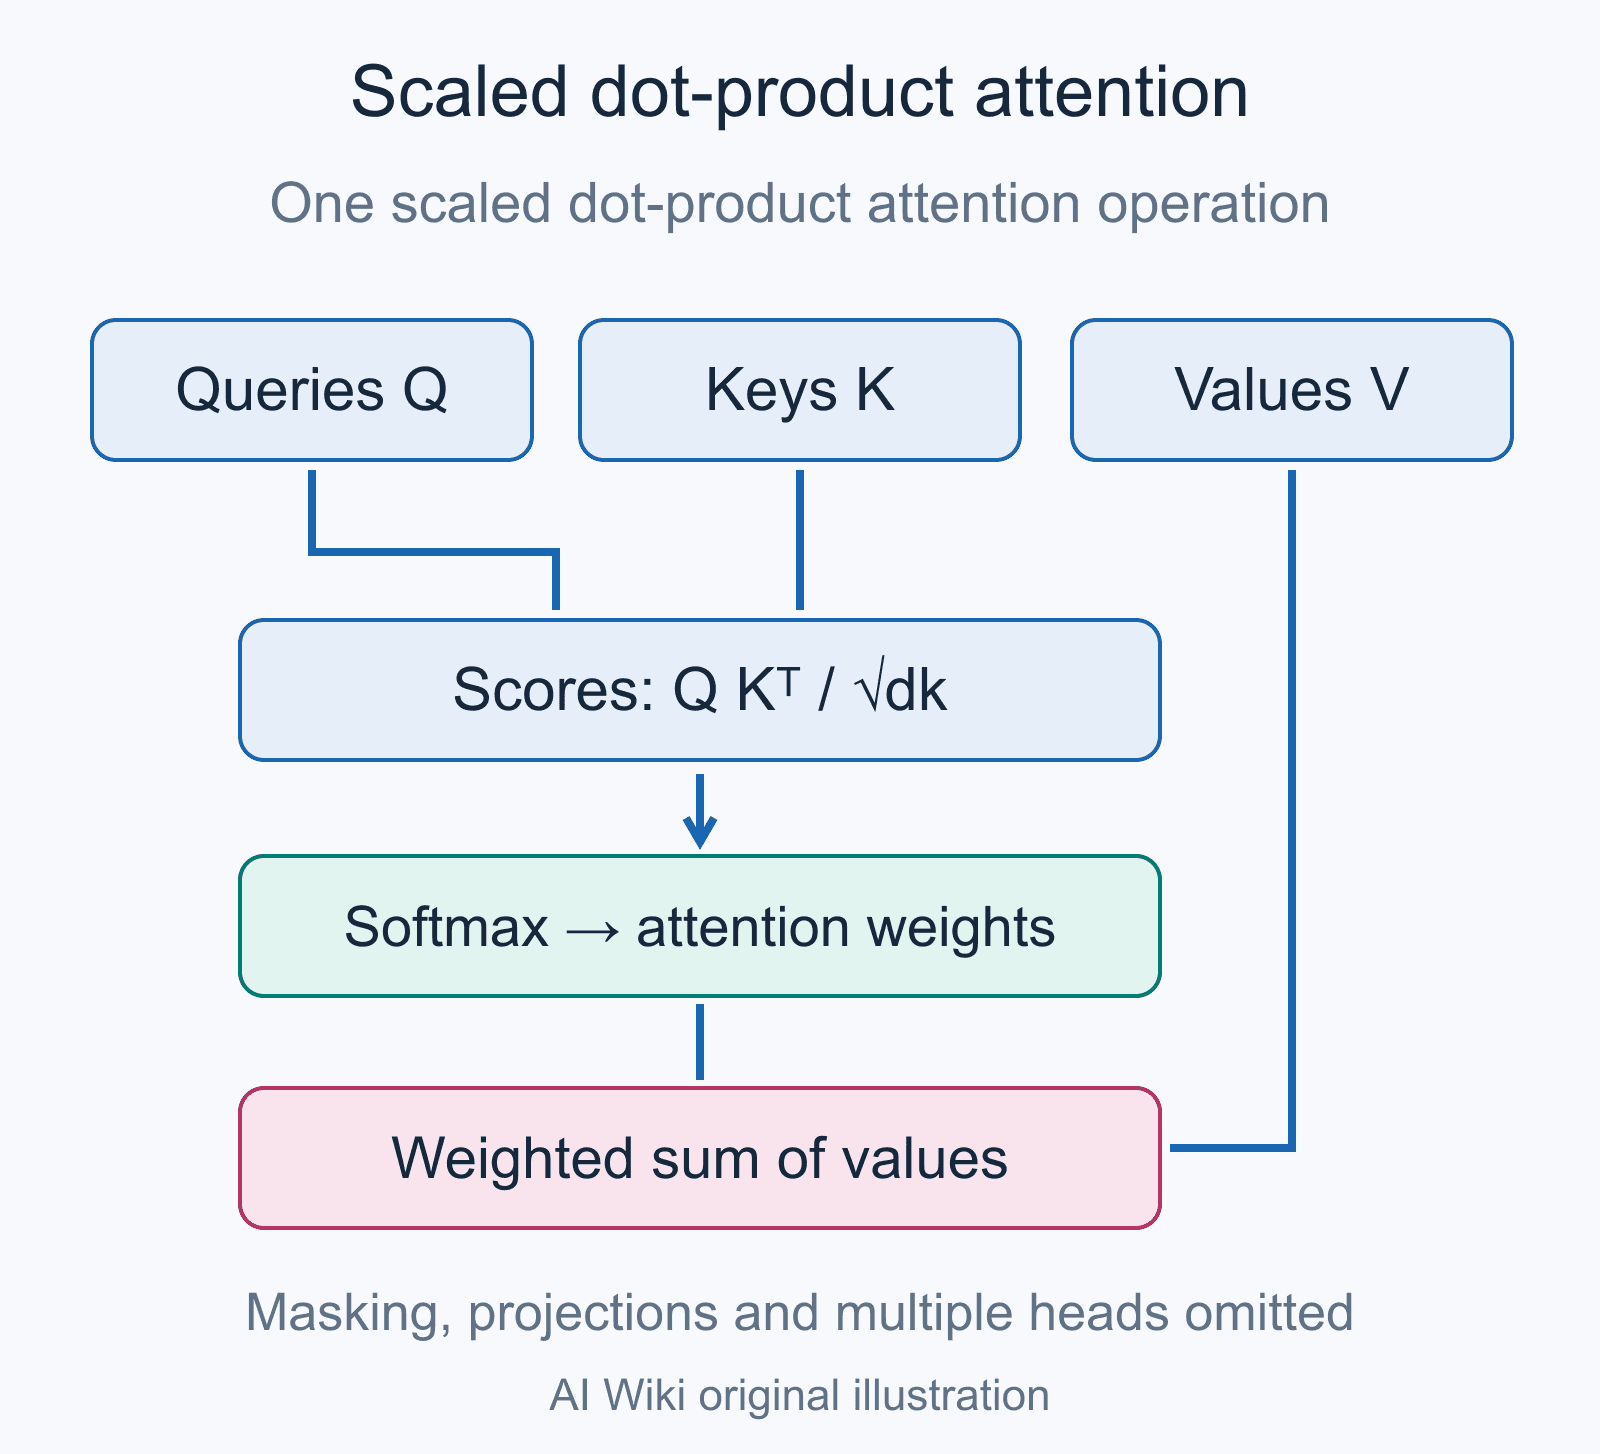
Note: This article is about the open-source Python library by Hugging Face. For the neural network architecture introduced in the 2017 paper "Attention Is All You Need," see Transformer (architecture).
Hugging Face Transformers is an open-source Python library that provides general-purpose architectures, a unified API, and pretrained weights for state-of-the-art machine learning models across text, vision, audio, and multimodal tasks, installable with a single pip install transformers command.[3] In the words of its own EMNLP 2020 paper, "Transformers is an open-source library with the goal of opening up these advances to the wider machine learning community."[1] It started life as a PyTorch port of Google's BERT reference code, and has since become the de facto standard interface for natural language understanding, text generation, computer vision, audio processing, and multimodal modeling.[16] The library covers more than 400 model architectures, including BERT, GPT, T5, BART, ViT, CLIP, Whisper, LLaMA, Mistral, Mixtral, Gemma, Phi, Qwen, and DeepSeek, and (through version 4.x) worked with PyTorch, TensorFlow, and JAX.[3] It is developed and maintained by Hugging Face, an open-source AI company headquartered in New York City, which agreed in September 2026 to be acquired by NVIDIA.[15][22]
Transformers is licensed under Apache 2.0 and tightly integrated with the Hugging Face Hub, which hosts more than 2 million public model checkpoints and over 500,000 public datasets as of 2026.[6][11] The repository carries roughly 162,000 GitHub stars and about 33,600 forks as of June 2026, making it one of the most starred machine learning projects on GitHub.[7] The associated EMNLP demo paper, Wolf et al. 2020, has been cited thousands of times (OpenAlex counts more than 8,700 citations for the 2020 paper alone) and is one of the most cited software papers in modern NLP.[1][19] The official GitHub tagline now describes it as "the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training."[7]
What is the Hugging Face Transformers library?
In practical terms, transformers is a single Python package (pip install transformers) that exposes:
- A unified Python API for loading pretrained models, tokenizers, image processors, and feature extractors from the Hub.
- Standardized model classes that mirror the original research implementations as closely as possible.
- A high-level
pipelineAPI for one-line inference on common tasks. - A
Trainerclass for fine-tuning with mixed precision, gradient accumulation, and distributed training. - A
generateAPI for text generation, supporting greedy decoding, beam search, sampling, contrastive search, and speculative decoding. - Hooks for quantization, parameter-efficient fine-tuning, hardware acceleration, and serving.
The library is, in the words of its own documentation, the "model-definition framework" for the broader ecosystem: if a model is supported in transformers, it tends to be compatible with downstream training frameworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch Lightning) and inference engines (vLLM, SGLang, TGI, llama.cpp, MLX) that build on top of those definitions.[3] Hugging Face frames the v5 release the same way: "Transformers, at the core, remains a model architecture toolkit." A partner quote in the same post, from Michael Han of Unsloth, calls it "the backbone of hundreds of thousands of projects."[18]
When was the Transformers library released? History and timeline
The library predates the Hugging Face Hub and even predates Hugging Face's pivot from a chatbot company to an ML platform. It began in late 2018 when Thomas Wolf and a small team ported Google's TensorFlow BERT code to PyTorch.[15] The package went through two renames before settling on transformers in late 2019.[15]
| Year | Milestone |
|---|---|
| 2016 | Hugging Face founded by Clément Delangue, Julien Chaumond, and Thomas Wolf in New York City as a chatbot startup for teenagers. |
| Nov 2018 | Hugging Face releases pytorch-pretrained-bert, a PyTorch port of Google's BERT, on PyPI. |
| Feb 2019 | Library expands to OpenAI GPT, GPT-2, and Transformer-XL after PyTorch reimplementations of GPT-2 small. |
| Jul 2019 | Library renamed to pytorch-transformers (v1.0) to reflect its broader scope; adds XLNet and XLM, with RoBERTa and DistilBERT following in August 2019. |
| Sep 2019 | Renamed again to transformers (v2.0); TensorFlow 2.0 support added so models can be loaded interchangeably between frameworks. |
| Oct 2019 | Wolf et al. publish the technical report "HuggingFace's Transformers: State-of-the-art Natural Language Processing" on arXiv (1910.03771).[2] |
| 2020 | Wolf et al. paper accepted to EMNLP 2020 (System Demonstrations), pp. 38-45, formally introducing the library to the research community. Pipelines API gains traction.[1] |
| Jun 2020 | v3.0 release (June 29, 2020); new tokenizer API, TensorFlow improvements, and expanded documentation and tutorials. The Trainer class had arrived in v2.9 in May 2020.[23] |
| Nov 2020 | v4.0 release (November 30, 2020); fast Rust tokenizers become the default, alongside model output objects and a file reorganization.[23] |
| 2021 | Acquires Gradio (December 2021) to provide easy demo hosting through Spaces. |
| 2021-2022 | Adds vision models (ViT, DETR, Swin) and audio models (Wav2Vec2 in February 2021, Whisper in October 2022); BigScience releases BLOOM through the Hub in 2022.[23] |
| Apr 2023 | Native support for LLaMA ships in v4.28.0 (April 13, 2023), weeks after Meta's February release; Mistral, Falcon, MPT, and other open LLMs follow throughout the year. |
| Aug 2023 | Hugging Face raises $235M Series D at a $4.5B valuation from investors including Google, Amazon, NVIDIA, Intel, Salesforce, and AMD.[14] |
| 2024 | Multimodal pipelines, agentic features (smolagents), assisted decoding, and integration with Inference Providers. Acquires Argilla in June 2024 ($10M) and XetHub in August 2024.[21] |
| Apr 2025 | Acquires Pollen Robotics, the maker of the open-source Reachy 2 humanoid robot.[12] |
| Dec 2025 | Transformers v5.0.0rc-0 released (December 1, 2025): PyTorch-only backend, quantization promoted to a first-class feature, and the start of the sunset of TensorFlow and Flax support.[18] |
| Jun 2026 | The v5 line continues at a fast cadence, reaching v5.12.1 on June 15, 2026; the Hub has crossed 2 million public models, 500,000 public datasets, and 13 million users.[11][17] |
The November 2018 release of pytorch-pretrained-bert matters because it made BERT, which had only just been published by Google, usable in PyTorch with a few lines of Python.[16][17] That single design choice (mirror the official architecture, ship pretrained weights, and let people fine-tune in their own training loop) is the pattern the library has followed ever since.
Architecture and core concepts
The library is organized around a small set of abstractions that get reused across every model.
Three-class pattern
Every model in transformers is implemented with three main classes:
- A configuration class (e.g.,
BertConfig) that holds all hyperparameters as plain Python attributes. - A model class (e.g.,
BertModel,BertForSequenceClassification) implementing the forward pass. - A preprocessor class such as a tokenizer, image processor, or feature extractor.
The philosophy is intentionally light on abstraction. Each model file is meant to be readable on its own without chasing class hierarchies. Hugging Face calls this the "single model file" policy.[3]
AutoClasses
Most users do not instantiate model classes directly. Instead they use the Auto family, which inspects a checkpoint's config and picks the right class:
AutoConfigloads the configuration.AutoTokenizerreturns the correct tokenizer (fast Rust-backed when available, slow Python otherwise).AutoModelreturns the base model.AutoModelForCausalLM,AutoModelForSequenceClassification,AutoModelForQuestionAnswering,AutoModelForSeq2SeqLM, etc., return models with the right task head.AutoImageProcessorandAutoFeatureExtractorhandle vision and audio inputs.
This is what lets the same five lines of code load BERT, RoBERTa, DeBERTa, DistilBERT, or any compatible checkpoint by changing only the model name.[3]
Pipelines
The pipeline factory wraps preprocessing, the model, and postprocessing into one callable. It is the easiest entry point for prototyping and accounts for many of the library's tutorials.[4] Tasks supported include:
| Modality | Pipeline tasks |
|---|---|
| Text | text-classification (alias sentiment-analysis), token-classification (alias ner), table-question-answering, fill-mask, text-generation, zero-shot-classification, feature-extraction (the v4-era question-answering, text2text-generation, summarization, and translation pipelines are gone from v5) |
| Vision | image-classification, image-segmentation, object-detection, depth-estimation, mask-generation, keypoint-matching, image-feature-extraction, zero-shot-image-classification, zero-shot-object-detection, video-classification |
| Audio | automatic-speech-recognition, audio-classification, text-to-audio (alias text-to-speech), zero-shot-audio-classification |
| Multimodal | image-text-to-text, document-question-answering, any-to-any |
A one-liner like pipeline("automatic-speech-recognition", model="openai/whisper-large-v3") will download Whisper, set up its feature extractor, and return a callable that transcribes audio files.[4]
Trainer
Trainer is the library's training loop. It handles:
- Mixed precision (fp16, bf16, fp8 where supported).
- Gradient accumulation and gradient checkpointing.
- Distributed training via
accelerate, including DDP, FSDP, and DeepSpeed ZeRO. torch.compileintegration.- Hyperparameter search backends (Optuna, Ray Tune, Weights & Biases sweeps).
- Logging to TensorBoard, W&B, MLflow, Comet, Neptune, and Hugging Face Hub.
- Automatic model card generation and Hub upload on save.
For reinforcement learning from human feedback or preference optimization, users typically reach for trl (Transformer Reinforcement Learning) on top of Trainer.[10]
generate API
The model.generate() method is the main interface for text generation in causal LMs and sequence-to-sequence models. It supports greedy decoding, beam search, sampling with temperature, top-k and top-p (nucleus), contrastive search and diverse (group) beam search (both now loaded from Hub-hosted custom_generate repositories rather than built into the core library), and speculative or assisted decoding (where a smaller draft model proposes tokens that a larger model accepts or rejects).[3] Streaming output is supported through TextStreamer and TextIteratorStreamer.
Generation also includes a configurable KV cache, RoPE scaling for extended context windows, repetition penalties, logit processors, and stopping criteria. Tool calling and structured output, including JSON-grammar constrained decoding, are supported on compatible models.[3]
Model coverage
As of v5.x the library ships definitions for more than 400 architectures.[18] The roster spans encoder-only models (BERT, RoBERTa, DeBERTa, DistilBERT, ALBERT, ELECTRA), decoder-only models (GPT-2, GPT-J, GPT-NeoX, OPT, BLOOM, LLaMA 1-4, Mistral, Mixtral, Gemma, Phi, Qwen, DeepSeek, Falcon, MPT), encoder-decoder models (T5, mT5, BART, mBART, Pegasus, MarianMT, NLLB), vision models (ViT, DeiT, Swin, ConvNeXt, DINOv2, BEiT, MAE, DETR, Mask2Former), audio models (Wav2Vec2, HuBERT, Whisper, MMS, SeamlessM4T, MusicGen), and multimodal models (CLIP, BLIP, BLIP-2, LLaVA, IDEFICS, Pix2Struct, Donut, Kosmos-2, PaliGemma, Qwen-VL, Llama 3.2 Vision).
The Hugging Face ecosystem
Transformers does not stand alone. The library ships with hooks into roughly a dozen sister packages, most of them maintained by Hugging Face itself:
| Library | Purpose |
|---|---|
transformers | Model architectures, tokenizers, training, generation, pipelines. |
tokenizers | Fast Rust-backed tokenizers (BPE, WordPiece, Unigram, byte-level). |
datasets | Streaming-capable dataset loading; over 500,000 datasets on the Hub. |
accelerate | Hardware-agnostic distributed training and inference; abstracts CUDA, ROCm, TPU, and Apple Silicon. |
peft | Parameter-efficient fine-tuning (LoRA, QLoRA, IA3, prefix tuning, prompt tuning, adapters). |
trl | RLHF and preference optimization (SFT, PPO, DPO, KTO, ORPO, GRPO). |
diffusers | Diffusion models (Stable Diffusion, SDXL, SD 3, Flux, video diffusion). |
optimum | Hardware-specific optimization backends: ONNX Runtime, TensorRT, OpenVINO, Habana Gaudi, AWS Neuron, Apple Neural Engine. |
evaluate | Standardized evaluation metrics. |
safetensors | Safe, fast tensor serialization format that has largely replaced pickle-based PyTorch checkpoints. |
huggingface_hub | Programmatic Hub access, file downloads, repo management, Inference API client. |
gradio | UI library for building demo apps; powers most Hugging Face Spaces. |
smolagents | Lightweight agent framework for tool-using LLMs. |
The ecosystem is designed so that you can mix and match. For example, fine-tuning Llama 3 with QLoRA in 4-bit precision typically uses transformers for the model, bitsandbytes for the 4-bit quantization, peft for the LoRA adapters, datasets for the training data, accelerate for distributed training, and trl if the recipe involves DPO or PPO.[8][9][10] Every step touches huggingface_hub for downloads and uploads.
Which deep learning frameworks does Transformers support?
Transformers is unusual in that it long tried to keep a single Python interface across multiple deep learning frameworks. In practice the support became uneven, and with the v5 release of December 2025 Hugging Face consolidated on PyTorch: "Finally, we're sunsetting our Flax/TensorFlow support in favor of focusing on PyTorch as the sole backend."[18]
| Framework | Support level | Notes |
|---|---|---|
| PyTorch | First-class for essentially every model | The reference implementations live in modeling_*.py files. As of v5.x, PyTorch is the sole supported backend. |
| TensorFlow / Keras | Removed in the v5 line | Historically implemented in modeling_tf_*.py; the v5 line sunsets TF support in favor of PyTorch. |
| JAX / Flax | Removed in the v5 line | Historically implemented in modeling_flax_*.py; Hugging Face is instead working with Jax-ecosystem partners on compatibility rather than maintaining in-tree Flax models. |
| ONNX | Via optimum | Most common production export path for CPU and GPU inference. |
| TensorRT-LLM, vLLM, SGLang, TGI | Via separate inference servers | These projects re-implement the hot path for serving but reuse transformers model definitions and tokenizers. |
Hugging Face Hub integration
The Hub is the network effect that has made the library hard to dislodge. Loading a checkpoint with from_pretrained("meta-llama/Llama-3.1-8B-Instruct") resolves to a Hub repository, downloads the relevant files (config, tokenizer, weights, often in safetensors), caches them locally, and instantiates the model.[6] Uploads are symmetrical: model.push_to_hub("my-org/my-model") creates a Hub repository (stored on the Xet backend, with Git LFS still supported) with a model card.[6][20]
Hugging Face's State of Open Source on Hugging Face: Spring 2026 report gives a precise snapshot of the Hub circa early 2026:[11]
- More than 2 million public model repositories and over 500,000 public datasets.
- 13 million users in 2025, with model, dataset, and user counts all close to doubling year over year.
- Heavy concentration: the top 200 most-downloaded models, about 0.01 percent of all models, account for 49.6 percent of downloads, while roughly half of all models have fewer than 200 total downloads.
- A geographic shift: Chinese models reached a plurality at about 41 percent of downloads in 2025, following the viral release of DeepSeek R1.
- A move from corporate to community: industry's share of overall development fell from around 70 percent before 2022 to roughly 37 percent in 2025, while independent or unaffiliated developers rose from 17 percent to 39 percent of all downloads.
- A widening size distribution: the mean downloaded open model grew from 827 million parameters in 2023 to 20.8 billion in 2025, while the median rose only marginally from 326 million to 406 million parameters.
- A robotics surge: robotics datasets grew from 1,145 in 2024 to 26,991 in 2025, climbing from the 44th-largest dataset category to the single largest.
The Hub is backed by the Xet storage system (acquired through XetHub in 2024), which deduplicates large files at the chunk level and significantly speeds up uploads and downloads of multi-gigabyte model weights.[20][21]
How widely is the Transformers library used?
A few numbers give a sense of the scale.
- GitHub stars: about 162,000 on
huggingface/transformersas of June 2026, with roughly 33,600 forks and tens of thousands of contributors and pull requests, ranking it among the most starred ML projects on GitHub.[7] - Releases: development moves fast, with the v5 line reaching v5.12.1 on June 15, 2026 after several point releases earlier the same month.[17]
- Downloads: more than 3 million pip installs per day and more than 1.2 billion installs in total at the v5 launch in December 2025, making it consistently one of the most-downloaded ML packages.[18]
- Citations: Wolf et al. 2020 has been cited more than 8,700 times according to OpenAlex, putting it among the most cited NLP software papers.[19]
- Industry use: Microsoft, Meta, Google DeepMind, Amazon, NVIDIA, Anthropic, Cohere, IBM, Salesforce, Apple, and many startups use the library directly for research or as a baseline. Most public open-weight models from these organizations ship with
transformers-compatible code. - Education: It is the standard teaching library in graduate NLP courses and bootcamps; the official Hugging Face NLP and LLM courses are widely used.
It is fair to say that releasing a new pretrained model without a transformers-compatible implementation is now the exception rather than the rule.
Major features
A partial inventory of features that have shaped how people use the library.
- Quantization: integrations with
bitsandbytes(8-bit and 4-bit, QLoRA-friendly), AWQ, GPTQ / GPTQModel, AQLM, HQQ, EETQ, FBGEMM FP8, Quanto, torchao, compressed-tensors, GGUF interoperability withllama.cpp, and built-in fine-grained FP8. With v5, Hugging Face made quantization a first-class feature: "we move to quantization being a first-class citizen."[5][18] - Long context: rotary position embedding (RoPE) scaling, position interpolation, YARN, NTK-aware scaling; KV cache management for streaming and long generations.
- Speculative decoding: assisted generation with a draft model, EAGLE-style and Medusa-style heads where supported.
- Streaming:
TextStreamerand async iterators for token-by-token output. - Tool calling and structured output: chat templates, function-calling formats, JSON-schema constrained decoding via integration with libraries such as Outlines and XGrammar.
- FlashAttention 2 and 3: drop-in attention implementations selectable through
attn_implementation="flash_attention_2"or"sdpa". - Mixed-precision and
torch.compile: bf16 default on modern hardware;torch.compilesupported across many architectures. - Chat templates: per-model Jinja templates that turn structured chat messages into the exact prompt format a given instruction-tuned model expects.
- Multimodal pipelines: image-text-to-text, document QA, video classification.
What is the Transformers library used for?
The library shows up in roughly four kinds of work.
- Research: it is the standard way to release a paper's code. New architectures usually land first as a research repo and then as a
transformersPR, after which the rest of the ecosystem (vLLM, TGI, llama.cpp, MLX) adapts. - Prototyping: the
pipelineAPI and the Hub make it possible to wire up a working classifier, summarizer, or speech transcriber in under five minutes. - Fine-tuning:
Trainerpluspeftis the most common way to adapt an open-weight LLM to a specific domain, instruction format, or task. QLoRA fine-tuning of 7B-70B parameter models on a single GPU is now routine.[8] - Production inference: companies sometimes serve directly from
transformers, but high-throughput LLM serving usually moves to vLLM, TGI, SGLang, or TensorRT-LLM, all of which importtransformersmodel definitions and tokenizers.
How does Transformers differ from vLLM, TGI, and llama.cpp?
| Tool | Primary focus | Strengths | Trade-offs |
|---|---|---|---|
| Hugging Face Transformers | Model definitions and training | Largest model catalog; standard API; tight Hub integration | Inference is slower than dedicated servers; some abstraction overhead |
| vLLM | High-throughput LLM serving | Continuous batching, PagedAttention, very fast | Inference only; smaller model coverage than transformers |
| Text Generation Inference (TGI) | Production LLM serving by Hugging Face | Production hardened, container-friendly, integrates with the Hub | Inference only; less flexible than transformers for research |
| llama.cpp | CPU and GGUF inference | Runs on laptops, phones, and edge devices; very small footprint | C++ codebase, not a Python training library |
| Ollama | Local model runner built on llama.cpp | Easiest end-user UX for local LLMs | Inference only, opinionated wrapper |
| TensorFlow Hub | TF model catalog | First-party for TF | Smaller catalog; no PyTorch support; not the standard for LLMs |
| JAX/Flax model libraries | Research and TPU work | Functional style; first-class TPU support | Smaller community; mostly subset of transformers |
| spaCy + spacy-transformers | NLP pipelines | Production-grade NLP for traditional tasks | Narrower scope; wraps transformers rather than replacing it |
Strengths
- The single largest catalog of pretrained model code and weights, with new state-of-the-art models often supported within days of release.
- Standardized API across very different architectures, which makes swapping models a one-line change.
- Permissive Apache 2.0 license.
- Active development: typically a release every few weeks, frequent bug fixes, transparent design discussions on GitHub.[7]
- High-quality documentation, course material, and a large community of contributors.[3]
- Tight integration with the rest of the open-source ML stack, from training (Accelerate, DeepSpeed, FSDP, PEFT) to inference (vLLM, TGI, llama.cpp, MLX) to evaluation (
evaluate,lm-evaluation-harness). - Reproducibility: model definitions track the original papers closely, so loading a checkpoint usually gives results within rounding error of the source.
Limitations
- For high-throughput LLM serving,
transformersis slower than purpose-built servers. Production teams generally pair the library with vLLM or TGI rather than serving it directly. - The genericity that makes the library easy to use also imposes some memory and latency overhead, especially for very small models or very large batch sizes.
- Major version transitions (3.x to 4.x in 2020, 4.x to 5.x in 2025-2026) have introduced breaking changes that downstream code needs to track.
- TensorFlow and Flax coverage was dropped in the v5 line; new architectures ship PyTorch-only.
- CPU inference works but is much slower than what a quantized
llama.cppbuild can do for the same model. - Some custom architectures (especially research models with non-standard layers) require
trust_remote_code=True, which carries a security implication users sometimes overlook.
Hugging Face the company
Hugging Face was founded in 2016 in New York by Clément Delangue (CEO), Julien Chaumond (CTO), and Thomas Wolf (CSO). All three are French.[15] The original product was a chatbot app aimed at teenagers; the company name and the hugging-face emoji come from that era. After releasing the chatbot's models as open source in 2017, the team noticed that the open-source release was getting more attention than the app itself.[15] The November 2018 release of pytorch-pretrained-bert accelerated that pivot.[16] By 2019 the company had effectively repositioned itself as an ML platform built around the library and what would become the Hugging Face Hub.
Key corporate milestones:
- 2019: $15M Series A.
- 2021: $40M Series B; acquired Gradio (December 2021).
- 2022: $100M Series C at a $2B valuation; BigScience, the open research collaboration Hugging Face launched in April 2021, released BLOOM.
- August 2023: $235M Series D led by Salesforce, with participation from Google, Amazon, NVIDIA, Intel, AMD, IBM, Qualcomm, and Sound Ventures, at a $4.5B valuation.[14]
- June 2024: acquired Argilla (a data-labeling and dataset-quality startup) for around $10M.[13]
- August 2024: acquired XetHub, the basis of the Xet storage backend now used for Hub repos.[21]
- April 2025: acquired Pollen Robotics, the French maker of the open-source Reachy 2 humanoid robot.[12]
- 2025-2026: continued growth of the Hub past 2 million models and 13 million users.[11]
- September 2026: agreed to be acquired by NVIDIA for about $12.9 billion.[22]
The company's strategic position is unusual: it does not train its own frontier models and does not sell a closed model API at the scale of OpenAI or Anthropic. Instead it monetizes the Hub through enterprise plans, hosted inference, training credits, and consulting. The transformers library is the gravitational center that makes everything else possible.
Recent context (2024 to 2026)
A few threads stand out in the last two years.
- Agentic features: the
smolagentslibrary, which replaced the oldertransformers.agentsmodule, supports tool-using LLMs, including code agents that write and execute Python. - Edge and on-device: tighter integration with MLX (Apple Silicon),
llama.cpp(GGUF interoperability), and ONNX Runtime Web has pushed the library toward laptops, phones, and browsers. - Inference Providers: a Hub-level feature that routes inference requests to third-party serving partners like Together AI, Replicate, Fireworks, and Groq, through the
huggingface_hubInferenceClient or OpenAI-compatible APIs.[24] - Multimodal everywhere: vision-language models (LLaVA, Idefics, Qwen-VL, PaliGemma, Llama 3.2 Vision) and audio-language models (Whisper, SeamlessM4T) are now first-class citizens, not bolt-ons.
- v5 release line: the 5.x line, whose first release candidate landed on December 1, 2025 and which reached v5.12.1 by June 15, 2026, modernizes the codebase around PyTorch as the sole backend, removes long-deprecated TF and Flax helpers, formalizes attention backends, makes quantization a first-class feature, and reworks the chat-template and tool-calling layer.[17][18]
Continue reading
- TransformersA Transformer is a deep learning architecture, introduced by eight Google researchers in the 2017 paper "Attention Is All You Need", that uses attention as the sole mechanism for modeling relationships between…Mentioned 42 times above
- Hugging FaceHugging Face is an artificial intelligence company and collaboration platform for machine learning.Mentioned 30 times above
- llama.cppllama.cpp is an open-source large language model inference engine written in C and C++ by Bulgarian software engineer Georgi Gerganov that runs large language models on consumer-grade hardware without…Mentioned 9 times above
- QwenQwen is a family of large language models and multimodal models developed by the Qwen Team at Alibaba Cloud.Mentioned 4 times above
- PEFTParameter-efficient fine-tuning (PEFT) is a family of methods that adapt a pre-trained large language model to a downstream task by updating only a small fraction of its parametersMentioned 4 times above
- GPT-2GPT-2 is a family of autoregressive language models introduced by OpenAI on February 14, 2019.Mentioned 3 times above
More to read
References
- ^1 ^2 ^3Wolf, T., Debut, L., Sanh, V., Chaumond, J., Delangue, C., Moi, A., Cistac, P., Rault, T., Louf, R., Funtowicz, M., Davison, J., Shleifer, S., von Platen, P., Ma, C., Jernite, Y., Plu, J., Xu, C., Le Scao, T., Gugger, S., Drame, M., Lhoest, Q., Rush, A. M. (2020). Transformers: State-of-the-Art Natural Language Processing. *Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations*, pp. 38-45. aclanthology.org/2020.emnlp-demos.6
- ^Wolf, T. et al. (2019). HuggingFace's Transformers: State-of-the-art Natural Language Processing. arXiv:1910.03771. arxiv.org/...1910.03771
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Hugging Face. Transformers documentation. huggingface.co/...transformers
- ^1 ^2Hugging Face. Pipelines documentation. huggingface.co/...pipelines
- ^Hugging Face. Quantization overview. huggingface.co/...overview
- ^1 ^2 ^3Hugging Face. Hub documentation. huggingface.co/...index
- ^1 ^2 ^3 ^4huggingface/transformers GitHub repository. github.com/...transformers
- ^1 ^2Hugging Face. PEFT documentation. huggingface.co/...index
- ^Hugging Face. Accelerate documentation. huggingface.co/...index
- ^1 ^2Hugging Face. TRL documentation. huggingface.co/...index
- ^1 ^2 ^3 ^4Hugging Face. State of Open Source on Hugging Face: Spring 2026. huggingface.co/...state-of-os-hf-spring-2026
- ^1 ^2Hugging Face. Hugging Face to sell open-source robots thanks to Pollen Robotics acquisition (April 2025). huggingface.co/...face-pollen-robotics-acquisition
- ^Argilla. Argilla is joining Hugging Face (June 2024). argilla.io/...argilla-joins-hugggingface
- ^1 ^2TechCrunch. Hugging Face raises $235M from investors, including Salesforce and NVIDIA (August 2023). techcrunch.com/...-including-salesforce-and-nvidia
- ^1 ^2 ^3 ^4 ^5Wikipedia. Hugging Face. en.wikipedia.org/...Hugging_Face
- ^1 ^2 ^3Synced. Hugging Face Releases PyTorch BERT Pretrained Models and More (February 2019). syncedreview.com/...t-pretrained-models-and-more-2
- ^1 ^2 ^3 ^4PyPI. transformers. pypi.org/...transformers
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Hugging Face. Transformers v5: Simple model definitions powering the AI ecosystem (December 2025). huggingface.co/...transformers-v5
- ^1 ^2OpenAlex. Transformers: State-of-the-Art Natural Language Processing (citation record). api.openalex.org/...2020.emnlp-demos.6
- ^1 ^2Hugging Face. Xet storage backend documentation. huggingface.co/...index
- ^1 ^2 ^3Hugging Face. XetHub is joining Hugging Face! (August 2024). huggingface.co/...xethub-joins-hf
- ^1 ^2Semafor. Nvidia to buy Hugging Face for nearly $13 billion (September 2026). semafor.com/...-hugging-face-for-nearly-13-billion
- ^1 ^2 ^3huggingface/transformers release notes (v2.9.0, v3.0.0, v4.0.0, v4.3.0, v4.6.0, v4.23.0). github.com/...releases
- ^Hugging Face. Inference Providers documentation. huggingface.co/...index
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
10 revisions · v10 · 4,280 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (130 claims, 36 sources fetched); 9 material + 22 minor fixed
Cite this page: AI Wiki. "Hugging Face Transformers." aiwiki.ai, updated 21 Jun 2026, fact-checked 1 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/transformers_library