

Titans (neural architecture)
Titans is a family of neural sequence-modeling architectures from Google Research that combines an attention-based "short-term memory" with a deep neural "long-term memory" module that updates its own parameters at test time using online gradient descent on a "surprise" signal. Introduced by Ali Behrouz, Peilin Zhong, and Vahab Mirrokni in the paper "Titans: Learning to Memorize at Test Time" (arXiv:2501.00663, submitted 31 December 2024)[1][2], the design is motivated by the limitations of standard Transformer models on extremely long contexts and by the lossy fixed-size state of modern linear recurrent baselines such as Mamba and Mamba 2. Titans treats the parameters of a small multi-layer perceptron as a writable long-term memory that is overwritten as tokens stream in, with a momentum term, a learned decay (forget) gate, and an associative key-value loss. The paper proposes three variants that differ in how the neural memory is wired to attention: Memory-as-Context (MAC), Memory-as-Gate (MAG), and Memory-as-Layer (MAL)[1][3]. A version of the paper was published at NeurIPS 2025[10], and the same group has since extended the line of work with the MIRAS framework, the ATLAS memory module, and the Nested Learning paradigm with its Titans-derived Hope architecture[6][11][12].
Background and motivation
Two families of sequence models dominated language modeling in the years leading up to Titans. Decoder-only Transformers using softmax attention obtain strong accuracy and recall but pay quadratic time and memory in the sequence length, which limits feasible context windows in training[1]. A second family of modern linear recurrent models, including Mamba, Mamba 2, RetNet, Linear Attention variants, and RWKV, achieves linear-time training and constant-memory inference by compressing the past into a fixed-size hidden state[1]. The Titans authors argue that this compression is the family's weakness: "a very long context cannot be properly compressed in a small vector-valued or matrix-valued states"[1].
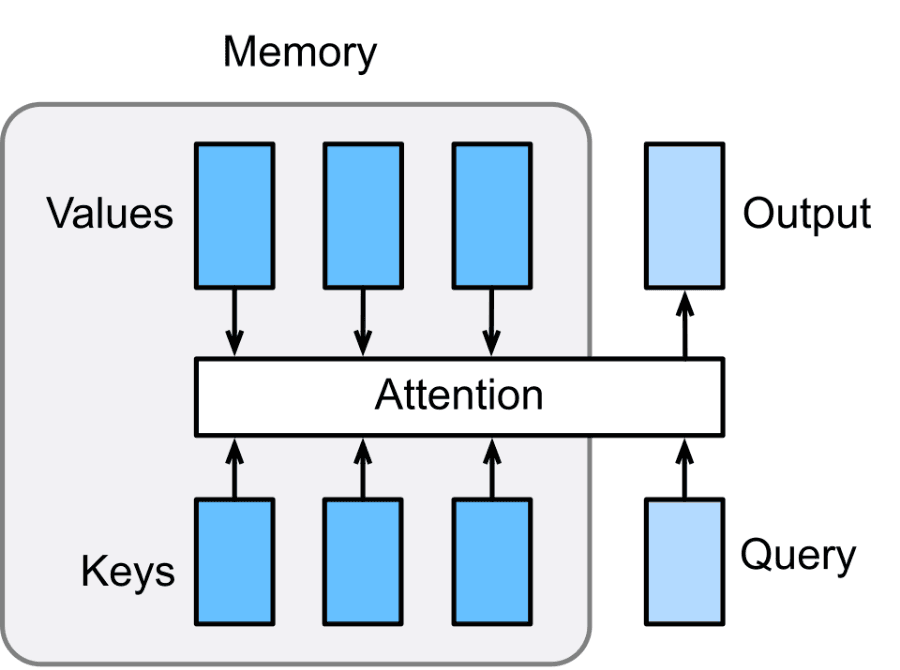
Behrouz, Zhong, and Mirrokni framed this as a memory problem rather than an architecture problem[1][2]. Their thesis is that attention behaves like a precise but short-horizon memory, modern linear recurrences provide an efficient but lossy summary, and what is missing is an explicit long-term memory that can be written to during inference and read from again later[1][2]. The Titans paper formulates that long-term memory as a neural network whose parameters are themselves the storage medium, with writes implemented by gradient updates on an internal loss[1]. This connects Titans to a thread of work on test-time learning, including Test-Time Training[5] and earlier "fast weights" ideas, and to the wider meta-learning view that an inner optimization loop can serve as a memory mechanism[1][2].
The paper was first posted to arXiv on 31 December 2024 and has only one arXiv version (v1) as of October 2026[1]. A version was presented as a poster at NeurIPS 2025; the abstract on the NeurIPS page is worded more cautiously than the arXiv abstract, saying Titans "are effective compared to baselines" and "can effectively scale to larger context window in needle-in-haystack tasks", without the arXiv abstract's "larger than 2M" figure[1][10]. A companion overview, "Titans + MIRAS: Helping AI have long-term memory", appeared on the Google Research blog on 4 December 2025[2]. The same team generalized the framework in April 2025 with MIRAS, a design space defined by four choices (memory architecture, "attentional bias", "retention gate", and memory learning algorithm), of which Titans is one instance[2][6].
How the long-term memory module works
The core component of Titans is the neural long-term memory module, abbreviated LMM in the paper[1]. The module is not a static buffer or a fixed-size hidden state; it is a small multi-layer perceptron whose weights M_t are updated as the model consumes tokens. Reads and writes happen during the forward pass, so what is stored depends on the current input rather than being fixed after training; the paper calls it a "contextual memory" whose output "is fully depend[ent] on the context"[1].
Associative key-value loss
For each incoming token x_t, two learned linear projections produce a key k_t = x_t W_K and a value v_t = x_t W_V[1]. The memory M_{t-1} is treated as a function from keys to predicted values, and the internal loss is the squared error of the prediction:
l(M_{t-1}; x_t) = || M_{t-1}(k_t) - v_t ||_2^2
Minimizing this loss makes the memory store the association k_t -> v_t, so that the same key presented later produces the same value[1]. Training of the memory happens in the inner loop: the memory's weights are optimized in the inner loop, while W_K, W_V and the rest of the architecture are optimized in the outer training loop[1]. Reading uses a third projection q_t = x_t W_Q and a forward pass through the memory without a weight update, y_t = M*(q_t)[1].
Surprise, momentum, and decay
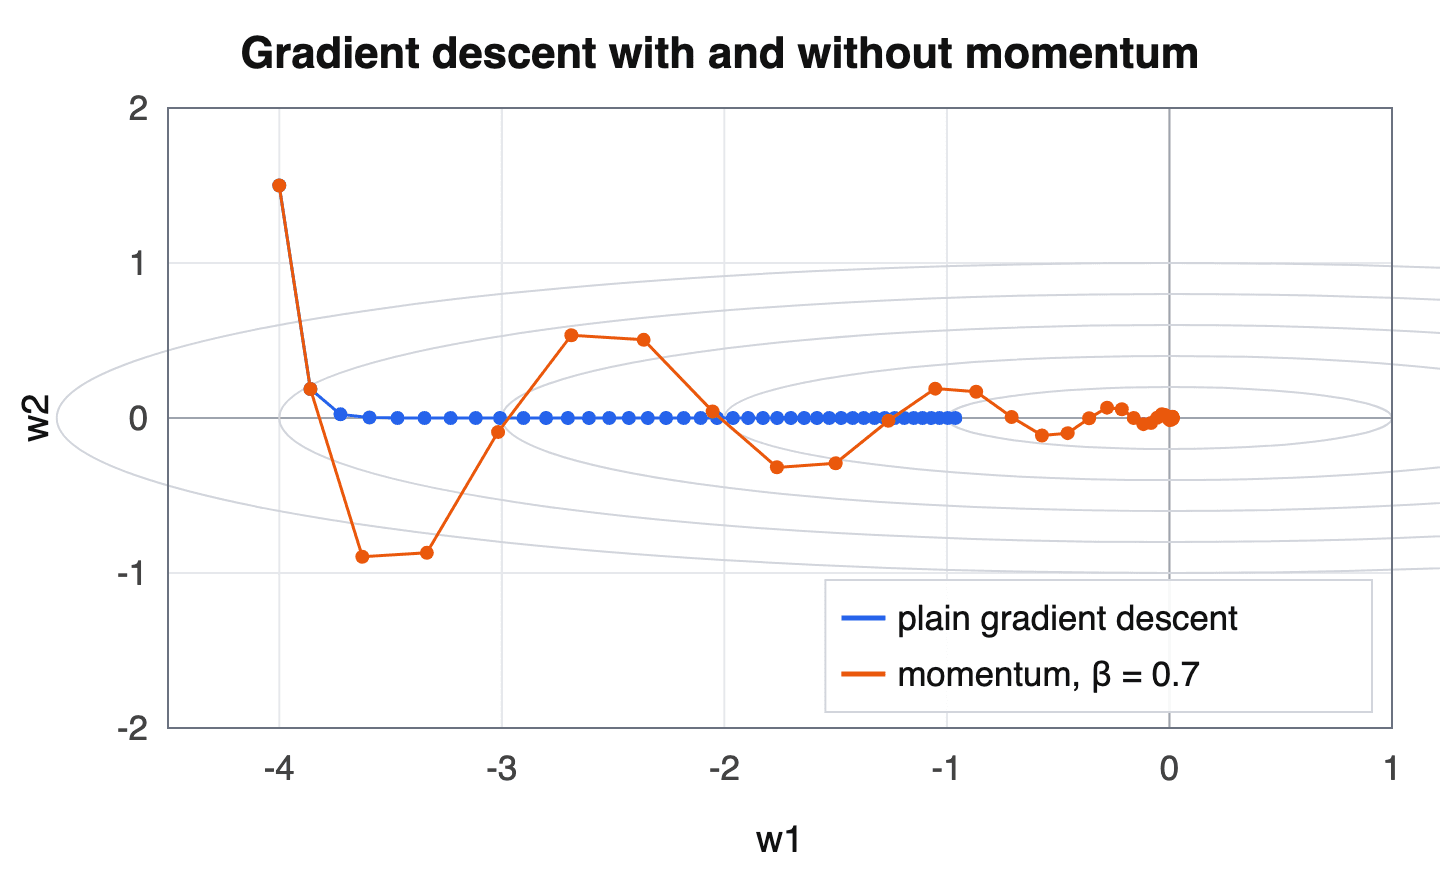
The paper's starting point is a single gradient step per token, M_t = M_{t-1} - theta_t * grad l(M_{t-1}; x_t), where the gradient term is labeled "surprise"[1]. In the prose the authors describe surprise as the model's "gradient with respect to the input"; in the equations it is the gradient of the associative loss with respect to the memory's parameters[1]. Because a single large surprise can be followed by many small gradients, Titans splits surprise into "past surprise" and "momentary surprise" with a momentum-style state S_t, a data-dependent surprise decay eta_t, and a data-dependent scale theta_t[1][2]:
S_t = eta_t * S_{t-1} - theta_t * grad l(M_{t-1}; x_t)
The memory itself then evolves with a gate alpha_t in [0,1] that the paper calls a forgetting mechanism and shows to be equivalent to weight decay[1]:
M_t = (1 - alpha_t) * M_{t-1} + S_t
The first term implements a soft erase that lets the model release capacity when long sequences would otherwise saturate the parameters[1]. The second term injects the accumulated, momentum-smoothed surprise into the parameters. With alpha_t -> 1 the memory is cleared; with alpha_t -> 0 the update leaves the past abstraction untouched[1]. A data-dependent eta_t lets the model either ignore the last surprise (eta_t -> 0, for example at a change of context) or fully carry it forward (eta_t -> 1)[1]. The paper draws an explicit analogy to human memory: events that violate expectations are more memorable, and the momentum term keeps the tokens that follow a surprising event in memory even when they are not individually surprising[1][2].
Parallel training
The authors show that this update is equivalent to training the memory with mini-batch gradient descent, momentum, and weight decay, and that it can be reformulated to use mostly matrix multiplications[1]. Building on the tensorized mini-batch gradient descent of the TTT layer paper[5], they split the sequence into chunks of size b, compute the gradients inside a chunk with respect to the memory state at the start of the chunk, and evaluate the momentum recurrence S_t = eta_t S_{t-1} - theta_t u_t with a parallel associative scan[1]. They note that making alpha, theta and eta constant within each chunk would allow an even faster global-convolution form, but in their experiments these parameters are functions of individual tokens[1].
Deep MLP memory
The paper argues that a matrix-valued memory M = W reduces the inner problem to online linear regression, which assumes the dependencies in the history are linear, and uses MLPs with L_M >= 1 layers instead[1]. DeltaNet and Gated DeltaNet use a matrix-valued state with a delta-rule update; the TTT paper's TTT-Linear and TTT-MLP layers use a linear model and a two-layer MLP as the hidden state[1][5]. The Titans authors say TTT layers allow deeper memory but that "the advantages/disadvantages of such deeper memory modules have not been experimentally evaluated", and they run that evaluation themselves[1]. In experiments on a subset of the Pile with L_M from 1 to 4 at three model sizes, deeper memory gave better perplexity at all sequence lengths tested, while training throughput fell roughly linearly as depth increased; the authors conclude that "it is not always efficient to use deeper memory modules"[1].
Persistent memory
Titans also includes persistent memory, a set of N_p learnable but input-independent parameters prepended to every input sequence[1]. The paper motivates it three ways: as task knowledge that should not depend on the input, as an analogue of the data-independent feedforward weights of a Transformer, and as a fix for the bias of causal attention toward the first tokens of a sequence[1]. The three components together (an attention "core", the neural long-term memory, and persistent memory) form what the paper calls Titans' "three hyper-heads"[1].
Architectural details
In all blocks the paper uses residual connections, SiLU activations for computing queries, keys and values, and ℓ2 normalization of queries and keys[1]. Following recent linear recurrent models, it adds a 1D depthwise-separable convolution after each of the query, key and value projections, and uses normalization and gating with a linear layer before the final output projection[1]. The paper also states a theoretical result (Theorem 4.1): unlike Transformers, diagonal linear recurrent models and DeltaNet, which are limited to the complexity class TC^0, Titans "are capable of solving problems beyond TC^0", which the authors read as greater expressiveness in state-tracking tasks[1].
Architectural variants
The Titans paper proposes three ways to couple the long-term memory module to attention, and reports experiments on all three plus the memory module alone, called Titans (LMM)[1]. The variants differ in where the memory output enters the computation graph relative to the attention layers.
Memory-as-Context (MAC)
In MAC, the input is split into fixed-size segments. Before processing a new segment with attention, the model queries the long-term memory with the segment, retrieves the corresponding historical information h_t, and prepends it, together with the persistent memory tokens, to the segment[1]. Full causal attention then runs over the concatenation [persistent, h_t, segment][1][3]. The attention output y_t is used to update the long-term memory for the next segment, and the final output combines y_t with a read from the updated memory[1]. The authors list as advantages that attention can decide whether long-term information is needed for the current data, and that attention helps the memory store only useful information from the segment instead of every token[1]. They also describe MAC as a generalization of the Recurrent Memory Transformer, with a neural memory in place of a small vector-valued memory[1].
MAC is the variant the paper reports as strongest on long-range dependencies: in the needle-in-a-haystack tests "the best results correspond to MAC", and MAC is the variant fine-tuned for BABILong[1].
Memory-as-Gate (MAG)
MAG runs two branches. One is a sliding window attention over the input with the persistent memory tokens as a prefix; the other is the neural long-term memory, which is updated directly from the input. Unlike MAC, the input is not segmented[1]. The two outputs are combined by a non-linear gate; in the experiments the outputs are normalized with learnable vector-valued weights and passed through a non-linearity[1]. The paper describes the sliding window attention as "a precise short-term memory" and the neural memory as "a fading memory", and notes that the design can be viewed as a multi-head architecture in which the heads have different structures, citing the Hymba hybrid model[1].
Memory-as-Layer (MAL)
MAL is the simplest variant. The neural memory module is a layer of its own, applied to the input (with persistent tokens prepended) before a sliding window attention layer; for the experiments the authors use an H3-like block with the sequence model replaced by the neural memory[1]. The paper notes that this sequential, layer-wise design is the one most common in the hybrid literature, and that its drawback is that the model "cannot take advantage of the complementary data processing of attention and neural memory module"[1]. In the paper's experiments MAL was trained faster than the baselines, which the authors attribute to FlashAttention kernels used for the sliding window attention, and the authors write that both MAC and MAG perform better than MAL. In the ablation table, however, MAL is below both only on reasoning accuracy: its perplexity (25.91) is better than MAC's (26.67), and its long-context accuracy (96.91) is slightly above MAG's (96.70)[1].
Comparison of the three variants
| Variant | Memory placement | Attention type used | Reported strength |
|---|---|---|---|
| MAC | Retrieved memory prepended to each segment | Full causal attention over [persistent, retrieved, segment] | Best long-context results per the authors (S-NIAH; the only variant run on BABILong), though MAG scores higher on S-NIAH-N at 16K[1] |
| MAG | Parallel branch combined via a non-linear gate | Sliding window with persistent-token prefix | Close to MAC on language modeling and reasoning; lowest WikiText perplexity at 400M and 760M parameters[1] |
| MAL | Memory layer before attention | Sliding window | Fastest training in the efficiency study; lowest reasoning accuracy of the three in the ablation, which the authors summarize as below MAC and MAG[1] |
Experiments
Titans is evaluated on language modeling, common-sense reasoning, needle-in-a-haystack retrieval, the BABILong long-context reasoning benchmark, time-series forecasting, and DNA modeling[1]. The results below are the authors' own; the paper's footnote says that the first version aims "to provide insights/evidences" and that the authors were "working on finalizing the results of larger models"[1].
Scales and training setup
The paper considers four scales, 170M, 340M, 400M, and 760M parameters. The first three are trained on 15B tokens sampled from FineWeb-Edu, and the 760M models on 30B tokens[1]. Training follows the Gated DeltaNet recipe: the Llama 2 tokenizer with a 32K vocabulary, a 4K-token training length, AdamW with a learning rate of 4e-4, a cosine annealing schedule, a batch size of 0.5M tokens, and weight decay of 0.1[1]. The language-modeling baselines are Transformer++, RetNet, Gated Linear Attention, Mamba, Mamba 2, DeltaNet, TTT, and Gated DeltaNet, plus the hybrids Samba and Gated DeltaNet-H2; the 400M baseline numbers are taken from the Gated DeltaNet paper[1].
The largest model in the arXiv preprint is 760M parameters. The NeurIPS 2025 version adds a fifth scale, 1.3B parameters trained on 100B tokens, and reports only Titans (LMM) at that size: WikiText perplexity 15.60 and average common-sense accuracy 56.82, against 15.91 and 56.18 for Gated DeltaNet-H2 and 16.42 and 55.32 for Gated DeltaNet[17]. The same 1.3B Titans (LMM) numbers appear as a baseline in the group's ATLAS paper[11].
Language modeling and common-sense reasoning
In the paper's Table 1, a Titans variant has the lowest WikiText perplexity and the highest average accuracy at each of the three reported scales[1]. At 340M parameters, Titans (MAG) reaches a WikiText perplexity of 25.07 against 27.01 for Gated DeltaNet and 31.52 for Transformer++; at 760M, Titans (MAC) reaches 19.93 and Titans (MAG) 18.61, against 21.18 for Gated DeltaNet and 19.88 for the Gated DeltaNet-H2 hybrid[1]. The results are not uniform: at 400M, Titans (MAC) has a WikiText perplexity of 25.61, behind Samba (25.32) and Gated DeltaNet-H2 (24.19)[1].
| Model (760M params, 30B tokens) | WikiText ppl (lower is better) | LAMBADA ppl | Average accuracy |
|---|---|---|---|
| Transformer++ | 25.21 | 27.64 | 48.69 |
| Mamba 2 | 22.94 | 28.37 | 48.34 |
| Gated DeltaNet | 21.18 | 22.09 | 49.69 |
| Samba (hybrid) | 20.63 | 22.71 | 51.08 |
| Gated DeltaNet-H2 (hybrid) | 19.88 | 20.83 | 51.49 |
| Titans (LMM) | 20.04 | 21.96 | 51.56 |
| Titans (MAC) | 19.93 | 20.12 | 52.51 |
| Titans (MAG) | 18.61 | 19.86 | 52.50 |
| Titans (MAL) | 19.07 | 20.33 | 50.97 (52.29 in the NeurIPS 2025 version, where the row's SIQA score of 30.98 becomes 40.57) |
The average is over LAMBADA accuracy, PIQA, HellaSwag, WinoGrande, ARC-Easy, ARC-Challenge, SIQA, and BoolQ[1]. Among non-hybrid models, the authors report that the memory module alone outperforms all baselines including Transformer++, and that all three hybrid Titans variants outperform Samba and Gated DeltaNet-H2[1]. They attribute the gap to TTT, the other gradient-based recurrent model, to weight decay and momentum[1].
Ablations
The ablation table removes one component at a time from the memory module (the model scale is not stated in the table)[1]:
| Configuration | Perplexity | Reasoning accuracy | Long-context accuracy |
|---|---|---|---|
| LMM (full memory module) | 27.01 | 47.83 | 92.68 |
| + attention (MAC) | 26.67 | 48.65 | 97.95 |
| + attention (MAG) | 25.70 | 48.60 | 96.70 |
| + attention (MAL) | 25.91 | 47.87 | 96.91 |
| Linear memory | 28.49 | 46.97 | 85.34 |
| Without convolution | 28.73 | 45.82 | 90.28 |
| Without momentum | 28.98 | 45.49 | 87.12 |
| Without weight decay | 29.04 | 45.11 | 85.60 |
| Without persistent memory | 27.63 | 46.35 | 92.49 |
The authors state that all components contribute, "where the greatest contribution comes from weight decay, momentum, convolution, and persistent memory, respectively"[1].
Needle-in-a-haystack retrieval
On the single-needle (S-NIAH) tasks of the RULER benchmark, which test Needle in a Haystack retrieval with a pass-key (PK), a number (N), or a word (W) as the needle, models are evaluated at 2K, 4K, 8K, and 16K tokens[1]. At 16K on S-NIAH-PK, Titans (LMM) scores 96.2 percent, compared with 88.4 for TTT, 71.4 for DeltaNet, and 5.4 for Mamba 2[1]. The harder word-needle task separates the models more sharply:
| Model | S-NIAH-PK 16K | S-NIAH-N 16K | S-NIAH-W 16K |
|---|---|---|---|
| TTT | 88.4 | 4.4 | 0.0 |
| Mamba 2 | 5.4 | 0.0 | 0.0 |
| DeltaNet | 71.4 | 5.4 | 0.0 |
| Titans (LMM) | 96.2 | 80.2 | 80.6 |
| Titans (MAC) | 98.4 | 97.4 | 95.2 |
| Titans (MAG) | 97.4 | 98.6 | 88.2 |
| Titans (MAL) | 97.8 | 96.4 | 90.4 |
The authors attribute the memory module's stability, relative to TTT, to momentum and the forgetting mechanism; relative to Mamba 2, to deep non-linear memory; and relative to DeltaNet, to the ability to erase memory[1].
BABILong and the "2M context" claim
BABILong is a long-context benchmark in which the model must reason over facts scattered through very long documents[1]. The paper reports two settings. In the few-shot setting, Titans (MAC) is compared with Mamba 2.8B, RWKV-6-7B, RecurrentGemma-9B, Gemma-9B, Llama 3.1 8B, GPT-4, and GPT-4o-mini, and the authors report that it outperforms all of them "while Titans (MAC) is having much less number of parameters than baselines"[1]. In the fine-tuning setting, a small fine-tuned Titans (MAC) is compared with fine-tuned Mamba and RMT, Llama 3.1 8B with retrieval-augmented generation, and GPT-4, GPT-4o-mini, Qwen2.5-72B, and Llama 3.1 70B, with baseline numbers taken from the BABILong authors[1]. The paper states that "augmenting Llama3.1-8B model with RAG performs worse than Titans with about ×70 less parameters"[1]. In the fine-tuning plot the Titans (MAC) curve stays above the baselines across the plotted range, which extends to about 10^7 tokens, with accuracy declining at the longest lengths[1].
The headline claim appears in the arXiv abstract as "They further can effectively scale to larger than 2M context window size with higher accuracy in needle-in-haystack tasks compared to baselines", and in the conclusion as "Titans can scale to larger than 2M context window size with better accuracy than baselines"[1]. The Google Research blog repeats it as "Titans further demonstrates the capability to scale effectively to context window sizes larger than 2 million tokens"[2]. The NeurIPS 2025 version drops the 2M figure from both its abstract and its conclusion[10][17]. Its BABILong appendix notes that the very large baselines (Llama, Qwen, GPT-4) were run zero-shot while Titans was fine-tuned, and acknowledges that other architectures, such as the associative recurrent memory transformer ARMT, report better BABILong results than Titans[17]. In the later ATLAS paper, the same group reports that on BABILong, ATLAS is on par with Titans up to 1M tokens but that "the performance of Titans drops in 10M"[11].
Time series and DNA
The paper also applies the memory module outside language. For long-term time-series forecasting it replaces the Mamba module of the Simba framework with the neural memory and reports that it outperforms Simba, iTransformer, RLinear, PatchTST, Crossformer, TiDE, TimesNet, and DLinear on ETT, ECL, Traffic, and Weather; in the paper's table it has the lowest mean squared error on all seven dataset splits, though not the lowest mean absolute error on Traffic[1]. On the GenomicsBenchmarks DNA classification tasks, the authors describe the memory module as "competitive with state-of-the-art architectures", with the highest accuracy on two of the five tasks (the two enhancer datasets) in a comparison that included HyenaDNA, Transformer++, Mamba, and Based[1].
Efficiency
In the throughput comparison, the neural memory module is "slightly slower than Mamba2 and Gated DeltaNet", which the authors attribute to the deep memory with a more expressive update and to the highly optimized Mamba 2 kernel[1]. Titans (MAL) is faster than the baselines and the memory module alone because it uses FlashAttention for its attention layers[1]. Separately, all memory depths scale linearly with context length, with deeper memory training more slowly[1].
Position within related work
The Titans paper places its own contribution in the context of three overlapping research threads.
Modern linear recurrent and state space models
State space models such as S4 and Mamba, gated linear attentions, DeltaNet and Gated DeltaNet, and the broader family that includes RetNet and RWKV share an architectural pattern: compress the past into a hidden state of fixed size and update that state with a recurrence that admits fast parallel training[1]. The Titans appendix argues that the memory module generalizes Gated DeltaNet in three ways: a momentum-based rule that considers past as well as momentary surprise, deep (non-matrix) memory, and non-linear recurrence across chunks with linear recurrence inside a chunk; with eta_t = 0 and a linear memory the two update rules coincide[1]. It makes a similar argument for Longhorn, which lacks a forget gate[1]. The MIRAS follow-up recasts many members of the recurrent family as different choices of memory architecture, attentional bias, retention gate, and learning algorithm, with Titans' memory as one configuration[2][6].
Test-time training and fast weights
Titans is closely related to Test-Time Training (TTT) layers, whose hidden state is itself a model trained by a self-supervised gradient step on each test sequence[5]. The Titans authors call their module a generalized TTT layer and list three differences: a forgetting mechanism equivalent to weight decay, a momentum-based update instead of purely momentary surprise, and an experimental study of deeper memory[1]. Both belong to the broader test-time training literature, which updates parameters on test inputs; that article covers the TTT layer line in detail. The paper also traces the key-value memory view of linear layers to fast weight programs and describes most of that literature as relying on momentary surprise and lacking a forgetting gate[1].
Attention and hybrid architectures
The "core" branch of every Titans hybrid variant is softmax attention: full causal attention within segments for MAC and sliding window attention for MAG and MAL[1]. The paper positions Titans not as a replacement for the Transformer but as a way to give attention a separate, writable long-term memory that it can be conditioned on (MAC), fused with through a gate (MAG), or stacked with (MAL)[1]. It notes that existing hybrids such as Griffin, Samba, H3, and the hybrid versions of DeltaNet, Gated DeltaNet, and Mamba 2 all use a sequential layer-wise design, and that apart from Hymba, current hybrid models use the MAL-style combination[1].
Comparison table
| Family | Representative model | State / memory | Long-context behavior |
|---|---|---|---|
| Attention | Transformer | Full key-value cache | Strong recall, quadratic cost[1] |
| State space | Mamba, Mamba 2 | Fixed-size state with gating | Linear cost; Mamba 2 falls to 5.4% on S-NIAH-PK at 16K in the Titans tests[1] |
| Linear attention / delta rule | RetNet, DeltaNet, Gated DeltaNet | Matrix-valued state | Linear cost, lossy compression of long history[1] |
| Test-time trained | TTT-Linear, TTT-MLP[5] | Linear model or two-layer MLP updated by gradient steps | No forget gate or momentum, per the Titans authors[1] |
| Online deep memory | Titans (this article) | Deep MLP updated with momentum and weight decay | Linear-cost memory; strongest S-NIAH and BABILong results in the paper's own tests[1] |
Implementations and follow-up work
Code availability
The Titans paper states that "Titans are implemented in Pytorch and JAX and we intend to make the code we used to train and evaluate our models available soon"[1]. In October 2025 the authors of an independent reimplementation still described "the lack of publicly available code and ambiguities in the original description" as obstacles to reproduction[14].
The most-starred community port is titans-pytorch, an unofficial PyTorch implementation by Phil Wang (lucidrains) released under the MIT license[8]. The repository was created on 8 January 2025, eight days after the arXiv posting, and had about 2,000 GitHub stars and 210 forks as of 31 October 2026[8]. It provides a standalone NeuralMemory module and a MemoryAsContextTransformer class for the MAC variant, with configurable segment length, number of persistent-memory tokens (4 in the README example), and number of long-term memory tokens, and it describes itself as also exploring memory architectures "beyond their simple 1-4 layer MLP"[8].
Independent reimplementation and critique
"Titans Revisited: A Lightweight Reimplementation and Critical Analysis of a Test-Time Memory Model" (Gavriel Di Nepi, Federico Siciliano, and Fabrizio Silvestri, Sapienza University of Rome; arXiv:2510.09551, 10 October 2025) rebuilt the MAC variant and a memory-only variant and evaluated them on masked language modeling, time-series forecasting, and recommendation[14]. The authors list details they found under-specified in the original paper, including whether predictions come from only the last chunk or all chunks, how outputs are reduced after concatenating memory and persistent tokens, whether a MAC block is a shallow encoder or a stackable layer, and the internal attention configuration[14]. They report that "Titans does not always outperform established baselines due to chunking", that the neural memory "consistently improves performance compared to attention-only models", that larger chunks improve accuracy at a substantial compute cost, and that "memory updates alone proved insufficient for meaningful test-time learning when the backbone is frozen"[14].
Retrofitting pretrained models
"TPTT: Transforming Pretrained Transformers into Titans" (Fabien Furfaro, arXiv:2506.17671, June 2025) is a framework that augments pretrained Transformers with linearized attention and internal memory gating through a Memory-as-Gate design, using parameter-efficient LoRA fine-tuning rather than full retraining[9]. It was tested on models of roughly 1B parameters such as Llama-1B, OLMoE-1B-7B, and Qwen2.5-1.5B, mainly on MMLU; the author reports that Titans-Llama-1B showed "up to a 20% relative increase in Exact Match scores in one-shot evaluation" and calls the findings preliminary[9].
MIRAS (April 2025)
"It's All Connected: A Journey Through Test-Time Memorization, Attentional Bias, Retention, and Online Optimization" (Ali Behrouz, Meisam Razaviyayn, Peilin Zhong, Vahab Mirrokni; arXiv:2504.13173, 17 April 2025) reinterprets Transformers, Titans, and modern linear recurrent networks as associative memories that learn a key-value mapping under an internal objective the authors call attentional bias, and reinterprets forget gates as retention regularization[6]. The resulting framework, Miras (styled MIRAS on the Google blog), designs a sequence model by choosing an associative memory architecture, an attentional bias objective, a retention gate, and a memory learning algorithm[6]. It introduces three attention-free models: Moneta, Yaad, and Memora[6]. The Google blog describes Yaad as using a Huber loss to be less sensitive to outliers, Moneta as using generalized norms, and Memora as constraining its memory to act like a probability map[2]. The blog describes the relationship as "Titans is the specific architecture (the tool), and MIRAS is the theoretical framework (the blueprint) for generalizing these approaches"[2].
ATLAS (May 2025)
"ATLAS: Learning to Optimally Memorize the Context at Test Time" (Behrouz, Zeman Li, Praneeth Kacham, Majid Daliri, Yuan Deng, Peilin Zhong, Meisam Razaviyayn, Mirrokni; arXiv:2505.23735, 29 May 2025) targets what it calls the "online nature" of memories like Titans, which optimize the memory only with respect to the latest input[11]. It introduces the Omega rule, which updates the memory using a sliding window of past tokens; polynomial feature maps on keys and queries to raise memory capacity; and ATLAS, which uses the Muon optimizer to update its internal memory[11]. The paper also defines DeepTransformers, a family it describes as strict generalizations of the Transformer[11]. The authors report that ATLAS "further improves the long context performance of Titans, achieving +80% accuracy in 10M context length of BABILong benchmark", where Titans' accuracy drops[11].
Nested Learning and Hope (NeurIPS 2025)
Google Research introduced Nested Learning in a blog post on 7 November 2025, and the paper "Nested Learning: The Illusion of Deep Learning Architectures" (Behrouz, Razaviyayn, Zhong, Mirrokni) was posted to arXiv on 31 December 2025 as arXiv:2512.24695, with a version published at NeurIPS 2025[12][13]. The paradigm treats a model as a set of nested or parallel optimization problems, each with its own "context flow" and update frequency, and treats optimizers such as SGD with momentum and Adam as associative memories[12][13]. Its proof-of-concept architecture, Hope, is described by Google as "a variant of the Titans architecture"[13]. According to the blog, Titans has "only two levels of parameters update, resulting in a first-order in-context learning", while Hope is a self-modifying recurrent architecture augmented with "continuum memory system" blocks that update at different frequencies[13]. Google reports that Hope "demonstrates lower perplexity and higher accuracy compared to modern recurrent models and standard transformers" on language modeling and common-sense reasoning, in a comparison that included Titans, and stronger needle-in-a-haystack results in a comparison with Titans, TTT, and Mamba 2[13].
Later continual-learning work (2026)
In "Language Models Need Sleep: Learning to Self-Modify and Consolidate Memories" (arXiv:2606.03979, June 2026; a version was on OpenReview from September 2025), Behrouz, Farnoosh Hashemi, Adel Javanmard, and Mirrokni propose an offline "sleep" phase that distills short-term memories into long-term parameters[15]. Google's 27 October 2026 blog post on the work says it uses a Mixture of Experts and the Hope architecture, and reports BABILong results up to 10M tokens that outperform baselines including GPT-4 and Titans[16].
Limitations and open questions
Several limitations are noted by the authors or by independent work.
The deep neural memory costs more per token than a matrix-valued state. The memory module trains slightly slower than Mamba 2 and Gated DeltaNet, and deeper memory trains more slowly still, so the authors frame memory depth as a trade-off between effectiveness and efficiency[1]. Gains also vary by setting: Titans variants do not lead every metric at every scale in the paper's own tables, and the Titans Revisited reimplementation found that chunking can leave Titans behind established baselines[1][14]. Early press coverage noted that "the model's memory depth and scaling efficiency depend heavily on the task and dataset"[7].
The arXiv preprint reports models up to 760M parameters trained on 30B tokens. The NeurIPS 2025 version adds a 1.3B-parameter memory-only model trained on 100B tokens. Both are small compared with current frontier large language models[1][17]. Neither version shows whether the surprise-plus-decay mechanism keeps its advantage at tens of billions of parameters and trillions of training tokens.
As of October 2025, the Titans Revisited authors described reproduction as hampered by the lack of publicly available code and by under-specified details[14]. The NeurIPS 2025 version's reproducibility checklist says the authors "plan to provide data and code via Github after the paper is made publicly available online"[17]. As with other meta-learning systems, the memory's contents are encoded in the parameter vector of an MLP rather than in an explicit set of tokens, which makes them harder to inspect than a key-value cache.
The long-term memory is contextual: it is written from the current input, so it is not designed to accumulate knowledge across separate sessions the way an external retrieval store or an agent memory system does[1]. The group's later Nested Learning and "sleep" work is framed explicitly around continual learning, the problem of retaining new knowledge over time without catastrophic forgetting[13][16].
Connection to optimization and meta-learning
The Titans paper is explicit that the inner update rule for the memory is equivalent to mini-batch gradient descent with momentum and weight decay applied to the MLP parameters[1]. This identification has several practical consequences.
First, it lets the authors reuse parallelization tricks. Within a chunk the gradients can be computed against the memory state at the start of the chunk and written as matrix multiplications, and the momentum term becomes a linear recurrence with input-dependent transitions that a parallel associative scan can evaluate[1]. In the efficiency study this keeps the memory module's training throughput close to, though slightly below, Mamba 2 and Gated DeltaNet[1].
Second, the rule makes the memory's hyperparameters (the momentum coefficient eta_t, the step size theta_t, and the decay alpha_t) data-dependent functions of the input rather than fixed scalars, so the model decides per token how strongly to write and how quickly to forget[1]. In the ablation, removing weight decay raises perplexity from 27.01 to 29.04, the largest single drop among the removed components[1].
Third, framing the long-term memory as the output of an inner online learning process places Titans in the meta-learning tradition: the outer training loop optimizes the architecture and the projection matrices W_K, W_V, W_Q so that an inner gradient-descent-with-momentum-and-decay procedure produces a useful memory for downstream prediction[1][2][5]. The paper relates this view to earlier ideas including fast weight programs, learning to learn, and Test-Time Training[1][5]. MIRAS and Nested Learning later generalize the same view, the first by varying the inner objective and retention regularizer, the second by treating optimizers themselves as associative memories[6][12].
Persistent vs. dynamic memory taxonomy
The paper offers a three-way taxonomy of memory that is reused throughout the architecture descriptions[1][3].
The core attention acts as short-term memory, holding the current segment or window in full resolution but with strict capacity bounds set by the window length. The neural long-term memory is a contextual store: its parameters keep learning at test time and encode an abstraction of the past of the current input. The persistent memory consists of learnable parameters that are trained end-to-end and fixed at test time, functioning as task knowledge prepended to every input[1]. In the MAC description the paper sums up the split at test time: persistent memory parameters are fixed, attention weights act as in-context learners, and the long-term memory is still learning[1].
This decomposition lets each memory specialize: persistent memory holds task-level priors, the neural memory holds sequence-level facts and dependencies, and attention handles tight local interactions[1].
Implementation details and hyperparameters
The arXiv version of the paper documents several implementation choices that are not always reflected in summaries[1][3].
The outer training loop uses AdamW with a learning rate of 4e-4, cosine annealing, a 0.5M-token batch, and weight decay 0.1 on FineWeb-Edu[1]. Training contexts are 4K tokens. The S-NIAH evaluations run from 2K to 16K tokens, so their 8K and 16K results test lengths beyond the training context, while the BABILong experiments use a separate setup from the benchmark's authors, including fine-tuning[1].
Queries, keys, and values are computed with SiLU activations and the queries and keys are ℓ2-normalized[1]. The paper reports memory depth as a lever on both quality and speed, testing L_M from 1 to 4[1]. The persistent memory budget is a hyperparameter N_p; the public titans-pytorch example configuration uses four persistent tokens and sixteen long-term memory tokens[8].
The paper adds a 1D depthwise-separable convolution after each of the query, key, and value projections, following Mamba and Gated DeltaNet[1]. The text says these convolutions do "not significantly affect the performance", but in the ablation table removing them raises perplexity from 27.01 to 28.73 and lowers long-context accuracy from 92.68 to 90.28[1].
Reception and adoption
Press and explainer coverage appeared within weeks of the arXiv posting. A DataCamp explainer (24 January 2025) presented the design as a form of learning at inference time and emphasized the analogy to human memory, in which surprising events are stored more strongly[4]. The AI Insider (16 January 2025) repeated the paper's 2-million-token claim and noted that the generalizability of the memory system "across all AI applications remains an open question"[7]. Google's December 2025 blog post presented Titans together with MIRAS as work on "test-time memorization"[2].
Within research, Titans' memory module is used as a baseline or starting point in the group's own MIRAS, ATLAS, and Nested Learning papers[6][11][12], and outside the group in the Titans Revisited reimplementation and the TPTT retrofitting framework[9][14]. The release of the unofficial titans-pytorch port eight days after the arXiv posting let third parties experiment with the MAC variant without waiting for an official code release[8].
Significance
Titans gives a concrete, parallelizable instantiation of the idea that the parameters of a small neural network can serve as the long-term memory of a larger model, and that those parameters can be updated during inference using a structured online-learning rule[1][2]. By recasting the long-context problem as an online associative-memory problem, with surprise as the write signal and a learned forget gate as the retention mechanism, the paper set out a vocabulary (surprise, retention, persistent memory) that the subsequent MIRAS framework reuses to organize a much broader family of architectures[2][6].
The empirical case rests mainly on the authors' own experiments at up to 1.3B parameters (760M in the arXiv preprint), with long-context results most favorable on the BABILong and S-NIAH tasks[1]. Whether the design will displace standard attention at frontier scales is unsettled. Its influence is clearest in the follow-up line of work from the same group, which extends it with new objectives (MIRAS), context-window memory updates (ATLAS), and multi-frequency memories (Hope)[6][11][13], and in community ports such as titans-pytorch[8].
Continue reading
- AttentionAttention is a family of operations in neural networks that computes an output by assigning data-dependent weights to a collection of representations and combining them.Mentioned 43 times above
- MambaMamba is a neural network architecture for sequence modeling that uses selective state space models (SSMs) to process sequential data in linear time with respect to sequence lengthMentioned 24 times above
- Gated DeltaNetGated DeltaNet is a linear attention sequence model that augments the delta rule, a key-value error-correction update used in the earlier DeltaNet architectureMentioned 22 times above
- MomentumMomentum is an optimization technique that accelerates gradient descent by accumulating an exponentially weighted moving average of past gradients into a velocity vector and using that velocity, rather than…Mentioned 20 times above
- Mamba 2Mamba 2 is a state space model architecture introduced in the paper "Transformers are SSMs: Generalized Models and Efficient Algorithms Through Structured State Space Duality" by Tri Dao and Albert GuMentioned 15 times above
- BABILongBABILong is a benchmark for testing how well a large language model can reason over facts scattered through very long text.Mentioned 14 times above
More from See also
- Transformers
- Sliding window attention
- Retentive Network (RetNet)
- RWKV
- Linear Attention
- State space model (deep learning)
- Hyena
- Test-Time Training (TTT)
- Test-time compute
- Continual learning
- Meta-Learning
- Online learning
- Long-context language models
- Needle in a Haystack (NIAH)
- RULER (benchmark)
- Weight Decay
- Gradient Descent
- AdamW
- FineWeb
- Long Short-Term Memory (LSTM)
- Recurrent Neural Network
- Agent memory
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32 ^33 ^34 ^35 ^36 ^37 ^38 ^39 ^40 ^41 ^42 ^43 ^44 ^45 ^46 ^47 ^48 ^49 ^50 ^51 ^52 ^53 ^54 ^55 ^56 ^57 ^58 ^59 ^60 ^61 ^62 ^63 ^64 ^65 ^66 ^67 ^68 ^69 ^70 ^71 ^72 ^73 ^74 ^75 ^76 ^77 ^78 ^79 ^80 ^81 ^82 ^83 ^84 ^85 ^86 ^87 ^88 ^89 ^90 ^91 ^92 ^93 ^94 ^95 ^96 ^97 ^98 ^99 ^100 ^101 ^102 ^103 ^104 ^105 ^106 ^107 ^108 ^109 ^110 ^111 ^112 ^113 ^114 ^115 ^116 ^117 ^118 ^119Ali Behrouz, Peilin Zhong, Vahab Mirrokni, "Titans: Learning to Memorize at Test Time", arXiv, 2024-12-31. arxiv.org/...2501.00663. Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16Ali Behrouz, Meisam Razaviyayn, Vahab Mirrokni, "Titans + MIRAS: Helping AI have long-term memory", Google Research blog, 2025-12-04. research.google/...elping-ai-have-long-term-memory. Accessed 2026-10-31.
- ^1 ^2 ^3 ^4Ali Behrouz, Peilin Zhong, Vahab Mirrokni, "Titans: Learning to Memorize at Test Time (HTML version)", arXiv, 2025-01-02. arxiv.org/...2501.00663v1. Accessed 2026-05-20.
- ^François Aubry, "Google's Titans Architecture: Key Concepts Explained", DataCamp blog, 2025-01-24. datacamp.com/...titans-architecture. Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Yu Sun et al., "Learning to (Learn at Test Time): RNNs with Expressive Hidden States", arXiv, 2024-07-05. arxiv.org/...2407.04620. Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10Ali Behrouz, Meisam Razaviyayn, Peilin Zhong, Vahab Mirrokni, "It's All Connected: A Journey Through Test-Time Memorization, Attentional Bias, Retention, and Online Optimization", arXiv, 2025-04-17. arxiv.org/...2504.13173. Accessed 2026-10-31.
- ^1 ^2Matt Swayne, "Google's 'Titans' Models Offer a Scalable Memory System for AI", The AI Insider, 2025-01-16. theaiinsider.tech/...scalable-memory-system-for-ai. Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5 ^6Phil Wang, "titans-pytorch: Unofficial implementation of Titans, SOTA memory for transformers, in Pytorch", GitHub, repository created 2025-01-08 (stars and forks from the GitHub API, 2026-10-31). github.com/...titans-pytorch. Accessed 2026-10-31.
- ^1 ^2 ^3Fabien Furfaro, "TPTT: Transforming Pretrained Transformers into Titans", arXiv, 2025-06-21. arxiv.org/...2506.17671. Accessed 2026-10-31.
- ^1 ^2 ^3"Titans: Learning to Memorize at Test Time", NeurIPS 2025 poster page (Ali Behrouz, Peilin Zhong, Vahab Mirrokni). neurips.cc/...119639. Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Ali Behrouz, Zeman Li, Praneeth Kacham, Majid Daliri, Yuan Deng, Peilin Zhong, Meisam Razaviyayn, Vahab Mirrokni, "ATLAS: Learning to Optimally Memorize the Context at Test Time", arXiv, 2025-05-29. arxiv.org/...2505.23735. Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5Ali Behrouz, Meisam Razaviyayn, Peilin Zhong, Vahab Mirrokni, "Nested Learning: The Illusion of Deep Learning Architectures", arXiv, 2025-12-31 (a version published at NeurIPS 2025). arxiv.org/...2512.24695. Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Ali Behrouz, Vahab Mirrokni, "Introducing Nested Learning: A new ML paradigm for continual learning", Google Research blog, 2025-11-07. research.google/...paradigm-for-continual-learning. Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Gavriel Di Nepi, Federico Siciliano, Fabrizio Silvestri, "Titans Revisited: A Lightweight Reimplementation and Critical Analysis of a Test-Time Memory Model", arXiv, 2025-10-10. arxiv.org/...2510.09551. Accessed 2026-10-31.
- ^Ali Behrouz, Farnoosh Hashemi, Adel Javanmard, Vahab Mirrokni, "Language Models Need Sleep: Learning to Self-Modify and Consolidate Memories", arXiv, 2026-06-02. arxiv.org/...2606.03979. Accessed 2026-10-31.
- ^1 ^2Ali Behrouz, Vahab Mirrokni, "The sleep framework: A new way for LLMs to retain knowledge in continual learning", Google Research blog, 2026-10-27. research.google/...knowledge-in-continual-learning. Accessed 2026-10-31.
- ^1 ^2 ^3 ^4 ^5Ali Behrouz, Peilin Zhong, Vahab Mirrokni, "Titans: Learning to Memorize at Test Time", Advances in Neural Information Processing Systems 38 (NeurIPS 2025), proceedings paper. proceedings.neurips.cc/...d4b1-Abstract-Conference. Accessed 2026-10-31.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
6 revisions by 1 contributor · v6 · 6,768 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independently verified 2026-10-31 against the Titans arXiv preprint (2501.00663) and NeurIPS 2025 proceedings version, ATLAS, MIRAS, Nested Learning and Titans Revisited papers, Google Research blog posts and GitHub API; 11 verifier defects (4 material) fixed before stamping.
Cite this page: AI Wiki. "Titans (neural architecture)." aiwiki.ai, updated 31 Oct 2026, fact-checked 31 Oct 2026. CC BY 4.0. https://aiwiki.ai/wiki/titans_architecture