

AMD Instinct MI300X
The AMD Instinct MI300X is a data center GPU accelerator that Advanced Micro Devices released on December 6, 2023, built on the CDNA 3 architecture and paired with 192 GB of HBM3 memory at 5.3 TB/s of bandwidth, the largest memory capacity of any commercially available GPU at launch.[1][2] It uses a multi-chiplet design that combines eight GPU compute dies and four I/O dies on a single package, and AMD positioned it as a direct competitor to NVIDIA's H100, emphasizing that its 2.4x memory-capacity advantage is particularly relevant for large language model inference.[2][6] AMD CEO Lisa Su called it "the most advanced AI accelerator in the industry" at the December 2023 launch,[51] and when AMD first unveiled the chip in June 2023 it marketed it as "the world's most advanced accelerator for generative AI."[52]
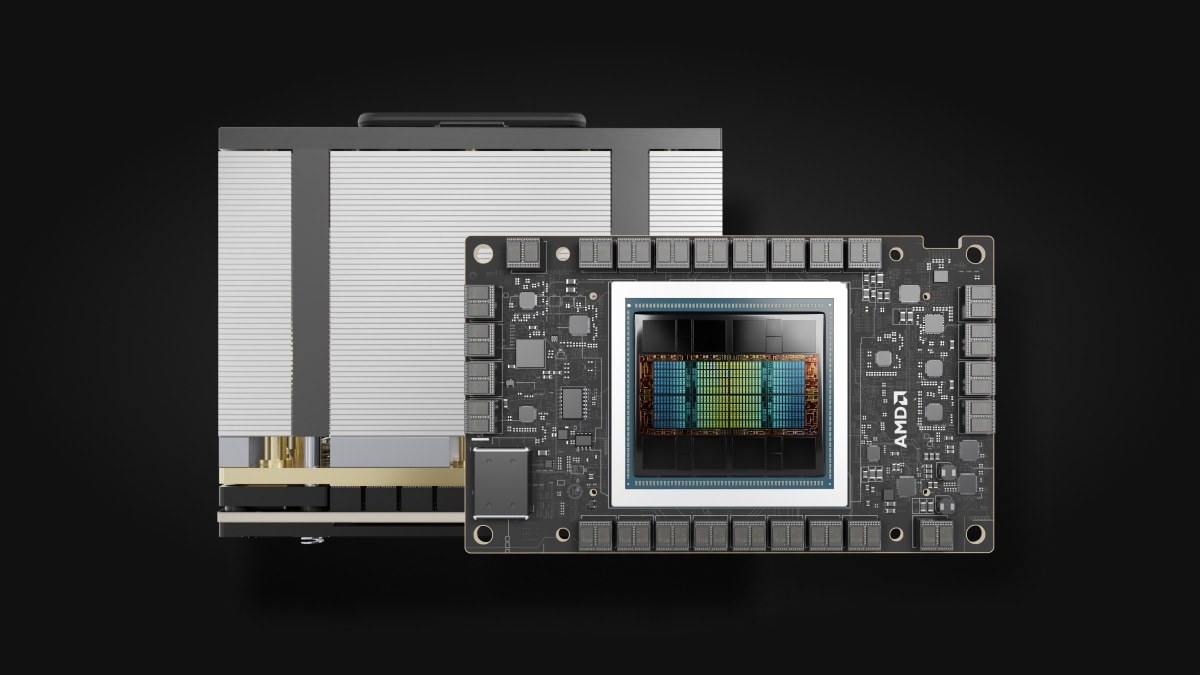
The MI300X represents AMD's most significant attempt to challenge NVIDIA's dominance in the AI accelerator market. It launched alongside the MI300A, a related APU variant that combines CPU and GPU cores on the same package,[1] and came with AMD's expectation of roughly $400 million in data center GPU revenue in the fourth quarter of 2023. AMD then raised its 2024 forecast for the MI300 series several times as demand exceeded initial projections.[37] By the end of 2024 AMD reported more than $5 billion in Instinct accelerator revenue for the year, the bulk of it from MI300X sales,[53] and the company crossed $1 billion in MI300X revenue in a single quarter (Q2 2024) within nine months of launch.[37][39]
MI300X is the first AMD accelerator that customers and analysts treated as a credible alternative to NVIDIA H100 rather than a niche HPC part. It became the GPU that hyperscalers used to diversify their AI fleets in 2024, and the foundation for AMD's Q4 2024 MI325X refresh and the CDNA 4 MI350 series in 2025. Independent benchmarks from SemiAnalysis, ChipsAndCheese, and academic groups have repeatedly confirmed two themes: the hardware is real and competitive, and the software ecosystem still trails NVIDIA's CUDA stack despite rapid improvement.[7][10]
Background
AMD's data center GPU history
AMD entered the data center GPU accelerator market in 2016 with the original Radeon Instinct product line, which targeted scientific computing and machine learning workloads.[36] The Instinct branding distinguished these professional accelerators from AMD's consumer Radeon GPUs. The early Instinct cards used graphics-derived architectures with limited software maturity, and AMD struggled to gain traction against NVIDIA's established CUDA ecosystem.
The introduction of the CDNA (Compute DNA) architecture in late 2020 marked a deliberate shift away from graphics-derived designs. AMD released the Instinct MI100 in November 2020, the first GPU built from the ground up for compute rather than graphics.[36] The MI100 used the "Arcturus" die with 7,680 stream processors, 32 GB of HBM2 memory, and support for the then-new BF16 data type.[36] While performance was competitive in certain workloads, software maturity remained a persistent challenge.
In 2021, AMD launched the MI250 and MI250X using the CDNA 2 architecture. The MI250X paired two "Aldebaran" dies in a multi-chip module, delivering 128 GB of HBM2e memory and up to 383 TFLOPS of FP16 performance.[36] The Department of Energy's Frontier supercomputer at Oak Ridge National Laboratory adopted the MI250X, and Frontier became the world's first verified exascale supercomputer in June 2022.[36] That deployment validated AMD's architecture for scientific HPC workloads but did not translate immediately into broad commercial AI adoption.
With MI300X, AMD aimed to convert its HPC credibility into AI infrastructure wins during the generative AI boom of 2023. The product was conceived as a CPU plus GPU unified package (the MI300A) and re-spun as a GPU-only design (the MI300X) when AMD recognized that the AI training and inference market wanted maximum GPU memory and compute, not CPU integration.
From MI300A to MI300X
The MI300 program began as an HPC APU, originally targeted at the El Capitan supercomputer at Lawrence Livermore National Laboratory. AMD added the GPU-only MI300X variant in 2022 after demand from cloud customers for an AI accelerator with more compute and memory than any then-shipping competitor. AMD swapped three of the MI300A's CPU chiplets for two additional XCDs in the MI300X, increasing GPU compute and memory at the cost of removing the on-package CPU.[24] The two products share the same I/O dies and packaging approach, which let AMD amortize design and packaging investment across both SKUs.
When was the MI300X released?
AMD launched the MI300X at its "Advancing AI" event on December 6, 2023, held in San Jose, California, six months after first previewing the chip.[1][26] AMD CEO Lisa Su delivered the keynote, describing the MI300X as "the most advanced AI accelerator in the industry."[51] AMD's initial performance claims focused on inference workloads, where the company said the MI300X delivered 1.6x faster throughput than the H100 on Bloom 176B and a 1.4x latency advantage on Llama 2 70B chat.[26]
Microsoft was announced as the launch cloud partner.[1] Microsoft Azure planned to deploy MI300X accelerators for its Azure OpenAI Service, which at the time powered ChatGPT and GPT-4 inference at scale.[6][12] AMD also announced commitments from Meta and Oracle at or shortly after the event.[1][6] SemiAnalysis, a semiconductor research firm, published an analysis the same day noting that the MI300X's memory capacity and bandwidth gave it a concrete hardware advantage over the H100 for large model inference, while raising questions about software maturity.[6]
The launch came during a period of acute GPU scarcity. NVIDIA's H100 had months-long lead times, and hyperscalers were actively seeking alternative supply. AMD's timing was deliberate: the company had been preparing MI300X production through 2023 and aligned the announcement with cloud provider commitments that were already in progress. The keynote also previewed customer endorsements from OpenAI (in the form of optimized inference for OpenAI Triton), Meta, Microsoft, Oracle, Dell, HPE, Lenovo, and Supermicro.[1][6]
About a week after the event, NVIDIA published a blog post disputing AMD's H100 comparison numbers.[55] NVIDIA argued that AMD compared an unoptimized H100 configuration to a tuned MI300X stack, and showed H100 numbers under TensorRT-LLM that exceeded AMD's quoted figures. AMD responded on December 15, 2023 with updated benchmarks[56] claiming the MI300X retained an inference lead even after applying NVIDIA's recommended optimizations. The exchange foreshadowed a recurring pattern: AMD's marketing benchmarks usually look impressive on paper, and independent third-party measurements tend to land somewhere between AMD's claims and NVIDIA's counter-claims.
CDNA 3 architecture
The MI300X is the flagship implementation of AMD's CDNA 3 compute architecture.[19] CDNA 3 is a successor to CDNA 2 and was designed exclusively for data center workloads, with no shared design lineage with AMD's consumer RDNA graphics architecture. The architecture targets HPC and AI in a single package and is the first AMD compute architecture to support FP8 numerics, structured 2:4 sparsity, and TF32 matrix operations.[19]
CDNA 3 introduced several compute enhancements over CDNA 2. Each CDNA 3 compute unit (CU) contains 64 stream processors, unchanged from CDNA 2, but the architecture added a second-generation matrix math unit capable of executing native FP8 operations, as well as BF16 and FP16 matrix operations.[24] The FP8 support was significant because many AI training and inference workflows were beginning to use FP8 quantization to reduce memory footprint and increase throughput per GPU. Each XCD has a 4 MB L2 cache shared by its compute units, smaller than CDNA 2's because it now sits in front of a new last-level cache and introduced a shared last-level cache called the Infinity Cache (also referred to as MALL, for Memory Attached Last Level).[19]
The MI300X has 304 active compute units, out of a maximum of 320 in a fully enabled eight-XCD configuration.[50] The 16 disabled compute units represent a yield-driven decision common in high-transistor-count designs. With 64 stream processors per CU, the MI300X exposes 19,456 stream processors.[24] Each compute unit also has four matrix cores, giving the chip 1,216 matrix cores in total.[24]
New matrix math features in CDNA 3 include 2:4 structured sparsity, which doubles effective throughput on supported precisions when half of the weights in each four-element group are zero, and an asynchronous matrix multiply pipeline that overlaps load and compute stages.[24] The MI300X also added support for TF32, which uses an FP32 exponent with FP16 mantissa, providing FP32 dynamic range at four times the FP32 matrix rate (half the FP16 rate).[19]
Chiplet design
The MI300X is built from 12 individual silicon dies: eight Accelerator Complex Dies (XCDs) and four I/O Dies (IODs).[24] This makes it one of the most complex chiplet assemblies in any commercial processor at its launch.
Each XCD is manufactured on TSMC's N5 (5nm) process node and contains 38 active compute units (40 physically present, with two disabled for yield purposes).[24] The XCDs are stacked vertically in pairs on top of the IODs using TSMC's SoIC (System on Integrated Chip) hybrid bonding technology.[41] This 3D stacking places two XCDs directly atop a single IOD, with the connection made through dense arrays of fine-pitch copper bonds carrying tens of terabytes per second of aggregate bandwidth.[41]
The four IODs serve as the system infrastructure layer. Each IOD is manufactured on TSMC's N6 (6nm) process node and manages memory access, I/O connectivity, and inter-die communication for the two XCDs sitting above it.[24] The IODs connect to the HBM3 stacks and expose the PCIe 5.0 host interface and the xGMI links that connect MI300X GPUs to each other.[24]
The Infinity Fabric interconnect runs between IODs at high bandwidth, and the IODs use a mesh topology internally to maintain coherency across the full 304-CU compute space. AMD's official total transistor count for the MI300X package is 153 billion, which it cites at Hot Chips 2024.[24] The 146 billion figure that also circulates is AMD's count for the related MI300A APU, which Tom's Hardware reported in January 2023.[27]
The full die area exceeds 1,000 mm-squared of active silicon across the package, far larger than what could fit on a single reticle. The chiplet approach was a necessity rather than a preference: a monolithic implementation of MI300X would not be manufacturable on N5 with current photolithography reticle limits.
AMD also offered the MI300X in a GPU partitioning mode. In NPS4 (Non-Uniform Memory Access 4-node) configuration, the GPU presents as four logical partitions to the operating system, each with 48 GB of memory.[19] This allows operators to run multiple independent workloads on a single physical accelerator or to improve memory locality for NUMA-sensitive applications. SPX (single partition) mode keeps all 304 CUs under a single domain.[19]
HBM3 memory subsystem
The MI300X carries 192 GB of HBM3 memory across eight stacks, each providing 24 GB.[2] The aggregate theoretical bandwidth is 5.3 TB/s.[2] This was the largest memory capacity on any commercially available GPU accelerator at launch and represented a 1.5x increase over the MI250X's 128 GB of HBM2e.
The memory advantage over NVIDIA's H100 SXM5 was substantial at launch. The H100 SXM5 carries 80 GB of HBM3 at 3.35 TB/s, meaning the MI300X provides 2.4x more memory and 1.6x more bandwidth per accelerator.[6] For large model inference, this difference has practical consequences: models too large to fit on a single H100 fit on a single MI300X, reducing the need for tensor parallelism across multiple GPUs and the associated inter-GPU communication overhead. A 70-billion-parameter Llama model in FP16 occupies approximately 140 GB; it fits on one MI300X but requires sharding across two H100s.[6]
In addition to the HBM3 main memory, the MI300X includes 256 MB of Infinity Cache (L3 cache), distributed across the four IODs.[19] ChipsAndCheese measured Infinity Cache bandwidth at about 11.9 TB/s against a 17 TB/s theoretical peak, substantially higher than the HBM3 bandwidth.[10]
The cache hierarchy has multiple levels:
| Level | Size | Approximate bandwidth |
|---|---|---|
| L1 cache | 32 KB per CU | Tens of TB/s |
| L2 cache | 4 MB per XCD shared by 38 CUs | High |
| Infinity Cache (MALL) | 256 MB shared across all four IODs | ~11.9 TB/s |
| HBM3 | 192 GB total | 5.3 TB/s |
Memory latency is one area where the MI300X does not lead. ChipsAndCheese found that the H100 had slightly faster VRAM access from a single thread's point of view, and attributed at least part of that to TLB misses on the MI300X.[10] Latency is comparable when work is split across multiple workgroups, which reduces TLB pressure.[10]
Compute specifications
The MI300X exposes the following key hardware parameters:
| Parameter | Value |
|---|---|
| Architecture | CDNA 3 |
| Process | TSMC N5 (XCDs), TSMC N6 (IODs) |
| Chiplets | 8 XCDs + 4 IODs + 8 HBM3 stacks |
| Transistors | 153 billion |
| Compute units | 304 active (320 total) |
| Stream processors | 19,456 |
| Matrix cores | 1,216 |
| Peak engine clock | 2,100 MHz |
| HBM3 capacity | 192 GB across 8 stacks |
| HBM3 bandwidth | 5.3 TB/s |
| Memory bus width | 8,192-bit |
| Infinity Cache | 256 MB |
| L2 per XCD | 4 MB |
| Host interface | PCIe 5.0 x16 (128 GB/s) |
| Inter-GPU | 7 Infinity Fabric (xGMI) links, 128 GB/s bidirectional (64 GB/s per direction) each |
| Form factor | OAM (OCP Accelerator Module) |
| Rated TDP | 750 W |
Performance
AMD published the following theoretical peak performance figures for the MI300X at the 2,100 MHz peak boost engine clock:[2]
| Precision | Peak performance (dense) | With 2:4 sparsity |
|---|---|---|
| FP64 vector | 81.7 TFLOPS | n/a |
| FP64 matrix | 163.4 TFLOPS | n/a |
| FP32 matrix | 163.4 TFLOPS | n/a |
| TF32 matrix | 653.7 TFLOPS | 1,307.4 TFLOPS |
| BF16 matrix | 1,307.4 TFLOPS | 2,614.9 TFLOPS |
| FP16 matrix | 1,307.4 TFLOPS | 2,614.9 TFLOPS |
| FP8 matrix | 2,614.9 TFLOPS | 5,229.8 TFLOPS |
| INT8 | 2,614.9 TOPS | 5,229.8 TOPS |
These figures assume dense arithmetic without sparsity unless otherwise noted. AMD followed a convention NVIDIA introduced with the A100 by also publishing sparsity-enabled peak numbers at 2x the dense figures for supported precisions.
In an eight-GPU MI300X Platform, the aggregate peak figures multiply by eight: 10.5 PFLOPS BF16 dense, 20.9 PFLOPS FP8 dense, and 41.8 PFLOPS FP8 with structured sparsity, on top of 1.5 TB of total HBM3 capacity.[3]
How fast is the MI300X in practice?
Benchmarks from independent researchers and cloud operators showed a significant gap between theoretical and sustained throughput. SemiAnalysis, which conducted extensive training benchmarks published in late 2024, found that the MI300X achieved roughly 620 TFLOPS in sustained BF16 matrix operations, compared to approximately 720 TFLOPS for the H100.[7] For FP8, the H100 achieved around 1,280 TFLOPS while the MI300X reached approximately 990 TFLOPS.[7]
The utilization efficiency difference was large: by those figures, the H100 reached about 73 percent of its rated 989.5 TFLOPS BF16 peak, while the MI300X reached about 47 percent of its rated 1,307 TFLOPS.[7] AMD's hardware delivers more raw compute capacity on paper, but the software stack, particularly kernel-level optimizations and tuned libraries, had not yet closed the gap with NVIDIA's mature cuBLAS and cuDNN implementations. SemiAnalysis titled the report "CUDA Moat Still Alive" to summarize the gap, while noting that AMD's MFU was actively improving over the report's five-month observation window.[7]
A notable detail from the SemiAnalysis investigation was that the H100 numbers reflected out-of-the-box performance with no special tuning, while the MI300X numbers required custom Docker images, environment variables, and direct AMD engineering involvement to reach the levels measured.[7] The same reviewers found that many MI300X workloads stalled at under 150 TFLOP/s in default configurations because of bugs in attention backwards passes and torch.compile.[7]
For inference workloads, particularly large language model inference where memory capacity is the binding constraint, the MI300X performed more competitively. Tests running 70B-parameter models showed the MI300X delivering better throughput than the H100 in single-GPU configurations, largely because the H100 requires model sharding across multiple GPUs at that scale while the MI300X can hold the full model in memory.[8] By late 2024, several inference benchmarks (Moreh, AMD ROCm Blogs, Oracle Cloud) were showing MI300X matching or exceeding H100 throughput on Llama 70B inference, particularly at batch sizes where H100 systems are limited by memory.[23]
DeepSeek R1 and large MoE inference
In early 2025, after the release of DeepSeek-R1 and DeepSeek V3, several groups demonstrated that MI300X could serve large mixture-of-experts models at competitive throughput. AMD published results in which a single 8-GPU MI300X node served DeepSeek R1 671B with time per output token below 50 ms at up to 32 concurrent requests using SGLang.[21] Moreh, a Korean software vendor, reported reaching 21,224 tokens per second on the same model and node configuration, close to the 22,282 tokens per second SGLang reported on an 8x H100 node.[45] SemiAnalysis's May 2025 inference benchmark found that for very large models such as Llama 3.1 405B and DeepSeek V3 670B, MI300X beat H100 in absolute performance and in performance per dollar, where the larger memory advantage matters most.[8]
Power consumption
The MI300X has a rated Thermal Design Power (TDP) of 750 W.[2] This is higher than the H100 SXM5's 700 W TDP and substantially higher than previous AMD Instinct accelerators. The MI300X uses the OAM (OCP Accelerator Module) form factor, which is an Open Compute Project standard for high-power AI accelerators.[2] OAM-based systems use direct liquid cooling or high-airflow forced-air cooling to manage the thermal load.
At 750 W per accelerator, deploying MI300X at scale requires power infrastructure rated for roughly 6 kW per server in an 8-GPU configuration before accounting for CPU, memory, networking, and power supply losses. Full 8-GPU MI300X servers from Supermicro, Dell, HPE, and Lenovo draw substantially more once CPUs, memory, networking and power-supply losses are included. This places the MI300X at the edge of what air-cooled data centers can reliably operate, driving interest in direct liquid cooling, which AMD made standard for the next-generation MI355X (1,400 W).[29]
Form factors and platforms
MI300X OAM module
The primary product is a single-GPU OAM module that mounts directly onto a Universal Baseboard (UBB). The OAM module exposes a 16-lane PCIe 5.0 host link (128 GB/s) and seven xGMI links for GPU-to-GPU communication.[2] Each xGMI link runs at 64 GB/s raw in each direction (128 GB/s bidirectional), with effective unidirectional bandwidth of approximately 45 to 48 GB/s after CRC and protocol overhead.[2][20]
MI300X Platform (8-GPU UBB 2.0)
AMD's reference design is the Instinct MI300X Platform, an 8-GPU UBB 2.0 baseboard.[3] The Platform exposes 1.5 TB of HBM3 (192 GB times eight), 5.3 TB/s of bandwidth per GPU, and 896 GB/s of aggregate peer-to-peer GPU bandwidth.[3] Each GPU's seven xGMI links connect to the other seven GPUs in a fully meshed topology.[3] The Platform uses industry-standard HGX host connectors, which lets OEM partners reuse server designs built for 8-GPU baseboards.[2]
OEM systems
OEM 8-GPU MI300X systems shipped from Dell (PowerEdge XE9680), HPE (Cray and ProLiant variants), Lenovo (ThinkSystem SR685a V3), and Supermicro (AS-8125GS-TNMR2 and others).[46][47] All shared the UBB 2.0 baseboard design, with vendor-specific differences in CPU host (typically AMD EPYC Genoa or Intel Xeon Sapphire Rapids), system memory (typically 2 TB), networking (often eight 400 GbE NICs), and storage.[47] Cluster-scale builds rely on RoCEv2 over Ethernet or InfiniBand for inter-node networking, which is also where the MI300X's collective performance characteristics tend to show up.
Single-GPU and PCIe form factors
AMD did not ship a PCIe add-in-card MI300X variant for general retail, in contrast to the MI210 (CDNA 2) which had a PCIe form factor. The MI300X is OAM-only at the module level. Some OEMs and cloud providers package single MI300X modules into purpose-built carrier boards, but the supported reference platform is the 8-GPU UBB.
ROCm software stack
ROCm (Radeon Open Compute) is AMD's open-source GPU computing platform, serving as the primary software stack for MI300X workloads. ROCm provides the runtime, compilers, math libraries, and machine learning framework integrations needed to run AI workloads on AMD hardware.
ROCm includes HIP (Heterogeneous-computing Interface for Portability), a C++ API that mirrors CUDA's programming model. Existing CUDA code can often be translated to HIP using AMD's hipify tool, which handles the mechanical renaming of CUDA APIs to their HIP equivalents. AMD claims that a large fraction of CUDA code translates automatically, but workloads using hand-written CUDA kernels, intrinsics, or architecture-specific optimizations require manual porting work.
Key ROCm library components relevant to MI300X workloads include:
- rocBLAS: Basic Linear Algebra Subprograms for GPU matrix operations
- MIOpen: AMD's deep learning primitive library, analogous to NVIDIA's cuDNN
- RCCL: Collective communications library, structurally a fork of NVIDIA's NCCL with HIP backend
- hipBLASLt: A library for high-performance matrix operations with auto-tuning
- Composable Kernel (CK): A template-based kernel composition library used to build optimized GEMM, attention, and convolution kernels
- AITER: AMD's tensor kernel library for AI workloads, introduced in March 2025[60] and used as the AMD-side equivalent of NVIDIA's CUTLASS for fused MoE and attention kernels
ROCm 6, announced with the MI300X in December 2023,[1] added meaningful improvements to PyTorch and TensorFlow integration and improved performance on several LLM inference kernels. AMD also introduced FlashAttention support for CDNA 3 in ROCm 6, though this arrived several months after NVIDIA's implementation became available.
ROCm 6.2, released in mid-2024, brought further improvements: Composable Kernel-based FlashAttention-2, OpenAI Triton-based FlashAttention-2, native FP8 support paths, and tuned vLLM and PyTorch images. In early 2025 AMD and the SGLang community raised DeepSeek-R1 throughput on MI300X by up to 4x in two weeks,[21] and AMD's AITER kernel library claimed up to 3x faster fused MoE kernels.[60] In August 2025 AMD described QuickReduce, a quantized all-reduce integrated into vLLM and SGLang that it says is up to 3x faster for some message sizes.[22]
The software maturity gap with CUDA remained a consistent criticism. Third-party benchmarks showed that achieving competitive training throughput on MI300X required non-trivial configuration: custom Docker images built from source, environment variable tuning flags not set by default, and in some cases direct AMD engineering support.[7] By contrast, NVIDIA's pre-built containers and optimized libraries generally worked without customization. AMD's response was to ship an increasing number of prebuilt vLLM, SGLang, and PyTorch Docker images aligned to specific MI300X tuning targets, and to expand the ROCm catalog of validated models on the Hugging Face Hub.[23]
Inference frameworks
The most active integration work happened around inference. By late 2024 the MI300X was a first-class citizen in:
- vLLM: Upstream support for ROCm and MI300X with paged attention and prefix caching. Prebuilt ROCm vLLM Docker images ship from AMD with FP8 KV cache, native FP8 weight quantization, and CK or Triton FlashAttention-2 backends.[44]
- SGLang: AMD-tuned SGLang builds were used for the high-throughput DeepSeek inference results in 2025. SGLang's RadixAttention and continuous batching benefit from MI300X's larger memory pool.[21]
- Hugging Face Transformers: The transformers, accelerate, and TGI libraries support ROCm. Hugging Face was one of the first customers on Azure ND MI300X v5 VMs, and said its users could run hundreds of thousands of Hub models on them without code changes.[12][18]
- OpenAI Triton: Triton has had a ROCm backend since 2023, and AMD contributed CDNA 3 codegen support. Many MI300X-tuned attention and quantization kernels are written in Triton rather than HIP.
- PyTorch and JAX: Both frameworks have native ROCm builds. PyTorch ROCm wheels are published on download.pytorch.org alongside the CUDA wheels.
- DeepSpeed and FSDP: Both supported, with the usual caveats around multi-node collective performance.
Hugging Face partnership
Hugging Face announced an expanded collaboration with AMD in mid-2024, formally validating its model libraries on MI300X and Azure ND MI300X v5.[18] Hugging Face's MI300 launch blog noted 2x to 3x improvements in time-to-first-token compared to MI250 on Llama 3 70B and said the 192 GB HBM3 footprint let it load and LoRA fine-tune Llama 3 70B on a single device.[18]
MI300A APU variant
Alongside the MI300X, AMD released the Instinct MI300A, a heterogeneous APU (Accelerated Processing Unit) that integrates CPU cores, GPU compute, and HBM3 memory on a single package.[1] The MI300A combines 24 Zen 4 CPU cores with a CDNA 3 GPU containing 228 active compute units and 128 GB of HBM3 memory shared between the CPU and GPU.[11]
The shared memory architecture eliminates the PCIe transfer bottleneck for CPU-GPU data movement, which is particularly valuable in HPC workloads that involve frequent data exchange between simulation code running on CPU cores and numerical acceleration on GPU compute units.[11]
The MI300A's primary application was the El Capitan supercomputer at Lawrence Livermore National Laboratory, built by Hewlett Packard Enterprise. El Capitan uses about 44,500 MI300A APUs across 11,136 nodes and was verified as the world's fastest supercomputer in the November 2024 TOP500 list with a High-Performance Linpack score of 1.742 exaflops (FP64), displacing Frontier from the top position.[28][34] It held the top spot through the November 2025 list and dropped to second when China's LineShine debuted at No. 1 on the June 2026 list.[35][58] Each El Capitan node holds four MI300A APUs, and each APU's 24 Zen 4 CPU cores and CDNA 3 GPU share 128 GB of unified HBM3.[28][35]
Which companies use the MI300X?
Microsoft Azure
Microsoft was the first major cloud provider to deploy the MI300X at scale. The ND MI300X v5 VM series, announced as generally available on May 21, 2024, uses eight MI300X accelerators per instance connected via PCIe Gen 5.0 and AMD Infinity Fabric.[12] The instance pairs the eight GPUs with two 4th-generation Intel Xeon Scalable (Sapphire Rapids) processors for 96 physical cores total, 1.5 TB of aggregate HBM3, and 5.3 TB/s of HBM bandwidth per GPU.[13]
Microsoft deployed MI300X to power portions of its Azure OpenAI Service workloads, including inference for GPT-3.5 and GPT-4 variants.[12] Hugging Face was the launch validation customer on ND MI300X v5 and reported 2x to 3x improvements in time-to-first-token on Meta Llama 3 70B versus the prior-generation MI250-based ND VMs.[18] The Azure deployment represented a meaningful diversification away from exclusive NVIDIA GPU dependence for cloud AI inference.
Meta
Meta began integrating MI300X accelerators in 2024 to run inference workloads on its Llama family of models.[6] Meta's adoption was partly enabled by ROCm 6 optimizations specifically tuned for Llama 2 models. Meta ran ranking, recommendation, and content generation workloads on AMD Instinct hardware, making it one of the largest real-world validations of ROCm's inference capability. By 2025 Meta was using MI300X for a meaningful share of its Llama 3 and Llama 4 inference fleet, with AMD calling out Meta as one of the largest single-customer commitments to MI300X.
Oracle Cloud Infrastructure
Oracle Cloud Infrastructure announced general availability of the BM.GPU.MI300X.8 bare-metal instance on September 26, 2024.[15] The instance ships eight MI300X accelerators, 2 TB of system memory, eight 3.84 TB NVMe drives, and a non-blocking RDMA network fabric supporting up to 16,384 MI300X GPUs in a single OCI Supercluster.[16][42] Oracle priced the bare-metal MI300X instance at $6.00 per GPU per hour.[16] Fireworks AI was an early reference customer for the OCI MI300X cluster; its CEO said the MI300X's memory capacity let it scale services as models grow.[15]
In October 2025, Oracle and AMD announced plans for an initial 50,000 MI450-series GPUs in OCI Superclusters, with deployment starting in calendar Q3 2026.[59]
Other cloud providers and customers
A wide group of neoclouds and AI specialty providers built businesses around MI300X capacity:
| Provider | Notes |
|---|---|
| Crusoe | MI300X cloud GPU instances on dedicated infrastructure with on-demand and reserved pricing |
| Vultr | Bare-metal and on-demand MI300X instances; opened MI300X price competition with sub-$2/hr rates |
| TensorWave | MI300X-only neocloud, prices as low as approximately $1.50 per GPU per hour for bare-metal |
| RunPod | Self-service MI300X access with hourly pricing |
| Hot Aisle | MI300X bare-metal specialist used by independent researchers and ChipsAndCheese |
| Lamini | Model fine-tuning platform built on MI300X |
| Fireworks AI | Inference provider, adopted MI300X on OCI |
| Moreh | Korean software/inference provider, optimized SGLang for MI300X DeepSeek inference |
Databricks, Lamini, and Hugging Face were public-named partners in the MI300X ecosystem development effort. Samsung reportedly purchased approximately $20 million worth of MI300X GPUs for internal AI development work. Smaller cloud providers such as TensorWave deployed MI300X to serve customers seeking alternatives to NVIDIA hardware amid H100 scarcity.
How does the MI300X compare to NVIDIA H100, H200, and B200?
The MI300X was designed to compete directly with NVIDIA's H100 and later H200 accelerators. The B200, NVIDIA's Blackwell generation released in 2024, is the closest contemporary in the next NVIDIA tier. The following table compares key specifications:
| Specification | AMD MI300X | NVIDIA H100 SXM5 | NVIDIA H200 SXM | NVIDIA B200 |
|---|---|---|---|---|
| Architecture | CDNA 3 | Hopper | Hopper | Blackwell |
| Process node | TSMC N5 / N6 | TSMC 4N | TSMC 4N | TSMC 4NP |
| Transistors | 153 billion | 80 billion | 80 billion | 208 billion (2 dies) |
| Compute units | 304 CUs | 132 SMs | 132 SMs | 160 SMs (2 dies) |
| FP8 peak (dense) | 2,615 TFLOPS | 1,979 TFLOPS | 1,979 TFLOPS | ~4,500 TFLOPS |
| BF16 peak (dense) | 1,307 TFLOPS | 990 TFLOPS | 990 TFLOPS | ~2,250 TFLOPS |
| FP4 peak | not supported | not supported | not supported | ~9,000 TFLOPS |
| Memory | 192 GB HBM3 | 80 GB HBM3 | 141 GB HBM3e | 180 GB HBM3e |
| Memory bandwidth | 5.3 TB/s | 3.35 TB/s | 4.8 TB/s | 8 TB/s |
| GPU-to-GPU interconnect | 7 xGMI links @ 128 GB/s bidirectional each | NVLink 4 @ 900 GB/s | NVLink 4 @ 900 GB/s | NVLink 5 @ 1.8 TB/s |
| TDP | 750 W | 700 W | 700 W | 1,000 W |
| Form factor | OAM | SXM5 | SXM5 | SXM6 |
| Launch | December 2023 | March 2022 | November 2023 | March 2024 |
On paper, the MI300X holds substantial advantages in memory capacity and memory bandwidth versus H100 and H200, and roughly matches B200 on memory capacity (192 GB versus 180 GB) while ceding bandwidth and FP4 throughput.[6][63] In sustained compute throughput for training, independent benchmarks place the H100 and H200 ahead of MI300X due to better software utilization.[7] The MI300X's interconnect topology differs in an architecturally important way: its xGMI fabric provides a fully meshed point-to-point topology where each GPU pair can exchange data over a single link of 128 GB/s bidirectional (64 GB/s each way), compared to NVIDIA's NVLink switched topology, which lets any two GPUs use up to the full 900 GB/s bidirectional NVLink bandwidth through the NVSwitch fabric.[3][20] This difference affects all-reduce collective operation performance and scales unfavorably as cluster size grows beyond a single node.
For multi-node training NVIDIA's H100 and H200 clusters typically use NVLink within the node and InfiniBand between nodes, with NCCL-aware topology routing. AMD MI300X clusters use xGMI within the node and RoCEv2 (or InfiniBand) between nodes, with RCCL providing the collective implementation.[20] In a 32-GPU all-reduce test, SemiAnalysis found MI300X over RoCEv2 ran at about half the speed of an H100 InfiniBand (non-SHARP) cluster for real-world message sizes, and ranked last among the setups tested.[7]
Independent benchmarks
SemiAnalysis training (December 2024)
SemiAnalysis's "MI300X vs H100 vs H200 Benchmark Part 1: Training" report, published in December 2024 after a five-month investigation, was the most influential independent benchmark of the MI300X.[7] Key findings:
- GEMM throughput: MI300X reached approximately 620 TFLOPS BF16 sustained, compared to roughly 720 TFLOPS for H100 and H200 (out-of-the-box, no tuning).[7]
- FP8 GEMM: H100 hit roughly 1,280 TFLOPS while MI300X reached approximately 990 TFLOPS.[7]
- Single-node training throughput on public AMD software trailed H100 and H200 on every model tested (GPT 1.5B, Llama 3 8B, a Llama 3 70B proxy and Mistral 7B), by more than 2.5x on GPT 1.5B and Mistral 7B; only an unmerged AMD development build beat them on the Llama 3 proxies. In two-node training, H100 was 10 to 25 percent faster.[7]
- The MI300X numbers were measured using AMD-supplied custom Docker images and tuning settings developed during a months-long debugging exercise. The H100 numbers used stock NVIDIA NGC images.[7]
- Many MI300X workloads stalled at under 150 TFLOP/s in default configurations because of bugs in attention backwards passes and torch.compile graph compilation. AMD shipped fixes during the investigation window.[7]
The report concluded that the "CUDA moat" remains real for training, while acknowledging meaningful AMD progress over the test period. As SemiAnalysis put it, "in theory, the MI300X should be at a huge advantage over Nvidia's H100 and H200," but its on-paper specs "are not representative of performance that can be expected in a real-world environment."[7]
ChipsAndCheese microarchitecture testing
ChipsAndCheese published "Testing AMD's Giant MI300X" in 2024 with low-level microbenchmarks.[10] Their findings:
- Measured VRAM bandwidth was 2.6x that of the H100 PCIe card tested (an HBM2e part slower than the H100 SXM).[10]
- Local memory bandwidth (LDS) on MI300X exceeded H100 measurably.[10]
- Single-thread VRAM latency was slightly worse than H100's, at least partly because of TLB misses; splitting the test across workgroups made it comparable.[10]
- L2 cache latency was lower on MI300X than H100, but H100's L2 was larger overall (50 MB versus 4 MB per XCD).[10]
- Infinity Cache (256 MB) at approximately 11.9 TB/s provides a useful intermediate tier between L2 and HBM, and ChipsAndCheese characterized it as one of the more interesting architectural design choices.[10]
SemiAnalysis InferenceMAX
SemiAnalysis launched InferenceMAX in 2025 as a continuously updated open inference benchmark that runs across NVIDIA and AMD hardware.[9] Its findings position MI300X as competitive on memory-heavy workloads:
- In SemiAnalysis's earlier May 2025 benchmark, MI300X beat H100 in both absolute throughput and performance per dollar on Llama 3 405B and DeepSeek V3 670B.[8]
- For smaller models (Llama 3 70B and below), H200 beat MI300X on absolute throughput and per-dollar metrics in most scenarios.[8]
- For competitive economics, MI300X cloud rentals needed to be priced at approximately $1.90/hr for translation/chat workloads (1k input, 1k output) and $2.10 to $2.40/hr for reasoning workloads (1k input, 4k output) on one-month contracts to match H200 cost-effectiveness.[8]
- Power efficiency: gpt-oss 120B in MX4 reasoning configuration delivered 750,000 tokens per second per provisioned megawatt on MI300X.[9]
AMD-published benchmarks
AMD's own benchmarks often show favorable comparisons that NVIDIA disputes. Examples include:
- 1.6x throughput versus H100 on Bloom 176B inference (December 2023 Advancing AI keynote)[26]
- 1.4x latency advantage versus H100 on Llama 2 70B chat inference (December 2023)[26]
- Up to 1.4x the inference performance of H200 on Mixtral 8x7B at FP16, for the MI325X (October 2024)[31]
These figures should be read with the standard caveat that vendor-published comparisons usually pick favorable configurations. The independent SemiAnalysis and ChipsAndCheese numbers above are a more reliable guide to typical performance.
How much does the MI300X cost?
AMD did not publicly announce list pricing for the MI300X at launch. Third-party reports from late 2023 and 2024 cited customer acquisition costs of approximately $10,000 to $20,000 per GPU for direct purchasers, broadly comparable to or modestly below NVIDIA H100 pricing of $25,000 to $30,000+. Reports of $15,000 single-unit pricing at the OAM level appeared in trade press coverage, with hyperscale-volume pricing presumed lower.
Fully populated 8-GPU MI300X server systems from OEM vendors typically priced in the $200,000 to $300,000 range depending on configuration. Oracle priced its OCI BM.GPU.MI300X.8 bare-metal instance at $6.00 per GPU per hour at launch, with reserved capacity rates lower.[17]
Cloud rental pricing for the MI300X moved aggressively downward during 2024 and 2025. By mid-2025, single-GPU on-demand rates from neoclouds settled in the $1.50 to $3.00 per hour range, with TensorWave at approximately $1.50 per GPU per hour for bare-metal and Vultr opening pricing at $1.85 per hour. RunPod self-service MI300X started at $2.30 per hour. Reserved one-month or annual pricing typically ran 20 to 40 percent below on-demand rates. SemiAnalysis noted that for MI300X to remain economically competitive against H200 on like-for-like inference workloads, pricing needed to land near or below $2 per hour.[8]
AMD's financial disclosures showed that MI300-series products generated revenue that exceeded its initial $400 million forecast for 2023, with the company raising full-year guidance multiple times through 2024 as hyperscaler demand materialized.[37]
Limitations
Software maturity
The most consistent criticism of the MI300X across independent analyses was software quality. CUDA's 15-plus year head start had produced an ecosystem of optimized kernels, profiling tools, and community knowledge that ROCm could not replicate quickly. Specific pain points documented during the 2024 SemiAnalysis investigation included:[7]
- Flash Attention's backward pass ran at under 20 TFLOPS on early ROCm releases, far below CPU-equivalent performance, requiring AMD to ship a patched image[7]
- torch.compile, PyTorch's graph compiler, was incompatible with several attention layer patterns and forced developers to mark regions as non-compilable[7]
- FP8 training caused hard errors in certain configurations until late 2024[7]
- Getting GPUs to function inside containers required passing multiple non-default environment flags[7]
- Custom CUDA kernels used in production ML pipelines required manual HIP porting, with no automated path[7]
- Default Docker images sometimes lagged the latest performance fixes by months[7]
AMD's response was a sustained investment in shipping prebuilt validated images, expanding the ROCm Compatibility Matrix, and contributing upstream to PyTorch, Triton, vLLM, and Hugging Face.[23] By mid-2025 the gap on inference-only workloads had narrowed substantially, while training remained the area where CUDA's lead was most visible.
Interconnect at scale
The point-to-point xGMI topology limits the efficiency of collective operations across multiple GPUs. In multi-node configurations (clusters larger than 8 GPUs), AMD used RoCEv2 over standard Ethernet or InfiniBand for inter-node networking.[20] Independent benchmarks found that AMD's collective operations ran 2 to 4 times slower than NVIDIA's InfiniBand-based configurations at 32-GPU scale, with the gap growing further at larger node counts.[7] NVIDIA's NVLink Switch architecture, introduced with the H100, allows intra-node collective operations to bypass the CPU entirely; AMD's architecture did not offer an equivalent at 8-GPU scale. AMD signaled an intent to address this with the Helios rack-scale design and UALink interconnect in the 2026 MI400 generation.[30]
Memory latency and TLB
While the MI300X's HBM3 capacity and bandwidth lead the market at launch, single-thread access latency is higher than the H100's.[10] Workloads sensitive to small-message access latency rather than streaming bandwidth saw measurable performance impact. In practice this affected only a narrow class of irregular-memory-access kernels. Splitting work across multiple workgroups eliminates most of the gap.[10]
Ecosystem depth
Most third-party AI software, from optimized inference runtimes like TensorRT-LLM to profiling tools like Nsight, targeted NVIDIA hardware. Many model serving frameworks added ROCm support incrementally and often without the same level of testing as their CUDA paths. This created integration friction for organizations that had built production pipelines around NVIDIA-specific tooling. The most popular third-party kernel libraries (xFormers, FlashAttention, Cutlass) added ROCm support over time, but typically months after the CUDA implementation.
Reception and impact
Industry reaction at launch was cautiously positive. Press coverage from AnandTech, Tom's Hardware, ServeTheHome, and HPCwire treated MI300X as the first AMD AI accelerator to credibly threaten NVIDIA's data center GPU monopoly.[40] SemiAnalysis's launch-day analysis acknowledged the hardware advantage in memory capacity and bandwidth while flagging software risk.[6] NVIDIA's response was confrontational: a same-week blog post disputed AMD's H100 comparison numbers, and TensorRT-LLM optimizations released within weeks pushed H100 inference throughput up.
Customer adoption exceeded AMD's initial guidance. AMD raised its 2024 data center GPU revenue target multiple times through the year, ending 2024 with more than $5 billion in Instinct accelerator revenue and a record $3.9 billion in Q4 data center segment revenue.[53] In Q1 2026 AMD's data center segment reported $5.8 billion in revenue, up 57 percent year over year.[57] At its November 2025 analyst day Lisa Su forecast tens of billions of dollars in AI accelerator revenue annually by 2027 and roughly 35 percent annual top-line growth across the company over the following three to five years.[38]
The MI300X also reset expectations of what is competitively possible for non-NVIDIA accelerators in the AI training and inference market. Until 2023, hyperscalers treated AMD's data center GPUs as HPC-only and kept AI workloads on NVIDIA. The MI300X changed that calculus, and the resulting MI325X, MI350 series, and MI400 roadmap commitments reflect AMD's view that AI accelerators can carry the company's data center segment at multi-tens-of-billions-of-dollars scale.
AMD AI revenue trajectory
AMD's AI accelerator revenue trajectory tracks the MI300X's customer ramp:
| Period | Reported metric |
|---|---|
| Q4 2023 | About $400M in data center GPU revenue expected (AMD guidance); 2024 forecast later raised several times |
| Q2 2024 | First quarter exceeding $1 billion in MI300X revenue |
| 2024 (full year) | More than $5 billion in data center GPU revenue, primarily MI300X |
| 2025 (full year) | $16.6 billion data center segment revenue (EPYC CPUs plus Instinct GPUs)[54] |
| Q4 2025 | Data center segment revenue (CPUs and GPUs) of a record $5.4 billion[54] |
| Q1 2026 | Data center segment revenue $5.8 billion, up 57 percent year over year |
| 2027 forecast | AMD AI data center business projected to reach tens of billions of dollars annually with 80 percent annual growth |
The 2024 figure is Instinct GPU revenue, mostly MI300X; the later rows are Data Center segment totals that also include EPYC server CPUs, because AMD does not report Instinct revenue separately by product.
Successors
MI325X
AMD announced the Instinct MI325X on October 10, 2024.[31] The MI325X uses the same CDNA 3 architecture and chiplet configuration as the MI300X but upgrades the memory to 256 GB of HBM3E with 6.0 TB/s bandwidth.[31] The memory upgrade was the primary change; compute specifications remained largely identical to the MI300X. The MI325X carried a 1,000 W TDP, 250 W higher than the MI300X, requiring updated thermal infrastructure. AMD had originally planned 288 GB of HBM3E for the MI325X but scaled back to 256 GB due to supply constraints on 36 GB HBM stacks. AMD positioned the MI325X as a 40 percent inference performance lead over the H200 on selected workloads, though independent verification of those numbers was mixed.[31]
MI350 series and MI355X
AMD introduced the MI350X and MI355X in 2025, based on the CDNA 4 architecture.[33] Both models carry 288 GB of HBM3E with 8 TB/s bandwidth and add support for FP4 and FP6 data types.[29] AMD claimed up to 4x improvement in AI compute performance compared to the MI300X and a 35x improvement in inference throughput for certain workloads.[29] The MI355X, designed for liquid-cooled systems, operates at up to 1,400 W total board power and is rated at about 10 PFLOPS of FP4 and 5 PFLOPS of FP8 dense throughput per GPU (twice that with sparsity).[29] The MI350X targets air-cooled configurations at lower power and lower clocks.
In an 8-GPU MI355X platform configuration, AMD quotes 2.3 TB of HBM3E aggregate, 64 TB/s aggregate bandwidth, and about 20 PFLOPS of FP16, 40 PFLOPS of FP8, and 80 PFLOPS of FP6 or FP4 dense throughput (double with sparsity).[29] AMD reported during 2025 that the MI350 series became the company's fastest-ramping product in history.
MI400 series and Helios
AMD detailed the Instinct MI400 series at Advancing AI 2025 and CES 2026.[30][33] The series includes the MI430X (HPC plus AI with full FP32 and FP64), MI440X, and MI455X (AI-focused with low-precision emphasis).[30] The lineup is built on CDNA 5 using TSMC's N2 (2nm) class process and is the first AMD accelerator family to support the UALink scale-up interconnect alongside Infinity Fabric.[30] AMD's preliminary 2025 specifications listed up to 40 petaflops FP4, 20 petaflops FP8, 432 GB of HBM4 memory, and 19.6 TB/s bandwidth per GPU; its MI400 product page now lists up to 23.3 TB/s for the MI455X.[62]
The corresponding rack-scale platform is Helios, a 72-GPU MI455X rack with EPYC Venice (Zen 6) CPU hosts.[30] Helios delivers 31 TB of HBM4, 1.4 PB/s aggregate memory bandwidth, 2.9 FP4 exaflops of inference, and 1.4 FP8 exaflops of training in a single rack.[30] Lisa Su called Helios "the world's best AI rack" at CES 2026.[61] Oracle committed to deploy 50,000 MI450-series GPUs in OCI Superclusters beginning in calendar Q3 2026.[59]
Continue reading
- NVIDIA H100NVIDIA H100 (also called the H100 Tensor Core GPU) is a data-center graphics processing unit built by NVIDIA on the Hopper microarchitecture, fabricated with over 80 billion transistors on a custom TSMC 4N (4…Mentioned 53 times above
- ROCmROCm is AMD's open software stack for GPU computing and the main alternative to NVIDIA's CUDA platform.Mentioned 23 times above
- CUDACUDA (Compute Unified Device Architecture) is NVIDIA's platform and programming model for general-purpose computation on its graphics processing units.Mentioned 16 times above
- SGLangSGLang (short for Structured Generation Language) is a high-performance, open-source serving framework for large language models and multimodal models, originally developed at UC Berkeley's Sky Computing Lab…Mentioned 9 times above
- vLLMvLLM is an open-source inference and serving engine for large language models. It is software for running already trained models, either through a Python interface for offline work or through a network server…Mentioned 6 times above
- NVIDIA H200The NVIDIA H200 is a data center Tensor Core GPU for AI and high-performance computing that was the first GPU to ship with HBM3e memory, packing 141 GB at 4.8 TB/s on its SXM and NVL boards.Listed in See also
More from See also
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8AMD Newsroom. "AMD Delivers Leadership Portfolio of Data Center AI Solutions with AMD Instinct MI300 Series." December 6, 2023. amd.com/...s-leadership-portfolio-of-data-center-a
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10AMD. "AMD Instinct MI300X Accelerator Data Sheet." amd.com/...amd-instinct-mi300x-data-sheet.pdf
- ^1 ^2 ^3 ^4 ^5AMD. "AMD Instinct MI300X Platform Data Sheet." amd.com/...instinct-mi300x-platform-data-sheet.pdf
- AMD. "AMD Instinct MI300X Accelerators Product Page." amd.com/...mi300x
- AMD. "AMD Instinct MI300 CDNA3 Instruction Set Architecture Reference Guide." August 2025. amd.com/...-cdna3-instruction-set-architecture.pdf
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10SemiAnalysis. "AMD MI300 Performance: Faster Than H100, But How Much?" December 6, 2023. semianalysis.com/...-mi300-performance-faster-than
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25SemiAnalysis. "MI300X vs H100 vs H200 Benchmark Part 1: Training: CUDA Moat Still Alive." December 2024. newsletter.semianalysis.com/...ark-part-1-training
- ^1 ^2 ^3 ^4 ^5 ^6SemiAnalysis. "AMD vs NVIDIA Inference Benchmark: Who Wins? Performance & Cost Per Million Tokens." newsletter.semianalysis.com/...-per-million-tokens
- ^1 ^2SemiAnalysis. "InferenceMAX: Open Source Inference Benchmarking." newsletter.semianalysis.com/...en-source-inference
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12ChipsAndCheese. "Testing AMD's Giant MI300X." chipsandcheese.com/...testing-amds-giant-mi300x
- ^1 ^2ChipsAndCheese. "Inside the AMD Instinct MI300A's Giant Memory Subsystem." chipsandcheese.com/...-amd-radeon-instinct-mi300as
- ^1 ^2 ^3 ^4AMD Newsroom. "AMD Instinct MI300X Accelerators Power Microsoft Azure OpenAI Service Workloads and New Azure ND MI300X V5 VMs." May 21, 2024. amd.com/...t-mi300x-accelerators-power-microsoft-a
- ^Microsoft Tech Community. "Introducing the new Azure AI infrastructure VM series ND MI300X v5." May 2024. techcommunity.microsoft.com/...4145152
- Microsoft Learn. "ND-MI300X-v5 size series Azure Virtual Machines." learn.microsoft.com/...ndmi300xv5-series
- ^1 ^2AMD Newsroom. "AMD Instinct MI300X Accelerators Available on Oracle Cloud Infrastructure for Demanding AI Applications." September 26, 2024. amd.com/...t-mi300x-accelerators-available-on-orac
- ^1 ^2Oracle Blog. "Announcing General Availability of OCI Compute with AMD MI300X GPUs." blogs.oracle.com/...ga-oci-compute-amd-mi300x-gpus
- ^Constellation Research. "With Oracle Cloud win, AMD MI300X gains traction as Nvidia counterweight." constellationr.com/...raction-nvidia-counterweight
- ^1 ^2 ^3 ^4Hugging Face. "Hugging Face on AMD Instinct MI300 GPU." huggingface.co/...huggingface-amd-mi300
- ^1 ^2 ^3 ^4 ^5 ^6 ^7AMD ROCm Documentation. "AMD Instinct MI300 Series Microarchitecture." web.archive.org/...mi300
- ^1 ^2 ^3 ^4AMD ROCm Blogs. "Understanding RCCL Bandwidth and xGMI Performance on AMD Instinct MI300X." rocm.blogs.amd.com/...README
- ^1 ^2 ^3AMD ROCm Blogs. "Unlock DeepSeek-R1 Inference Performance on AMD Instinct MI300X GPU." rocm.blogs.amd.com/...README
- ^AMD ROCm Blogs. "QuickReduce: Up to 3x Faster All-reduce for vLLM and SGLang." rocm.blogs.amd.com/...README
- ^1 ^2 ^3AMD ROCm Blogs. "Best practices for competitive inference optimization on AMD Instinct MI300X GPUs." rocm.blogs.amd.com/...README
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10AMD Hot Chips 2024. "AMD Instinct MI300X Generative AI Accelerator and Platform Architecture." August 2024. web.archive.org/...MI300X%29.v1.Final.20240817.pdf
- ServeTheHome. "AMD Instinct MI300X Architecture at Hot Chips 2024." servethehome.com/...architecture-at-hot-chips-2024
- ^1 ^2 ^3 ^4Tom's Hardware. "AMD unveils Instinct MI300X GPU and MI300A APU, claims up to 1.6X lead over Nvidia's competing GPUs." December 6, 2023. tomshardware.com/...ad-over-nvidias-competing-gpus
- ^Tom's Hardware. "AMD Instinct MI300 Data Center APU Pictured Up Close: 13 Chiplets, 146 Billion Transistors." tomshardware.com/...iplets-146-billion-transistors
- ^1 ^2Tom's Hardware. "AMD-powered El Capitan is now the world's fastest supercomputer with 1.7 exaflops of performance." tomshardware.com/...-to-third-place-on-top500-list
- ^1 ^2 ^3 ^4 ^5Tom's Hardware. "AMD announces MI350X and MI355X AI GPUs, claims up to 4X generational performance gain." tomshardware.com/...x-faster-inference-performance
- ^1 ^2 ^3 ^4 ^5 ^6Tom's Hardware. "AMD touts Instinct MI430X, MI440X, and MI455X AI accelerators and Helios rack-scale AI architecture at CES." tomshardware.com/...ture-and-customer-requirements
- ^1 ^2 ^3 ^4AMD Newsroom. "AMD Delivers Leadership AI Performance with AMD Instinct MI325X Accelerators." October 10, 2024. amd.com/...s-leadership-ai-performance-with-amd-in
- AMD Newsroom. "AMD Accelerates Exascale Computing to New Heights Powering the Fastest Supercomputer Ever, El Capitan." November 18, 2024. amd.com/...ates-exascale-computing-to-new-heights-
- ^1 ^2AMD Newsroom. "AMD Unveils Vision for an Open AI Ecosystem, Detailing New Silicon, Software and Systems at Advancing AI 2025." June 12, 2025. amd.com/...s-vision-for-an-open-ai-ecosystem-detai
- ^Lawrence Livermore National Laboratory. "El Capitan verified as world's fastest supercomputer." llnl.gov/...-verified-worlds-fastest-supercomputer
- ^1 ^2Wikipedia. "El Capitan (supercomputer)." en.wikipedia.org/...El_Capitan_(supercomputer)
- ^1 ^2 ^3 ^4 ^5Wikipedia. "AMD Instinct." en.wikipedia.org/...AMD_Instinct
- ^1 ^2 ^3The Next Platform. "AMD Breaks $1 Billion In Datacenter GPU Sales In Q2." nextplatform.com/...-in-datacenter-gpu-sales-in-q2
- ^CNBC. "AMD's Lisa Su sees 35% annual sales growth driven by 'insatiable' AI demand." November 11, 2025. cnbc.com/...amd-lisa-su-growth-ai-analyst-day
- ^DataCenter Dynamics. "AMD posts record data center revenue in Q2 2024 thanks to $1bn in MI300X sales." datacenterdynamics.com/...s-to-1bn-in-mi300x-sales
- ^HPCwire. "AMD Instinct MI300 Series Launch: Accelerating Next-Gen AI and Supercomputing." hpcwire.com/...ting-next-gen-ai-and-supercomputing
- ^1 ^2IEEE Spectrum. "AMD's Next GPU Is a 3D-Integrated Superchip." spectrum.ieee.org/amd-mi300
- ^Inside HPC. "Oracle Cloud Supercluster Supports 16,000 AMD Instinct MI300X GPUs." insidehpc.com/...ts-16000-amd-instinct-mi300x-gpus
- ROCm Documentation. "vLLM inference performance testing." rocm.docs.amd.com/...vllm-benchmark
- ^vLLM Blog. "Serving LLMs on AMD MI300X: Best Practices." October 2024. blog.vllm.ai/...vllm-serving-amd
- ^Moreh. "21K Output Tokens Per Second DeepSeek Inference on AMD Instinct MI300X GPUs with Expert Parallelism." moreh.io/...0x-gpus-with-expert-parallelism-251113
- ^Lenovo Press. "ThinkSystem AMD MI300X 192GB 750W 8-GPU Board Product Guide." lenovopress.lenovo.com/...x-192gb-750w-8-gpu-board
- ^1 ^2Supermicro. "Powered by AMD Instinct MI300X Accelerators." supermicro.com/...datasheet_H13_8U_8GPU_MI300.pdf
- AMD Blog. "Introducing the AMD Instinct MI300 Series accelerators, Powering the Growth of AI and HPC at Scale." amd.com/...g-the-amd-instinct-mi300-series-acceler
- AMD. "AMD Instinct MI300X Customer Acceptance Guide." instinct.docs.amd.com/...mi300x
- ^WCCFTech. "AMD Breaks Down Instinct MI300X MCM GPU: Full Chip Packs 320 CDNA 3 Compute Units, 192 GB HBM3." wccftech.com/...0-cdna-3-compute-units-192-gb-hbm3
- ^1 ^2SDxCentral (DatacenterDynamics). "AMD launches MI300X GPUs and MI300A APUs in generative AI push." December 7, 2023. sdxcentral.com/...i300a-apus-in-generative-ai-push
- ^80 Level. "AMD Announced MI300X Accelerator for Generative AI." June 2023. 80.lv/...nced-mi300x-accelerator-for-generative-ai
- ^1 ^2AMD Newsroom. "AMD Reports Fourth-Quarter and Full-Year 2024 Financial Results." February 4, 2025. newsroom.amd.com/...uarter-and-full-year-2024-fina
- ^1 ^2AMD Investor Relations. "AMD Reports Fourth Quarter and Full Year 2025 Financial Results." ir.amd.com/...1276
- ^NVIDIA Technical Blog. "Achieving Top Inference Performance with the NVIDIA H100 Tensor Core GPU and NVIDIA TensorRT-LLM." December 2023. developer.nvidia.com/...pu-and-nvidia-tensorrt-llm
- ^AMD Blog. "Competitive performance claims and industry leading Inference performance on AMD Instinct MI300X." December 15, 2023. amd.com/...-performance-claims-and-industry-leadin
- ^StorageNewsletter. "AMD: Fiscal 1Q26 Financial Results." May 19, 2026. storagenewsletter.com/...al-1q26-financial-results
- ^TOP500. "June 2026." top500.org/...06
- ^1 ^2AMD Newsroom. "Oracle, AMD Expand Partnership to Help Customers Achieve Next-Gen AI Scale." October 14, 2025. newsroom.amd.com/...tnership-to-help-customers-ach
- ^1 ^2AMD ROCm Blogs. "AITER: AI Tensor Engine For ROCm." March 21, 2025. rocm.blogs.amd.com/...README
- ^Yahoo Finance. "AMD reveals new AI PC chips, details next-gen data center chips at CES 2026." January 6, 2026. finance.yahoo.com/...r-chips-at-ces-2026-041117636
- ^AMD. "AMD Instinct MI400 Series GPUs." amd.com/...mi400
- ^NVIDIA. "DGX B200." nvidia.com/...dgx-b200
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
9 revisions · v9 · 8,388 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (175 claims, 61 sources fetched); 26 material + 39 minor fixed
Cite this page: AI Wiki. "AMD Instinct MI300X." aiwiki.ai, updated 28 Oct 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/amd_instinct_mi300x