

Agent
This article covers the foundational, conceptual, and historical idea of an agent in AI and computer science (the rational agent, PEAS, classical architectures, reinforcement learning, and pre-LLM milestones). For contemporary LLM agents in practice, see AI agents; for the 2023 to 2026 "agentic AI" paradigm and discourse, see Agentic AI.
See also: AI agents, Agentic AI, Multi-agent system, Machine learning terms
In artificial intelligence (AI), an agent is an entity that perceives its environment through sensors and acts upon that environment through actuators in pursuit of objectives. In Artificial Intelligence: A Modern Approach, Stuart Russell and Peter Norvig define an agent as "anything that can be viewed as perceiving its environment through sensors and acting upon that environment through actuators," and they make the idea the organising principle of the whole book: "The main unifying theme is the idea of an intelligent agent. We define AI as the study of agents that receive percepts from the environment and perform actions."[1] The textbook was first published in 1995, and its fourth edition was released in 2020 (with a 2021 copyright). The authors describe it as "the authoritative, most-used AI textbook" and list at least 1,556 schools in 134 countries or regions that have adopted it.[20][1]
This article focuses on the foundational concept of an agent as it has developed across more than five decades of AI research: from the actor model and early planning systems of the 1970s, through the reactive and BDI architectures of the 1980s and 1990s, into reinforcement learning, classical game-playing agents, and finally the modern LLM-driven systems of the 2020s. For the contemporary product and engineering landscape (Operator, Claude Code, Devin, frameworks, benchmarks, market data), see the companion articles AI agents and Agentic AI.
Explain like I'm 5 (ELI5)
Imagine you have a robot friend who can look around a room, think about what to do, and then do it. If the robot sees that the floor is dirty, it decides to vacuum. If it bumps into a chair, it turns and goes another way. That robot is an "agent" because it can sense things (see the dirty floor), think about them (decide to vacuum), and take action (start cleaning). AI agents work the same way, but most live inside computers. Some play chess, some answer questions, some help drive cars, and the newest ones can read websites and write computer code for you. They all share the same simple recipe: sense, think, act, repeat.
What is an agent in artificial intelligence? (formal definition)
Russell and Norvig define an agent abstractly through its agent function, a mathematical mapping from every possible percept sequence to an action:
where is the set of all possible percept sequences and is the set of actions available to the agent. The agent function is the abstract mathematical description; the agent program is the concrete implementation that runs on a physical or virtual platform (the agent architecture). A rational agent is one that, for each possible percept sequence, selects the action expected to maximise its performance measure, given the evidence the percept sequence provides and whatever built-in knowledge it possesses.[1]
Russell and Norvig are careful to distinguish rationality from omniscience and from perfection. Rationality maximises expected performance given what the agent can know; perfection would require knowing the actual outcome of every action in advance, which is generally impossible.[1]
Four ingredients fully specify an agent: the percepts it can receive, the actions it can take, the goals or performance measure it tries to optimise, and the environment in which it operates. Russell and Norvig package these into the PEAS framework (Performance measure, Environment, Actuators, Sensors), which they use to specify the task environment of any agent before discussing its internal design. The table follows the book's own example of an automated taxi driver.[1]
| PEAS element | Question it answers | Self-driving taxi example |
|---|---|---|
| Performance measure | What counts as success? | Safe, fast, legal, comfortable trip; maximise profits; minimise impact on other road users |
| Environment | What does the agent live in? | Roads, other traffic, police, pedestrians, customers, weather |
| Actuators | What can the agent change? | Steering, accelerator, brake, signal, horn, display, speech |
| Sensors | What can the agent perceive? | Cameras, radar, speedometer, GPS, engine sensors, accelerometer, microphones, touchscreen |
A second taxonomy classifies the task environment itself along several axes that determine how hard the design problem is.[1] An environment is fully observable if sensors give access to the complete state and partially observable otherwise; deterministic if the next state is fully determined by the current state and action, stochastic otherwise; episodic if each action stands alone, sequential if actions have lasting consequences; static or dynamic; discrete or continuous; single-agent or multi-agent; and known or unknown (whether the agent has access to the rules). In the book's examples, chess played with a clock is fully observable, multi-agent, deterministic, sequential, semidynamic, and discrete, while taxi driving is partially observable, multi-agent, stochastic, sequential, dynamic, and continuous, the hard end of nearly every axis.[1]
The agent environment interface
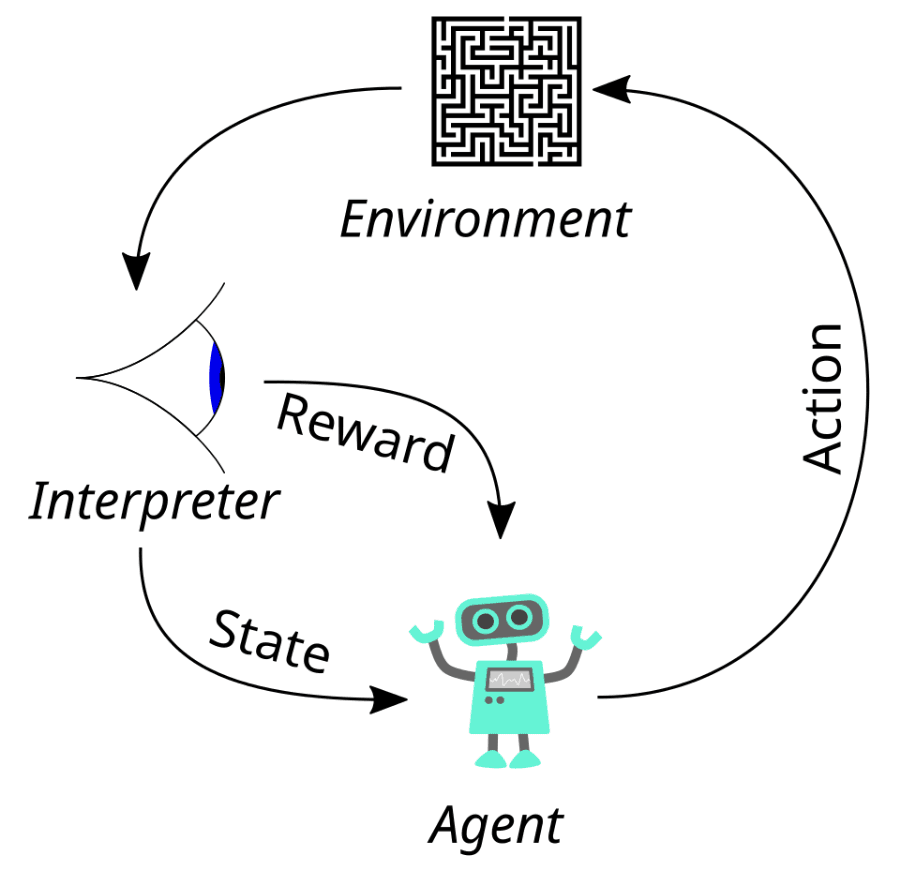
The interaction between an agent and its environment follows a cyclical pattern that is especially well formalised in reinforcement learning. At each discrete time step , the agent:
- Observes the current state of the environment (or a partial observation in partially observable settings).
- Selects an action according to its policy, a mapping from states to actions.
- Receives a reward , a scalar signal indicating how good or bad the outcome was.
- Transitions to a new state .
This cycle repeats until a terminal condition is met or the process continues indefinitely. When the environment satisfies the Markov property (future states depend only on the current state and action, not on history), the framework is called a Markov Decision Process (MDP).[2]
| Component | Symbol | Description |
|---|---|---|
| State | Representation of the environment at time t | |
| Action | Choice made by the agent | |
| Reward | Scalar feedback signal from the environment | |
| Policy | Mapping from states to actions | |
| Value function | Expected cumulative reward from state s | |
| Action-value function | Expected cumulative reward from taking action a in state s | |
| Transition function | Probability of moving to state s' after taking action a in state s | |
| Discount factor | Weight on future rewards, typically 0.9 to 0.99 |
The expected return from a state under policy is . Optimal control reduces to finding the policy that maximises this quantity. The same loop describes a thermostat regulating a room, a chess engine choosing moves, a robot arm placing a chip on a circuit board, and an LLM calling tools in a browser. The differences lie in the action space, the observation space, and how the policy is computed, not in the abstraction.
What are the types of agents? (Russell and Norvig's taxonomy)
Russell and Norvig's textbook outlines four basic kinds of agent program, ordered by internal structure and sophistication: simple reflex, model-based reflex, goal-based, and utility-based agents. It then explains in general terms how any of them can be turned into a learning agent, which is why the scheme is often summarised as five types.[1] Each successive type builds on the capabilities of the previous one, and the scheme is a common way of introducing the agent concept.
Simple reflex agents
Simple reflex agents select actions based solely on the current percept, ignoring the entire percept history. They operate through condition-action rules ("if the car ahead is braking, then apply brakes"). They work well in fully observable environments but fail when the environment is partially observable because they have no memory of past events. A household thermostat is a classic example: it turns on heating when the temperature drops below a threshold and turns it off when the threshold is exceeded. A spam filter that only inspects the current message and applies fixed rules is another. Simple reflex agents fail catastrophically in any setting where the right action depends on context the current percept does not reveal.
Model-based reflex agents
Model-based reflex agents maintain an internal model of the world that tracks aspects of the environment not directly visible at any moment. This internal state is updated after each action and percept using two kinds of knowledge: how the world evolves independently of the agent, and how the agent's own actions affect the world. By maintaining this model, the agent can handle partially observable environments far more effectively than a pure reflex agent. A self-driving car that remembers a pedestrian who briefly stepped behind a parked truck is a model-based reflex agent. The internal model can be as simple as a flag ("the lights are on") or as elaborate as a 3D occupancy grid of the surrounding street.
Goal-based agents
Goal-based agents extend model-based agents by incorporating explicit goal information that describes desirable states. Rather than just reacting, these agents use search and planning algorithms to identify sequences of actions that will achieve their goals. This makes them flexible: when the environment or goals change, the agent can recompute its plan rather than requiring a complete rewrite of its condition-action rules. A robot vacuum that plans an efficient path through a room is a goal-based agent. So is a route planner that searches a graph of intersections to compute the shortest path to a destination, and a STRIPS planner that chains preconditions and effects to assemble a plan.
Utility-based agents
Utility-based agents go further by employing a utility function that maps each state (or sequence of states) to a real number representing how desirable that state is. While goal-based agents have a binary notion of success and failure, utility-based agents can compare multiple outcomes on a continuous scale. This is especially important when there are conflicting goals ("arrive on time" vs. "avoid bumpy roads"), when goals can be achieved to different degrees, or when there is uncertainty about outcomes. A rational utility-based agent selects the action that maximises expected utility, weighing probabilities and desirability of potential outcomes. A financial trading agent that balances expected return against variance is a utility-based agent.
Learning agents
Learning agents improve their performance over time through experience. They consist of four conceptual components in Russell and Norvig's diagram: a learning element that makes improvements based on feedback, a performance element that selects actions, a critic that evaluates how well the agent is doing relative to a fixed performance standard, and a problem generator that suggests exploratory actions to discover new experiences.[1] Nearly all sophisticated AI systems today are learning agents in some form. AlphaGo's neural networks were trained first by supervised learning from human expert games and then by reinforcement learning from games of self-play;[24] an LLM-based coding agent learns implicitly from the gradient updates that produced its base model and then explicitly from examples in its prompt.
| Agent type | Internal state | Planning | Learning | Example |
|---|---|---|---|---|
| Simple reflex | None | No | No | Thermostat |
| Model-based reflex | World model | No | No | Spam filter with context state |
| Goal-based | World model + goals | Yes | No | Route planner, STRIPS |
| Utility-based | World model + utility function | Yes | No | Financial trading agent |
| Learning | All of the above + learning element | Yes | Yes | Self-driving car, AlphaGo |
This taxonomy is conceptual rather than architectural. A modern coding agent like Devin blends elements of all five: it reacts to immediate test failures, maintains a model of the codebase, decomposes goals into subtasks, weighs alternative implementations against a quality measure, and updates its plan as new information arrives.
Classical agent architectures
Russell and Norvig's agent types describe what agents do conceptually. A parallel research literature, mostly developed between the mid-1980s and late 1990s, addresses how to actually build them. Three architectural families dominated that period and still shape modern systems.
Deliberative agents and symbolic planning
The earliest AI agents were deliberative, following a sense-model-plan-act cycle. STRIPS (1971), the planner inside the SRI robot Shakey, took a symbolic model of the world plus a goal and produced a sequence of actions whose preconditions and effects led from the initial state to the goal. Later approaches such as NOAH, partial-order planning, and Graphplan refined the search but kept the same shape. Deliberative agents are powerful when the world model is accurate and tractable but brittle when the environment changes faster than the planner can replan.
Reactive agents and the subsumption architecture
In 1986, Rodney Brooks at the MIT AI Lab introduced the subsumption architecture in the paper "A Robust Layered Control System for a Mobile Robot," published in the IEEE Journal of Robotics and Automation.[3] Brooks rejected the central role of symbolic world models in mobile robotics. Instead of a single planner, a subsumption robot is built from layered behaviours, each of which couples sensors directly to actuators. Lower layers (avoid obstacles, wander) run continuously; higher layers (explore, identify objects) can subsume lower ones by suppressing their outputs when needed. The approach produced robots that worked in real time in unstructured environments, among them Allen, Herbert, and Genghis, and is closely associated with the rise of behaviour-based robotics.[3][22] In "Elephants Don't Play Chess" (1990), Brooks stated the physical grounding hypothesis, that to build an intelligent system "it is necessary to have its representations grounded in the physical world," and argued that "the world is its own best model."[22] His paper "Intelligence without representation," received by Artificial Intelligence in 1987 and published in 1991, became a widely read statement of the case for reactive agents.[3]
Purely reactive agents have no memory and no model; they cannot reason about distant goals. The trade-off motivated hybrid architectures, such as TouringMachines (Ferguson, 1992) and InteRRaP (Muller, 1996), which layer a deliberative planner on top of a reactive component.
BDI: belief desire intention
One of the most influential symbolic agent architectures is the belief-desire-intention (BDI) model, originally a philosophical theory of human practical reasoning proposed by Michael Bratman in Intention, Plans, and Practical Reason (Harvard University Press, 1987).[4] Bratman argued that intentions cannot be reduced to combinations of belief and desire; they are a third kind of mental state that commits an agent to future action and stabilises planning over time.
Anand Rao and Michael Georgeff translated Bratman's framework into a computational architecture in a series of papers culminating in "BDI Agents: From Theory to Practice" at ICMAS 1995.[5] In a BDI agent:
- Beliefs represent what the agent thinks is true about the world. They form the agent's informational state and are continually revised by perception.
- Desires represent the agent's motivational state: the states of affairs it would like to bring about.
- Intentions are the subset of desires the agent has committed to and is currently planning to achieve. They constrain future deliberation and ensure persistence.
The deliberation cycle of a BDI agent updates beliefs from percepts, chooses which desires to adopt as intentions, selects a plan to achieve those intentions, and executes the plan while monitoring for events that would require reconsideration.
The Procedural Reasoning System (PRS), developed by Georgeff, Amy Lansky, and colleagues at SRI International in the mid-1980s, was in Rao and Georgeff's words "one of the first implemented agent-oriented systems based on the BDI architecture."[5][6] An early application was a fault-detection system for the reaction control system of NASA's Space Shuttle.[6] Rao and Georgeff also list uses of PRS and its successor dMARS in telecommunications network management, air-combat modelling, and business process management, and describe OASIS, a BDI air-traffic management system then in trials at Sydney airport.[5] PRS inspired a family of BDI agent programming languages, including AgentSpeak(L) (Rao, 1996) and its open source implementation Jason (Bordini and Hubner), as well as Jadex and Jack Intelligent Agents.[7]
| Architecture family | Year | Key contributors | Idea |
|---|---|---|---|
| Symbolic planning (STRIPS) | 1971 | Fikes, Nilsson (SRI) | Search over action sequences with preconditions and effects |
| Actor model | 1973 | Hewitt, Bishop, Steiger (MIT) | Concurrent objects communicating by message passing |
| Blackboard systems (HEARSAY-II) | 1980 | Erman et al. (CMU) | Cooperating knowledge sources sharing a workspace |
| Subsumption | 1986 | Brooks (MIT) | Layered reactive behaviours, no central world model |
| BDI | 1987 to 1995 | Bratman, Rao, Georgeff (SRI) | Beliefs, desires, intentions; PRS, AgentSpeak |
| Soar | 1987 | Laird, Newell, Rosenbloom | Unified cognitive architecture with chunking |
| Hybrid layered (TouringMachines, InteRRaP) | 1992 to 1996 | Ferguson, Muller | Reactive plus deliberative layers |
| Agent-oriented programming (AOP) | 1993 | Shoham (Stanford) | Programming paradigm in mentalistic terms[8] |
Carl Hewitt, Peter Bishop, and Richard Steiger introduced the actor model in their 1973 IJCAI paper "A Universal Modular ACTOR Formalism for Artificial Intelligence."[9] Actors are concurrent computational entities that respond to messages by sending new messages, creating new actors, and changing their own future behaviour. The actor model became an influential model of message-passing concurrency and of agent communication generally.
Yoav Shoham's "Agent-Oriented Programming" (Stanford, 1990; revised 1993) proposed that the natural way to specify an agent is in mentalistic terms (belief, commitment, choice, ability) and that a programming language should expose these primitives directly. His AGENT0 language, although a research prototype, framed the conceptual goal of agent-oriented programming and is widely cited.[8]
What makes an agent "intelligent"
Michael Wooldridge and Nicholas Jennings's survey "Intelligent Agents: Theory and Practice" (The Knowledge Engineering Review, 1995) set out a working definition of an agent. They distinguished two usages of the word: a weak one, "relatively uncontentious," and a stronger one, "potentially more contentious."[10] Under the weak notion of agency, an agent is a hardware or (more usually) software-based computer system with four properties:[10]
| Property | Definition |
|---|---|
| Autonomy | Operates without direct human intervention; controls its own state and behaviour |
| Reactivity | Perceives its environment and responds in a timely manner to changes |
| Proactiveness | Exhibits goal-directed behaviour by taking the initiative, not just responding |
| Social ability | Interacts with other agents (or humans) through some agent communication language |
The authors noted that this weak notion had "found currency with a surprisingly wide range of researchers." Under the strong notion of agency, used particularly in AI, an agent is in addition conceptualised or implemented using concepts more usually applied to humans, such as knowledge, belief, intention, and obligation.[10] The four properties also give a quick test for any system: a thermostat would count as autonomous and reactive but neither proactive nor social, while a deliberative robot may be proactive but not yet social, and so on.
A parallel definitional thread comes from MIT. Pattie Maes worked at the MIT AI Lab with Marvin Minsky and Rodney Brooks before becoming a professor at the MIT Media Lab, and her Media Lab profile credits her with having "pioneered the concept of Software Agents in the 90s."[11] Her 1994 Communications of the ACM article "Agents that Reduce Work and Information Overload" described the interface agent this way: "The metaphor used is that of a personal assistant who is collaborating with the user in the same work environment." Her lab's projects included HOMR (Helpful Online Music Recommendation), a personalised music recommendation system released in late 1994 that led to the company Firefly, which Maes co-founded.[11] The personal-assistant framing anticipates the way many LLM agents are presented today.
Michael Genesereth and Steven Ketchpel's 1994 Communications of the ACM article "Software Agents" tied agency to communication: agents, they wrote, "communicate with their peers by exchanging messages in an expressive agent communication language." Wooldridge and Jennings quote this as a statement of the weak notion of agency in agent-based software engineering.[10]
Multi-agent systems and agent communication
When several agents share an environment, the design problem becomes the design of a multi-agent system (MAS). Multi-agent research is closely tied to distributed AI, game theory, and economics. Yoav Shoham and Kevin Leyton-Brown's textbook Multiagent Systems: Algorithmic, Game-Theoretic, and Logical Foundations (Cambridge, 2009) is a standard modern treatment, and its authors make a PDF available online.[8]
Three threads dominate the MAS literature:
- Cooperation and coordination. How can agents work together when each has private information and preferences? Distributed problem solving, contract nets (Smith, 1980), and joint intention theories (Cohen and Levesque, 1991) address this.
- Competition and strategic interaction. When agents have conflicting interests, the right tools are game theory and mechanism design: equilibrium concepts, auctions, voting, and the design of interaction rules that produce desirable outcomes.
- Communication. Agents need a shared language. Two standards dominated the classical period: KQML and FIPA-ACL.
KQML (Knowledge Query and Manipulation Language), an early and influential agent communication language, was developed by the ARPA-supported Knowledge Sharing Effort; Tim Finin and colleagues described it as an agent communication language at CIKM in 1994. KQML is organised around performatives: speech-act-style message types such as ask-if, ask-one, tell, subscribe, and achieve that name the intent of a message rather than just its content.[12]
The Foundation for Intelligent Physical Agents (FIPA) was formed in 1996 as a Swiss-based organisation, a non-profit association registered in Geneva, to produce software standards for heterogeneous, interacting agents.[13] Its agent communication language, FIPA-ACL, uses the same performative idea. FIPA's Communicative Act Library specification, which reached standard status in 2002, defines 22 communicative acts (including inform, request, propose, agree, confirm, query-if, and subscribe) and gives them a formal semantics built on three primitive mental attitudes: belief, uncertainty, and choice.[13] FIPA also specified interaction protocols (contract net, request, query), agent management, and message transport. The IEEE accepted FIPA as its eleventh standards committee on June 8, 2005.[13] Reference platforms such as JADE (Java Agent Development Framework) implement the FIPA specifications.
The International Conference on Autonomous Agents and Multiagent Systems (AAMAS), the field's flagship venue, was created in 2002 in Bologna, Italy by merging three predecessor conferences: the International Conference on Autonomous Agents (AGENTS), the International Conference on Multiagent Systems (ICMAS), and the International Workshop on Agent Theories, Architectures, and Languages (ATAL). AAMAS is run by the non-profit International Foundation for Autonomous Agents and Multiagent Systems (IFAAMAS) and has met annually since.[14]
Agents in reinforcement learning
In reinforcement learning (RL), the agent is the central learning entity. Unlike supervised learning where correct answers are provided, an RL agent must discover which actions yield the highest reward through trial and error. The agent interacts with its environment over many episodes, gradually improving its policy.
RL agents are broadly categorised as model-based or model-free. Model-based agents build an internal model of the environment's transition dynamics and use it for planning. Model-free agents learn directly from experience without constructing an explicit environment model. Model-free approaches are often simpler to implement but may require more training data; model-based methods can be more sample efficient but rely on the accuracy of the learned model.[2]
Key RL algorithms for training agents include:[2]
- Q-learning: A model-free off-policy algorithm that learns the value of state-action pairs using temporal difference updates.
- SARSA: An on-policy algorithm that updates Q-values based on the action actually taken by the current policy.
- Policy gradient methods (REINFORCE): Directly optimise a parameterised policy by estimating the gradient of expected return.
- Actor-critic methods: Combine a policy (actor) with a value function (critic) for more stable learning, with A2C and A3C as common variants.
- Proximal Policy Optimisation (PPO): A widely used policy gradient method that clips updates to prevent large, destabilising changes; OpenAI used it to train OpenAI Five.[18]
- Deep Q-Network (DQN): Combines Q-learning with deep neural networks, experience replay, and a target network. The 2013 DQN paper from Volodymyr Mnih and colleagues at DeepMind presented "the first deep learning model to successfully learn control policies directly from high-dimensional sensory input using reinforcement learning." Taking raw Atari pixels as input, it outperformed all previous approaches on six of seven games and surpassed a human expert on three of them (Breakout, Enduro, and Pong).[15]
- MuZero: Combines learning with planning. It learns a model that predicts reward, policy, and value, and runs its tree search inside that learned model instead of a simulator of the rules; the real environment is queried only to mask illegal actions at the root of the search tree.[25]
- Decision Transformer: Reformulates RL as a sequence modelling problem, conditioning a transformer on returns, states, and actions.[42]
After DQN, the same conceptual loop, now powered by neural function approximators, produced AlphaGo, AlphaStar, and OpenAI Five, making the agent abstraction concrete in a way classical control theory had not.
Agents in game playing
Game playing has been one of the most visible domains for AI agents, producing landmark achievements that demonstrated the power of different agent architectures.
Deep Blue (IBM, 1997) defeated chess world champion Garry Kasparov using brute-force search with hand-crafted evaluation functions. The decisive rematch ran in New York City from May 3 to May 11, 1997, and Deep Blue won 3.5 to 2.5, the first time a computer defeated a reigning world champion in a match under standard tournament time controls; Kasparov had won their first encounter 4 to 2 in Philadelphia in February 1996. While not a learning agent, Deep Blue showcased the power of combining search algorithms with domain expertise and dedicated hardware.[16]
AlphaGo (DeepMind, 2015 to 2017) was the first computer program to defeat a human professional Go player on a full-sized 19x19 board without a handicap: in October 2015 it beat the European champion Fan Hui 5-0, a result DeepMind published in Nature in January 2016.[24] It then defeated the 9-dan professional Lee Sedol 4 games to 1 in Seoul from March 9 to March 15, 2016; DeepMind says the match was watched by over 200 million people worldwide.[21] AlphaGo combined deep neural networks with Monte Carlo tree search, and its networks were trained by supervised learning from human expert games followed by reinforcement learning from games of self-play.[24]
Its successor, AlphaZero, learned Go, chess, and shogi entirely through self-play, with no human game data and no domain knowledge except the game rules. The two papers that describe it report different training figures. The December 2017 arXiv preprint said AlphaZero "achieved within 24 hours a superhuman level of play" in all three games; it gave the training hardware as 5,000 first-generation TPUs generating self-play games and 64 second-generation TPUs training the networks, and reported that AlphaZero outperformed the world-champion chess program Stockfish after 4 hours, the shogi program Elmo after less than 2 hours, and the version of AlphaGo that beat Lee Sedol (AlphaGo Lee) after 8 hours.[23] The peer-reviewed Science paper of December 2018 dropped the 24-hour claim. It gave 16 second-generation TPUs for network training (with the same 5,000 first-generation TPUs for self-play) and reported that AlphaZero first outperformed Stockfish after 4 hours, Elmo after 2 hours, and AlphaGo Lee after 30 hours.[17] In both papers these milestones were read off Elo ratings measured during training. In the Science paper's final evaluation matches, AlphaZero "convincingly defeated a world champion program" in each of the three games.[17]
OpenAI Five (2019) defeated the reigning Dota 2 world champions, team OG, winning a best-of-three exhibition 2-0 on April 13, 2019. Each of the five heroes on its team was controlled by a replica of the same neural network, trained with PPO through self-play; by OpenAI's count the final system had experienced about 45,000 years of Dota self-play over 10 real-time months. The game was played with some restrictions, including a pool of 17 of the 117 heroes. In the public OpenAI Five Arena, open from April 18 to April 21, 2019, it played 7,257 games and won 99.4% of them, losing 42; the paper notes that 3,140 of its 7,215 wins came from games that human players abandoned, which were counted as wins. The result showed that RL agents could reach the top level in a complex, partially observable, multi-agent game.[18]
AlphaStar (DeepMind, 2019) played StarCraft II, a real-time strategy game requiring long-horizon planning, imperfect information handling, and real-time decision making. In online games against human players it was rated at Grandmaster level for all three StarCraft races and above 99.8% of officially ranked human players.[26]
Voyager (Wang et al., 2023), which its authors describe as "the first LLM-powered embodied lifelong learning agent in Minecraft," played the game autonomously by querying GPT-4 as a black box, without fine-tuning the model. It combined three components: an automatic curriculum that proposed exploration tasks, an ever-growing skill library of executable code, and an iterative prompting loop that incorporated environment feedback, execution errors, and self-verification. It obtained 3.3 times more unique items, travelled 2.3 times longer distances, and unlocked key tech tree milestones up to 15.3 times faster than prior state-of-the-art methods. It was the only method in the comparison, against ReAct, Reflexion, and AutoGPT baselines, to reach the diamond level of the tech tree, which it did in one of its three runs. In a newly created Minecraft world it solved each of four unseen tasks in all three trials, while ReAct, Reflexion, and AutoGPT solved none of them within 50 prompting iterations.[19] Voyager helped popularise the idea that an LLM could serve as the policy of an open-ended agent in a simulated world.
| Agent | Game | Year | Key technique | Achievement |
|---|---|---|---|---|
| Deep Blue | Chess | 1997 | Search + evaluation | Beat world champion Kasparov 3.5-2.5 |
| AlphaGo | Go | 2016 | Neural nets + MCTS + RL | Beat Fan Hui 5-0 (2015) and 9 dan professional Lee Sedol 4-1 (2016) |
| AlphaZero | Go, chess, shogi | 2017 | Pure self-play RL | Defeated a world-champion program in each game |
| OpenAI Five | Dota 2 | 2019 | Multi-agent PPO | Beat world champion team OG 2-0 |
| AlphaStar | StarCraft II | 2019 | Multi-agent RL + imitation | Grandmaster level for all three races |
| MuZero | Atari, Go, chess, shogi | 2020 | Learned model + MCTS | Matched AlphaZero in chess and shogi and slightly exceeded it in Go without a rules simulator in its search (legal moves masked at the root); new state of the art on 57 Atari games |
| Voyager | Minecraft | 2023 | GPT-4 + skill library | Lifelong learning embodied agent |
From classical agents to LLM based agents
The post-2022 wave of agents built around large language models inherits the same abstraction but rearranges its parts. The LLM serves as the policy: given a context that encodes the agent's beliefs (transcript, retrieved documents, recent observations) and goals (system prompt, user request), it emits actions in the form of tokens, which downstream machinery decodes into tool calls or messages. The "environment" is the digital world of websites, APIs, file systems, and operating systems rather than a physical workshop.
Three patterns in particular bridge classical agent theory and the LLM era:
- ReAct (Yao et al., October 2022) interleaves explicit Thought, Action, and Observation steps in the model's output, recreating a deliberation cycle that closely resembles the classical sense-think-act loop. Released on October 6, 2022, just weeks before ChatGPT, the paper describes itself as a way for a model "to generate both reasoning traces and task-specific actions in an interleaved manner."[27] See ReAct prompting.
- Reflexion (Shinn et al., 2023) adds a verbal self-critique step: the agent reflects on task feedback, stores its reflections in an episodic memory buffer, and uses them in subsequent attempts, improving without any update to the model's weights.[28] The reflection step plays a role similar to the "critic" in Russell and Norvig's learning agent diagram.
- Tool use and function calling generalise the classical actuator abstraction: every tool with a JSON schema is a discrete action, and the model's task is to choose the next one. Toolformer (Schick et al., February 2023) showed that a language model could teach itself, in a self-supervised way, which APIs to call (a calculator, a question-answering system, search engines, a translation system, and a calendar), when to call them, and what arguments to pass.[29]
AutoGPT, an open-source project by Toran Bruce Richards whose GitHub repository was created in March 2023, drew wide attention as a demonstration that an LLM driven by a continuous loop of plan, act, and reflect could pursue open-ended goals, even though its reliability was limited; the repository had more than 180,000 GitHub stars by October 2026.[30] Subsequent systems such as Devin (announced by Cognition in March 2024), Claude Code, and Operator extended the idea into production.[40][39] The full landscape of these products, frameworks, benchmarks, and standards is covered in AI agents and Agentic AI. What matters for the conceptual definition is that all of them remain agents in the Russell and Norvig sense: percepts in, actions out, policy in between, performance measured by a goal.
Protocols, computer use, and measurement (2024 to 2026)
From late 2024 onward, much of the engineering around LLM agents went into shared interfaces: how an agent sees a computer, how it reaches tools and data, and how agents built by different companies talk to each other.
- Computer use. On October 22, 2024, Anthropic released computer use in public beta, letting developers direct Claude 3.5 Sonnet to use computers "by looking at a screen, moving a cursor, clicking buttons, and typing text."[38] OpenAI followed on January 23, 2025 with Operator, a research preview of "an agent that can use its own browser to perform tasks for you."[39] In classical terms, screenshots are the percepts and keyboard and mouse events are the actuators.
- Tool and context protocols. Anthropic introduced the Model Context Protocol (MCP) on November 25, 2024 as "an open standard that enables developers to build secure, two-way connections between their data sources and AI-powered tools."[31] On December 9, 2025, it donated MCP to the Agentic AI Foundation (AAIF), a directed fund under the Linux Foundation co-founded by Anthropic, Block, and OpenAI. At that point Anthropic counted more than 10,000 active public MCP servers and listed ChatGPT, Cursor, Gemini, Microsoft Copilot, and Visual Studio Code among the products that had adopted the protocol.[32] The specification is versioned by date; as of October 2026 the latest revision is dated July 28, 2026.[33]
- Agent-to-agent protocols. Google announced the Agent2Agent protocol (A2A) on April 9, 2025 with more than 50 technology partners. It presented A2A as a complement to MCP: MCP gives an agent tools and context, while A2A lets agents advertise their capabilities in a JSON "Agent Card" and hand tasks to one another, using existing web standards such as HTTP, SSE, and JSON-RPC.[34] The Linux Foundation launched an A2A project on June 23, 2025.[35] According to the AAIF, IBM's Agent Communication Protocol merged into A2A in August 2025, A2A v1.0, the first stable specification, shipped in March 2026, and A2A joined the AAIF as a hosted project on August 17, 2026.[36] A2A addresses much the same problem that KQML and FIPA-ACL addressed in the 1990s: a common language for agents from different builders.
- Packaged skills. Anthropic launched Agent Skills, folders built around a SKILL.md file that teach an agent a specific task, in October 2025 and published them as an open standard in December 2025. On October 22, 2026 it donated the standard to the AAIF, saying more than 70 agent platforms had integrated it.[37] As of late October 2026, the AAIF's project list includes MCP, A2A, Agent Skills, AGENTS.md, and goose, among others.[36]
- Measuring agents. METR proposed the 50%-task-completion time horizon: the length of task, measured by how long it takes skilled humans, that a model can complete with 50% success. Its paper, first released in March 2025, put Claude 3.7 Sonnet at about 50 minutes and found that the frontier time horizon had been doubling roughly every seven months since 2019, adding that the trend "may have accelerated in 2024."[41]
Agent capabilities and components
A practical agent, classical or modern, is an assembly of capabilities. The classical Russell and Norvig categorisation above describes them at a high level; the contemporary engineering view is more granular and maps cleanly onto modern frameworks.
| Capability | What it does | Classical realisation | Modern realisation in 2026 |
|---|---|---|---|
| Perception | Convert raw inputs into a usable representation | Hand-engineered sensor fusion | Text tokenisation, vision encoders, ASR, screenshot parsing |
| World modelling | Track non-observable state | Symbolic knowledge base, belief base | Context window, retrieval, scratchpad |
| Reasoning | Decide what to do given current state | First-order logic, search, planning | LLM forward pass, possibly with extended thinking |
| Planning | Decompose a goal into ordered subgoals | STRIPS, HTN, BDI plan library | Chain of thought, ReAct, tree of thoughts |
| Action | Change the environment | Effectors, API calls, robot motors | Tool calls, code execution, browser actions |
| Memory | Retain useful information across time | BDI belief base, episodic memory | Context window, vector DB, key-value store |
| Reflection | Critique own behaviour | Russell and Norvig "critic" component | Reflexion, verifier model, judge LLM |
| Communication | Talk to humans or other agents | KQML, FIPA-ACL | Chat UI, MCP, A2A protocol, structured outputs |
What is the difference between an agent and a chatbot?
The distinction between an agent and a chatbot turns on autonomous action. A chatbot answers questions and produces text in response to prompts. An agent decides on its own to call tools, take actions in external systems, and pursue multi-step goals over time. The same underlying LLM can serve both roles depending on the scaffolding around it. ChatGPT in plain conversation is a chatbot; ChatGPT with browsing, code interpreter, and the ability to navigate websites becomes an agent.
Many products blur the line. A coding assistant that suggests a single completion is a chatbot; the same product in agent mode that reads files, runs tests, and applies a multi-file refactor is an agent. The relevant question is whether the system maintains state, takes consequential actions, and makes its own decisions about what to do next. In Wooldridge and Jennings's terminology, the agent is autonomous, reactive, and proactive; the chatbot has only the first two properties to a limited degree.
History and milestones
The concept of an agent in AI has evolved across more than seven decades. The table below picks out a selection of milestones from the academic and industrial literature.
| Year | Milestone |
|---|---|
| 1950 | Alan Turing's "Computing Machinery and Intelligence" proposes the imitation game; agent-style framing is implicit |
| 1956 | Dartmouth conference establishes AI as a field; Logic Theorist embodies agent-like behaviour |
| 1966 | ELIZA at MIT, often described as the first chatbot |
| 1971 | STRIPS introduces formal planning with preconditions and effects; the Shakey robot runs it |
| 1973 | Hewitt, Bishop, and Steiger publish the actor model at IJCAI |
| 1976 | MYCIN expert system at Stanford diagnoses bacterial infections from rules |
| 1986 | Brooks introduces the subsumption architecture and behaviour-based robotics |
| 1987 | Bratman publishes Intention, Plans, and Practical Reason; Georgeff and Lansky describe the Procedural Reasoning System at AAAI-87 |
| 1990 | Brooks's "Elephants Don't Play Chess" states the physical grounding hypothesis[22] |
| 1993 | Shoham's "Agent-Oriented Programming" with AGENT0 appears in Artificial Intelligence |
| 1994 | Maes publishes "Agents that Reduce Work and Information Overload"; Finin and colleagues present KQML as an agent communication language |
| 1995 | Wooldridge and Jennings publish "Intelligent Agents: Theory and Practice"; Rao and Georgeff publish "BDI Agents: From Theory to Practice" |
| 1995 | Russell and Norvig's Artificial Intelligence: A Modern Approach (1st ed.) makes the intelligent agent the unifying theme of an AI textbook |
| 1996 | FIPA founded to standardise agent interoperability |
| 1997 | IBM Deep Blue defeats Garry Kasparov at chess 3.5-2.5 |
| 2002 | First AAMAS conference held in Bologna; FIPA's Communicative Act Library (22 communicative acts) reaches standard status |
| 2005 | FIPA becomes an IEEE Computer Society standards committee |
| 2013 | DeepMind DQN learns to play Atari games from raw pixels |
| 2015 | AlphaGo defeats European champion Fan Hui 5-0, the first time a program beat a Go professional on a full-sized board without handicap |
| 2016 | AlphaGo defeats Lee Sedol 4-1 at Go |
| 2017 | AlphaZero masters Go, chess, and shogi via self-play (preprint; Science paper 2018) |
| 2019 | OpenAI Five defeats Dota 2 world champions; AlphaStar reaches StarCraft II Grandmaster |
| Oct 2022 | ReAct paper formalises the reasoning + acting loop for LLM agents |
| Mar to Apr 2023 | AutoGPT and BabyAGI bring autonomous LLM agent loops to wide attention[30] |
| Oct 2024 | Anthropic releases computer use in public beta |
| Nov 2024 | Anthropic introduces the Model Context Protocol |
| Jan 2025 | OpenAI releases Operator as a research preview |
| Apr 2025 | Google announces the Agent2Agent protocol |
| Dec 2025 | MCP is donated to the new Agentic AI Foundation under the Linux Foundation |
| Mar 2026 | A2A v1.0, the first stable A2A specification, ships |
| Aug 2026 | A2A joins the Agentic AI Foundation as a hosted project |
| Oct 2026 | Anthropic donates the Agent Skills standard to the Agentic AI Foundation |
| 2024 to 2026 | LLM agent products go mainstream: see AI agents and Agentic AI |
Continue reading
- EnvironmentIn reinforcement learning (RL), an environment is the external system that an agent interacts with: it receives the agent's actions, transitions to a new state, and returns an observation together with a…Mentioned 34 times above
- Large Language ModelA large language model (LLM) is an artificial intelligence system built on a transformer neural network with billions to trillions of parameters, trained on massive text corpora to predict the next token in a…Mentioned 20 times above
- PolicyIn reinforcement learning (RL), a policy is the function that maps an agent's observed state to the action it takes, defining the agent's complete strategy of behavior.Mentioned 18 times above
- Model Context ProtocolModel Context Protocol (MCP) is an open protocol for exchanging context and invoking capabilities between applications that use large language models and external programs or data sources.Mentioned 10 times above
- Agentic AIAgentic AI is an umbrella term for artificial intelligence systems that pursue a user-specified objective through a sequence of decisions and actions.Mentioned 9 times above
- Reinforcement learningReinforcement learning (RL) is a branch of machine learning in which an agent learns to make decisions by taking actions in an environment to maximize a cumulative reward signal, discovering good behavior…Mentioned 8 times above
More from See also
- AI Agents
- Agentic workflow
- Multi-agent system
- Tool use
- Function calling
- ReAct (prompting)
- Harness (AI)
- Computer use
- OpenAI Operator
- Auto-GPT
- Claude Code
- Devin (AI software engineer)
- Reward
Topics:AI Agents
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Russell, S. and Norvig, P. *Artificial Intelligence: A Modern Approach* (4th ed.). Pearson, released 2020 (copyright 2021). Chapter 2: Intelligent Agents. Companion site: aima.cs.berkeley.edu ; 4th-edition preface (source of the "unifying theme" quotation): aima.cs.berkeley.edu/newchap00.pdf ; 4th-edition figures, including Figure 2.4 (PEAS description of the automated taxi) and Figure 2.6 (task environments): aima.cs.berkeley.edu/figures.pdf ; sample text of Chapter 2 from an earlier edition: aima.cs.berkeley.edu/...newchap02.pdf
- ^1 ^2 ^3Sutton, R. S. and Barto, A. G. (2018). *Reinforcement Learning: An Introduction* (2nd ed.). MIT Press. Section 3.1: The Agent-Environment Interface.
- ^1 ^2 ^3Brooks, R. A. (1986). "A Robust Layered Control System for a Mobile Robot." *IEEE Journal of Robotics and Automation*, RA-2(1), 14-23. See also Brooks, R. A. (1991), "Intelligence without representation," *Artificial Intelligence*, 47, 139-159 (PDF: people.csail.mit.edu/...representation.pdf ). Wikipedia overview: en.wikipedia.org/...Subsumption_architecture
- ^Bratman, M. E. (1987). *Intention, Plans, and Practical Reason*. Harvard University Press; reprinted by CSLI Publications, 1999. philpapers.org/...BRAIPA
- ^1 ^2 ^3Rao, A. S. and Georgeff, M. P. (1995). "BDI Agents: From Theory to Practice." *Proceedings of the First International Conference on Multi-Agent Systems* (ICMAS-95), San Francisco, June 1995, 312-319. cdn.aaai.org/...ICMAS95-042.pdf
- ^1 ^2Georgeff, M. P. and Lansky, A. L. (1987). "Reactive Reasoning and Planning." *Proceedings of AAAI-87*, Seattle. aaai.org/...AAAI87-121.pdf See also the Procedural Reasoning System overview (including the Space Shuttle reaction control system application): en.wikipedia.org/...Procedural_reasoning_system
- ^Bordini, R. H., Hubner, J. F., and Wooldridge, M. (2007). *Programming Multi-Agent Systems in AgentSpeak using Jason*. Wiley. Project: jason-lang.github.io
- ^1 ^2 ^3Shoham, Y. (1993). "Agent-Oriented Programming." *Artificial Intelligence*, 60(1), 51-92. Shoham's later overview chapter, "An Overview of Agent-Oriented Programming": infor.uva.es/...AOP-Shoham.pdf See also Shoham, Y. and Leyton-Brown, K. (2009). *Multiagent Systems: Algorithmic, Game-Theoretic, and Logical Foundations*. Cambridge University Press. masfoundations.org
- ^Hewitt, C., Bishop, P., and Steiger, R. (1973). "A Universal Modular ACTOR Formalism for Artificial Intelligence." *Proceedings of the 3rd International Joint Conference on Artificial Intelligence* (IJCAI), Stanford, August 1973, 235-245. eighty-twenty.org/...artificial%20intelligence.pdf
- ^1 ^2 ^3 ^4Wooldridge, M. and Jennings, N. R. (1995). "Intelligent Agents: Theory and Practice." *The Knowledge Engineering Review*, 10(2), 115-152. cs.cmu.edu/...woodridge_intelligent_agents.pdf (quotes Genesereth, M. R. and Ketchpel, S. P. (1994), "Software Agents," *Communications of the ACM*, 37(7), p. 48).
- ^1 ^2Maes, P. (1994). "Agents that Reduce Work and Information Overload." *Communications of the ACM*, 37(7), 30-40; the "personal assistant" passage is quoted in Middleton, S. E. (2002), "Interface agents: A review of the field," arXiv:cs/0203012, arxiv.org/...0203012 . MIT Media Lab, "Pattie Maes" profile: media.mit.edu/...overview ; "Intelligent Agent: How Pattie Maes Almost Invented Social Media," MIT Media Lab, April 25, 2022: media.mit.edu/...maes-almost-invented-social-media
- ^Finin, T., Fritzson, R., McKay, D., and McEntire, R. (1994). "KQML as an Agent Communication Language." *Proceedings of CIKM '94*. csee.umbc.edu/...kqml-acl.pdf Overview: en.wikipedia.org/...Agent_Communications_Language
- ^1 ^2 ^3FIPA (Foundation for Intelligent Physical Agents). Home page (founding in 1996; IEEE standards committee from June 8, 2005), archived: web.archive.org/...www.fipa.org ; FIPA Communicative Act Library Specification, SC00037J, standard, 2002/12/03: web.archive.org/...SC00037J.pdf ; FIPA ACL specifications: fipa.org/...aclspecs
- ^International Foundation for Autonomous Agents and Multiagent Systems (IFAAMAS), "About IFAAMAS" (AAMAS initiated in 2002 as a merger of AGENTS, ICMAS, and ATAL): ifaamas.org ; AAMAS conference history: en.wikipedia.org/..._Agents_and_Multiagent_Systems
- ^Mnih, V. et al. (2013). "Playing Atari with Deep Reinforcement Learning." *arXiv:1312.5602*. arxiv.org/...1312.5602 Followed by Mnih, V. et al. (2015). "Human-level control through deep reinforcement learning." *Nature*, 518(7540), 529-533.
- ^Campbell, M., Hoane, A. J., and Hsu, F. (2002). "Deep Blue." *Artificial Intelligence*, 134(1-2), 57-83. IBM, "Deep Blue": ibm.com/...deep-blue Match record: Deep Blue versus Garry Kasparov: en.wikipedia.org/...Deep_Blue_versus_Garry_Kasparov
- ^1 ^2Silver, D. et al. (2018). "A general reinforcement learning algorithm that masters chess, shogi, and Go through self-play." *Science*, 362(6419), 1140-1144. science.org/...science.aar6404 Accepted manuscript hosted by DeepMind: storage.googleapis.com/...alphazero_preprint.pdf See also Silver, D. et al. (2017). "Mastering the game of Go without human knowledge." *Nature*, 550(7676), 354-359.
- ^1 ^2Berner, C. et al. (2019). "Dota 2 with Large Scale Deep Reinforcement Learning." *arXiv:1912.06680*. arxiv.org/...1912.06680 Announcement (April 15, 2019): openai.com/...-five-defeats-dota-2-world-champions (archived: web.archive.org/...-defeats-dota-2-world-champions )
- ^Wang, G. et al. (2023). "Voyager: An Open-Ended Embodied Agent with Large Language Models." *arXiv:2305.16291*. arxiv.org/...2305.16291 Project: voyager.minedojo.org
- ^Russell, S. and Norvig, P. "Schools Worldwide That Have Adopted AIMA" (at least 1,556 schools in 134 countries or regions): aima.cs.berkeley.edu/adoptions ; book home page ("The authoritative, most-used AI textbook"): aima.cs.berkeley.edu ; publication history (fourth edition released April 28, 2020): en.wikipedia.org/...ntelligence:_A_Modern_Approach
- ^"AlphaGo versus Lee Sedol." Wikipedia (five-game match, Seoul, March 9-15, 2016, AlphaGo 4-1). en.wikipedia.org/...AlphaGo_versus_Lee_Sedol See also DeepMind, "AlphaGo" ("watched by over 200 million people worldwide"): deepmind.google/...alphago
- ^1 ^2 ^3Brooks, R. A. (1990). "Elephants Don't Play Chess." *Robotics and Autonomous Systems*, 6, 3-15. people.csail.mit.edu/...elephants.pdf
- ^Silver, D. et al. (2017). "Mastering Chess and Shogi by Self-Play with a General Reinforcement Learning Algorithm." *arXiv:1712.01815*, December 5, 2017. arxiv.org/...1712.01815
- ^1 ^2 ^3Silver, D. et al. (2016). "Mastering the game of Go with deep neural networks and tree search." *Nature*, 529(7587), 484-489. Published January 27, 2016. nature.com/...nature16961
- ^Schrittwieser, J. et al. (2020). "Mastering Atari, Go, chess and shogi by planning with a learned model." *Nature*, 588, 604-609. nature.com/...s41586-020-03051-4 Preprint: *arXiv:1911.08265*, arxiv.org/...1911.08265
- ^Vinyals, O. et al. (2019). "Grandmaster level in StarCraft II using multi-agent reinforcement learning." *Nature*, 575, 350-354. Published October 30, 2019. nature.com/...s41586-019-1724-z
- ^Yao, S. et al. (2022). "ReAct: Synergizing Reasoning and Acting in Language Models." *arXiv:2210.03629*, submitted October 6, 2022. arxiv.org/...2210.03629
- ^Shinn, N. et al. (2023). "Reflexion: Language Agents with Verbal Reinforcement Learning." *arXiv:2303.11366*. arxiv.org/...2303.11366
- ^Schick, T. et al. (2023). "Toolformer: Language Models Can Teach Themselves to Use Tools." *arXiv:2302.04761*. arxiv.org/...2302.04761
- ^1 ^2Significant-Gravitas/AutoGPT, GitHub repository (created March 16, 2023): github.com/...AutoGPT ; yoheinakajima/babyagi, GitHub repository (created April 3, 2023): github.com/...babyagi
- ^Anthropic, "Introducing the Model Context Protocol," November 25, 2024. anthropic.com/...model-context-protocol
- ^Anthropic, "Donating the Model Context Protocol and establishing the Agentic AI Foundation," December 9, 2025. anthropic.com/...hing-of-the-agentic-ai-foundation
- ^Model Context Protocol, "Specification," version 2026-07-28 (latest as of October 2026). modelcontextprotocol.io/...latest
- ^Google Developers Blog, "Announcing the Agent2Agent Protocol (A2A)," April 9, 2025. developers.googleblog.com/...gent-interoperability
- ^Linux Foundation, "Linux Foundation Launches the Agent2Agent Protocol Project to Enable Secure, Intelligent Communication Between AI Agents," June 23, 2025. linuxfoundation.org/...unication-between-ai-agents
- ^1 ^2Agentic AI Foundation, "A2A joins AAIF's open agentic stack," August 17, 2026. aaif.io/...a2a-joins-aaif ; AAIF project list: aaif.io
- ^Anthropic, "Donating Agent Skills to the Agentic AI Foundation," October 22, 2026. anthropic.com/...ills-to-the-agentic-ai-foundation
- ^Anthropic, "Introducing computer use, a new Claude 3.5 Sonnet, and Claude 3.5 Haiku," October 22, 2024. anthropic.com/...3-5-models-and-computer-use
- ^1 ^2OpenAI, "Introducing Operator," January 23, 2025. openai.com/...introducing-operator (archived: web.archive.org/...introducing-operator )
- ^Cognition, "Introducing Devin, the first AI software engineer," March 12, 2024. cognition.ai/...introducing-devin
- ^Kwa, T. et al. (METR) (2025). "Measuring AI Ability to Complete Long Software Tasks." *arXiv:2503.14499*. arxiv.org/...2503.14499
- ^Chen, L. et al. (2021). "Decision Transformer: Reinforcement Learning via Sequence Modeling." *arXiv:2106.01345*. arxiv.org/...2106.01345
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
15 revisions · v15 · 8,157 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Fact-checked on 2026-10-30 against Russell and Norvig (4th ed.), the original agent-theory papers, FIPA specifications, the AlphaGo, AlphaZero, MuZero and OpenAI Five papers, and primary announcements for 2024-2026 agent standards, with an independent second review.
Cite this page: AI Wiki. "Agent." aiwiki.ai, updated 30 Oct 2026, fact-checked 30 Oct 2026. CC BY 4.0. https://aiwiki.ai/wiki/agent