

Gemma 2
Gemma 2 is a family of open-weights large language models developed by Google DeepMind and released starting June 27, 2024, in three parameter sizes: 2 billion (2B), 9 billion (9B), and 27 billion (27B).[1][2] Its central claim, stated in the technical report, is that the models "offer competitive alternatives to models that are 2-3 times bigger" and "deliver the best performance for their size."[2] On the LMSYS Chatbot Arena leaderboard the Gemma 2 27B instruction-tuned model scored an Elo of 1,218, edging out LLaMA 3 70B (1,206) despite having less than half the parameters, while the 9B model matched GPT-4-0314.[10] Gemma 2 introduced four architectural changes over its predecessor: interleaved sliding window and global attention, logit soft-capping for training stability, grouped-query attention, and RMSNorm applied both before and after each sublayer; the 2B and 9B models were also trained with knowledge distillation from a larger teacher model.[2] Google released both base and instruction-tuned variants under a custom Gemma Terms of Use that permits commercial deployment.[5] The July 31, 2024 release of the 2B model was accompanied by Gemma Scope, an open collection of more than 400 sparse autoencoders for mechanistic interpretability research,[6][7] and ShieldGemma, a safety content moderation classifier built on the same weights.[8]
Background and predecessor
The Gemma model family began in February 2024, when Google DeepMind published Gemma 1 in 2B and 7B parameter sizes. That first generation used a standard decoder-only transformer architecture derived from the one underlying Gemini. Gemma 1 was notable for demonstrating that compact, openly released models could compete with models two to four times larger on standard reasoning and language benchmarks. Both base and instruction-tuned checkpoints were published under a relatively permissive custom license, enabling fine-tuning and commercial use for most applications. The initial reception was strong enough that Google committed to treating Gemma as an ongoing model family rather than a one-time release.
Despite that positive start, Gemma 1 had several constraints. Its training used roughly 6 trillion tokens for the 7B model, and the architecture did not incorporate techniques like alternating attention patterns or knowledge distillation. Context length was set at 8,192 tokens. The instruction-tuning pipeline was relatively straightforward compared to what Google applied in Gemma 2.
When was Gemma 2 released?
Gemma 2 was announced at Google I/O 2024 and formally released on June 27, 2024, with the 9B and 27B sizes immediately available.[1] The 2B model followed on July 31, 2024.[15] A Japanese-language variant, Gemma 2 JPN 2B, shipped on October 3, 2024.[4] The technical report was posted to arXiv under the identifier 2408.00118.[2]
What model sizes does Gemma 2 come in?
Gemma 2 comes in three sizes, each available in a base (pretrained) and an instruction-tuned (IT) version.[2] The instruction-tuned versions are aligned for conversational and instruction-following tasks through supervised fine-tuning (SFT), reinforcement learning from human feedback (RLHF), and model merging, in which models from runs with different hyperparameters are averaged.[2]
| Variant | Parameters | Layers | Model dimension | Attention heads | KV heads | Training tokens |
|---|---|---|---|---|---|---|
| Gemma 2 2B | 2.6 billion | 26 | 2,304 | 8 | 4 | 2 trillion |
| Gemma 2 9B | 9 billion | 42 | 3,584 | 16 | 8 | 8 trillion |
| Gemma 2 27B | 27 billion | 46 | 4,608 | 32 | 16 | 13 trillion |
All three share a vocabulary of 256,128 tokens built with SentencePiece, a context window of 8,192 tokens, RoPE (Rotary Position Embedding) positional encoding, and GeGLU activation functions.[2] The head size is 256 for the 2B and 9B models and 128 for the 27B.[2]
The 27B model was trained from scratch using standard next-token prediction.[2] The 9B and 2B models used knowledge distillation from a larger teacher model during pretraining (the report describes its target as distillation "from 27B to 9B"), learning from the teacher's output distributions rather than only from raw data targets.[2] All three underwent the same post-training alignment pipeline.
The 2B model
The 2B model, released on July 31, 2024, drew particular attention for its size-to-performance ratio.[15] With 2.6 billion parameters, it is small enough to run inference on the free tier of an NVIDIA T4 GPU and to fit comfortably on edge hardware.[16] LMSYS Chatbot Arena evaluations placed the Gemma 2 2B instruction-tuned model at an Elo of about 1,126, ahead of GPT-3.5-Turbo-0613 (1,116) and Mixtral 8x7B (1,114), the latter being a mixture-of-experts model with roughly five times as many active parameters.[2][10] On MMLU the pre-trained 2B model scored 52.2%, and on MBPP (Mostly Basic Python Programming) it reached 30.2% (36.6% for the instruction-tuned version).[2]
VentureBeat described the 2B release as a "surprising upset," citing the rarity of a sub-3B model outperforming much larger baselines on human preference evaluations.[16] The result was attributed largely to the knowledge distillation training approach, where the small model absorbed signals from a larger teacher's full output distribution rather than learning only from one-hot next-token labels.[2]
How does the Gemma 2 architecture work?
Gemma 2 shares the decoder-only transformer foundation of its predecessor but adds four architectural features not present in Gemma 1: interleaved attention patterns, logit soft-capping, grouped-query attention, and a hybrid normalization scheme.[2]
Interleaved sliding window and global attention
Every other transformer layer in Gemma 2 applies local sliding window attention, where each token can attend only to the 4,096 preceding tokens.[2] The alternating layers use standard global (full quadratic) attention across the full 8,192-token context.[2] This means the model alternates between a local view (4K window) and a global view (8K window) as tokens pass through successive layers.
The motivation is computational: self-attention scales quadratically with sequence length, so applying full attention in every layer is expensive. Using sliding window attention in half the layers reduces the total attention cost while the global layers preserve the ability to reason across distant tokens. A similar hybrid approach appeared in Mistral 7B, which applies sliding window attention uniformly rather than alternating. Gemma 2's layer-by-layer alternation differs from Mistral's uniform application; the technical report's related ablation only showed that the sliding window could be shrunk at inference time with little effect on perplexity.[2]
Logit soft-capping
Gemma 2 applies a non-linearity to attention logits before the softmax operation and again to the final vocabulary logits before the output projection.[2] The formula is:
logits <- soft_cap * tanh(logits / soft_cap)
The self-attention layers use a cap value of 50.0. The final output layer uses 30.0.[2] This operation squashes extreme logit values into a bounded range without the discontinuities introduced by hard clipping. The practical effect is a more stable loss curve during training, particularly in the early stages when logit values tend to grow rapidly.
A significant engineering consequence is that soft-capping breaks compatibility with FlashAttention and PyTorch's fused scaled-dot-product attention (SDPA), both of which assume standard unbounded logits. At release, Hugging Face recommended that users fine-tuning Gemma 2 switch to eager (unfused) attention, which uses more GPU memory and runs more slowly, and this was a common point of friction for practitioners.[3] FlashAttention 2.6 later added soft-capping support for Gemma 2.[20]
Grouped-query attention
All three Gemma 2 sizes use grouped-query attention (GQA) with two query heads per key-value head pair (num_groups=2).[2] Standard multi-head attention (MHA) maintains separate key and value tensors for every attention head, which grows the key-value cache proportionally with the number of heads and the sequence length. GQA reduces this by having multiple query heads share a single key and value head. At num_groups=2, the KV cache is roughly half the size of what standard MHA would require, which translates directly to lower GPU memory usage during inference and enables higher batch sizes or longer sequences on the same hardware.
Post-norm and pre-norm hybrid
Gemma 2 applies RMSNorm to both the input (pre-norm) and the output (post-norm) of each attention and feedforward sublayer.[2] Most contemporary decoder-only models use only pre-norm. The report says the dual normalization is used to stabilize training.[2]
WARP model merging for alignment
For the final instruction-tuned models, Google averaged models obtained by running the post-training pipeline with different hyperparameters, citing WARP (Weight Averaged Rewarded Policies), a Google DeepMind merging method for reinforcement learning from human feedback.[2] As described in its own paper, WARP uses an exponential moving average of the policy as an anchor for KL regularization, merges independently fine-tuned policies with spherical linear interpolation (SLERP), and then interpolates the merged model back toward its initialization to recover pre-training knowledge. The Gemma 2 report does not detail how much of this recipe was used or publish a merged-versus-unmerged comparison.
What data was Gemma 2 trained on?
The 27B model trained on approximately 13 trillion tokens, making it one of the most extensively trained models in its parameter class at the time of release.[2] The 9B model used 8 trillion tokens and the 2B model 2 trillion tokens.[2] All three corpora draw from web documents (primarily English-language), code repositories, and scientific articles.[2] The exact data mix, filtering methodology, and source proportions were not disclosed, consistent with Google's general practice for Gemini-family training.
Data processing reused Gemma 1's filtering: removing unwanted or unsafe utterances and certain personal or sensitive information, decontaminating evaluation sets from the pre-training mix, and reducing the risk of recitation.[2] The SentencePiece tokenizer uses a 256,128-token vocabulary, considerably larger than the 32,000 tokens in Llama 2 or the 50,257 in GPT-2-era models.[2] The enlarged vocabulary helps the model handle non-English text, programming languages, and mathematical notation more efficiently, because common multi-character patterns in those domains are represented as single tokens rather than character sequences.
Knowledge distillation during pretraining
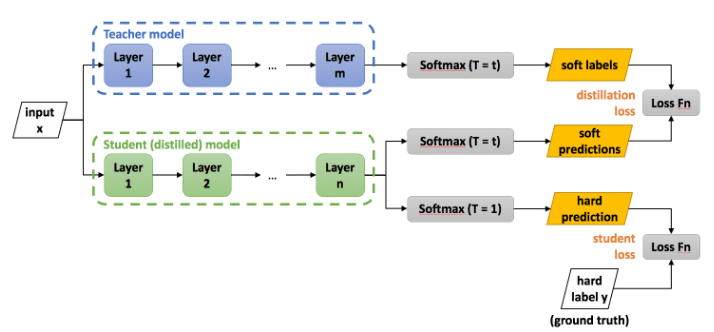
For the 9B and 2B models, the pretraining objective was augmented with knowledge distillation from the 27B teacher.[2] Rather than training only on the binary signal of whether the model predicted the correct next token, the smaller models were trained to match the full probability distribution the teacher assigned to all tokens at each position. The loss function minimizes the KL divergence between teacher and student distributions, computed over the same training corpus.
This approach, sometimes called token-level distillation, provides a richer training signal than standard cross-entropy on one-hot targets. The teacher's distribution encodes information about which tokens are nearly correct alternatives, which is information that gets discarded in standard language modeling. The benefit was quantified in the technical report: a 2B model trained with distillation for 500 billion tokens averaged 67.7 on three evaluation benchmarks, compared to 60.3 for the same model trained without distillation, a difference of about 12% in relative terms.[2]
Post-training pipeline
All Gemma 2 sizes underwent a multi-stage post-training pipeline:[2]
- Supervised fine-tuning on curated conversational datasets covering question answering, instruction following, and multi-turn dialogue.
- On-policy distillation, where the student model generates completions for SFT prompts and the teacher scores those completions. This reduces the mismatch between teacher signals (computed on reference completions) and student behavior (computed on its own generated text).
- Reinforcement learning with a reward model trained on human preference data, combined with WARP merging to stabilize the result.
The teacher model for post-training distillation was not named in the report; Hugging Face's launch write-up guessed it was Gemini Ultra.[3]
Training infrastructure
Training used Google Cloud TPU pods of different generations by model size: TPUv5e (512 chips arranged in a 2x16x16 configuration) for the 2B model, TPUv4 (4,096 chips in an 8x16x32 configuration) for the 9B, and TPUv5p (6,144 chips in an 8x24x32 configuration) for the 27B.[2] All training ran on JAX with the ML Pathways system for distributed computation.[2] Total reported carbon emissions were approximately 1,247.61 tCO2eq across all three models, produced at Google's carbon-neutral data centers.[2]
Is Gemma 2 open source? Terms of Use and licensing
Gemma 2 is distributed under the Gemma Terms of Use, a custom license that permits commercial use but differs from standard open-source licenses such as Apache 2.0 or MIT.[5] It is therefore best described as open-weights rather than open-source in the OSI sense. The key provisions are:
- Users may use, reproduce, modify, distribute, and create derivative works from the models.[5]
- Commercial deployment is permitted with no user count thresholds or scaling fees.[5]
- Redistributors must include the Gemma Terms of Use as an enforceable provision in downstream agreements and must include a notice that the model is subject to those terms.[5]
- Google claims no rights in outputs generated using Gemma; users own generated content.[5]
- Usage is subject to a Prohibited Use Policy covering harms to minors, critical infrastructure attacks, and other standard categories.[5]
- Google may revoke a user's rights if it determines a violation of the Prohibited Use Policy or applicable law.[5]
The revocation provision was the most-discussed limitation. Unlike Apache 2.0, which grants irrevocable rights once distributed, the Gemma license lets Google remotely restrict access. In practice this provision was rarely invoked, but it meant that enterprises with strict procurement requirements around irrevocable licenses could not adopt Gemma 2 under the same terms they might accept for an Apache-licensed model.
The custom Gemma Terms of Use carried forward through Gemma 3, which Google released on March 12, 2025, and which retained the same non-OSI license rather than switching to Apache 2.0.[18] The move to a fully permissive license came later: Gemma 4, announced on April 2, 2026, was the first generation in the family released under the OSI-approved Apache 2.0 license, removing the custom restrictions.[19] Gemma 2 remains under the original custom terms.
What is Gemma Scope?
Alongside the Gemma 2 models, Google DeepMind released Gemma Scope, an open collection of sparse autoencoders (SAEs) trained on the internal activations of Gemma 2.[6] The goal is to support mechanistic interpretability research: the practice of reverse-engineering what computations a neural network performs, rather than studying its external input-output behavior only.
Sparse autoencoder techniques for language models work by training an auxiliary model to reconstruct a target layer's activations as a sparse linear combination of learned feature vectors. Because the reconstruction must be sparse, the learned features tend to be interpretable concepts rather than statistical noise. Each feature can be inspected by finding the inputs that maximally activate it, which often reveals that a given feature corresponds to a recognizable concept such as a person's name, a syntactic pattern, or a topic domain.
Gemma Scope trained SAEs at every layer and sublayer of Gemma 2 2B and Gemma 2 9B, and at selected layers of Gemma 2 27B.[7] The resulting collection comprises more than 400 individual autoencoders with more than 30 million total learned features.[7] Training the suite required over 20% of the compute used to train GPT-3, and the team stored roughly 20 pebibytes of intermediate activations to disk.[7] The JumpReLU SAE architecture was selected because it achieves a better balance between detecting feature presence and estimating feature magnitude than standard ReLU-based SAEs.[7] The weights were released under a permissive CC-BY-4.0 license.[7]
Google DeepMind described Gemma Scope as "a collection of hundreds of freely available, open sparse autoencoders" for Gemma 2.[6] Weights were published on Hugging Face under the google/gemma-scope repository.[13] The Neuronpedia platform provided an interactive web interface for browsing learned features without requiring a local GPU.[6] The technical paper was posted to arXiv as 2408.05147.[7]
Intended use cases include studying how models represent factual knowledge, analyzing where unsafe behaviors originate in the computation graph, investigating chain-of-thought faithfulness, and detecting deceptive reasoning. The scale of the Gemma Scope release made it possible for small research groups to conduct mechanistic interpretability experiments that would have required significant proprietary infrastructure to replicate from scratch.
Gemma Scope 2, released on December 19, 2025 for the Gemma 3 family,[4] extended coverage to all Gemma 3 model sizes (270M to 27B) and added transcoders, which model how activations in one layer are transformed to produce activations in the next, enabling analysis of computational flow rather than static representations alone.
What is ShieldGemma?
ShieldGemma is a suite of safety content moderation classifiers released by Google alongside the Gemma 2 family.[8] The models are fine-tuned from Gemma 2 base weights to classify text inputs and outputs for four harm categories: sexually explicit content, dangerous or harmful content, hate speech, and harassment.[8] ShieldGemma is available in 2B, 9B, and 27B parameter sizes, matching the Gemma 2 family.[9]
The classifier is designed for two deployment patterns. In the pre-filter configuration, ShieldGemma processes incoming user messages before they reach the main generation model, blocking requests classified as harmful above the operator's chosen threshold. In the post-filter configuration, it screens the model's responses before they are returned to the user.[9] Both patterns can be used simultaneously for defense in depth.
Unlike binary classifiers that output only a harmful/not-harmful label, ShieldGemma outputs a probability score for each harm category, giving operators control over the sensitivity-specificity tradeoff for their specific application.[8]
On public safety benchmarks, the 9B ShieldGemma scored 10.8% higher average AU-PRC (area under the precision-recall curve) than the original Llama Guard, and its F1 score exceeded WildGuard's by 4.3%.[8] The technical paper was posted to arXiv as 2407.21772.[8]
Limitations documented in the ShieldGemma paper include label discrepancies when identity groups are swapped, difficulty grasping implicit harm within cultural contexts, policy interpretations that may be overly conservative and hurt helpfulness, and the risk of unsafe output if the classifier is used as a chat model.[8] ShieldGemma is included in Google's Responsible Generative AI Toolkit alongside other safety and evaluation resources.[11]
How does Gemma 2 perform on benchmarks?
The following tables present Gemma 2 performance on standard academic benchmarks as reported in the technical report (arXiv:2408.00118).[2] Base model results use few-shot prompting. Chatbot Arena scores reflect human preference ratings collected by LMSYS.[10]
Pre-trained model benchmarks
| Benchmark | Gemma 2 2B | Gemma 2 9B | Gemma 2 27B | Llama 3 8B | Llama 3 70B |
|---|---|---|---|---|---|
| MMLU (5-shot) | 52.2% | 71.3% | 75.2% | 66.6% | 79.2% |
| GSM8K (5-shot) | 24.3% | 68.6% | 74.0% | 45.7% | 76.9% |
| MATH (4-shot) | 16.0% | 36.6% | 42.3% | -- | -- |
| HumanEval (0-shot) | 20.1% | 40.2% | 51.8% | -- | -- |
| ARC-Challenge | 55.7% | 68.4% | 71.4% | 59.2% | 68.8% |
| HellaSwag | 72.9% | 81.9% | 86.4% | 82.0% | 88.0% |
| Winogrande | 71.3% | 80.6% | 83.7% | 76.1% | 85.3% |
Comparison with similar-size models (9B class)
| Benchmark | Mistral 7B | Llama 3 8B | Gemma 2 9B |
|---|---|---|---|
| MMLU | 62.5% | 66.6% | 71.3% |
| GSM8K | 39.6% | 45.7% | 68.6% |
| ARC-Challenge | 60.5% | 59.2% | 68.4% |
| HellaSwag | 83.0% | 82.0% | 81.9% |
| Winogrande | 78.5% | 76.1% | 80.6% |
Chatbot Arena Elo ratings (instruction-tuned models, July 2024)
Chatbot Arena ratings are derived from head-to-head human preference votes using the Bradley-Terry model. The Gemma 2 27B instruction-tuned model exceeded Llama 3 70B (a model with more than twice the parameters) by 12 Elo points.[10] Gemma 2 9B matched GPT-4-0314.[10] Gemma 2 2B surpassed both GPT-3.5-Turbo and Mixtral 8x7B.[10] In its launch announcement, Google's launch post said the 27B model "offers competitive alternatives to models more than twice its size."[1]
How does Gemma 2 compare to Llama 3 and Mistral 7B?
LLaMA 3, released by Meta in April 2024, and Mistral 7B, released by Mistral AI in September 2023, represent the two most widely used open-weights baselines at the time of Gemma 2's release.[12]
| Dimension | Mistral 7B | Llama 3 8B | Gemma 2 9B | Llama 3 70B | Gemma 2 27B |
|---|---|---|---|---|---|
| Parameters | 7B | 8B | 9B | 70B | 27B |
| Context window | 32K | 8K | 8K | 8K | 8K |
| Training tokens | Not disclosed | 15T | 8T | 15T | 13T |
| MMLU | 62.5% | 66.6% | 71.3% | 79.2% | 75.2% |
| GSM8K | 39.6% | 45.7% | 68.6% | 76.9% | 74.0% |
| License | Apache 2.0 | Llama 3 Community | Gemma ToU | Llama 3 Community | Gemma ToU |
| Architecture | Sliding window | Dense transformer | Hybrid attention | Dense transformer | Hybrid attention |
Gemma 2 9B outperformed Mistral 7B on every reported benchmark except HellaSwag, where Mistral 7B held a narrow margin of 83.0% to 81.9%.[12] The gap on math and reasoning was large: Gemma 2 9B scored 68.6% on GSM8K compared to 39.6% for Mistral 7B.[2] Against LLaMA 3 8B, Gemma 2 9B led on every shared benchmark except HellaSwag (81.9% to 82.0%).[2] Gemma 2 27B came within a few points of Llama 3 70B on most tasks despite having 2.5 times fewer parameters and training on 2 trillion fewer tokens.
Mistral 7B retains a significant advantage in context length: its 32K window (versus Gemma 2's 8K) supports tasks involving long documents, codebases, or extended multi-turn conversations that exceed what Gemma 2 can process. Mistral 7B also distributes under Apache 2.0, offering irrevocable commercial rights. Llama 3's community license imposes restrictions on redistribution for applications with more than 700 million monthly active users, a threshold well above what most organizations encounter but a consideration for large-scale deployment.
What is Gemma 2 used for?
Gemma 2 was designed with practical deployment efficiency as a core goal. The 27B model runs at full precision on a single NVIDIA A100 80GB or H100 GPU, or on a single Google Cloud TPU host.[1] The 9B model requires approximately 18 GB of VRAM, fitting on high-end consumer cards including the NVIDIA RTX 4090 (24 GB) and the RTX 3090 (24 GB). With 4-bit quantization via GGUF or GPTQ formats, the 27B model compresses to roughly 18 GB, enabling it to run on the same hardware as the unquantized 9B.
Documented deployment use cases include:
- Text generation, summarization, and question answering in enterprise chatbots where organizations want to run inference on-premises to avoid sending sensitive data to external APIs.
- Code assistance, where the 9B and 27B models perform competitively on HumanEval and MBPP for organizations operating in air-gapped or high-security environments.
- Domain-specific fine-tuning using QLoRA (quantized low-rank adaptation) or full fine-tuning. The 9B model's relatively modest hardware requirements make it practical to fine-tune on a single A100 80GB GPU in a few hours for many task types.
- On-device and edge inference using GGUF-quantized variants through llama.cpp and Ollama, which run Gemma 2 on consumer laptops including Apple Silicon MacBooks and Windows laptops with NVIDIA RTX cards.
- Interpretability research using Gemma Scope, with the complete SAE weights enabling experiments on feature discovery, circuit analysis, and safety research without requiring original training infrastructure.
- Multilingual adaptation, where community fine-tuners applied continuous pre-training on non-English corpora to extend Gemma 2's primarily English capabilities to target languages.[17]
The instruction-tuned models use a chat template with <start_of_turn> and <end_of_turn> tokens marking speaker boundaries, which maps straightforwardly onto Hugging Face Transformers chat template formats and is supported natively in Ollama and llama.cpp.[3]
Adoption
Gemma 2 integration across the open model ecosystem moved quickly after the June 2024 release. Hugging Face Transformers added support in version 4.42, and all six canonical model variants (base and instruction-tuned across three sizes) were hosted in the google organization on Hugging Face.[3] The Text Generation Inference (TGI) server added Gemma 2 support for high-throughput production deployments.[3] Google AI Studio provided free access to the instruction-tuned 9B and 27B models, and Kaggle hosted the models with notebook integration for experimentation.[1]
Community fine-tuned variants appeared within days of the initial release. The Gemmaverse, Google's informal name for the community ecosystem around Gemma models, accumulated hundreds of derivative checkpoints on Hugging Face within the first few months. Notable community derivatives built on Gemma 2 included:
- SEA-LION V3, a Southeast Asian language model from the AI Singapore team that used Gemma 2 9B as a base for continuous pre-training on multilingual Southeast Asian corpora, improving performance on Indonesian, Thai, Vietnamese, and other regional languages.[17]
- BgGPT, INSAIT's Bulgarian model built on Gemma 2 27B, which continued pre-training on roughly 85 billion Bulgarian tokens using a combination of continued pre-training, instruction fine-tuning, and model merging techniques presented at EMNLP 2024.[17]
Google published Gemma.cpp as a dedicated C++ inference engine for the Gemma architecture, and compatibility was added to vLLM for high-throughput batched serving. GGUF-quantized community releases for llama.cpp and Ollama appeared within hours or days of each official Google release.
Vertex AI added Gemma 2 to its model garden for managed enterprise deployment, with monitoring and access control capabilities not available in self-hosted configurations.[14] By the time Gemma 3 was announced in early 2025, the Gemma 2 models had accumulated millions of downloads across Hugging Face and Kaggle.
Reception
Gemma 2 received broadly positive coverage from the AI research and developer community at launch. The Chatbot Arena results attracted particular attention because they demonstrated that parameter count is not the primary determinant of human preference ratings when architecture and training methodology are both improved.[10] On Hacker News, several commenters noted that the 27B model's Elo score exceeding Llama 3 70B was a more informative result than standard benchmark scores because it reflected real user preference rather than curated academic tasks.
The Gemma Scope release was described by the interpretability research community as a significant contribution.[6] The scale of the SAE collection (400+ autoencoders, 30 million features) was beyond what any individual lab had previously made available in open form.[7] Researchers noted that having SAEs trained at every layer and sublayer of 2B and 9B models enabled types of circuit analysis that had previously been feasible only at small scales or on proprietary infrastructure.
ShieldGemma received more mixed commentary. The performance improvements over prior safety classifiers were acknowledged, but the paper itself warned that the models' interpretation of policy violations may be overly conservative and advised operators to tune thresholds.[8] Setting the right safety principle description to get consistent results required iteration that was not always straightforward.
Some reviews focused on the Gemma Terms of Use. The commercial permissions were seen as adequate for most use cases, but the revocation provision was flagged as a structural difference from Apache 2.0 that made Gemma 2 less suitable for enterprise deployments where legal counsel required irrevocable rights.[5] This was frequently contrasted with Mistral AI's fully permissive licensing approach.
Gemma 2 also generated significant discussion about what the distillation results imply for the practical value of scaling pretraining compute. The paper's ablation showed a distilled 2B student clearly beating the same model trained from scratch on the same 500 billion tokens, and the authors presented distillation as a way to simulate training beyond the number of available tokens.[2] This was taken as evidence that access to a strong teacher model may matter as much as raw scale, a point with implications for how organizations without frontier-model training budgets should approach model development.
Limitations
Context window
All Gemma 2 models are capped at an 8,192-token context window.[2] This is identical to Llama 3 8B at release, but substantially shorter than the 32K offered by Mistral 7B and far below the 128K or longer contexts provided by Claude 3, GPT-4 Turbo, and later models. Tasks involving long documents, full codebases, multi-document research summaries, or extended dialogue histories are constrained by this limit. The sliding window attention mechanism operates efficiently within 8K but does not provide a path to extending the effective context at inference time without retraining.
Gemma 3, released by Google DeepMind in March 2025, extended the context window to 128K tokens for its 4B, 12B and 27B models (the 1B model supports 32K), directly addressing this gap.[18]
Training data transparency
The technical report describes the training corpus as web documents, code, and scientific articles with English-primary coverage, but does not disclose source proportions, filtering criteria, or specific datasets.[2] This limits the ability of external researchers to audit for data contamination on benchmarks, identify demographic or cultural biases, or assess the representation of specific domains. The opacity is consistent across the Gemma and Gemini families and reflects Google's standard practice, but it differs from more transparent documentation in some contemporaneous releases.
English-language bias
The primary English-language training corpus means Gemma 2 performs unevenly on non-English tasks.[2] The Gemma 2 JPN 2B variant addressed Japanese specifically, but no equivalent targeted release was made for other languages at launch.[4] Community projects like SEA-LION and INSAIT's BgGPT partially filled this gap through continued pre-training, but these required additional resources to produce and were not available at release.[17]
FlashAttention incompatibility
At release, the logit soft-capping design meant Gemma 2 could not use FlashAttention or PyTorch SDPA for fine-tuning, so Hugging Face recommended eager attention, which is slower and uses more GPU memory.[3] FlashAttention 2.6 later added soft-capping support.[20] This practical constraint was a recurring topic in community discussions around fine-tuning Gemma 2, especially for the 27B model where memory pressure is already significant.
End-to-end task performance
The technical report's dangerous-capability evaluations found Gemma 2 27B weak on autonomous end-to-end tasks: it passed none of 10 self-proliferation challenges end-to-end (completing 22 of 45 intermediate milestones) and could not complete the easiest one, installing a Bitcoin wallet.[2] This limitation was present across open models at the time and was not unique to Gemma 2, but it is worth noting as a constraint on agentic use cases.
Continue reading
- Gemma(first-generation Gemma models, February 2024)Mentioned 119 times above
- Llama 3Llama 3 is a family of open-weight large language models developed by Meta. Meta released the original Llama 3 checkpoints on April 18, 2024, in 8-billion-parameter and 70-billion-parameter sizes.Mentioned 17 times above
- Mistral 7BMistral 7B is a 7.3-billion-parameter, decoder-only large language model released by mistral ai on September 27, 2023, under the Apache 2.0 license.Mentioned 11 times above
- Google DeepMindGoogle DeepMind is an artificial intelligence research and model-development organization at Google.Mentioned 7 times above
- Knowledge DistillationKnowledge distillation is a training method in which a student model learns from signals produced by a teacher model.Mentioned 6 times above
- Gemini (language model)(Google DeepMind's proprietary model family)Mentioned 4 times above
More from See also
More to read
Topics:AI ModelsGoogleGoogle DeepMindLarge Language ModelsOpen Source AISmall Language Models
References
- ^1 ^2 ^3 ^4 ^5Google DeepMind. "Google launches Gemma 2, its next generation of open models." Google Blog, June 27, 2024. blog.google/...google-gemma-2
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32 ^33 ^34 ^35 ^36 ^37 ^38 ^39 ^40 ^41 ^42Gemma Team, Google DeepMind. "Gemma 2: Improving Open Language Models at a Practical Size." arXiv:2408.00118, 2024. arxiv.org/...2408.00118
- ^1 ^2 ^3 ^4 ^5 ^6Hugging Face. "Welcome Gemma 2 - Google's new open LLM." Hugging Face Blog, 2024. huggingface.co/...gemma2
- ^1 ^2 ^3Google AI for Developers. "Gemma releases." ai.google.dev/...releases
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Google AI for Developers. "Gemma Terms of Use." ai.google.dev/...terms
- ^1 ^2 ^3 ^4 ^5Google DeepMind. "Gemma Scope: helping the safety community shed light on the inner workings of language models." DeepMind Blog, August 2024. deepmind.google/...ner-workings-of-language-models
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Lieberum, Tom et al. "Gemma Scope: Open Sparse Autoencoders Everywhere All At Once on Gemma 2." arXiv:2408.05147, 2024. arxiv.org/...2408.05147
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Zeng, Wenjun et al. "ShieldGemma: Generative AI Content Moderation Based on Gemma." arXiv:2407.21772, 2024. arxiv.org/...2407.21772
- ^1 ^2Google AI for Developers. "ShieldGemma model card." ai.google.dev/...model_card
- ^1 ^2 ^3 ^4 ^5 ^6 ^7LMSYS Chatbot Arena. Leaderboard scores, July 2024. chat.lmsys.org
- ^Google Developers Blog. "Smaller, Safer, More Transparent: Advancing Responsible AI with Gemma." developers.googleblog.com/...onsible-ai-with-gemma
- ^1 ^2Novita AI Blog. "Gemma 2 vs Llama 3: Which Model Is Better for You in 2024?" blogs.novita.ai/...model-is-better-for-you-in-2024
- ^Hugging Face. google/gemma-scope model card. huggingface.co/...gemma-scope
- ^Google DeepMind. "Gemma model page." deepmind.google/...gemma
- ^1 ^2The Next Web. "Google DeepMind launches 2B parameter Gemma 2 model." July 31, 2024. thenextweb.com/...pmind-2b-parameter-gemma-2-model
- ^1 ^2VentureBeat. "Google's tiny AI model 'Gemma 2 2B' challenges tech giants in surprising upset." 2024. venturebeat.com/...tech-giants-in-surprising-upset
- ^1 ^2 ^3 ^4Google Developers Blog. "Beyond English: How Gemma open models are bridging the language gap." developers.googleblog.com/...ing-gemma-open-models
- ^1 ^2Google. "Introducing Gemma 3." Google Blog, March 12, 2025. blog.google/...gemma-3
- ^Google Open Source Blog. "Gemma 4: Expanding the Gemmaverse with Apache 2.0." April 2, 2026. opensource.googleblog.com/...averse-with-apache-20
- ^1 ^2Dao-AILab. "FlashAttention" README (changelog entry "2.6: Softcapping"). GitHub. github.com/...flash-attention
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
9 revisions · v9 · 5,343 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (130 claims, 24 sources fetched); 15 material + 23 minor fixed
Cite this page: AI Wiki. "Gemma 2." aiwiki.ai, updated 28 Oct 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/gemma_2