

GraphRAG
GraphRAG is a graph-based approach to retrieval-augmented generation developed by Microsoft Research, first described publicly on February 13, 2024 and formalized in the paper "From Local to Global: A Graph RAG Approach to Query-Focused Summarization" (arXiv:2404.16130), submitted April 24, 2024.[1][2] Rather than retrieving text chunks by semantic similarity alone, GraphRAG uses a large language model to build a knowledge graph from source documents, detects communities of related entities using the Leiden algorithm, generates hierarchical natural-language summaries of those communities, and uses that structured representation at query time. Microsoft describes it as a system that "uses LLM-generated knowledge graphs to provide substantial improvements in question-and-answer performance when conducting document analysis of complex information."[2] The result is a system that can answer both narrow factual questions and broad, corpus-wide sensemaking questions that defeat conventional vector search.
Across Microsoft's published evaluations, GraphRAG beat a conventional vector-RAG baseline on the comprehensiveness and diversity of answers at roughly a 70-80% win rate (formally 72 to 83% on comprehensiveness and 62 to 82% on diversity, p < .01 or better).[1][3] Microsoft released the system as open-source software under the MIT License at github.com/microsoft/graphrag on July 2, 2024.[3][8] On November 25, 2024, the same team published LazyGraphRAG, a cheaper variant that defers almost all LLM use to query time; Microsoft reports its "data indexing costs are identical to vector RAG and 0.1% of the costs of full GraphRAG."[4]
What problem does GraphRAG solve?
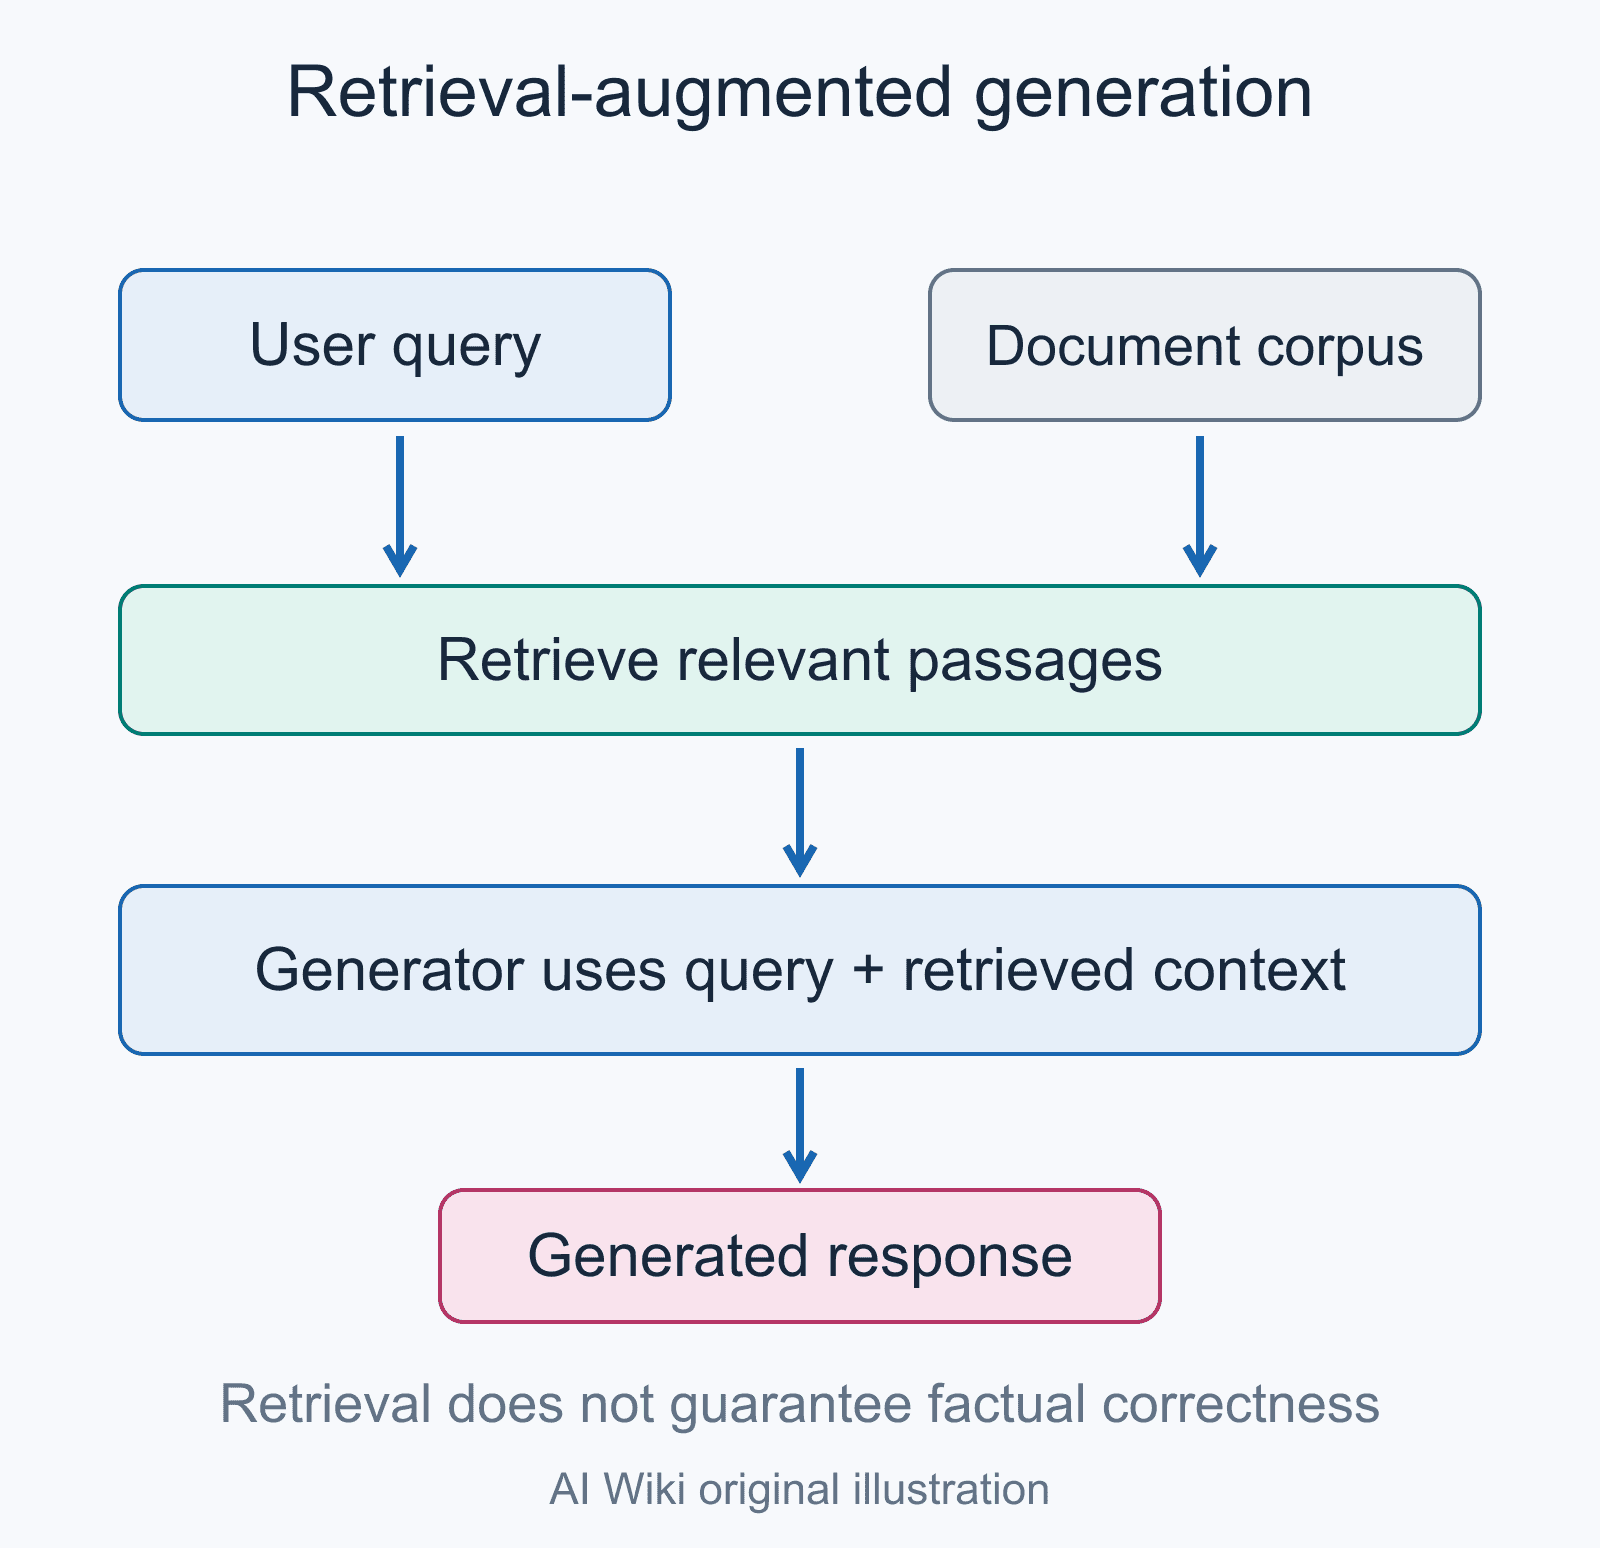
Conventional retrieval-augmented generation works by splitting documents into fixed-size text chunks, embedding each chunk with a vector embedding model, and storing the resulting vectors in an index. When a user poses a query, the system converts that query into a vector and retrieves the chunks whose embeddings are closest by cosine similarity. The retrieved chunks are then injected into an LLM prompt to generate a final answer.
This architecture works well for queries where the answer is localized: a user asking "What year was the Eiffel Tower built?" will find the relevant sentence in whichever chunk contains that sentence. The vector similarity between the question and the answer-containing passage is high enough to reliably surface it.
The architecture struggles with what Microsoft researchers call global sensemaking questions: queries directed at the corpus as a whole rather than at specific passages within it. The GraphRAG paper states the failure mode directly: "RAG fails on global questions directed at an entire text corpus, such as 'What are the main themes in the dataset?', since this is inherently a query-focused summarization (QFS) task, rather than an explicit retrieval task."[1] Questions such as "What are the dominant themes in this dataset of financial reports?" or "How do the different authors in this archive disagree on climate policy?" require synthesizing information scattered across thousands of documents. No single chunk contains the answer; the answer is a property of the corpus in aggregate. Retrieving the top-k closest chunks does not solve this problem because relevance by chunk similarity does not correspond to relevance for a corpus-level question.
A second class of failures involves relationship queries: finding that Entity A and Entity B are related through a chain of intermediate entities that are never mentioned together in any single passage. Microsoft observed that baseline RAG "struggles to connect the dots" when "answering a question requires traversing disparate pieces of information."[2] Vector search retrieves individual passages, not relationship chains, so multi-hop reasoning is difficult to perform reliably.
GraphRAG was designed specifically to address the global sensemaking failure mode while preserving the ability to answer local, entity-specific questions.
The GraphRAG paper
The paper "From Local to Global: A Graph RAG Approach to Query-Focused Summarization" was submitted to arXiv on April 24, 2024 (revised February 19, 2025) by Darren Edge, Ha Trinh, Newman Cheng, Joshua Bradley, Alex Chao, Apurva Mody, Steven Truitt, Dasha Metropolitansky, Robert Osazuwa Ness, and Jonathan Larson, affiliated with Microsoft Research, Microsoft Strategic Missions and Technologies, or the Microsoft Office of the CTO.[1]
The paper frames the problem as query-focused summarization over private text corpora that can run into the millions of tokens. Standard RAG, the paper argues, treats all questions as local retrieval problems, and prior query-focused summarization methods "do not scale to the quantities of text indexed by typical RAG systems."[1] The contribution of GraphRAG is to provide a principled path for global questions by building a structured, hierarchical representation of the corpus before any query arrives. The authors summarize the two-stage indexing approach as using an LLM "first, to derive an entity knowledge graph from the source documents, then to pregenerate community summaries for all groups of closely related entities."[1]
The evaluation used two datasets: podcast transcripts from "Behind the Tech with Kevin Scott" (approximately 1 million tokens, yielding a graph of 8,564 nodes and 20,691 edges after indexing) and a set of news articles spanning September 2013 through December 2023 (approximately 1.7 million tokens, 15,754 nodes, 19,520 edges).[1] The team tested multiple conditions, labeling them C0 through C3 to represent progressively finer levels of the community hierarchy, alongside a source-text map-reduce baseline (TS) and a vector RAG semantic search baseline (SS).
All GraphRAG conditions substantially outperformed vector RAG on comprehensiveness (72 to 83% win rates, p < .001 across datasets) and on diversity of perspectives (62 to 82% win rates).[1] Vector RAG scored higher on directness, which the authors treated as a validation control: a system that retrieves a close passage should indeed give a more directly targeted answer to a local question, while GraphRAG's broader synthesis produces more comprehensive but less tightly focused responses. Root-level community summaries (C0) required 97% fewer tokens per query than source-text summarization, while the most detailed level (C3) still required 26 to 33% fewer tokens than the naive summarization baseline.[1]
The paper also introduced a second evaluation approach based on counting factual claims extracted from each answer. LLM judgment of comprehensiveness aligned with claim-count comprehensiveness at a 78% rate, giving the evaluation some validation beyond pure LLM preference.[1]
How does the GraphRAG architecture work?
GraphRAG's architecture has two distinct phases: an indexing pipeline that runs once per corpus and a query engine that runs at request time.[6] The indexing pipeline is computationally expensive and involves multiple LLM calls over every text unit in the corpus. The query engine consults the pre-built structures and uses a smaller number of LLM calls to synthesize an answer.
Entity and relationship extraction
The first substantive step of the indexing pipeline is splitting source documents into text units. The default chunk size in the Microsoft implementation is 1,200 tokens (the paper used 600-token chunks with 100-token overlaps).[1][6] Each text unit is then processed by an LLM to extract a structured list of entities (people, organizations, locations, concepts, events) along with the relationships between them and concise descriptions of each. A self-reflection prompt is used after the initial extraction to ask the model whether any entities or relationships were missed, improving recall at the cost of additional LLM calls.
Because the same real-world entity may appear under different names across different text units ("Microsoft," "Microsoft Corporation," "MSFT"), a deduplication and merging step consolidates entity descriptions. Multiple descriptions extracted from different text units are summarized by the LLM into a single canonical description per entity and per relationship. The result is a unified knowledge graph covering the entire corpus.
The paper notes that this extraction is domain-sensitive. The system ships with auto-tuning tooling that generates corpus-specific prompts to improve extraction quality for specialized text (legal documents, scientific papers, clinical notes, and so on).[5]
Knowledge graph construction
The extracted entities and relationships form the nodes and edges of a property graph. Each node carries its canonical description. Each edge carries a description of the relationship, the strength of that relationship (derived from how many text units co-mention the two entities), and the source text units that support it. Optional claim extraction (disabled by default) can attach covariates to entities, such as time-bounded assertions about the entity's state.[6]
The graph is stored as a set of tables (entities, relationships, covariates, communities, community reports, and text units) rather than as a native graph database, making the system compatible with standard data infrastructure. Third-party integrations with Neo4j, LangChain, and LlamaIndex allow teams to store and query these structures using graph databases if preferred.
Community detection with the Leiden algorithm
Once the knowledge graph is built, GraphRAG applies the Leiden algorithm to partition the graph into communities of closely related entities.[9] Leiden is an improvement over the older Louvain algorithm that addresses a specific failure mode: Louvain can produce internally disconnected communities, where nodes in the same community are not reachable from each other. Leiden guarantees that every identified community is internally connected, producing a more coherent grouping.[9]
Leiden is also inherently hierarchical. Running the algorithm recursively produces a community tree: the root level (level 0) holds the fewest, broadest communities, and each lower level recursively partitions those communities into smaller sub-communities until reaching leaf communities that can no longer be partitioned.[1] Microsoft describes this stage as "bottom-up clustering that organizes the data hierarchically into semantic clusters," which "allows for pre-summarization of semantic concepts and themes."[2] This hierarchy directly maps to the C0-C3 conditions evaluated in the paper: C0 uses the root-level communities, C1 is one level down, C2 and C3 are progressively finer.
The hierarchical structure is important because it controls the tradeoff between comprehensiveness and token cost at query time. Querying C0 (root-level summaries) consumes very few tokens per query but may lose fine-grained detail. Querying C3 (lowest-level summaries) produces more nuanced answers but requires processing many more summaries.
Hierarchical summaries
For each community at every level of the hierarchy, the pipeline makes one or more LLM calls to generate a natural-language community report. These reports describe the key entities in the community, the principal relationships among them, and the major themes or findings that emerge from combining the extracted information. An executive summary is written for the community as a whole, followed by more detailed subsections covering individual entities and relationships.
The community reports are the core retrieval unit for global search. Because they are precomputed, they are available instantly at query time without any additional LLM calls for summarization. The tradeoff is that they encode a snapshot of the corpus at indexing time; if the corpus changes, the reports must be regenerated for affected communities.
After community summarization, the pipeline generates vector embeddings for text units, entity descriptions, and community reports. These embeddings support semantic search during local queries, where the system needs to find entities or passages that are semantically similar to the user's question.
How do local search and global search differ?
GraphRAG ships with three primary query modes, each suited to a different class of question.
Global search addresses corpus-wide sensemaking questions. When a user submits a query, the system retrieves community reports from an appropriate level of the hierarchy and generates partial answers from each relevant report in parallel. As the paper puts it, "each community summary is used to generate a partial response, before all partial responses are again summarized in a final response to the user."[1] These partial answers are aggregated through a second LLM call (a reduce step) into a final, synthesized answer. Partial answers that are scored as unhelpful by the LLM are discarded before reduction. Because every community at the queried level is consulted, global search can draw on information from anywhere in the corpus, at the cost of processing many summaries.
Local search addresses entity-specific questions. It begins with a vector similarity search over entity descriptions to identify entities most relevant to the query, then retrieves those entities' direct relationships, neighboring entities, associated community reports, and the source text units that support them. All of this context is combined into an LLM prompt capped at 12,000 tokens by default (configurable).[6] Local search is faster and cheaper than global search but cannot synthesize information from parts of the graph that are not directly connected to the seed entities.
DRIFT search (Dynamic Reasoning and Inference with Flexible Traversal), introduced on October 31, 2024, combines elements of both modes.[7][13] It first performs a semantic search over community reports to establish an initial broad answer, then uses that answer to generate follow-up questions, which are executed as local searches in parallel. The parallel local results are re-ranked and merged to form the final answer. In Microsoft's test on more than 5,000 AP news articles with 50 local questions, DRIFT beat local search on comprehensiveness 78% of the time and on diversity 81% of the time.[13]
Indexing pipeline costs and timing
The indexing pipeline is the primary cost driver for GraphRAG. Every text unit in the corpus must be processed by an LLM for entity extraction (with self-reflection), entity merging requires additional LLM summarization calls, and community report generation adds one more round of LLM calls per community across the full hierarchy.
The paper reported that indexing the 1-million-token podcast dataset using GPT-4-turbo took 281 minutes on a 16 GB RAM machine.[1] Community detection uses the graspologic library and runs locally without LLM calls, so its cost is comparatively negligible.
Realworld cost reports from early users varied widely based on model choice and corpus size. Using GPT-4-turbo or GPT-4o, indexing a corpus in the hundreds of thousands of words cost tens to hundreds of dollars in API fees. Using cheaper models (GPT-4o-mini, open-source models via local inference) substantially reduces cost but may degrade extraction quality.
LangChain, LlamaIndex, and the official Python package all allow using any OpenAI-compatible API, which means teams can route calls through locally hosted models to avoid per-token charges entirely.
What is LazyGraphRAG?
LazyGraphRAG was announced on November 25, 2024, in a Microsoft Research blog post by Darren Edge, Ha Trinh, and Jonathan Larson, the same core team that published the original GraphRAG paper.[4]
The central observation motivating LazyGraphRAG is that the expensive parts of standard GraphRAG (LLM-based entity extraction and LLM-based community summarization) happen entirely at indexing time. If a team only needs to run a few queries over a corpus, paying the full indexing cost is not justified. LazyGraphRAG removes those steps from the indexing phase and defers all LLM use to query time.
During indexing, LazyGraphRAG uses NLP noun phrase extraction (not an LLM) to identify concepts in text units and builds a concept co-occurrence graph from those noun phrases. Community structure is derived from the co-occurrence graph using the same Leiden algorithm, but without LLM-generated community reports. The result, in Microsoft's words, is that LazyGraphRAG's "data indexing costs are identical to vector RAG and 0.1% of the costs of full GraphRAG."[4]
At query time, LazyGraphRAG generates 3 to 5 subqueries from the user's question using an LLM. For each subquery, it ranks text chunks by vector similarity, then ranks communities by aggregating the ranks of their top-k chunks. It then uses an LLM to assess sentence-level relevance within those communities, recursing into sub-communities when a given community does not contain relevant content, and terminating when the relevance test budget is exhausted or no relevant communities remain. This "iterative deepening" combines best-first and breadth-first traversal, concentrating LLM calls on the portions of the graph most likely to contain useful information.[4]
The evaluation on 5,590 AP news articles with 100 synthetic queries (50 local, 50 global) showed that at a relevance test budget of 500 (the Z500 configuration), LazyGraphRAG significantly outperformed all eight competing conditions tested, including plain vector RAG, RAPTOR, full GraphRAG global search, and DRIFT search, on both local and global query types.[4] Microsoft reports that this happens "for 4% of the query cost of GraphRAG global search."[4] At a budget of 100 (Z100_Lite), it still matched or exceeded most baselines at a fraction of their cost. The team summarized the result as showing "that it is possible for a single, flexible query mechanism to substantially outperform a diverse range of specialized query mechanisms."[4]
The main tradeoff is that LazyGraphRAG does all of its LLM work at query time, so its per-query cost rises with the relevance test budget. Microsoft nonetheless measured the Z500 configuration at 4% of the query cost of GraphRAG global search, and the Z100_Lite configuration at the same cost as vector RAG retrieving 8k tokens.[4]
As of June 2025, LazyGraphRAG had been integrated into Microsoft Discovery, an agentic platform for scientific research built on Azure, and into Azure Local services as part of a public preview.[4]
How does GraphRAG compare with vector RAG and hybrid RAG?
The table below summarizes key differences between plain vector RAG, GraphRAG, and hybrid approaches that combine the two.
| Dimension | Vector RAG | GraphRAG | Hybrid RAG |
|---|---|---|---|
| Index structure | Dense vector index | Knowledge graph + community hierarchy + vectors | Vector index + knowledge graph |
| Indexing cost | Low | High (many LLM calls) | Medium |
| Local (entity) queries | Strong | Strong (local search mode) | Strong |
| Global (corpus-wide) queries | Weak | Strong (global search mode) | Variable |
| Multi-hop reasoning | Weak | Strong | Strong |
| Relationship queries | Weak | Strong | Strong |
| Latency per query | Low | Medium to high | Medium |
| Corpus update handling | Easy (re-embed changed chunks) | Expensive (re-extract and re-summarize) | Partial |
| Hallucination risk | Moderate | Moderate (LLM extraction introduces noise) | Moderate |
| Transparency | Low (black-box similarity) | Medium (graph is inspectable) | Medium |
Vector RAG's primary advantage is simplicity and cost. It requires no domain-specific configuration, indexes quickly, and handles corpus updates by re-embedding only the changed chunks. It consistently outperforms GraphRAG on directness for local factual questions because the nearest-neighbor retrieval is well-matched to that query type.[1]
GraphRAG's advantage grows with query complexity and corpus size. For questions that require synthesizing information across many documents or understanding global patterns in data, standard vector RAG accuracy drops substantially. Vendor benchmarks point the same way. Diffbot's 2023 KG-LM benchmark of enterprise questions, as summarized by the graph-database company FalkorDB, reported 16.7% accuracy for an LLM without knowledge-graph grounding versus 56.2% with it, and found accuracy without a knowledge graph falling to 0% once a query involved more than five entities; that benchmark tested knowledge-graph grounding in general rather than Microsoft's GraphRAG.[14]
Hybrid approaches combine a vector index with a knowledge graph, using techniques like Reciprocal Rank Fusion (RRF) to merge the ranked results from both retrieval systems. This gives strong performance on both local and relational queries at the cost of maintaining two separate indices and pipelines. LangChain, LlamaIndex, and Neo4j all provide hybrid RAG implementations that incorporate GraphRAG-style knowledge graphs.
Is GraphRAG open source, and what tools support it?
The reference implementation is the official Microsoft Python package at github.com/microsoft/graphrag, released under the MIT License on July 2, 2024.[3][8] It provides CLI tools for indexing (graphrag index), query (graphrag query), and prompt auto-tuning (graphrag prompt-tune), and stores outputs as Parquet files that can be consumed by downstream systems. The package is available via pip (pip install graphrag). The July 2024 announcement noted that the code repository is complemented by "a solution accelerator" providing an API experience hosted on Azure that can be deployed in a few clicks.[3]
Neo4j has published detailed integration guides showing how to load GraphRAG's Parquet outputs into a Neo4j graph database and expose them through LangChain or LlamaIndex retrievers.[10] Because Neo4j stores the entities and relationships natively, it can apply Cypher queries to the knowledge graph in addition to the standard GraphRAG search modes, enabling more precise relational traversals.
LangChain supports GraphRAG through its graph-aware document loaders and retriever abstractions. Teams can connect LangChain chains to a GraphRAG-built Neo4j instance, a FalkorDB instance, or any other graph store, and compose those retrievers with other LangChain components such as memory modules or agent executors.
LlamaIndex provides a GraphRAG cookbook and PropertyGraph abstractions that integrate with Neo4j.[11] The cookbook implements the extraction, Leiden community detection, and community summarization steps in Python on top of LlamaIndex's property graph abstractions.
FalkorDB, NebulaGraph, and Memgraph also promote their graph databases as GraphRAG backends. Microsoft also published a GraphRAG solution accelerator for deploying the pipeline on Azure.[3]
Beyond the official implementation, the broader research community has developed variants. RAPTOR (Recursive Abstractive Processing for Tree-Organized Retrieval, Stanford 2024) independently converged on a similar idea of recursive summarization, though it builds trees rather than graphs. HippoRAG and PathRAG are other graph-based retrieval variants that optimize different aspects of the traversal. OG-RAG uses ontology grounding during extraction to reduce hallucinations by constraining entity types to a predefined schema.
What is GraphRAG used for?
GraphRAG's design makes it particularly well-suited to a specific set of information retrieval problems.
Question answering over large private corpora is the primary use case described in the original paper. Internal corporate knowledge bases, archives of customer support tickets, collections of legal documents, and repositories of scientific literature all share the property that useful information is distributed across many documents and that users need answers requiring synthesis across that distribution. A legal team querying a contract archive for clauses with a particular risk profile, or a researcher asking what an archive of clinical trial reports says about a particular mechanism, benefit from the global summarization capabilities that GraphRAG provides.
Thematic analysis and corpus summarization are tasks where GraphRAG's community hierarchy is directly useful even without a specific question. Running global search at the root community level effectively generates an executive summary of the entire corpus organized around the principal entity clusters. News archives, corporate strategy documents, and academic literature collections can be mapped in this way without manual curation.
Competitive intelligence and investigative research involve building a picture of how organizations, people, products, and events relate to each other across many documents. Because the knowledge graph explicitly encodes these relationships, multi-hop queries ("What organizations does Person A fund that also partner with Organization B?") are tractable in a way they are not with pure vector search.
Streaming and exploratory data analysis is a use case better served by LazyGraphRAG than by standard GraphRAG. When a corpus is changing frequently or when only a handful of queries will be run, the up-front indexing cost of standard GraphRAG is not justified. LazyGraphRAG's near-zero indexing cost and flexible quality-cost tradeoff via the relevance budget make it well suited to one-off analyses.
Cost considerations
For teams evaluating GraphRAG for production deployment, cost deserves careful analysis at both the indexing and query stages.
At indexing time, the dominant cost driver is the number of LLM calls multiplied by the cost per token of the chosen model. Costs scale roughly linearly with corpus size, so a corpus 100 times larger costs on the order of 100 times more to index with the same model. Using a local or open-source model reduces this to infrastructure cost only.
At query time, global search is more expensive than local search because it processes many community summaries. A single global search query can consume thousands of tokens in processing community reports, while a local search query is bounded by the context window of a single LLM call. Teams with high query volume and a stable corpus will generally find that the per-query cost of global search justifies the up-front indexing investment once the query count is high enough to amortize it.
LazyGraphRAG's 0.1% indexing cost changes the economics substantially for low-query-volume use cases.[4] The tradeoff is that per-query cost at the Z500 budget level is higher than a plain vector RAG query (because multiple LLM relevance tests are run), although Microsoft measured it at 4% of the query cost of GraphRAG global search.[4]
Several optimization strategies have been documented by practitioners. Reducing the chunk overlap (or setting it to zero) decreases the number of extraction calls. Using a cheaper model for entity extraction and a stronger model only for community summarization and query answering captures most of the quality benefit at reduced cost. Selective re-indexing (re-running extraction only on newly added documents rather than the full corpus) reduces update costs for growing corpora.
Limitations
GraphRAG has several practical limitations that constrain its applicability.
High indexing cost is the most frequently cited barrier to adoption. For teams exploring a new dataset or running exploratory analyses, paying the full indexing cost before seeing any results is a significant commitment. LazyGraphRAG mitigates this but does not fully eliminate it for all deployment scenarios.
Graph extraction quality is sensitive to the quality of the underlying LLM and to the domain of the text. General-purpose extraction prompts may miss specialized entities or relationships in technical domains. The auto-tuning system helps, but tuning requires running the pipeline on a sample of the target corpus, which adds a setup step before production use.
Corpus staleness is a problem for any system that relies on a precomputed index. When source documents change, the extracted graph, community structure, and community reports must all be updated. Unlike vector RAG, where updating requires only re-embedding the changed chunks, GraphRAG updates may cascade: a change in one document affects extraction of entities and relationships, which may alter community membership, which may require re-generating community reports for affected communities. The official package added an incremental graphrag update command in version 0.4.0 (November 2024), which reduces but does not remove this cost.[15]
Hallucination risk exists at each LLM-mediated step: entity extraction, relationship extraction, entity description summarization, and community report generation all involve LLM calls that can introduce errors or fabrications. Because the knowledge graph is built from LLM-extracted content rather than from exact text, errors made during indexing are encoded into the permanent structure of the graph and propagate into query answers. Post-extraction verification tooling is available but not yet standard practice.
Latency is higher than vector RAG for complex queries. Global search queries process many community summaries in parallel, which requires multiple LLM calls even with batching. On a large corpus, a global search query can take tens of seconds.
The system is primarily designed for text corpora. Structured data (tables, databases), code repositories, or multi-modal content (images, audio) require additional preprocessing or specialized extraction pipelines that are not included in the standard implementation.
Future directions
Microsoft's published roadmap and research blog posts point to several active development areas.
Dynamic community selection has already moved from research into the library. Rather than pre-selecting a fixed community level (C0, C1, C2, C3), dynamic global search uses an LLM to rate community reports for relevance and descends only into the children of relevant ones. A November 2024 Microsoft Research post reported answer quality comparable to static global search at an average 77% lower token cost, and moderate, statistically significant gains when the search was allowed to go deeper.[12]
Incremental indexing, allowing the graph to be updated with new documents without full re-indexing, is a practical engineering priority cited repeatedly by the community. The official package has supported incremental indexing since version 0.4.0 (November 2024) through the graphrag update command, which merges new documents into an existing index; third-party implementations have proposed other approaches.[15]
Multi-modal GraphRAG is an area of active interest. Extending entity extraction to images, audio transcripts, and structured tables would allow the knowledge graph to capture relationships across heterogeneous data types, which is a common requirement in domains like medical research, where information appears in both clinical notes and imaging reports.
Agent integration is a natural extension. LLM agents that have access to a GraphRAG knowledge graph can use the graph as a structured external memory, querying it as one tool among many. Mem0 and similar memory management systems provide related infrastructure for persistent agent memory; combining these with GraphRAG's structured representation is an active research direction.
Scalability beyond the million-token range is another open question. The original paper evaluated on corpora up to 1.7 million tokens. Corpora of hundreds of millions of tokens (enterprise document repositories, legal archives, entire scientific fields) require architectural changes to the extraction and community detection pipelines to remain tractable.
Continue reading
- Knowledge graphA knowledge graph is a structured representation of real-world entities and the relationships between them, organized as a network of interconnected nodes and edges.Mentioned 16 times above
- LangChainLangChain is an open-source software framework for applications that use large language models.Mentioned 7 times above
- LlamaIndexLlamaIndex is an open-source data framework for building large language model (LLM) applications, with a particular focus on retrieval-augmented generation (RAG) and document processing.Mentioned 6 times above
- Microsoft ResearchMicrosoft Research (MSR) is Microsoft's industrial research organization. Established in 1991, it conducts fundamental and applied research in computing and other sciences through regional laboratories and…Mentioned 4 times above
- Retrieval-Augmented GenerationRetrieval-augmented generation (RAG) is a family of methods that retrieves information from an external collection and conditions a generative model on that information when producing an output.Mentioned twice above
- Vector embeddingsVector embeddings are dense numerical representations of objects (text, images, audio, video, code, graphs, or any structured data) that map them into a continuous vector space such that semantic similarity…Mentioned twice above
More from See also
More to read
Topics:AI InferenceInformation RetrievalMicrosoftOpen Source AI
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15Edge, D., Trinh, H., Cheng, N., Bradley, J., Chao, A., Mody, A., Truitt, S., Metropolitansky, D., Ness, R. O., & Larson, J. (2024). From Local to Global: A Graph RAG Approach to Query-Focused Summarization. arXiv:2404.16130. arxiv.org/...2404.16130
- ^1 ^2 ^3 ^4Larson, J., & Truitt, S. (2024, February 13). GraphRAG: Unlocking LLM discovery on narrative private data. Microsoft Research Blog. microsoft.com/...scovery-on-narrative-private-data
- ^1 ^2 ^3 ^4 ^5Microsoft Research. (2024, July 2). GraphRAG: New tool for complex data discovery now on GitHub. microsoft.com/...plex-data-discovery-now-on-github
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11Edge, D., Trinh, H., & Larson, J. (2024, November 25). LazyGraphRAG: Setting a new standard for quality and cost. Microsoft Research Blog. microsoft.com/...new-standard-for-quality-and-cost
- ^Microsoft. (2024). GraphRAG documentation. microsoft.github.io/graphrag
- ^1 ^2 ^3 ^4Microsoft. (2024). GraphRAG: Default dataflow. microsoft.github.io/...default_dataflow
- ^Microsoft. (2024). DRIFT Search. microsoft.github.io/...drift_search
- ^1 ^2Microsoft. (2024). GraphRAG GitHub repository (MIT License). github.com/...graphrag
- ^1 ^2Traag, V. A., Waltman, L., & van Eck, N. J. (2019). From Louvain to Leiden: guaranteeing well-connected communities. Scientific Reports, 9, 5233. doi.org/...s41598-019-41695-z
- ^Bratanic, T. (2024). Integrating Microsoft GraphRAG into Neo4j. Neo4j Developer Blog. neo4j.com/...microsoft-graphrag-neo4j
- ^LlamaIndex. (2024). GraphRAG Implementation with LlamaIndex - V2. developers.llamaindex.ai/...graphrag_v2
- ^Microsoft Research. (2024). GraphRAG: Improving global search via dynamic community selection. microsoft.com/...h-via-dynamic-community-selection
- ^1 ^2Microsoft Research. (2024, October 31). Introducing DRIFT Search: Combining global and local search methods to improve quality and efficiency. microsoft.com/...to-improve-quality-and-efficiency
- ^Shubeli, G. (2025, April 7). How GraphRAG Outperforms Vector Search in Enterprise LLM Accuracy. FalkorDB Blog. falkordb.com/...graphrag-accuracy-diffbot-falkordb
- ^1 ^2Microsoft. (2024, November 6). GraphRAG v0.4.0 release notes ("Add Incremental Indexing"). github.com/...v0.4.0
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
6 revisions · v6 · 4,952 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (120 claims, 24 sources fetched); 6 material + 15 minor fixed
Cite this page: AI Wiki. "GraphRAG." aiwiki.ai, updated 1 Nov 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/graphrag