

MNIST
The Modified National Institute of Standards and Technology (MNIST) database is a collection of 70,000 grayscale images of handwritten digits (0 through 9) that has served as one of the most widely used benchmarks in machine learning and computer vision. Each image is 28 by 28 pixels, and the dataset is split into 60,000 training examples and 10,000 test examples. Created by Yann LeCun, Corinna Cortes, and Christopher J.C. Burges, MNIST was first released in 1998 and remains a standard first exercise for students learning deep learning and neural networks.
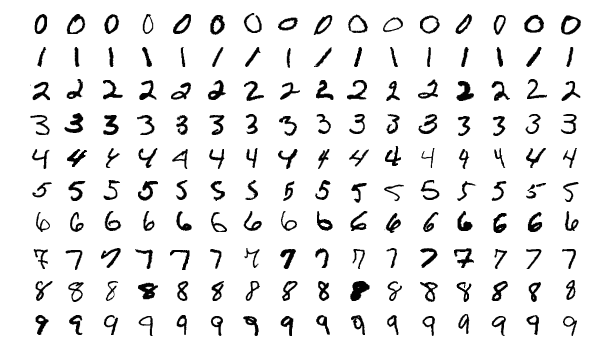
MNIST's simplicity, small size, and ease of use have made it ubiquitous, but its difficulty has been exhausted: the best published systems reach roughly 99.91% accuracy (a 0.09% error rate), close to the estimated human error rate of about 0.2%.[5][15][16] Because modern algorithms routinely exceed 99.5% accuracy, researchers have increasingly turned to more challenging alternatives such as Fashion-MNIST, EMNIST, and CIFAR-10. The foundational paper associated with the dataset, "Gradient-based learning applied to document recognition" (LeCun et al., 1998), has accumulated over 64,000 citations on Semantic Scholar as of November 2026, making it one of the most cited works in the history of artificial intelligence.[1]
ELI5 (Explain like I'm 5)
Imagine you have a big box of flashcards, and each flashcard has a number written on it by hand, anywhere from 0 to 9. Some people write their numbers in neat, tidy ways, and others write them all wobbly and messy. There are 70,000 flashcards in the box. Scientists use these flashcards to teach computers how to read handwritten numbers. The computer looks at thousands of flashcards, learns what each number looks like, and then tries to guess the number on flashcards it has never seen before. MNIST is basically that box of flashcards, and it has been the most popular box for testing whether a computer is good at reading numbers.
What is MNIST used for?
MNIST is primarily a research and educational benchmark for training and comparing image classification models. The underlying task, handwritten digit recognition, also has several real-world applications, and MNIST itself is the canonical "hello world" dataset of deep learning: nearly every major framework (TensorFlow, PyTorch, Keras) ships it in an introductory tutorial. In the words of its creators, MNIST "is a good database for people who want to try learning techniques and pattern recognition methods on real-world data while spending minimal efforts on preprocessing and formatting."[3]
History and origins
When was MNIST created?
MNIST was constructed before the summer of 1994 and first distributed publicly in 1998 alongside the LeNet-5 work on convolutional neural networks. It was assembled from two earlier NIST handwriting databases to fix a distribution-shift problem in those source sets.[3]
NIST source databases
In the late 1980s, the United States Census Bureau needed automated systems to read handwritten census forms. The Bureau partnered with the National Institute of Standards and Technology (NIST) to develop optical character recognition (OCR) tools, and NIST created several handwriting databases to support this effort.[2]
- Special Database 1 (SD-1): Released in May 1990, SD-1 contained segmented data entry fields from handwriting sample forms completed by approximately 2,100 Census Bureau field workers during the 1990 census.
- Special Database 3 (SD-3): Released in February 1992, SD-3 contained 223,125 binary 128x128 pixel digit images, along with upper-case and lower-case letter images, also written by Census Bureau employees.
- Special Database 7 (SD-7, also called TD-1): Released in April 1992, SD-7 contained 58,646 digit images written by approximately 500 high school students in Bethesda, Maryland.
NIST originally designated SD-3 as a training set and SD-7 (TD-1) as a test set. However, researchers discovered a serious distribution mismatch: SD-3 was written entirely by Census Bureau employees, while SD-7 was written by high school students.[5] Models trained on SD-3 often saw their error rates jump from under 1% to around 10% when evaluated on SD-7, illustrating the distribution shift problem.[3]
Construction of MNIST
The MNIST dataset was constructed before summer 1994 to address the distribution shift between NIST databases. LeCun and collaborators mixed samples from both SD-3 and SD-7 (which the original MNIST documentation calls SD-1)[11] so that the training and test sets each contained digits from a diverse pool of writers.[3]
The 500 high-school writers of the NIST test set were split in half: digits from the first 250 went into the new training set and digits from the other 250 into the new test set, giving nearly 30,000 examples each. Each set was then filled out to 60,000 images with Census Bureau digits from SD-3. Only 10,000 of the 60,000 test images were ever distributed: the first 5,001 come from the 250 high-school test writers and the remaining 4,999 from 48 Census Bureau employees. The original documentation summarizes this as 30,000 training and 5,000 test patterns from each source.[3][11]
Image preprocessing
The original NIST binary images were 128x128 pixels. To create MNIST, each digit was processed through several steps:[3]
- Size normalization: Each digit was fit into a 20x20 pixel bounding box while preserving its original aspect ratio.
- Anti-aliasing: The size normalization process introduced grayscale values through anti-aliasing, converting the originally binary images into 8-bit grayscale (0 to 255).
- Centering: The 20x20 normalized digit was placed inside a 28x28 pixel field by computing the center of mass of the pixels and translating the image so that the center of mass coincided with the center of the 28x28 field.
This preprocessing pipeline reduced spatial variance and ensured consistent formatting across all samples.
Dataset structure
Composition
| Property | Value |
|---|---|
| Total images | 70,000 |
| Training set | 60,000 images |
| Test set | 10,000 images |
| Image dimensions | 28 x 28 pixels |
| Color space | Grayscale (8-bit, values 0-255) |
| Number of classes | 10 (digits 0-9) |
| Source databases | NIST SD-3 and SD-7 (TD-1), the latter called SD-1 in the original documentation |
| Writers (training) | 250 high-school writers (SD-7) plus Census Bureau employees (SD-3) |
| Writers (test, released 10,000) | 250 high-school writers (SD-7) plus 48 Census Bureau employees (SD-3) |
| File format | IDX (custom binary) |
| License | Creative Commons Attribution-Share Alike 3.0 |
The digit classes are roughly balanced, though not perfectly equal. Each pixel value ranges from 0 (white/background) to 255 (black/foreground).
IDX file format
MNIST data is stored in the IDX binary format, a simple format for vectors and multidimensional matrices. The dataset consists of four files:[4]
| File | Contents | Size |
|---|---|---|
train-images-idx3-ubyte.gz | Training set images | ~9.9 MB |
train-labels-idx1-ubyte.gz | Training set labels | ~29 KB |
t10k-images-idx3-ubyte.gz | Test set images | ~1.6 MB |
t10k-labels-idx1-ubyte.gz | Test set labels | ~5 KB |
Each IDX file begins with a magic number header. The first two bytes are always zero. The third byte encodes the data type (0x08 for unsigned byte). The fourth byte indicates the number of dimensions (3 for image files, 1 for label files). Following the header, dimension sizes are stored as 4-byte big-endian integers, and then the raw data follows in row-major order.
Benchmark results
MNIST has served as a proving ground for nearly every major classification algorithm developed since the late 1990s. The table below summarizes notable benchmark results reported on the official MNIST test set.[3][5]
| Classifier | Error rate (%) | Year | Notes |
|---|---|---|---|
| Linear classifier (1-layer NN) | 12.0 | 1998 | No preprocessing |
| K-nearest neighbors (L2) | 5.0 | 1998 | Baseline, no preprocessing |
| K-nearest neighbors (non-linear deformation, P2DHMDM) | 0.52 | 2007 | Shiftable-edges preprocessing (Keysers et al.) |
| Support vector machine (Virtual SVM) | 0.56 | 2002 | Degree-9 polynomial kernel, 2-pixel jitter, deskewing (DeCoste and Scholkopf) |
| 2-layer NN, 300 hidden units | 4.7 | 1998 | Standard MLP |
| 2-layer NN, 800 hidden units | 1.6 | 2003 | Cross-entropy loss (Simard et al.) |
| LeNet-1 | 1.7 | 1998 | Early CNN architecture |
| LeNet-5 | 0.95 | 1998 | Classic CNN |
| Boosted LeNet-4 | 0.7 | 1998 | Ensemble boosting with distortions |
| LIRA neural classifier | 0.42 | 2004 | Associative neural classifier |
| Large CNN, unsupervised pretraining | 0.39 | 2006 | Data augmentation with elastic distortions (Ranzato et al.) |
| Committee of 35 CNNs | 0.23 | 2012 | Multi-column deep neural network (MCDNN) by Ciresan et al. |
| DropConnect ensemble (5 CNNs) | 0.21 | 2013 | Regularization variant |
| Batch-normalized Maxout Network in Network | 0.24 | 2015 | No data augmentation |
| Committee of 20 CNNs with SE blocks | 0.17 | 2020 | Squeeze-and-Excitation blocks, data augmentation |
| Ensemble of 3 simple CNNs (3x3/5x5/7x7 kernels) | 0.09 | 2020 | Two-layer homogeneous ensemble, 99.91% accuracy (An et al.) |
| Single CNN (branching/merging) | 0.17 | 2021 | Advanced single-model architecture |
A simple linear classifier can reach about 88% accuracy (12% error) without any feature engineering, while modern deep learning models with ensembles and heavy data augmentation have pushed error rates as low as 0.09%, equivalent to 99.91% accuracy.[15] The human error rate on MNIST is estimated at around 0.2%, meaning the best machines now exceed typical human performance on this task.[16]
Role in deep learning history
MNIST played a significant role in demonstrating the practical viability of neural networks during a period when the field was largely out of favor. In the late 1990s, support vector machines dominated supervised learning research, and many researchers considered neural networks impractical. LeCun's work on LeNet-5, trained and benchmarked on MNIST, showed that convolutional neural networks could match or outperform SVMs on real-world pattern recognition tasks.[3]
The 1998 paper "Gradient-based learning applied to document recognition" by LeCun, Bottou, Bengio, and Haffner introduced the LeNet-5 architecture and demonstrated end-to-end trainable systems for document recognition. LeNet was adopted commercially by NCR to read the amounts on handwritten checks, first in ATMs and from 1996 in bank back-office check readers that by 2001 handled an estimated 10% of US checks; its 1989 precursor had been developed on handwritten zip codes supplied by the United States Postal Service. These deployments helped sustain interest in neural networks in the early 2000s, when the approach was out of favor.[17]
MNIST's role as a shared benchmark allowed researchers to compare approaches objectively. When deep learning experienced a resurgence after 2012, MNIST remained a standard baseline test for new architectures, optimizers, and regularization techniques. Nearly every major deep learning framework (TensorFlow, PyTorch, Keras) includes MNIST in its introductory tutorials.
Applications
Although MNIST is primarily used as a research and educational benchmark, the underlying task of handwritten digit recognition has several real-world applications:
- Postal automation: Recognizing handwritten zip codes on envelopes to automate mail sorting. LeCun's 1989 convolutional network, the precursor of LeNet, was developed on zip-code digits from the U.S. Postal Service.[5]
- Banking and finance: Automatically reading handwritten amounts on checks and deposit slips. LeNet systems were deployed in ATMs and bank check-reading machines by NCR.[17]
- Document digitization: Extracting handwritten numbers from invoices, receipts, tax forms, and census documents.
- Education: MNIST is widely used in university courses and online tutorials as a first exercise in building and training neural networks, CNNs, and other classifiers.
Criticisms and limitations
Despite its historical significance, MNIST has faced sustained criticism from the research community for several reasons:
Why is MNIST considered too easy for modern methods?
Modern convolutional neural networks routinely achieve above 99.5% accuracy on MNIST. Even simple models, such as logistic regression or a small fully connected network, can reach 97% or higher. Because nearly all architectures perform well on MNIST, the dataset provides little discriminative power for comparing different approaches. In an April 2017 Twitter thread, Google Brain research scientist Ian Goodfellow called for people to move away from the benchmark, observing that "instead of moving on to harder datasets than MNIST, the ML community is studying it more than ever."[8] Francois Chollet, the creator of Keras, wrote the same day that "many good ideas will not work well on MNIST (e.g. batch norm)," while many bad ideas may work on MNIST and not transfer to real computer vision, a critique that directly motivated Zalando Research to release Fashion-MNIST as a harder drop-in replacement.[7][8]
Limited diversity
The handwriting samples come from a narrow demographic, primarily Census Bureau employees and American high school students. The writing styles are relatively uniform compared to the global diversity of handwriting. Models trained on MNIST may not generalize well to handwritten digits from other populations or written in different contexts.[3][11]
Small and low-resolution images
At 28x28 pixels in grayscale, MNIST images are tiny by modern standards. Real-world digit recognition often involves higher-resolution, color images with complex backgrounds, noise, and varying lighting conditions that MNIST does not capture.
Known labeling errors
Researchers have documented at least four incorrect labels in the MNIST dataset. While four errors out of 70,000 is a tiny fraction, this has prompted discussion about data quality standards in benchmark datasets.[5]
Lack of real-world complexity
MNIST digits are pre-segmented, centered, size-normalized, and presented on a clean white background. Real-world digit recognition requires handling segmentation, variable-size inputs, cluttered backgrounds, and connected or overlapping characters. Success on MNIST does not necessarily translate to success in production OCR systems.
MNIST variants and alternatives
The limitations of MNIST have motivated the creation of numerous alternative datasets that follow the same 28x28 grayscale format but present more challenging classification tasks.
Fashion-MNIST
Fashion-MNIST, introduced by Zalando Research in 2017, is a drop-in replacement for MNIST. It contains 70,000 grayscale images (60,000 training, 10,000 test) of 10 categories of clothing and accessories: T-shirt/top, trouser, pullover, dress, coat, sandal, shirt, sneaker, bag, and ankle boot. Fashion-MNIST is significantly harder than MNIST; state-of-the-art models achieve roughly 96-97% accuracy compared to 99.7%+ on the original.[8]
EMNIST
The Extended MNIST (EMNIST) dataset, introduced by Cohen et al. in 2017, extends the original MNIST format to include handwritten letters in addition to digits. EMNIST is derived from NIST Special Database 19 and is available in six splits:[9]
| Split | Classes | Total samples | Description |
|---|---|---|---|
| ByClass | 62 | 814,255 | Full set, all digits and letters (unbalanced) |
| ByMerge | 47 | 814,255 | Merged upper/lower case (unbalanced) |
| Balanced | 47 | 131,600 | Equal samples per class |
| Digits | 10 | 280,000 | Digits only (balanced) |
| Letters | 26 | 145,600 | Letters only (merged case, balanced) |
| MNIST | 10 | 70,000 | Direct MNIST equivalent |
KMNIST
Kuzushiji-MNIST (KMNIST) contains 70,000 images of 10 classes of cursive Japanese (Kuzushiji) Hiragana characters, formatted identically to MNIST. KMNIST is considered more challenging than MNIST because multiple visually distinct characters can map to the same class label.[10]
QMNIST
QMNIST, introduced by Chhavi Yadav and Leon Bottou in 2019, is a reconstruction of the MNIST dataset that recovers the full 60,000-image test set originally selected from NIST databases but never distributed. QMNIST traces each digit back to its NIST source image and associated metadata (writer identifier, partition, etc.), enabling investigation of potential overfitting to the original 10,000-image test set over 25 years of repeated benchmarking.[11]
Other notable variants
| Dataset | Description | Image format |
|---|---|---|
| notMNIST | Letters A-J rendered in various computer fonts | 28x28 grayscale |
| Kannada-MNIST | Digits in the Kannada script (South Indian language) | 28x28 grayscale |
| MedMNIST | 18 biomedical image classification datasets (12 in 2D, 6 in 3D) | 28x28 (2D) or 28x28x28 (3D) |
| AudioMNIST | 30,000 spoken digit recordings (0-9) from 60 speakers | Audio waveforms |
| 3D MNIST | Volumetric (voxel) representations of digits | 3D voxels |
| affNIST | MNIST digits with random affine transformations | 40x40 grayscale |
| MNIST-1D | A 1D analog of MNIST designed for rapid prototyping | 40-element vectors |
| SVHN | Street View House Numbers from Google Street View | 32x32 color |
| HASYv2 | 168,233 handwritten mathematical symbols across 369 classes | 32x32 grayscale |
How does MNIST compare with other benchmark datasets?
The following table compares MNIST with other commonly used image classification benchmarks. MNIST is the smallest and lowest-resolution of the group, which is why typical accuracy is near-saturated while richer datasets like CIFAR-100 and ImageNet leave far more headroom.
| Dataset | Images | Classes | Resolution | Color | Typical accuracy |
|---|---|---|---|---|---|
| MNIST | 70,000 | 10 | 28x28 | Grayscale | 99.7%+ |
| Fashion-MNIST | 70,000 | 10 | 28x28 | Grayscale | ~96-97% |
| EMNIST (Balanced) | 131,600 | 47 | 28x28 | Grayscale | ~91% |
| KMNIST | 70,000 | 10 | 28x28 | Grayscale | ~98% |
| CIFAR-10 | 60,000 | 10 | 32x32 | RGB | ~96-99% |
| CIFAR-100 | 60,000 | 100 | 32x32 | RGB | ~80-90% |
| SVHN | 630,000+ | 10 | 32x32 | RGB | ~98% |
| ImageNet | 14M+ | 1,000+ | Variable | RGB | ~90% (top-1) |
How to use MNIST
MNIST is built into most major machine learning frameworks and can be loaded with a single function call.
TensorFlow/Keras:
from tensorflow.keras.datasets import mnist
(x_train, y_train), (x_test, y_test) = mnist.load_data()
PyTorch:
from torchvision import datasets, transforms
train_dataset = datasets.MNIST(root='./data', train=True, download=True,
                               transform=transforms.ToTensor())
test_dataset = datasets.MNIST(root='./data', train=False, download=True,
                              transform=transforms.ToTensor())
from sklearn.datasets import fetch_openml
mnist = fetch_openml('mnist_784', version=1)
The original files were distributed from Yann LeCun's website (now an empty directory; archived copies remain on the Internet Archive), and the dataset is also available from Hugging Face Datasets, the UCI Machine Learning Repository, and OpenML.
Continue reading
- LeNetLeNet is the pioneering family of convolutional neural networks developed by Yann LeCun and collaborators at AT&T Bell Labs between roughly 1988 and 1998 to read handwritten charactersMentioned 9 times above
- Deep LearningDeep learning is a subset of machine learning that uses artificial neural networks with multiple layers to automatically learn representations of data at multiple levels of abstractionMentioned 6 times above
- Data AugmentationData augmentation is a set of techniques that artificially expand the size and diversity of a training dataset by applying label-preserving transformations to existing examples, rather than collecting new…Mentioned 4 times above
- Convolutional Neural NetworkA convolutional neural network (CNN, or ConvNet) is a neural network that uses convolution-like linear operators in at least some layers.Mentioned 3 times above
- Image classificationImage classification is the task of assigning a whole image to one category drawn from a fixed set of labels.Mentioned 3 times above
- Computer VisionComputer vision is the study of computational methods that extract, estimate, or generate useful representations from visual measurements.Mentioned twice above
More from See also
More to read
References
- ^LeCun, Y., Bottou, L., Bengio, Y., & Haffner, P. (1998). "Gradient-based learning applied to document recognition." *Proceedings of the IEEE*, 86(11), 2278-2324. ieeexplore.ieee.org/...726791
- ^NIST Special Database 19. National Institute of Standards and Technology. nist.gov/...nist-special-database-19
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9LeCun, Y., Cortes, C., & Burges, C.J.C. (1998). "The MNIST Database of Handwritten Digits." Archived: web.archive.org/...mnist
- ^LeCun, Y. "THE MNIST DATABASE of handwritten digits." Archived: web.archive.org/...MNIST_doc.pdf
- ^1 ^2 ^3 ^4 ^5Wikipedia contributors. "MNIST database." *Wikipedia, The Free Encyclopedia*. en.wikipedia.org/...MNIST_database
- LeCun, Y. "LeNet-5, convolutional neural networks." yann.lecun.com/...lenet
- ^Xiao, H., Rasul, K., & Vollgraf, R. (2017). "Fashion-MNIST: a Novel Image Dataset for Benchmarking Machine Learning Algorithms." *arXiv preprint arXiv:1708.07747*.
- ^1 ^2 ^3Zalando Research. "Fashion-MNIST." GitHub. github.com/...fashion-mnist
- ^Cohen, G., Afshar, S., Tapson, J., & van Schaik, A. (2017). "EMNIST: Extending MNIST to handwritten letters." *arXiv preprint arXiv:1702.05373*.
- ^Clanuwat, T., Bober-Irizar, M., Kitamoto, A., Lamb, A., Yamamoto, K., & Ha, D. (2018). "Deep Learning for Classical Japanese Literature." *arXiv preprint arXiv:1812.01718*.
- ^1 ^2 ^3 ^4Yadav, C. & Bottou, L. (2019). "Cold Case: The Lost MNIST Digits." *Advances in Neural Information Processing Systems*, 32. papers.nips.cc/...4cb0b8467eafad1330bce66-Abstract
- Yang, J., Shi, R., Wei, D., et al. (2023). "MedMNIST v2: A large-scale lightweight benchmark for 2D and 3D biomedical image classification." *Scientific Data*, 10, 41. nature.com/...s41597-022-01721-8
- Greydanus, S. & Kobak, D. (2020). "Scaling Down Deep Learning with MNIST-1D." *arXiv preprint arXiv:2011.14439*.
- MNIST Database of Handwritten Digits. UCI Machine Learning Repository. archive.ics.uci.edu/...abase+of+handwritten+digits
- ^1 ^2An, S., Lee, M., Park, S., Yang, H., & So, J. (2020). "An Ensemble of Simple Convolutional Neural Network Models for MNIST Digit Recognition." *arXiv preprint arXiv:2008.10400*. arxiv.org/...2008.10400
- ^1 ^2Ciresan, D., Meier, U., & Schmidhuber, J. (2012). "Multi-column Deep Neural Networks for Image Classification." *arXiv preprint arXiv:1202.2745*. arxiv.org/...1202.2745
- ^1 ^2Wikipedia contributors. "LeNet." *Wikipedia, The Free Encyclopedia*. en.wikipedia.org/...LeNet
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
9 revisions · v9 · 3,360 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (110 claims, 24 sources fetched); 15 material + 13 minor fixed
Cite this page: AI Wiki. "MNIST." aiwiki.ai, updated 28 Oct 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/mnist