

Monte Carlo Tree Search
Monte Carlo Tree Search (MCTS) is a heuristic search algorithm for sequential decision-making that finds strong actions by running many simulated playthroughs of a problem and aggregating their outcomes into a search tree; in its basic form it needs no hand-designed evaluation function. It is the search algorithm at the heart of DeepMind's AlphaGo, which in March 2016 defeated Lee Sedol, a winner of 18 world Go titles, four games to one in a match that DeepMind says was watched by over 200 million people worldwide.[8][28] Variants of it remain the planning engine inside AlphaZero, MuZero, and DeepMind's algorithm-discovery and theorem-proving systems.[10][11][14][15][16] MCTS builds its tree incrementally by performing many rollouts (also called playouts), using random or lightly informed play, and aggregating the results to estimate the value of each candidate action at the root. In the words of the field's standard survey, it "combines the precision of tree search with the generality of random sampling."[3]
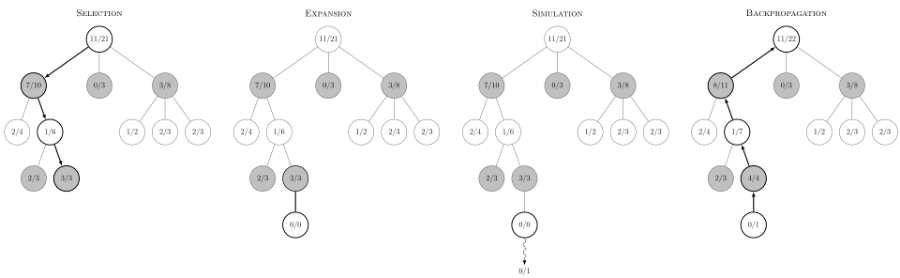
The algorithm has four phases that repeat thousands or millions of times within a single decision: selection of a path through the existing tree using a tree policy, expansion of the tree by adding a new leaf node, simulation of a rollout from that leaf to a terminal state, and backpropagation of the rollout outcome back up the tree to update visit counts and value estimates.[3] The most influential variant uses the UCB1 bandit formula, originally introduced by Auer, Cesa-Bianchi, and Fischer for the multi-armed bandit problem, applied at every node in the tree.[4] This instantiation, called UCT for Upper Confidence Bounds applied to Trees, was introduced by Levente Kocsis and Csaba Szepesvari in 2006, and the Browne survey describes it as "the most popular algorithm in the MCTS family."[2][3]
MCTS is anytime, meaning it can be stopped at any moment and will return the best action discovered so far, with the quality of the recommendation improving smoothly with additional computation.[3] It grows its tree asymmetrically, devoting more visits to promising subtrees while ignoring obviously bad ones, which is essential for problems with extremely large branching factors such as Go (around 250 legal moves per turn).[3][8] The algorithm is general purpose: the only domain-specific code required is a description of the legal action set, a transition function, and a terminal reward signal.[3] This generality has made MCTS the backbone of reinforcement learning systems that learn complex environments without hand-engineered evaluation, including AlphaZero for chess, shogi, and Go, MuZero for Atari and board games with a learned dynamics model, AlphaTensor for matrix-multiplication algorithm discovery, AlphaDev for sorting algorithm synthesis, and AlphaProof for formal mathematical theorem proving.[10][11][14][15][16] Since 2023, MCTS and related tree searches have also been applied to the intermediate reasoning steps of large language models.[17][18][19]
When and by whom was MCTS invented?
The roots of MCTS reach back to Monte Carlo evaluation of game positions and to the broader field of stochastic dynamic programming. In 1990 Bruce Abramson showed that the expected outcome of random play could be used to evaluate a game state.[3] The first explicit use of Monte Carlo simulation for Go is usually credited to Bernd Brugmann's 1993 report "Monte Carlo Go," which described a program called Gobble that played 9x9 Go by evaluating moves through random games.[3][5][30] In 1996 Gerald Tesauro and Gregory Galperin used Monte Carlo simulation for on-line policy improvement in backgammon, reporting large reductions in the error rate of base players that ranged from a random policy to TD-Gammon.[25] As Coulom later summarized, the traditional approach to two-player games was alpha-beta search with a hand-built position evaluator, which had worked for chess, checkers, and Othello but had failed for Go, partly because an accurate static evaluator for Go positions was so hard to write.[1] In the early 2000s Bruno Bouzy and Bernard Helmstetter developed Monte Carlo Go further, and Bouzy combined Monte Carlo evaluation with a shallow, selective global tree search on the 9x9 board.[1]
The modern formulation of MCTS as a tree search guided by simulation outcomes was introduced by Remi Coulom in 2006. His paper "Efficient Selectivity and Backup Operators in Monte-Carlo Tree Search," presented at the Computers and Games conference in Turin, proposed a framework that combines tree search with Monte Carlo evaluation without separating a min-max phase from a Monte Carlo phase, using a backup operator that "progressively changes from averaging to min-max as the number of simulations grows."[1] The Browne survey credits Coulom with coining the term "Monte Carlo tree search."[3] Coulom's program Crazy Stone, which implemented the approach, won the 10th KGS computer-Go tournament and the 9x9 Go tournament at the 11th Computer Olympiad in Turin in 2006.[1][29] The now-standard description of MCTS as four repeated steps (selection, expansion, simulation, backpropagation), used in the Browne survey, follows Guillaume Chaslot and colleagues' 2008 framing of MCTS as a general framework for game AI.[3]
In the same year as Coulom's paper, Levente Kocsis and Csaba Szepesvari published "Bandit Based Monte-Carlo Planning" at the European Conference on Machine Learning, introducing UCT.[2] Their paper supplied the theoretical justification missing from earlier empirical methods: it treats the choice of action at every internal node as a multi-armed bandit problem and applies the UCB1 formula of Auer and colleagues.[2] For a finite-horizon Markov decision process with rewards scaled to the interval [0, 1], they showed that the bias of the estimated payoff shrinks as O(log n / n) and that the probability of choosing a suboptimal action at the root goes to zero as the number of simulated episodes grows.[2] As the authors state, in finite-horizon or discounted Markov decision processes "the algorithm is shown to be consistent and finite sample bounds are derived on the estimation error due to sampling."[2] The Browne survey notes that this result implies that, given enough time and memory, UCT converges to the minimax tree.[3] The combination of a selective Monte Carlo tree search with Kocsis and Szepesvari's selection rule gave the field a method that was both practically strong and theoretically grounded.
The years 2006 to 2010 saw a Monte Carlo revolution in computer Go. Sylvain Gelly and colleagues applied UCT to Go in the program MoGo, and Gelly and David Silver then introduced Rapid Action Value Estimation (RAVE) and heuristic UCT.[3][6] With these extensions MoGo became the first program to reach dan (master) level at 9x9 Go, won the gold medal at the 2007 Computer Olympiad, and became the first program to beat a human professional player at 9x9 Go.[7][30] Other strong programs of the era included Fuego (developed at the University of Alberta), Erica, Pachi, and Zen, all built on MCTS.[3][20] By the time of the 2012 Browne survey, more than three dozen of the leading Go programs used the algorithm.[3]
The canonical reference work for the field is Cameron Browne and colleagues' 2012 survey "A Survey of Monte Carlo Tree Search Methods," published in the IEEE Transactions on Computational Intelligence and AI in Games.[3] The 43-page survey, which cites about 240 works, was intended as "a snapshot of the state of the art after the first five years of MCTS research" and covers the core algorithm, its many variants and enhancements, and applications across games, scheduling, planning, and procedural content generation.[3] It is still widely used as an introduction to the field.
The combination of MCTS with deep neural networks by DeepMind transformed the algorithm from a Go-specialized technique into a general framework for learned planning. AlphaGo, published by David Silver and colleagues in Nature in January 2016, used a value network and a policy network to guide MCTS, beating European Go champion Fan Hui 5-0 in October 2015 and Lee Sedol 4-1 in March 2016.[8][28] AlphaGo Zero (2017) removed the need for human game data, learning entirely from self-play with a single network.[9] AlphaZero (December 2017 preprint, full Science paper 2018) generalized the same recipe to chess and shogi.[10][27] MuZero (2020) removed the need for a known model of the environment by learning a dynamics function alongside the policy and value networks.[11] The same AlphaZero template has since been adapted for matrix multiplication discovery (AlphaTensor, 2022), assembly-level sorting algorithm synthesis (AlphaDev, 2023), and formal mathematical proof search (AlphaProof, announced 2024).[14][15][16] The Tree of Thoughts framework introduced by Shunyu Yao and colleagues at NeurIPS 2023 applies tree search (breadth-first and depth-first) to the generation steps of a large language model, and the Reasoning via Planning method of Shibo Hao and colleagues at EMNLP 2023 uses MCTS for the same purpose.[17][18]
How does the MCTS algorithm work? The four phases
MCTS proceeds by repeating an outer loop, each iteration of which executes four phases on a partially built search tree.[3] The tree is rooted at the current state, and each node stores statistics summarizing the simulations that have passed through it: typically a visit count and an estimate of the action value for each action available at the node. After a budget of iterations or a wall-clock time limit, the algorithm reports the action with the highest visit count or highest mean value as the move to play.[3]
| Phase | Description | Typical implementation |
|---|---|---|
| 1. Selection | Starting from the root, recursively choose the child with the highest tree-policy score until a node is reached that has at least one unexpanded action. | UCB1 / UCT in classical MCTS, PUCT with neural network priors in AlphaZero-style systems. |
| 2. Expansion | If the selected node has untried actions and is not terminal, add one or more new child nodes corresponding to those actions. | Add a single new child per iteration (most common), or expand all untried actions at once for vectorized neural network inference. |
| 3. Simulation | From the newly added node, play out a complete trajectory to a terminal state using a default policy. The trajectory is not stored in the tree. | Uniform random rollouts in pure MCTS, hand-crafted heavy playouts in early Go programs, neural network value estimate in AlphaZero (no explicit rollout). |
| 4. Backpropagation | Walk back up from the new node to the root, incrementing the visit count and updating the value estimate of every node along the path with the rollout's outcome. | Add the result to a running sum and increment the count, taking care to invert sign across alternating turns in two-player games. |
After many iterations, the visit counts at the children of the root show how much search effort each move attracted, which tracks how promising the search found it. A common choice is the most visited child (the "robust child") as the recommended action, and in self-play systems the root visit counts also serve as the training target for the policy network.[3][9]
Selection and the UCB1 formula
The selection step decides how to descend the existing tree. Each node faces an exploration-exploitation trade-off identical to the multi-armed bandit problem: should the next visit go to the action with the best estimated value, exploiting current knowledge, or to a less-tried action that might prove better, exploring? The UCB1 formula due to Auer, Cesa-Bianchi, and Fischer (2002) addresses this trade-off with a closed-form bonus term:[4]
Here is the average reward observed from action a in state s, is the number of times state s has been visited, is the number of times action a has been chosen from s, and c is an exploration constant. The original UCB1 corresponds to for rewards in the unit interval.[3][4] The square-root term grows logarithmically with the parent's visit count and shrinks with the action's visit count, so under-explored actions accumulate an exploration bonus that eventually forces them to be tried. UCT applies this rule at every internal node of the tree.[2]
Kocsis and Szepesvari proved that UCT is consistent: with rewards in [0, 1], the probability that the search recommends a suboptimal action at the root goes to zero as the number of simulations grows, and the bias of the root estimate shrinks at a rate of O(log n / n).[2] These guarantees helped explain why UCT worked in practice and made it the default selection rule for MCTS implementations.[3]
Expansion, simulation, and backpropagation
When selection reaches a node with at least one action that has never been tried, expansion adds a new node to the tree. The most common strategy is to add a single new node per iteration, choosing the untried action either uniformly at random or via a heuristic, which keeps memory growth linear in the simulation budget.[3]
From the new node, the algorithm plays out a trajectory to a terminal state using the default policy. In pure MCTS the default policy is uniform random play. Stronger Go programs used hand-crafted heavy playouts that incorporated local patterns and tactical rules.[3] AlphaGo evaluated each leaf with an equal mixture of a value network and a fast rollout policy, a combination that performed best in its experiments.[8] AlphaGo Zero and its successors dropped rollouts entirely and evaluate the leaf with a single neural network value estimate, which removes rollout variance at the cost of requiring a trained value network.[9] The AlphaProof paper accordingly describes each iteration of its search as three phases: selection, expansion, and backpropagation.[16]
Once the simulation produces an outcome, the algorithm walks back up the path from the new node to the root, updating the statistics at every node along the way.[3] Each visited node has its visit count incremented by one and its accumulated value updated by the simulation's outcome. In two-player zero-sum games the value is read from the perspective of the player to move, so its sign flips at every level. AlphaZero stores the total value W and the mean value Q = W/N for each edge.[10] MuZero generalizes the backup to environments with intermediate rewards and discounting by backing up an n-step discounted return, and because values in many environments are unbounded it normalizes Q values to [0, 1] using the minimum and maximum values seen in the search tree so far.[11]
What makes MCTS different from other search methods?
MCTS has several properties that distinguish it from older game-tree search methods such as alpha-beta pruning.[3]
Anytime. The algorithm produces a best-so-far recommendation at every iteration. There is no need to specify a search depth in advance, and the quality of the answer improves smoothly with more time, which makes MCTS suitable for real-time decisions.[3]
Asymmetric tree growth. Unlike depth-limited iterative deepening, MCTS does not visit all nodes uniformly. The UCB1 selection rule concentrates visits on subtrees that look promising, producing a tree that is deep in critical lines and shallow in obvious blunders.[3] This adaptivity is what allows MCTS to be useful in games like Go where the branching factor exceeds 200 and complete search to even modest depth is impossible.[3]
Aheuristic in pure form. The basic algorithm needs only a generative model of the environment and a terminal reward signal. There is no need for a hand-designed evaluation function or move ordering heuristic. This generality made MCTS a natural fit for general game playing competitions, where the rules of the game are revealed to the agent only at runtime.[3]
Convergent. UCT is provably consistent for finite-horizon or discounted Markov decision processes with bounded rewards.[2] Given enough time and memory, the search converges to the minimax tree in two-player games.[3]
Parallelizable. Independent simulations from the same root can be run in parallel, with care taken to avoid race conditions when updating shared statistics. Three common parallelization schemes are leaf parallelization, root parallelization, and tree parallelization, which can add a temporary "virtual loss" to nodes so that different threads explore different branches; each has different trade-offs between speedup and search quality.[3][22]
Limitations. MCTS struggles in environments with sparse or deceptive rewards because random rollouts can take exponentially many samples to reach a high-reward terminal state. It can also struggle with "trap states," moves that lose within a few plies: Ramanujan and colleagues argued that UCT performs poorly in domains with many such traps while iterative-deepening minimax does relatively well, and the Browne survey notes that traps are common in chess but relatively uncommon in Go.[3] Continuous action spaces require special treatment because the basic algorithm assumes a discrete branching factor at every node.
What are the main MCTS variants?
Research on MCTS has produced a large family of refinements, many of which the Browne 2012 survey catalogues.[3] The most influential variants are summarized below.
| Year | Variant | Key idea |
|---|---|---|
| 2006 | UCT (Kocsis and Szepesvari) | UCB1 formula applied at every node; the dominant selection rule for MCTS. |
| 2007 | RAVE / AMAF (Gelly and Silver) | Rapid Action Value Estimation: combines the value of a move across all simulations in which it appeared, not just those in which it was chosen first. |
| 2007-2008 | Heuristic UCT / Progressive bias | Incorporates domain knowledge as prior values or as an additive bonus on the UCB1 score that decays as visit counts grow. |
| 2008 | MCTS-Solver (Winands, Bjornsson, Saito) | Backs up proven wins and losses through the tree so the search can prove game-theoretic values. |
| 2012 | Information Set MCTS (Cowling et al.) | Extension to imperfect information games, searching trees of information sets rather than determinized game states. |
| 2015 | GRAVE (Cazenave) | Generalized RAVE, designed to give more accurate estimates near the leaves of the tree. |
| 2016 | AlphaGo PUCT | Two networks: a policy network providing priors for action selection and a value network, mixed with fast rollouts, for leaf evaluation. |
| 2017 | AlphaZero | Single network outputting both policy and value, learned entirely from self-play with no human data. PUCT formula is the standard selection rule. |
| 2020 | MuZero (Schrittwieser et al.) | Learns a dynamics model alongside policy and value networks, removing the need for an explicit environment simulator inside the search. |
| 2021 | Sampled MuZero (Hubert et al.) | Samples a small set of candidate actions from the policy at each node, enabling planning in continuous and combinatorial action spaces; the framework applies equally to AlphaZero. |
| 2022 | Gumbel MuZero / Gumbel AlphaZero (Danihelka et al.) | Replaces AlphaZero's heuristic root mechanisms with Gumbel-Top-k sampling and Sequential Halving, guaranteeing a policy improvement when the searched actions are correctly evaluated. |
| 2022 | AlphaTensor (Fawzi et al.) | AlphaZero-based agent with a sample-based MCTS (from Sampled AlphaZero) for tensor decomposition, discovering faster matrix multiplication algorithms for some matrix sizes. |
| 2023 | AlphaDev (Mankowitz et al.) | Extension of AlphaZero for assembly-level sorting algorithm discovery, producing routines integrated into the LLVM standard C++ library. |
| 2023 | RAP / Tree of Thoughts (Hao et al., Yao et al.) | Apply MCTS (RAP) or breadth-first and depth-first tree search (Tree of Thoughts) to the reasoning steps of a large language model. |
| 2024 | AlphaProof (Google DeepMind) | AlphaZero-inspired tree search over Lean tactics; with AlphaGeometry 2, reached silver-medal standard at the 2024 International Mathematical Olympiad. |
| 2025 | rStar-Math (Guan et al.) | MCTS test-time search with a process preference model lets a 7B model surpass o1-preview and match o1-mini on the MATH benchmark. |
RAVE and the all-moves-as-first heuristic
In games like Go where the value of a move is often largely independent of the order in which earlier moves were played, the all-moves-as-first heuristic (AMAF) updates the statistics of every move that appeared anywhere in a simulation, not just the move actually chosen at the relevant node.[7] RAVE, introduced in MoGo by Gelly and Silver, blends an AMAF estimate with the standard MCTS estimate using a weighting that favors AMAF when visit counts are low and MCTS as visits accumulate.[7] RAVE was a major contributor to MoGo's success, and the Browne survey reports that most Go programs of the time used AMAF or RAVE.[3][7] Tristan Cazenave's Generalized RAVE (GRAVE, 2015) extends the idea so as to give more accurate estimates near the leaves, and was tested on Atarigo, Knightthrough, Domineering, and Go.[23]
Other enhancements exploit known game outcomes. MCTS-Solver, proposed by Mark Winands, Yngvi Bjornsson, and Jahn-Takeshi Saito in 2008, backs up proven wins and losses through the tree, borrowing the logic of proof-number search: a position is a proven win if any child is a proven win and a proven loss if every child is a proven loss.[3][24]
PUCT and neural network priors
The PUCT rule modifies the exploration bonus to incorporate a prior probability supplied by a neural network policy. The AlphaGo papers describe their selection rule as a variant of the PUCT algorithm and credit it to Christopher Rosin's 2011 work on multi-armed bandits with episode context.[8][31] In the form given in the AlphaGo Zero paper:[9]
Here is the prior probability of action a from state s as predicted by the policy network.[9] The exploration bonus is scaled by this prior, so actions that the policy considers promising receive more exploration even when their visit counts are low. The constant controls the strength of exploration; AlphaGo used .[8] Later systems let the coefficient grow slowly with the parent's visit count. In the AlphaZero Science paper it is , which is "essentially constant during the fast training games," and MuZero uses an equivalent form with constants 1.25 and 19,652.[10][11]
Versions of the rule are also the selection step in DeepMind's algorithm-discovery and proving systems. AlphaTensor maximizes a PUCT bound computed over the empirical distribution of a set of sampled actions, following Sampled AlphaZero.[14] AlphaDev's paper calls its rule the "predictor upper confidence tree bound."[15] AlphaProof selects actions with a PUCT bound adapted from AlphaZero, with a temperature applied to the policy prior.[16]
Gumbel MCTS
AlphaZero's mechanisms for choosing which actions to search are heuristic, and the Gumbel paper shows that AlphaZero "can fail to improve its policy network, if not visiting all actions at the root of a search tree."[13] Gumbel MCTS, introduced by Ivo Danihelka and colleagues at ICLR 2022, replaces these mechanisms with a procedure based on policy improvement: at the root it samples candidate actions without replacement using the Gumbel-Top-k trick on policy logits, then applies Sequential Halving to allocate simulations across the candidates, and it also replaces the selection rule at non-root nodes.[13] The authors show that this guarantees a policy improvement when the searched actions' values are correctly evaluated, and they report that on Go, chess, and Atari the Gumbel agents "keep improving, even when learning from two simulations" per move.[13] According to the paper, Gumbel AlphaZero and Gumbel MuZero "match the state of the art on Go, chess, and Atari, and significantly improve prior performance when planning with few simulations."[13]
How is MCTS used in large language model reasoning?
A line of work since 2023 applies tree search to the reasoning chain of a large language model, turning the search loop into a form of test-time search. Tree of Thoughts, by Shunyu Yao and colleagues at Princeton University and Google DeepMind, treats each intermediate reasoning step (a "thought") as a node in a tree and explores the tree with breadth-first search, which keeps the b most promising states at each step (in effect a beam search), or with depth-first search; the authors left more advanced searches such as A* and MCTS "for future work."[17] On the Game of 24, GPT-4 with chain-of-thought prompting solved 4 percent of tasks, while Tree of Thoughts solved 74 percent.[17] Reasoning via Planning (RAP), by Shibo Hao and colleagues, casts the LLM itself as both a world model (predicting the next state given an action) and a reasoning agent, with MCTS choosing among candidate reasoning steps.[18] The authors report that RAP on LLaMA-33B surpassed chain-of-thought on GPT-4 with a 33 percent relative improvement in a plan-generation setting.[18]
Later work replaced prompted evaluation with learned values. TS-LLM, by Xidong Feng and colleagues, argued that Tree of Thoughts and RAP rely on prompting a pretrained model to act as the value function and focus on shallow searches, and instead trained a value function and used AlphaZero-like tree search to guide both decoding and training, handling trees up to depth 64.[32] rStar-Math, by Xinyu Guan and colleagues at Microsoft Research, uses MCTS in which a math policy small language model "performs test-time search guided by an SLM-based process reward model."[19] On the MATH benchmark, rStar-Math improved Qwen2.5-Math-7B from 58.8 percent to 90.0 percent, 4.5 points above OpenAI's o1-preview and level with o1-mini; on the 2024 American Invitational Mathematics Examination (AIME) it solved on average 53.3 percent of problems (8 of 15), a result the authors place among the top 20 percent of the brightest high school math students.[19] In place of the random rollouts of classical MCTS, a learned process preference model scores intermediate steps to guide the search.[19]
Not every attempt has worked at scale. In the DeepSeek-R1 report, DeepSeek described an unsuccessful effort to use MCTS during reinforcement learning: unlike chess, "token generation presents an exponentially larger search space," and a fine-grained value model was hard to train. It concluded that MCTS "can improve performance during inference when paired with a pre-trained value model" but that iteratively improving the model through self-search "remains a significant challenge," while cautioning that sharing the failure "does not imply that these approaches are incapable of developing effective reasoning models."[33]
What is MCTS used for? Notable applications
| Application | Year | Domain | Role of MCTS |
|---|---|---|---|
| Crazy Stone | 2006 | Computer Go | Coulom's MCTS program; won the 9x9 Go event at the 11th Computer Olympiad (Turin). |
| MoGo | 2007 | Computer Go | UCT with RAVE; first program to reach dan level at 9x9 and first to beat a human professional at 9x9. |
| Fuego | 2009 | Computer Go | Open-source MCTS framework; first program to win an even 9x9 game against a top 9-dan professional (August 2009). |
| AlphaGo | 2016 | Computer Go | Combined MCTS with deep neural networks; defeated Lee Sedol 4-1. |
| AlphaGo Zero / AlphaZero | 2017 | Go, chess, shogi | Single neural network, MCTS as the policy improvement operator in self-play training. |
| MuZero | 2020 | Atari, Go, chess, shogi | MCTS over a learned model rather than an explicit simulator; matched AlphaZero in chess and shogi, slightly exceeded it in Go, and set a new state of the art on 57 Atari games. |
| AlphaTensor | 2022 | Matrix multiplication algorithm discovery | Sample-based MCTS for tensor decomposition; 47 multiplications for 4x4 matrices in arithmetic modulo 2, improving on Strassen's two-level algorithm "for the first time, to our knowledge" since its discovery. |
| AlphaDev | 2023 | Sorting algorithm synthesis | MCTS over CPU instruction sequences; new sort 3, sort 4, and sort 5 routines integrated into LLVM libc++. |
| AlphaProof | 2024 | Formal theorem proving | MCTS-style search over Lean tactics; with AlphaGeometry 2, silver-medal standard at the 2024 International Mathematical Olympiad. |
| Tree of Thoughts / RAP | 2023 | LLM reasoning | Tree search over reasoning steps generated by a language model. |
| rStar-Math | 2025 | LLM math reasoning | MCTS test-time search with a process reward model; 7B model surpasses o1-preview and matches o1-mini on MATH. |
| General Game Playing | 2007 onward | Board, card, and arcade games | Dominant approach in GGP competitions because MCTS requires no domain knowledge beyond the rules. |
| Information Set MCTS and determinized UCT | 2010s | Skat, poker, Dou Di Zhu, Magic: The Gathering | MCTS variants for stochastic and imperfect information games. |
| Autonomous driving tactical decisions | 2019 onward | Robotics | MCTS combined with a learned network evaluates tactical decisions in simulated highway driving. |
| Procedural content generation | 2010s onward | Game design and creative domains | UCT used to create and tune game content, for example strategy-game unit types evaluated by simulated battles. |
AlphaGo and the Lee Sedol match
AlphaGo, described by David Silver and colleagues in their January 2016 Nature paper "Mastering the game of Go with deep neural networks and tree search," is the system that brought MCTS to mainstream attention.[8] AlphaGo combined three components: a policy network trained by supervised learning on 30 million positions from the KGS Go Server and then refined with self-play reinforcement learning, a value network trained to predict game outcomes from positions, and an MCTS search that used policy-network priors to guide selection and a mixture of the value network and a fast rollout policy to evaluate leaves.[8] The paper notes that the supervised policy network, not the stronger reinforcement-learning one, worked better as the source of search priors, "presumably because humans select a diverse beam of promising moves."[8] In a five-game match in Seoul in March 2016, AlphaGo defeated Lee Sedol, whom DeepMind describes as a winner of 18 world titles, four games to one; DeepMind says the match was watched by over 200 million people worldwide.[28]
AlphaGo's design, with learned priors and learned evaluations guiding MCTS, carried forward into AlphaGo Zero, AlphaZero, and MuZero, all of which keep MCTS at their core.[9][10][11]
AlphaGo Zero, AlphaZero, and self-play
AlphaGo Zero, published in October 2017, removed the dependence on human game data.[9] A single neural network outputting both a policy and a value was trained from scratch by self-play, with MCTS acting as a policy improvement operator: the visit counts produced by the search were stronger than the raw network policy, and the network was trained to mimic them.[9] After three days of training, AlphaGo Zero defeated AlphaGo Lee, the version that had beaten Lee Sedol, by 100 games to 0, playing on a single machine with 4 TPUs against AlphaGo Lee's 48 TPUs.[9] The same recipe, generalized as AlphaZero, was described in a December 2017 preprint and applied to chess and shogi as well as Go; the preprint reported superhuman play "within 24 hours" and a win over a world-champion program in each game.[27] In the 2018 Science paper, AlphaZero first outperformed Stockfish in chess after about 4 hours of training and Elmo in shogi after about 2 hours.[10]
The key insight of AlphaGo Zero and AlphaZero is that MCTS does not just play the game well, it generates training data for the network. The visit counts at the root form a sharper distribution than the network's policy output, and the AlphaGo Zero paper describes training the network to match those visit counts, together with the game outcome, as a policy iteration procedure.[9] Iterating this loop drives the network and the search to improve together, with no need for human knowledge beyond the rules.[9]
MuZero and learned models
MuZero, by Julian Schrittwieser and colleagues at DeepMind, was published in Nature in December 2020.[11] Whereas AlphaZero requires a perfect model of the environment to expand the search tree, MuZero learns its own model. Three functions are trained jointly: a representation function that encodes the observation into a hidden state, a dynamics function that maps hidden state and action to a next hidden state and predicted reward, and a prediction function that outputs a policy and value from the hidden state.[11] MCTS unrolls the dynamics function in latent space without stepping the real environment. Its one use of the rules during planning is at the root, where it masks illegal actions "where the environment can be queried"; it does no masking inside the tree.[11]
In chess and shogi, MuZero matched the performance of AlphaZero, which was given the rules, and in Go it slightly exceeded AlphaZero while using less computation per node.[11] On the 57 Atari games of the Arcade Learning Environment, it set a new state of the art for both mean and median human-normalized score, outperforming the previous best method, the model-free R2D2, in 42 of 57 games.[11] The MuZero line has since been extended to large and continuous action spaces (Sampled MuZero), sample-efficient learning from limited data (EfficientZero), and small simulation budgets (Gumbel MuZero).[12][13][35]
AlphaTensor, AlphaDev, AlphaProof
AlphaTensor, published in Nature in October 2022, is described in its paper as "a deep reinforcement learning approach based on AlphaZero"; it builds on AlphaZero and its extension Sampled AlphaZero, combining a neural network with "a sample-based MCTS search algorithm."[14] The task is cast as a single-player game, TensorGame, in which each move subtracts a rank-one tensor from the current residual and the goal is to reach zero in as few moves as possible; the moves played then form a low-rank decomposition that corresponds to a matrix multiplication algorithm.[14] AlphaTensor found an algorithm for multiplying 4x4 matrices in arithmetic modulo 2 using 47 multiplications, against 49 for two levels of Strassen's algorithm; the authors write that this "improves on Strassen's two-level algorithm for the first time, to our knowledge, since its discovery 50 years ago."[14]
AlphaDev, published in Nature in June 2023, applies the approach to the synthesis of small assembly-level sorting routines. Its paper states that "the primary learning algorithm in AlphaDev is an extension of AlphaZero," which guides an MCTS planning procedure with a deep neural network; MuZero appears in the paper only as background.[15] Each move appends a CPU instruction, and the reward combines correctness on test cases with latency. AlphaDev's fixed sort routines for sort 3, sort 4, and sort 5 were integrated into the LLVM libc++ standard sorting library, where the authors report improvements of up to 70 percent for sequences of length five and roughly 1.7 percent for sequences of more than 250,000 elements.[15]
AlphaProof was announced by Google DeepMind in July 2024; its Nature paper was published online in November 2025 and appeared in the journal's March 2026 issue.[16] The paper describes AlphaProof as "an AlphaZero-inspired agent" that searches over Lean tactics with a tree search based on AlphaZero and Sampled MuZero, adapted with an AND-OR tree structure for proofs that split into independent subgoals.[16] At the 2024 International Mathematical Olympiad, AlphaProof solved two algebra problems and one number theory problem, including the hardest problem of the competition, and AlphaGeometry 2 solved the geometry problem; together the systems scored 28 of 42 points, equivalent to the top end of the silver-medal range.[16] DeepMind said its systems solved one problem within minutes and took up to three days on the others.[16] For training, a Gemini-based model auto-formalized approximately 1 million natural-language problems into around 80 million formal Lean problems.[16]
Robotics, planning, and general game playing
MCTS has been applied to tactical decision-making for autonomous vehicles. Carl-Johan Hoel and colleagues, for example, combined MCTS with a deep neural network in a framework based on AlphaGo Zero, extended it to a continuous state space where self-play cannot be used, and applied it to two simulated highway driving cases, where it performed better than a commonly used baseline method.[34]
General game playing competitions, such as those held at AAAI, supply each agent with the rules of a previously unseen game and ask it to play strongly against opponents. Because there is no time to design a domain-specific evaluator, MCTS-based agents have dominated general game playing since their introduction.[3] CadiaPlayer, developed by Hilmar Finnsson and Yngvi Bjornsson at Reykjavik University, was the first MCTS-based general game player and won the 2007 and 2008 AAAI General Game Playing competitions.[3][21]
How does MCTS compare with other search methods?
MCTS occupies a particular niche in the landscape of decision-time planning algorithms. For decades the strongest chess and shogi programs used alpha-beta search with handcrafted evaluation, and the AlphaZero paper argued that "the high performance of AlphaZero, using MCTS, calls into question the widely held belief" that alpha-beta search is inherently superior in these domains.[10] Since then the two approaches have borrowed from each other: Leela Chess Zero, an open reproduction of AlphaZero for chess, won the Top Chess Engine Championship in 2019, while top alpha-beta engines replaced their handcrafted evaluation functions with efficiently updatable neural networks (NNUE).[13] Pure UCT has been the dominant approach in general game playing because it requires no domain knowledge.[3] MCTS with neural network guidance (PUCT) has been the basis of the strongest Go programs since AlphaGo.[8][9][26] Best-first heuristic search such as A* and IDA* remains the natural choice for single-agent shortest path problems with admissible heuristics.
Implementations and software
Fuego is a long-standing open-source framework for board games and an MCTS Go engine developed at the University of Alberta.[20] Pachi is a strong open-source MCTS Go program.[20] KataGo is a self-play MCTS Go engine in the AlphaZero tradition; its paper reports a 50x reduction in computation over comparable methods, and its maintainers describe it as one of the strongest open-source Go bots available.[26][39] Leela Zero is an open-source reimplementation of AlphaGo Zero for Go, and Leela Chess Zero was created to reproduce AlphaZero's results in chess.[13][40] OpenSpiel is DeepMind's framework for reinforcement learning research in games and includes MCTS and AlphaZero.[36] LightZero is a benchmark and library, presented at NeurIPS 2023, with a PyTorch implementation of AlphaZero, MuZero, Sampled MuZero, Stochastic MuZero, EfficientZero, and Gumbel MuZero.[37] Mctx is DeepMind's JAX-native library implementing AlphaZero, MuZero, and Gumbel MuZero search, designed to run batched searches on accelerators.[38] LightZero and Mctx are Python libraries built on PyTorch and JAX respectively, while KataGo and Fuego are written in C++.[20][37][38][39]
Limitations and ongoing research
Despite its successes, MCTS has open problems. Sparse-reward environments such as long-horizon robotics tasks present extreme difficulty because random rollouts almost never reach a positive reward. Tactical positions with shallow traps, common in chess, are harder for UCT than for iterative-deepening minimax search.[3] Continuous action spaces require sampling-based variants such as progressive widening, kernel regression UCT (KR-UCT), or Sampled MuZero.[3][12][42]
The simulation budget remains a concern. The distributed AlphaGo described in the 2016 paper used 40 search threads, 1,202 CPUs, and 176 GPUs; the 1,920-CPU, 280-GPU figure sometimes given for the Lee Sedol match is the largest configuration in that paper's scalability tests, which were played at 2 seconds per move.[8] The AlphaGo Zero paper says that AlphaGo Lee, the version that played Lee Sedol, was distributed over many machines and used 48 TPUs, while AlphaGo Zero played on a single machine with 4 TPUs.[9] Each AlphaGo Zero self-play move still used 1,600 MCTS simulations, about 0.4 seconds of thinking time.[9] Reducing the number of simulations while preserving strength is an active area of research; Gumbel MuZero, for example, targets planning with very few simulations.[13] For LLM-based MCTS, where each expansion requires running a large model, DeepSeek reported that the search space of token generation and the difficulty of training a fine-grained value model made MCTS hard to scale during training.[33]
Theoretically, the guarantees of UCT are stated for problems with bounded rewards and finite horizons, conditions that are sometimes violated in practice.[2] MuZero, for instance, normalizes its value estimates using the range seen in the search tree because values in many environments are unbounded.[11] Bayesian variants keep uncertainty estimates over node values; Gerald Tesauro, V. T. Rajan, and Richard Segal proposed a Bayesian MCTS formalism with convergence proofs in 2010.[3][41] More recent work has combined MCTS with learned environment models (MuZero and its successors) and with pretrained language models (AlphaProof and rStar-Math).[11][16][19]
Continue reading
- AlphaZeroAlphaZero is a general-purpose reinforcement learning algorithm developed by DeepMind that taught itself to play chess, shogi (Japanese chess), and Go at a superhuman level from scratch, using only the rules…Mentioned 46 times above
- AlphaGoAlphaGo is a computer program developed by DeepMind that plays the board game Go, and it was the first program to defeat a human professional Go player on a full 19x19 board without a handicap.Mentioned 32 times above
- MuZeroMuZero is a model-based reinforcement learning algorithm developed by DeepMind that reached superhuman play in Go, chess, and shogi and set a new state of the art on the 57-game Atari benchmark without being…Mentioned 30 times above
- Neural NetworkA neural network (also called an artificial neural network or ANN) is a computational model, loosely inspired by the networks of biological neurons in animal brainsMentioned 16 times above
- Google DeepMindGoogle DeepMind is an artificial intelligence research and model-development organization at Google.Mentioned 14 times above
- Reinforcement learningReinforcement learning (RL) is a branch of machine learning in which an agent learns to make decisions by taking actions in an environment to maximize a cumulative reward signal, discovering good behavior…Mentioned 5 times above
More from See also
More to read
References
- ^1 ^2 ^3 ^4Coulom, R. (2006). "Efficient Selectivity and Backup Operators in Monte-Carlo Tree Search." In H. J. van den Herik, P. Ciancarini, and H. H. L. M. Donkers (Eds.), Computers and Games, 5th International Conference, CG 2006, Lecture Notes in Computer Science, vol. 4630, pp. 72 to 83, Springer.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Kocsis, L., and Szepesvari, C. (2006). "Bandit Based Monte-Carlo Planning." In J. Furnkranz, T. Scheffer, and M. Spiliopoulou (Eds.), Machine Learning: ECML 2006, Lecture Notes in Computer Science, vol. 4212, pp. 282 to 293, Springer. link.springer.com/...11871842_29
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32 ^33 ^34 ^35 ^36 ^37 ^38 ^39 ^40 ^41Browne, C., Powley, E., Whitehouse, D., Lucas, S. M., Cowling, P. I., Rohlfshagen, P., Tavener, S., Perez, D., Samothrakis, S., and Colton, S. (2012). "A Survey of Monte Carlo Tree Search Methods." IEEE Transactions on Computational Intelligence and AI in Games, 4(1), 1 to 43.
- ^1 ^2 ^3Auer, P., Cesa-Bianchi, N., and Fischer, P. (2002). "Finite-time Analysis of the Multiarmed Bandit Problem." Machine Learning, 47(2 to 3), 235 to 256.
- ^Brugmann, B. (1993). "Monte Carlo Go." Technical report, Max-Planck-Institute of Physics, Munich, October 9, 1993.
- ^Gelly, S., and Silver, D. (2007). "Combining Online and Offline Knowledge in UCT." Proceedings of the 24th International Conference on Machine Learning, pp. 273 to 280.
- ^1 ^2 ^3 ^4Gelly, S., and Silver, D. (2011). "Monte-Carlo Tree Search and Rapid Action Value Estimation in Computer Go." Artificial Intelligence, 175(11), 1856 to 1875.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11Silver, D., Huang, A., Maddison, C. J., Guez, A., Sifre, L., van den Driessche, G., Schrittwieser, J., Antonoglou, I., Panneershelvam, V., Lanctot, M., Dieleman, S., Grewe, D., Nham, J., Kalchbrenner, N., Sutskever, I., Lillicrap, T., Leach, M., Kavukcuoglu, K., Graepel, T., and Hassabis, D. (2016). "Mastering the game of Go with deep neural networks and tree search." Nature, 529(7587), 484 to 489.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14Silver, D., Schrittwieser, J., Simonyan, K., Antonoglou, I., Huang, A., Guez, A., Hubert, T., Baker, L., Lai, M., Bolton, A., Chen, Y., Lillicrap, T., Hui, F., Sifre, L., van den Driessche, G., Graepel, T., and Hassabis, D. (2017). "Mastering the game of Go without human knowledge." Nature, 550(7676), 354 to 359.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Silver, D., Hubert, T., Schrittwieser, J., Antonoglou, I., Lai, M., Guez, A., Lanctot, M., Sifre, L., Kumaran, D., Graepel, T., Lillicrap, T., Simonyan, K., and Hassabis, D. (2018). "A general reinforcement learning algorithm that masters chess, shogi, and Go through self-play." Science, 362(6419), 1140 to 1144.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13Schrittwieser, J., Antonoglou, I., Hubert, T., Simonyan, K., Sifre, L., Schmitt, S., Guez, A., Lockhart, E., Hassabis, D., Graepel, T., Lillicrap, T., and Silver, D. (2020). "Mastering Atari, Go, chess and shogi by planning with a learned model." Nature, 588(7839), 604 to 609. Preprint: arxiv.org/...1911.08265
- ^1 ^2Hubert, T., Schrittwieser, J., Antonoglou, I., Barekatain, M., Schmitt, S., and Silver, D. (2021). "Learning and Planning in Complex Action Spaces." Proceedings of the 38th International Conference on Machine Learning, PMLR 139, 4476 to 4486. arxiv.org/...2104.06303
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Danihelka, I., Guez, A., Schrittwieser, J., and Silver, D. (2022). "Policy improvement by planning with Gumbel." Proceedings of the International Conference on Learning Representations (ICLR). openreview.net/forum
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Fawzi, A., Balog, M., Huang, A., Hubert, T., Romera-Paredes, B., Barekatain, M., Novikov, A., Ruiz, F. J. R., Schrittwieser, J., Swirszcz, G., Silver, D., Hassabis, D., and Kohli, P. (2022). "Discovering faster matrix multiplication algorithms with reinforcement learning." Nature, 610(7930), 47 to 53. nature.com/...s41586-022-05172-4
- ^1 ^2 ^3 ^4 ^5 ^6Mankowitz, D. J., Michi, A., Zhernov, A., Gelmi, M., Selvi, M., Paduraru, C., Leurent, E., Iqbal, S., Lespiau, J. B., Ahern, A., Koppe, T., Millikin, K., Gaffney, S., Elster, S., Broshear, J., Gamble, C., Milan, K., Tung, R., Hwang, M., Cemgil, T., Barekatain, M., Li, Y., Mandhane, A., Hubert, T., Schrittwieser, J., Hassabis, D., Kohli, P., Riedmiller, M., Vinyals, O., and Silver, D. (2023). "Faster sorting algorithms discovered using deep reinforcement learning." Nature, 618(7964), 257 to 263. nature.com/...s41586-023-06004-9
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11Hubert, T., Mehta, R., Sartran, L., et al. (2025). "Olympiad-level formal mathematical reasoning with reinforcement learning." Nature, 651, 607 to 613 (published online November 12, 2025; issue dated March 19, 2026). nature.com/...s41586-025-09833-y . See also Google DeepMind (July 25, 2024), "AI achieves silver-medal standard solving International Mathematical Olympiad problems," deepmind.google/...-problems-at-silver-medal-level
- ^1 ^2 ^3 ^4Yao, S., Yu, D., Zhao, J., Shafran, I., Griffiths, T. L., Cao, Y., and Narasimhan, K. (2023). "Tree of Thoughts: Deliberate Problem Solving with Large Language Models." Advances in Neural Information Processing Systems 36 (NeurIPS). arxiv.org/...2305.10601
- ^1 ^2 ^3 ^4Hao, S., Gu, Y., Ma, H., Hong, J. J., Wang, Z., Wang, D. Z., and Hu, Z. (2023). "Reasoning with Language Model is Planning with World Model." Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing (EMNLP), 8154 to 8173. arxiv.org/...2305.14992
- ^1 ^2 ^3 ^4 ^5Guan, X., Zhang, L. L., Liu, Y., Shang, N., Sun, Y., Zhu, Y., Yang, F., and Yang, M. (2025). "rStar-Math: Small LLMs Can Master Math Reasoning with Self-Evolved Deep Thinking." Proceedings of the 42nd International Conference on Machine Learning (ICML 2025), PMLR 267, 20640 to 20661. arxiv.org/...2501.04519
- ^1 ^2 ^3 ^4Enzenberger, M., Muller, M., Arneson, B., and Segal, R. (2010). "Fuego: An Open-Source Framework for Board Games and Go Engine Based on Monte Carlo Tree Search." IEEE Transactions on Computational Intelligence and AI in Games, 2(4), 259 to 270.
- ^Bjornsson, Y., and Finnsson, H. (2009). "CadiaPlayer: A Simulation-Based General Game Player." IEEE Transactions on Computational Intelligence and AI in Games, 1(1), 4 to 15.
- ^Chaslot, G., Winands, M. H. M., and van den Herik, H. J. (2008). "Parallel Monte-Carlo Tree Search." Computers and Games, Lecture Notes in Computer Science, vol. 5131, pp. 60 to 71, Springer.
- ^Cazenave, T. (2015). "Generalized Rapid Action Value Estimation." Proceedings of the 24th International Joint Conference on Artificial Intelligence (IJCAI), pp. 754 to 759. ijcai.org/...112
- ^Winands, M. H. M., Bjornsson, Y., and Saito, J. T. (2008). "Monte-Carlo Tree Search Solver." Computers and Games, Lecture Notes in Computer Science, vol. 5131, pp. 25 to 36, Springer.
- ^Tesauro, G., and Galperin, G. R. (1996). "On-line Policy Improvement using Monte-Carlo Search." Advances in Neural Information Processing Systems 9, 1068 to 1074.
- ^1 ^2Wu, D. J. (2019). "Accelerating Self-Play Learning in Go." arXiv:1902.10565. arxiv.org/...1902.10565
- ^1 ^2Silver, D., Hubert, T., Schrittwieser, J., Antonoglou, I., Lai, M., Guez, A., Lanctot, M., Sifre, L., Kumaran, D., Graepel, T., Lillicrap, T., Simonyan, K., and Hassabis, D. (2017). "Mastering Chess and Shogi by Self-Play with a General Reinforcement Learning Algorithm." arXiv:1712.01815. arxiv.org/...1712.01815
- ^1 ^2 ^3Google DeepMind. "AlphaGo." Research page, accessed October 30, 2026. deepmind.google/...alphago
- ^ICGA Tournaments. "Crazy Stone" (program record: Go 9x9, 2006, Turin, gold medal). game-ai-forum.org/...program
- ^1 ^2Gelly, S., and Silver, D. (2008). "Achieving Master Level Play in 9 x 9 Computer Go." Proceedings of the Twenty-Third AAAI Conference on Artificial Intelligence, pp. 1537 to 1540.
- ^Rosin, C. D. (2011). "Multi-armed bandits with episode context." Annals of Mathematics and Artificial Intelligence, 61, 203 to 230.
- ^Feng, X., Wan, Z., Wen, M., McAleer, S. M., Wen, Y., Zhang, W., and Wang, J. (2023). "Alphazero-like Tree-Search can Guide Large Language Model Decoding and Training." arXiv:2309.17179. arxiv.org/...2309.17179
- ^1 ^2DeepSeek-AI (2025). "DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning." arXiv:2501.12948 (version 1, January 22, 2025, section 4.2 "Unsuccessful Attempts"); later published in Nature, 645, 633 to 638 (2025). arxiv.org/...2501.12948
- ^Hoel, C.-J., Driggs-Campbell, K., Wolff, K., Laine, L., and Kochenderfer, M. J. (2019). "Combining Planning and Deep Reinforcement Learning in Tactical Decision Making for Autonomous Driving." IEEE Transactions on Intelligent Vehicles. arXiv:1905.02680. arxiv.org/...1905.02680
- ^Ye, W., Liu, S., Kurutach, T., Abbeel, P., and Gao, Y. (2021). "Mastering Atari Games with Limited Data." Advances in Neural Information Processing Systems 34 (NeurIPS 2021). arXiv:2111.00210. arxiv.org/...2111.00210
- ^Lanctot, M., Lockhart, E., Lespiau, J.-B., Zambaldi, V., Upadhyay, S., Perolat, J., Srinivasan, S., Timbers, F., Tuyls, K., et al. (2019). "OpenSpiel: A Framework for Reinforcement Learning in Games." arXiv:1908.09453. arxiv.org/...1908.09453
- ^1 ^2Niu, Y., Pu, Y., Yang, Z., Li, X., Zhou, T., Ren, J., Hu, S., Li, H., Liu, Y., et al. (2023). "LightZero: A Unified Benchmark for Monte Carlo Tree Search in General Sequential Decision Scenarios." NeurIPS 2023. arXiv:2310.08348. arxiv.org/...2310.08348
- ^1 ^2Google DeepMind. "Mctx: MCTS-in-JAX." GitHub repository README, accessed October 30, 2026. github.com/...mctx
- ^1 ^2Wu, D. J. "KataGo." GitHub repository README, accessed October 30, 2026. github.com/...KataGo
- ^Leela Zero contributors. "Leela Zero." GitHub repository README, accessed October 30, 2026. github.com/...leela-zero
- ^Tesauro, G., Rajan, V. T., and Segal, R. (2010). "Bayesian Inference in Monte-Carlo Tree Search." Proceedings of the Conference on Uncertainty in Artificial Intelligence (UAI), pp. 580 to 588.
- ^Yee, T., Lisy, V., and Bowling, M. (2016). "Monte Carlo Tree Search in Continuous Action Spaces with Execution Uncertainty." Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence (IJCAI), pp. 690 to 696. ijcai.org/...104
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
11 revisions · v11 · 8,112 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Fact-checked on 2026-10-30 against the original MCTS, UCT, AlphaGo, AlphaGo Zero, AlphaZero, MuZero, AlphaTensor, AlphaDev and AlphaProof papers, the Browne et al. survey, ICGA records, and the LLM tree-search papers cited, with an independent second review.
Cite this page: AI Wiki. "Monte Carlo Tree Search." aiwiki.ai, updated 30 Oct 2026, fact-checked 30 Oct 2026. CC BY 4.0. https://aiwiki.ai/wiki/monte_carlo_tree_search