

MuZero
MuZero is a model-based reinforcement learning algorithm developed by DeepMind that reached superhuman play in Go, chess, and shogi and set a new state of the art on the 57-game Atari benchmark without being given a simulator of the environment's rules. It was introduced in an arXiv preprint on 19 November 2019 and published in Nature on 23 December 2020. MuZero is the direct successor to AlphaZero and the broader AlphaGo lineage.[1][13] Its central innovation is that it learns its own internal model of environment dynamics, then plans inside that learned model using Monte Carlo tree search, rather than relying on a hand-coded simulator. The Nature paper reports that on Go, chess, and shogi, MuZero "matched, without any knowledge of the game dynamics, the superhuman performance of the AlphaZero algorithm that was supplied with the rules of the game," while also achieving state of the art performance on the 57 game Atari benchmark, a visually complex domain where model-based planning had historically struggled and where MuZero, unlike AlphaZero, was given no access to the environment's dynamics during search.[1][13]
MuZero's first application outside games was at Google: DeepMind and YouTube used a MuZero-based rate controller in the open source VP9 video codec, and after launching it on a portion of YouTube's live traffic DeepMind reported an average 4% bitrate reduction across a large, diverse set of videos.[4] A family of variants extends MuZero to continuous action spaces, stochastic environments, sample efficient learning, and offline data, including Sampled MuZero, Stochastic MuZero, MuZero Reanalyse and MuZero Unplugged, EfficientZero, and Gumbel MuZero.[5][6][7][8][9] Two later DeepMind algorithm-discovery systems that are often grouped with MuZero, AlphaTensor (2022) and AlphaDev (2023), are described in their own papers as built on AlphaZero rather than MuZero; AlphaTensor did use the sampled search developed in the Sampled MuZero paper, in its AlphaZero form.[2][3][11]
What problem does MuZero solve?
From AlphaGo to AlphaZero
MuZero sits at the end of a multi year research program at DeepMind that began with AlphaGo in 2016. AlphaGo combined supervised learning from expert human games, reinforcement learning from self play, and Monte Carlo tree search to defeat the top professional Go player Lee Sedol in 2016. AlphaGo Zero, introduced in 2017, removed the dependency on human games and learned entirely from self play, using a single neural network that output both a move policy and a value estimate. AlphaZero generalized AlphaGo Zero to chess and shogi using the same algorithm and architecture, again learning from scratch through self play guided by Monte Carlo tree search.[1]
Despite their power, these systems shared one assumption: each required a perfect simulator of the game. The MuZero paper lists three places where AlphaGo Zero and AlphaZero used knowledge of the rules: state transitions in the search tree, the actions available at each node, and episode termination within the tree.[13] This requirement was acceptable in board games where rules are known and easy to encode, but it ruled out problems where the dynamics are unknown or visually complex. The paper notes that lookahead planning algorithms all rely on knowledge of the environment's dynamics, "such as the rules of the game or an accurate simulator, preventing their direct application to real-world domains like robotics, industrial control, or intelligent assistants."[13] The MuZero project asked whether a planning agent could reach AlphaZero-level performance without being given those rules.
Model based reinforcement learning
Reinforcement learning algorithms are commonly divided into model free and model based methods. Model free methods such as Q learning, DQN, and policy gradient algorithms learn a value function or policy directly from experience, without an explicit representation of how the environment behaves. Model based methods first learn a transition model, often called a world model, that predicts the next observation and reward given a current state and an action, and then use that model for planning. The MuZero paper notes that model-based planning approaches had "historically struggled" on Atari, where the best results before MuZero came from model-free systems such as R2D2.[13][10]
MuZero takes a distinctive position inside this design space. Rather than learning a model that reconstructs full pixel observations or full game states, it learns a model whose only obligation is to predict the quantities that planning actually needs: the action policy, the value of the position, and the immediate reward. The paper places this in the line of value equivalent models, which require that, starting from the same real state, "the cumulative reward of a trajectory through the abstract MDP matches the cumulative reward of a trajectory in the real environment," with no requirement that the model reproduce the observations.[13] By relaxing the modeling target, MuZero can learn internal representations that need bear no visual or symbolic resemblance to the true environment yet remain accurate enough to drive a tree search. In the words of the 2019 preprint, MuZero "learns a model that, when applied iteratively, predicts the quantities most directly relevant to planning: the reward, the action-selection policy, and the value function."[13] The Nature abstract puts it as "an iterable model that produces predictions relevant to planning: the action-selection policy, the value function and the reward."[1]
How does the MuZero algorithm work?
MuZero combines three learned functions with a search procedure. At inference time, given a sequence of observations, the algorithm encodes them into a hidden state and then runs a Monte Carlo tree search inside the hidden state space to choose the next action. At training time, all three functions are optimized jointly so that the predictions made along simulated trajectories match the targets collected from real play.
The three networks
The MuZero model has three components, each implemented as a deep neural network and trained end to end.[1]
The representation function maps the recent history of raw observations to an initial hidden state. In a board game it consumes a stack of recent positions, and in Atari it consumes a stack of recent frames. Formally, , where is the initial hidden state used to seed planning. The representation function is purely an encoder. It does not need to be invertible and does not have to reconstruct the input.
The dynamics function models how the hidden state evolves under actions. Given a hidden state and an action , it produces a successor hidden state and a predicted immediate reward: . This is the learned analogue of an environment simulator. It runs entirely inside the abstract latent space and never touches raw pixels or board configurations after the first encoding.
The prediction function maps a hidden state to a policy and a value: . The policy is a probability distribution over actions and the value estimates the expected return from that hidden state. Together, and play the role that a hand coded simulator and a value network would play in AlphaZero.
The table below summarizes the role of each component.
| Component | Symbol | Inputs | Outputs | Role |
|---|---|---|---|---|
| Representation function | Sequence of past observations | Initial hidden state | Encodes raw observations into a planning friendly latent state | |
| Dynamics function | Hidden state and action | Next hidden state and predicted reward | Learned model of environment transitions and rewards | |
| Prediction function | Hidden state | Policy and value | Provides priors and value estimates that guide MCTS |
A key conceptual point is that the hidden state has no semantics imposed by the designer. It is whatever vector representation the network finds useful for predicting reward, value, and policy along simulated trajectories. The model is therefore not constrained to match the true mechanics of the world; it only has to be value equivalent to the true world along the trajectories it explores.
In the published experiments, the representation function used the same convolutional and residual architecture as AlphaZero but with 16 residual blocks instead of 20; the dynamics function used the same architecture as the representation function; and all networks used 256 hidden planes.[13]
Planning with Monte Carlo tree search
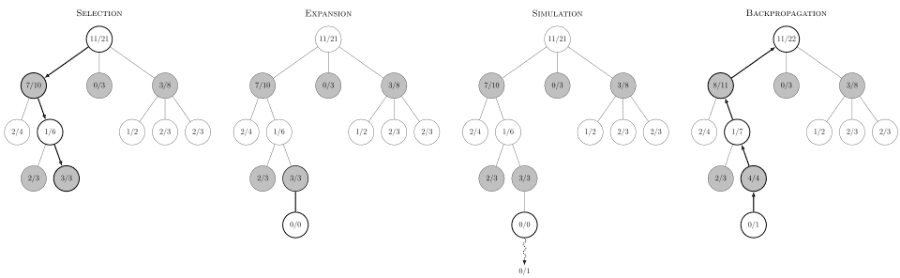
MuZero plans using a variant of the Monte Carlo tree search procedure introduced in AlphaGo Zero and AlphaZero, generalized to single-agent domains with intermediate rewards.[13] The root of the search tree is the initial hidden state produced by the representation function. Each edge corresponds to an action. Each simulation of the search proceeds in three phases.
During selection, the search descends the tree by repeatedly choosing the action that maximizes an upper confidence bound that combines the policy prior, the visit count, and the running value estimate. This is the same PUCT style rule used by AlphaZero, adapted to operate over hidden states.
During expansion and evaluation, when the search reaches a leaf, it applies the dynamics function to obtain a new hidden state and a predicted reward, then applies the prediction function to obtain a policy and value for that new state. The value is backed up along the visited path, accumulating predicted rewards along the way.
During backup, statistics for visited edges are updated. After all simulations are complete, the agent samples or selects an action based on the visit counts at the root.
This search runs inside the learned latent space, and the agent does not step the real environment during planning. The one point of contact with the real rules is the root: MuZero masks illegal actions at the root of the search tree, "where the environment can be queried," but performs no masking inside the tree, relying on the network having learned not to predict actions that never occur in its training trajectories. It also gives no special treatment to terminal states inside the tree, which are learned as absorbing states.[13] In the published experiments, MuZero used 800 simulations per search in board games, the same as AlphaZero, and 50 simulations per search in Atari, where the paper cites the much smaller branching factor.[1][13]
How is MuZero trained?
MuZero generates its own training data by acting with search (self play in the board games) and stores each trajectory in a replay buffer. To form a training example, a starting state is sampled from the buffer and the network is unrolled for hypothetical steps using the actual actions that were taken. At each unrolled step, the model produces predictions of policy, value, and reward, and these are compared against three targets.
The policy target is the visit count distribution that MCTS produced at the corresponding real step. This is the same self play improvement signal that AlphaZero uses: the search is treated as a stronger policy than the network alone, and the network is trained to match it.
The value target is an n step bootstrapped return computed from the actual rewards observed in the trajectory plus a discounted search value at a later state. In board games, where win, draw, and loss are treated as a final reward, this is the game outcome; in Atari the paper bootstraps 10 steps into the future.[13]
The reward target is the actual reward observed at the corresponding real step.
The loss is the sum of cross entropy or squared error terms for each prediction at each unrolled step, plus an L2 weight regularization term. Board games used the same squared error loss as AlphaZero for values and rewards, while Atari used a cross entropy loss, which the authors found more stable for rewards and values of variable scale. All three functions are differentiated through the unrolled hidden state trajectory and updated jointly.[13]
The experiments unrolled the model for hypothetical steps and trained for 1 million mini-batches, of size 2048 in board games and 1024 in Atari. The arXiv version reports that all experiments ran on third-generation Google Cloud TPUs: for each board game, 16 TPUs for training and 1,000 TPUs for self play; for each Atari game, 8 TPUs for training and 32 for self play.[13]
Why is a learned model enough?
The central claim of MuZero is that an internal model only needs to be accurate where it matters for planning. Earlier model based methods often tried to learn pixel perfect or state accurate models, spending capacity on details that may be irrelevant to good decisions. By training the model end to end against the same quantities that drive search and policy improvement, MuZero focuses learning capacity on the parts of the world that change action choice. Empirically, this allowed MuZero to match a system, AlphaZero, that had access to perfect rules.[1]
What results did MuZero achieve?
The MuZero paper reported results on four benchmark sets: Go, chess, shogi, and the 57 game Arcade Learning Environment (Atari).[1] The figures below are from the arXiv version of the paper (v2, February 2020); the Atari per-game data in the Nature supplementary information match it.[13][1]
In Go, MuZero "slightly exceeded the performance of AlphaZero, despite using less computation per node in the search tree" (16 residual blocks per evaluation against AlphaZero's 20).[13] When the fully trained networks were given more thinking time, MuZero's learned model kept pace with AlphaZero's perfect simulator even for searches of up to 10 seconds per move, about two orders of magnitude longer than the roughly 0.1 seconds per search it was trained with.[13] DeepMind's announcement of the Nature paper put it this way: playing strength "increases by more than 1000 Elo" as time per move rises from one-tenth of a second to 50 seconds, which it compared to "the difference between a strong amateur player and the strongest professional player."[10]
In chess and shogi, MuZero matched AlphaZero's superhuman performance.[1] It did so without a rules engine inside the search: as described above, its only use of the rules during planning is the legal-move mask at the root.[13]
In Atari, MuZero set a new state of the art for both mean and median human-normalized score across the 57 games, outperforming the previous best method, the model-free R2D2, in 42 of 57 games, and the earlier model-based method SimPLe in all 36 games on which SimPLe had been evaluated.[13] MuZero achieved this without access to the Atari emulator's dynamics during planning: its search ran entirely inside the learned model.[13]
| Agent | Median | Mean | Environment frames | Training time | Training steps |
|---|---|---|---|---|---|
| Ape-X | 434.1% | 1695.6% | 22.8B | 5 days | 8.64M |
| R2D2 | 1920.6% | 4024.9% | 37.5B | 5 days | 2.16M |
| MuZero | 2041.1% | 4999.2% | 20.0B | 12 hours | 1M |
| MuZero Reanalyze | 731.1% | 2168.9% | 200M | 12 hours | 1M |
Human-normalized Atari scores from Table 1 of the arXiv version. The MuZero Reanalyze row is the low-data (200 million frame) setting, where the previous best median scores cited by the paper were 192% (IMPALA), 231% (Rainbow), and 431% (LASER).[13]
DeepMind filed a Greek patent application, GR20200100037, covering the MuZero algorithm on 28 January 2020, according to the competing-interests statement of the Nature paper. The Nature paper released the algorithm as pseudocode in its supplementary information.[1]
The table below summarizes how MuZero relates to its immediate predecessors.
| Property | AlphaGo (2016) | AlphaZero (2017) | MuZero (2019) |
|---|---|---|---|
| Domains | Go | Go, chess, shogi | Go, chess, shogi, 57 Atari games |
| Human data required | Yes, supervised pretraining | No, learns from self play | No, learns from self play |
| Rules of the environment | Required | Required | Not required in the search tree (legal moves masked at the root only) |
| Simulator | Hand coded perfect simulator | Hand coded perfect simulator | Learned dynamics network |
| Search algorithm | Monte Carlo tree search | Monte Carlo tree search | Monte Carlo tree search in latent space |
| Visual inputs | Board features | Board features | Raw pixels for Atari, board features for others |
| Atari support | No | No | Yes |
What are the main MuZero variants?
Since its publication, MuZero has spawned an active line of research that extends it to settings the original algorithm could not handle and improves its sample efficiency.
MuZero Reanalyse and MuZero Unplugged
MuZero Reanalyse (spelled "Reanalyze" in the original paper) was introduced in the MuZero paper as a more sample efficient variant and examined in depth in a 2021 follow up by Schrittwieser, Hubert, and colleagues, published at NeurIPS 2021.[13][5] The idea is to revisit older trajectories in the replay buffer and re run MCTS on them using the latest version of the network, producing fresh policy and value targets without any new environment interaction. In the original paper this fresh policy served as the policy target for 80% of updates, and the variant reached a 731.1% median normalized score on Atari with 200 million frames per game.[13] The 2021 paper introduced MuZero Unplugged, which combines Reanalyse with MuZero into a single algorithm for any data budget, including fully offline learning from a fixed dataset, by varying the fraction of training targets computed through Reanalyse. MuZero Unplugged set new state of the art results on the RL Unplugged offline benchmark and on online Atari in the standard 200 million frame setting.[5]
Sampled MuZero
Sampled MuZero, introduced by Hubert and colleagues at ICML 2021, extends MuZero to environments with very large or continuous action spaces. The original MuZero enumerates every action at each tree node, which is impossible when actions are continuous vectors or when the action set is combinatorially large. Sampled MuZero instead draws a small set of candidate actions at each node and runs MCTS over only those samples, and the paper provides a framework for policy evaluation and improvement over such sampled subsets. In Go, with only 50 of 362 possible actions sampled, it closely approached the baseline that searches all actions; in the Atari game Ms. Pac-Man, three samples out of 18 actions were enough to approach the baseline. It also learned continuous control tasks on the DeepMind Control Suite, from both state and raw pixel inputs, and on the Real-World RL Suite.[6]
Stochastic MuZero
Stochastic MuZero, introduced by Antonoglou and colleagues at ICLR 2022, extends MuZero to environments with intrinsic randomness. Earlier versions of the approach were limited to deterministic models. In games like backgammon or 2048, parts of the state transition are governed by dice rolls or random tile spawns, which a deterministic model cannot represent. Stochastic MuZero factors each transition into a deterministic step from the current state to an afterstate, then a stochastic step from the afterstate to the next state, conditioned on a learned discrete chance outcome. The factored model is trained to stay value equivalent and is used by a stochastic variant of tree search. Stochastic MuZero "matched or exceeded the state of the art" in environments including 2048 and backgammon "while maintaining the same performance as standard MuZero in the game of Go."[7]
EfficientZero and EfficientZero V2
EfficientZero, introduced by Ye and colleagues (Tsinghua University and UC Berkeley) at NeurIPS 2021, is a sample efficient variant of MuZero designed for the Atari 100k benchmark, where agents get only 100,000 environment steps, about two hours of real-time game experience. EfficientZero adds three changes to MuZero: a self supervised consistency loss that ties together hidden states predicted by the dynamics model and hidden states encoded from real observations, end to end prediction of the value prefix (the sum of rewards over a span) to reduce compounding error in reward prediction, and a model-based off-policy correction for stale value targets in the replay buffer. EfficientZero achieved 194.3% mean and 109.0% median human normalized score on Atari 100k; the authors called it "the first time an algorithm achieves super-human performance on Atari games with such little data," and reported performance close to DQN at 200 million frames while using 500 times less data.[8]
EfficientZero V2, by Shengjie Wang, Shaohuai Liu, Weirui Ye, Jiacheng You, and Yang Gao, was published at ICML 2024. It extends the approach to continuous control and low-dimensional inputs, with two main additions: a sampling-based Gumbel search for action planning and a search-based value estimation that makes better use of older data. For continuous actions it uses a Gaussian policy, an idea it credits to Sampled MuZero. The authors report that it outperformed DreamerV3 on 50 of 66 evaluated tasks across Atari 100k and proprioceptive and vision-based control benchmarks.[15]
Gumbel MuZero and Gumbel AlphaZero
Gumbel MuZero, by Danihelka, Guez, Schrittwieser, and Silver at ICLR 2022, addresses a weakness the paper identifies in AlphaZero-style search: the policy network can fail to improve when not all actions at the root are visited. At the root, it samples actions without replacement using the Gumbel-Top-k trick and allocates simulations among them with Sequential Halving; at non-root nodes, it replaces the PUCT rule with a selection rule derived from the same policy improvement idea. According to the paper, Gumbel AlphaZero and Gumbel MuZero "match the state of the art on Go, chess, and Atari, and significantly improve prior performance when planning with few simulations."[9]
Other related work
Muesli, by Hessel and colleagues at DeepMind (2021), combines regularized policy optimization with model learning as an auxiliary loss. It matches MuZero's state of the art Atari performance "without using deep search": it acts directly with a policy network and runs at a computation speed comparable to model-free baselines.[14] DreamerV3 by Hafner and colleagues belongs to a different family of world model based reinforcement learning. Unlike MuZero, its world model is trained partly to reconstruct observations, and it improves its behavior by learning inside imagined rollouts rather than by planning with explicit tree search. DreamerV3 outperformed specialized methods across more than 150 diverse tasks with a single hyperparameter configuration, and was the first algorithm to collect diamonds in Minecraft from scratch without human data or curricula.[12] It is often compared with MuZero because the two make different choices about whether to reconstruct observations and whether to plan with explicit search (see Dreamer).
The table below summarizes the main MuZero variants and their target settings.
| Variant | Year | Authors | Key contribution | Target setting |
|---|---|---|---|---|
| MuZero | 2019, Nature 2020 | Schrittwieser et al. | Original learned model and MCTS planning | Discrete actions, deterministic environments, Go, chess, shogi, Atari |
| MuZero Reanalyse and Unplugged | 2021, NeurIPS | Schrittwieser, Hubert et al. | Reanalysing old data with the latest model, unified online and offline RL | Sample efficient and offline RL |
| Sampled MuZero | 2021, ICML | Hubert et al. | MCTS over sampled actions | Continuous and combinatorial action spaces |
| Stochastic MuZero | 2022, ICLR | Antonoglou et al. | Afterstate factorization and learned chance outcomes | Stochastic environments such as backgammon and 2048 |
| EfficientZero | 2021, NeurIPS | Ye et al. | Self supervised consistency loss, value prefix, off-policy correction | Sample efficient visual RL, Atari 100k |
| EfficientZero V2 | 2024, ICML | Wang et al. | Sampling-based Gumbel search and search-based value estimation | Discrete and continuous control with limited data |
| Gumbel MuZero | 2022, ICLR | Danihelka et al. | Gumbel-Top-k sampling and Sequential Halving at the root | Low simulation budgets |
What is MuZero used for beyond games?
DeepMind presented MuZero as a step toward planning agents for problems where "the rules of the game" are not known, naming robotics and industrial systems as possible targets.[10] Its best documented real-world application is video compression at YouTube.
How is MuZero used for video compression on YouTube?
On 11 February 2022, DeepMind announced that a MuZero based agent had been deployed in a video compression setting at YouTube. The agent, called the MuZero Rate Controller (MuZero-RC), replaces the default rate control in libvpx, the open source implementation of the VP9 codec. For each frame, rate control chooses the quantisation parameter (QP), which sets how much compression to apply; given a target bitrate, these choices are made sequentially to maximize overall video quality. DeepMind described MuZero as well suited to the problem because it works "especially well in large, combinatorial action spaces." To handle the varied objectives and constraints of real video, the team introduced a "self-competition" mechanism that turns them into a simple win/loss signal by comparing the agent's current performance with its own historical performance.[4]
In its evaluation, the accompanying paper reported that MuZero-RC "achieves an average 6.28% reduction in size of the compressed videos for the same delivered video quality level (measured as PSNR BD-rate) compared to libvpx's two-pass VBR rate control policy."[4] After launching to production on a portion of YouTube's live traffic, DeepMind reported "an average 4% bitrate reduction across a large, diverse set of videos," and later described the saving as coming "without compromising on visual quality."[4][11] In June 2023 DeepMind said it had extended the work from per-frame compression decisions to decisions about how frames are grouped and referenced during encoding, leading to further bitrate savings.[11]
AlphaTensor
AlphaTensor, published by Fawzi and colleagues in Nature in October 2022, searches for faster matrix multiplication algorithms. It is sometimes described as a MuZero application, but its paper describes "a deep reinforcement learning approach based on AlphaZero" and does not mention MuZero. It builds on AlphaZero and on "its extension Sampled AlphaZero," the AlphaZero form of the sampled search introduced in the Sampled MuZero paper.[2][6] The task is cast as a single player game called TensorGame, in which the agent decomposes a target tensor that represents a matrix product into a sum of rank one outer products. Each move adds one outer product, and the goal is to reach an exact decomposition using as few moves as possible. The action space exceeds 10^12 actions "for most interesting cases." To handle this scale, AlphaTensor combines sample-based MCTS with synthetic demonstrations, random changes of basis, and data augmentation. It rediscovered the best known algorithms such as Strassen's and Laderman's, and found a way to multiply 4 by 4 matrices in arithmetic modulo 2 with 47 multiplications instead of the 49 required by Strassen's two-level algorithm, which the paper describes as, to the authors' knowledge, the first improvement on Strassen's two-level algorithm since its discovery 50 years earlier. It also found up to thousands of algorithms for each matrix size, including more than 14,000 non-equivalent factorizations for 4 by 4 matrices in standard arithmetic.[2]
AlphaDev
AlphaDev, published by Mankowitz and colleagues in Nature in June 2023, discovered faster sorting routines at the assembly instruction level. Its paper states: "The primary learning algorithm in AlphaDev is an extension of AlphaZero." DeepMind calls it "a version of AlphaZero"; MuZero appears in the paper only as background, described as "a model-based variant of AlphaZero."[3][11] The task is framed as a single player game in which the agent constructs a program one instruction at a time, with rewards that combine correctness and latency. AlphaDev's fixed-length sorting routines for three, four, and five elements gave improvements of up to 70% for sequences of length five and about 1.7% for sequences of more than 250,000 elements. The routines were added to LLVM's libc++ standard sort in April 2022, before the paper appeared, and the authors estimate that they are called trillions of times every day.[3][16]
Why is MuZero significant?
MuZero removed a long standing constraint on the AlphaGo and AlphaZero approach: the dependency on a hand coded simulator inside the search. It showed empirically that a value equivalent learned model can support planning at the level of a perfect simulator in Go, chess, and shogi, and it brought board games and pixel based video games into a single algorithmic framework.[1] It also showed that search can act as a policy improvement operator with a learned model, and its follow-ups carried that recipe into continuous action spaces, stochastic environments, offline learning, and production video compression.[4][5][6][7]
The algorithm has also influenced thinking about the relationship between learning and search in artificial intelligence. AlphaGo Zero and AlphaZero made the case that search dramatically amplifies the strength of a learned policy. MuZero strengthened that case by showing that even the model used during search can itself be learned, leaving little of the original AlphaGo recipe that requires human design.
At the same time, MuZero has limitations that motivated much of the follow up work cited above. The original algorithm enumerates discrete actions and uses a deterministic model, which Sampled MuZero and Stochastic MuZero address.[6][7] Its headline Atari results used 20 billion frames of experience, which MuZero Reanalyse, MuZero Unplugged, and EfficientZero target.[13][5][8] Training used substantial accelerator resources (1,000 TPUs for self play per board game), and DeepMind published pseudocode rather than a full training system.[13][1] Open source reimplementations include the muzero-general project by Werner Duvaud and the EfficientZero codebase released by Ye and colleagues.[17][8]
Continue reading
- AlphaZeroAlphaZero is a general-purpose reinforcement learning algorithm developed by DeepMind that taught itself to play chess, shogi (Japanese chess), and Go at a superhuman level from scratch, using only the rules…Mentioned 34 times above
- Google DeepMindGoogle DeepMind is an artificial intelligence research and model-development organization at Google.Mentioned 17 times above
- AlphaGoAlphaGo is a computer program developed by DeepMind that plays the board game Go, and it was the first program to defeat a human professional Go player on a full 19x19 board without a handicap.Mentioned 12 times above
- Monte Carlo Tree SearchMonte Carlo Tree Search (MCTS) is a heuristic search algorithm for sequential decision-making that finds strong actions by running many simulated playthroughs of a problem and aggregating their outcomes into a…Mentioned 9 times above
- Reinforcement learningReinforcement learning (RL) is a branch of machine learning in which an agent learns to make decisions by taking actions in an environment to maximize a cumulative reward signal, discovering good behavior…Mentioned 6 times above
- AlphaTensorAlphaTensor is an artificial-intelligence system from DeepMind that uses deep reinforcement learning to discover faster algorithms for matrix multiplication.Mentioned 5 times above
More from See also
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13Schrittwieser, J., Antonoglou, I., Hubert, T., Simonyan, K., Sifre, L., Schmitt, S., Guez, A., Lockhart, E., Hassabis, D., Graepel, T., Lillicrap, T., and Silver, D. "Mastering Atari, Go, chess and shogi by planning with a learned model." *Nature* 588, 604-609 (2020), published 23 December 2020. nature.com/...s41586-020-03051-4
- ^1 ^2 ^3Fawzi, A., Balog, M., Huang, A., Hubert, T., Romera Paredes, B., Barekatain, M., Novikov, A., Ruiz, F. J. R., Schrittwieser, J., Swirszcz, G., Silver, D., Hassabis, D., and Kohli, P. "Discovering faster matrix multiplication algorithms with reinforcement learning." *Nature* 610, 47-53 (2022). nature.com/...s41586-022-05172-4
- ^1 ^2 ^3Mankowitz, D. J., Michi, A., Zhernov, A., Gelmi, M., Selvi, M., Paduraru, C., Leurent, E., Iqbal, S., Lespiau, J. B., Ahern, A., Koppe, T., Millikin, K., Gaffney, S., Elster, S., Broshear, J., Gamble, C., Milan, K., Tung, R., Hwang, M., Cemgil, T., Barekatain, M., Li, Y., Mandhane, A., Hubert, T., Schrittwieser, J., Hassabis, D., Kohli, P., Riedmiller, M., Vinyals, O., and Silver, D. "Faster sorting algorithms discovered using deep reinforcement learning." *Nature* 618, 257-263 (2023). nature.com/...s41586-023-06004-9
- ^1 ^2 ^3 ^4 ^5Mandhane, A., Zhernov, A., Rauh, M., et al. "MuZero with Self-competition for Rate Control in VP9 Video Compression." arXiv preprint arXiv:2202.06626, 2022. arxiv.org/...2202.06626 . See also DeepMind blog post, "MuZero's first step from research into the real world," 11 February 2022. deepmind.google/...om-research-into-the-real-world
- ^1 ^2 ^3 ^4 ^5Schrittwieser, J., Hubert, T., Mandhane, A., Barekatain, M., Antonoglou, I., and Silver, D. "Online and Offline Reinforcement Learning by Planning with a Learned Model." *Advances in Neural Information Processing Systems*, 2021. arxiv.org/...2104.06294
- ^1 ^2 ^3 ^4 ^5Hubert, T., Schrittwieser, J., Antonoglou, I., Barekatain, M., Schmitt, S., and Silver, D. "Learning and Planning in Complex Action Spaces." *Proceedings of the 38th International Conference on Machine Learning*, PMLR 139, 4476-4486, 2021. arxiv.org/...2104.06303
- ^1 ^2 ^3 ^4Antonoglou, I., Schrittwieser, J., Ozair, S., Hubert, T. K., and Silver, D. "Planning in Stochastic Environments with a Learned Model." *International Conference on Learning Representations*, 2022. openreview.net/forum
- ^1 ^2 ^3 ^4Ye, W., Liu, S., Kurutach, T., Abbeel, P., and Gao, Y. "Mastering Atari Games with Limited Data." *Advances in Neural Information Processing Systems*, 2021. arxiv.org/...2111.00210
- ^1 ^2Danihelka, I., Guez, A., Schrittwieser, J., and Silver, D. "Policy improvement by planning with Gumbel." *International Conference on Learning Representations*, 2022. openreview.net/forum
- ^1 ^2 ^3DeepMind. "MuZero: Mastering Go, chess, shogi and Atari without rules." DeepMind blog post, 23 December 2020. deepmind.google/...s-shogi-and-atari-without-rules
- ^1 ^2 ^3 ^4DeepMind. "MuZero, AlphaZero, and AlphaDev: Optimizing computer systems." DeepMind blog post, 12 June 2023. deepmind.google/...dev-optimizing-computer-systems
- ^Hafner, D., Pasukonis, J., Ba, J., and Lillicrap, T. "Mastering Diverse Domains through World Models." arXiv preprint arXiv:2301.04104, 2023. arxiv.org/...2301.04104
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25Schrittwieser, J., Antonoglou, I., Hubert, T., Simonyan, K., Sifre, L., Schmitt, S., Guez, A., Lockhart, E., Hassabis, D., Graepel, T., Lillicrap, T., and Silver, D. "Mastering Atari, Go, Chess and Shogi by Planning with a Learned Model." arXiv preprint arXiv:1911.08265 (v1 19 November 2019; v2 21 February 2020). arxiv.org/...1911.08265
- ^Hessel, M., Danihelka, I., Viola, F., Guez, A., Schmitt, S., Sifre, L., Weber, T., Silver, D., and van Hasselt, H. "Muesli: Combining Improvements in Policy Optimization." arXiv preprint arXiv:2104.06159, 2021. arxiv.org/...2104.06159
- ^Wang, S., Liu, S., Ye, W., You, J., and Gao, Y. "EfficientZero V2: Mastering Discrete and Continuous Control with Limited Data." *Proceedings of the 41st International Conference on Machine Learning*, PMLR 235, 2024. arxiv.org/...2403.00564
- ^Gelmi, M. "Introduce branchless sorting functions for sort3, sort4 and sort5." LLVM project commit 194d1965d2c8 (Differential Revision D118029), 8 April 2022. github.com/...1965d2c841fa81e107d19e27fae1467e7f11
- ^Duvaud, W., et al. "muzero-general." GitHub repository, 2019-. github.com/...muzero-general
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
9 revisions · v9 · 5,439 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Fact-checked on 2026-10-30 against the MuZero arXiv preprint and Nature 2020 paper with its supplementary data, the AlphaTensor and AlphaDev Nature papers, DeepMind's blog posts, and the papers for each MuZero variant, with an independent second review.
Cite this page: AI Wiki. "MuZero." aiwiki.ai, updated 30 Oct 2026, fact-checked 30 Oct 2026. CC BY 4.0. https://aiwiki.ai/wiki/muzero