

Mixtral
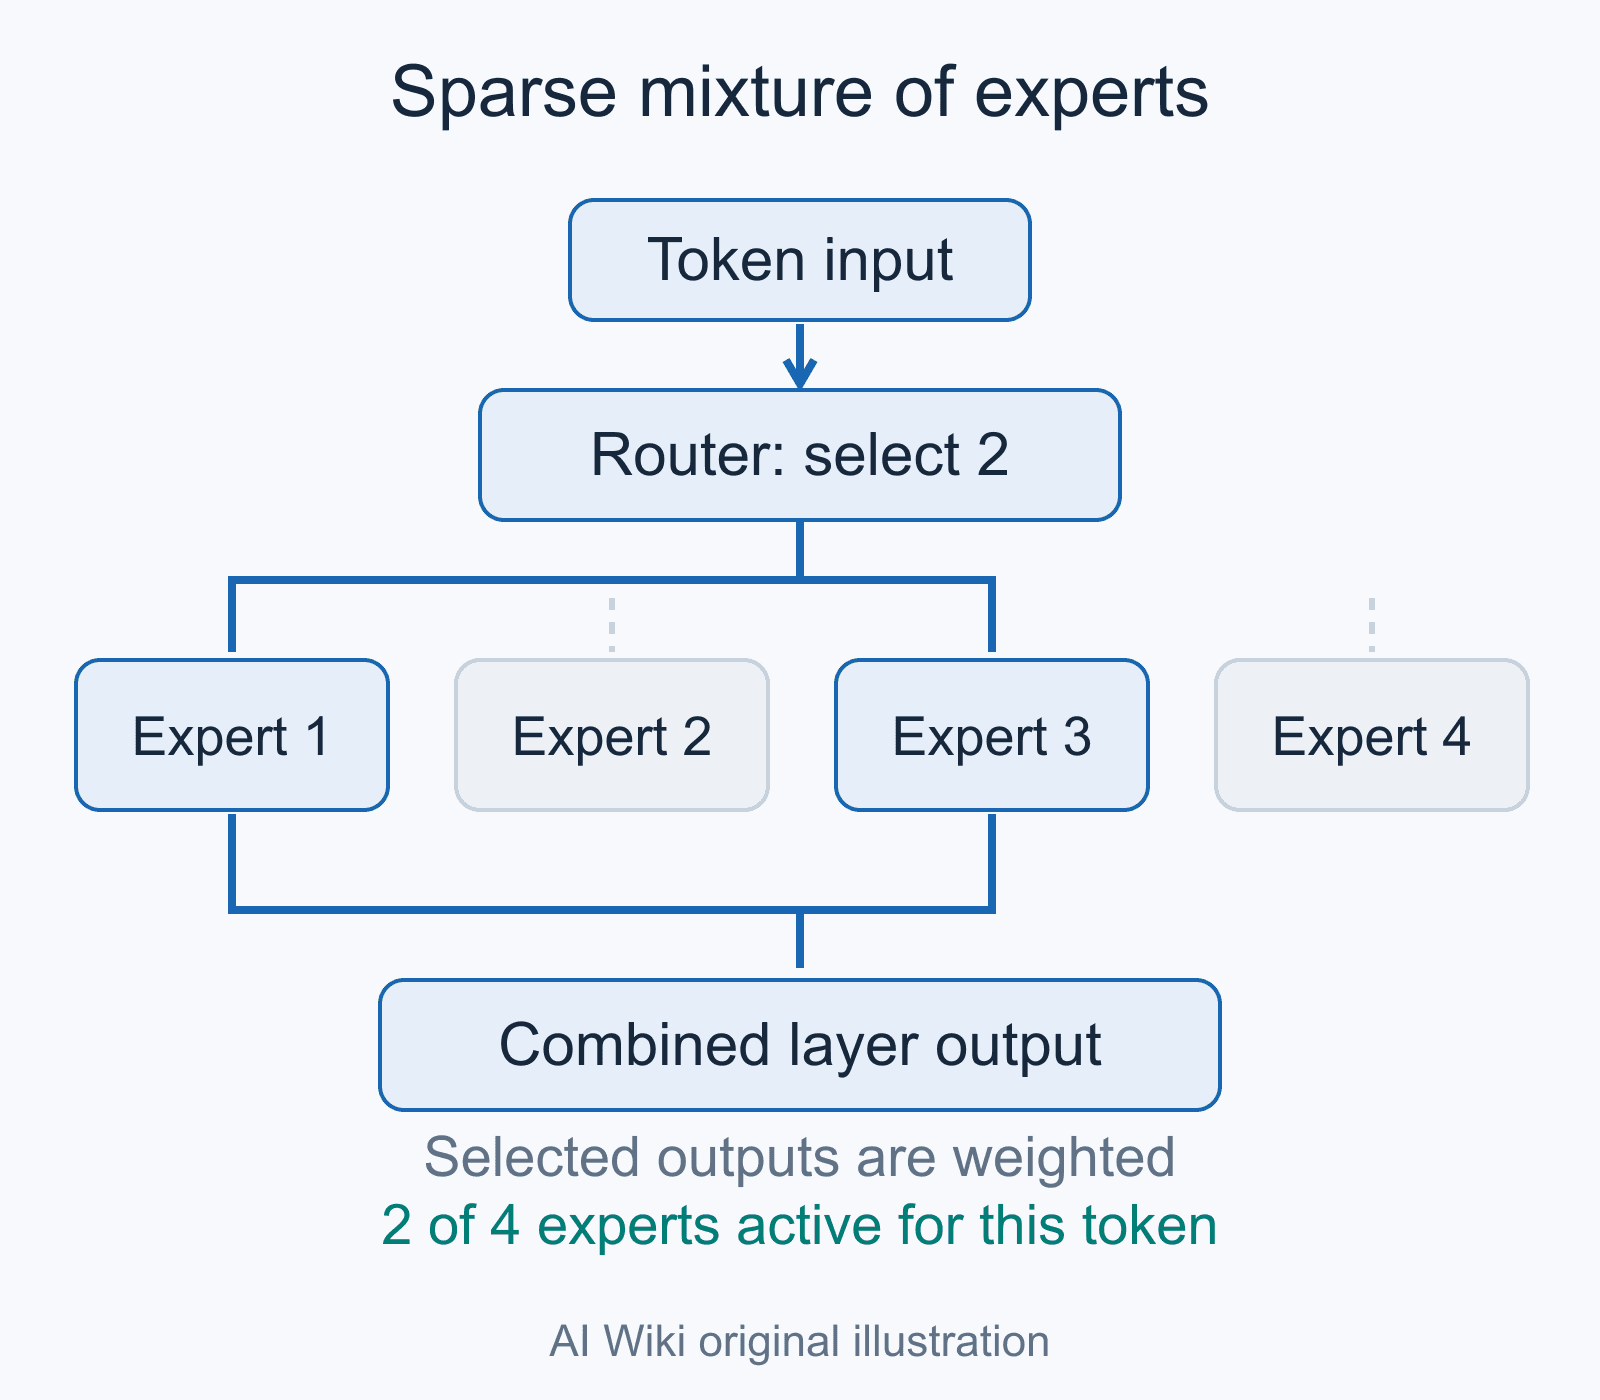
Mixtral is a family of open-weight Sparse Mixture of Experts (SMoE) large language models developed by Mistral AI, a French artificial intelligence company founded in April 2023. The family contains two main models: Mixtral 8x7B, released on December 11, 2023, and Mixtral 8x22B, released on April 10, 2024.[2][3] In Mixtral 8x7B, as the original paper states, "each token has access to 47B parameters, but only uses 13B active parameters during inference," because a learned router selects two of eight expert subnetworks at every layer.[1] This design lets the model carry a large total parameter count for capacity while activating only a fraction of those parameters per token, so it runs much faster than a dense model of comparable quality and is cheaper to serve.[1]
Mixtral 8x7B was the first open-weight Mixture of Experts model that clearly matched or beat much larger dense systems such as LLaMA 2 70B and GPT-3.5 Turbo on standard benchmarks, and its release under the Apache 2.0 license showed that sparse MoE could be a practical, fully open recipe rather than a research curiosity confined to internal Google papers.[1][2] Mistral's launch post described it as "a high-quality sparse mixture of experts model (SMoE) with open weights" that "outperforms Llama 2 70B on most benchmarks with 6x faster inference."[2] Mixtral 8x22B extended the same recipe with a larger network, a 64K context window, and stronger reasoning, math, and multilingual scores.[3] Together the two releases helped trigger the wave of open MoE models that followed in 2024 (DBRX, Snowflake Arctic, Qwen 1.5 MoE, DeepSeek-V2 and later DeepSeek-V3) and made sparse routing one of the dominant designs in modern open-weight language models.
The Mixtral name is a portmanteau of Mistral and "mixture," which signals its lineage. Mixtral 8x7B reuses most of the Mistral 7B design (grouped query attention, RoPE, the SentencePiece tokenizer) but drops Mistral 7B's sliding window attention in favor of a fully dense 32K context, then swaps each dense feedforward layer for an MoE block of eight expert feedforward networks.[1] That architectural continuity, plus the public weights and permissive license, made Mixtral easy to study, fine-tune, quantize, and integrate into existing inference engines such as llama.cpp, Ollama, and vLLM within days of release.
What is Mixtral?
Mixtral is a sparse Mixture of Experts language model: a decoder-only Transformer in which each dense feedforward block is replaced by eight expert feedforward networks plus a router that activates only two of them per token.[1] Mistral AI shipped two open-weight Mixtral models, both under Apache 2.0, and both released first as bare magnet-link torrents before any blog post. Mixtral 8x7B carries about 46.7 billion total parameters but activates only about 12.9 billion per token, and Mixtral 8x22B carries about 141 billion total while activating about 39 billion per token.[1][7] The single most-cited fact about the family is that Mixtral 8x7B "outperforms or matches Llama 2 70B and GPT-3.5 across all evaluated benchmarks" while using roughly five times fewer active parameters than Llama 2 70B.[1]
Background
The Mixture of Experts idea predates modern deep learning. The 1991 paper "Adaptive Mixtures of Local Experts" by Robert Jacobs, Michael Jordan, Steven Nowlan, and Geoffrey Hinton proposed splitting a network into specialist subnetworks managed by a gating function.[8] The modern, deep learning version arrived in 2017 with Noam Shazeer's "Outrageously Large Neural Networks: The Sparsely-Gated Mixture-of-Experts Layer," which scaled language models to 137 billion parameters by routing each token to a small number of experts.[9]
Google then ported MoE into Transformer-based language models. GShard (2020) trained a 600-billion-parameter multilingual translation model that replaced every other dense feedforward layer with a top-2 MoE block.[10] The Switch Transformer (2021) simplified routing further to top-1 and pushed past one trillion parameters.[11] GLaM (2021) reached 1.2 trillion parameters with similar techniques while activating only a fraction during inference. GShard and GLaM were never released. Google did publish Switch Transformer checkpoints, including the 1.6-trillion-parameter Switch-C, under Apache 2.0 in late 2022, but these were T5-style research models rather than general-purpose chat or instruction models.
Mistral AI was founded in April 2023 by Arthur Mensch, Guillaume Lample, and Timothee Lacroix, who came from Google DeepMind and Meta AI. The company's first model, Mistral 7B, shipped in September 2023. It was a 7.3-billion-parameter dense Transformer released as a torrent under Apache 2.0, and it noticeably outperformed Llama 2 13B on most benchmarks while being roughly half the size. Mistral 7B introduced two architecture choices: sliding window attention, which limits each token's attention to a moving window of recent context, and grouped query attention, which shares key and value projections across multiple query heads to cut the memory bandwidth needed during inference. When Mistral built Mixtral, it kept grouped query attention and the rest of the Mistral 7B design but replaced sliding window attention with a fully dense 32K-token context and swapped the feedforward layers for MoE blocks.[1]
Mixtral 8x7B
When was Mixtral 8x7B released?
Mistral AI announced Mixtral 8x7B on December 11, 2023, with a blog post titled "Mixtral of Experts."[2] The actual model weights had appeared three days earlier, on December 8, 2023, when Mistral's official X (Twitter) account posted a single tweet containing only a magnet link. The torrent contained the raw model weights without code, documentation, or benchmarks. This unconventional drop became a recurring Mistral marketing pattern (the company had used the same magnet-link teaser for Mistral 7B in September 2023 and would repeat it for Mixtral 8x22B in April 2024) and gave the release a viral, hacker-culture flavor that contrasted sharply with the carefully staged announcements typical of large AI labs.
The official blog post on December 11 introduced Mixtral 8x7B as "a high-quality sparse mixture of experts model (SMoE) with open weights," claimed it outperformed Llama 2 70B on most benchmarks with 6x faster inference, and stated that it matched or exceeded GPT-3.5 on standard benchmarks.[2] The instruction-tuned variant, Mixtral 8x7B Instruct v0.1, was released on the same day.[2] Both the base and Instruct variants ship under the Apache 2.0 license, which permits commercial use, redistribution, fine-tuning, and modification with no field-of-use restrictions.[6] Hugging Face uploaded the weights on December 11 and added official transformers library support, including a MixtralForCausalLM class, the same day in transformers release 4.36.[4]
The technical paper followed a month later. Albert Q. Jiang, Alexandre Sablayrolles, Antoine Roux, Arthur Mensch, Blanche Savary, Chris Bamford, Devendra Singh Chaplot, Diego de las Casas, Emma Bou Hanna, Florian Bressand, Gianna Lengyel, Guillaume Bour, Guillaume Lample, Lelio Renard Lavaud, Lucile Saulnier, Marie-Anne Lachaux, Pierre Stock, Sandeep Subramanian, Sophia Yang, Szymon Antoniak, Teven Le Scao, Theophile Gervet, Thibaut Lavril, Thomas Wang, Timothee Lacroix, and William El Sayed published "Mixtral of Experts" on arXiv on January 8, 2024 (arXiv:2401.04088).[1] The paper was the first detailed account of the model's architecture, training, expert routing behavior, and benchmark numbers.[1]
Architecture
Mixtral 8x7B is a decoder-only Transformer with the same backbone as Mistral 7B except that each feedforward layer is replaced by a sparse MoE layer containing eight experts.[1] Each expert is itself a SwiGLU feedforward block of the same shape as the dense FFN in Mistral 7B. The architectural numbers are:
| Parameter | Value |
|---|---|
| Hidden dimension (d_model) | 4,096 |
| Number of layers | 32 |
| Attention heads | 32 |
| Key-value heads | 8 (Grouped-Query Attention) |
| Head dimension | 128 |
| Intermediate (FFN) size per expert | 14,336 |
| Vocabulary size | 32,000 |
| Context length | 32,768 tokens |
| Number of experts per layer | 8 |
| Active experts per token | 2 (top-2 routing) |
| Total parameters | ~46.7 billion |
| Active parameters per token | ~12.9 billion |
| Activation function | SiLU (within SwiGLU) |
| Positional encoding | Rotary Position Embedding (RoPE), |
| Tokenizer | SentencePiece BPE, 32K vocab (shared with Mistral 7B) |
| Precision | bfloat16 |
Why 46.7 billion total parameters and not 56 billion (8 x 7B)? The "8x7B" name is a marketing convenience, not a literal multiplication. Only the feedforward layers are replicated eight times. The token embedding, attention layers, layer norms, and output projection are shared across experts.[1] Each expert is a SwiGLU block of about 176 million parameters per layer (3 x 4,096 x 14,336), or about 5.6 billion per expert across all 32 layers, so the eight experts together hold roughly 45 billion parameters; the shared attention, embedding, and output layers add only about 1.6 billion more. Active parameters per token (about 12.9 billion) reflect the shared stack plus the two experts selected by the router at each layer.[1]
How does sparse routing work?
At every MoE layer, for every input token, the router selects two of the eight experts and combines their outputs as a weighted sum.[1] The router is a single learned linear layer of shape followed by a softmax. Concretely, given an input vector x at an MoE layer:
- Compute logits , where is the router weight matrix.
- Take the top-2 indices by logit value.
- Apply softmax over only those two logits to get gating weights such that .
- The layer output is , where is the i-th expert FFN.
This is similar to the top-2 routing introduced in GShard, though GShard used a more elaborate gating strategy for the second expert.[1][10] Unlike GShard, which placed an MoE block on every other feedforward layer, Mixtral applies MoE on every feedforward layer in the model.[1] Routing is independent at each layer, so a single token can be processed by 64 distinct experts on its way through 32 layers (two per layer). Because the router operates per token, neighboring tokens can take very different paths through the network, which is why MoE inference benefits enormously from large batch sizes that smooth out per-expert load.
Load balancing loss
A naive sparse MoE layer is unstable: nothing prevents the router from collapsing onto one or two favored experts and ignoring the rest. Mistral has not documented Mixtral's training losses; the Hugging Face transformers implementation of Mixtral includes the auxiliary load balancing loss introduced in the Switch Transformer paper.[5][11] The loss for one MoE layer is:
where N is the number of experts (8), is the fraction of tokens in the batch routed to expert i, is the average router probability for expert i across the batch, and is a small coefficient. The published model configs set this coefficient (router_aux_loss_coef) to 0.02 for Mixtral 8x7B and 0.001 for Mixtral 8x22B.[6][7] The loss is added to the standard cross-entropy training objective. Minimizing pushes both the routing distribution f and the router probabilities P toward uniform, which keeps all eight experts trained.
Memory and compute trade-off
The key practical property of Mixtral is that compute scales with active parameters while memory scales with total parameters. A forward pass over one token activates roughly 12.9 billion parameters, so latency per token is similar to a dense 13B model.[1] But all 46.7 billion parameters must be resident in VRAM (or fast-loadable from CPU) because any token at any layer might pick any pair of experts. This gives Mixtral the inference cost profile of a 13B dense model and the memory footprint of a 47B dense model. The full bfloat16 checkpoint is about 93 GB (87 GiB); Hugging Face estimated that half-precision inference needs more than 90 GB of VRAM, so the unquantized model does not fit on a single 80 GB A100 or H100 and is typically served on two 80 GB GPUs.[4]
Training
Mistral has disclosed very little about Mixtral's training corpus, total token count, or hardware. Mistral's launch post says only that the model was "pre-trained on data extracted from the open Web" and that experts and routers were trained simultaneously; the paper adds that the proportion of multilingual data was significantly upsampled relative to Mistral 7B.[1][2] There is no published number for tokens consumed, no breakdown of language or domain mixture, and no description of the GPU cluster used.
The Instruct variant (Mixtral 8x7B Instruct v0.1) was created with two-stage post-training: supervised fine-tuning on instruction-response pairs followed by Direct Preference Optimization on a paired feedback dataset.[1] DPO is a closed-form alternative to RLHF that avoids training a separate reward model, and Mixtral was one of the earliest widely deployed Instruct models trained with DPO rather than PPO. The combination produced an Instruct model that scored 8.30 on MT-Bench, the highest score for any openly available model at the time.[1]
How does Mixtral 8x7B perform on benchmarks?
The Mixtral paper compared Mixtral 8x7B against LLaMA 2 70B and GPT-3.5 across a wide range of standard evaluations.[1] The headline result, in the authors' words, was that "Mixtral outperforms or matches Llama 2 70B and GPT-3.5 across all evaluated benchmarks" and "vastly outperforms Llama 2 70B on mathematics, code generation, and multilingual benchmarks," while activating roughly five times fewer parameters per token.[1]
| Benchmark | Mixtral 8x7B | LLaMA 2 70B | GPT-3.5 |
|---|---|---|---|
| MMLU (5-shot) | 70.6% | 69.9% | 70.0% |
| HellaSwag (10-shot) | 86.7% | 87.1% | 85.5% |
| WinoGrande (5-shot) | 81.2% | 83.2% | 81.6% |
| ARC Challenge (25-shot) | 85.8% | 85.1% | 85.2% |
| PIQA (0-shot) | 83.6% | 82.6% | -- |
| ARC-Easy (0-shot) | 83.1% | 79.9% | -- |
| NaturalQuestions (5-shot) | 30.6% | 25.4% | -- |
| TriviaQA (5-shot) | 71.5% | 73.0% | -- |
| HumanEval (pass@1) | 40.2% | 29.3% | -- |
| MBPP (pass@1) | 60.7% | 49.8% | 52.2% |
| MATH (4-shot, maj@4) | 28.4% | 13.8% | -- |
| GSM8K (5-shot) | 58.4% | 53.6% | 57.1% |
| MT-Bench (Instruct) | 8.30 | 6.86 | 8.32 |
The gains were largest on code and math: Mixtral beat LLaMA 2 70B by roughly 11 points on HumanEval and more than doubled its score on the MATH dataset.[1] On MMLU and most other knowledge benchmarks the margin was smaller, around half a point to a few points. Mixtral 8x7B Instruct's MT-Bench score of 8.30 placed it nearly even with GPT-3.5 Turbo (8.32) and well ahead of Llama 2 70B Chat (6.86), making it the strongest open-weight chat model on MT-Bench at release.[1]
On the LMSYS Chatbot Arena leaderboard, Mixtral 8x7B Instruct had an Arena Elo of 1121 in a December 22, 2023 leaderboard snapshot reported in the Mixtral paper, ahead of Claude 2.1 (1117), the best GPT-3.5 Turbo version (1117), and Gemini Pro (1111).[1] For several months it was the highest-ranked openly available model on the Arena.
Multilingual evaluation showed that Mixtral substantially outperformed LLaMA 2 70B on French, German, Spanish, and Italian versions of HellaSwag, ARC Challenge, and MMLU.[1] On the Bias Benchmark for QA (BBQ), Mixtral scored 56.0% versus LLaMA 2 70B's 51.5%, indicating somewhat lower social bias.[1]
Do the experts specialize by topic?
A natural question for any MoE model is whether the experts specialize. The Mixtral paper investigated this by tracking which experts were selected for tokens drawn from different subsets of The Pile validation set, including ArXiv papers, PubMed abstracts, PhilPapers, GitHub code, DM Mathematics, and English Wikipedia.[1] The result was the opposite of what many expected. The router does not learn topical specialization. There is no "math expert" or "code expert." Instead, expert selection correlates strongly with token syntax and position.[1] Consecutive tokens are often routed to the same experts, and recurring tokens such as "self" in Python, "Question" in English, and indentation in code tend to go through the same expert. The only notable distributional difference was on DM Mathematics, a synthetic dataset, which the authors attribute to its narrow coverage of natural language; nothing approaching strict topical partitioning appears. The routing pattern in middle layers is more diffuse than in the first or last layers.
This finding has been repeatedly reproduced in subsequent MoE work and is now widely cited as the standard observation: token-level routers tend to discover syntactic, positional, or low-level lexical patterns rather than human-interpretable topics. Later models such as DeepSeek-MoE attacked the problem with finer-grained experts and shared "always-on" experts to encourage more specialization, while still tolerating the diffuse routing behavior that Mixtral demonstrated.
Long-context behavior
Mixtral 8x7B has a native 32,768-token context window. The Mixtral paper reports a passkey retrieval test in which a random short passkey is inserted at a random position inside a long prompt. Mixtral 8x7B achieved 100% retrieval accuracy across the full 32K window, which means the model can locate and copy a string from anywhere in its context in this synthetic test.[1] Real-world long-context performance (multi-document QA, long-form summarization) is somewhat weaker than the synthetic passkey result suggests, a pattern observed in essentially every long-context model evaluated since 2023.
Mixtral 8x22B
When was Mixtral 8x22B released?
Mistral released Mixtral 8x22B on April 10, 2024, again as a magnet link posted to its official X account. The torrent contained 281 GB of raw weights with no code or documentation. Hugging Face uploads followed within hours. Mistral published the official blog post ("Cheaper, Better, Faster, Stronger") on April 17, 2024, alongside the Instruct variant Mixtral 8x22B Instruct v0.1.[3] As before, both base and Instruct were released under Apache 2.0.[3][7] In that post Mistral described the model directly: "It is a sparse Mixture-of-Experts (SMoE) model that uses only 39B active parameters out of 141B, offering unparalleled cost efficiency for its size."[3]
The release landed in a busy window for open models. Meta released Llama 3 8B and 70B on April 18, 2024, eight days after Mixtral 8x22B's torrent and one day after Mistral's blog post.[13] Snowflake announced its Arctic 480B MoE on April 24.[15] April 2024 ended up being one of the most concentrated months in open-weight LLM history, and Mixtral 8x22B briefly led open-weight models on MMLU before Llama 3 70B's score of 82.0 took the lead.[13]
How does Mixtral 8x22B differ from 8x7B?
Mixtral 8x22B keeps the same sparse MoE recipe but scales every dimension. It still uses eight experts per layer and top-2 routing, so the headline 8x22B name reflects expert-FFN size, not a deeper change in design.[7]
| Parameter | Mixtral 8x7B | Mixtral 8x22B |
|---|---|---|
| Hidden dimension | 4,096 | 6,144 |
| Number of layers | 32 | 56 |
| Attention heads | 32 | 48 |
| Key-value heads | 8 | 8 |
| Head dimension | 128 | 128 |
| Intermediate (FFN) size per expert | 14,336 | 16,384 |
| Vocabulary size | 32,000 | 32,000 (32,768 in Instruct v0.1) |
| Context length | 32,768 | 65,536 |
| Experts per layer | 8 | 8 |
| Active experts per token | 2 | 2 |
| Total parameters | ~46.7B | ~141B |
| Active parameters per token | ~12.9B | ~39B |
| RoPE theta | 1,000,000 | 1,000,000 |
| Load balancing coefficient | 0.02 | 0.001 |
The move to 56 layers (up from 32), 6,144 hidden dimension (up from 4,096), 48 attention heads (up from 32), and 16,384-wide expert FFNs (up from 14,336) bring the total parameter count to about 141 billion, with about 39 billion activated per token.[7] The context window doubled to 65,536 tokens.[7] Grouped query attention is preserved at the same 8 key-value heads, which now serve 48 query heads (a 6:1 ratio).
Capabilities
Mistral's announcement highlighted four main capabilities: fluency in English, French, Italian, German, and Spanish; strong code and math performance; native function calling support in the Instruct variant; and constrained-output / structured-generation support.[3] The post claimed the model delivers "the best performance-to-cost ratio within models provided by the community" and that its "sparse activation patterns make it faster than any dense 70B model, while being more capable than any other open-weight model."[3] Function calling and JSON-mode generation made the Instruct variant directly usable as a tool-using agent without external scaffolding, an important practical feature in 2024 when most open chat models still required prompt engineering to emit clean JSON.
Benchmarks
Mistral's announcement reports the following numbers for the Mixtral 8x22B base model:[3]
| Benchmark | Mixtral 8x22B (Base) |
|---|---|
| MMLU (5-shot) | 77.7% |
| HellaSwag (10-shot) | 88.5% |
| ARC Challenge (25-shot) | 91.3% |
| WinoGrande (5-shot) | 84.7% |
| GSM8K (maj@1, 5-shot) | 78.6% |
| GSM8K (maj@8, 8-shot) | 88.4% |
| TriviaQA (5-shot) | 82.2% |
| HumanEval (pass@1) | 45.1% |
| MBPP (pass@1) | 71.2% |
| MATH (4-shot) | 41.8% |
For the Instruct variant, Mistral reported GSM8K with majority voting (maj@8) of 90.8% and MATH (maj@4) of 44.6%.[3] Compared to Mixtral 8x7B, the 8x22B base model improved MMLU by about 7 points (70.6% to 77.75%), raised MATH maj@4 from 28.4% to 41.8%, and pulled ahead on code generation (HumanEval 45.1% versus 40.2%, MBPP 71.2% versus 60.7%).[3]
Comparison with Llama 3 70B
Llama 3 70B (also April 2024) reported MMLU 82.0%, GSM8K 93.0%, and HumanEval 81.7% (the Instruct variant).[13] On raw benchmark scores Llama 3 70B beat Mixtral 8x22B in most categories, despite using a fully dense architecture with 70 billion parameters. The trade-off was that Llama 3 70B activates all 70B parameters per token while Mixtral 8x22B activates only 39B, so Mixtral retained an inference-speed advantage. The two models occupied different points on the same Pareto frontier: Llama 3 70B for raw quality, Mixtral 8x22B for efficiency at scale, and at the time of release Llama 3's larger pretraining corpus (15 trillion tokens versus an undisclosed but presumably smaller Mixtral 8x22B corpus) was widely credited with the gap.[13]
How does Mixtral compare with contemporary models?
The table below sets Mixtral against the major open-weight and proprietary models of late 2023 and 2024.
| Model | Developer | Release | Total params | Active params | Context | Architecture | MMLU | License |
|---|---|---|---|---|---|---|---|---|
| Mixtral 8x7B | Mistral AI | Dec 2023 | 46.7B | 12.9B | 32K | Sparse MoE (top-2 / 8) | 70.6% | Apache 2.0 |
| Mixtral 8x22B | Mistral AI | Apr 2024 | 141B | 39B | 65K | Sparse MoE (top-2 / 8) | 77.7% | Apache 2.0 |
| LLaMA 2 70B | Meta AI | Jul 2023 | 70B | 70B | 4K | Dense | 69.9% | Meta Community |
| Llama 3 70B | Meta AI | Apr 2024 | 70B | 70B | 8K | Dense | 82.0% (Instruct) | Meta Community |
| Falcon 180B | TII | Sep 2023 | 180B | 180B | 2K | Dense | 70.6% | Falcon TII |
| Qwen 72B | Alibaba | Nov 2023 | 72B | 72B | 32K | Dense | 77.4% | Tongyi Qianwen License |
| Qwen 1.5 MoE A2.7B | Alibaba | Mar 2024 | 14.3B | 2.7B | 32K | Sparse MoE (top-4 / 60 + 4 shared) | 62.5% | Tongyi Qianwen License |
| DBRX Instruct | Databricks | Mar 2024 | 132B | 36B | 32K | Sparse MoE (top-4 / 16) | 73.7% | DBRX Open |
| Grok-1 | xAI | Mar 2024 | 314B | 86B | 8K | Sparse MoE (top-2 / 8) | 73.0% | Apache 2.0 |
| Snowflake Arctic | Snowflake | Apr 2024 | 480B | 17B | 4K | Dense + Sparse MoE (top-2 / 128) | 67.3% | Apache 2.0 |
| DeepSeek-V2 | DeepSeek | May 2024 | 236B | 21B | 128K | Sparse MoE (top-6 / 162) | 78.5% | DeepSeek Custom |
| DeepSeek-V3 | DeepSeek | Dec 2024 | 671B | 37B | 128K | Sparse MoE (top-8 / 256 + shared) | 88.5% | DeepSeek Open |
| GPT-3.5 Turbo | OpenAI | Mar 2023 | undisclosed | undisclosed | 16K | undisclosed | 70.0% | Proprietary |
A few patterns stand out. First, the basic Mixtral recipe (eight experts, top-2) was simple compared to what came later. Snowflake Arctic uses 128 experts with top-2; DeepSeek-V3 uses 256 fine-grained experts with top-8 plus shared always-on experts; Qwen 1.5 MoE uses 60 experts with top-4. The trend after Mixtral was clearly toward more, smaller experts and finer-grained routing. Second, Mixtral's permissive Apache 2.0 license was matched by some later open MoE releases (Grok-1, Snowflake Arctic) but not by others, which shipped under custom licenses (DBRX, Qwen 1.5 MoE, DeepSeek-V2). Third, the gap in raw quality between dense and sparse models at fixed total parameter budget closed through 2024 and reversed by 2025: DeepSeek-V3 at 88.5 MMLU is higher than any dense open model of comparable cost.[12]
Inference and deployment
For a model with 47 billion (or 141 billion) parameters that is intended for the open-source community, the inference story matters as much as the model itself. Mixtral was unusually well supported from day one because it shared its tokenizer and attention stack with Mistral 7B.
Hugging Face Transformers added a MixtralForCausalLM class in release 4.36 on December 11, 2023, the day of the public announcement.[4][5] The implementation uses standard PyTorch matrix multiplications for the experts, gathers token activations per expert, and is therefore not particularly fast for batch size 1, but it is correct and easy to fine-tune.
vLLM added Mixtral support in version 0.2.4 (December 11, 2023), using code contributed by Mistral that integrated Megablocks CUDA kernels.[2] vLLM's PagedAttention combined with batched expert dispatch lets two 80 GB A100 or H100 GPUs serve unquantized Mixtral 8x7B with high aggregate tokens per second across many concurrent requests (a single 80 GB GPU needs a quantized checkpoint).[4] As of 2025 vLLM remains the most common production server for Mixtral.
llama.cpp added Mixtral support on December 13, 2023, two days after release, including GGUF quantization. The community user TheBloke published quantized GGUF files within days. A 4-bit quantized Mixtral 8x7B (Q4_K_M) is approximately 26 GB and runs on a single 24 GB consumer GPU with some CPU offload, on dual 24 GB GPUs without offload, or fully on CPU at a few tokens per second using AVX-512 or Apple Silicon. Ollama packages a Mixtral 8x7B model that wraps the llama.cpp backend and is one of the simplest ways for a developer to run Mixtral locally.
Quantization has been particularly important for Mixtral because of the unusual memory profile. Full bfloat16 Mixtral 8x7B is 87 GB; 4-bit quantization brings it to about 24 to 26 GB; 2-bit experimental quantizations have been demonstrated as low as 14 GB at significant quality cost. Mixtral 8x22B at full precision needs roughly 262 GB; 4-bit Q4_K_M is approximately 80 GB and requires multiple consumer GPUs. Community experiments found that MoE models tolerate aggressive quantization slightly better than dense models because rarely-activated experts contribute less to any given token's prediction, so quantization error in those experts is partly hidden.
Other engines. TensorRT-LLM, MLC-LLM, ExLlamaV2, AutoAWQ, GPTQ-for-LLaMA, and Apple's MLX framework all added Mixtral support during 2024. Microsoft's DeepSpeed-MoE work, which predates Mixtral, had already shown that MoE inference could be made several times cheaper than equivalently sized dense models through expert parallelism and specialized kernels, and these techniques carried over directly to serving Mixtral at scale.[20] AWS announced Mixtral 8x22B in Amazon SageMaker JumpStart on May 17, 2024,[19] and Together AI, Anyscale, Replicate, Fireworks, and Groq also offered hosted Mixtral inference.
Use in Mistral products
Within Mistral's own product line, Mixtral 8x7B was originally served behind the mistral-small API endpoint on La Plateforme (Mistral's developer API).[2] On February 26, 2024, when Mistral launched the proprietary Mistral Large, it introduced a new optimized Mistral Small model (mistral-small-2402) and moved Mixtral 8x7B to an open-mixtral-8x7b open-weight endpoint.[23] Mixtral 8x22B was later served as open-mixtral-8x22b.[18]
Le Chat, Mistral's consumer chatbot launched in beta on February 26, 2024, could use Mistral Large, the new Mistral Small (a model Mistral said outperforms Mixtral 8x7B), or a prototype called Mistral Next.[23][24] Mixtral itself was not one of the launch options.
Mistral deprecated the open-mixtral-8x7b and open-mixtral-8x22b API endpoints on November 30, 2024 and retired them on March 30, 2025; its documentation lists Mistral Small 4 as the replacement.[18] Both Mixtral models remain freely downloadable from Hugging Face under Apache 2.0 and can still be fine-tuned and self-hosted.[6][7]
Influence and successors
Did Mixtral start the open MoE era?
Mixtral 8x7B is widely credited with starting the open-source mixture-of-experts era. Before December 2023, the strongest publicly described MoE language models (GShard, Switch Transformer, GLaM) were all Google research projects. Mixtral was the first MoE language model with strong benchmark scores, full open weights, a permissive license, and same-week support in the standard inference stack. Within five months of Mixtral 8x7B's release, the open community shipped:
- DeepSeek-MoE 16B (January 2024) with finer-grained experts and shared expert isolation.
- Qwen 1.5 MoE A2.7B (March 2024) with 60 routed experts plus 4 shared experts, upcycled from Qwen-1.8B.
- Grok-1 (March 2024), xAI's 314B-parameter MoE released under Apache 2.0.
- DBRX (March 2024) by Databricks, 132B total parameters with top-4 routing across 16 experts.[16]
- Mixtral 8x22B (April 2024).[3]
- Snowflake Arctic (April 2024), a 480B hybrid dense-plus-MoE design with 128 experts.[15]
- DeepSeek-V2 (May 2024), introducing Multi-head Latent Attention with a 162-expert sparse routing scheme.
And by the end of 2024 and into 2025, DeepSeek-V3 (671B / 37B active) and the Mistral / Llama / Qwen successors all converged on sparse MoE as the default architecture for the largest open-weight models. DeepSeek-V3's technical report cites Mistral's Mixtral 8x22B release among the open-source model series working to close the gap with closed-source models.[12] Llama 4 (2025) also moved Meta's flagship line to MoE.
Fine-tuning ecosystem
Mixtral 8x7B became one of the most actively fine-tuned base models of 2024. Notable community-released variants include:
- NousResearch Nous Hermes 2 Mixtral 8x7B DPO (January 2024), an instruction-tuned variant on the Hermes dataset with DPO alignment.
- Cognitive Computations Dolphin 2.5 / 2.6 Mixtral, uncensored fine-tunes by Eric Hartford.
- DiscoResearch DiscoLM Mixtral, focused on conversational and German-language ability.
- Open-Orca Mixtral SlimOrca, a fine-tune on the SlimOrca distilled dataset.
- Toppy Mixtral, Bagel Mixtral, and many other community blends and merges.
The permissive Apache 2.0 license (no field-of-use restriction, no monthly active user threshold like Llama's) made Mixtral particularly attractive for downstream commercial use. Several startups built products directly on Mixtral fine-tunes during 2024, including coding tools, translation services, and chat applications.
Model merging and "FrankenMoEs"
Mixtral inspired a new category of model engineering called MoE merging, sometimes nicknamed "FrankenMoE" or "MoErge." The MergeKit library by Charles Goddard at Arcee AI added support for assembling custom MoE models out of multiple existing fine-tuned dense Mistral 7B models.[17] The recipe is to take the attention and norm weights from a base model, plug different fine-tuned models in as the eight experts, and then either initialize the router from positive and negative example prompts or train it on a small dataset.[17] The result is a Mixtral-architecture model whose experts have known specializations (one fine-tuned on math, one on code, one on roleplay, etc.). FrankenMoE models such as Beyonder and Mixtral_AI_Cyber became popular community releases through 2024 and demonstrated that Mixtral's architecture was useful even without retraining from scratch.
MLPerf inference benchmark
In August 2024, MLCommons added Mixtral 8x7B as the official MoE workload in MLPerf Inference v4.1.[14] The choice cemented Mixtral as the reference model for MoE inference hardware comparisons.[14] The v4.1 round drew eight Mixtral 8x7B submissions with 34 results.[14]
Technical considerations
Why is MoE inference awkward at small batch size?
The routing pattern at the heart of MoE makes small-batch inference inefficient. A single token at a single layer activates only two experts; the other six experts contribute nothing to that forward pass but still occupy memory and bandwidth. At batch size one, the active compute fraction can drop below 25% of theoretical peak FLOPs because each matrix multiply per expert is a small operation that fails to saturate the GPU. As batch size grows, more tokens reach each expert, the matrix multiplies get larger, and utilization rises. Mixtral therefore reaches its full speed advantage in serving scenarios with high concurrency, not in single-user chat sessions. This is one reason production Mixtral deployments use vLLM or TensorRT-LLM with continuous batching; without it, the speedup over a dense 13B model is much smaller.
Routing imbalance and "dead" experts
Despite the load balancing loss, real Mixtral checkpoints show some imbalance. Some experts in some layers are selected slightly more often than others. Expert pruning experiments have shown that removing the least-used expert from a few middle layers degrades quality only modestly, suggesting that those experts are partly redundant with their neighbors. Conversely, removing the most-used expert from the same layers causes a much larger quality drop. This kind of post-hoc analysis has informed the design of follow-up MoE models such as DeepSeek-MoE, which use shared experts that are always active to absorb the parts of the computation that benefit from a single shared specialist.
Effective parameter count and scaling laws
Researchers have argued about how to count parameters for MoE models in scaling-law contexts. The classic Chinchilla scaling law was derived for dense models and uses total parameters. For MoE, it is not obvious whether to substitute total parameters, active parameters, or some compromise. Empirical results from Mixtral, DBRX, and DeepSeek suggest that active parameters underestimate effective capacity (a Mixtral 8x7B at 12.9B active is clearly stronger than a dense 13B), but total parameters overestimate it (Mixtral 8x7B at 47B total is weaker than a dense 47B would be). A common rule of thumb is to compute the geometric mean of active and total parameters as an effective dense-equivalent size, which puts Mixtral 8x7B around 25 billion equivalents and Mixtral 8x22B around 75 billion equivalents.
Limitations
Mixtral has several recognized limitations:
- Memory hungry. Even at 4-bit quantization, Mixtral 8x7B does not fit on most laptops or low-end consumer GPUs without CPU offload. Mixtral 8x22B requires multi-GPU configurations even after aggressive quantization.
- Knowledge cutoff. Like all pre-trained language models, Mixtral's knowledge ends at its training cutoff. Mistral has not published exact dates, but downstream evaluations suggest mid-2023 for 8x7B and early 2024 for 8x22B.
- Hallucinations. Mixtral can produce plausible-sounding but factually wrong text, the same failure mode that affects all current language models.
- Routing imbalance. Some experts are systematically under-used, which wastes capacity and is a known open problem.
- Long-context reasoning. Synthetic passkey retrieval at 32K tokens is near perfect, but real long-document QA and multi-hop reasoning at long context degrades faster than the synthetic benchmark suggests.
- Language coverage. While multilingual across European languages, the model is primarily optimized for English, French, German, Italian, and Spanish; other languages have less consistent quality.
- Cost at small batch size. As discussed above, the inference speed advantage over dense models requires high concurrency and good batching.
Subsequent Mistral models
After the Mixtral releases, Mistral pursued a parallel track of dense and MoE models, mostly under proprietary licenses for the largest releases.
| Model | Date | Architecture | Params (active / total) | License |
|---|---|---|---|---|
| Mistral Large | Feb 2024 | Dense | undisclosed | Proprietary |
| Mistral Large 2 (2407) | Jul 2024 | Dense | 123B | Mistral Research / Commercial |
| Mistral NeMo | Jul 2024 | Dense | 12B | Apache 2.0 |
| Codestral 22B | May 2024 | Dense | 22B | Mistral Non-Production |
| Codestral Mamba | Jul 2024 | Mamba (state space) | 7.3B | Apache 2.0 |
| Mathstral 7B | Jul 2024 | Dense | 7.3B | Apache 2.0 |
| Pixtral 12B | Sep 2024 | Multimodal dense | 12B | Apache 2.0 |
| Ministral 3B / 8B | Oct 2024 | Dense | 3B / 8B | Mistral Research / Commercial |
| Mistral Small 3 | Jan 2025 | Dense | 24B | Apache 2.0 |
| Mistral Large 3 | Dec 2025 | Sparse MoE (multimodal) | 41B / 675B | Apache 2.0 |
| Mistral Small 4 | Mar 2026 | Sparse MoE (128 experts, top-4) | 6B / 119B | Apache 2.0 |
Mistral has not released a direct "Mixtral 3" successor in the same naming line. It has since returned to open-weight sparse MoE under other names. Mistral Large 3, released on December 2, 2025 under Apache 2.0 with 41B active and 675B total parameters, was described by Mistral as its "first mixture-of-experts model since the seminal Mixtral series."[21] Mistral Small 4 followed on March 16, 2026 as an Apache 2.0 MoE with 128 experts, 4 active per token, and 119B total parameters.[22]
Continue reading
- LLaMALLaMA is the original name of a family of large language models developed by Meta AI.Mentioned 31 times above
- DeepSeekDeepSeek is a Chinese artificial intelligence company based in Hangzhou. It was founded in 2023 by Liang Wenfeng, who had previously co-founded the quantitative investment firm High-Flyer.Mentioned 18 times above
- QuantizationQuantization is the representation of values from a large or continuous set by values from a smaller, usually finite set.Mentioned 8 times above
- Mistral AIMistral AI is a French artificial intelligence company that develops large language models, multimodal models, software for building and operating AI systems, and computing infrastructure.Mentioned 7 times above
- Mixture of Experts (MoE)A mixture of experts (MoE) is a machine-learning architecture that contains multiple component functions called experts and a gating or routing mechanism that determines how their outputs contribute to a…Mentioned 6 times above
- DBRXDBRX is an open-weight mixture of experts large language model developed by Databricks and its Mosaic AI research team, released on March 27, 2024.Mentioned 6 times above
More from See also
Topics:Large Language ModelsMixture of ExpertsOpen Source AI
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30Jiang, A. Q., Sablayrolles, A., Roux, A., Mensch, A., Savary, B., Bamford, C., Chaplot, D. S., de las Casas, D., Bou Hanna, E., Bressand, F., Lengyel, G., Bour, G., Lample, G., Lavaud, L. R., Saulnier, L., Lachaux, M.-A., Stock, P., Subramanian, S., Yang, S., Antoniak, S., Le Scao, T., Gervet, T., Lavril, T., Wang, T., Lacroix, T., & El Sayed, W. (2024). "Mixtral of Experts." arXiv:2401.04088. arxiv.org/...2401.04088
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Mistral AI. (2023, December 11). "Mixtral of Experts." Mistral AI Blog. mistral.ai/...mixtral-of-experts
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11Mistral AI. (2024, April 17). "Cheaper, Better, Faster, Stronger." Mistral AI Blog. mistral.ai/...mixtral-8x22b
- ^1 ^2 ^3 ^4Hugging Face. (2023). "Welcome Mixtral, a SOTA Mixture of Experts on Hugging Face." huggingface.co/...mixtral
- ^1 ^2Hugging Face. (2024). "Mixtral Model Documentation." huggingface.co/...mixtral
- ^1 ^2 ^3Mistral AI. (2024). "Mixtral-8x7B-v0.1 model card." Hugging Face. huggingface.co/...Mixtral-8x7B-v0.1
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Mistral AI. (2024). "Mixtral-8x22B-v0.1 model card." Hugging Face. huggingface.co/...Mixtral-8x22B-v0.1
- ^Jacobs, R. A., Jordan, M. I., Nowlan, S. J., & Hinton, G. E. (1991). "Adaptive Mixtures of Local Experts." Neural Computation, 3(1), 79-87.
- ^Shazeer, N., Mirhoseini, A., Maziarz, K., Davis, A., Le, Q., Hinton, G., & Dean, J. (2017). "Outrageously Large Neural Networks: The Sparsely-Gated Mixture-of-Experts Layer." arXiv:1701.06538. arxiv.org/...1701.06538
- ^1 ^2Lepikhin, D., Lee, H., Xu, Y., Chen, D., Firat, O., Huang, Y., Krikun, M., Shazeer, N., & Chen, Z. (2020). "GShard: Scaling Giant Models with Conditional Computation and Automatic Sharding." arXiv:2006.16668. arxiv.org/...2006.16668
- ^1 ^2Fedus, W., Zoph, B., & Shazeer, N. (2022). "Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity." Journal of Machine Learning Research, 23(120), 1-39. arxiv.org/...2101.03961
- ^1 ^2DeepSeek-AI. (2024). "DeepSeek-V3 Technical Report." arXiv:2412.19437. arxiv.org/...2412.19437
- ^1 ^2 ^3 ^4Meta AI. (2024). "Introducing Meta Llama 3: The most capable openly available LLM to date." ai.meta.com/...meta-llama-3
- ^1 ^2 ^3MLCommons. (2024). "Mixtral 8x7B: a new MLPerf Inference benchmark for mixture of experts." mlcommons.org/...moe-mlperf-inference-benchmark
- ^1 ^2Snowflake. (2024, April 24). "Snowflake Arctic: The best LLM for enterprise AI." snowflake.com/...ndation-language-models-snowflake
- ^Databricks. (2024, March 27). "Introducing DBRX: A New State-of-the-Art Open LLM." databricks.com/...cing-dbrx-new-state-art-open-llm
- ^1 ^2Labonne, M. (2024). "Create Mixtures of Experts with MergeKit." towardsdatascience.com/...th-mergekit-11b318c99562
- ^1 ^2Mistral AI. (2024). "Mistral AI Documentation: Open weight models." docs.mistral.ai/...open_weight_models
- ^AWS. (2024, May 17). "Mixtral 8x22B is now available in Amazon SageMaker JumpStart." aws.amazon.com/...le-in-amazon-sagemaker-jumpstart
- ^Rajbhandari, S., et al. (2022). "DeepSpeed-MoE: Advancing Mixture-of-Experts Inference and Training to Power Next-Generation AI Scale." arXiv:2201.05596. arxiv.org/...2201.05596
- ^Mistral AI. (2025, December 2). "Introducing Mistral 3." Mistral AI Blog. mistral.ai/...mistral-3
- ^Mistral AI. (2026, March 16). "Introducing Mistral Small 4." Mistral AI Blog. mistral.ai/...mistral-small-4
- ^1 ^2Mistral AI. (2024, February 26). "Au Large." Mistral AI Blog. mistral.ai/...mistral-large
- ^Mistral AI. (2024, February 26). "Le Chat." Mistral AI Blog. mistral.ai/...le-chat-mistral
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
13 revisions · v13 · 6,650 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (170 claims, 34 sources fetched); 24 material + 25 minor fixed
Cite this page: AI Wiki. "Mixtral." aiwiki.ai, updated 28 Oct 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/mixtral