

GELU (Gaussian Error Linear Unit)
The Gaussian Error Linear Unit (GELU) is a smooth, non-monotonic activation function defined as GELU(x) = x · Φ(x), where Φ(x) is the cumulative distribution function of the standard normal distribution. It was introduced by Dan Hendrycks and Kevin Gimpel in the 2016 paper Gaussian Error Linear Units (GELUs), posted to arXiv on 27 June 2016 as 1606.08415, and it is the default nonlinearity in the feed-forward layers of BERT, the GPT series, and most transformer models built between 2018 and 2022.[1] The paper's defining sentence is that the GELU "weights inputs by their value, rather than gates inputs by their sign as in ReLUs."[1]
Hendrycks was then at the University of Chicago (later UC Berkeley), and Gimpel was at the Toyota Technological Institute at Chicago. The earliest preprint was titled Bridging Nonlinearities and Stochastic Regularizers with Gaussian Error Linear Units, and the authors kept revising the manuscript through June 2023 (final revision v5).[1]
BERT, GPT-2, GPT-3, RoBERTa, ALBERT, ELECTRA, the original GPT (often called GPT-1), and the original Vision Transformer all use GELU between the two linear layers of each feed-forward block. OpenAI's Whisper speech-recognition model uses it as well.[11] Newer architectures like PaLM and LLaMA have moved to gated variants such as SwiGLU, but GELU remains common in encoder models, vision transformers, and codebases descended from BERT.
Quick facts
| Introduced | June 2016 |
| Paper | Gaussian Error Linear Units (GELUs) |
| arXiv ID | 1606.08415 (versions v1 through v5) |
| Authors | Dan Hendrycks, Kevin Gimpel |
| Affiliations | University of Chicago / UC Berkeley; Toyota Technological Institute at Chicago |
| Exact formula | GELU(x) = x · Φ(x) = (x / 2) · (1 + erf(x / √2)) |
| Tanh approximation | 0.5 · x · (1 + tanh(√(2/π) · (x + 0.044715 · x³))) |
| Sigmoid approximation | x · σ(1.702 · x) |
| Smooth | Yes (infinitely differentiable) |
| Monotonic | No (small dip near x ≈ -0.75) |
| Used in | BERT, GPT-1, GPT-2, GPT-3, RoBERTa, ALBERT, ELECTRA, T5 v1.1 (via GeGLU), Vision Transformer, Whisper |
| Frameworks | PyTorch, TensorFlow, JAX, Hugging Face Transformers |
What problem does GELU solve?
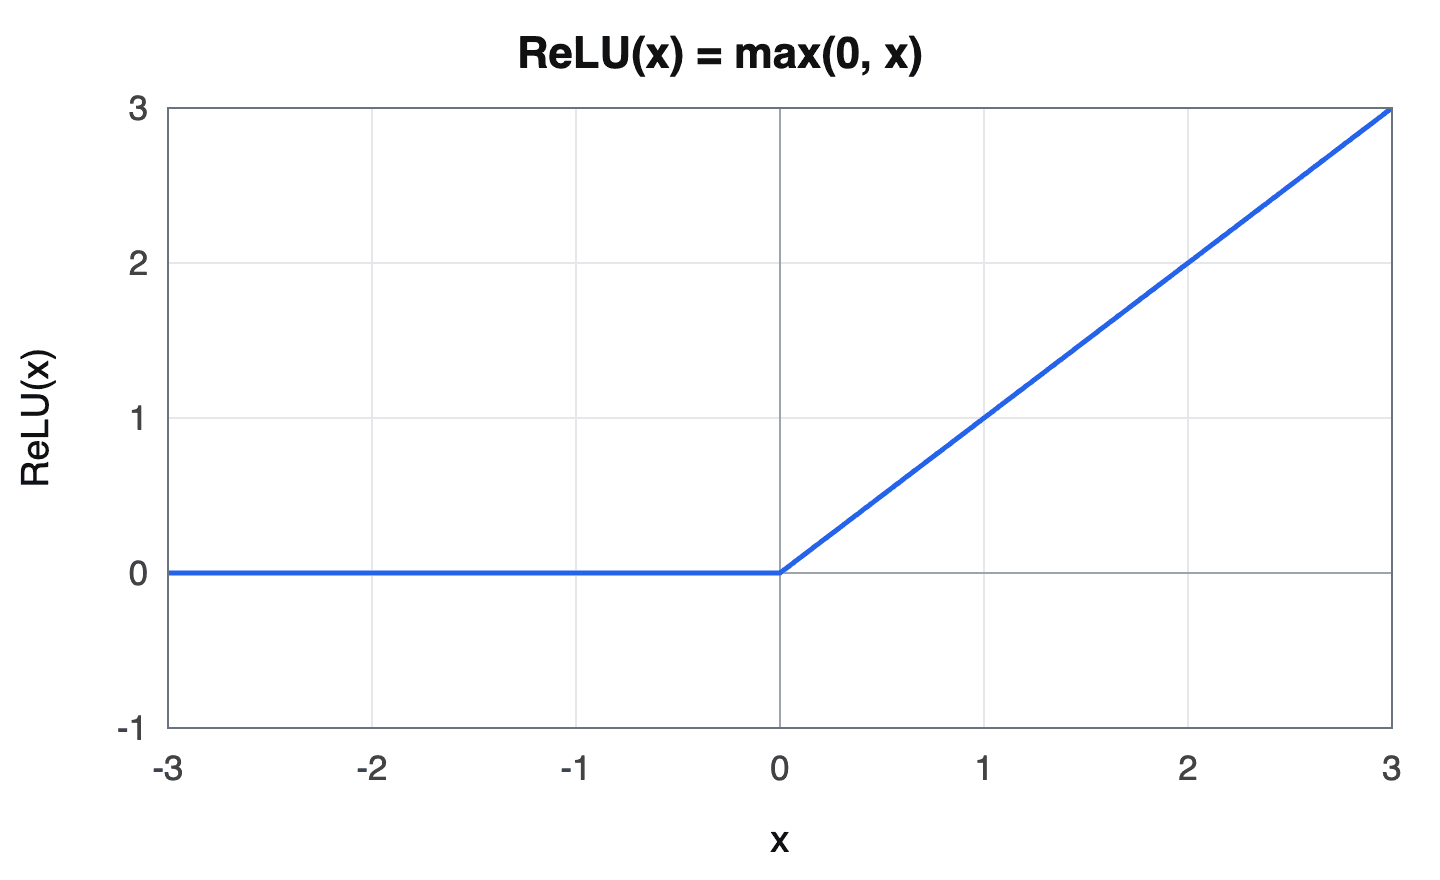
Before GELU, the dominant nonlinearity in deep networks was the rectified linear unit (ReLU), introduced in its modern form by Nair and Hinton (2010) and popularised by AlexNet (Krizhevsky, Sutskever, Hinton, 2012). ReLU is max(0, x). It is cheap, sparsity-inducing, and largely solves the vanishing-gradient problem that plagued sigmoidal networks. It also has a well-known failure mode usually called the dead ReLU problem: once a unit has a sufficiently negative pre-activation, its gradient is exactly zero, and standard gradient descent cannot recover it.
A family of patches followed. Leaky ReLU (Maas, Hannun, Ng, 2013) replaces the flat negative half with a small linear slope αx.[16] PReLU (He et al., 2015) makes that slope a learned parameter.[17] ELU (Clevert, Unterthiner, Hochreiter, 2015) replaces the negative half with α · (eˣ - 1), giving a smooth saturating curve below zero.[14] SELU (Klambauer et al., 2017) adds a fixed multiplicative scale chosen so successive layers self-normalise their activation statistics.[15]
All of these are deterministic point-wise functions of the pre-activation. In parallel, regularisation work was producing increasingly sophisticated stochastic perturbations of the forward pass: dropout (Srivastava et al., 2014), zoneout (Krueger et al., 2016), and stochastic depth (Huang et al., 2016). Hendrycks and Gimpel's contribution was to notice that a particular kind of stochastic gating gives rise, in expectation, to a smooth deterministic activation that outperforms ReLU and ELU.[1] The paper contrasts the two by how they treat the input: an activation function can be read as a way to weight or gate its input by some function of itself. ReLU weights the input by 1[x > 0], ELU weights the negative half by (eˣ - 1) / x, and GELU weights it by the probability that a Gaussian random variable is below the input.[1]
How is GELU defined?
The exact definition is
GELU(x) = x · Φ(x)
where Φ is the standard normal CDF. Equivalently, using the error function erf:
GELU(x) = 0.5 · x · (1 + erf(x / √2))
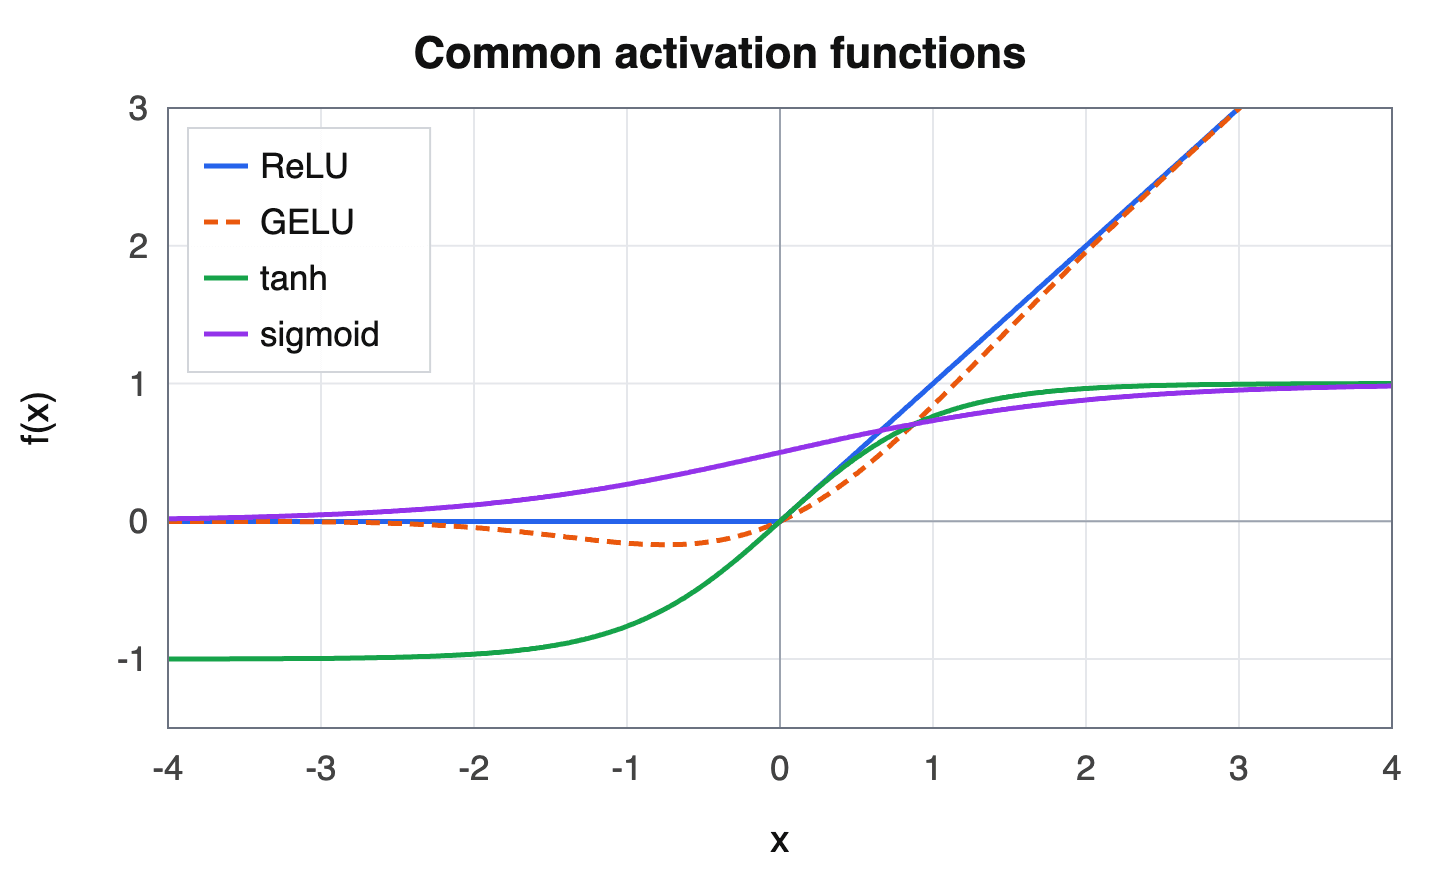
The function is smooth (infinitely differentiable), non-monotonic, and approximately linear for large positive x. For negative x it stays small but never identically zero, so unlike ReLU it does not produce dead units that always output zero. Asymptotically, GELU coincides with ReLU: GELU(x) → x as x → +∞ and GELU(x) → 0 as x → -∞.
A few quick numerical values give a feel for the shape:
Input x | Φ(x) | GELU(x) |
|---|---|---|
| -3 | 0.00135 | -0.00405 |
| -2 | 0.0228 | -0.0455 |
| -1 | 0.1587 | -0.1587 |
| -0.75 | 0.2266 | -0.170 |
| -0.5 | 0.3085 | -0.1543 |
| 0 | 0.5 | 0 |
| 0.5 | 0.6915 | 0.3457 |
| 1 | 0.8413 | 0.8413 |
| 2 | 0.9772 | 1.9545 |
| 3 | 0.99865 | 2.996 |
GELU has a small negative dip near x ≈ -0.75, where it bottoms out at roughly -0.170 (the global minimum). Past x ≈ 2 it is essentially equal to x. Past x ≈ -3 it is essentially zero. Figure 1 of the original paper plots GELU alongside ReLU and ELU and is the reference picture most readers carry in their heads.[1]
The derivative of the exact form is
GELU'(x) = Φ(x) + x · φ(x)
where φ(x) = (1 / √(2π)) · exp(-x² / 2) is the standard normal probability density function. The autograd engines in PyTorch, TensorFlow, and JAX all generate this analytically. The derivative is bounded (its supremum is about 1.13, at x = √2 ≈ 1.41), so GELU does not amplify gradients in the way some unbounded activations can.
Why a Gaussian gate? The stochastic regularizer interpretation
The original paper motivates GELU as a deterministic version of an input-dependent stochastic regularizer.[1] Suppose you multiply each input by a Bernoulli mask m, where m = 1 with probability Φ(x) and m = 0 otherwise. The expected value of the output is
E[m · x] = Φ(x) · x = GELU(x)
Under this view, GELU is the expected value of an input that is either kept (probability Φ(x)) or dropped (probability 1 - Φ(x)), where the keep probability rises with the input's magnitude on the positive side. Hendrycks and Gimpel describe it as combining the gating behaviour of ReLU and the stochasticity of dropout and zoneout into a single deterministic nonlinearity.[1] Inputs that look more like noise (small in absolute value, especially negative) get attenuated more aggressively in expectation than inputs that are clearly signal.
This framing explains the slight negative bump: when x is moderately negative, the mask is unlikely to be 1, but if it is, the output is small and negative. The expected value reflects that. The paper also reports that networks trained solely with the stochastic mask m ~ Bernoulli(Φ(x)), with no other nonlinearity, were competitive on MNIST and TIMIT.[1] In practice the deterministic version is what everyone uses.
The choice of the Gaussian CDF rather than the logistic sigmoid matches the assumption that pre-activations in well-initialised deep networks are approximately Gaussian. The sigmoid approximation x · σ(1.702 · x) substitutes the logistic CDF, rescaled so that σ(1.702 · x) closely tracks Φ(x).
What are the GELU approximations?
The exact form requires evaluating erf, which is more expensive than the elementary operations used by ReLU or the sigmoid function. The 2016 paper proposed two approximations that became standard practice for years.[1]
Tanh approximation:
GELU(x) ≈ 0.5 · x · (1 + tanh(√(2/π) · (x + 0.044715 · x³)))
The constant √(2/π) ≈ 0.7978845608 and the cubic coefficient 0.044715 come from an approximation to the normal CDF that the paper credits to Choudhury (2014).[1] This is the form used in the GPT-1 and GPT-2 reference code and in Google's BERT repository from February 2019 (the October 2018 BERT release used the exact erf form), and a great deal of pretrained-checkpoint code still uses it.[24][25]
Sigmoid approximation:
GELU(x) ≈ x · σ(1.702 · x)
where σ is the logistic sigmoid. This is faster than the tanh approximation but less accurate. It is rarely used in production but appears in the original paper as a convenient closed form.[1] The constant 1.702 is the scaling at which the logistic CDF σ(1.702 · x) closely tracks the Gaussian CDF Φ(x), and it is also the factor that turns plain SiLU (x · σ(x)) into a GELU approximation.[1][13]
Exact form uses erf directly. Most modern hardware has fast erf instructions or libm implementations, so on contemporary GPUs the exact form is competitive with the tanh approximation in wall-clock time. PyTorch exposes the choice through torch.nn.functional.gelu(x, approximate='none') (the default, which calls erf) and approximate='tanh' (the formulation used in OpenAI's GPT code).[20] TensorFlow exposes the same selection through tf.nn.gelu with an approximate=True/False flag.[21] JAX provides jax.nn.gelu with an approximate keyword argument that defaults to True.[22]
The maximum absolute deviation between the tanh approximation and the exact erf form is on the order of 1e-4 over the range [-5, 5]. The sigmoid approximation deviates by closer to 1e-2 in the same range.
Properties
- Smooth. Continuous derivatives of all orders, unlike ReLU (kink at zero) or Leaky ReLU.
- Non-monotonic. Decreases on
(-∞, -0.75)then increases, so it is not one-to-one near the origin. - Differentiable everywhere. No special handling for
x = 0. - Asymptotically ReLU.
GELU(x) - max(0, x) → 0as|x| → ∞. - Bounded below.
GELU(x) ≥ -0.170for all realx. - Approximately zero-centred outputs. Easier to layer-normalise than ReLU.
- Self-gated. The function gates each input by some monotone function of itself, putting it in the same family as Swish/SiLU and Mish.
GELU's small negative bump means that two distinct inputs can produce the same output, which complicates some theoretical analyses but does not seem to hurt training in practice.
How does GELU differ from ReLU and other activations?
| Activation | Formula | Smooth | Non-monotonic | Notes |
|---|---|---|---|---|
| ReLU | max(0, x) | No | No | Cheapest. Standard before transformers. Has dead-unit problem. |
| Leaky ReLU | max(αx, x), α = 0.01 typical | No | No | Avoids dead units. Cheap. |
| PReLU | max(αx, x), α learned | No | No | Adds parameters per channel. |
| ELU | x if x > 0, else α(eˣ - 1) | Yes | No | Smooth saturating negatives. |
| SELU | Scaled ELU with fixed α, λ | Yes | No | Self-normalising. |
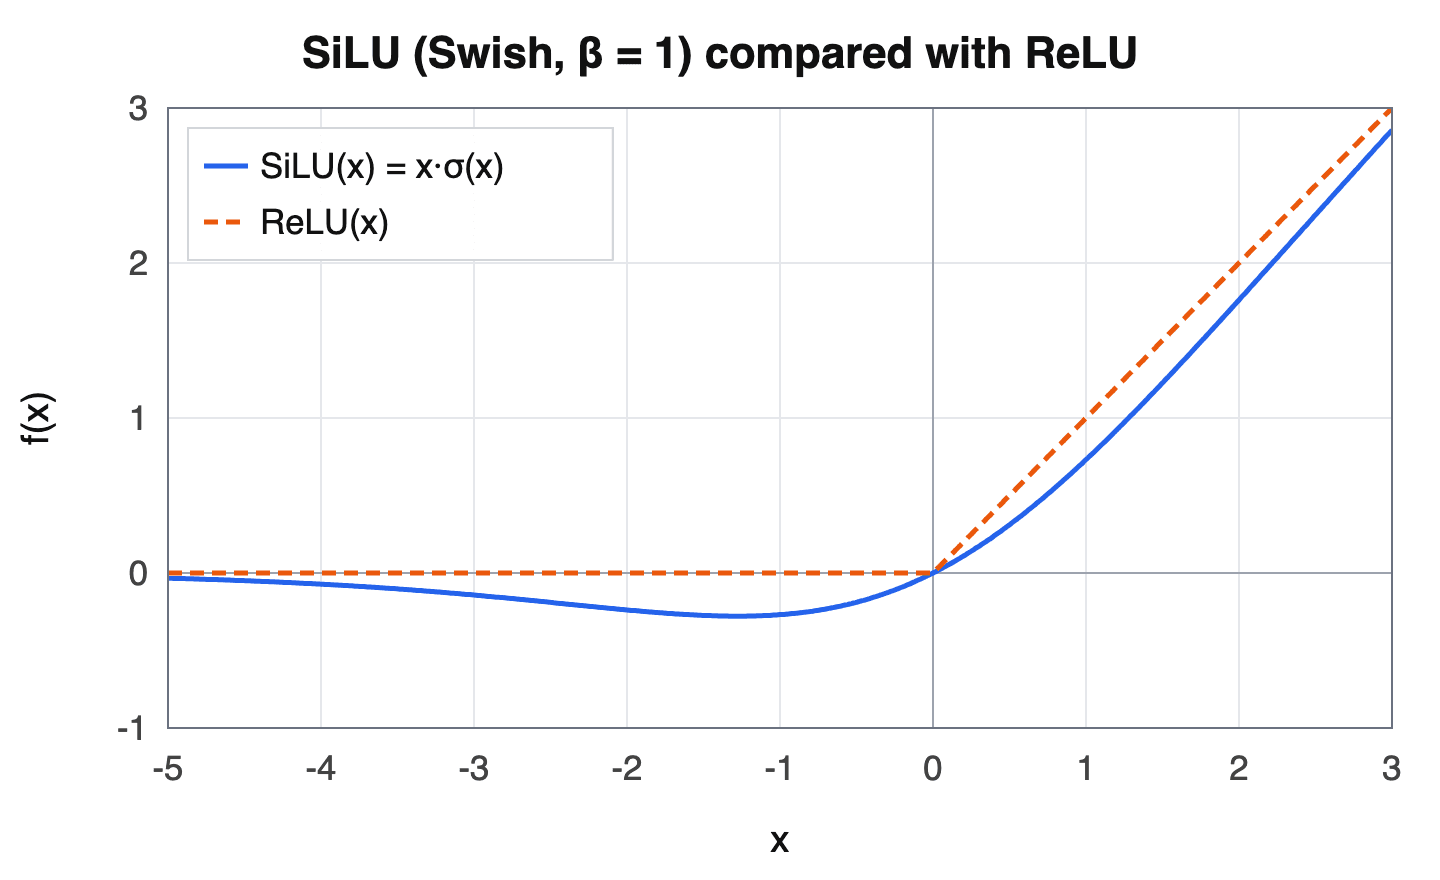
| SiLU / Swish | x · σ(x) | Yes | Yes | GELU's sigmoid form with the 1.702 coefficient set to 1. |
| GELU (exact) | x · Φ(x) | Yes | Yes | Gaussian gate. Min around -0.170. |
| GELU (tanh approx) | 0.5 · x · (1 + tanh(√(2/π) · (x + 0.044715 · x³))) | Yes | Yes | BERT/GPT-2 default. |
| Mish | x · tanh(softplus(x)) | Yes | Yes | Min about -0.31. |
The key difference from ReLU is captured by the original abstract: GELU "weights inputs by their value, rather than gates inputs by their sign."[1] ReLU makes a hard binary decision based on the sign of the pre-activation; GELU applies a smooth, probabilistic weighting that keeps a small nonzero signal for negative inputs and so avoids dead units.
The SiLU function x · σ(x) was introduced and named in the same 2016 paper, as a separate activation from the GELU sigmoid approximation (which uses the 1.702 coefficient), and was rediscovered by Ramachandran, Zoph, and Le of Google Brain in 2017 under the name Swish.[1][13] Libraries such as TensorFlow and PyTorch later adopted the name SiLU. The two names refer to the same function. GELU is sometimes described as Swish with a Gaussian gate instead of a sigmoid one. In practice GELU and SiLU produce very similar shapes, with GELU having a slightly more pronounced negative dip.
What did the original experiments show?
Hendrycks and Gimpel ran experiments on MNIST classification, MNIST autoencoding, Twitter part-of-speech tagging, TIMIT frame classification, CIFAR-10, and CIFAR-100, reporting "performance improvements across all considered computer vision, natural language processing, and speech tasks."[1] GELU had the best median result against ReLU and ELU in every setting they tested, with the largest gap on CIFAR-100. The differences were modest but consistent.[1]
- MNIST classification. Eight-layer, 128-neuron-wide fully connected networks trained for 50 epochs with a batch size of 128. GELU tended to have the lowest median training log loss with and without dropout, and was at least as robust as ReLU and ELU to noised inputs.
- MNIST autoencoding. Deep autoencoder with layers of width 1000, 500, 250, 30, 250, 500, 1000. GELU achieved lower reconstruction error than ReLU or ELU at both learning rates tested.
- Twitter POS tagging. Two-layer network on part-of-speech-annotated tweets. Median test error 12.57% for GELU, 12.67% for ReLU, and 12.91% for ELU.
- CIFAR-10 and CIFAR-100. A 9-layer CNN trained for 200 epochs on CIFAR-10 (median error 7.89% for GELU, 8.16% for ReLU, 8.41% for ELU) and a 40-layer Wide ResNet with widening factor 4 trained for 50 epochs on CIFAR-100 (20.74%, 21.77%, and 22.98%).
- TIMIT frame classification. Five-layer, 2048-neuron-wide fully connected classifier. Median test error 29.3% for GELU versus 29.5% for ReLU and 29.6% for ELU.
These benchmarks predate the transformer era. The reason GELU caught on was not the MNIST result but the fact that the GPT and BERT teams adopted it for the FFN layers, and pretty much every transformer paper after that used whatever the BERT codebase used.
Which transformer models use GELU?
GELU was not the first nonlinearity used inside a transformer. The original Attention Is All You Need paper (Vaswani et al., 2017) used ReLU in the position-wise feed-forward sublayer.[19] The shift to GELU happened with the next generation of pretrained models.
| Model | Year | FFN activation | Approximation in reference code |
|---|---|---|---|
| Original Transformer | 2017 | ReLU | n/a |
| GPT (GPT-1) | 2018 | GELU | Tanh approximation |
| BERT | 2018 | GELU | Exact (erf) at the October 2018 release; tanh in the repository from February 2019[24] |
| GPT-2 | 2019 | GELU | Tanh approximation |
| RoBERTa | 2019 | GELU | Exact (fairseq gelu)[27] |
| XLNet | 2019 | GELU | Tanh approximation |
| ALBERT | 2019 | GELU | Tanh approximation |
| T5 (v1.0) | 2019 | ReLU | n/a |
| T5 (v1.1) | 2020 | GeGLU (uses GELU) | Tanh approximation[28] |
| ELECTRA | 2020 | GELU | Tanh approximation |
| GPT-3 | 2020 | GELU | No public code (architecture follows GPT-2) |
| Vision Transformer | 2020 | GELU | Tanh approximation |
| Whisper | 2022 | GELU | Exact (PyTorch default)[26] |
| PaLM | 2022 | SwiGLU | n/a |
| LLaMA | 2023 | SwiGLU | n/a |
BERT (Devlin et al., October 2018) is the single largest cause of GELU's spread.[2] Its public TensorFlow reference implementation first defined gelu with the exact erf form and switched to the tanh approximation in February 2019, and much of the code that built on BERT inherited one form or the other.[24] The OpenAI GPT-1 paper (Radford et al., June 2018) also used GELU, but BERT's open-source release was the catalyst that pushed it into nearly every transformer codebase between 2018 and 2022.[3]
How does GELU compare to SwiGLU?
The activation question got more complicated in February 2020 with Noam Shazeer's paper GLU Variants Improve Transformer (arXiv:2002.05202), which proposed using gated linear units in place of the standard FFN.[12] Two variants became popular:
- GeGLU:
GeGLU(x, W, V, b, c) = GELU(xW + b) ⊗ (xV + c). T5 v1.1 and the LaMDA family use this.[12] - SwiGLU: same structure but with SiLU/Swish in place of GELU.[12] PaLM and LLaMA adopted this, and the Mistral and Mixtral lines kept it.
Gated FFNs use three weight matrices instead of two and reduce the inner dimension by 2/3 to keep parameter count roughly constant.[12] They consistently produce small but reliable perplexity improvements over plain GELU FFNs. Most large open-weight models released after 2022 use SwiGLU. GELU is still the default in encoder-only and encoder-decoder models, in vision transformers, and in any transformer codebase matching the BERT lineage. Shazeer offers no theoretical account of the gains, concluding: "We offer no explanation as to why these architectures seem to work; we attribute their success, as all else, to divine benevolence."[12]
Implementation
A reference PyTorch implementation of all three forms looks like this:
import math
import torch
import torch.nn.functional as F

def gelu_exact(x):
    return 0.5 * x * (1.0 + torch.erf(x / math.sqrt(2.0)))

def gelu_tanh(x):
    c = math.sqrt(2.0 / math.pi)
    return 0.5 * x * (1.0 + torch.tanh(c * (x + 0.044715 * x.pow(3))))

def gelu_sigmoid(x):
    return x * torch.sigmoid(1.702 * x)

# Library-provided versions
y1 = F.gelu(x)                        # exact, uses erf
y2 = F.gelu(x, approximate='tanh')    # tanh approximation
The library version is preferable in real code because it dispatches to fused kernels on supported hardware.
Framework APIs
- PyTorch.
torch.nn.GELU(approximate='none' | 'tanh')andtorch.nn.functional.gelu. Theapproximate='tanh'flag was added in PyTorch 1.12 (June 2022); before that, only the exact form was available.[20] - TensorFlow.
tf.keras.activations.gelu(x, approximate=False). Theapproximateflag has been present since TensorFlow 2.4.[21] - JAX.
jax.nn.gelu(x, approximate=True). The default is the tanh approximation, the opposite of PyTorch's default.[22] - Hugging Face Transformers. The
transformers.activationsmodule exposesgelu(exacterf),gelu_new(BERT tanh approximation, kept for checkpoint compatibility),gelu_fast(cheaper tanh variant),gelu_pytorch_tanh(callsF.gelu(x, approximate='tanh')),quick_gelu(sigmoid approximation, used by CLIP), andgelu_python(a pure-Python reference). The names are historical artefacts.[23]
The quick_gelu variant matches the QuickGELU module in OpenAI's CLIP code, which is used in the transformer blocks of both its text encoder and its ViT image encoder.[29] Loading CLIP weights with the wrong activation produces clearly degraded zero-shot accuracy, which is a recurring source of confusion.
Numerical reproducibility pitfalls
Small numerical differences between the exact and tanh approximations can affect reproducibility. Hugging Face Transformers keeps both forms for this reason: its gelu is documented as the original implementation in Google's BERT repository when it was first created (exact erf), gelu_new as the version later used in that repository and identical to OpenAI GPT (tanh), and gelu_pytorch_tanh calls PyTorch's native approximate='tanh' kernel, which the library notes is not an exact numerical match to gelu_new because of rounding.[23][24]
Practical rules:
- Match the activation used at training time. If a checkpoint was trained with the tanh approximation, evaluate it with the tanh approximation.
- For new training runs, the exact
erfform is the safer default. It is framework-agnostic and avoids the historical baggage of competing approximations. - Test for numerical equivalence carefully. Comparing forward passes between frameworks at a tolerance of
1e-6will fail if one side uses the exact form and the other uses the tanh approximation;1e-3is more realistic.
A related issue affects half-precision (FP16/BF16) training. The tanh approximation involves a cubic term 0.044715 · x³, which can overflow in FP16 for large x even though the final output is well-behaved. Most framework implementations compute the cubic in higher precision to avoid this. The exact erf form is more numerically stable in low precision.
Computational considerations
On modern GPUs, the cost of erf is dominated by the surrounding elementwise * matmul + bias pattern, so the activation choice is not the bottleneck for most transformer training. The tanh approximation can be marginally faster on hardware with weak transcendental support, which is one reason older code paths still use it.
The more practical reason to keep using the tanh form is checkpoint compatibility. If you are running a pretrained model whose weights were tuned against the tanh approximation, switching to the exact form changes the function values slightly, and the model's downstream metrics will drift. The drift is small but reproducible. Derivatives are inexpensive in either form: the exact derivative is Φ(x) + x · φ(x), and every autograd framework computes the tanh derivative correctly.
Continue reading
- ReLUReLU, short for rectified linear unit, is an activation function that maps a real input to its positive part:Mentioned 31 times above
- BERTBERT, short for Bidirectional Encoder Representations from Transformers, is a pretrained language model introduced by researchers at Google Research in 2018.Mentioned 16 times above
- SwiGLUSwiGLU (Swish-Gated Linear Unit) is the activation function used inside the feed-forward sublayer of most modern transformer large language models, including LLaMA, PaLM, Mistral, Qwen, and DeepSeek.Mentioned 7 times above
- TransformersA Transformer is a deep learning architecture, introduced by eight Google researchers in the 2017 paper "Attention Is All You Need", that uses attention as the sole mechanism for modeling relationships between…Mentioned 7 times above
- Activation FunctionAn activation function is a nonlinear mathematical function applied to the output of each neuron in an artificial neural network, and it is what gives the network the ability to learn complexMentioned 4 times above
- arXivarXiv is the free, open-access repository where nearly every consequential artificial intelligence paper of the deep learning era first appeared in public, often months before, or instead ofMentioned 3 times above
More from See also
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17Hendrycks, Dan; Gimpel, Kevin. *Gaussian Error Linear Units (GELUs)*. arXiv:1606.08415, 27 June 2016 (final revision v5, June 2023). arxiv.org/...1606.08415
- ^Devlin, Jacob; Chang, Ming-Wei; Lee, Kenton; Toutanova, Kristina. *BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding*. arXiv:1810.04805, October 2018.
- ^Radford, Alec; Narasimhan, Karthik; Salimans, Tim; Sutskever, Ilya. *Improving Language Understanding by Generative Pre-Training* (GPT-1), OpenAI, June 2018.
- Radford, Alec; Wu, Jeffrey; Child, Rewon; Luan, David; Amodei, Dario; Sutskever, Ilya. *Language Models are Unsupervised Multitask Learners* (GPT-2), OpenAI, 2019.
- Brown, Tom et al. *Language Models are Few-Shot Learners* (GPT-3). arXiv:2005.14165, May 2020.
- Liu, Yinhan et al. *RoBERTa: A Robustly Optimized BERT Pretraining Approach*. arXiv:1907.11692, July 2019.
- Lan, Zhenzhong et al. *ALBERT: A Lite BERT for Self-supervised Learning of Language Representations*. arXiv:1909.11942, September 2019.
- Clark, Kevin; Luong, Minh-Thang; Le, Quoc V.; Manning, Christopher D. *ELECTRA*. arXiv:2003.10555, March 2020.
- Raffel, Colin et al. *Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer* (T5). arXiv:1910.10683, October 2019.
- Dosovitskiy, Alexey et al. *An Image is Worth 16x16 Words* (Vision Transformer). arXiv:2010.11929, October 2020.
- ^Radford, Alec et al. *Robust Speech Recognition via Large-Scale Weak Supervision* (Whisper). arXiv:2212.04356, December 2022.
- ^1 ^2 ^3 ^4 ^5Shazeer, Noam. *GLU Variants Improve Transformer*. arXiv:2002.05202, February 2020. arxiv.org/...2002.05202
- ^1 ^2Ramachandran, Prajit; Zoph, Barret; Le, Quoc V. *Searching for Activation Functions* (Swish). arXiv:1710.05941, October 2017.
- ^Clevert, Djork-Arne; Unterthiner, Thomas; Hochreiter, Sepp. *Fast and Accurate Deep Network Learning by Exponential Linear Units (ELUs)*. arXiv:1511.07289, November 2015.
- ^Klambauer, Gunter et al. *Self-Normalizing Neural Networks* (SELU). arXiv:1706.02515, June 2017.
- ^Maas, Andrew L.; Hannun, Awni Y.; Ng, Andrew Y. *Rectifier Nonlinearities Improve Neural Network Acoustic Models* (Leaky ReLU). ICML 2013.
- ^He, Kaiming et al. *Delving Deep into Rectifiers* (PReLU). arXiv:1502.01852, February 2015.
- Misra, Diganta. *Mish: A Self Regularized Non-Monotonic Activation Function*. arXiv:1908.08681, August 2019.
- ^Vaswani, Ashish et al. *Attention Is All You Need*. arXiv:1706.03762, June 2017.
- ^1 ^2PyTorch documentation, `torch.nn.functional.gelu`. pytorch.org/...torch.nn.functional.gelu
- ^1 ^2TensorFlow documentation, `tf.keras.activations.gelu`. tensorflow.org/...gelu
- ^1 ^2JAX documentation, `jax.nn.gelu`. jax.readthedocs.io/...jax.nn.gelu
- ^1 ^2Hugging Face Transformers, `transformers.activations` source. github.com/...activations.py
- ^1 ^2 ^3 ^4Google Research, `bert` repository, `modeling.py` (initial release of 31 October 2018 uses `tf.erf`; tanh form from the commit of 7 February 2019). github.com/...modeling.py
- ^OpenAI, `gpt-2` repository, `src/model.py`. github.com/...model.py
- ^OpenAI, `whisper` repository, `whisper/model.py`. github.com/...model.py
- ^fairseq, `fairseq/modules/gelu.py`. github.com/...gelu.py
- ^Hugging Face Transformers, `configuration_t5.py` (maps T5 v1.1's `gated-gelu` to `gelu_new`). github.com/...configuration_t5.py
- ^OpenAI, `CLIP` repository, `clip/model.py`. github.com/...model.py
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
8 revisions · v8 · 3,865 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (95 claims, 22 sources fetched); 16 material + 12 minor fixed
Cite this page: AI Wiki. "GELU (Gaussian Error Linear Unit)." aiwiki.ai, updated 22 Jun 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/gelu