

SciCode
SciCode is a research coding benchmark that asks large language models to write Python code for realistic, PhD level scientific problems drawn from working scientists' day to day workflows. It contains 80 main problems decomposed into 338 subproblems across 16 subfields in mathematics, physics, chemistry, biology, and materials science. SciCode was introduced by Minyang Tian and 29 collaborators in the paper "SciCode: A Research Coding Benchmark Curated by Scientists" (arXiv:2407.13168, July 2024) and accepted to the NeurIPS 2024 Datasets and Benchmarks Track.[1][2][3]
| SciCode | |
|---|---|
| Overview | |
| Full name | SciCode: A Research Coding Benchmark Curated by Scientists |
| Abbreviation | SciCode |
| Description | A research coding benchmark of PhD level scientific problems decomposed into subproblems, with scientist annotated gold solutions and numerical test cases |
| Release date | July 2024 (arXiv); NeurIPS 2024 Datasets and Benchmarks Track |
| Authors | Minyang Tian, Luyu Gao, Shizhuo Dylan Zhang, et al. (30 authors) |
| Lead institutions | University of Illinois Urbana-Champaign, Carnegie Mellon University, Argonne National Laboratory |
| Technical Details | |
| Type | Scientific computing, code generation, LLM evaluation |
| Modality | Text (Python code) |
| Task format | Multi step Python function implementation with executable test cases |
| Total main problems | 80 (65 test, 15 development) |
| Total subproblems | 338 (288 test, 50 development) |
| Disciplines covered | 16 subfields across 5 domains (the project website says 6) |
| Domains | Mathematics, physics, chemistry, biology, materials science |
| Languages | Python |
| Evaluation | Numerical test cases, domain specific tests, pass@1 |
| Performance | |
| Random baseline | Approximately 0% |
| Best main problem score (no background) | 7.7% (o1 preview, Sept 2024); 9.2% to 10.8% (o3 mini and o4 mini variants, 2025) |
| Best subproblem score (no background) | 28.5% (o1 preview, 2024); 34.4% (o3 mini high, official leaderboard, 2025) |
| Best score with background (2024 paper) | 13.8% (o1 mini, main); 37.2% (Claude 3.5 Sonnet (new), subproblems) |
| Best subproblem score, with background (2026) | 66.9% (Claude Opus 5.5, Artificial Analysis, November 2026); about 60% for mid 2026 leaders such as Claude Fable 5 |
| Saturated | No |
| Resources | |
| Website | scicode-bench.github.io |
| Paper | arXiv:2407.13168 |
| GitHub | scicode-bench/SciCode |
| Leaderboard | HAL Princeton SciCode |
| License | Apache 2.0 |
The project is led from the University of Illinois Urbana-Champaign, Carnegie Mellon University, and Argonne National Laboratory, with contributions from MIT, Harvard, the University of Chicago, Stanford, and Princeton. Unlike exam style benchmarks such as HumanEval or MBPP, SciCode targets the kind of code that produces published results, including numerical methods, simulations, and quantitative modeling.[1][4]
SciCode is notably difficult. The authors report that "Claude3.5-Sonnet, the best-performing model among those tested, can solve only 4.6% of the problems in the most realistic setting," meaning fully correct solutions to just 4.6% of the 65 main test problems without background notes.[1] Progress since has diverged by metric. On the strict main problem metric, where every subproblem in a problem must pass, the best score on the official and HAL leaderboards (no background) is still only about 9% to 11% (o3 mini and o4 mini variants, 2025).[5][6] An August 2026 re-run of twelve 2026 frontier models with background on the original dataset found 9% to 27% main problem accuracy.[10] On the easier subproblem metric with scientist background supplied, 2026 frontier models such as Gemini 3.1 Pro, GPT-5.4, and Claude Fable 5 clustered near 60% pass@1 on the Artificial Analysis leaderboard by mid 2026, and as of November 2026 the top score there is 66.9% (Claude Opus 5.5).[8] The August 2026 SciCode-Verified audit attributed much of that plateau to defects in the benchmark's tests; Artificial Analysis removed SciCode from its Intelligence Index in version 5.0 (October 2026) and marked its SciCode results as under review.[8][10][11]
Background and motivation
Research software is messy in ways that classroom problems are not. A scientist usually has to combine knowledge of an underlying physical theory, a numerical method that handles stiffness or stability, an implementation in NumPy or SciPy, and a way to validate the output against a known limiting case. Existing code generation benchmarks largely ignore this layered structure: HumanEval evaluates short self contained functions, SWE-bench targets software engineering bug fixes, and competitive programming sets focus on puzzles.[1]
The SciCode authors wanted a benchmark that reflects how scientists actually use code. Many problems were sourced directly from scripts the contributors had written for their own published research, then rewritten so that the solution path is well defined and a hidden numerical test exists for every subproblem. Several problems reproduce methods from Nobel Prize winning research: the self consistent field (SCF) method for density functional theory (Chemistry, 1998), the PMNS matrix for neutrino oscillation in matter (Physics, 2015), the Haldane model for the anomalous quantum Hall effect (Physics, 2016), optical tweezer simulations for microscopic thermodynamics (Physics, 2018), and the replica method for spin glasses (Physics, 2021).[1][2]
Dataset composition
The full benchmark contains 80 main problems and 338 subproblems. The authors release a development split (15 main problems, 50 subproblems) for prompt engineering and a held out test split (65 main problems, 288 subproblems) used for the public leaderboard. The breakdown of main problems by subfield follows the table below.[1][2]
| Domain | Subfield | Main problems |
|---|---|---|
| Physics | Condensed matter physics | 13 |
| Physics | Optics | 10 |
| Physics | Quantum information and computing | 6 |
| Physics | Computational physics | 5 |
| Physics | Astrophysics | 2 |
| Physics | Particle physics | 1 |
| Mathematics | Numerical linear algebra | 8 |
| Mathematics | Computational mechanics | 5 |
| Mathematics | Computational finance | 1 |
| Chemistry | Quantum chemistry | 5 |
| Chemistry | Computational chemistry | 3 |
| Materials science | Semiconductor materials | 7 |
| Materials science | Molecular modeling | 6 |
| Biology | Ecology | 6 |
| Biology | Biochemistry | 1 |
| Biology | Genetics | 1 |
Main problems are split into a median of 3 and a maximum of 15 subproblems (some have only one), ordered so that earlier steps can be reused as helper functions in later ones. Subproblems are written as Python function signatures with a docstring that describes the scientific task, inputs, and expected outputs. Test cases live in a numerical results file (test_data.h5) and many of them check agreement with closed form analytical solutions, published results, or independent reference implementations.[1][2][6]
Problem structure
Every subproblem combines four kinds of difficulty: knowledge recall (retrieving the relevant scientific facts), mathematical reasoning (deriving or rearranging the right equations), algorithm design (picking and adapting a numerical method), and code synthesis (writing a runnable Python function). The model is also required to remain consistent across subproblems, since later steps typically import the solutions of earlier ones.[1]
| Required skill | What the model has to do | Example |
|---|---|---|
| Knowledge recall | Pull domain specific facts from memory | Reflection from a quarter wave distributed Bragg reflector; the Lotka Volterra predator prey equations |
| Mathematical reasoning | Derive or rearrange formulas | Going from the time independent Schrodinger equation to a tridiagonal matrix system |
| Algorithm design | Choose stable, efficient numerical methods | Using Numerov shooting for a quantum harmonic oscillator, or Metropolis sampling for a 2D Ising model |
| Code synthesis | Translate the chosen approach into Python | Implementing the SCF loop in a quantum chemistry calculation |
| Cross step consistency | Reuse outputs from earlier subproblems | Plugging an earlier Hamiltonian builder into a later eigensolver |
Reproducing methods like density functional theory, density matrix renormalization group (DMRG) calculations, or grand canonical Monte Carlo simulations from scratch in Python requires both conceptual understanding and the bookkeeping discipline that real research demands.[1][2]
How is SciCode scored?
SciCode runs in two main settings. In the standard setting, the model receives only the function signature, a brief docstring, and any imports already produced for earlier subproblems. In the with background setting, the model also gets a scientist authored note that explains the relevant physics, equations, or algorithm. The two settings let researchers separate two skills: how much a model knows about a field versus how well it can implement an already explained method.[1]
| Setting | Inputs to model | What it measures |
|---|---|---|
| Standard (no background) | Function signature, docstring, prior subproblem solutions | Combined knowledge, reasoning, and implementation |
| With background | All of the above plus scientist annotated background | Implementation and instruction following, given correct knowledge |
Generated code is executed against the hidden numerical tests with np.allclose style comparisons. A subproblem counts as correct when all of its tests pass; a main problem counts as correct only when every subproblem in it passes, which is why main problem accuracy is far lower than subproblem accuracy. The paper defines the bar precisely: "The LM is considered to have successfully solved the main problem when all subproblem solutions are correct and the integrated solution to the main problem is correct."[1] The original harness used a two step pipeline (gencode.py then test_generated_code.py); newer evaluations integrate with the Inspect AI framework maintained by the UK AI Security Institute (formerly the AI Safety Institute).[2][6]
Quality control involved three rounds of validation: at least two in domain scientists cross checking each problem and its tests, an out of domain scientist checking clarity, and a GPT-4 pass used to flag ambiguous prompts. Dependencies are kept to widely used libraries such as NumPy, SciPy, and SymPy.[1][2]
Headline results
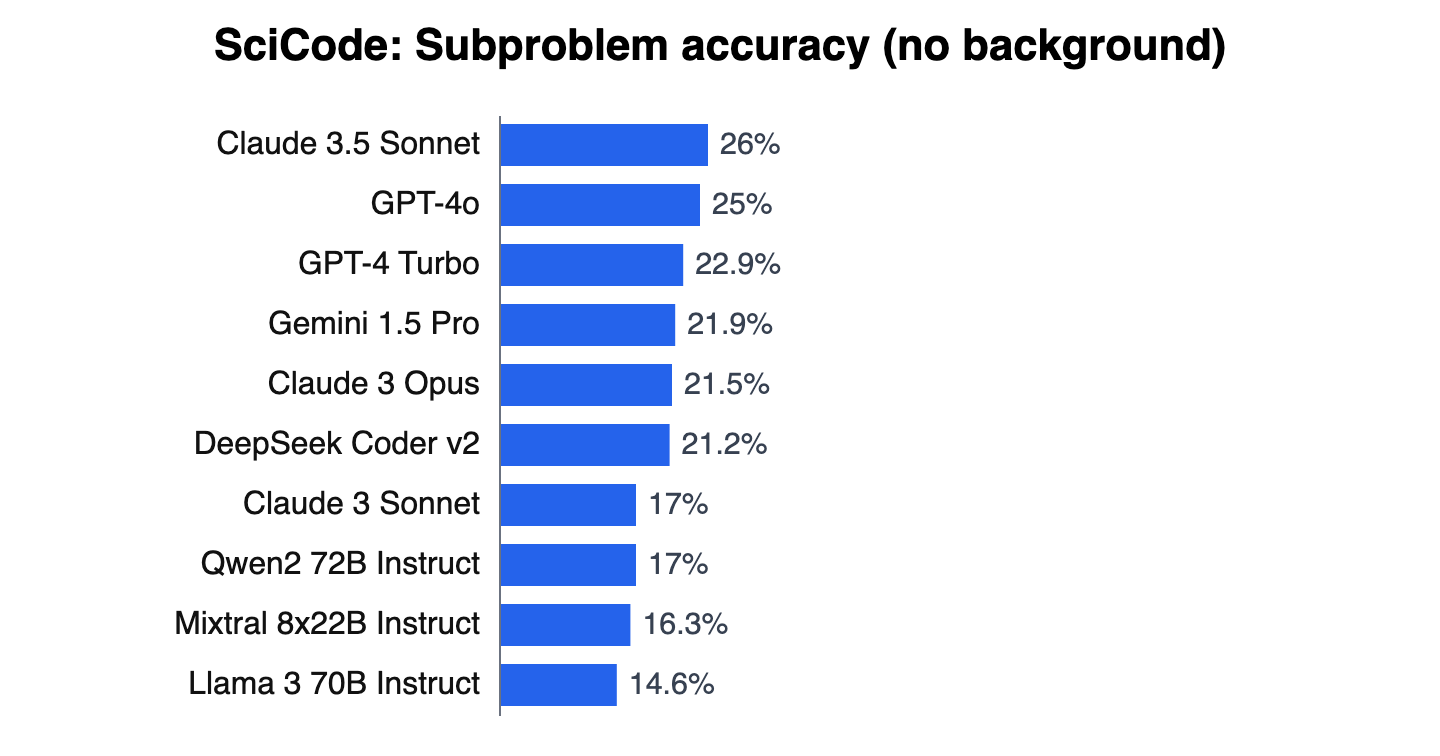
The original paper reported pass@1 scores for ten models. Claude 3.5 Sonnet led the standard setting with 4.6% main problem accuracy, with GPT-4o, GPT-4 Turbo, Gemini 1.5 Pro, and Claude 3 Opus clustered near 1.5%. Subproblem scores were much higher, since many subproblems are isolated helper functions that do not require all earlier code to be perfect.[1]
| Model | Subproblem accuracy (no background) | Main problem accuracy (no background) |
|---|---|---|
| Claude 3.5 Sonnet | 26.0% | 4.6% |
| GPT-4o | 25.0% | 1.5% |
| GPT-4 Turbo | 22.9% | 1.5% |
| Gemini 1.5 Pro | 21.9% | 1.5% |
| Claude 3 Opus | 21.5% | 1.5% |
| DeepSeek Coder v2 | 21.2% | 3.1% |
| Claude 3 Sonnet | 17.0% | 1.5% |
| Qwen2 72B Instruct | 17.0% | 1.5% |
| Mixtral 8x22B Instruct | 16.3% | 0.0% |
| Llama 3 70B Instruct | 14.6% | 0.0% |
Adding scientist annotated background boosted performance, especially for reasoning models. Claude 3.5 Sonnet jumped to 35.4% on subproblems and 12.3% on main problems. OpenAI's o1 mini gained the most from background knowledge and topped that chart at around 13.8% pass@1 on main problems in the NeurIPS camera ready version of the paper (an improvement of 12.3 points), which suggests knowledge gaps, not pure reasoning, are a major bottleneck.[4]
What is the current best score on SciCode?
SciCode is reported two different ways, and the two numbers look very different. The main problem metric counts a problem correct only when every subproblem passes and the integrated solution runs; the subproblem metric scores each step independently, usually with scientist background supplied. Because a single main problem can contain up to 15 subproblems, main problem accuracy is far lower than subproblem accuracy.[6][8]
On the main problem metric, the maintained leaderboard at HAL (Holistic Agent Leaderboard) hosted by Princeton tracks both raw accuracy and dollar cost per evaluation across newer models and agent scaffolds. As of its 2025 snapshot the top entries include o4 mini and o3 variants, GPT-4.1, and Claude Opus 4.1 running under either zero shot or tool calling SciCode agents, none of which clears 10%. HAL noted on October 5, 2026 that its reported costs are overstated (by exactly 2x for some models), so the cost column is approximate.[5]
| Agent | Model | Main problem accuracy | Estimated cost |
|---|---|---|---|
| SciCode zero shot agent | o4 mini Low | 9.23% | About $1.74 |
| SciCode tool calling agent | o3 Medium | 9.23% | About $111 |
| SciCode tool calling agent | Claude Opus 4.1 | 7.69% | About $625 |
| SciCode tool calling agent | Claude Opus 4.1 High | 6.92% | About $551 |
| SciCode zero shot agent | GPT-4.1 | 6.15% | About $2.82 |
| Not a HAL run | o1 preview (Sept 2024) | 7.7% | NeurIPS paper figure, not on HAL |
The GitHub leaderboard also lists o3 mini variants between roughly 9% and 11%, records its highest main problem score at 10.8% (o3 mini, low reasoning), and reports DeepSeek R1 at 4.6% main problem accuracy, matching Claude 3.5 Sonnet from the original paper. HAL has since paused adding new models to concentrate on measuring agent reliability, so its main problem figures reflect 2025 systems.[5][6]
Subproblem scores tell a faster moving story. Artificial Analysis, which scores the 288 test subproblems pass@1 with scientist background included, reported that 2026 frontier models clustered near 60% by mid 2026 (in a June 2026 snapshot, Claude Fable 5 at 60.2%, Gemini 3.1 Pro Preview at 58.9% and GPT-5.4 at 56.6%), and as of November 2026 its top score is 66.9% (Claude Opus 5.5). Artificial Analysis removed SciCode from its Intelligence Index in version 5.0 (October 2026) and lists it as a legacy evaluation under review after the SciCode-Verified audit. Vendor self-reported figures collected by llm-stats are not independent runs and can differ from Artificial Analysis numbers.[8][9][11]
| Model | Developer | Subproblem accuracy (with background) |
|---|---|---|
| Claude Opus 5.5 (max), November 2026 | Anthropic | 66.9% |
| Claude Opus 5.5 (xhigh), November 2026 | Anthropic | 65.0% |
| Claude Fable 5.1 (max), November 2026 | Anthropic | 63.1% |
| Claude Fable 5, June 2026 | Anthropic | 60.2% |
| Gemini 3.1 Pro Preview, June 2026 | 58.9% | |
| GPT-5.4 (xhigh), June 2026 | OpenAI | 56.6% |
| Gemini 3 Pro Preview (high), June 2026 | 56.1% | |
| Kimi K2.6, June 2026 | Moonshot AI | 53.5% |
Even at 60% to 67% subproblem accuracy on the original dataset, no system reliably solves whole research problems on it, although the SciCode-Verified authors argue many of those failures are false rejections caused by defective tests.[10] The two metrics together capture the state of play: individual scientific coding steps are increasingly within reach, while stringing 10 to 15 of them into a correct, self consistent program is not.[8][9]
Is SciCode saturated?
No, on the original dataset. On the official and HAL leaderboards, which stopped adding models in 2025, the best no-background main problem score is about 10.8% (o3 mini, low reasoning).[5][6] An August 2026 re-run of twelve frontier models with background found 9% to 27% main problem accuracy on the original data, rising to 69% to 92% on the corrected SciCode-Verified release.[10] Subproblem accuracy with background has passed 50%, but solving a complete research problem end to end, where every subproblem must be correct and mutually consistent, is still out of reach. That is the gap the benchmark was built to expose.
Common failure modes and example problems
A recurring pattern in scientific code generation is that models produce code that looks reasonable but uses a wrong sign convention, an outdated empirical formula, or an unstable algorithm. Cross subproblem consistency is another sticking point, where later functions expect shapes earlier ones do not return. Problems that combine two separate ideas, such as a finite difference scheme with a custom boundary condition, also push models past their reliability point.
| Failure mode | Description | Example |
|---|---|---|
| Domain knowledge gap | Wrong constant, formula, or sign convention | Mixing CGS and SI units in an electrodynamics problem |
| Numerical instability | Choosing an unstable scheme for a stiff problem | Using forward Euler on a stiff chemical kinetics ODE |
| Cross step inconsistency | Mismatched input or output shapes between subproblems | Returning a list when a dense ndarray is expected |
| Unfinished implementation | Leaving a stub or placeholder | Returning zeros instead of computing the integral |
| Misreading the prompt | Solving a related but different problem | Computing a different transform than the one requested |
The public dataset spans a wide range of real research tasks. A few representative examples are listed below.[1][2]
| Subfield | Example task | Required ideas |
|---|---|---|
| Quantum chemistry | Solving for atomic bound states and charge density with a self consistent field loop | Schrodinger equation, Hartree potential, self consistent iteration |
| Condensed matter | Computing band structures via tight binding | Bloch theorem, Hamiltonian construction, diagonalization |
| Optics | Computing the reflection spectrum of a GaAs/AlAs distributed Bragg reflector | Quarter wave stacks, transfer matrix method |
| Ecology | Simulating predator prey dynamics with stochastic perturbations | Lotka Volterra equations, Monte Carlo methods |
| Computational physics | Finding the transition temperature of a 2D Ising model | Metropolis-Hastings sampling, Monte Carlo methods |
| Numerical linear algebra | Implementing iterative eigensolvers | Lanczos or Arnoldi iteration, Krylov subspaces |
How does SciCode compare to other coding benchmarks?
SciCode sits in a small but growing group of benchmarks for science focused code generation and reasoning, complementing more famous coding evaluations.
| Benchmark | Focus | How it differs from SciCode |
|---|---|---|
| HumanEval | Short Python function synthesis | No scientific domain knowledge required |
| MBPP | Basic Python programming problems | Aimed at entry level coders, not researchers |
| SWE-bench | Real GitHub issue fixing | Software engineering, not numerical science |
| MATH | Competition mathematics | No code execution, pure math reasoning |
| GPQA | Graduate level multiple choice science questions | No coding component |
| MLE-bench | Machine learning engineering | Kaggle style ML competitions |
| LAB-Bench | Biology lab tasks for AI agents | Wet lab and protocol focus |
| ResearchBench | Open ended research tasks | Less structured evaluation |
SciCode's combination of executable tests, scientist authored gold solutions, and broad scientific scope makes it one of the few standardized ways to track progress on AI assistants for research computing.[1][3]
Limitations
Several limitations follow from the benchmark's design. The benchmark is Python only, so it does not test Fortran, C++, or Julia. The dataset is fixed, which means scores can drift as public solutions seep into training corpora, though the held out test split helps. The 16 subfields are a sample of natural science computing, not a complete map; computational social science, neuroscience, and large scale climate simulation are out of scope. Evaluation also requires running scientific Python code with real dependencies, which adds engineering overhead.[1][2] An August 2026 domain expert audit of all 65 test problems reported 263 defects, 192 of which wrongly reject correct solutions through non-reproducible gold answers, over-tight tolerances or self-contradictory specifications, and released a corrected version called SciCode-Verified.[10]
| Limitation | Why it matters |
|---|---|
| Python only | Underestimates gaps in Fortran or C++ scientific code |
| Static dataset | Public solutions can leak into training corpora |
| Limited subfield coverage | Excludes whole sectors of computational science |
| Numerical tolerances | Strict tests; small numerical bugs cause failures |
| Cost and compute | Long generations under reasoning models can be expensive |
Reception and use
SciCode has become a standard reference in discussions of AI for science and the question of whether LLMs can do real research work. It was a constituent of the Artificial Analysis Intelligence Index through version 4.3.2 (removed in version 5.0, October 2026) and is tracked on the HAL leaderboard at Princeton and in Inspect AI evaluation suites, and frontier releases from Anthropic, OpenAI, Google DeepMind, and DeepSeek have included SciCode scores in technical reports or third party comparisons.[5][8][11]
Where state of the art models now solve the majority of HumanEval problems, SciCode's leaderboards still show main problem accuracy in the single digits or low tens years after release. That gap preserves a meaningful signal for future models to climb against, which is the job of a benchmark.[1][5]
Continue reading
- HumanEvalHumanEval is a benchmark for measuring whether a code-generating large language model can complete short Python functions so that they pass unit tests. It contains 164 hand-written tasks.Mentioned 4 times above
- SWE-benchSWE-bench is an execution-based benchmark for evaluating whether a language-model system can resolve real software issues.Mentioned twice above
- Reasoning modelsReasoning models are large language models that are post-trained or configured to spend additional inference-time computation on intermediate steps before returning an answer.Mentioned twice above
- LLM EvaluationLLM evaluation is the practice of measuring what a large language model can do, how reliably it does it, and how it behaves under adversarial or high-stakes conditions.Listed in See also
- GPQAGPQA (Graduate-Level Google-Proof Q&A) is a benchmark of expert-written, four-option multiple-choice questions in biology, physics, and chemistry.Listed in See also
- AI for ScienceAI for science is the use of artificial intelligence, particularly deep learning and large language models, to accelerate scientific discovery across biology, chemistry, physics, materials science…Listed in See also
More from See also
More to read
Topics:AI Benchmarks
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17Tian, M., Gao, L., Zhang, S. D., et al. "SciCode: A Research Coding Benchmark Curated by Scientists." arXiv:2407.13168, July 2024. arxiv.org/...2407.13168
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9SciCode official website. scicode-bench.github.io
- ^1 ^2NeurIPS 2024 Datasets and Benchmarks Track poster page for SciCode. neurips.cc/...97822
- ^1 ^2NeurIPS 2024 proceedings PDF, "SciCode: A Research Coding Benchmark Curated by Scientists." proceedings.neurips.cc/...and_Benchmarks_Track.pdf
- ^1 ^2 ^3 ^4 ^5 ^6HAL Princeton SciCode leaderboard. hal.cs.princeton.edu/scicode
- ^1 ^2 ^3 ^4 ^5 ^6SciCode GitHub repository. github.com/...SciCode
- OpenReview discussion thread for SciCode. openreview.net/forum
- ^1 ^2 ^3 ^4 ^5 ^6Artificial Analysis SciCode evaluations page. artificialanalysis.ai/...scicode
- ^1 ^2llm-stats SciCode benchmark leaderboard. llm-stats.com/...scicode
- ^1 ^2 ^3 ^4 ^5Hu, S., Huang, L., Deng, Y., Chen, K., et al. "SciCode-Verified: How Benchmark Defects Underestimated the Scientific-Coding Ability of Language Models." arXiv:2608.04975, August 2026. arxiv.org/...2608.04975
- ^1 ^2 ^3Artificial Analysis, Intelligence Benchmarking Methodology (SciCode, legacy evaluations). artificialanalysis.ai/...intelligence-benchmarking
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
9 revisions · v9 · 3,705 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (120 claims, 16 sources fetched); 13 material + 21 minor fixed
Cite this page: AI Wiki. "SciCode." aiwiki.ai, updated 28 Oct 2026, fact-checked 4 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/scicode