

Vector database
See also: AI terms
A vector database is a database that stores data as high-dimensional vectors (numerical embeddings produced by a machine learning model) and retrieves records by similarity rather than exact match, using approximate nearest neighbor search to find the items closest to a query vector. It is the storage layer that gives large language models long-term memory and powers semantic search, recommendation, and retrieval-augmented generation (RAG).
Explain Vector database Like I'm 5 (ELI5)
A vector database is a special kind of computer storage that helps find things that are similar, like finding pictures that look like a cat or finding songs that sound happy. It is really good at helping computers understand what things mean, even if those things are words, pictures, or sounds.
Vector databases also help big computer brains called "large language models" remember things, so they can give better answers when you ask them questions. They can find what you are looking for really fast, even when there are lots and lots of items inside.
Introduction
A vector database is a type of database specifically designed for storing and querying high-dimensional vector data, which is often used in artificial intelligence applications (AI apps). Complex data, including unstructured forms like documents, images, videos, and plain text, is growing rapidly. Traditional databases designed for structured data struggle to store and analyze complex data effectively, often requiring extensive keyword and metadata classification. Vector databases address this issue by transforming complex data into vector embeddings, which describe data objects in numerous dimensions. These databases are gaining popularity due to their ability to extend large language models (LLMs) with long-term memory and provide efficient querying for AI-driven applications.[34]
Vector databases manage embeddings generated by large language models, computer vision systems, and recommendation engines. The category sits at the center of the retrieval-augmented generation stack and has become a standard component in modern AI infrastructure alongside model-serving platforms, orchestration frameworks, and feature stores.[39][46]
The first generation of dedicated vector database vendors appeared between 2017 and 2022, including Faiss (Meta, 2017), Milvus (Zilliz, 2019), Weaviate (SeMI Technologies, 2019), Pinecone (2019), Qdrant (2021), and Chroma (2022). A second wave of relational database extensions arrived in parallel, led by pgvector for PostgreSQL (Andrew Kane, 2021), MongoDB Atlas Vector Search (general availability December 2023), Oracle Database 23ai vector type (2024), and SQL Server vector functions. By 2025, the divide between purpose-built vector engines and traditional databases with vector add-ons had narrowed considerably, and many production teams run a mix of both.[45]
What is a vector database?
In a relational database, data is organized in rows and columns, while in a document database, it is organized in documents and collections. In contrast, a vector database stores arrays of floating-point numbers (or quantized representations of them) along with associated metadata, indexed for similarity rather than exact match. These databases can be queried with ultra-low latency, making them suitable for AI-driven applications.
A vector database indexes and stores vector embeddings for efficient retrieval and similarity search. In addition to traditional CRUD (create, read, update, and delete) operations and metadata filtering, vector databases enable the organization and comparison of any vector to one another or to the vector of a search query. This capability allows vector databases to excel at similarity search or vector search, providing more comprehensive search results that would not be possible with traditional search technology.[34]
The fundamental query is the k-nearest-neighbor (kNN) lookup: given a query vector q and a target k, return the k vectors in the index whose distance to q is smallest under a chosen metric. For high-dimensional data, exact kNN requires comparing the query against every stored vector, which is impractical at scale. Vector databases therefore implement approximate nearest neighbor (ANN) search, which trades a small amount of recall for orders-of-magnitude gains in throughput and latency.[34]
The curse of dimensionality
A long-standing challenge in vector search is the curse of dimensionality. As dimensionality grows, the volume of the embedding space grows exponentially, points drawn from typical distributions become roughly equidistant from one another, and the contrast between nearest and farthest neighbors collapses. In purely random high-dimensional spaces, distance-based nearest neighbor methods can fail to discriminate at all. Real-world embeddings produced by neural networks escape the worst of this problem because the data lies on lower-dimensional manifolds inside the ambient space, but the phenomenon still motivates the design of every modern ANN algorithm. Techniques such as random projections, learned partitions, navigable small-world graphs, and quantization all aim to exploit the manifold structure of real embeddings rather than treat them as uniformly distributed points.
Vector databases vs. vector search libraries
Practitioners distinguish between vector libraries and vector databases. A library such as Faiss, Annoy, hnswlib, or ScaNN is an in-process toolkit that exposes APIs for index construction and search but leaves operational concerns (sharding, replication, persistence, multi-tenancy, security) to the application. A vector database wraps one or more such algorithms inside a managed runtime that handles those concerns, exposes a network API, and integrates with monitoring and access control. Faiss is the canonical library, while Pinecone, Weaviate, Milvus, Qdrant, and Chroma are canonical databases.[7]
Indexing algorithms
The performance of a vector database depends heavily on its indexing strategy. Three indexing families dominate the landscape: HNSW, IVF, and Product Quantization. Production systems often combine two or more of these to balance recall, latency, memory, and throughput.
| Algorithm | Family | Year | Origin | Typical Build Complexity | Typical Query Complexity | Memory Use |
|---|---|---|---|---|---|---|
| Flat (brute force) | Exact | classical | n/a | O(N) | O(N · d) per query | 1x raw vectors |
| LSH | Hashing | 1998 | Indyk and Motwani, STOC 1998 | O(N · L · d) | O(L · d) average | Multiple hash tables |
| IVF | Inverted file | 2010 | Jegou, Douze, Schmid (with PQ) | O(N · nlist · d) | O((nprobe / nlist) · N · d) | 1x raw + centroids |
| Product Quantization | Quantization | 2010 | Jegou, Douze, Schmid (TPAMI 2011) | O(N · d) after codebook training | O(M · K) lookup per query | Up to 64x compression |
| HNSW | Graph | 2016 | Malkov and Yashunin (arxiv 1603.09320) | O(N · log N) average | O(log N) average | 1.5 to 2x raw vectors |
| ScaNN | Tree + AQ | 2020 | Guo et al., ICML 2020 (arxiv 1908.10396) | O(N · d) with codebook | Sub-linear typical | Compressed |
| DiskANN (Vamana) | Graph on SSD | 2019 | Subramanya et al., NeurIPS 2019 | O(N · log N) | O(log N) with SSD reads | Compressed (PQ) vectors in RAM |
| SPANN | Inverted on disk | 2021 | Chen et al., NeurIPS 2021 (arxiv 2111.08566) | Hierarchical clustering + graph | Sub-linear with SSD reads | Centroids in RAM |
HNSW (Hierarchical Navigable Small World)
HNSW is a graph-based approximate nearest neighbor algorithm published by Yu. A. Malkov and D. A. Yashunin in March 2016 (arxiv 1603.09320, later in IEEE Transactions on Pattern Analysis and Machine Intelligence, 42(4):824-836, 2020).[1] It builds a multi-layered navigable graph over the vector space. Each layer contains a subset of the vectors, with the top layers holding fewer nodes and longer-range connections, and the bottom layers holding all nodes with short-range connections. During a search, the algorithm starts at the top layer and greedily traverses toward the query vector, descending through layers and refining the candidate set at each level. As the authors describe it, "Starting search from the upper layer together with utilizing the scale separation boosts the performance compared to NSW and allows a logarithmic complexity scaling."[1]
HNSW offers several strengths that make it the default choice for most vector database deployments:
- High recall. Without quantization, HNSW typically reaches recall of around 98% or higher, versus roughly 95% for unquantized IVF.[36]
- No training phase required. Unlike IVF, HNSW does not require a separate clustering step before the index can serve queries. Vectors can be inserted incrementally.
- Tunable accuracy. The
ef_searchparameter controls how many candidates the algorithm considers during a query. Increasingef_searchimproves recall at the cost of higher latency. - Tunable construction. The
Mparameter controls the number of connections per node, andef_constructioncontrols the quality of the graph at build time. Higher values produce a more accurate but larger index.
The main drawback of HNSW is memory consumption. Because the entire graph must reside in memory for fast traversal, HNSW typically requires 1.5 to 2 times the raw vector data size in RAM. For billion-scale datasets, this can become prohibitively expensive, which is why vendors increasingly pair HNSW with quantization to compress the in-memory representation.
HNSW is the primary index type in Qdrant, Weaviate, pgvector, Elasticsearch, OpenSearch, and Redis (RediSearch 2.4 and later), and is supported as an option in Milvus and Faiss.
IVF (Inverted File Index)
IVF is a partition-based indexing method derived from the inverted-file approach popularized in image retrieval research. It works by first running k-means clustering on the dataset to divide the vector space into a configurable number of clusters (called nlist). Each cluster is represented by a centroid, and every vector in the dataset is assigned to its nearest centroid. At query time, the algorithm computes the distance between the query vector and all centroids, selects the nprobe closest clusters, and then performs an exhaustive search only within those clusters.[36]
IVF is well suited for scenarios where HNSW is impractical:
- Billion-scale datasets. Because IVF can store the index on disk and only load relevant clusters into memory during a query, it can handle datasets far larger than available RAM.
- Filtered search. IVF handles metadata filtering efficiently through a two-level process: first performing coarse-grained filtering at the centroid level to narrow down candidates, then conducting fine-grained distance calculations within selected clusters.
- Batch search workloads. When throughput matters more than individual query latency, IVF can process many queries in parallel across clusters.
The main trade-off is that IVF requires a training phase (the k-means clustering step), which can be time-consuming for large datasets. Additionally, IVF generally achieves lower recall than HNSW at equivalent latency, because queries that fall near cluster boundaries may miss relevant vectors in neighboring clusters.[36] Practitioners typically tune nlist near the square root of the dataset size and adjust nprobe to trade recall against latency.
IVF is available in Faiss, Milvus, and Oracle Database 23ai, among other systems.
Product Quantization (PQ)
Product Quantization is a lossy compression technique introduced by Hervé Jégou, Matthijs Douze, and Cordelia Schmid in their 2011 IEEE TPAMI paper (DOI 10.1109/TPAMI.2010.57).[2] It reduces the memory footprint of vector indexes by up to 97%.[37] PQ works by dividing each high-dimensional vector into a set of smaller subvectors and then quantizing each subvector independently using a separate codebook trained with k-means.
As an example, a 128-dimensional float32 vector occupies 512 bytes. PQ might split it into 8 subvectors of 16 dimensions each, train a 256-centroid codebook for each subvector, and replace each subvector with a single byte. The result compresses the vector to 8 bytes, a reduction of roughly 98%. At query time, PQ uses precomputed lookup tables to estimate distances against quantized database vectors without decompressing them.[37] PQ is lossy and is rarely used alone; it is typically combined with IVF (as IVF-PQ) or HNSW to form a two-stage retrieval pipeline where the index identifies a candidate set and a re-ranking step refines results using full-precision vectors.
While int8 scalar quantization achieves 4x compression and binary quantization 32x, PQ commonly reaches 64x (512 bytes to 8 bytes in the example above) or more, making it especially valuable for cost-sensitive deployments at very large scale. Faiss, Milvus, Qdrant, and OpenSearch all offer product quantization.
Scalar quantization and binary quantization
In addition to product quantization, vector databases increasingly support scalar and binary forms of compression that trade more accuracy for further memory savings.
- Scalar quantization maps each float32 component of a vector to an integer with fewer bits, typically int8. This produces 4x compression with a small recall penalty;
int8_hnswbecame the default dense_vector index type in Elasticsearch 8.14 (2024), and since version 9.1 it is the default only for float vectors with fewer than 384 dimensions.[47] - Binary quantization maps each float component to a single bit by sign thresholding (positive becomes 1, non-positive becomes 0). On a 1536-dimensional embedding such as OpenAI's text-embedding-3-small output, the raw float32 representation is 6,144 bytes, and the binary representation is 192 bytes, a 32x compression. Distance computations on binary codes use Hamming distance, which is computed with a single XOR followed by a population count. Qdrant and other engines report up to 40x speedups on binary-quantized HNSW with high-dimensional embeddings, often combined with full-precision re-ranking on a smaller candidate set.[15]
- Better Binary Quantization (BBQ), introduced in Elasticsearch 8.16 and Lucene and derived from the RaBitQ technique, improves recall on binary-quantized vectors using per-vector error-correction values and asymmetric quantization (queries are quantized at higher precision than stored vectors); unlike RaBitQ, it does not randomly rotate vectors.[48]
Binary quantization works best on embeddings of dimension 1024 or higher; on lower-dimensional vectors, the loss of information is too large to preserve useful similarity rankings.[15]
ScaNN
ScaNN (Scalable Nearest Neighbors) was published by Ruiqi Guo and colleagues at Google Research in 2020 (ICML 2020, arxiv 1908.10396). It introduces an anisotropic vector quantization loss that penalizes the parallel component of a datapoint's residual relative to its orthogonal component, on the observation that database points with the largest inner products are more relevant for a given query.[4] ScaNN combines tree-based partitioning with this quantization to deliver leading results on benchmarks such as glove-100-angular.[4] It is available as an open-source library and underlies vector search in Google Cloud's Vertex AI Vector Search service.
DiskANN
DiskANN was published at NeurIPS 2019 by Suhas Jayaram Subramanya, Devvrit, Rohan Kadekodi, Ravishankar Krishaswamy, and Harsha Vardhan Simhadri, from Microsoft Research India, Carnegie Mellon University, and the University of Texas at Austin. It introduced a graph-based algorithm called Vamana with a smaller search radius than NSG and HNSW, designed specifically for SSD storage.[3] On the SIFT1B billion-point benchmark, DiskANN serves more than 5,000 queries per second with under 3 ms mean latency at 95% 1-recall@1 on a 16-core machine with 64 GB of RAM and an inexpensive SSD.[3] The Microsoft DiskANN code is open source on GitHub, and the algorithm is integrated into Milvus, pgvectorscale (the Timescale extension on top of pgvector), and other systems.
SPANN
SPANN was published in 2021 (NeurIPS 2021, arxiv 2111.08566) by researchers at Microsoft, Peking University, Tencent, and Baidu.[5] It implements a hybrid memory-disk inverted-file system: centroids of the posting lists are kept in RAM via a Microsoft SPTAG index, while the larger posting lists themselves live on disk. A hierarchical balanced clustering scheme keeps posting lists similar in length, and a query-aware pruning scheme avoids reading unnecessary lists at search time. SPANN can reach 90% recall@1 in around one millisecond on billion-scale datasets with only 32 GB of RAM, about twice as fast as DiskANN at the same memory budget on three billion-scale datasets.[5]
Locality-Sensitive Hashing (LSH)
LSH is the classical hashing-based ANN technique, introduced by Piotr Indyk and Rajeev Motwani in 1998 (STOC 1998).[6] LSH families are designed so that hash collisions are maximized for nearby points and minimized for distant points.[6] p-stable LSH targets Euclidean and Manhattan distances by projecting points onto random lines and bucketing the projections, random-hyperplane LSH (SimHash) targets cosine similarity, and MinHash targets Jaccard similarity. LSH is fast and memory-efficient but tends to deliver lower recall than graph-based methods at equivalent throughput, and it has largely been displaced by HNSW in modern vector databases. It remains useful for very high-dimensional sparse data, near-duplicate detection in web crawls, and theoretically grounded approximate search.
Other indexing approaches
Other algorithms appear in production: Flat (brute-force) gives perfect recall by exhaustive comparison and is useful below a few hundred thousand vectors; Annoy uses random-projection forests of binary trees and is popular for read-heavy workloads from Spotify; NSG (Cong Fu et al., 2017) is a graph algorithm focused on small index size; hnswlib is a reference C++ implementation of HNSW that several engines embed; and RaBitQ is a newer quantization scheme with theoretical recall guarantees that has begun to appear in research benchmarks.
Distance metrics
Vector databases rely on distance or similarity metrics to determine how close two vectors are in the embedding space. Choosing the correct metric is important because it should match the metric used during the training of the embedding model.[35] Using cosine similarity with a model trained for inner-product retrieval, for example, can degrade recall noticeably.
| Metric | Formula Summary | Best For | Notes |
|---|---|---|---|
| Cosine Similarity | cos(θ) = (a · b) / (‖a‖ ‖b‖); measures angle, ignores magnitude | Text similarity, document comparison, NLP tasks | Most common default; insensitive to vector length |
| Euclidean Distance (L2) | √(Σ (a_i - b_i)²); straight-line distance | Clustering, anomaly detection, spatial data | Sensitive to magnitude; penalizes large absolute differences |
| Dot Product (Inner Product) | a · b = Σ a_i b_i; sum of element-wise products | Recommendation systems, ranking tasks | Equivalent to cosine similarity when vectors are normalized |
| Manhattan Distance (L1) | Σ | a_i - b_i | ; sum of absolute differences |
| Hamming Distance | Number of positions where two binary vectors differ | Binary embeddings, hash-based search | Used with binary quantization for speed |
| Jaccard | A ∩ B | / | |
| Squared Euclidean | Σ (a_i - b_i)² | Same ranking as L2 with cheaper math | Skips the square root for speed |
When vectors are normalized to unit length, cosine similarity and dot product produce identical rankings.[35] Many embedding models, such as OpenAI's text-embedding-3 family and Sentence Transformers trained with cosine objectives, output normalized vectors, so either metric can be used interchangeably in those cases. For maximum-inner-product search, where vectors are not normalized and magnitude carries information, dot product is preferred and is the metric ScaNN's anisotropic quantization is designed for.[4]
Quick guide to picking a distance metric:
- text embeddings (most modern models): cosine or dot product (interchangeable when normalized)
- recommendation systems with biased magnitudes: dot product
- clustering or geometric data: Euclidean (L2)
- compressed binary representations: Hamming
- sparse hash-based fingerprints: Jaccard
Core database operations
Beyond similarity search, modern vector databases support a broader set of operations that distinguish them from pure ANN libraries.
CRUD and upserts
Vectors can be inserted, updated, deleted, and fetched by primary key. Most engines accept an upsert operation that inserts a vector if its ID is new and replaces the existing entry otherwise. Because graph indexes are sensitive to deletions, engines such as Qdrant, Weaviate, and Milvus implement tombstoning with periodic background compaction.
Metadata filtering
Each vector typically carries a payload of structured metadata such as document IDs, timestamps, tags, languages, prices, or access-control attributes. Filtering this metadata alongside vector similarity is essential for production retrieval. Approaches include:
- Pre-filtering evaluates the metadata predicate first and runs ANN only on the surviving subset. It produces correct top-k results but can be slow when the predicate is expensive or returns a small fraction of the corpus.
- Post-filtering runs ANN first to retrieve a larger candidate set and then applies the metadata filter. It is fast but may return fewer than k results when filters are highly selective.
- Single-stage filtering integrates the metadata predicate directly into the ANN traversal, pruning graph edges or inverted-list buckets that violate the filter. Pinecone implements this with bitmap indexes, Qdrant with payload-aware HNSW link selection, and Milvus with bitmap and bloom filters.
The choice between strategies depends on filter selectivity, ANN parameters, and dataset size, and most engines pick one automatically based on workload heuristics.
Hybrid search (sparse plus dense)
Hybrid search combines lexical retrieval (typically BM25 or SPLADE) with dense vector search. Dense embeddings capture semantic similarity but can miss exact-match cues such as product SKUs, person names, or rare technical terms. Lexical search excels at exact match but lacks semantic generalization. Combining the two consistently outperforms either alone.
The fusion step combines two ranked lists into one. The most popular method is Reciprocal Rank Fusion (RRF), which scores a document as the sum of 1 / (k + rank_i) across the two retrievers, with k typically set to 60.[31] RRF is insensitive to score-scale differences and requires no tuning.[30] Other approaches include weighted score normalization, learned-to-rank rerankers, and convex combinations. Hybrid retrieval has become the default in production RAG systems through 2025 and 2026; one VentureBeat survey reported hybrid retrieval intent tripling among enterprise teams in Q1 2026.[44]
RRF score for a document d:
RRF(d) = sum over retrievers i of 1 / (k + rank_i(d))
default k = 60
Weaviate, Milvus, Qdrant, Elasticsearch, OpenSearch, and pgvector (via PostgreSQL full-text search and extensions such as ParadeDB's pg_search) all support hybrid search natively.
Multi-vector and named vector support
A single record can carry multiple embeddings: one for the title, one for the body, one from a multilingual model, one from a multimodal model. Vector databases support this through named vectors (Qdrant), multi-vector fields (Weaviate, Pinecone), or separate collections joined by foreign keys (pgvector). Multi-vector queries typically combine per-vector similarities via maxSim, average, or weighted aggregation. ColBERT-style late-interaction models, which produce one vector per token, are increasingly supported as a special case.
Major vector database products
Several vector databases have emerged to cater to the growing demand for AI applications. The following table compares the most widely adopted systems as of early 2026.
| Feature | Pinecone | Weaviate | Milvus | Qdrant | Chroma | pgvector |
|---|---|---|---|---|---|---|
| Type | Fully managed (serverless) | Open-source + managed cloud | Open-source + managed (Zilliz) | Open-source + managed cloud | Open-source (embedded) | PostgreSQL extension |
| Founded | 2019 | 2019 (project from 2016) | 2019 (Zilliz 2017) | 2021 | 2022 | 2021 |
| Founders | Edo Liberty | Bob van Luijt, Etienne Dilocker, Micha Verhagen | Charles Xie | Andrey Vasnetsov, Andre Zayarni | Jeff Huber, Anton Troynikov | Andrew Kane |
| License | Proprietary | BSD-3-Clause | Apache 2.0 | Apache 2.0 | Apache 2.0 | PostgreSQL License |
| Written In | Proprietary (undisclosed) | Go | Go / C++ | Rust | Rust (rewritten 2025) | C |
| Index Types | Proprietary (auto-tuned) | HNSW | HNSW, IVF-Flat, IVF-PQ, DiskANN, GPU indexes | HNSW (with quantization) | HNSW | HNSW, IVFFlat |
| Max Dimensions | 20,000 | Configurable | 32,768 | 65,536 | Configurable | 16,000 (with halfvec up to 4,000 indexed) |
| Distance Metrics | Cosine, Euclidean, Dot Product | Cosine, L2, Dot, Hamming, Manhattan | Cosine, L2, IP, Jaccard, Hamming | Cosine, Euclidean, Dot Product, Manhattan | Cosine, L2, IP | Cosine, L2, Inner Product, L1; Hamming and Jaccard for bit vectors |
| Hybrid Search | Sparse vectors (2024+) | Native BM25 + vector (BlockMax WAND) | Sparse-BM25 (Milvus 2.5+) | Sparse vectors (v1.7+); native fusion via Query API (v1.10+) | Metadata + full-text | SQL + vector via standard PostgreSQL |
| Metadata Filtering | Single-stage with bitmap indexes | GraphQL-based filtering | Boolean expressions | Rich JSON payload filtering | Metadata filtering | Standard SQL WHERE clauses |
| Multi-Tenancy | Namespaces | Native tenant isolation | Partitions / collections | Payload-based or collection-based | Collections | Schema-based (standard PostgreSQL) |
| Cloud Regions | AWS, GCP, Azure | AWS, GCP, Azure | Zilliz: AWS, GCP, Azure | AWS, GCP, Azure | Chroma Cloud (winding down; closes December 22, 2026)[60] | Any PostgreSQL host |
| GitHub Stars (Nov 2026) | N/A (closed source) | ~17,000 | ~46,500 | ~35,000 | ~30,000 | ~23,500 |
| Best For | Zero-ops managed vector search | Hybrid/semantic search with GraphQL | Billion-scale deployments | Cost-efficient filtered search | Rapid prototyping | Adding vectors to existing PostgreSQL |
Pinecone
Pinecone was founded in 2019 by Edo Liberty, who previously led the creation of Amazon SageMaker at AWS and worked at Yahoo Research.[8] The company raised a USD 10 million seed in 2021,[8] a USD 28 million Series A in 2022, and a USD 100 million Series B in April 2023 led by Andreessen Horowitz at a USD 750 million valuation, bringing total disclosed funding to roughly USD 138 million.[9] Announcing the Series B, Liberty described Pinecone's mission as providing "the Long Term Memory for AI."[9] Pinecone uses proprietary, auto-tuned indexing and offers single-stage metadata filtering with bitmap indexes, namespace-based multi-tenancy, and scale-to-zero. In 2024 it replaced pod-based pricing with a serverless model, and in 2025 introduced sparse vector support for hybrid search. In September 2025, founder Edo Liberty moved to chief scientist and former Google director Ash Ashutosh became CEO;[10][42] The Information reported that Pinecone, last valued at USD 750 million, had spoken to investment bankers about a potential sale and had received takeover interest, with speculation about a valuation north of USD 2 billion.[43]
Weaviate
Weaviate is an open-source vector database written in Go. The Weaviate project was started in March 2016 by Bob van Luijt, who co-founded SeMI Technologies (short for Semantic Machine Insights) in 2019 with Etienne Dilocker and Micha Verhagen; the company later renamed itself Weaviate B.V.[11] SeMI raised a USD 16 million Series A in February 2022 led by Cortical Ventures and a USD 50 million Series B in April 2023 led by Index Ventures with Battery Ventures, NEA, Zetta Venture Partners, and ING Ventures participating.[12] Weaviate provides a GraphQL API, native BM25 plus vector hybrid search using BlockMax WAND, and built-in vectorization modules for OpenAI, Cohere, and Hugging Face. Weaviate Cloud offers managed hosting across AWS, GCP, and Azure.
Milvus
Milvus is an open-source, cloud-native vector database under the Apache 2.0 license, written primarily in Go and C++. It was created by Charles Xie, who founded Zilliz in 2017 and previously worked at Oracle as a founding engineer of the Oracle 12c project. Milvus was first released in 2019 and donated to the LF AI and Data Foundation in 2020. Zilliz raised USD 43 million in its initial Series B and an additional USD 60 million Series B extension in August 2022 led by Prosperity7 Ventures, with Pavilion Capital, Hillhouse Capital, 5Y Capital, and Yunqi Capital participating, bringing total funding to roughly USD 113 million.[16] Milvus has a distributed architecture that separates compute and storage and supports the widest range of index types, including HNSW, IVF-Flat, IVF-PQ, DiskANN, and GPU-accelerated indexes. Milvus 2.5 introduced native sparse-BM25 hybrid search. Zilliz Cloud provides managed versions with serverless and dedicated deployment options.
Qdrant
Qdrant is an open-source vector database written in Rust, founded in 2021 in Berlin by Andrey Vasnetsov (CTO) and Andre Zayarni (CEO).[14] The company raised an early USD 7.5 million seed round and a USD 28 million Series A in January 2024 led by Spark Capital with participation from Unusual Ventures and 42CAP.[13] Qdrant is known for its compact memory footprint and strong filtering performance.
Qdrant uses HNSW indexing with built-in scalar, product, and binary quantization options. Its payload-based filtering system supports rich JSON queries and can be combined with vector search in a single request. Qdrant v1.7 added sparse vectors and v1.10 added a Universal Query API with native sparse/dense fusion for hybrid search,[50][51] and 2025 releases added GPU-accelerated index construction. The Qdrant Cloud managed service offers a permanent free tier with 1 GB of vector storage.
Chroma
Chroma is an open-source, embedded vector database designed for rapid prototyping and small-to-medium applications. It was founded on April 1, 2022 by Jeff Huber (CEO) and Anton Troynikov (CTO) in San Francisco. The company raised a pre-seed round in May 2022 and an USD 18 million seed round, announced in April 2023, led by Quiet Capital with angels including Naval Ravikant.[17] The first GitHub commit landed in October 2022, and the initial release shipped on October 22, 2022.
Originally written in Python, Chroma underwent a major rewrite in Rust during 2025, delivering approximately 4x faster writes and queries. Chroma provides a simple, NumPy-like API with built-in metadata filtering and full-text search. It is commonly used in local development environments and as an embedded store in LangChain and LlamaIndex workflows. Chroma Cloud launched in 2025 with a credit-based pricing model. On October 23, 2026, Chroma announced a definitive agreement to join Replit and began winding down Chroma Cloud (writes disabled December 7, 2026, reads disabled December 22, 2026); open-source Chroma remains available under the Apache 2.0 license.[59][60]
pgvector
pgvector is an open-source PostgreSQL extension authored by Andrew Kane and first released as version 0.1.0 on April 20, 2021.[18] It adds vector similarity search capabilities to any PostgreSQL database. pgvector supports HNSW (added in version 0.5.0, August 2023) and IVFFlat indexes, with distance metrics including cosine, L2, and inner product.[19] The companion pgvectorscale extension (developed by Timescale, now Tiger Data) adds DiskANN-based indexing and Statistical Binary Quantization, enabling competitive performance on datasets of up to 50 million vectors.
pgvector supports standard vectors, half-precision vectors (halfvec, up to 4,000 indexed dimensions), sparse vectors (sparsevec), and binary vectors (bit type, up to 64,000 indexed dimensions).[18] Because pgvector runs inside PostgreSQL, developers can store vectors alongside relational data and query both with standard SQL, eliminating the need for a separate vector database in many use cases. pgvector is available in managed PostgreSQL offerings from AWS RDS, Google Cloud SQL, Azure Database for PostgreSQL, Supabase, Neon, and Tiger Data.
Faiss
Faiss (Facebook AI Similarity Search) is an open-source library released by Meta AI Research on March 29, 2017.[20] Hervé Jégou initiated the project and wrote the first implementation, with Matthijs Douze implementing most of the CPU code and Jeff Johnson contributing the GPU implementation. Announcing the release, Meta wrote: "We've built nearest-neighbor search implementations for billion-scale data sets that are some 8.5x faster than the previous reported state-of-the-art."[20] Faiss is a library rather than a standalone database; it provides reference implementations of IVF, PQ, IVF-PQ, OPQ, HNSW, and many composite indexes.[7] It is the algorithmic foundation for several systems, including Milvus.
Vespa
Vespa is an open-source big-data serving engine developed at Yahoo and open-sourced in September 2017 under the Apache 2.0 license.[21] Yahoo had built Vespa from technology acquired with Overture and the AlltheWeb search engine in the mid-2000s. Jon Bratseth, the distinguished architect who led Vespa's development, became CEO when Yahoo spun Vespa out as an independent company in October 2023, and Vespa.ai raised a USD 31 million Series A from Blossom Capital in November 2023.[22] Vespa supports HNSW, learned ranking models, lexical search, and tensor evaluation in the same engine, and is used by Spotify, OkCupid, and Wix, among others.
LanceDB
LanceDB is an open-source, serverless vector database founded in 2022 by Chang She and Lei Xu. Chang She is one of the original co-authors of the pandas library, and Lei Xu was a core HDFS contributor and led ML infrastructure at Cruise. LanceDB is built on the Lance columnar file format, an alternative to Parquet optimized for ML workloads. By May 2024 the company had raised USD 11 million, including a seed round led by CRV, Essence VC, and Swift Ventures, and its customers included Midjourney, Character.ai, WeRide, and Airtable.[23] LanceDB targets multimodal workloads where image, text, and metadata vectors live alongside source media, with object storage as the primary persistence tier.
Turbopuffer
Turbopuffer is a serverless vector and full-text search engine founded in 2023 by Simon Hørup Eskildsen and Justine Li, both former Shopify engineers. Turbopuffer stores its primary copy of data in object storage such as Amazon S3 and layers SSD and memory caches on top, achieving roughly 10x lower storage cost than RAM-resident vector databases.[24] The company is backed by Lachy Groom, Thrive Capital, and others. As of 2025 and 2026, Turbopuffer reported powering search at Cursor, Notion, Linear, and other large AI-native applications, handling more than 1 trillion documents, more than 10 million writes per second, and more than 100,000 queries per second in production.[24]
MongoDB Atlas Vector Search
MongoDB Atlas Vector Search reached general availability on December 4, 2023, after a public preview launched in June 2023.[25] It allows MongoDB users to add vector indexes to existing collections and run $vectorSearch aggregation pipelines that combine vector similarity with MongoDB's existing query operators and aggregation framework. At general availability, MongoDB said Atlas Vector Search had the highest developer net promoter score and was the second most widely used vector database in Retool's State of AI report, helped by existing MongoDB users being able to adopt vector search without standing up a new database.[25]
Elasticsearch and OpenSearch
Elasticsearch added a dense_vector field type in 7.x and introduced HNSW-based ANN search in version 8.0 (February 2022).[26] Version 8.14 (2024) made int8_hnsw the default dense_vector index type, and since version 9.1 (2025) the default for float vectors with 384 or more dimensions is bbq_hnsw, which uses BBQ (Better Binary Quantization).[47][48] OpenSearch, the fork of Elasticsearch created by AWS and governed since 2024 by the Linux Foundation's OpenSearch Software Foundation, ships an analogous knn_vector type with HNSW via the NMSLIB, Faiss, and Lucene back ends, plus first-class support for Reciprocal Rank Fusion.[30] Both engines are popular for teams that already operate an inverted-index search cluster and want to add vectors without introducing a new system.
Redis
Redis added vector similarity search in RediSearch 2.4, announced at RedisDays NY 2022.[27] The module supports both flat (brute force) and HNSW indexes, with cosine, inner product, and Euclidean distances.[27] Redis vector search is commonly used as a low-latency cache for embeddings or as an in-memory primary store for small-to-medium corpora, with Redis Enterprise Cloud and Azure Cache for Redis Enterprise offering managed deployments.
Other notable systems
| System | Type | Notes |
|---|---|---|
| Annoy | Library | Random-projection forest, by Erik Bernhardsson at Spotify; widely used for read-heavy use cases |
| ScaNN | Library | Google's open-source ANN library; underlies Vertex AI Vector Search |
| Snowflake | Data warehouse | VECTOR data type and VECTOR_COSINE_SIMILARITY function (2024) |
| Databricks Vector Search | Lakehouse | Unity Catalog-aware vector index over Delta tables |
| Oracle Database 23ai | Relational DB | Native VECTOR data type and AI Vector Search (2024) |
| SQL Server | Relational DB | VECTOR_DISTANCE function and ANN indexes (2025) |
| Amazon S3 Vectors | Object store | S3-native vector index and query API (2025) |
Pricing comparison
Vector database pricing varies significantly depending on whether the service is fully managed, self-hosted, or serverless. The following table summarizes list prices from vendor pricing pages as of November 2026; vendors change plans often.[53][54][55][56][57][58]
| Database | Free Tier | Paid Starting Price | Pricing Model |
|---|---|---|---|
| Pinecone | Starter plan (limited) | Builder $20/month flat; Standard $50/month minimum, then $0.33/GB/month storage, $16-$18 per 1M read units, $4-$4.50 per 1M write units | Serverless consumption-based |
| Weaviate | Free tier (no credit card) | Flex from $45/month; Premium from $400/month | Vector dimensions plus storage |
| Milvus / Zilliz | Zilliz free plan (5 GB storage) | Standard serverless pay-as-you-go; Enterprise dedicated from $197/month | Usage-based (serverless) or dedicated clusters |
| Qdrant | Free tier (1 GB RAM, 4 GB disk) | Standard tier, usage-based dedicated clusters | Compute and storage based |
| Chroma | Open-source (free); Chroma Cloud Starter ($0 plus usage, free credits) until the December 2026 wind-down[60] | Team $250/month plus usage | Usage-based |
| pgvector | Free (open-source extension) | Infrastructure cost only | Runs on your PostgreSQL instance |
| Turbopuffer | None (commercial only) | Launch plan $16/month minimum usage | Storage, write, and query consumption |
| MongoDB Atlas Vector Search | Atlas free tier | Atlas cluster pricing | Cluster pricing plus optional dedicated search nodes |
| Elasticsearch / OpenSearch | Self-hosted free | Managed cluster pricing | Cluster size plus storage |
Usage-based cloud pricing can become volatile at scale. This prompts some organizations to evaluate reserved capacity or self-hosted alternatives. Object-storage-backed engines such as Turbopuffer and Amazon S3 Vectors target this exact pain point by trading a small amount of latency for a much lower price per stored vector.
Performance benchmarks
Vector database benchmarks measure queries per second (QPS), recall (the fraction of true nearest neighbors found), and latency (typically p50, p95, or p99).[32] Results depend heavily on dataset size, vector dimensionality, hardware, and precision thresholds, so benchmarks should be compared only when similar configurations are used.[33]
Benchmarking suites
| Benchmark | Maintainer | Scope | Notes |
|---|---|---|---|
| ANN-Benchmarks | Erik Bernhardsson, Martin Aumüller | Library-level | Plots recall vs QPS on standard datasets like SIFT-1M, GIST-1M, glove-100; widely cited |
| Big-ANN-Benchmarks | NeurIPS billion-scale challenge | Billion-scale | Tracks T1 (in-memory), T2 (out-of-memory), T3 (custom hardware) |
| VectorDBBench | Zilliz, open source | Database-level | End-to-end benchmark across managed and self-hosted vector DBs |
| BEIR | Information retrieval benchmark | Retrieval quality | Measures end-to-end retrieval, including embeddings |
| MTEB | Massive Text Embedding Benchmark | Embedding quality | Measures embedding model performance on retrieval, classification, clustering |
Representative benchmark results
| Database | Dataset | Vectors | Dimensions | QPS | Recall | Latency (p95) | Source |
|---|---|---|---|---|---|---|---|
| Qdrant | dbpedia-openai-1M | 1M | 1,536 | 1,238 (100 parallel clients) | 99% | ~5 ms | Qdrant Benchmarks, June 2024[38] |
| pgvectorscale | Cohere 50M | 50M | 768 | 471 | 99% | 60.42 ms | Tiger Data (Timescale) benchmark[49] |
| Qdrant | Cohere 50M | 50M | 768 | 41 | 99% | 36.73 ms | Tiger Data (Timescale) benchmark[49] |
| DiskANN | SIFT1B | 1B | 128 | >5,000 | 95%+ (1-recall@1) | <3 ms (mean) | NeurIPS 2019 paper |
| SPANN | SIFT1B | 1B | 128 | High | 90% (recall@1, recall@10) | ~1 ms | NeurIPS 2021 paper |
Key observations from recent benchmarks:
- Qdrant's own benchmarks report that it achieves the highest requests per second and lowest latencies in almost all tested scenarios on datasets of 1 million to 10 million vectors.[38]
- pgvectorscale has demonstrated surprisingly competitive throughput (471 QPS at 99% recall on 50 million vectors, versus 41 QPS for Qdrant) in a benchmark run by its developer, Tiger Data, although Qdrant had lower p95 and p99 latency.[49]
- DiskANN and SPANN continue to set the bar for billion-scale workloads on a single node, and both are now integrated into commercial systems.[3][5]
Embedding models commonly paired with vector databases
A vector database is only as useful as the embeddings it stores. Most production systems pair a vector database with a managed or open-source embedding model. The most widely used models as of 2026 include:
| Model | Provider | Dimensions | Context | Notes |
|---|---|---|---|---|
| text-embedding-3-large | OpenAI | up to 3,072 (Matryoshka) | 8K tokens | Default OpenAI text embedding; supports dimension truncation |
| text-embedding-3-small | OpenAI | up to 1,536 (Matryoshka) | 8K tokens | Cheaper sibling of text-embedding-3-large |
| voyage-3-large | Voyage AI | 1,024 default; 256 to 2,048 (Matryoshka, with int8/binary variants) | 32K tokens | Outperforms text-embedding-3-large by ~10% on Voyage's 100-dataset benchmark |
| embed-english-v3.0 | Cohere | 1,024 | 512 tokens | Strong for English RAG; binary and int8 variants available |
| embed-multilingual-v3.0 | Cohere | 1,024 | 512 tokens | 100+ languages |
| all-MiniLM-L6-v2 | Sentence Transformers | 384 | 256 tokens | Open weights; common baseline |
| BGE-M3 | BAAI | 1,024 | 8K tokens | Open weights; strong multilingual performance |
| nomic-embed-text-v1.5 | Nomic | 768 (Matryoshka) | 8K tokens | Open weights; popular for self-hosted RAG |
| Gemini text-embedding | up to 3,072 | 2K tokens | Tightly integrated with Vertex AI Vector Search |
Matryoshka representation learning, used by OpenAI, Voyage AI, and Nomic, encodes the most semantically important information into the first dimensions of each vector.[28] OpenAI reports that a text-embedding-3-large embedding shortened from 3,072 to 256 dimensions still outperforms the full 1,536-dimension text-embedding-ada-002 on MTEB, turning dimension count into a runtime knob that lets teams trade storage cost for retrieval quality.[28]
Vector databases in retrieval-augmented generation (RAG)
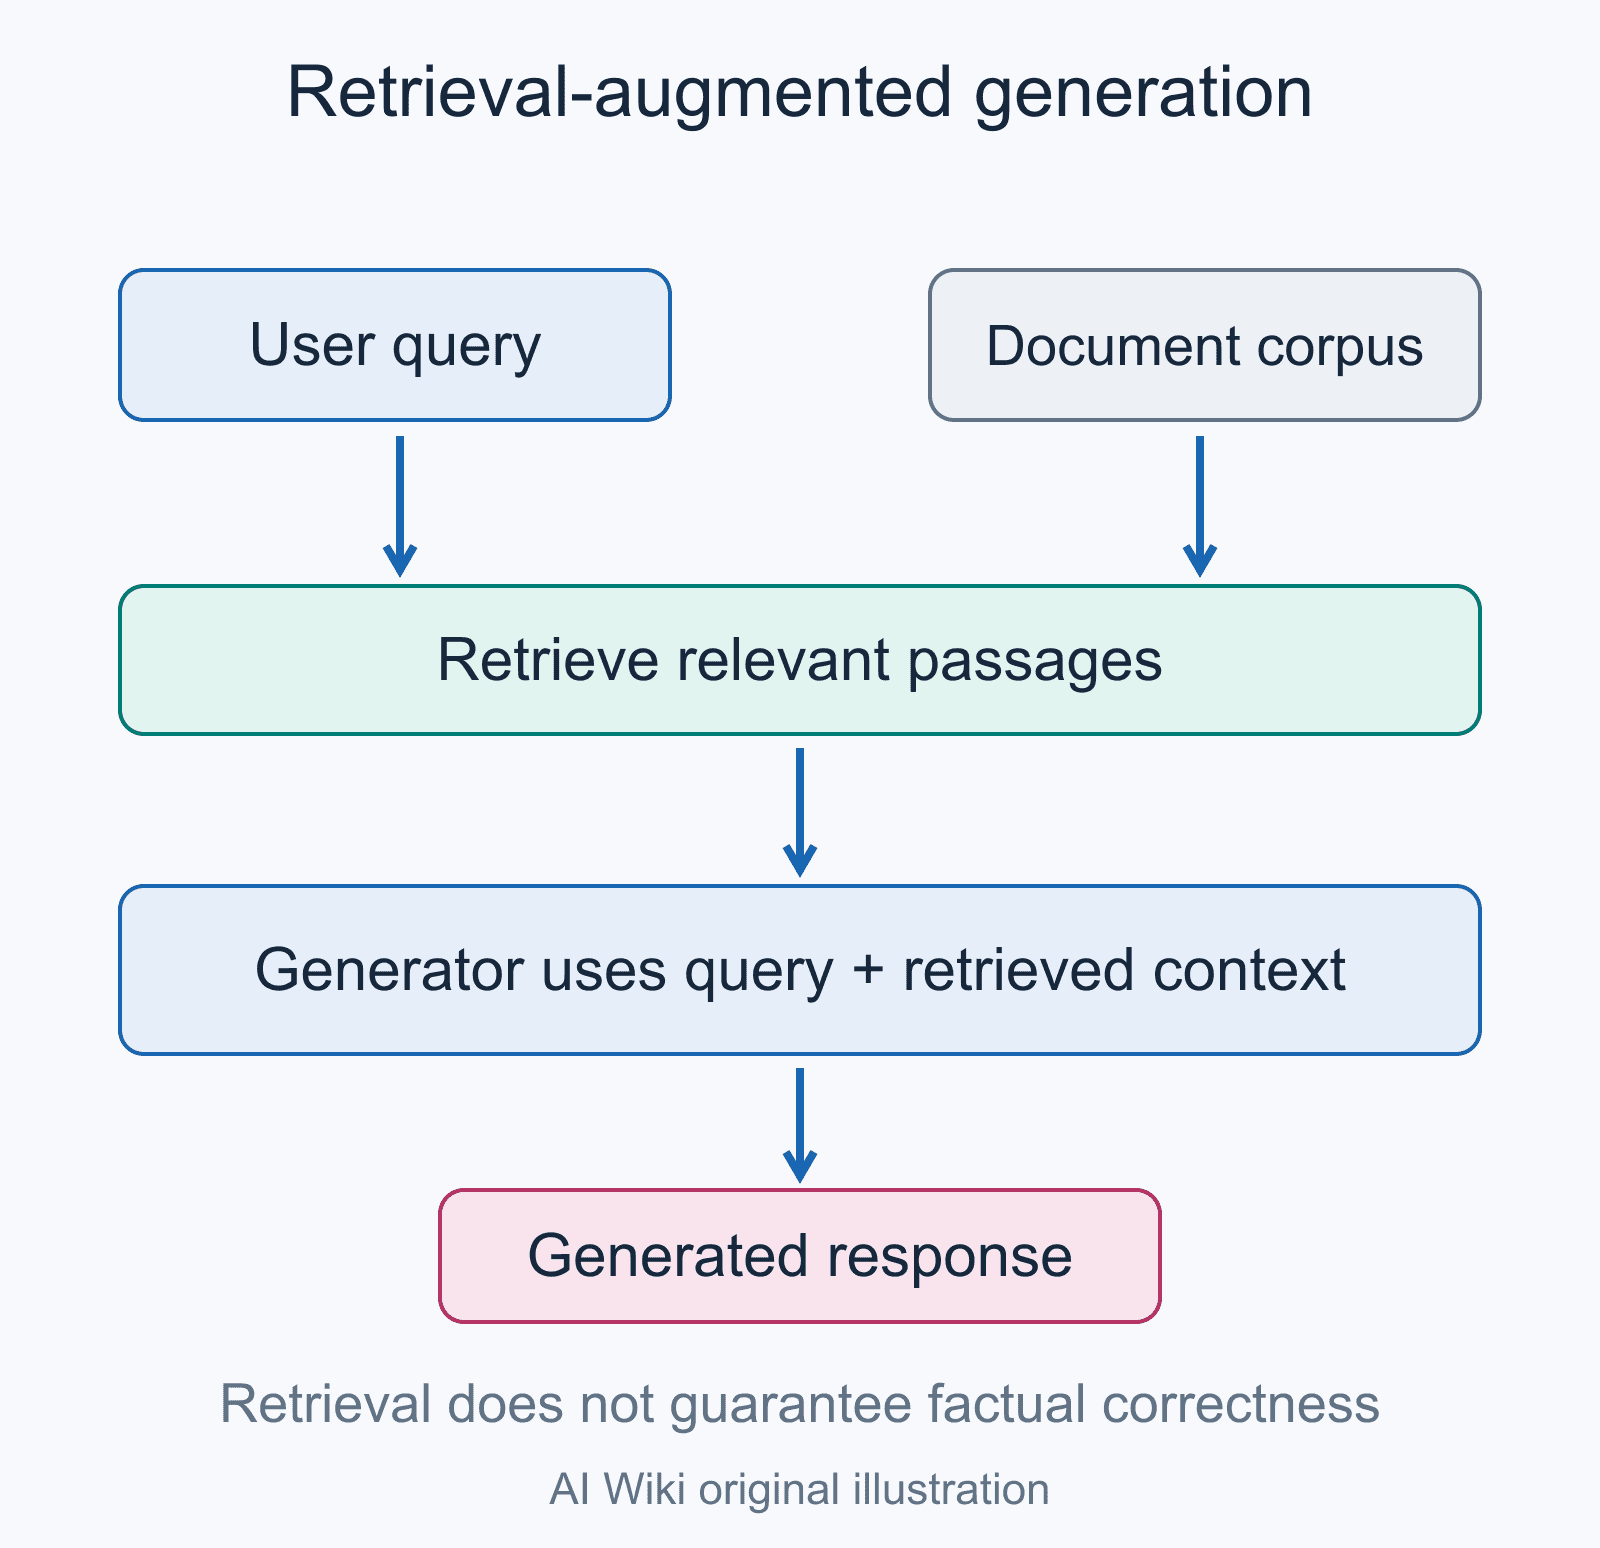
One of the most significant applications of vector databases is retrieval-augmented generation (RAG), an architecture that combines external knowledge retrieval with large language models to produce more accurate and grounded responses.
How RAG works with vector databases
A RAG pipeline operates through four stages:
- Ingestion. Documents, web pages, or other knowledge sources are split into chunks and passed through an embedding model (such as OpenAI's text-embedding-3-large or Cohere's embed-v3) to produce vector representations.[28] These vectors are stored in a vector database along with the original text as metadata.
- Retrieval. When a user submits a query, the query is embedded using the same model. The vector database performs a similarity search to find the most relevant document chunks, typically returning the top-k results. Filters and hybrid scoring may be applied at this stage.
- Augmentation. The retrieved chunks are inserted into the LLM's prompt as context, along with the user's original question. Many systems also pass system instructions, formatting rules, and citation templates.
- Generation. The LLM generates a response grounded in the retrieved context, reducing hallucination and improving factual accuracy. A re-ranking model (such as Cohere Rerank or a cross-encoder) is often inserted between retrieval and augmentation to improve relevance.
Why vector databases are essential for RAG
RAG applications demand sub-100 ms retrieval latency to avoid adding perceptible delay to the LLM's response time. Vector databases are built for exactly this workload, with in-memory indexes, SIMD-accelerated distance calculations, and distributed architectures that scale horizontally. Traditional databases and search engines can perform keyword matching, but they cannot capture the semantic meaning of queries the way vector similarity search does.
Advanced RAG techniques (2025-2026)
Several advanced techniques have emerged to improve RAG quality:
- Hybrid search. Combining BM25 keyword search with vector similarity search consistently outperforms either method alone.[44] Reciprocal Rank Fusion is the default fusion method, and most major vector databases now support it natively.[31]
- Query rewriting. Multi-query expansion (asking the LLM to generate paraphrases of the user query) and HyDE (Hypothetical Document Embeddings, where the LLM hallucinates a likely answer that is then embedded and used as the query) both materially improve recall.
- Re-ranking. A cross-encoder re-ranker scores the top 50 to 200 retrieved chunks against the query and re-orders them before generation. Cohere Rerank and BGE Reranker are widely used examples.
- Self-RAG. This technique trains models to decide when retrieval is necessary and to critique their own outputs, improving factuality and citation accuracy.
- Multimodal RAG. New embedding families (such as voyage-multimodal-3 and CLIP-style models) unify text and images into a shared vector space, enabling retrieval across modalities. This is useful for technical manuals with diagrams or scanned forms.
- Graph-enhanced retrieval. Combining vector search with knowledge graphs to capture relationships between entities, not just semantic similarity. This approach is gaining traction in 2026 as a way to improve retrieval for complex, multi-hop questions.
- Agentic memory. In AI agent systems, vector databases serve as long-term memory stores, allowing agents to recall previous interactions and context across sessions.
- ColBERT and late interaction. Token-level embedding models such as ColBERTv2 store one vector per token and aggregate similarity at query time using maxSim. Several vector databases (Vespa, Qdrant, LanceDB) support this pattern through multi-vector or multi-tensor fields.
Use cases
Vector databases support a broad set of applications across industries.
Semantic search
Unlike lexical search, which relies on exact word or string matches, semantic search uses the meaning and context of a search query or question. Vector databases use Natural Language Processing models to store and index vector embeddings, allowing for more accurate and relevant search results. E-commerce, support knowledge bases, intranet search, and code search all rely on semantic retrieval at scale.
Similarity search for unstructured data
Vector databases facilitate the search and retrieval of unstructured data like images, audio, video, and JSON, which can be challenging to classify and store in traditional databases. Image-similarity search powers reverse-image lookup, content moderation, fashion recommendation, and visual product search.
Recommendation systems
By finding similar items or users based on nearest matches in a learned embedding space, vector databases power recommendation engines for online retailers and streaming media services. Two-tower models, where users and items each have their own embedding tower, are typically deployed by computing user vectors at request time and looking up nearest items in a vector index.
Deduplication and record matching
Vector similarity search can be used to find near-duplicate records for applications such as removing duplicate items from a catalog, deduplicating user-generated content, and matching customer records across systems (entity resolution).
Anomaly detection
Vector databases can identify anomalies in applications used for threat assessment, fraud detection, and IT operations by finding objects that are distant or dissimilar from expected results. Time-series embeddings, log embeddings, and network flow embeddings are all routinely indexed to detect outliers.
Code search and developer tools
GitHub Copilot, Cursor, Sourcegraph Cody, and other AI coding tools embed code and documentation into vector indexes to support semantic code search, repository-aware completion, and chat over codebases. Cursor and Notion are both reported users of Turbopuffer.[24]
Using vector databases with large language models
One of the primary reasons for the increasing popularity of vector databases is their ability to extend large language models (LLMs) with long-term memory. By providing a general-purpose model, such as OpenAI's GPT-4, Anthropic's Claude, Meta's LLaMA, or Google's Gemini, users can store their own data in a vector database. When prompted, the database can query relevant documents to update the context, customizing the final response and providing the AI with long-term memory.
In addition, vector databases integrate with orchestration frameworks like LangChain, LlamaIndex, Haystack, and Semantic Kernel, which combine multiple LLMs, retrievers, and tools into multi-step pipelines. These frameworks abstract over individual vector databases and let teams swap engines without changing the application code.
Features of a vector database
Vector indexes for search and retrieval
Vector databases employ algorithms to index and retrieve vectors efficiently. Accuracy, latency, or memory usage may need to be prioritized depending on specific use cases. Common similarity and distance metrics used in vector indexes are Euclidean distance, cosine similarity, and dot products.
Approximate Nearest Neighbor (ANN) search is a popular technique to balance precision and performance. ANN algorithms, such as HNSW, IVF, or PQ, focus on improving specific performance properties like memory reduction or fast and accurate search times. Composite indexes combine several components and are often used to achieve optimal performance for a given use case.
Single-stage filtering
Single-stage filtering is essential for effective vector databases, as it enables users to limit search results based on vector metadata. It combines the accuracy of pre-filtering with the speed of post-filtering, merging vector and metadata indexes into a single index for optimal performance.
API and observability
REST and gRPC APIs allow vector databases to be accessed from any environment capable of making network calls, with native clients in Python, Java, Go, JavaScript, and Rust. Production deployments expose Prometheus or OpenTelemetry metrics, structured logs, and audit trails. Multi-tenancy support typically includes per-collection access control, namespace-level encryption, and customer-managed keys (BYOK) on managed services. SOC 2, ISO 27001, HIPAA, and GDPR-aligned operations are common requirements for enterprise deployments.
Comparison with traditional databases
| Aspect | Relational DB | Document DB | Search Engine | Vector Database |
|---|---|---|---|---|
| Primary data unit | Row | Document | Document with inverted index | Vector with payload |
| Primary query | SELECT with WHERE | find with predicate | match query (BM25) | k-nearest-neighbor |
| Index type | B-tree, hash | B-tree, geo | Inverted index | HNSW, IVF, PQ, DiskANN |
| Distance / scoring | Equality, ranges | Predicate match | TF-IDF, BM25 | Cosine, L2, dot product |
| Schema | Strict | Flexible | Mapped fields | Vectors plus payload |
| Scale | Vertical first, sharded | Horizontal | Horizontal | Horizontal |
| Strength | Transactions, joins | Flexible documents | Full-text search | Semantic similarity |
In practice, no production AI system relies on only one of these. The polystore pattern (relational data in PostgreSQL, vectors in pgvector or a dedicated engine, full-text in OpenSearch or in the same engine) has become standard. PostgreSQL with pgvector blurs the line further by hosting transactional, lexical, and vector workloads in a single database.
Operating considerations
Capacity planning
The dominant capacity drivers for a vector database are vector count, dimensionality, index type, replication factor, and quantization. As a worked example, 100 million 1,536-dimensional float32 vectors occupy roughly 614 GB of raw data; with HNSW (about 1.7x overhead), the index needs around 1 TB of RAM. With int8 scalar quantization that drops to roughly 150 GB, and binary quantization with full-precision re-ranking can fit in around 19 GB.
Update workloads
Vector indexes vary in how cleanly they handle updates. HNSW supports incremental insertions naturally but degrades with frequent deletions; engines compensate with periodic rebuilds. IVF requires retraining when the data distribution shifts substantially, although small inserts can use the existing centroids. DiskANN's Vamana graph supports incremental updates through the FreshDiskANN extension, and SPFresh plays a similar role for SPANN. Engines often expose a flush or build operation that the application can trigger after bulk inserts.
Cost optimization patterns
- Quantize aggressively. Switching from float32 to int8 or binary on high-dimensional embeddings cuts storage by 4 to 32x with limited recall impact.
- Right-size dimensions. Matryoshka embeddings let teams truncate to 512 or 768 dimensions instead of using the full 1,024 to 3,072.
- Use object storage for cold tiers. Turbopuffer and Amazon S3 Vectors store cold vectors at object-storage prices.
- Cap replication. Replication factor 2 or 3 is sufficient for most read-heavy workloads.
- Cache query embeddings. Repeated queries (especially in chat applications) benefit from caching the embedding result.
- Reserve capacity for steady traffic. Reserved or committed-use pricing can reduce serverless costs on predictable workloads.
Common pitfalls
- Mismatched distance metrics. Using cosine similarity with a model trained for dot product (or vice versa) silently degrades recall.
- Inadequate chunking strategy. Chunks that are too long dilute relevance; chunks that are too short lose context. Recursive character splitting with overlap is a typical default.
- Ignoring filter selectivity. Highly selective filters interact badly with naive ANN; engines that support single-stage filtering avoid this.
- Not measuring recall. Throughput numbers without recall measurements are meaningless; benchmark with a held-out kNN ground truth.
2025-2026 developments and trends
The vector database landscape has undergone significant changes in 2025 and early 2026, driven by the rapid adoption of generative AI and AI agents.[39]
Convergence with traditional databases
One of the most important trends is the convergence of vector search into traditional relational and document databases. PostgreSQL (via pgvector and pgvectorscale), MongoDB (via Atlas Vector Search), Oracle 23ai, Snowflake, Databricks, and Microsoft SQL Server have all integrated native vector support. PostgreSQL was the most-used database among developers in Stack Overflow's 2025 survey at 46.5% adoption, and in 2025 alone Snowflake (Crunchy Data, USD 250 million) and Databricks (Neon, USD 1 billion) spent approximately USD 1.25 billion acquiring PostgreSQL-focused companies.[39][41]
Polystore architecture
Production teams have converged on a polystore architecture where the relational database handles ACID transactions and structured queries while the vector database handles embedding search and semantic retrieval. By 2026, this pattern has become the default for teams shipping AI-augmented products.
AI agent workloads
The rise of AI agents has created new demands on vector database infrastructure. According to vector-database vendor Actian, AI agents generate roughly 10x more queries than human-driven applications, forcing a rethink of database throughput architecture.[39] Vector databases now serve as long-term memory systems for agents, storing conversation history, tool-use logs, and retrieved context across sessions. Patterns such as semantic caching (returning a cached LLM response when an incoming query matches a recent question above a similarity threshold) reduce both cost and latency for agent workloads.
Object-storage-native architectures
A new generation of engines builds primarily on object storage rather than block-attached SSDs. Turbopuffer, launched in 2023, demonstrated that an object-storage-first architecture could serve sub-10 ms p50 queries while costing roughly 10x less than RAM-resident managed services.[24] Amazon S3 Vectors, announced in 2025, takes the same approach inside the S3 service itself. This pattern is well suited to the long-tail, multi-tenant workloads typical of AI-native SaaS products.
Graph-enhanced vector retrieval
One of the most notable developments in 2026 is the emergence of graph-enhanced vector retrieval, which combines vector similarity search with knowledge graph traversal. This approach captures both semantic similarity (via vectors) and structural relationships (via graph edges), producing higher-quality retrieval for complex multi-hop queries.[41] Multiple vector database vendors have begun integrating graph capabilities or partnering with graph database providers, and Microsoft's open-source GraphRAG project popularized the pattern in 2024.
Edge deployment
Comprehensive edge-native vector database solutions remain scarce despite a USD 168 billion edge computing market and 39 billion projected connected IoT devices by 2030.[39] Lightweight engines such as LanceDB, Chroma in embedded mode, and DuckDB-VSS target this segment for healthcare, autonomous systems, manufacturing, and retail.
Performance and cost optimization
Chroma's 2025 Rust rewrite delivered approximately 4x performance improvements. Qdrant and Milvus have added more aggressive quantization options (binary quantization, scalar quantization) to reduce memory costs. pgvectorscale's DiskANN-based indexing has brought competitive performance to PostgreSQL at a fraction of the cost of managed vector databases. Across the board, vendors are investing in techniques to reduce the cost per query as AI workloads scale.
Consolidation pressure on pure-play vendors
By late 2025, pure-play vendors faced consolidation pressure. In August 2025 The Information reported that Pinecone had engaged bankers about a potential sale, with speculation about a valuation north of USD 2 billion.[43] The report named Oracle, IBM, MongoDB, and Snowflake as possible suitors.[52] The September 2025 appointment of Ash Ashutosh as Pinecone's CEO and the founder's transition to chief scientist were widely read as positioning the company for either a strategic exit or a deeper enterprise push.[42]
Frequently asked questions
What is a vector database used for?
Vector databases are used wherever applications need to retrieve items by meaning rather than exact keywords: semantic search, recommendation systems, image and audio similarity search, deduplication and entity resolution, anomaly and fraud detection, code search in developer tools, and, most prominently, as the retrieval layer in retrieval-augmented generation and as long-term memory for AI agents.[34][41]
How is a vector database different from a traditional database?
A relational or document database answers exact-match and range queries over rows or documents using B-tree or inverted indexes, while a vector database answers nearest-neighbor queries over high-dimensional embeddings using approximate nearest neighbor indexes such as HNSW, IVF, or DiskANN. The traditional database is optimized for transactions, joins, and full-text search; the vector database is optimized for semantic similarity. In practice the two are combined in a polystore architecture, and PostgreSQL with pgvector can serve both roles in one engine.[34]
Is a vector database the same as a vector search library?
No. A vector search library such as Faiss or hnswlib is an in-process toolkit that builds and queries an index but leaves persistence, sharding, replication, multi-tenancy, and access control to the application. A vector database wraps those algorithms in a managed runtime with a network API, durability, and security. Faiss is the canonical library; Pinecone, Weaviate, Milvus, and Qdrant are canonical databases.[7]
Which vector database is best?
There is no single best engine; the right choice depends on scale and operational constraints. Pinecone suits teams that want zero-ops managed search, Milvus targets billion-scale deployments, Qdrant emphasizes cost-efficient filtered search, Weaviate offers hybrid and GraphQL search, Chroma is popular for prototyping, and pgvector lets teams add vectors to an existing PostgreSQL database without standing up a new system.[45][46]
Glossary
| Term | Definition |
|---|---|
| Embedding | A vector representation of a piece of data, produced by a neural network |
| ANN | Approximate Nearest Neighbor; algorithms that trade some recall for large speedups |
| kNN | k-Nearest Neighbor; the exact version of nearest-neighbor search |
| HNSW | Hierarchical Navigable Small World; the dominant graph-based ANN algorithm |
| IVF | Inverted File Index; partition-based ANN method |
| PQ | Product Quantization; subvector codebook compression method |
| LSH | Locality-Sensitive Hashing; classical hashing-based ANN approach |
| Recall | Fraction of true nearest neighbors found by an approximate search |
| QPS | Queries Per Second; throughput metric |
| BM25 | A classical lexical ranking function used in full-text search |
| RRF | Reciprocal Rank Fusion; method for combining ranked lists |
| Hybrid search | Combination of lexical (BM25) and dense vector retrieval |
| Pre-filter / Post-filter | Whether metadata constraints are applied before or after ANN |
| Quantization | Lossy compression of vectors to reduce memory and compute |
| Matryoshka | Embedding training scheme that nests information from coarse to fine dimensions |
| Polystore | An architecture combining multiple databases for different workloads |
Continue reading
- HNSWHierarchical Navigable Small World (HNSW) is an approximate nearest-neighbor search algorithm that indexes high-dimensional vectors in a multi-layer proximity graph and answers similarity queries in expected…Mentioned 41 times above
- QuantizationQuantization is the representation of values from a large or continuous set by values from a smaller, usually finite set.Mentioned 36 times above
- Approximate Nearest-Neighbor SearchApproximate nearest-neighbor search (ANN or ANNS) finds points close to a query while allowing some error relative to an exact nearest-neighbor result. It is a family of search methods, not a single algorithm.Mentioned 21 times above
- Semantic searchSemantic search is an information retrieval approach that finds results based on the meaning and intent behind a query rather than relying solely on exact keyword matches.Mentioned 6 times above
- Retrieval-Augmented GenerationRetrieval-augmented generation (RAG) is a family of methods that retrieves information from an external collection and conditions a generative model on that information when producing an output.Mentioned 5 times above
- LangChainLangChain is an open-source software framework for applications that use large language models.Mentioned 4 times above
More from See also
More to read
Topics:AI InfrastructureDeveloper ToolsInformation RetrievalMachine Learning
References
- ^1 ^2Malkov, Yu. A.; Yashunin, D. A. "Efficient and Robust Approximate Nearest Neighbor Search Using Hierarchical Navigable Small World Graphs." arxiv preprint 1603.09320, 2016. Later in IEEE Transactions on Pattern Analysis and Machine Intelligence, 42(4):824-836, 2020. arxiv.org/...1603.09320
- ^Jégou, Hervé; Douze, Matthijs; Schmid, Cordelia. "Product Quantization for Nearest Neighbor Search." IEEE TPAMI, 33(1):117-128, 2011. DOI 10.1109/TPAMI.2010.57. inria.hal.science/...document
- ^1 ^2 ^3Subramanya, Suhas Jayaram; Devvrit; Kadekodi, Rohan; Krishaswamy, Ravishankar; Simhadri, Harsha Vardhan. "DiskANN: Fast Accurate Billion-point Nearest Neighbor Search on a Single Node." NeurIPS 2019. microsoft.com/...-neighbor-search-on-a-single-node
- ^1 ^2 ^3Guo, Ruiqi; Sun, Philip; Lindgren, Erik; Geng, Quan; Simcha, David; Chern, Felix; Kumar, Sanjiv. "Accelerating Large-Scale Inference with Anisotropic Vector Quantization." ICML 2020. arxiv 1908.10396. arxiv.org/...1908.10396
- ^1 ^2 ^3Chen, Qi et al. "SPANN: Highly-efficient Billion-scale Approximate Nearest Neighbor Search." NeurIPS 2021. arxiv 2111.08566. arxiv.org/...2111.08566
- ^1 ^2Indyk, Piotr; Motwani, Rajeev. "Approximate Nearest Neighbors: Towards Removing the Curse of Dimensionality." STOC 1998.
- ^1 ^2 ^3Douze, Matthijs et al. "The Faiss library." arxiv 2401.08281, 2024. arxiv.org/...2401.08281
- ^1 ^2Pinecone. "Announcing the Pinecone Vector Database and $10M in Seed Funding." Pinecone Blog, 2021. pinecone.io/...announcing-vector-database
- ^1 ^2Pinecone. "Announcing Our $100M Series B Funding to Build Long-Term Memory for AI." Pinecone Blog, April 2023. pinecone.io/...series-b
- ^Pinecone. "Edo Liberty to Spearhead Pinecone's Growing AI Ambitions; Appoints Ash Ashutosh as CEO." Pinecone Newsroom, September 2025. pinecone.io/...next-chapter
- ^Weaviate. "The History of Weaviate." Weaviate Blog. weaviate.io/...history-of-weaviate
- ^SiliconANGLE. "Weaviate reels in $50M for its AI-optimized vector database." April 21, 2023. siliconangle.com/...m-ai-optimized-vector-database
- ^Qdrant. "Announcing Qdrant's $28M Series A Funding Round." Qdrant Blog, January 2024. qdrant.tech/...series-a-funding-round
- ^Qdrant. "About Us." qdrant.tech/about-us
- ^1 ^2Qdrant. "Binary Quantization - Vector Search, 40x Faster." qdrant.tech/...binary-quantization
- ^TechCrunch. "Zilliz raises $60M, relocates to SF." August 2022. techcrunch.com/...s-raises-60m-and-relocates-to-sf
- ^Chroma. "Chroma raises $18M seed round." Chroma Blog, April 7, 2023. trychroma.com/...seed
- ^1 ^2GitHub. "pgvector/pgvector." github.com/...pgvector
- ^PostgreSQL News. "pgvector 0.7.0 Released!" postgresql.org/...pgvector-070-released-2852
- ^1 ^2Engineering at Meta. "Faiss: A library for efficient similarity search." March 2017. engineering.fb.com/...-efficient-similarity-search
- ^Vespa Blog. "Open Sourcing Vespa, Yahoo's Big Data Processing and Serving Engine." September 2017. blog.vespa.ai/...-vespa-yahoos-big-data-processing
- ^TechCrunch. "Yahoo spins out Vespa, its search tech, into an independent company." October 2023. techcrunch.com/...tech-into-an-independent-company
- ^TechCrunch. "LanceDB, which counts Midjourney as a customer, is building databases for multimodal AI." May 2024. techcrunch.com/...ding-databases-for-multimodal-ai
- ^1 ^2 ^3 ^4Turbopuffer. "turbopuffer: fast search on object storage." turbopuffer.com/...turbopuffer
- ^1 ^2MongoDB. "Atlas Vector Search Generally Available." MongoDB Blog, December 2023. mongodb.com/...-search-now-in-general-availability
- ^Elastic. "Introducing approximate nearest neighbor search in Elasticsearch 8.0." Elastic Blog. elastic.co/...neighbor-search-in-elasticsearch-8-0
- ^1 ^2Redis. "Rediscover Redis for Vector Similarity Search." Redis Blog. redis.io/...ver-redis-for-vector-similarity-search
- ^1 ^2 ^3OpenAI. "New embedding models and API updates." January 2024. openai.com/...new-embedding-models-and-api-updates
- Voyage AI. "voyage-3-large: the new state-of-the-art general-purpose embedding model." January 2025. blog.voyageai.com/...voyage-3-large
- ^1 ^2OpenSearch. "Introducing reciprocal rank fusion for hybrid search." OpenSearch Blog. opensearch.org/...procal-rank-fusion-hybrid-search
- ^1 ^2Microsoft Learn. "Hybrid Search Scoring (RRF) - Azure AI Search." learn.microsoft.com/...hybrid-search-ranking
- ^ANN-Benchmarks. ann-benchmarks.com
- ^Big-ANN-Benchmarks. big-ann-benchmarks.com/neurips21
- ^1 ^2 ^3 ^4 ^5Pinecone. "What is a Vector Database?" Pinecone Documentation. pinecone.io/...vector-database
- ^1 ^2Weaviate. "Distance Metrics in Vector Search." weaviate.io/...distance-metrics-in-vector-search
- ^1 ^2 ^3Milvus. "How to Choose Between IVF and HNSW." milvus.io/...ks-and-when-to-choose-it-over-hnsw.md
- ^1 ^2Pinecone. "Product Quantization: Compressing high-dimensional vectors by 97%." pinecone.io/...product-quantization
- ^1 ^2Qdrant. "Vector Search Benchmarks." qdrant.tech/benchmarks
- ^1 ^2 ^3 ^4 ^5DEV Community. "What's Changing in Vector Databases in 2026." dev.to/...hanging-in-vector-databases-in-2026-3pbo
- ^1 ^2 ^3VentureBeat. "Six data shifts that will shape enterprise AI in 2026." venturebeat.com/...ill-shape-enterprise-ai-in-2026
- ^1 ^2VentureBeat. "Pinecone founder Edo Liberty appoints Googler Ash as CEO." September 2025. venturebeat.com/...rty-appoints-googler-ash-as-ceo
- ^1 ^2The Information. "Pinecone weighs sale at over $2 billion valuation." 2025.
- ^1 ^2VentureBeat. "Enterprise RAG rebuild: hybrid retrieval adoption tripled in Q1 2026." venturebeat.com/...rag-programs-hit-the-scale-wall
- ^1 ^2LiquidMetal AI. "Vector Database Comparison: Pinecone vs Weaviate vs Qdrant vs FAISS vs Milvus vs Chroma (2025)." April 9, 2025. Archived at web.archive.org/...vector-comparison
- ^1 ^2DataCamp. "The 7 Best Vector Databases in 2026." datacamp.com/...the-top-5-vector-databases
- ^1 ^2Elastic. "Dense vector field type." Elasticsearch Reference. elastic.co/...dense-vector
- ^1 ^2Elastic. "Better Binary Quantization (BBQ) in Lucene and Elasticsearch." Elasticsearch Labs. elastic.co/...ry-quantization-lucene-elasticsearch
- ^1 ^2 ^3Tiger Data. "Pgvector vs. Qdrant." Tiger Data Blog. tigerdata.com/...pgvector-vs-qdrant
- ^Qdrant. "Qdrant 1.10 - Universal Query, Built-in IDF & ColBERT Support." Qdrant Blog, 2024. qdrant.tech/...qdrant-1.10.x
- ^Qdrant. "Qdrant 1.7.0 has just landed!" Qdrant Articles, December 2023. qdrant.tech/...qdrant-1.7.x
- ^CTech by Calcalist. "AI database startup Pinecone weighs sale amid rising competition." August 31, 2025. calcalistech.com/...rz31q82b5
- ^Pinecone. "Pricing." Accessed November 2026. pinecone.io/pricing
- ^Weaviate. "Pricing." Accessed November 2026. weaviate.io/pricing
- ^Zilliz. "Zilliz Cloud Pricing." Accessed November 2026. zilliz.com/pricing
- ^Qdrant. "Pricing." Accessed November 2026. qdrant.tech/pricing
- ^Chroma. "Pricing." Accessed November 2026. trychroma.com/pricing
- ^turbopuffer. "Pricing." Accessed November 2026. turbopuffer.com/pricing
- ^Chroma. "Chroma joins Replit." Chroma Blog, October 23, 2026. trychroma.com/...chroma-joins-replit
- ^1 ^2 ^3Chroma. "Chroma Cloud wind-down timeline." October 23, 2026. trychroma.com/cloud-wind-down
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
14 revisions · v14 · 10,484 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (175 claims, 64 sources fetched); 18 material + 51 minor fixed
Cite this page: AI Wiki. "Vector database." aiwiki.ai, updated 20 Jun 2026, fact-checked 1 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/vector_database