

Apple Neural Engine
The Apple Neural Engine (ANE) is the dedicated neural network accelerator, a type of neural processing unit (NPU), that Apple builds into the Apple silicon system-on-chip powering iPhone, iPad, Mac, Apple Watch, Apple Vision Pro, and HomePod. It debuted in the A11 Bionic chip, announced for iPhone 8, iPhone 8 Plus, and iPhone X on September 12, 2017 as a two-core unit rated at 600 billion operations per second (0.6 TOPS), and by the M4 in 2024 it had grown to a 16-core design rated at 38 trillion operations per second (38 TOPS), which Apple says is 60 times faster than the original [1][2][21]. In 2026 Apple moved to a Dual 16-core Neural Engine (32 cores) in the M6 and A20 Pro [34][36]. The ANE accelerates on-device machine learning inference, such as Face ID, computational photography, speech recognition, and, since 2024, the on-device large language model that underpins Apple Intelligence, delivering roughly an order of magnitude better performance per watt than running the same models on the CPU or GPU [3][4][6].
Developers do not target the ANE directly. Instead, they ship Core ML models built with the Python coremltools library, and the Core ML runtime decides at load time which subgraphs of the model to dispatch to the ANE, the GPU, or the CPU based on the operations supported, the precision required, and the device's current thermal and power state [5]. With the launch of Apple Intelligence at WWDC on June 10, 2024, the ANE became the execution target for a roughly three billion parameter on-device foundation model that powers writing tools, notification summaries, the rebuilt Siri, Genmoji, and Image Playground on supported iPhone, iPad, and Mac hardware [6][7].
What is the Apple Neural Engine?
The ANE, sometimes referred to internally as the Neural Processing Unit, is a fixed-function block on the same SoC die as the CPU, GPU, image signal processor, and Secure Enclave. It exists for one reason: to run neural network inference far more efficiently than a general-purpose CPU or GPU. Apple's neural accelerator program traces back to a small silicon team that began work on a custom inference engine for Face ID in the mid-2010s. The first hardware shipped to consumers in late 2017 and has been iterated every year, with the macro story being a steady increase in core count, throughput, and supported numerical precisions, plus closer integration with transformer workloads from 2022 onward [3][8].
How fast is the Apple Neural Engine?
Apple's quoted ANE throughput has grown unevenly, from 0.6 TOPS on the A11 in 2017 to 35 TOPS on the A17 Pro and 38 TOPS on the M4 in 2024. When Apple introduced the M4, it described the part in plain superlatives: "M4 has Apple's fastest Neural Engine ever, capable of up to 38 trillion operations per second, which is faster than the neural processing unit of any AI PC" [21]. Apple says the M4 ANE is 60x faster than the first Neural Engine in the A11 [21]; by the same arithmetic, the A18's 35 TOPS is about 58 times the A11 figure [22].
| Year | Chip | First device | ANE cores | Peak throughput | Notable additions |
|---|---|---|---|---|---|
| 2017 | A11 Bionic | iPhone 8, 8 Plus, iPhone X | 2 | 0.6 TOPS | First Neural Engine; powers Face ID and Animoji [1][9] |
| 2018 | A12 Bionic | iPhone XS, XS Max, XR | 8 | 5 TOPS | First ANE accessible to third-party apps via Core ML 2 [10] |
| 2019 | A13 Bionic | iPhone 11, 11 Pro | 8 | ~6 TOPS | Adds AMX matrix coprocessors on the CPU side; Deep Fusion photography [11] |
| 2020 | A14 Bionic | iPhone 12 series, iPad Air 4 | 16 | 11 TOPS | First 16-core ANE; first 5 nm chip [12] |
| 2020 | M1 | MacBook Air, MacBook Pro 13, Mac mini, iMac, iPad Pro | 16 | 11 TOPS | First Apple silicon Mac chip; same ANE as A14 [13] |
| 2021 | A15 Bionic | iPhone 13 series, iPad mini 6 | 16 | 15.8 TOPS | Roughly 43% faster than A14 [14] |
| 2021 | M1 Pro / M1 Max | MacBook Pro 14, MacBook Pro 16 | 16 | 11 TOPS | Same ANE as M1, paired with much larger CPU/GPU and memory bandwidth [15] |
| 2022 | M1 Ultra | Mac Studio | 32 | ~22 TOPS | Two M1 Max dies fused via UltraFusion, doubling the ANE [15] |
| 2022 | M2 | MacBook Air, 13-inch MacBook Pro, Mac mini, Vision Pro | 16 | 15.8 TOPS | Roughly 40% faster than M1 [16] |
| 2022 | A16 Bionic | iPhone 14 Pro, 14 Pro Max | 16 | ~17 TOPS | Driven hard by computational photography (Photonic Engine) [17] |
| 2023 | M2 Pro / M2 Max | MacBook Pro 14/16, Mac mini | 16 | 15.8 TOPS | Same ANE as M2 [18] |
| 2023 | M2 Ultra | Mac Studio, Mac Pro | 32 | ~31.6 TOPS | UltraFusion variant of M2 [18] |
| 2023 | A17 Pro | iPhone 15 Pro, 15 Pro Max, iPad mini 7 | 16 | 35 TOPS | First 3 nm Apple SoC; ~2x faster ANE; minimum requirement for Apple Intelligence on iPhone [19] |
| 2023 | M3 / M3 Pro / M3 Max | MacBook Pro, iMac (24-inch) | 16 | 18 TOPS | Up to 60% faster ANE than M1; first 3 nm Mac chip [20] |
| 2024 | M4 | iPad Pro (May 2024) | 16 | 38 TOPS | Apple's fastest Neural Engine at launch, 60x the A11 [21] |
| 2024 | A18 / A18 Pro | iPhone 16, 16 Plus, 16 Pro, 16 Pro Max, iPhone 16e | 16 | 35 TOPS | Apple Intelligence baked into the launch software [22] |
| 2024 | M4 Pro / M4 Max | MacBook Pro 14/16, Mac mini, Mac Studio (2025) | 16 | 38 TOPS | Same ANE as M4 [23][24] |
| 2025 | M3 Ultra | Mac Studio (March 2025) | 32 | Not stated by Apple | UltraFusion variant of M3, paired with up to 512 GB unified memory [24] |
| 2025 | A19 / A19 Pro | iPhone 17, iPhone Air, iPhone 17 Pro | 16 | Not stated by Apple | Neural Accelerators added to each GPU core, working alongside the Neural Engine [35] |
| 2025 | M5 | 14-inch MacBook Pro, iPad Pro, Apple Vision Pro | 16 | Not stated by Apple | Improved 16-core Neural Engine plus a Neural Accelerator in each GPU core [32] |
| 2026 | M5 Pro / M5 Max | MacBook Pro (March 2026) | 16 | Not stated by Apple | Faster Neural Engine with a higher-bandwidth connection to memory [33] |
| 2026 | M5 Ultra | Mac Studio (August 2026) | 32 | Not stated by Apple | Quad-die UltraFusion design [34] |
| 2026 | M6 | Mac mini (August 2026) | 2 x 16 | Not stated by Apple | First Dual 16-core Neural Engine; Apple claims up to 2x the peak compute of previous generations; first 2 nm Apple chip [34] |
| 2026 | A20 Pro | iPhone 18 Pro, iPhone 18 Pro Max | 2 x 16 | Not stated by Apple | Dual 16-core Neural Engine (32 cores), which Apple says doubles A19 Pro's AI processing power [36] |
The chart's figures are not all quoted at the same precision. Apple's 2022 transformer paper charts ANE peak throughput in FP16, giving the A15's 15.8 figure in teraflops [8], while The Register described the M4's 38 TOPS as presumably an INT8 figure [30]. Comparisons across the 2023 jump from 17-18 TOPS (A16, M3) to 35-38 TOPS (A17 Pro, M4) should be read with that in mind. Apple's per-generation marketing numbers, which describe relative speed-ups on internal benchmarks, line up with what third-party tests have reproduced:
- A14's 16-core ANE is rated at 11 TOPS, up from 5 TOPS on the A12's 8-core part [12][22].
- A15's ANE is about 43% faster than A14 on the same benchmarks [14].
- A17 Pro's ANE is roughly 2x A16 [19], and the A18 maintains that level [22].
- M3's 18 TOPS ANE is up to 60% faster than M1's, according to Apple [20], and the M4 is rated at 38 TOPS against the M3's 18 [3][21].
- Apple's foundation model on iPhone 15 Pro reports a time-to-first-token of about 0.6 ms per prompt token and a generation rate around 30 tokens per second, running directly on the A17 Pro ANE [6].
Energy efficiency is the lever Apple emphasises most. Apple's M4 announcement claims the chip as a whole (not the ANE specifically) matches M2 performance at half the power and matches the latest thin-and-light PC chip at a quarter of the power [21]. Apple does not publish general per-inference power figures for the ANE; its one published measurement, for an optimized DistilBERT on iPhone 13, is 3.47 ms per 128-token sequence at 0.454 W, or 9.44 ms at 0.072 W [8].
How is the Apple Neural Engine built?
The ANE is a custom Apple design built into the same SoC die as the CPU, GPU, image signal processor, and Secure Enclave. It is fabricated by TSMC on the same leading-edge process node as the rest of the chip: 10 nm for A11, 7 nm for A12 and A13, 5 nm-class nodes for A14 through A16 (the A16 on TSMC's N4P) and for M1 and M2, 3 nm for A17 Pro, A18, A19, M3, M4, and M5, and 2 nm for M6 [1][12][19][20][34].
While Apple has never published a full instruction set or microarchitecture diagram, third-party reverse engineering, an internal Apple paper on transformer optimisation, and the open apple/ml-ane-transformers repository together describe a fairly consistent picture [4][8]:
- The ANE is organised as multiple parallel cores, each containing arrays of multiply-accumulate (MAC) units optimised for the convolutions, matrix multiplications, and elementwise activation functions that dominate neural network inference.
- Cores share a pool of dedicated SRAM that holds activations and weight tiles, with high-bandwidth interfaces to the unified LPDDR memory used by the rest of the SoC.
- Native numerical formats include INT8 and FP16. Newer generations starting around the M3 and M4 add support for additional reduced-precision formats and palletised weight layouts useful for large language models.
- The hardware favours a (B, C, 1, S) channels-first 4D tensor layout. Apple's reference transformer code rewrites linear layers as 2D convolutions and aligns the sequence axis to a 64-byte boundary so that the compiler can map ops directly to the underlying buffers without intermediate transposes [8].
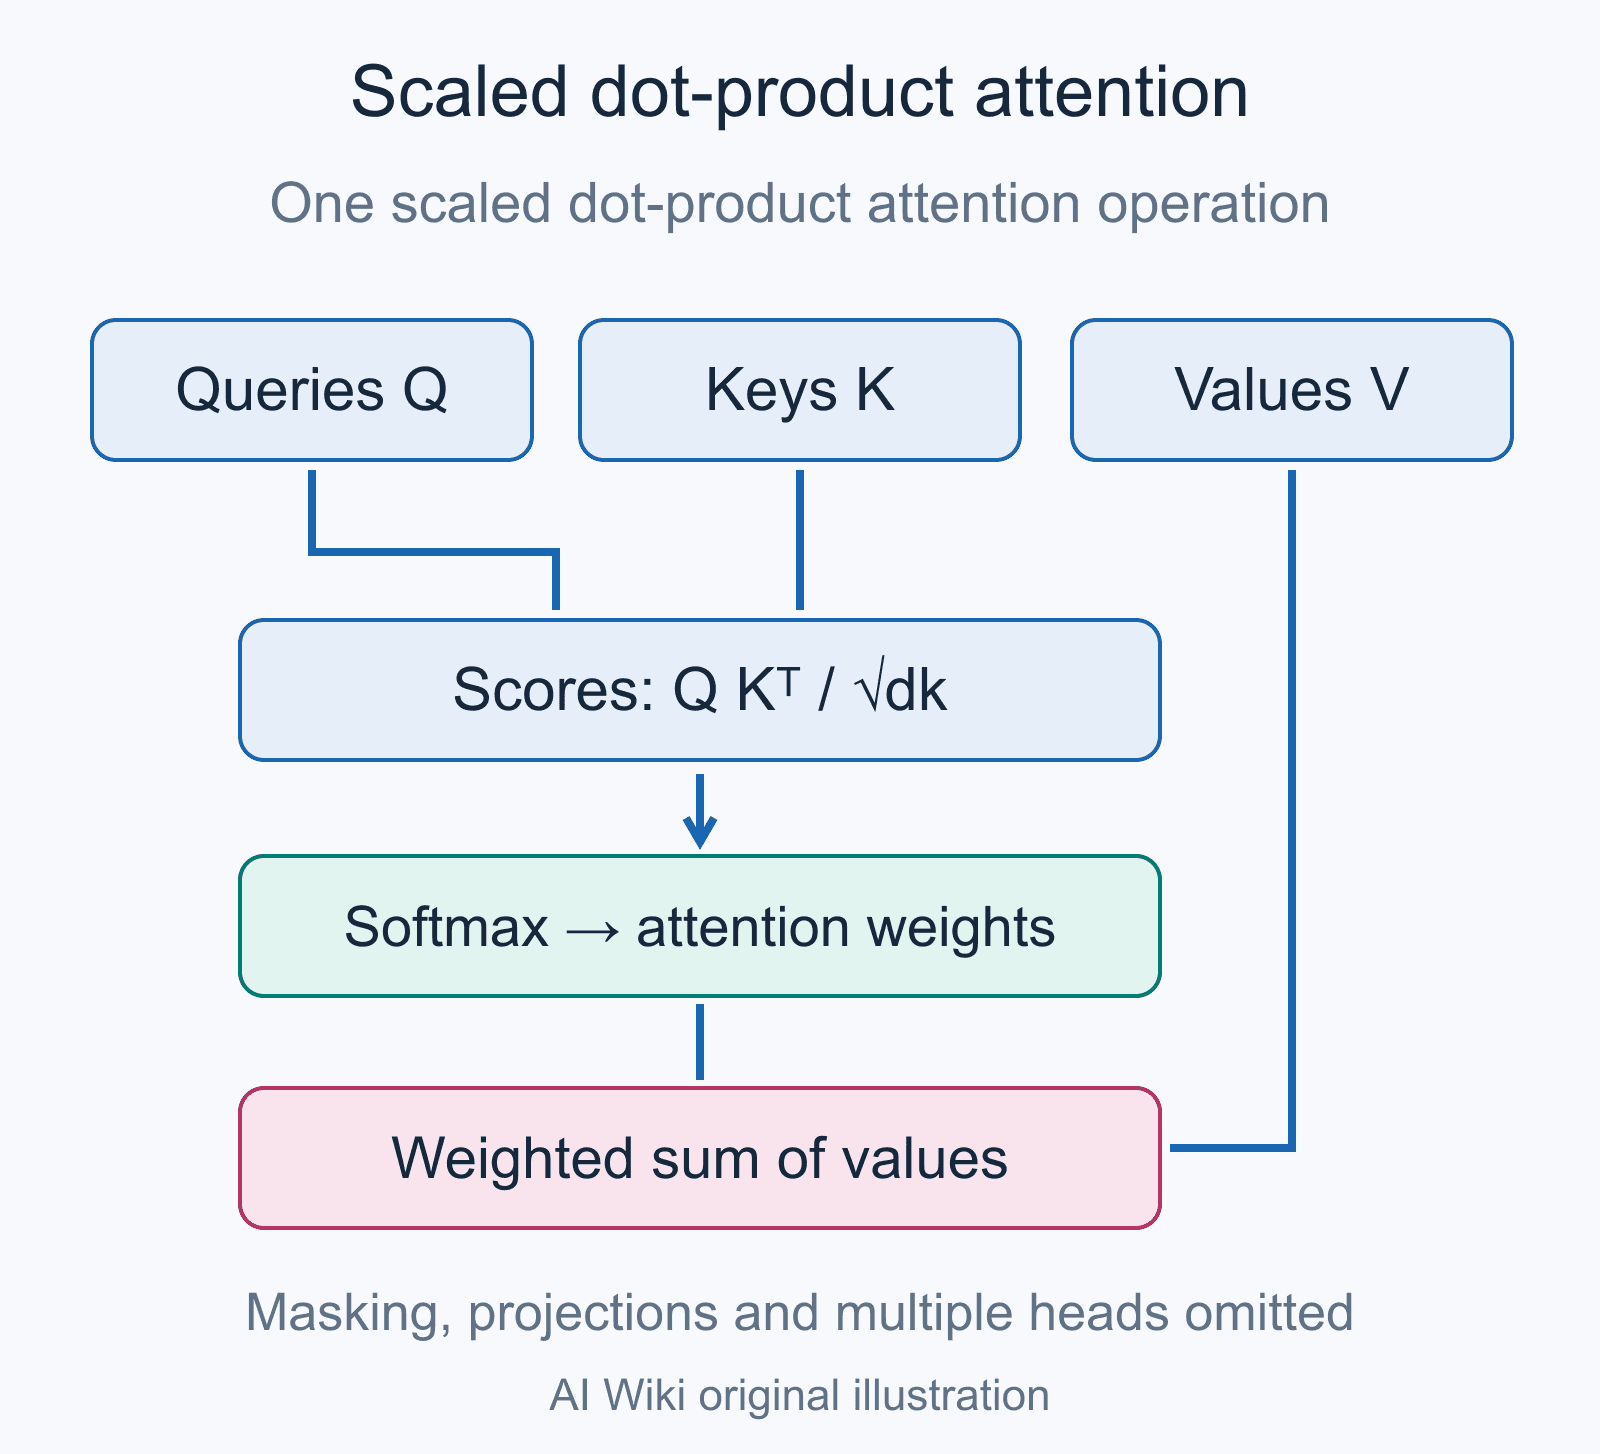
- Multi-head attention is split into single-head ops on smaller chunks. This improves L2 residency and lets multiple ANE cores work on different heads in parallel, which contributes to the up-to-10x speed-up Apple reports for its optimized DistilBERT on iPhone 13 [8].
- Apple does not publish typical ANE power draw; the measured figures in its transformer paper are well under 1 watt for an optimized DistilBERT on iPhone 13 [8].
In practice, the ANE is a feed-forward inference accelerator. It is not designed for training. Backpropagation, gradient computation, and large activation buffers fall back to the GPU or CPU when developers experiment with on-device training, and Apple has so far positioned all the ANE-optimised foundation models as inference-only with adapter layers updated separately [6].
How do developers program the Apple Neural Engine?
The public API for the ANE is Core ML, Apple's machine learning framework introduced at WWDC in June 2017, three months before the A11 Bionic. Developers convert models from PyTorch or TensorFlow, or from scikit-learn, XGBoost, and LibSVM through older converters, into the .mlpackage (or older .mlmodel) format using the Python coremltools package [5][37]. At build time, Xcode compiles .mlpackage files into .mlmodelc bundles that are shipped inside an app or downloaded on demand.
When the model is loaded, the Core ML runtime profiles the operation graph, partitions it across the available compute units, and dispatches each subgraph to the ANE, the GPU, or the CPU based on three factors: which ops are supported by the ANE on that device, how the precision and shape constraints are met, and the current power and thermal state. Developers can hint a preferred compute unit (computeUnits = .all, .cpuAndNeuralEngine, .cpuAndGPU, or .cpuOnly) but cannot otherwise force the runtime's hand [5]. This is by design: the same model binary can run efficiently across iPhone, iPad, Mac, Vision Pro, and Apple Watch without recompilation.
For transformer workloads, Apple released ane_transformers in 2022, an open reference PyTorch implementation that uses the data layout and chunking tricks described above. On an iPhone 13, a DistilBERT model rewritten with ane_transformers runs about 10x faster and uses about 14x less peak memory than a stock implementation, and lands inference at roughly 3.47 ms per 128-token sequence [8]. Independent work goes further: the maderix reverse-engineering series bypasses Core ML to drive the M4 ANE directly [4], and the 2026 Orion system by Ramchand Kumaresan characterises the ANE and uses it for small-model training as well as inference [31].
What is the Neural Engine used for?
The original justification for the ANE was Face ID, a per-unlock face-recognition pipeline that needed to clear the secure enclave, run on-device, and beat the Touch ID latency budget. Once that hardware existed, Apple gradually expanded the workloads it carried.
| Feature | First shipped | Notes |
|---|---|---|
| Face ID | 2017 (iPhone X) | Original motivating workload; runs in the Secure Enclave perimeter [1][9] |
| Animoji and Memoji | 2017 / 2018 | Real-time facial mesh tracking driving stylised avatars [1] |
| Photo Memories and on-device search | 2018 onward | Object, scene, and face clustering across the user's library [3] |
| Smart HDR and Deep Fusion | 2018 (Smart HDR, iPhone XS); 2019 (Deep Fusion, iPhone 11) | Per-pixel ML fusion of bracketed exposures [11] |
| Photonic Engine | 2022 (iPhone 14) | ML pipeline applied earlier in the image processing stack [17] |
| Live Text | 2021 (iOS 15) | OCR across photos, screenshots, and the camera viewfinder [3] |
| Visual Look Up | 2021 (iOS 15) | Identifies plants, pets, landmarks, and art on-device |
| Translate (offline) | 2020 (iOS 14) | Downloadable language packs run on the ANE |
| Voice Isolation in FaceTime | 2021 (iOS 15) | Real-time speech enhancement |
| Live Captions | 2022 (iOS 16) | On-device speech-to-text overlay for any audio |
| Personal Voice | 2023 (iOS 17) | User-trainable synthetic voice for accessibility |
| Apple Intelligence | 2024 (iOS 18.1) onward | Writing Tools and notification summaries first, Genmoji and Image Playground later; the rebuilt Siri (Siri AI) arrived with the 27.0 releases [6][7][25] |
Most of these features run silently. Users do not pick the ANE; the operating system does. The system-wide effect is that on-device ML has become the default, a pattern sometimes called edge AI. Cloud calls are reserved for cases where a model is too large to fit in unified memory or where the user explicitly invokes ChatGPT through Siri.
How does the Apple Neural Engine power Apple Intelligence?
Apple announced Apple Intelligence at WWDC on June 10, 2024 and shipped its first features in iOS 18.1, iPadOS 18.1, and macOS Sequoia 15.1 in October 2024 [6][7]. The system has two layers:
- An on-device foundation model in the neighbourhood of three billion parameters, fine-tuned with task-specific adapters and quantised aggressively (mixed 2-bit and 4-bit palletised weights, averaging about 3.7 bits per weight), running on the ANE [6].
- A larger server-side model running on Apple silicon servers under a system Apple calls Private Cloud Compute (PCC), used for harder requests where the on-device model cannot give a good answer.
As of the 27.0 software releases, Apple lists Apple Intelligence on iPhone 15 Pro and 15 Pro Max, iPhone 16 models or later, iPhone Air, iPhone Duo, iPad mini (A17 Pro), iPad and Mac models with M1 or later, MacBook Neo (A18 Pro), and Apple Vision Pro, with Apple Watch Series 9 or later, Ultra 2 or later, and SE 3 supported when paired with an eligible iPhone [25]. The first release required iOS 18.1, iPadOS 18.1, or macOS Sequoia 15.1 [7]. The 8 GB floor is the binding constraint: the on-device foundation model and its adapter caches need to be paged in alongside the rest of the operating system, which is why the otherwise capable iPhone 15 (A16, 6 GB) is excluded.
The on-device model is not a general chatbot. Apple ships it with adapters for specific tasks: text rewriting and proofreading, summarisation, prioritisation, response suggestions, notification summaries, and Genmoji generation [6]. Each adapter is on the order of tens of megabytes and is loaded into the ANE alongside the base model when the relevant feature runs. The full technical detail is laid out in Apple's "Apple Intelligence Foundation Language Models" report and its 2025 update, both published on the Apple Machine Learning Research site [6][26].
For reasoning, image generation, and other workloads beyond the on-device model's scope, the request is encrypted, attested, and sent to PCC. Apple publishes the operating system images for those servers and runs them on hardened Apple silicon, so that researchers can verify what is and is not running. The on-device ANE remains the default execution target; PCC only runs when needed and never persists user data after the request is served [27].
How does the Apple Neural Engine compare with competing NPUs?
The ANE was one of the first NPUs to ship at scale in a mass-market device. By 2024 nearly every silicon vendor offered a comparable accelerator. The numbers below report each vendor's headline INT8 figure for the most current laptop or smartphone-class chip available in 2024 and early 2025; data-centre accelerators are excluded.
| Vendor | Latest NPU | TOPS (INT8) | Key devices | Year | Software stack |
|---|---|---|---|---|---|
| Apple | Apple Neural Engine (M4 / A18) | 38 / 35 | iPad Pro, MacBook Pro, iPhone 16, iPhone 15 Pro | 2024 | Core ML, MLX [21][22] |
| Qualcomm | Hexagon NPU (Snapdragon X Elite) | 45 | Copilot+ PCs (Surface, Galaxy Book4 Edge) | 2024 | QNN, AI Hub, ONNX Runtime [28] |
| Qualcomm | Hexagon NPU (Snapdragon 8 Gen 3) | Not published | Samsung Galaxy S24, Xiaomi 14 | 2023 | QNN, AI Hub [28] |
| Edge TPU / Tensor TPU (Tensor G4) | Not published | Pixel 9, Pixel 9 Pro | 2024 | LiteRT (formerly TensorFlow Lite), AICore [29] | |
| Samsung | NPU (Exynos 2400) | ~42 (implied by Samsung) | Galaxy S24 (non-US) | 2024 | One UI AI APIs, ONNX Runtime [38] |
| MediaTek | APU (Dimensity 9400) | ~50 | Vivo X200, Oppo Find X8 | 2024 | NeuroPilot SDK [39] |
| Intel | NPU 4 (Lunar Lake Core Ultra 200V) | 48 | Copilot+ Intel laptops | 2024 | OpenVINO, DirectML, ONNX Runtime [40] |
| AMD | XDNA 2 (Ryzen AI 300, Ryzen AI Max+ 395) | 50 | ASUS ProArt, Framework Desktop | 2024 | Ryzen AI Software, ONNX Runtime [40] |
| NVIDIA | Jetson Orin (embedded modules) | Up to 275 | Robotics and edge dev kits | 2023 | TensorRT, CUDA [41] |
Since this snapshot, Apple has moved to a Dual 16-core Neural Engine in the M6 and A20 Pro without publishing TOPS figures [34][36]. The headline TOPS numbers are easy to misread. Vendors report at different precisions and pick the most flattering metric. What sets the ANE apart in practice is less raw throughput and more vertical integration: the same Core ML model runs on every shipping Apple device, the runtime handles fallback automatically, and feature work like Apple Intelligence is wired through the same stack that third-party app developers use [3][5]. Qualcomm's Hexagon and Intel's Lunar Lake NPU are competitive on TOPS but require developers to deal with separate SDKs and a less consistent operator coverage story across SoC generations.
What are the limitations of the Apple Neural Engine?
The ANE is a closed, single-vendor accelerator. Some practical consequences:
- Models must go through Core ML conversion. Operations not supported on the current ANE generation fall back to GPU or CPU silently, sometimes turning a fast model into a slow one without an obvious warning [5].
- Memory is shared with the rest of the SoC. On iPhones with 6 GB of RAM, large models simply will not fit. Memory is widely cited as the reason the 6 GB iPhone 15 and older models are excluded from Apple Intelligence [25].
- Developers cannot write CUDA-style kernels for the ANE. Anyone who wants lower-level control has to drop down to the GPU through Metal or use Apple's MLX framework, which targets unified memory rather than the ANE specifically.
- Some PyTorch and transformer ops, especially around dynamic shapes, custom kernels, or non-standard normalisation layers, do not have ANE-friendly implementations and end up on the GPU [4].
- The ANE is inference-first. Training large models on-device remains out of scope; even adapter fine-tuning for Apple Intelligence happens on Apple's own infrastructure rather than on user devices [6].
None of these are fatal for normal app development, but they explain why projects like the Whisper and Stable Diffusion ports for iOS often spend most of their effort on layout-friendly model rewrites rather than on inference logic.
Why does the Apple Neural Engine matter?
The ANE was one of the first NPUs to ship in a mass-market consumer device, arriving in 2017 [3]. It made on-device AI a default rather than a research demo. Face ID, computational photography, Live Text, and Apple Intelligence all rely on it. It also shifted the privacy conversation around mobile AI: because the inference happens on the user's device, the underlying images, voice samples, or text never need to leave it, and Apple has built a substantial part of its marketing around that fact [27].
For Apple itself, the ANE underpins the company's ability to compete in the generative AI cycle without relying on third-party data centres for every interaction. The on-device foundation model in Apple Intelligence runs on the same silicon that handles Face ID and photo Memories, which gives Apple a useful structural advantage: a captive distribution channel of hundreds of millions of devices already shipped with hardware capable of running its models. Whether that translates into a long-term lead over Google's Tensor and Qualcomm's Snapdragon NPUs is still being decided, but as of 2026 the ANE ships in every current iPhone, iPad, and Mac, and one 2026 research paper put the number of Apple devices carrying it at over two billion [31].
Continue reading
- Apple IntelligenceApple Intelligence is Apple's personal intelligence system, a suite of generative AI features built into iPhone, iPad, Mac, Apple Watch, and Apple Vision Pro that combines on-device machine learning models…Mentioned 14 times above
- Apple SiliconApple silicon is the family of ARM architecture system on a chip (SoC) and system in a package (SiP) processors that Apple Inc. designs for its own productsMentioned 4 times above
- SiriSiri is the voice assistant developed by Apple Inc. that launched on the iPhone 4S on October 14, 2011, a launch SRI credits with "bringing voice assistants into the mainstream".Mentioned 4 times above
- Apple Vision ProApple Vision Pro is a mixed-reality headset developed by Apple Inc. that the company markets under the term "spatial computing" rather than as a virtual or augmented reality device.Mentioned 3 times above
- TransformersA Transformer is a deep learning architecture, introduced by eight Google researchers in the 2017 paper "Attention Is All You Need", that uses attention as the sole mechanism for modeling relationships between…Mentioned 3 times above
- Large Language ModelA large language model (LLM) is an artificial intelligence system built on a transformer neural network with billions to trillions of parameters, trained on massive text corpora to predict the next token in a…Mentioned twice above
More to read
- TSMC (Taiwan Semiconductor Manufacturing Company)
- Edge AI
- Foundation Models
- TensorFlow Lite (LiteRT)
- Quantization
- Edge computing
Topics:AI CompaniesAI Hardware
See also
- Apple Intelligence, Apple silicon, Apple Vision Pro
- Edge AI
- Foundation model, large language model, transformer
- Quantization, edge computing, Gemini Nano
- TensorFlow Lite, Siri, TSMC
References
- ^1 ^2 ^3 ^4 ^5Apple Inc. "The future is here: iPhone X." Apple Newsroom, September 12, 2017. apple.com/...the-future-is-here-iphone-x
- ^CNBC. "Apple unveils A11 Bionic neural engine AI chip in iPhone X." September 12, 2017. cnbc.com/...onic-neural-engine-ai-chip-in-iphone-x
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Wikipedia. "Neural Engine." en.wikipedia.org/...Neural_Engine
- ^1 ^2 ^3 ^4Maderix. "Inside the M4 Apple Neural Engine, Part 1: Reverse Engineering." 2024. maderix.substack.com/...the-m4-apple-neural-engine
- ^1 ^2 ^3 ^4 ^5Apple Developer. "Core ML Overview." developer.apple.com/...coreml
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10Apple Machine Learning Research. "Introducing Apple's On-Device and Server Foundation Models." June 10, 2024. machinelearning.apple.com/...ple-foundation-models
- ^1 ^2 ^3 ^4Apple Inc. "Introducing Apple Intelligence for iPhone, iPad, and Mac." Apple Newsroom, June 10, 2024. apple.com/...-intelligence-for-iphone-ipad-and-mac
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Apple Machine Learning Research. "Deploying Transformers on the Apple Neural Engine." June 2022. machinelearning.apple.com/...l-engine-transformers
- ^1 ^2Wikipedia. "Apple A11." en.wikipedia.org/...Apple_A11
- ^Wikipedia. "Apple A12." en.wikipedia.org/...Apple_A12
- ^1 ^2Wikipedia. "Apple A13." en.wikipedia.org/...Apple_A13
- ^1 ^2 ^3Wikipedia. "Apple A14." en.wikipedia.org/...Apple_A14
- ^Apple Inc. "Apple unleashes M1." Apple Newsroom, November 10, 2020. apple.com/...apple-unleashes-m1
- ^1 ^2Wikipedia. "Apple A15." en.wikipedia.org/...Apple_A15
- ^1 ^2Apple Inc. "Apple unveils M1 Pro and M1 Max." Apple Newsroom, October 18, 2021. apple.com/...t-powerful-chips-apple-has-ever-built
- ^Apple Inc. "Apple unveils M2 with breakthrough performance and capabilities." Apple Newsroom, June 6, 2022. apple.com/...kthrough-performance-and-capabilities
- ^1 ^2Wikipedia. "Apple A16." en.wikipedia.org/...Apple_A16
- ^1 ^2Apple Inc. "Apple introduces M2 Pro and M2 Max." Apple Newsroom, January 17, 2023. apple.com/...ration-chips-for-next-level-workflows
- ^1 ^2 ^3Wikipedia. "Apple A17." en.wikipedia.org/...Apple_A17
- ^1 ^2 ^3Apple Inc. "Apple unveils M3, M3 Pro, and M3 Max." Apple Newsroom, October 30, 2023. apple.com/...dvanced-chips-for-a-personal-computer
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Apple Inc. "Apple introduces M4 chip." Apple Newsroom, May 7, 2024. apple.com/...apple-introduces-m4-chip
- ^1 ^2 ^3 ^4 ^5Wikipedia. "Apple A18." en.wikipedia.org/...Apple_A18
- ^Apple Inc. "New MacBook Pro features M4 family of chips and Apple Intelligence." Apple Newsroom, October 30, 2024. apple.com/...amily-of-chips-and-apple-intelligence
- ^1 ^2Apple Inc. "Apple unveils new Mac Studio, the most powerful Mac ever." Apple Newsroom, March 5, 2025. apple.com/...mac-studio-the-most-powerful-mac-ever
- ^1 ^2 ^3Apple Support. "How to get Apple Intelligence." support.apple.com/...121115
- ^Apple Machine Learning Research. "Apple Intelligence Foundation Language Models Tech Report 2025." machinelearning.apple.com/...dels-tech-report-2025
- ^1 ^2Apple Inc. "Private Cloud Compute: A new frontier for AI privacy in the cloud." Apple Security Research Blog, June 10, 2024. security.apple.com/...private-cloud-compute
- ^1 ^2TweakTown. "Qualcomm details its Snapdragon X Elite: all SKUs have NPU with 45 TOPS for AI workloads." 2024. tweaktown.com/...npu-with-45-tops-for-ai-workloads
- ^Android Authority. "Google Tensor G4 explained: Everything you need to know about the Pixel 9 processor." August 2024. androidauthority.com/...-pixel-9-processor-3466184
- ^The Register. "Apple unveils M4 chip with neural engine capable of 38 TOPS." May 7, 2024. theregister.com/...apple_m4_ipad
- ^1 ^2Kumaresan, Ramchand. "Orion: Characterizing and Programming Apple's Neural Engine for LLM Training and Inference." arXiv:2603.06728, March 6, 2026. arxiv.org/...2603.06728
- ^Apple Inc. "Apple unleashes M5, the next big leap in AI performance for Apple silicon." Apple Newsroom, October 15, 2025. apple.com/...p-in-ai-performance-for-apple-silicon
- ^Apple Inc. "Apple debuts M5 Pro and M5 Max to supercharge the most demanding pro workflows." Apple Newsroom, March 3, 2026. apple.com/...arge-the-most-demanding-pro-workflows
- ^1 ^2 ^3 ^4 ^5Apple Inc. "Apple introduces M6 and M5 Ultra for a big leap in performance and AI compute." Apple Newsroom, August 25, 2026. apple.com/...ig-leap-in-performance-and-ai-compute
- ^Apple Inc. "Apple unveils iPhone 17 Pro and iPhone 17 Pro Max." Apple Newsroom, September 9, 2025. apple.com/...s-iphone-17-pro-and-iphone-17-pro-max
- ^1 ^2 ^3Apple Inc. "Apple debuts iPhone 18 Pro and iPhone 18 Pro Max." Apple Newsroom, September 2026. apple.com/...s-iphone-18-pro-and-iphone-18-pro-max
- ^Apple. "Core ML Tools overview." coremltools documentation. apple.github.io/...overview-coremltools
- ^Samsung Semiconductor. "Exynos 2500." semiconductor.samsung.com/...exynos-2500
- ^DigiTimes. "Dimensity 9400's 50 TOPS pushes MediaTek to the forefront of mobile AI." October 11, 2024. apps.digitimes.com/...a20241011PD210
- ^1 ^2MobileSyrup. "Intel, AMD announce new chips destined for Copilot+ PCs." June 4, 2024. mobilesyrup.com/...-chips-destined-for-copilot-pcs
- ^NVIDIA. "Jetson Orin." nvidia.com/...jetson-orin
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
5 revisions · v5 · 4,468 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (120 claims, 44 sources fetched); 13 material + 27 minor fixed
Cite this page: AI Wiki. "Apple Neural Engine." aiwiki.ai, updated 25 Jun 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/apple_neural_engine