

Bidirectional
See also: Machine learning terms
Bidirectional describes a sequence model in which the representation at every position depends on the entire input sequence, both the tokens before it and the tokens after it, rather than only the preceding tokens. A bidirectional model processes its input in both the forward (left-to-right) and backward (right-to-left) directions and combines the two views, so each position is informed by past and future context at once. The idea predates deep learning and appears across many architectures, including recurrent neural networks, long short-term memory networks, gated recurrent units, and modern transformer encoders such as BERT.[1][7][11]
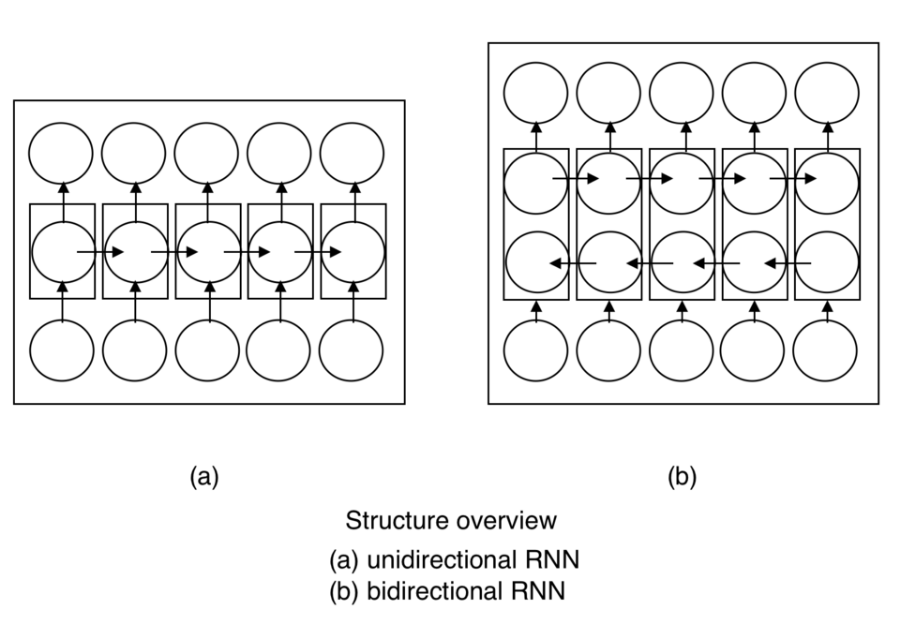
Bidirectionality is what makes a model good at understanding rather than generating. Because it can read the whole input before committing to an answer, a bidirectional model excels at labeling, tagging, classification, and retrieval, where the full input is already available. It cannot generate text one token at a time, however, because the future tokens it relies on do not yet exist at generation time. This single trade-off (full context for understanding, but no autoregressive generation) explains why BERT-style encoders dominate embedding and classification tasks while GPT-style decoders dominate chat and writing.[7]
This article covers the general concept of bidirectionality across neural architectures and tasks. For the language modeling specialization, where the same idea drives BERT-style pretraining, see bidirectional language model. For the contrast, see unidirectional language model.
What does bidirectional mean in machine learning?
A standard sequence model reads its input one position at a time and updates an internal state. In a forward-only (causal) model, the state at position t summarizes everything from position 1 through position t. The state never sees what comes later. That works for prediction tasks where the future genuinely is unknown, like writing the next token of a story, but it throws away information when the future is sitting right there in the input.
The motivating example used in almost every textbook is a homograph: "He went to the bank to deposit his check" versus "He sat by the bank of the river." A forward-only model trying to label "bank" at position 4 has no access to "deposit" or "river," because they have not been read yet. A bidirectional model has access to both sides, so it can disambiguate without any extra machinery. The same logic applies to phoneme classification (the next phoneme constrains the current one), named entity recognition ("Apple announced" pulls toward ORG, "Apple pie" toward FOOD), and many sequence labeling tasks.
What are the two ways to make a model bidirectional?
There are two technically different ways to make a model bidirectional, and the literature sometimes uses the same word for both. They are worth keeping straight.
The first is sequential bidirectionality, where two separate sequence models scan the input in opposite directions and their outputs are combined. This is the original Schuster and Paliwal recipe from 1997 and applies cleanly to RNNs, LSTMs, and GRUs.[1] The forward and backward streams never interact during their internal computation. They only meet at the end, usually through concatenation.
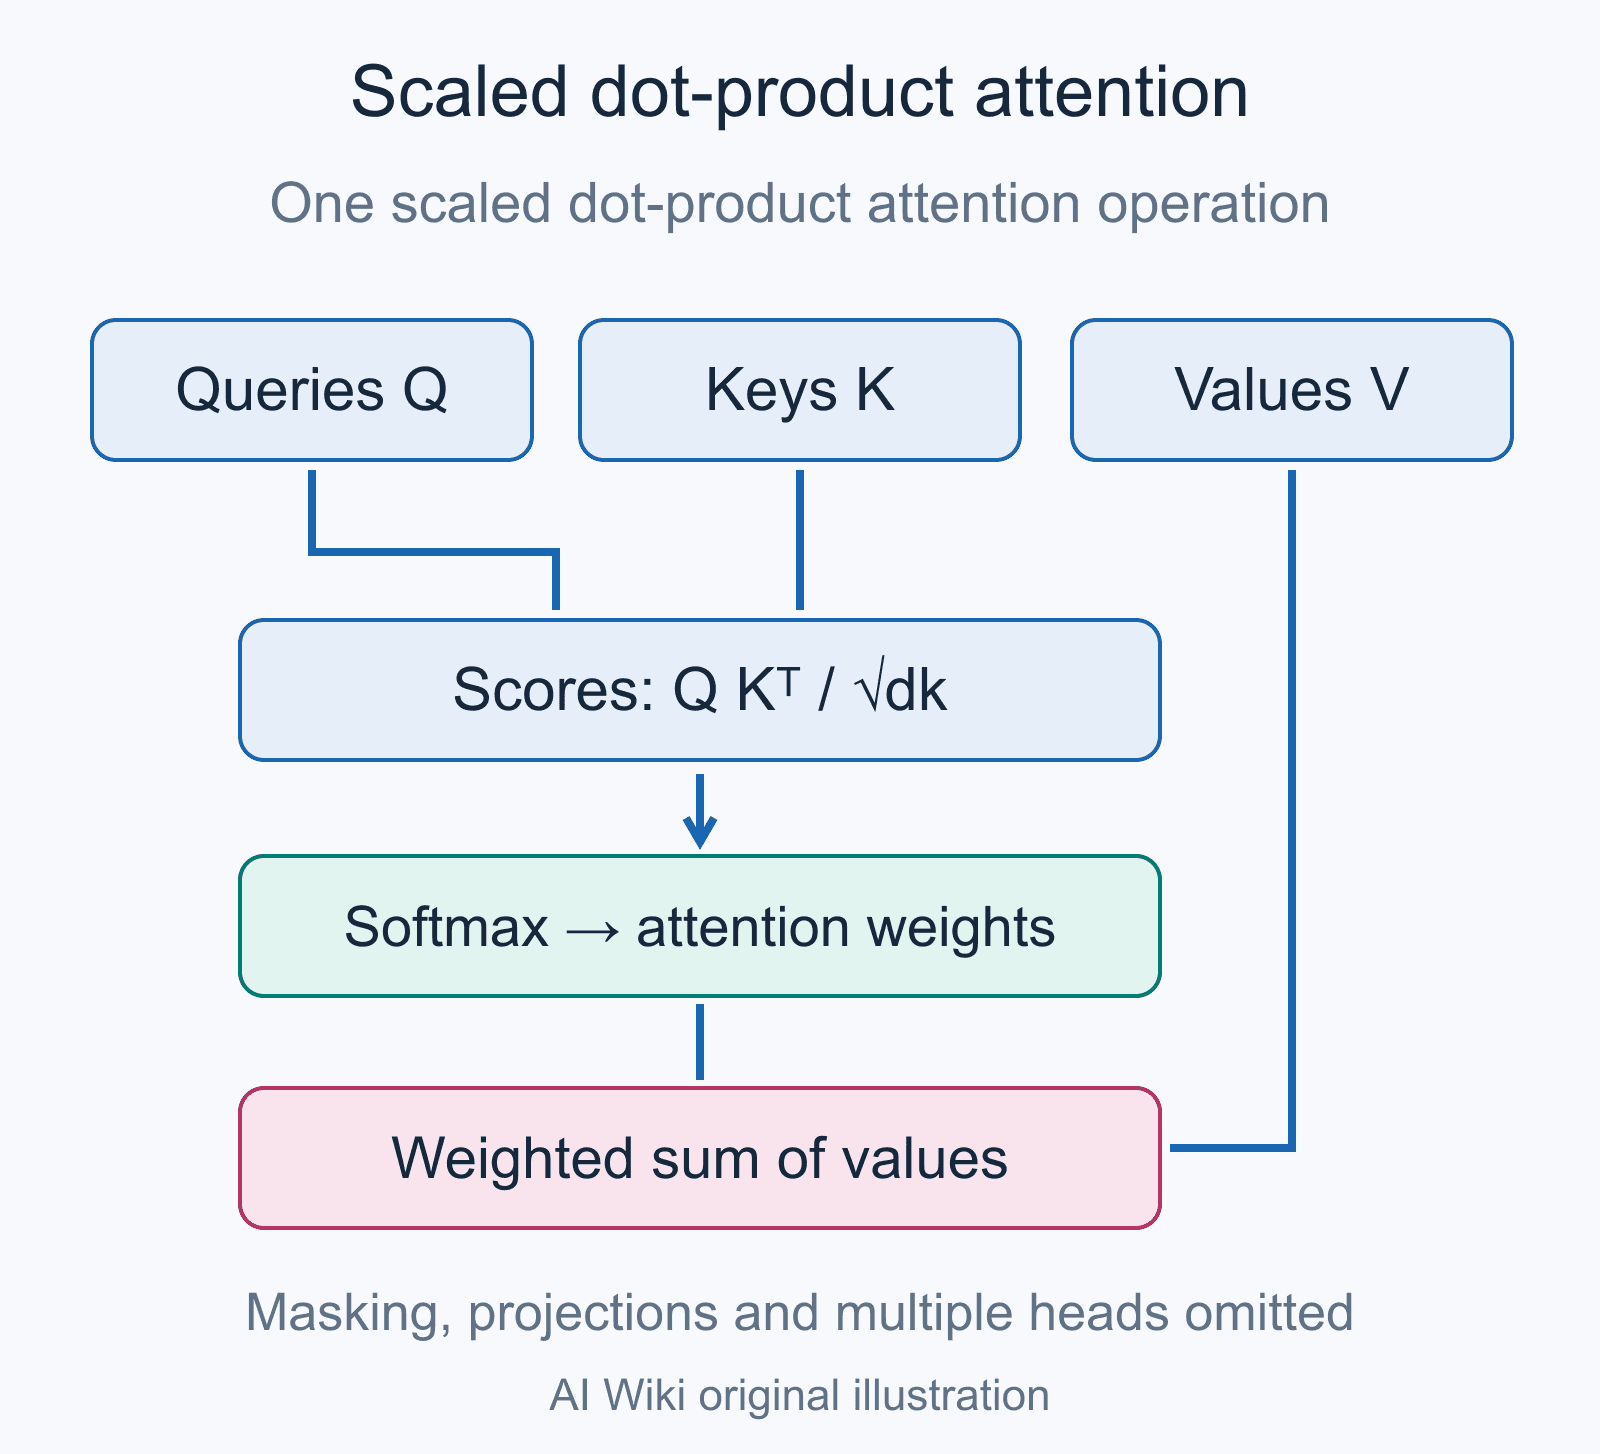
The second is bidirectional attention, where a single network looks at the whole sequence at once through self-attention. There are no separate streams. Each position simply attends to every other position, in both directions, at every layer. This is how BERT and other transformer encoders work.[7] The bidirectionality is not built into the math of attention; it is built into what the attention mask allows. Removing the causal mask that decoder-style transformers use turns the same architecture into a bidirectional one.[4]
| Property | Sequential bidirectional (BiRNN family) | Bidirectional attention (BERT family) |
|---|---|---|
| Streams | Two networks, opposite directions | One network, full self-attention |
| Backbone | RNN, LSTM, or GRU | Transformer encoder |
| Combination | Concatenation of forward and backward states | Single contextual vector per position |
| Directions combined | After each layer's two passes | Inside every attention layer |
| Compute cost | O(n) per layer, twice | O(n^2) per layer |
| Typical use | Sequence labeling, speech, time series | Pretraining, embeddings, classification |
| Origin paper | Schuster & Paliwal, 1997 | Vaswani et al., 2017 (encoder); Devlin et al., 2018 (BERT pretraining) |
The practical difference matters. Within a single BiLSTM layer, the forward and backward streams only meet after both recurrent passes are done; stacked BiLSTMs then feed that combined output into the next layer. A transformer encoder mixes both directions inside every layer. The BERT paper called its own encoder "deep" bidirectional and used "shallow" for ELMo-style models that concatenate independently trained left-to-right and right-to-left language models.[7]
What is a bidirectional RNN?
The original idea is the bidirectional recurrent neural network (BRNN), introduced by Mike Schuster and Kuldip Paliwal in 1997 in a paper in IEEE Transactions on Signal Processing, volume 45, issue 11, pages 2673-2681.[1] They were working on speech tasks where the relevant context for any given frame lies on both sides of it. As the abstract puts it, "The BRNN can be trained without the limitation of using input information just up to a preset future frame. This is accomplished by training it simultaneously in positive and negative time direction."[1] Their fix was structural rather than algorithmic: train one RNN that reads the input forward, train a second RNN with separate parameters that reads it backward, and at every position concatenate the two hidden states.[1] The paper reports that on phoneme classification experiments using the TIMIT database, the bidirectional structure gives better results than other approaches.[1]
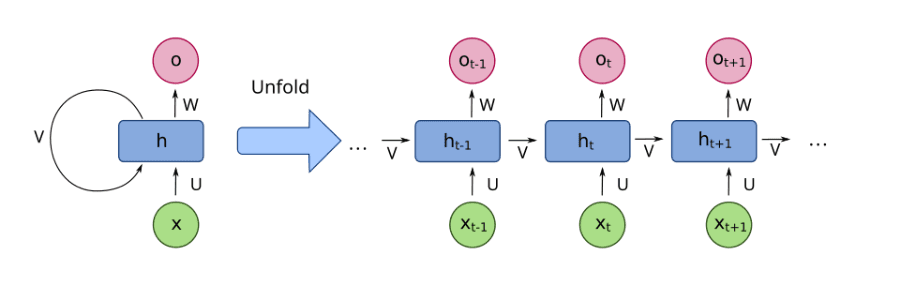
Formally, given an input sequence through , a forward RNN computes hidden states for to , and a backward RNN computes for down to 1. The combined representation at position is the concatenation . Because the two streams are independent, they can be trained with the same backpropagation through time algorithm used for vanilla RNNs, just unrolled in both directions.
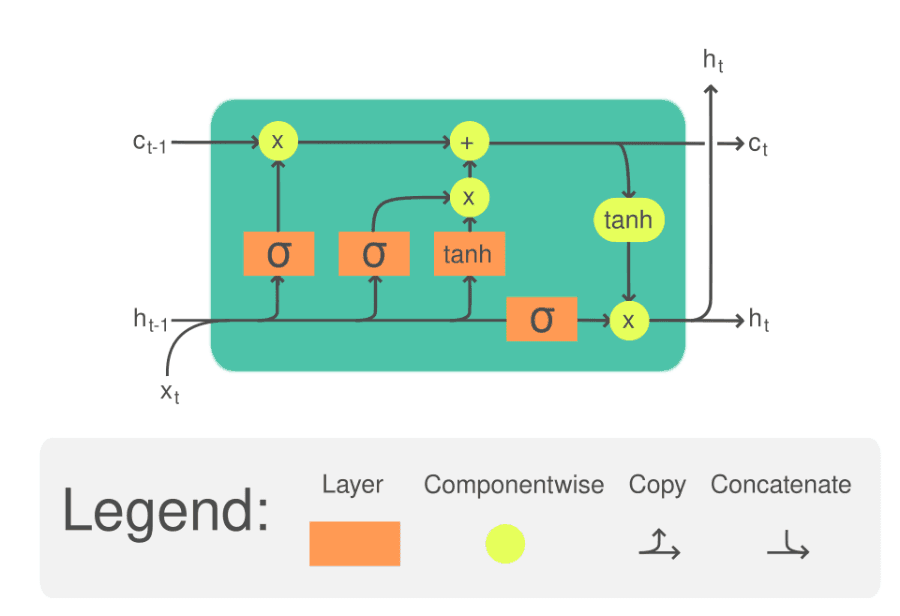
The approach sat relatively quietly for almost a decade because plain RNNs were hard to train on long sequences. The breakthrough came when Alex Graves and Jurgen Schmidhuber combined it with LSTM cells in 2005. Their paper "Framewise phoneme classification with bidirectional LSTM and other neural network architectures," published in Neural Networks (volume 18, issues 5-6, pages 602-610), applied the BRNN trick to LSTM and showed that the resulting bidirectional LSTM outperformed both unidirectional LSTM and standard RNNs on TIMIT phoneme classification.[2] They concluded that bidirectional LSTM "is an architecture well suited to this and other speech processing tasks, where context is vitally important."[2] They also introduced a full-gradient version of the LSTM training algorithm, replacing the original algorithm's gradient truncation; it gave slightly higher performance and let LSTM be trained with standard backpropagation through time.[2] The combination of LSTM gating and bidirectional context made the bidirectional LSTM (BiLSTM) the dominant architecture for sequence labeling for roughly the next decade.
The same wrapper trick works for other recurrent cells. A bidirectional GRU is a GRU running forward and a separate one running backward, with concatenated outputs.[3][12] A bidirectional vanilla RNN works the same way, although the vanishing gradient problem makes it less useful in practice. The distinction is the cell, not the bidirectionality.
| Variant | Underlying cell | First major use | Typical task |
|---|---|---|---|
| BiRNN | Vanilla RNN | Schuster & Paliwal 1997 | Speech frame classification |
| BiLSTM | LSTM | Graves & Schmidhuber 2005 | Phoneme classification, NER, POS tagging |
| BiGRU | GRU | Bahdanau, Cho & Bengio 2014 (translation encoder using the gated unit of Cho et al. 2014)[3][12] | Machine translation encoders, time series |
| BiQRNN | Quasi-RNN | QRNN layer from Bradbury et al. 2017[8], run in both directions | Faster sequence encoding |
| BiSRU | Simple Recurrent Unit | Lei et al. 2018 | Throughput-sensitive sequence tasks |
How does bidirectional attention work in transformers?
The transformer architecture, introduced in 2017, originally split into an encoder that read the input bidirectionally and a decoder that produced output causally.[4] The encoder used the standard self-attention mechanism without any mask, so every position could see every other position. This was bidirectional in exactly the sense above, but it had not yet been used as a standalone pretraining target.
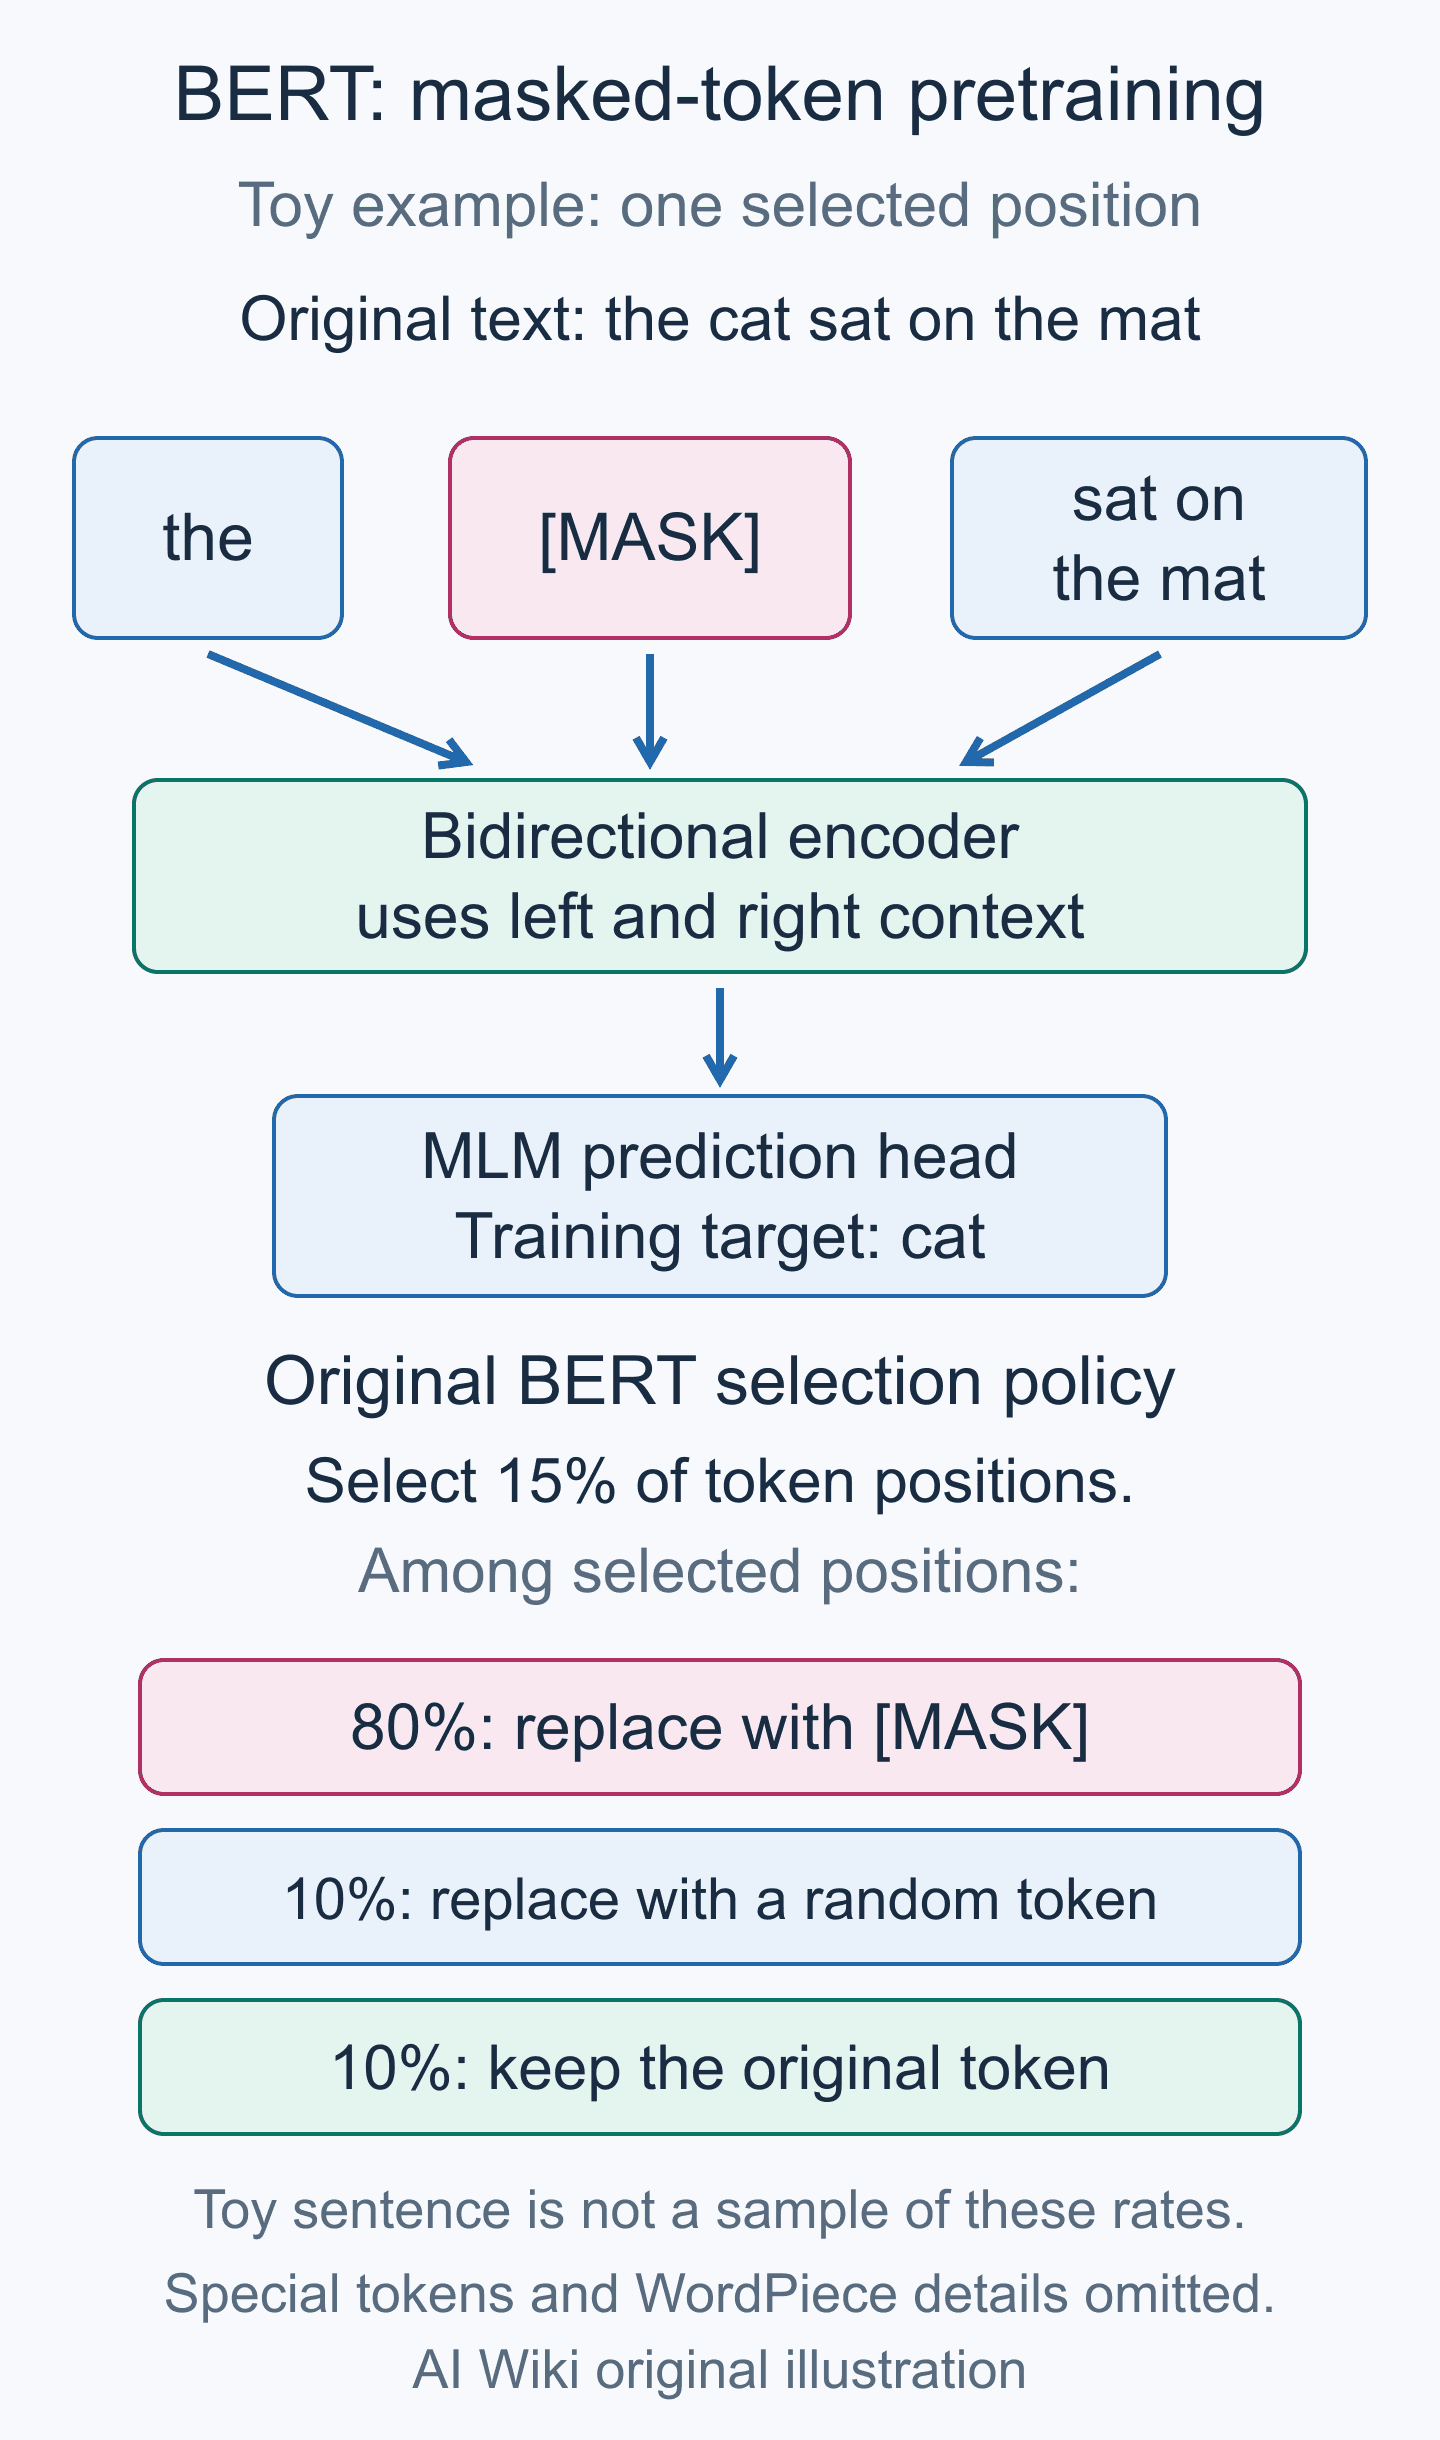
BERT, released by Google in 2018, took the transformer encoder, threw away the decoder, and turned the encoder into a general-purpose pretraining model.[7] In the words of the paper, "BERT is designed to pre-train deep bidirectional representations from unlabeled text by jointly conditioning on both left and right context in all layers."[7] The key trick was the masked language model (MLM) objective: randomly replace 15 percent of input tokens with a [MASK] token and ask the model to recover the original.[7] Because the answer has been deleted from the input, the model is forced to use surrounding context (in both directions) to make its prediction. This sidesteps the obvious problem that a vanilla next-token objective is trivial when the model can see the next token.
BERT and its descendants (RoBERTa, ALBERT, ELECTRA, DeBERTa) all share the same structural property: a transformer encoder with no causal mask, trained on some variant of MLM. The result is what the BERT paper called "deep bidirectional" representations,[7] contrasted with the "shallow" bidirectionality of older biLM approaches like ELMo that just concatenate a forward and a backward LM.[6][7] For the full story of how this lineage played out in language modeling specifically, see bidirectional language model.
Note that not every transformer is bidirectional. The GPT family uses the same transformer building blocks but applies a causal mask to the attention layer. That makes it unidirectional. The encoder-decoder family (T5, BART) puts a bidirectional encoder and a unidirectional decoder in the same model: the encoder reads the input both ways, and the decoder generates the output one token at a time while attending to the encoder's bidirectional output.
Why does bidirectionality help for understanding?
The reason bidirectional models work so well on understanding tasks is that the asymmetry between past and future is artificial when the entire input is already in front of the model. A model labeling parts of speech in a fixed sentence has no reason to ignore the right context. A model deciding whether two sentences are paraphrases has both sentences available from the start. A model retrieving a relevant passage for a query knows the entire query before it starts.
In each of these cases, half the available signal is downstream of the position the model is currently processing. A unidirectional model has to either store everything in a single forward state and hope the relevant bits survive, or run two passes and stitch them together (which is, again, just being bidirectional). A bidirectional model gets both sides natively.
The empirical gains are easiest to see in sequence labeling. On the CoNLL-2003 English named entity recognition dataset, a BiLSTM-CRF with character embeddings reached 90.94 F1 in 2016 (Lample et al.), which the authors described as very near the state of the art for English without hand-engineered features or gazetteers; the best reported score, 91.2 F1 from Luo et al. (2015), relied on external knowledge bases.[5] On the same benchmark, a BERT-large model fine-tuned in 2018 reached 92.8 F1, slightly behind the 93.1 F1 the BERT paper lists for contextual string embeddings (Akbik et al., 2018).[7] Bidirectional models also became the standard approach for part-of-speech tagging, semantic role labeling, and question answering.
Why can't generative models be bidirectional?
Bidirectionality is a poor fit when the model is supposed to produce text one token at a time, because the future does not exist yet. A bidirectional model's representation of position was trained assuming access to positions through . At inference time those positions have not been generated. There is no clean way to ask such a model for the next token.
This is why BERT and its descendants, despite their dominance on classification benchmarks, never replaced GPT for free-form generation.[7] People have tried (BERT-Gen, masked iterative refinement, conditional MLM) and for years the results lagged a properly trained autoregressive model. Masked diffusion language models have since narrowed the gap by generating a whole sequence through iterative unmasking instead of left to right: LLaDA (2025) uses a Transformer without a causal mask, and its authors report the 8B model as competitive with LLaMA3 8B on in-context learning.[13]
The encoder-decoder split in T5, BART, and similar models is the standard workaround. The encoder is bidirectional and reads the full input, the decoder is unidirectional and writes the output left to right while attending to the encoder. This gives you the understanding side of bidirectionality without giving up the ability to generate.
What is bidirectionality used for?
Bidirectional models, in one form or another, dominate any task where the input is fully observed and the output is some kind of label, span, or structured prediction over that input.
| Task | Why bidirectional helps | Typical architecture |
|---|---|---|
| Named entity recognition | Entity boundaries depend on surrounding words on both sides | BiLSTM-CRF, BERT |
| Part-of-speech tagging | Word category depends on local context windows | BiLSTM, BERT |
| Semantic role labeling | Argument identification needs the whole predicate-argument structure | BiLSTM, BERT |
| Speech recognition | Phoneme identity depends on surrounding acoustic context | BiLSTM-CTC, Conformer encoder |
| Machine translation (encoder) | Source words need full source-side context for translation | BiGRU encoder, transformer encoder |
| Text classification | Global sentence meaning summarized into a fixed vector | BERT [CLS] token, BiLSTM with pooling |
| Question answering (extractive) | Answer span boundaries depend on both query and surrounding passage | BERT, RoBERTa |
| Sentence embedding | Single vector per sentence, used for retrieval | Sentence-BERT, BGE, E5 |
| Time series anomaly detection | Anomaly score depends on both past and future trend | BiLSTM autoencoder |
| Protein secondary structure prediction | Local fold depends on residues on both sides | BiLSTM, transformer encoder |
| Handwriting recognition | Character identity depends on adjacent strokes in both directions | BiLSTM-CTC |
In some of these cases the bidirectional model is the entire system. In others (machine translation, retrieval-augmented generation) it is one component sitting next to a generator.
How do you implement a bidirectional model?
Both major deep learning frameworks treat bidirectionality as a flag rather than a separate class.
In PyTorch, the recurrent modules accept a bidirectional=True argument. A bidirectional LSTM is just nn.LSTM(input_size, hidden_size, bidirectional=True). The output tensor at each timestep has shape (seq_len, batch, 2 * hidden_size), with the forward direction in the first hidden_size slots and the backward direction in the last hidden_size slots.[9] The final hidden state h_n has shape (2 * num_layers, batch, hidden_size), with directions interleaved by layer. A common gotcha, flagged in the documentation, is that h_n is not the same as the last element of output: h_n holds the final forward and final reverse hidden states, while the last element of output holds the final forward hidden state and the initial reverse hidden state (the reverse direction's state after reading only the last timestep).[9]
In TensorFlow and Keras, bidirectionality is done through a wrapper layer: keras.layers.Bidirectional(keras.layers.LSTM(units)). The wrapper takes any RNN layer (LSTM, GRU, SimpleRNN, or a custom one) and produces a bidirectional version. A merge_mode argument controls how the forward and backward outputs are combined: the default is concat, but sum, mul, ave, and None (return both as a list) are available. A backward_layer argument lets the user pass a different layer for the reverse direction if the two should not share architecture.[10]
For transformer encoders, bidirectionality is implicit. There is no special flag because the encoder simply does not apply a causal mask. The Hugging Face transformers library treats this as part of the model class: BertModel, RobertaModel, and DebertaV2Model are bidirectional encoders, while GPT2Model and LlamaModel are causal decoders. The attention computation is essentially the same in both (each model class implements its own attention module rather than PyTorch's nn.MultiheadAttention); the difference is whether a causal mask of upper-triangular -inf values is applied.
What are the limitations of bidirectional models?
Bidirectional models give up some things in exchange for the contextual gains.
The most fundamental loss is generation. As discussed above, a model trained to use both-side context cannot be used as an autoregressive generator without either accepting a quality drop or layering on a separate causal model. Architectures that need to do both (like sequence-to-sequence translation) end up being hybrids.
Bidirectional attention has a quadratic cost in sequence length. A transformer encoder with full bidirectional self-attention has to compute an n by n attention matrix at every layer. For sequences of a few hundred tokens that is fine. For sequences of tens of thousands of tokens it becomes the bottleneck. Long-context variants recover near-linear cost (Longformer and BigBird sparsify the attention pattern, while Performer approximates it with random features), but they pay for it with weaker or approximate bidirectional context. Causal transformers have the same quadratic issue, but the lower-triangular mask makes some optimizations (like KV caching during generation) easier.
Masked language model pretraining introduces a small pretrain-finetune mismatch. The [MASK] token appears during pretraining but never at inference time. BERT mitigates this by replacing only 80 percent of selected tokens with [MASK], 10 percent with random tokens, and 10 percent unchanged, but the gap is not fully closed.[7] ELECTRA's replaced-token detection objective and XLNet's permutation language model were both designed in part to avoid this mismatch.
Bidirectional RNNs need the entire input before they can produce any output, because the backward pass starts from the end. That makes them awkward for streaming applications where data arrives one frame at a time and predictions are needed with low latency. Streaming speech recognition systems often use unidirectional or chunked-bidirectional variants for this reason.
How does bidirectional compare with unidirectional and hybrid models?
The big picture is a three-way split rather than a binary one.
| Property | Unidirectional (GPT, causal LSTM) | Bidirectional (BERT, BiLSTM) | Hybrid encoder-decoder (T5, BART) |
|---|---|---|---|
| Sees future tokens | No | Yes | Yes (encoder side only) |
| Can generate token by token | Yes | No | Yes (decoder generates) |
| Best for | Free-form generation, chat, code | Classification, tagging, retrieval | Translation, summarization, QA |
| Pretraining objective | Next-token prediction | Masked language model or denoising | Span corruption, denoising |
| Inference cost | Linear in output length | One forward pass over input | Encoder once, decoder per token |
| Well-known examples | GPT-4, Llama | RoBERTa, DeBERTa, sentence-transformers | T5, BART, FLAN-T5 |
In the modern LLM era the visible part of the field is dominated by the unidirectional column. Decoder-only generative models are what people interact with when they use a chatbot. The bidirectional column is quieter but still huge. A large share of the embedding models, rerankers, retrieval systems, and text classifiers in production descend from BERT. Sentence-transformers, the original BGE and E5 models, and ColBERT all use bidirectional encoders. The MTEB embedding leaderboard is more mixed: recent leaders include embedding models built on decoder LLMs, and some keep causal attention. Qwen3 Embedding, which reported a state-of-the-art 70.58 on MTEB Multilingual in June 2025, takes its embedding from the final [EOS] token of an LLM with causal attention.[14] When a chatbot retrieves documents to answer a question, the chatbot itself is unidirectional, but the retriever is often a bidirectional encoder.
Explain like I'm 5
Imagine you are filling in a crossword puzzle. To figure out a word in the middle, you look at the letters on both sides of the empty squares: some come from the across clue you already solved, and some come from the down clues. You use both directions of context at once.
That is what a bidirectional model does. When it tries to understand the word "bat" in a sentence, it looks at the words before it and the words after it. If "flapping" came earlier and "cave" comes later, it knows the bat has wings. If "swung" came earlier and "baseball" comes later, it knows the bat is for hitting balls.
This works great for understanding sentences, but it does not work for writing them. To write a story one word at a time, you cannot peek at the words you have not written yet, because they do not exist. So bidirectional models are champions of reading and unidirectional models are champions of writing. The biggest modern systems often use both, with one reading the input and the other writing the answer.
Continue reading
- BERTBERT, short for Bidirectional Encoder Representations from Transformers, is a pretrained language model introduced by researchers at Google Research in 2018.Mentioned 24 times above
- TransformersA Transformer is a deep learning architecture, introduced by eight Google researchers in the 2017 paper "Attention Is All You Need", that uses attention as the sole mechanism for modeling relationships between…Mentioned 20 times above
- Long Short-Term Memory (LSTM)Long short-term memory (LSTM) is a gated recurrent neural network architecture for processing sequences.Mentioned 19 times above
- Recurrent Neural NetworkA recurrent neural network (RNN) is a neural network whose computation includes a state that is passed from one step to the next.Mentioned 8 times above
- Sequence ModelA sequence model is a class of machine learning models that processes, generates, or predicts ordered data where the position and surrounding context of each element carry meaning.Mentioned 3 times above
- Deep LearningDeep learning is a subset of machine learning that uses artificial neural networks with multiple layers to automatically learn representations of data at multiple levels of abstractionMentioned twice above
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6Schuster, M., & Paliwal, K. K. (1997). "Bidirectional recurrent neural networks." *IEEE Transactions on Signal Processing*, 45(11), 2673-2681.
- ^1 ^2 ^3Graves, A., & Schmidhuber, J. (2005). "Framewise phoneme classification with bidirectional LSTM and other neural network architectures." *Neural Networks*, 18(5-6), 602-610.
- ^1 ^2Cho, K., van Merrienboer, B., Gulcehre, C., Bahdanau, D., Bougares, F., Schwenk, H., & Bengio, Y. (2014). "Learning Phrase Representations using RNN Encoder-Decoder for Statistical Machine Translation." arXiv:1406.1078.
- ^1 ^2Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017). "Attention Is All You Need." *NeurIPS 2017*. arXiv:1706.03762.
- ^Lample, G., Ballesteros, M., Subramanian, S., Kawakami, K., & Dyer, C. (2016). "Neural Architectures for Named Entity Recognition." *Proceedings of NAACL-HLT 2016*, pages 260-270. arXiv:1603.01360.
- ^Peters, M. E., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., & Zettlemoyer, L. (2018). "Deep contextualized word representations." *Proceedings of NAACL-HLT 2018*. arXiv:1802.05365.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018). "BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding." arXiv:1810.04805.
- ^Bradbury, J., Merity, S., Xiong, C., & Socher, R. (2017). "Quasi-Recurrent Neural Networks." *ICLR 2017*. arXiv:1611.01576.
- ^1 ^2PyTorch Contributors. "LSTM PyTorch documentation." docs.pytorch.org/...torch.nn.LSTM.
- ^Keras Team. "Bidirectional layer." Keras API reference. keras.io/...bidirectional.
- ^Wikipedia contributors. "Bidirectional recurrent neural networks." *Wikipedia, The Free Encyclopedia*. en.wikipedia.org/...onal_recurrent_neural_networks.
- ^1 ^2Bahdanau, D., Cho, K., & Bengio, Y. (2014). "Neural Machine Translation by Jointly Learning to Align and Translate." *ICLR 2015*. arXiv:1409.0473.
- ^Nie, S., Zhu, F., You, Z., Zhang, X., Ou, J., Hu, J., Zhou, J., Lin, Y., Wen, J.-R., & Li, C. (2025). "Large Language Diffusion Models." arXiv:2502.09992.
- ^Zhang, Y., Li, M., Long, D., Zhang, X., et al. (2025). "Qwen3 Embedding: Advancing Text Embedding and Reranking Through Foundation Models." arXiv:2506.05176.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
10 revisions · v10 · 3,808 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (72 claims, 19 sources fetched); 8 material + 14 minor fixed
Cite this page: AI Wiki. "Bidirectional." aiwiki.ai, updated 28 Oct 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/bidirectional