

BoolQ
BoolQ (Boolean Questions) is a natural language processing benchmark dataset of 15,942 naturally occurring yes/no question answering examples, each pairing a real Google search query with a Wikipedia passage and a True/False answer [1]. It was introduced in the 2019 paper "BoolQ: Exploring the Surprising Difficulty of Natural Yes/No Questions" by Christopher Clark, Kenton Lee, Ming-Wei Chang, Tom Kwiatkowski, Michael Collins, and Kristina Toutanova (Clark of the University of Washington, working as a Google intern, and the others of Google AI Language), published at the Conference of the North American Chapter of the Association for Computational Linguistics (NAACL 2019) and released as arXiv:1905.10044 [1]. BoolQ is one of the eight tasks in the SuperGLUE benchmark, and the original paper reported that the best model reached 80.4% accuracy against 90% for human annotators, leaving a clear gap that made the dataset a standard test of reading comprehension and inference for language models [1][2].
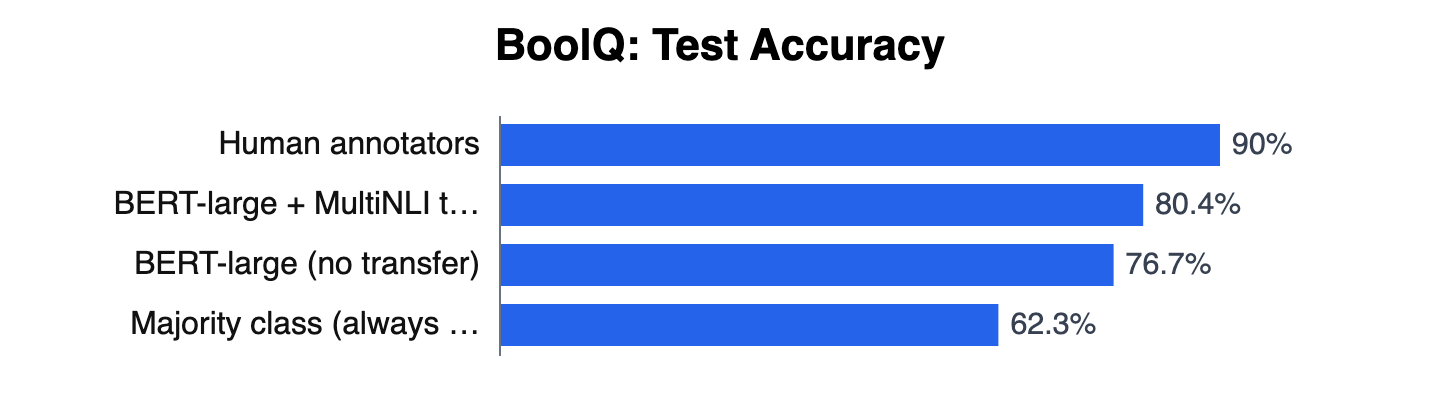
The paper's central, oft-quoted claim is that yes/no questions drawn from real users are deceptively hard. As the abstract states: "They often query for complex, non-factoid information, and require difficult entailment-like inference to solve" [1]. This is why the work is titled around the "surprising difficulty" of a task that sounds trivial.
What is BoolQ?
BoolQ is a reading-comprehension dataset for yes/no questions. Each example gives a model a short Wikipedia paragraph (the evidence passage) and a single yes/no question, and the model must output a boolean answer (yes/True or no/False) supported by that passage [1]. Unlike extractive datasets that ask a model to highlight a text span, BoolQ requires the model to reduce the entire passage to one bit of information, which often demands inference rather than copying [1].
The dataset was built by Google AI Language researchers and contains 15,942 examples in total [1]. Because the questions come from anonymized search logs rather than from annotators following instructions, they reflect genuine information needs and a wide spread of difficulty [1].
Background and Motivation
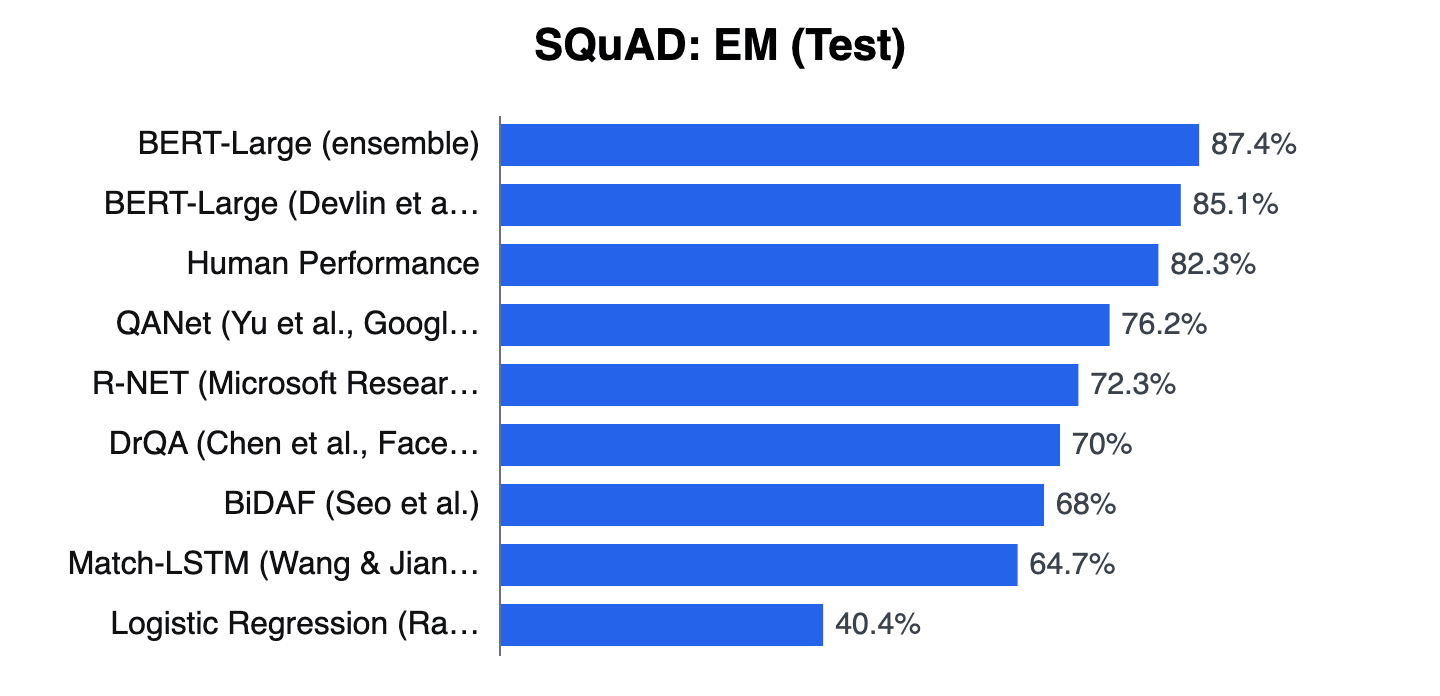
Yes/no questions represent one of the most common forms of information-seeking behavior. When people search the web, a significant portion of their queries can be answered with a simple "yes" or "no." Despite this prevalence, yes/no question answering received relatively little attention in NLP research prior to BoolQ. Most reading comprehension benchmarks, such as SQuAD, focused on extractive question answering, where models must identify a text span that answers the question. Other benchmarks tested natural language inference through artificially constructed sentence pairs.
The authors of BoolQ observed that naturally occurring yes/no questions present a different and often more difficult challenge than extractive QA or synthetic inference tasks. When people ask yes/no questions in real search scenarios, the questions tend to be more complex, requiring reasoning beyond simple word matching or paraphrase detection [1]. This observation motivated the creation of a dedicated benchmark that could capture the true difficulty of boolean question answering in a naturalistic setting.
Before BoolQ, yes/no questions were sometimes treated as a byproduct of other tasks or filtered out entirely from QA datasets. The BoolQ paper demonstrated that these questions deserve focused study because they require a distinct combination of reading comprehension, inference, and world knowledge [1].
How was BoolQ built?
Data Collection Pipeline
BoolQ follows a data collection pipeline adapted from Google's Natural Questions (NQ) project [1][8]. The process begins with anonymized, aggregated queries submitted to the Google search engine. From this pool of real user queries, the researchers applied heuristic filters to identify queries that are likely to be yes/no questions. This approach differs from many other NLP benchmarks where annotators are prompted to write questions, because BoolQ's questions reflect genuine information needs rather than researcher-designed tasks [1].
The key steps in the data collection process are:
-
Query sampling: Anonymized search queries were sampled from Google's search logs. These represent real questions that actual users typed into the search engine.
-
Yes/no filtering: Heuristic rules were applied to identify queries that can be interpreted as yes/no questions. Questions typically begin with words like "is," "are," "do," "does," "can," "was," "will," and similar auxiliaries.
-
Search-result filtering and question review: A question was kept only if a Wikipedia page was among the first five search results. An annotator then judged, before seeing the page, whether the question was comprehensible, unambiguous, and requesting factual information [1].
-
Passage selection: For good questions, the annotator found a passage in that Wikipedia page containing enough information to answer the question, or marked it "not answerable" [1].
-
Answer annotation: Human annotators read the selected passage and provided a boolean answer (yes or no) to the question based on the passage content.
Annotation Process
The annotation process involved human workers who reviewed each question-passage pair. Each question was labeled by a single annotator. To check quality, three of the authors labeled 110 randomly chosen examples, resolving disagreements by mutual agreement; the crowd annotations matched these gold-standard labels 90% of the time, so the authors kept singly-annotated examples to gather a larger dataset [1]. Each annotated example in BoolQ consists of four fields:
| Field | Type | Description |
|---|---|---|
| question | String | A naturally occurring yes/no question (typically 20 to 100 characters) |
| passage | String | A paragraph from a Wikipedia article (typically 35 to 4,720 characters) |
| answer | Boolean | True (yes) or False (no) |
| title | String | The title of the Wikipedia article (optional additional context) |
The use of real search queries rather than researcher-prompted questions is a defining characteristic of BoolQ. By sampling from actual information-seeking behavior, the dataset captures a wider range of question complexity and topic diversity than datasets built through crowdsourcing prompts alone [1].
Dataset Statistics
How big is BoolQ and how is it split?
The full BoolQ dataset contains 15,942 examples divided into three splits [1]:
| Split | Examples | Labels |
|---|---|---|
| Training | 9,427 | Provided |
| Development (validation) | 3,270 | Provided |
| Test | 3,245 | Withheld |
The training and development splits are publicly available with labeled answers. The test split answers are withheld and used for official evaluation through the SuperGLUE leaderboard [1][2].
Answer Distribution
The dataset has a moderately imbalanced answer distribution. Approximately 62% of the answers are "yes" (True), while 38% are "no" (False) [1]. This means a naive baseline that always predicts "yes" would achieve 62% accuracy, establishing the majority-class baseline for the task [1].
Question Characteristics
The questions in BoolQ cover a wide range of topics drawn from Wikipedia, including geography, history, science, entertainment, sports, law, and technology. Common question patterns include:
- "Is [X] the same as [Y]?"
- "Do [X] speak [language]?"
- "Can [X] do [Y]?"
- "Was [X] based on [Y]?"
- "Does [X] have [property]?"
- "Is [X] a type of [Y]?"
Example Questions
The following table shows representative examples from the BoolQ dataset:
| Question | Passage (excerpt) | Answer |
|---|---|---|
| Do Iran and Afghanistan speak the same language? | Persian, also known by its endonym Farsi, is one of the Western Iranian languages... It is primarily spoken in Iran, Afghanistan (officially known as Dari since 1958), and Tajikistan... | Yes |
| Is Harry Potter and the Escape from Gringotts a roller coaster ride? | Harry Potter and the Escape from Gringotts is an indoor steel roller coaster... at Universal Studios Florida... | Yes |
| Does ethanol take more energy to make than it produces? | The total amount of energy input into the process compared to the energy released by burning the resulting ethanol fuel is known as the energy balance... Figures compiled in a 2007 report by National Geographic Magazine point to modest results for corn ethanol produced in the US: one unit of fossil-fuel energy is required to create 1.3 energy units from the resulting ethanol... | No |
| Is Elder Scrolls Online the same as Skyrim? | As with other games in The Elder Scrolls series, the game is set on the continent of Tamriel. The events of the game occur a millennium before those of The Elder Scrolls V: Skyrim... | No |
| Is France the same timezone as the UK? | In September 1945, Metropolitan France returned to GMT+1 (pre-war summer time)... Metropolitan France was officially scheduled to return to GMT+0 on November 18, 1945 (the British returned to GMT+0 in on October 7, 1945), but the French government canceled the decision... and GMT+1 has since then remained the official time of Metropolitan France. | No |
These examples illustrate several properties of BoolQ questions. Some can be answered by straightforward paraphrase detection (the roller coaster question). Others require multi-step reasoning, background knowledge, or careful interpretation of the passage (the ethanol question).
Why is BoolQ surprisingly hard?
One of the central findings of the BoolQ paper is that naturally occurring yes/no questions are significantly more difficult than expected [1]. In the authors' words, the questions "often query for complex, non-factoid information, and require difficult entailment-like inference to solve" [1]. To quantify this, the authors performed a manual analysis of question types and found the following distribution of reasoning requirements:
| Reasoning Type | Percentage | Description |
|---|---|---|
| Paraphrase | 38.7% | The answer can be determined by matching or rephrasing words between the question and passage |
| By Example | 11.8% | The passage gives an example or counter-example to what the question asserts |
| Factual Reasoning | 8.5% | World knowledge is needed to connect what the passage states to the question |
| Implicit | 8.5% | The passage describes the question's entities in a way that would not make sense if the answer were otherwise |
| Missing Mention | 6.6% | The answer follows because, if it were otherwise, the passage would have mentioned it |
| Other Inference | 25.9% | The passage states a fact from which the answer can be inferred, outside the other categories |
Only 38.7% of the questions can be answered through simple paraphrase matching between the question and passage [1]. The remaining 61.3% require more complex reasoning, including reasoning from examples, world knowledge, other inferences, and subtler inferences from how the passage is written [1]. This distribution explains why BoolQ is more challenging than many natural language inference benchmarks, where surface-level pattern matching can achieve higher accuracy.
The difficulty of BoolQ questions stems from their natural origin. When people ask yes/no questions in a search engine, they are not constrained by instructions from researchers. Their questions reflect genuine uncertainty and often involve nuanced relationships that cannot be resolved by simple keyword overlap.
Evaluation
Metric
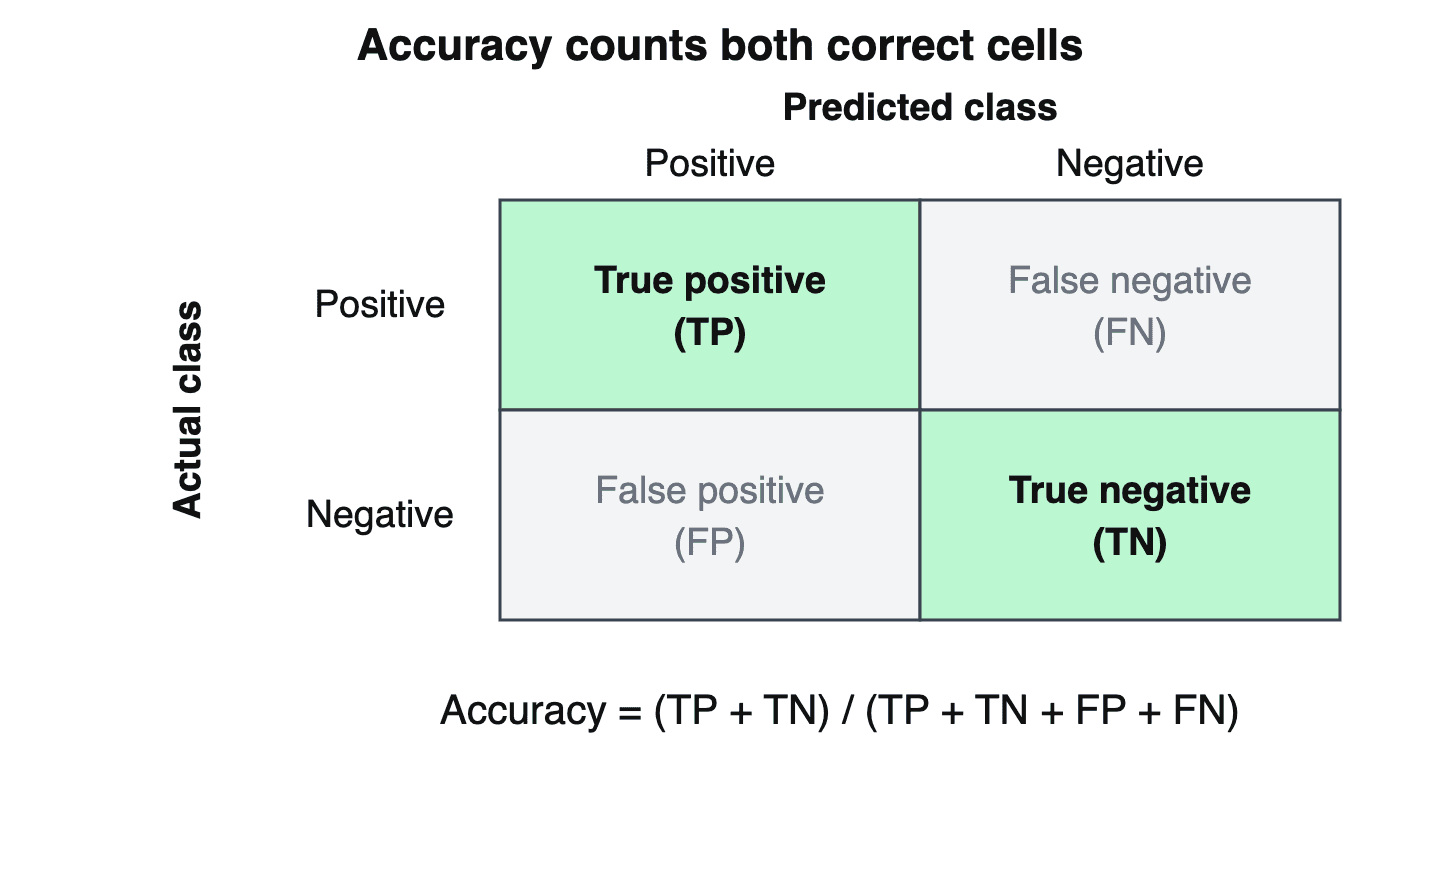
BoolQ uses accuracy as its sole evaluation metric [1][2]. Each prediction is either correct (matching the gold-standard boolean answer) or incorrect. The overall accuracy is computed as the percentage of correctly answered questions in the evaluation set.
What accuracy did the original BoolQ models reach?
The original BoolQ paper (Clark et al., 2019) established several baselines [1]:
| Model / Baseline | Dev Accuracy | Test Accuracy |
|---|---|---|
| Majority class (always "yes") | 62.2% | 62.3% |
| BERT-large (no transfer) | 78.1% | 76.7% |
| BERT-large + MultiNLI transfer | 82.2% | 80.4% |
| Human annotators | -- | 90.0% |
The majority-class baseline of 62% reflects the answer imbalance in the dataset [1]. BERT-large [3], when trained only on BoolQ data, achieved substantially higher accuracy, but still lagged well behind human performance. The best configuration in the original paper used a two-stage transfer learning approach: first fine-tuning BERT-large on the MultiNLI entailment dataset, then further fine-tuning on BoolQ training data. As the authors summarized, "Our best method trains BERT on MultiNLI and then re-trains it on our train set. It achieves 80.4% accuracy compared to 90% accuracy of human annotators (and 62% majority-baseline), leaving a significant gap for future work" [1]. That 80.4% test result sits 9.6 percentage points below the 90% human ceiling [1].
The 90% human figure measures how often the dataset's single-annotator answers matched gold labels that three of the authors assigned to 110 randomly chosen examples; of the 11 mismatches, six were ambiguous or debatable cases and five were annotator errors [1]. This lower agreement rate reflects the genuine ambiguity and difficulty present in naturally occurring yes/no questions.
Transfer Learning Findings
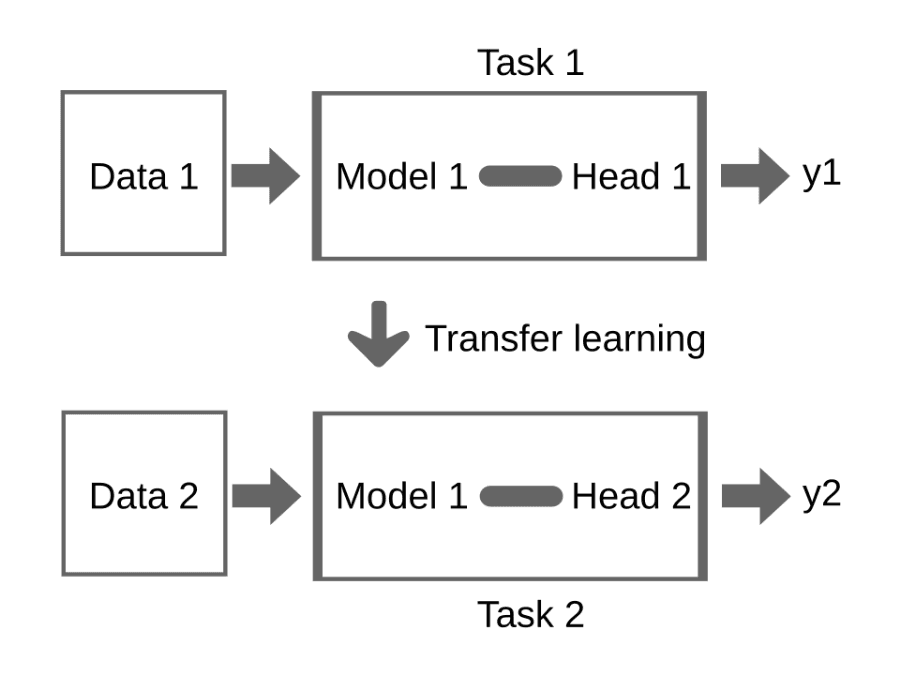
A major contribution of the BoolQ paper is its systematic study of transfer learning for boolean question answering [1]. The authors experimented with transferring knowledge from several related NLP tasks before fine-tuning on BoolQ (gains below are dev-set accuracy for the paper's recurrent model, against 69.60% with no transfer) [1]:
| Source Task | Dataset | Task Type | Accuracy Improvement |
|---|---|---|---|
| Entailment | MultiNLI | Natural language inference | Highest: +6.0 points (75.57%); about +3.5 points on top of BERT-large |
| Entailment | SNLI | Natural language inference | +3.6 points (73.16%) |
| Extractive QA | SQuAD 2.0 | Span extraction (converted to entailment-style pairs) | None (69.83%) |
| Extractive QA | QNLI | Sentence-pair classification | +1.8 points (71.36%) |
| Extractive QA | Natural Questions long answer | Paragraph selection | +3.2 points (72.78%) |
| Multiple-choice QA | RACE | Reading comprehension | None (68.40%, below baseline) |
| Paraphrase | QQP | Paraphrase detection | +1.7 points (71.30%) |
| Heuristic yes/no | Y/N MS Marco | Yes/no QA | +1.8 points (71.40%) |
The key findings from these experiments include:
-
Entailment transfer is most effective: Pre-training on the MultiNLI entailment dataset before fine-tuning on BoolQ yielded the largest accuracy gains [1]. This suggests that yes/no question answering shares deeper structural similarities with natural language inference than with extractive question answering.
-
Transfer from extractive QA helps less: Despite the superficial similarity between reading comprehension tasks, QNLI and Natural Questions gave only a few points of transfer, and SQuAD 2.0 and RACE gave none [1]. This indicates that the reasoning processes involved in yes/no questions differ from those in span extraction.
-
Transfer benefits persist with large models: Even when starting from BERT-large, which already encodes substantial linguistic knowledge through pre-training, additional task-specific transfer from MultiNLI continued to provide significant improvements [1]. The authors described this as "surprisingly" beneficial "even when starting from massive pre-trained language models such as BERT" [1].
-
Paraphrase transfer helps only a little: Transferring from QQP gave a small gain of about 1.7 points, in line with the abstract's finding that entailment data transfers better than paraphrase or extractive QA data [1].
These results have practical implications for building yes/no QA systems. They suggest that training pipelines for boolean question answering should include an intermediate stage of entailment training before task-specific fine-tuning.
How does BoolQ fit into SuperGLUE?
BoolQ is one of eight tasks in the SuperGLUE benchmark, which was introduced by Wang et al. (2019) as a successor to the GLUE benchmark [2]. SuperGLUE was designed to present more difficult language understanding challenges after several models had surpassed human performance on the original GLUE benchmark [2].
SuperGLUE Tasks
The eight tasks in SuperGLUE are [2]:
| Task | Type | Metric |
|---|---|---|
| BoolQ | Yes/no question answering | Accuracy |
| CB (CommitmentBank) | Natural language inference (3-class) | F1 / Accuracy |
| COPA | Causal reasoning | Accuracy |
| MultiRC | Multi-sentence reading comprehension | F1 / Exact Match |
| ReCoRD | Reading comprehension with commonsense | F1 / Exact Match |
| RTE | Textual entailment | Accuracy |
| WiC | Word sense disambiguation | Accuracy |
| WSC (Winograd Schema Challenge) | Coreference resolution | Accuracy |
BoolQ was selected for SuperGLUE because it met several criteria: it presents a meaningful gap between model and human performance, it tests a distinct form of language understanding (boolean QA), and it provides enough training data to support supervised learning approaches while remaining difficult [2].
SuperGLUE Baseline Results on BoolQ
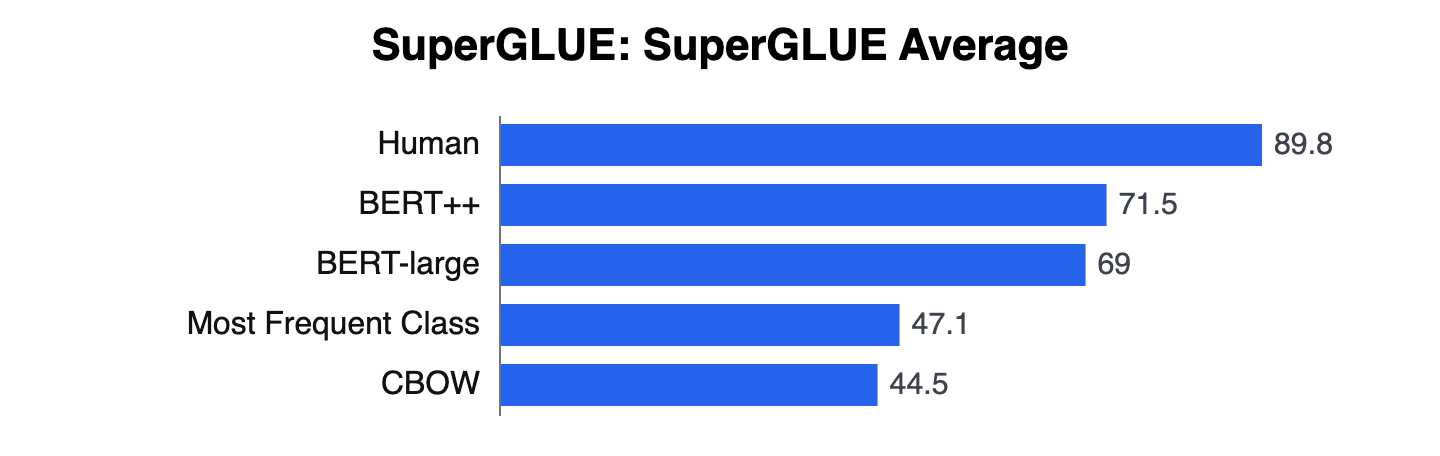
In the original SuperGLUE paper, baseline models were evaluated on all eight tasks. The BoolQ results were [2]:
The gap between BERT-large++ and human performance on BoolQ was approximately 10 points, which was among the smaller gaps in SuperGLUE [2]. Other tasks like WSC had gaps of 35 points [2]. Still, the BoolQ gap represented a significant challenge that motivated years of subsequent research.
Progress on BoolQ
Model Performance Over Time
Since BoolQ's introduction in 2019, a series of increasingly powerful models have narrowed and eventually closed the gap with human performance. The following table summarizes notable results:
| Model | Year | BoolQ Accuracy | Parameters | Notes |
|---|---|---|---|---|
| BERT-large + MultiNLI | 2019 | 80.4% | 340M | Original paper best result [1] |
| RoBERTa | 2019 | 87.1% | 355M | Improved pre-training approach; SuperGLUE test result [4] |
| ALBERT xxlarge | 2019 | Not reported | 235M | The ALBERT paper reports GLUE, SQuAD and RACE but no BoolQ score [7] |
| T5-11B | 2020 | 91.2% | 11B | Text-to-text framework [5] |
| DeBERTa (single model) | 2021 | 90.4% | 1.5B | Disentangled attention [4] |
| DeBERTa (ensemble) | 2021 | 90.4% | 1.5B x N | Topped SuperGLUE in January 2021 with 90.3 overall versus 89.8 human [4] |
| GPT-3 (few-shot) | 2020 | 76.4% | 175B | 32-shot, no fine-tuning (test set); 60.5% zero-shot on dev [12] |
| GPT-4 | 2023 | Not reported | Unknown | OpenAI's GPT-4 technical report gives no BoolQ score |
Several trends are apparent in this progression:
-
Pre-training improvements matter: Models like RoBERTa, which used improved pre-training procedures compared to BERT, achieved large gains on BoolQ (87.1% on the SuperGLUE test set) without changing the fundamental architecture [4][6].
-
Scale helps but is not everything: T5-11B with 11 billion parameters achieved approximately 91% accuracy, but DeBERTa with 1.5 billion parameters reached comparable accuracy through architectural innovations like disentangled attention [4][5]. Meanwhile, GPT-3 with 175 billion parameters performed relatively poorly in zero-shot and few-shot settings without task-specific fine-tuning.
-
Human parity achieved: By 2020-2021, the best fine-tuned models had matched or exceeded the 89-90% human accuracy baseline on BoolQ. Around the turn of 2021, Microsoft's DeBERTa became the first model to surpass the human baseline on the overall SuperGLUE score (89.9 for the single model as of December 29, 2020, and 90.3 for the ensemble as of January 6, 2021, versus 89.8), with BoolQ being one of the contributing tasks [4].
Open-Source Model Results
As of November 2026, the LLM Stats leaderboard lists 11 developer-reported BoolQ scores, the top of which are [11]:
| Model | Developer | BoolQ Score |
|---|---|---|
| Hermes 3 405B | Nous Research | 0.889 |
| Hermes 3 70B | Nous Research | 0.880 |
| Gemma 2 27B | 0.848 | |
| Phi-3.5-MoE-instruct | Microsoft | 0.846 |
| Gemma 2 9B | 0.842 | |
| Phi 4 Mini | Microsoft | 0.812 |
| Phi-3.5-mini-instruct | Microsoft | 0.780 |
These are unverified, developer-reported scores under varying setups (for example, 0-shot for Hermes 3 and Gemma 2), not fine-tuned results, which helps explain why they are lower than the fine-tuned results on the SuperGLUE leaderboard [11].
Dataset Format and Access
Data Format
BoolQ examples are stored in JSON Lines (JSONL) format. Each line contains a single JSON object with the following structure:
{
  "question": "do iran and afghanistan speak the same language",
  "passage": "Persian (/ˈpɜːrʒən, -ʃən/), also known by its endonym Farsi...",
  "answer": true,
  "title": "Persian language"
}
Loading with Hugging Face Datasets
The dataset can be loaded using the Hugging Face Datasets library:
from datasets import load_dataset

dataset = load_dataset("google/boolq")

# Access splits
train_set = dataset["train"]      # 9,427 examples
val_set = dataset["validation"]   # 3,270 examples

# View an example
print(dataset["train"][0])
Is BoolQ free to use? Availability and license
BoolQ is available through multiple channels:
| Source | URL |
|---|---|
| GitHub (official) | https://github.com/google-research-datasets/boolean-questions |
| Hugging Face | https://huggingface.co/datasets/google/boolq |
| TensorFlow Datasets | Available as bool_q in TFDS |
| SuperGLUE | Included in the SuperGLUE download |
The dataset is released under the Creative Commons Attribution-ShareAlike 3.0 (CC BY-SA 3.0) license, allowing free use with proper attribution and share-alike requirements [10].
How does BoolQ compare to other benchmarks?
BoolQ occupies a specific niche among NLP benchmarks. The following table compares it with related datasets:
| Benchmark | Task Type | Question Source | Answer Format | Size |
|---|---|---|---|---|
| BoolQ | Yes/no QA | Google search queries | Boolean (yes/no) | 15,942 |
| SQuAD | Extractive QA | Crowdsourced | Text span | 100,000+ |
| Natural Questions | Open-domain QA | Google search queries | Text span / yes-no / null | 300,000+ |
| MultiNLI | Natural language inference | Crowdsourced | Entailment / contradiction / neutral | 433,000 |
| GLUE benchmark | Multi-task NLU | Various | Various | ~950,000 training examples [13] |
| SuperGLUE | Multi-task NLU | Various | Various | ~125,000 training examples (101,000 from ReCoRD) [2] |
Relationship to Natural Questions
BoolQ shares its data collection methodology with Google's Natural Questions (NQ) dataset [1][8]. Both datasets start from real Google search queries and pair them with Wikipedia content. The difference is that BoolQ specifically filters for yes/no questions, while NQ includes a broader range of question types with extractive answers [8]. Some yes/no questions in NQ overlap conceptually with BoolQ, but the datasets were collected and annotated independently.
Comparison with NLI Tasks
BoolQ is often compared to natural language inference (NLI) tasks like MultiNLI and SNLI [9]. Like NLI, BoolQ involves determining whether a hypothesis (the question's implied statement) is supported by a premise (the passage). However, there are important differences:
- Question format: BoolQ uses natural yes/no questions rather than declarative sentence pairs.
- Naturalness: BoolQ questions come from real search behavior, while NLI datasets typically use crowdsourced sentence pairs.
- Difficulty: BoolQ questions tend to be more challenging because they were not designed to be easily answerable [1].
The strong transfer learning results from MultiNLI to BoolQ confirm the structural relationship between these tasks while also highlighting BoolQ's distinct challenges [1].
What is BoolQ used for?
BoolQ is used in several contexts within the NLP community:
Model Evaluation
BoolQ is commonly included in evaluation suites for large language models. It tests a model's ability to read a passage and determine whether a specific claim is supported. This makes it useful for assessing reading comprehension, factual reasoning, and inference capabilities.
Transfer Learning Research
The transfer learning findings from the original BoolQ paper have influenced how researchers approach multi-task learning and sequential fine-tuning [1]. The discovery that entailment pre-training benefits boolean QA has been applied to other task combinations.
Few-Shot and Zero-Shot Evaluation
With the rise of large language models like GPT-3 and GPT-4, BoolQ has been used to test few-shot and zero-shot capabilities. In these evaluations, models are given a few examples (or none) and must answer BoolQ questions without task-specific training. Performance in this setting is generally lower than fine-tuned performance, but it provides a measure of a model's general reasoning ability.
Robustness and Bias Testing
Researchers have used BoolQ to study model robustness, including sensitivity to question phrasing, passage length, and answer distribution. The dataset's natural origin makes it useful for testing whether models can handle the kind of variation found in real-world queries.
Limitations and Criticisms
While BoolQ has been widely adopted, it has several known limitations:
Language and Source Constraints
BoolQ contains only English-language questions and passages sourced exclusively from English Wikipedia [1]. This limits its applicability to evaluating multilingual models or models intended for domains not well covered by Wikipedia.
Answer Imbalance
The 62/38 split between "yes" and "no" answers introduces a class imbalance [1]. Models that learn to exploit this bias can achieve above-chance accuracy without genuine comprehension. Researchers must account for this imbalance when interpreting accuracy scores.
Passage Dependence
Each question is paired with a single Wikipedia passage. In some cases, the passage may not contain all information needed to definitively answer the question, or additional context from other sources might change the answer. This single-passage setup does not capture the full complexity of real-world information retrieval, where a user might consult multiple sources.
Human Ceiling
The 90% human accuracy comes from a 110-example check against author gold labels, and the authors judged six of the eleven mismatches to be ambiguous or debatable [1]. While this partly reflects genuine question difficulty, it also suggests that some questions may be inherently ambiguous or that the passage-question pairing introduces occasional mismatches. For questions where annotators disagreed, the "correct" answer may not always be clear-cut.
Benchmark Saturation
As of the early 2020s, state-of-the-art models have matched or surpassed human performance on BoolQ [4]. This "benchmark saturation" means BoolQ is no longer an effective discriminator among top-performing models, although it remains useful for evaluating mid-range models and for ablation studies.
Limited Reasoning Annotations
BoolQ does not include annotations for the type of reasoning required to answer each question. While the paper provides aggregate statistics (38.7% paraphrase, etc.), individual question-level reasoning labels are not part of the dataset, making fine-grained error analysis more difficult [1].
Influence and Legacy
BoolQ has had a substantial impact on the NLP research community since its introduction in 2019. As of 2025, the original paper has accumulated over 700 citations according to Semantic Scholar, reflecting its widespread use in model evaluation and benchmark design.
Several aspects of BoolQ's design have influenced subsequent work:
-
Natural question sourcing: BoolQ's use of real search queries rather than crowdsourced questions has been adopted by other benchmark designers who recognize that naturally occurring data produces more challenging and representative evaluations [1].
-
Transfer learning analysis: The systematic comparison of transfer sources (entailment vs. extractive QA vs. paraphrase) provided a template for studying how different pre-training tasks benefit downstream performance [1].
-
SuperGLUE contribution: As a component of SuperGLUE, BoolQ helped establish a new standard for NLU evaluation that lasted until models surpassed human performance on the benchmark in 2021 [2][4].
-
Yes/no QA as a research focus: BoolQ helped legitimize yes/no question answering as a distinct area of study within NLP, leading to follow-up work on boolean questions, unanswerable yes/no questions, and multi-domain yes/no QA [1].
Technical Details for Practitioners
Evaluation Setup
When evaluating models on BoolQ, the standard setup is:
- Input: Concatenate the passage and question, separated by a special token (e.g., [SEP] for BERT-family models).
- Output: A binary classification over {True, False} or equivalently {Yes, No}.
- Metric: Report accuracy on the development set for analysis and on the test set for official comparison.
For transformer-based models, the typical approach involves:
[CLS] question [SEP] passage [SEP]
A classification head (usually a linear layer) is applied to the [CLS] token representation to produce the binary prediction.
Few-Shot Prompting
For large language models evaluated in few-shot settings, a common prompt format is:
Passage: [passage text]
Question: [question text]
Answer (yes or no):
Providing 3 to 5 demonstrations before the target question typically improves answer formatting and accuracy. Research has shown that using more few-shot examples can improve the model's robustness in generating answers in the exact correct format.
Common Pitfalls
Practitioners should be aware of several common issues when working with BoolQ:
- Answer format sensitivity: In generative evaluation, models may produce answers like "Yes, because..." or "No, it is not..." rather than a clean "yes" or "no." Evaluation scripts must handle these variations through exact matching or keyword extraction.
- Majority class exploitation: Always compare model accuracy against the 62% majority baseline, not just against random chance (50%) [1].
- Title information: The page title field provides additional context that can improve accuracy. Some evaluation setups include the title while others omit it; results should specify which setup was used.
Continue reading
- AccuracyAccuracy is a classification metric that measures the fraction of predictions a model gets right: the number of correct predictions divided by the total number of predictions.Mentioned 34 times above
- SuperGLUESuperGLUE is a public benchmark for evaluating general-purpose English language understanding in machine learning systems, consisting of eight challenging reasoning and reading-comprehension tasks, two…Mentioned 21 times above
- BERTBERT, short for Bidirectional Encoder Representations from Transformers, is a pretrained language model introduced by researchers at Google Research in 2018.Mentioned 14 times above
- Question answeringQuestion answering (QA) is the task of producing an answer to a question, usually expressed in natural language.Mentioned 10 times above
- Transfer LearningTransfer learning is a family of machine learning methods in which information learned from one source domain or task is used while learning a target domain or task.Mentioned 7 times above
- SQuADSQuAD (the Stanford Question Answering Dataset) is a large-scale reading comprehension benchmark from Stanford University in which a model must answer a question by extracting the exact span of text that…Mentioned 5 times above
More from See also
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32 ^33 ^34 ^35 ^36 ^37 ^38 ^39 ^40 ^41 ^42 ^43 ^44 ^45 ^46 ^47 ^48 ^49 ^50Clark, C., Lee, K., Chang, M.-W., Kwiatkowski, T., Collins, M., & Toutanova, K. (2019). "BoolQ: Exploring the Surprising Difficulty of Natural Yes/No Questions." Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT 2019), pp. 2924-2936. Minneapolis, Minnesota. arXiv:1905.10044. DOI: 10.18653/v1/N19-1300.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12Wang, A., Pruksachatkun, Y., Nangia, N., Singh, A., Michael, J., Hill, F., Levy, O., & Bowman, S. (2019). "SuperGLUE: A Stickier Benchmark for General-Purpose Language Understanding Systems." Advances in Neural Information Processing Systems 32 (NeurIPS 2019). arXiv:1905.00537.
- ^Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019). "BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding." Proceedings of NAACL-HLT 2019, pp. 4171-4186.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8He, P., Liu, X., Gao, J., & Chen, W. (2021). "DeBERTa: Decoding-enhanced BERT with Disentangled Attention." Proceedings of ICLR 2021.
- ^1 ^2Raffel, C., Shazeer, N., Roberts, A., Lee, K., Narang, S., Matena, M., Zhou, Y., Li, W., & Liu, P. J. (2020). "Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer." Journal of Machine Learning Research, 21(140), pp. 1-67.
- ^Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019). "RoBERTa: A Robustly Optimized BERT Pretraining Approach." arXiv:1907.11692.
- ^Lan, Z., Chen, M., Goodman, S., Gimpel, K., Sharma, P., & Soricut, R. (2020). "ALBERT: A Lite BERT for Self-supervised Learning of Language Representations." Proceedings of ICLR 2020.
- ^1 ^2 ^3Kwiatkowski, T., Palomaki, J., Redfield, O., Collins, M., Parikh, A., Alberti, C., Epstein, D., Polosukhin, I., Devlin, J., & Lee, K. (2019). "Natural Questions: A Benchmark for Question Answering Research." Transactions of the Association for Computational Linguistics, 7, pp. 453-466.
- ^Williams, A., Nangia, N., & Bowman, S. (2018). "A Broad-Coverage Challenge Corpus for Sentence Understanding through Inference." Proceedings of NAACL-HLT 2018.
- ^Google Research Datasets. "Boolean Questions." GitHub repository. github.com/...boolean-questions. Accessed March 2026.
- ^1 ^2LLM Stats. "BoolQ Benchmark Leaderboard." llm-stats.com/...boolq (accessed November 2026). 11 self-reported results; top model Hermes 3 405B (0.889); average across all evaluated models: 0.823.
- ^Brown, T. B., et al. (2020). "Language Models are Few-Shot Learners." Advances in Neural Information Processing Systems 33 (NeurIPS 2020). arXiv:2005.14165.
- ^Wang, A., Singh, A., Michael, J., Hill, F., Levy, O., & Bowman, S. R. (2018). "GLUE: A Multi-Task Benchmark and Analysis Platform for Natural Language Understanding." arXiv:1804.07461.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
8 revisions · v8 · 5,209 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (110 claims, 14 sources fetched); 13 material + 16 minor fixed
Cite this page: AI Wiki. "BoolQ." aiwiki.ai, updated 28 Oct 2026, fact-checked 4 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/boolq