

RoBERTa
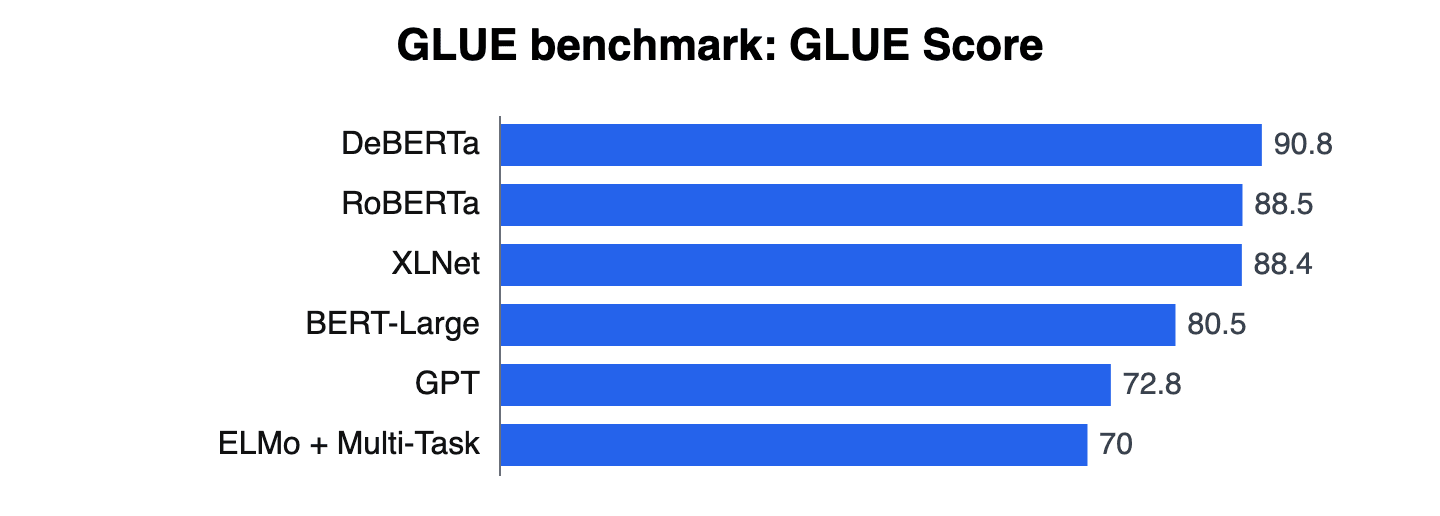
RoBERTa (Robustly Optimized BERT Pretraining Approach) is an open-source natural language processing model released in July 2019 by researchers at Facebook AI (now Meta AI) and the University of Washington that reproduces and retrains BERT with a better recipe and shows BERT was "significantly undertrained."[1] Using the identical transformer encoder architecture as BERT, RoBERTa trains longer on roughly ten times more data (over 160GB of text) with larger batches, drops the next sentence prediction objective, and adds dynamic masking, and as a result it matches or exceeds every model published after BERT at the time, reaching a score of 88.5 on the public GLUE leaderboard.[1] Introduced in the paper "RoBERTa: A Robustly Optimized BERT Pretraining Approach" by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, and Veselin Stoyanov, the work was posted to arXiv on July 26, 2019 (arXiv:1907.11692) and has since accumulated more than 32,000 citations according to Semantic Scholar (November 2026), making it one of the most referenced works in modern NLP.[13]
The paper's central conclusion is stated plainly in its abstract: "We find that BERT was significantly undertrained, and can match or exceed the performance of every model published after it."[1] In other words, RoBERTa's gains came not from a new architecture but from a better training procedure applied to the same model.
Quick facts
| Attribute | Value |
|---|---|
| Full name | Robustly Optimized BERT Pretraining Approach |
| Type | Bidirectional transformer encoder (encoder-only) |
| Developer | Facebook AI Research; University of Washington |
| Released | July 26, 2019 (arXiv:1907.11692) |
| Architecture | Identical to BERT (no architectural changes) |
| Sizes | RoBERTa-base (125M params), RoBERTa-large (355M params) |
| Pretraining data | Over 160GB of English text across five corpora |
| Pretraining objective | Masked language modeling only (no NSP) |
| Tokenizer | Byte-level BPE, 50,265 tokens |
| GLUE test score | 88.5 (state of the art at release)[1] |
| License | MIT (released with code in fairseq) |
| Citations | Over 32,000 (Semantic Scholar, November 2026)[13] |
Background and Motivation
When Google released BERT in October 2018, it represented a major advance in transfer learning for NLP. BERT introduced a bidirectional transformer encoder pretrained with two objectives: masked language modeling (MLM) and next sentence prediction (NSP). It achieved state-of-the-art results on a wide range of benchmarks, including GLUE, SQuAD, and others.[2]
However, shortly after BERT's release, several competing models appeared that claimed architectural superiority. XLNet (Yang et al., 2019) introduced permutation-based language modeling to capture bidirectional context without masking.[3] Other approaches proposed novel pretraining objectives or architectural modifications.
The Facebook AI team noticed that these follow-up studies often changed multiple variables simultaneously, making it difficult to isolate which factors actually contributed to performance improvements. The authors hypothesized that BERT's original training recipe was suboptimal and that better tuning alone could recover much of the gap between BERT and its successors. RoBERTa was designed as a careful replication study to test this hypothesis.[1] The paper frames this motivation directly, noting that hyperparameter choices "have significant impact on the final results" and that the work "raise[s] questions about the source of recently reported improvements."[1]
What did RoBERTa change from BERT?
The paper summarizes its modifications as four concrete changes to the BERT pretraining recipe: "(1) training the model longer, with bigger batches, over more data; (2) removing the next sentence prediction objective; (3) training on longer sequences; and (4) dynamically changing the masking pattern applied to the training data."[1] RoBERTa also collected a new dataset, CC-News, to control for the effect of training-set size, and switched to a byte-level Byte Pair Encoding tokenizer.[1]
The authors list their contributions as: "(1) We present a set of important BERT design choices and training strategies and introduce alternatives that lead to better downstream task performance; (2) We use a novel dataset, CC-News, and confirm that using more data for pretraining further improves performance on downstream tasks; (3) Our training improvements show that masked language model pretraining, under the right design choices, is competitive with all other recently published methods."[1]
Key Changes from BERT
RoBERTa uses the same underlying architecture as BERT but modifies several aspects of the pretraining procedure.[1] The following sections describe each change in detail.
Dynamic Masking
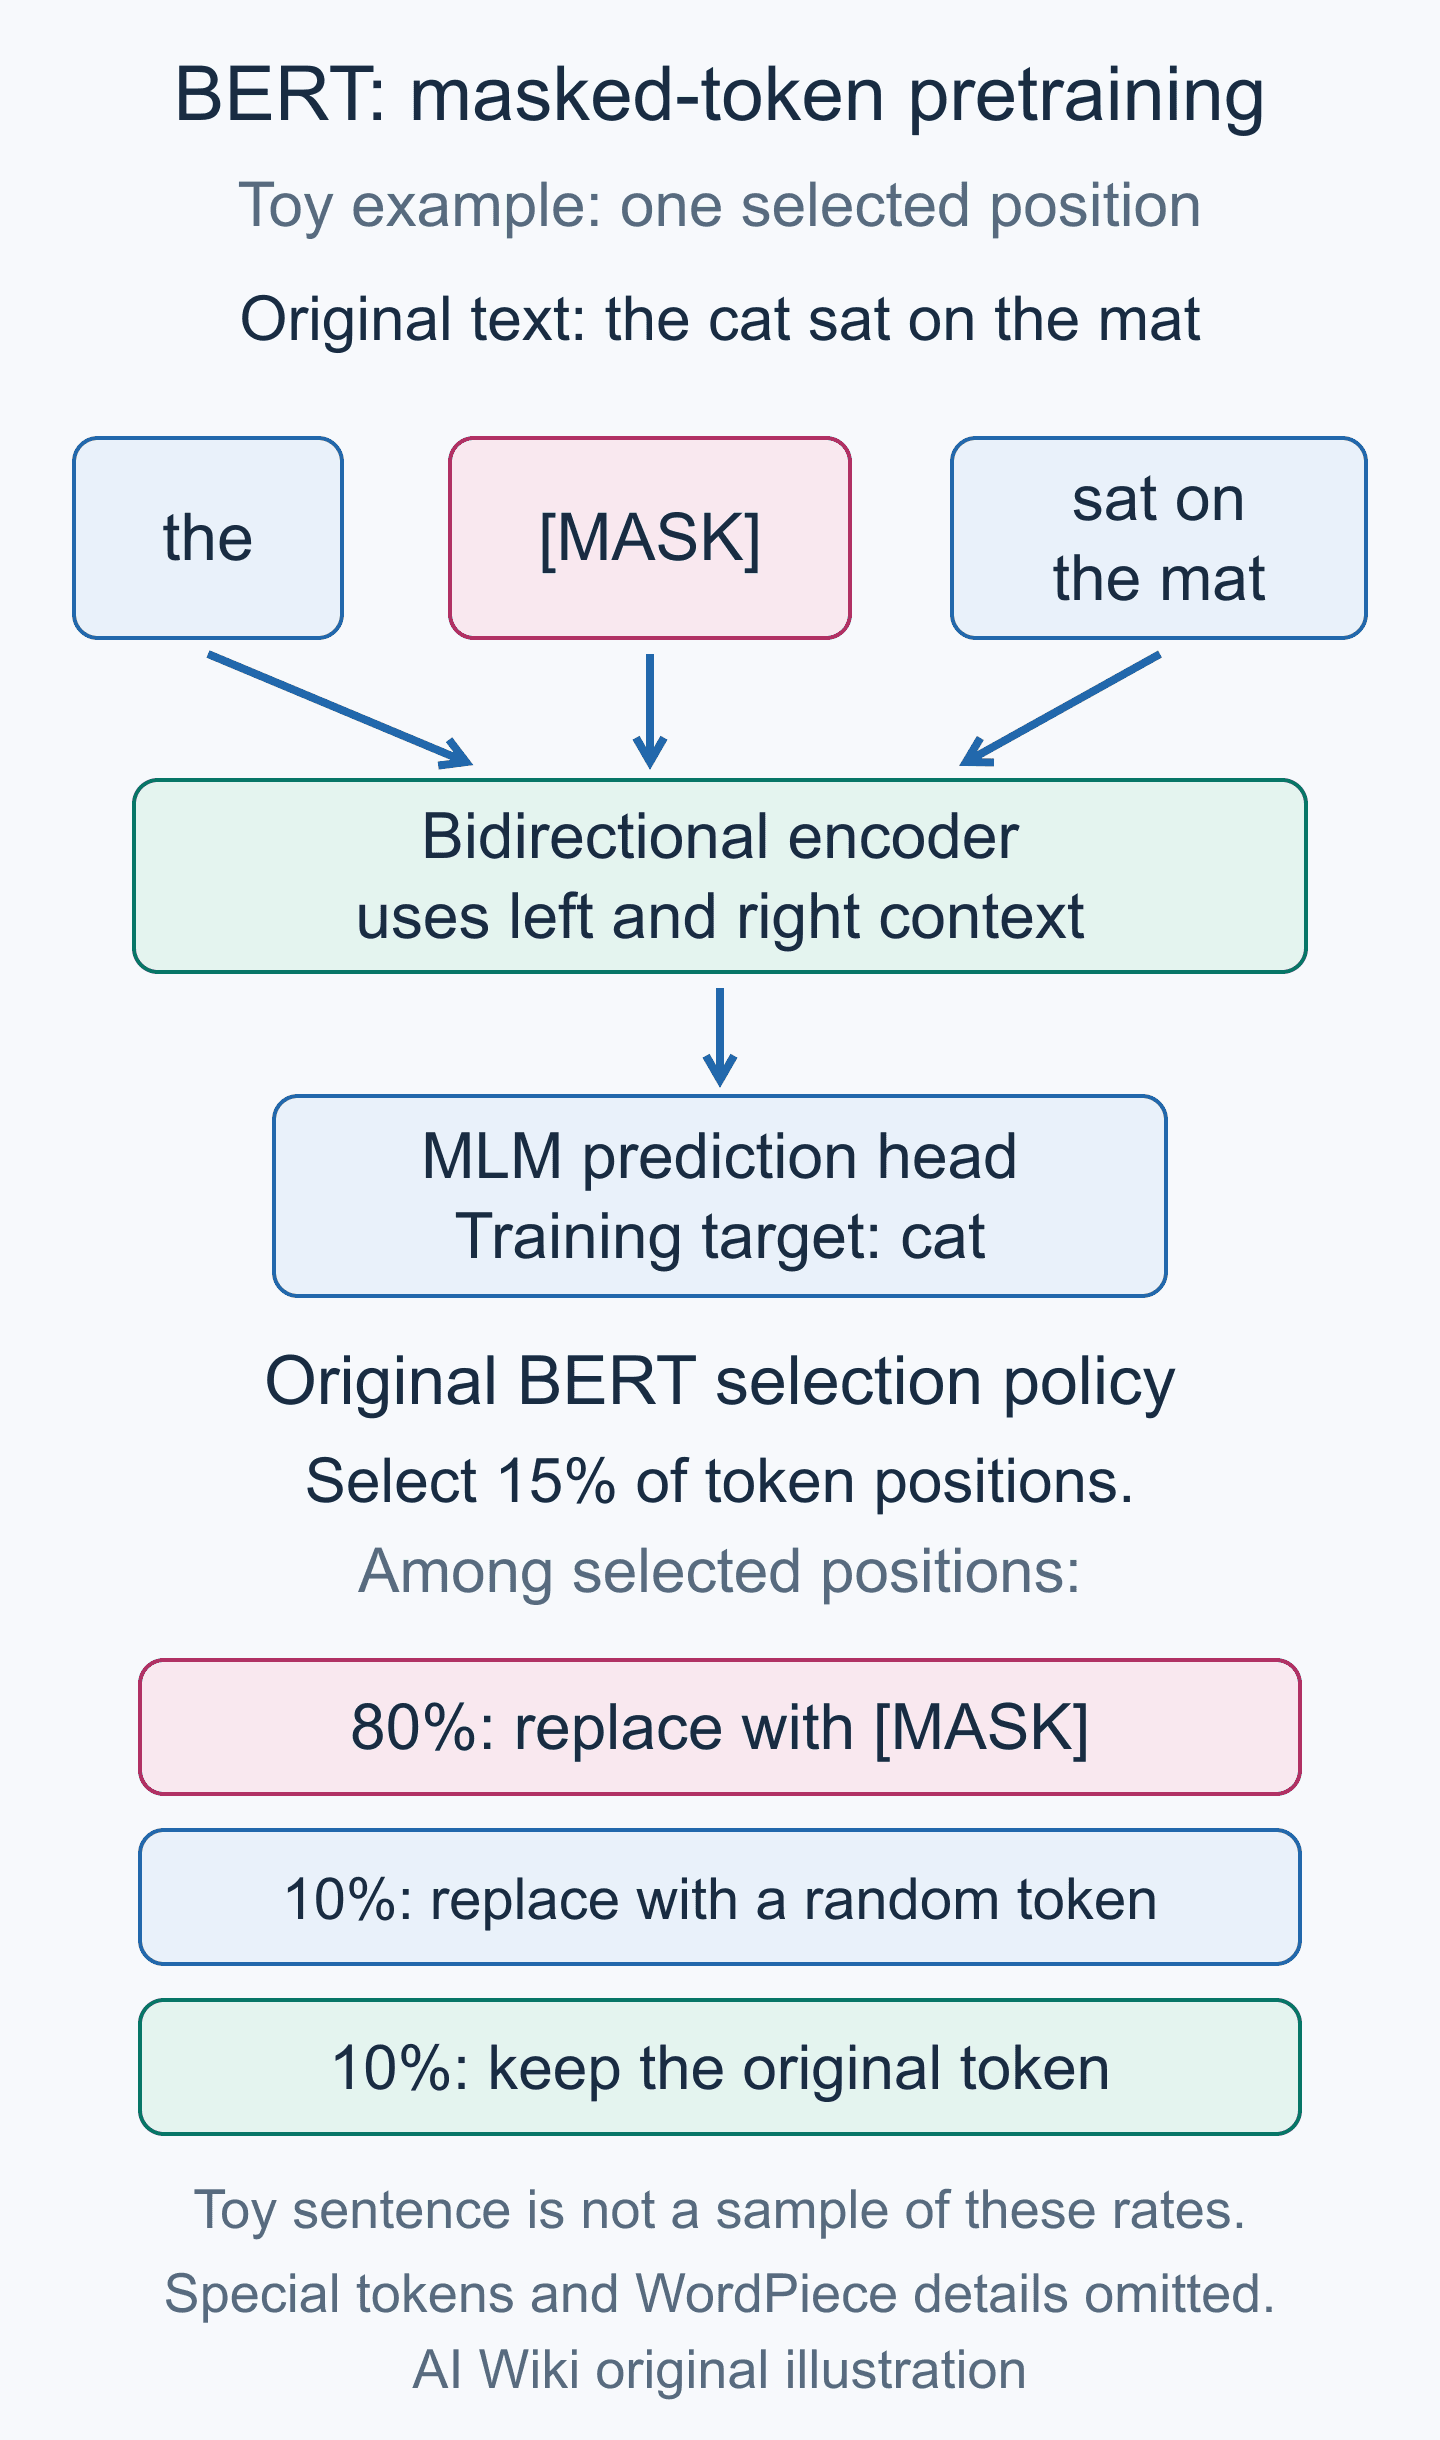
BERT's original implementation applies a single static masking pattern to each training example during data preprocessing. This means the model sees the same masked version of each sentence every time it encounters that sentence during training.[2]
RoBERTa replaces this with dynamic masking, where a new masking pattern is generated each time a sequence is fed to the model. This contrasts with the static baseline, in which the training data was duplicated 10 times so that each sequence was masked in 10 different ways over 40 epochs of training, meaning each training sequence was seen with the same mask four times. Experiments in the paper showed that dynamic masking performs comparably to or slightly better than static masking, with the advantage becoming more pronounced over longer training runs.[1]
| Masking Strategy | SQuAD 2.0 (F1) | MNLI-m (Acc) | SST-2 (Acc) |
|---|---|---|---|
| Static (BERT reimplementation) | 78.3 | 84.3 | 92.5 |
| Dynamic | 78.7 | 84.0 | 92.9 |
Removal of Next Sentence Prediction
BERT's pretraining included a next sentence prediction (NSP) objective, where the model learned to predict whether two segments came from consecutive sentences in the original text. The NSP task was intended to help with downstream tasks that involve reasoning about sentence pairs, such as natural language inference.[2]
The RoBERTa authors tested four different input format configurations:[1]
| Configuration | Description | SQuAD 1.1/2.0 | MNLI-m | SST-2 | RACE |
|---|---|---|---|---|---|
| Segment-pair + NSP | Two segments from same or different documents, with NSP loss | 90.4 / 78.7 | 84.0 | 92.9 | 64.2 |
| Sentence-pair + NSP | Two natural sentences, with NSP loss | 88.7 / 76.2 | 82.9 | 92.1 | 63.0 |
| Full-sentences (no NSP) | Full sentences packed from one or more documents, no NSP loss | 90.4 / 79.1 | 84.7 | 92.5 | 64.8 |
| Doc-sentences (no NSP) | Full sentences from a single document only, no NSP loss | 90.6 / 79.7 | 84.7 | 92.7 | 65.6 |
The results showed that removing the NSP loss matched or slightly improved downstream task performance. The "full-sentences" format, which packs consecutive full sentences from one or more documents up to the 512-token limit without NSP, was adopted for the final RoBERTa model because the "doc-sentences" format introduced variable batch sizes that complicated training.[1]
Larger Mini-Batches
BERT-large was originally trained with a batch size of 256 sequences for 1 million steps.[2] The RoBERTa authors explored the effect of increasing the batch size while keeping the total number of training tokens constant.[1]
| Batch Size | Steps | Learning Rate | Perplexity | MNLI-m | SST-2 |
|---|---|---|---|---|---|
| 256 | 1M | 1e-4 | 3.99 | 84.7 | 92.7 |
| 2K | 125K | 7e-4 | 3.68 | 85.2 | 92.9 |
| 8K | 31K | 1e-3 | 3.77 | 84.6 | 92.8 |
Training with a batch size of 2K sequences and 125K steps produced the best results, improving both perplexity and downstream task performance. Larger batches of 8K sequences also performed well and offered computational advantages through increased parallelism. The final RoBERTa model used a batch size of 8K sequences.[1]
More Training Data
BERT was pretrained on a combination of BookCorpus (approximately 800 million words) and English Wikipedia (approximately 2,500 million words), totaling roughly 16GB of uncompressed text.[2] RoBERTa expanded the pretraining corpus significantly by adding three additional datasets, bringing the total to over 160GB.[1]
Longer Training
The original BERT-large model was trained for 1 million steps with a batch size of 256.[2] RoBERTa was trained for 500K steps with a batch size of 8K, resulting in the model processing significantly more tokens overall. The authors observed that performance continued to improve as training progressed, with the best results at 500K steps.[1]
| Configuration | Data | Batch Size | Steps | SQuAD 1.1/2.0 (F1) | MNLI-m | SST-2 |
|---|---|---|---|---|---|---|
| RoBERTa (Books + Wiki) | 16GB | 8K | 100K | 93.6 / 87.3 | 89.0 | 95.3 |
| + additional data | 160GB | 8K | 100K | 94.0 / 87.7 | 89.3 | 95.6 |
| + pretrain longer (300K) | 160GB | 8K | 300K | 94.4 / 88.7 | 90.0 | 96.1 |
| + pretrain longer (500K) | 160GB | 8K | 500K | 94.6 / 89.4 | 90.2 | 96.4 |
This table illustrates the cumulative effect of each modification, showing steady gains from additional data and longer training.[1]
Byte-Level BPE Tokenizer
BERT uses a WordPiece tokenizer with a vocabulary of approximately 30,000 tokens.[2] RoBERTa switched to a byte-level Byte Pair Encoding (BPE) tokenizer, similar to the one used in GPT-2.[10] The paper describes a vocabulary of 50K subword units; the released tokenizer has 50,265 entries including special tokens.[1][12]
Byte-level BPE operates on raw bytes rather than Unicode characters, which means it can encode any input text without producing unknown tokens. The base vocabulary consists of 256 byte tokens, supplemented by 50,000 learned merge operations and special tokens. While this larger vocabulary adds approximately 15 million (base) and 20 million (large) parameters to the model, it eliminates the need for any text preprocessing or tokenization heuristics. The RoBERTa authors found that byte-level BPE performed slightly worse on some individual tasks but was comparable overall, with the advantage of greater robustness to diverse inputs.[1]
Paper Details
| Detail | Value |
|---|---|
| Title | RoBERTa: A Robustly Optimized BERT Pretraining Approach |
| Authors | Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov |
| Affiliation | Facebook AI Research; University of Washington |
| Published | July 26, 2019 (arXiv:1907.11692) |
| Conference Submission | Submitted to ICLR 2020 (not accepted) |
| Framework | Implemented in fairseq (Facebook AI Research Sequence-to-Sequence Toolkit) |
| Citations | Over 32,000 (Semantic Scholar, November 2026)[13] |
Although the paper was not accepted at ICLR 2020, its practical impact has been enormous. The systematic investigation and the resulting pretrained models became widely adopted across the NLP community.[1]
Architecture
RoBERTa does not introduce any architectural changes compared to BERT. It uses the standard transformer encoder architecture. The two primary variants follow the same configurations as BERT-base and BERT-large.[1]
Model Variants
| Specification | RoBERTa-base | RoBERTa-large |
|---|---|---|
| Transformer layers | 12 | 24 |
| Hidden size | 768 | 1,024 |
| Attention heads | 12 | 16 |
| Feed-forward dimension | 3,072 | 4,096 |
| Parameters | 125M | 355M |
| Vocabulary size | 50,265 | 50,265 |
| Max sequence length | 512 | 512 |
| Tokenizer | Byte-level BPE | Byte-level BPE |
The key insight of RoBERTa is that the architecture did not need to change; better training procedures alone were sufficient to achieve substantial performance improvements.[1]
Training Data
RoBERTa was pretrained on five English-language datasets totaling over 160GB of uncompressed text. This represents a tenfold increase over the 16GB of text used to train the original BERT.[1]
| Dataset | Size | Description |
|---|---|---|
| BookCorpus | 16GB combined with English Wikipedia | Collection of over 11,000 unpublished books from various genres, originally used in BERT pretraining |
| English Wikipedia | (included in the 16GB above) | Full text of English Wikipedia articles (excluding lists, tables, and headers), also used in BERT pretraining |
| CC-News | 76GB | A dataset of 63 million English news articles crawled from CommonCrawl News between September 2016 and February 2019 |
| OpenWebText | 38GB | An open-source recreation of the WebText corpus described by Radford et al. (2019), consisting of web content from URLs shared on Reddit with at least three upvotes |
| Stories | 31GB | A subset of CommonCrawl data filtered to match the style of Winograd schema stories, as introduced by Trinh and Le (2018) |
The CC-News, OpenWebText, and Stories datasets were the three additions beyond what BERT originally used. The diversity of these sources, spanning books, encyclopedic text, news articles, web content, and narrative stories, helped the model learn a broader range of language patterns.[1]
Training Configuration
The full RoBERTa model was trained using the Adam optimizer with the following hyperparameters.[1]
| Hyperparameter | RoBERTa-base | RoBERTa-large |
|---|---|---|
| Peak learning rate | 6e-4 | 4e-4 |
| Batch size (sequences) | 8,000 | 8,000 |
| Training steps | 500,000 | 500,000 |
| Warmup steps | 24,000 | 30,000 |
| Adam epsilon | 1e-6 | 1e-6 |
| Adam beta_2 | 0.98 | 0.98 |
| Weight decay | 0.01 | 0.01 |
| Dropout | 0.1 | 0.1 |
| Learning rate schedule | Linear decay | Linear decay |
| Max sequence length | 512 | 512 |
Training was conducted on 1,024 NVIDIA V100 GPUs using mixed-precision floating-point arithmetic. The DGX-1 machines used each contained 8 V100 GPUs with 32GB of memory, interconnected by Infiniband. The paper reports pretraining the 100K-step configuration on 1,024 V100 GPUs in approximately one day; it does not give the wall-clock time of the full 500K-step run.[1]
Notably, RoBERTa changed Adam's beta_2 parameter from BERT's default of 0.999 to 0.98, which the authors found to improve training stability with large batch sizes.[1]
Benchmark Results
GLUE Benchmark
The General Language Understanding Evaluation (GLUE) benchmark is a collection of nine natural language understanding tasks. RoBERTa achieved state-of-the-art results on the GLUE leaderboard at the time of publication, with an overall test score of 88.5.[1] The paper reports this milestone directly: "When trained for longer over additional data, our model achieves a score of 88.5 on the public GLUE leaderboard, matching the 88.4 reported by Yang et al."[1] Notably, RoBERTa's leaderboard submission relied only on single-task finetuning yet set new state-of-the-art results on 4 of the 9 GLUE tasks (MNLI, QNLI, RTE, and STS-B), whereas many competing submissions depended on multi-task finetuning; RoBERTa's test submission was itself an ensemble of 5 to 7 single-task models per task.[1]
The following table shows development set results for single-task, single-model fine-tuning.
| Model | MNLI | QNLI | QQP | RTE | SST-2 | MRPC | CoLA | STS-B |
|---|---|---|---|---|---|---|---|---|
| BERT-large | 86.6 | 92.3 | 91.3 | 70.4 | 93.2 | 88.0 | 60.6 | 90.0 |
| XLNet-large | 89.8 | 93.9 | 91.8 | 83.8 | 95.6 | 89.2 | 63.6 | 91.8 |
| RoBERTa-large | 90.2 | 94.7 | 92.2 | 86.6 | 96.4 | 90.9 | 68.0 | 92.4 |
RoBERTa outperformed both BERT-large and XLNet-large on every single GLUE task in the development set. The improvements were especially notable on CoLA (68.0 vs. 60.6 for BERT), RTE (86.6 vs. 70.4 for BERT), and MNLI (90.2 vs. 86.6 for BERT).[1]
On the GLUE test set, RoBERTa achieved an average score of 88.5, which was the highest score on the leaderboard at the time, matching the performance achieved by XLNet's multi-task ensemble submission.[1]
SQuAD
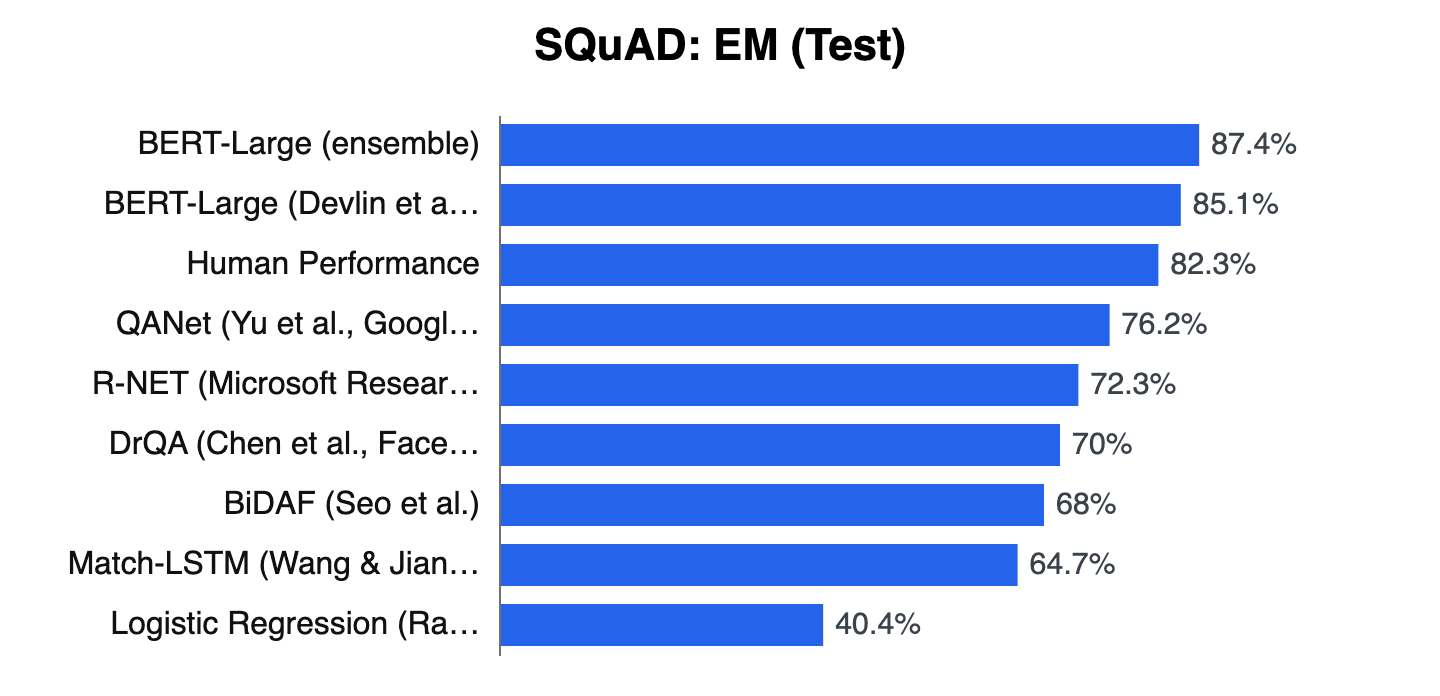
The Stanford Question Answering Dataset (SQuAD) evaluates reading comprehension. RoBERTa was evaluated on both SQuAD v1.1 and SQuAD v2.0, using only the provided SQuAD training data without any additional question answering datasets.[1]
| Model | SQuAD v1.1 EM | SQuAD v1.1 F1 | SQuAD v2.0 EM | SQuAD v2.0 F1 |
|---|---|---|---|---|
| BERT-large | 84.1 | 90.9 | 79.0 | 81.8 |
| XLNet-large | 89.0 | 94.5 | 86.1 | 88.8 |
| RoBERTa-large | 88.9 | 94.6 | 86.5 | 89.4 |
RoBERTa achieved results comparable to XLNet on SQuAD v1.1 (94.6 F1 vs. 94.5 F1) and slightly better on SQuAD v2.0 (89.4 F1 vs. 88.8 F1). Both models significantly outperformed the original BERT-large baseline.[1]
RACE
The RACE (ReAding Comprehension from Examinations) benchmark consists of multiple-choice reading comprehension questions collected from English exams for Chinese middle and high school students.
| Model | Middle | High | Overall |
|---|---|---|---|
| BERT-large | 76.6 | 70.1 | 72.0 |
| XLNet-large | 85.4 | 80.2 | 81.7 |
| RoBERTa-large | 86.5 | 81.3 | 83.2 |
RoBERTa achieved the best overall accuracy on RACE at 83.2%, surpassing XLNet-large (81.7%) and BERT-large (72.0%) by significant margins.[1]
How does RoBERTa compare with other transformer models?
RoBERTa emerged during a period of rapid development in pretrained language models. The following table provides a high-level comparison with other prominent models from the same era.
| Feature | BERT-large | RoBERTa-large | XLNet-large | ALBERT-xxlarge | ELECTRA-large |
|---|---|---|---|---|---|
| Year | 2018 | 2019 | 2019 | 2019 | 2020 |
| Organization | Facebook AI | Google/CMU | Google/Stanford | ||
| Parameters | 340M | 355M | 340M | 235M | 335M |
| Pretraining Objective | MLM + NSP | MLM only | Permutation LM | MLM + SOP | Replaced Token Detection |
| Tokenizer | WordPiece (30K) | Byte-level BPE (50K) | SentencePiece | SentencePiece (30K) | WordPiece (30K) |
| Training Data | 16GB | 160GB | ~126GB | 16GB plus RoBERTa and XLNet data | XLNet data (33B tokens) |
| Masking | Static | Dynamic | N/A (permutation) | Static | N/A (replacement) |
| NSP Task | Yes | No | No | No (uses SOP) | No |
| GLUE Dev (MNLI) | 86.6 | 90.2 | 89.8 | 90.8 | 90.9 |
| GLUE Dev (SST-2) | 93.2 | 96.4 | 95.6 | 96.9 | 96.9 |
| GLUE Dev (CoLA) | 60.6 | 68.0 | 63.6 | 71.4 | 69.1 |
| SQuAD v2.0 (F1) | 81.8 | 89.4 | 88.8 | 90.2 | 90.6 |
Several observations emerge from this comparison:
- RoBERTa vs. BERT: With identical architecture, RoBERTa demonstrated that better training procedures and more data could close the gap with newer models. The MNLI improvement from 86.6 to 90.2 and CoLA improvement from 60.6 to 68.0 were substantial.[1]
- RoBERTa vs. XLNet: Despite XLNet's more complex permutation language modeling approach, RoBERTa matched or exceeded XLNet on most benchmarks while using a simpler MLM objective.[1]
- RoBERTa vs. ALBERT: ALBERT achieved competitive or better scores with significantly fewer parameters (235M vs. 355M) through cross-layer parameter sharing and factorized embedding parameterization.[4]
- RoBERTa vs. ELECTRA: ELECTRA, published later in 2020, achieved comparable or better scores using a replaced token detection objective that is more sample-efficient, matching RoBERTa's performance with less than one-quarter of its pretraining compute.[5]
Why did RoBERTa show BERT was undertrained?
The central finding of the RoBERTa paper was that BERT was "significantly undertrained."[1] The authors supported this claim through a systematic ablation study that isolated the contribution of each change.[1]
Insufficient Training Duration
BERT-large was trained for 1 million steps with a batch size of 256.[2] When the RoBERTa authors retrained the same BERT architecture on the same BookCorpus and Wikipedia data, but for longer and with larger batches (8K batch size for 100K steps), they already observed improvements. Extending training to 300K and then 500K steps with the larger batch size yielded further gains on every benchmark.[1]
Suboptimal Data Volume
BERT's 16GB training corpus was limited in both size and diversity. When RoBERTa added CC-News, OpenWebText, and Stories to reach 160GB, performance improved even at the same number of training steps. The additional data provided the model with a broader distribution of language patterns and factual knowledge.[1]
Unnecessary NSP Objective
The next sentence prediction task was shown to be unnecessary: removing the NSP loss matched or slightly improved downstream task performance. Removing it freed up the model's capacity to focus entirely on the masked language modeling objective, which proved more beneficial for downstream tasks.[1]
Static Masking Limitations
BERT's static masking meant the model saw the same masking pattern for each training example in every epoch. Dynamic masking provided more diverse training signals, which became increasingly important over longer training runs.[1]
Undertuned Hyperparameters
The change in Adam's beta_2 from 0.999 to 0.98, the use of larger learning rates with large batches, and other hyperparameter adjustments all contributed to better training dynamics.[1]
Taken together, these findings demonstrated that the gap between BERT and subsequent models like XLNet was not primarily due to architectural innovation but rather to undertrained baselines.[1]
What is RoBERTa used for?
RoBERTa has been widely adopted for a variety of NLP tasks through fine-tuning.
Text Classification
RoBERTa serves as a strong backbone for sentiment analysis, topic classification, spam detection, and other document-level classification tasks. Its strong performance on SST-2 (96.4% accuracy) reflects its ability to capture nuanced language patterns relevant to sentiment.[1]
Named Entity Recognition
Named entity recognition (NER) benefits from RoBERTa's contextual representations. Fine-tuned RoBERTa models have been used for identifying persons, organizations, locations, and domain-specific entities in various domains including biomedical text and legal documents.
Question Answering
RoBERTa's strong SQuAD results translate to effective question answering systems. The model can be fine-tuned on extractive QA datasets to locate answer spans within passages.
Natural Language Inference
Tasks like MNLI, which require determining whether a hypothesis is entailed by, contradicted by, or neutral with respect to a premise, are well-served by RoBERTa's deep bidirectional representations.
Semantic Similarity
RoBERTa's performance on STS-B (92.4 on the development set) makes it effective for paraphrase detection, duplicate question identification, and semantic search applications.[1]
Variants and Extensions
RoBERTa-base and RoBERTa-large
The two primary variants correspond to BERT-base and BERT-large configurations. RoBERTa-base (125M parameters, 12 layers) is suitable for resource-constrained environments, while RoBERTa-large (355M parameters, 24 layers) provides the best performance.[1]
Development set results for both variants on the GLUE benchmark, as published in the fairseq RoBERTa README (the paper itself reports only RoBERTa-large):[11]
| Task | RoBERTa-base | RoBERTa-large |
|---|---|---|
| MNLI | 87.6 | 90.2 |
| QNLI | 92.8 | 94.7 |
| QQP | 91.9 | 92.2 |
| RTE | 78.7 | 86.6 |
| SST-2 | 94.8 | 96.4 |
| MRPC | 90.2 | 90.9 |
| CoLA | 63.6 | 68.0 |
| STS-B | 91.2 | 92.4 |
XLM-RoBERTa
XLM-RoBERTa (Conneau et al., 2020) extended RoBERTa's training approach to the multilingual setting. Pretrained on 2.5TB of filtered CommonCrawl data spanning 100 languages, XLM-RoBERTa achieved strong results on cross-lingual benchmarks.[6] It outperformed multilingual BERT (mBERT) by +14.6% average accuracy on XNLI and +13% average F1 on MLQA, while also performing competitively with monolingual models on English benchmarks.[6] XLM-RoBERTa demonstrated that the RoBERTa training recipe could scale effectively across languages.[6]
DistilRoBERTa
DistilRoBERTa applies knowledge distillation to RoBERTa, producing a smaller, faster model that retains much of RoBERTa's performance. With 82 million parameters (roughly 66% of RoBERTa-base), DistilRoBERTa is on average twice as fast as RoBERTa-base, which makes it a practical option for latency-sensitive applications.[14]
Is RoBERTa open source and how do I use it?
RoBERTa was released as open source alongside the paper, with code and pretrained weights distributed through the fairseq toolkit under the MIT license, and the paper explicitly states "We release our models and code."[1][11] RoBERTa models are also available through the Hugging Face Transformers library under the FacebookAI organization.[12] The primary model identifiers are:
| Model | Hugging Face ID | Parameters |
|---|---|---|
| RoBERTa-base | FacebookAI/roberta-base | 125M |
| RoBERTa-large | FacebookAI/roberta-large | 355M |
| RoBERTa-large (MNLI) | FacebookAI/roberta-large-mnli | 355M |
| XLM-RoBERTa-base | FacebookAI/xlm-roberta-base | 279M |
| XLM-RoBERTa-large | FacebookAI/xlm-roberta-large | 561M |
These models can be loaded with a few lines of Python code using the Transformers library:
from transformers import AutoTokenizer, AutoModel

tokenizer = AutoTokenizer.from_pretrained("FacebookAI/roberta-large")
model = AutoModel.from_pretrained("FacebookAI/roberta-large")
The Hugging Face model hub also hosts numerous community-contributed RoBERTa models fine-tuned for specific tasks, including sentiment analysis, NER, question answering, and domain-specific applications in biomedical, legal, and financial text.[12]
Legacy and Influence
RoBERTa's impact on the NLP field extends well beyond its benchmark scores.
Establishing Training Best Practices
The paper's most lasting contribution may be its demonstration that training procedure matters as much as, if not more than, model architecture. This insight influenced the entire field, leading researchers to invest more effort in hyperparameter tuning, data curation, and training duration before proposing new architectures.[1]
Influence on Subsequent Models
RoBERTa's training methodology directly influenced several important subsequent models:
- BART (Lewis et al., 2019): Also from Facebook AI, BART uses a similar encoder architecture to RoBERTa but adds a decoder for sequence-to-sequence tasks. On NLU benchmarks, BART performs comparably to RoBERTa.[8]
- DeBERTa (He et al., 2020): Microsoft's DeBERTa built upon the RoBERTa training recipe while introducing disentangled attention. Trained on half the data, DeBERTa outperformed RoBERTa on MNLI by +0.9%, SQuAD v2.0 by +2.3%, and RACE by +3.6%.[7]
- ELECTRA (Clark et al., 2020): While introducing a different pretraining objective, ELECTRA used RoBERTa as a primary baseline and demonstrated that replaced token detection could achieve RoBERTa-level performance with 25% of the compute.[5]
- Longformer (Beltagy et al., 2020): From the Allen Institute for AI, Longformer initialized from the RoBERTa checkpoint and extended it to handle long documents with up to 4,096 tokens using sparse attention.[9]
Widespread Adoption
RoBERTa became a default choice for many NLP practitioners and researchers as a strong pretrained encoder. Its availability through Hugging Face, combined with its consistent performance across tasks, made it a standard baseline in hundreds of research papers. Many shared task competitions and industrial NLP systems adopted RoBERTa as their starting point for fine-tuning.
The "Scaling" Lesson
Before RoBERTa, the NLP community often attributed performance gains to architectural novelty. RoBERTa shifted this narrative by showing that scaling data, compute, and training duration could be equally or more important. This insight foreshadowed the broader "scaling laws" findings that would later emerge in the context of large language models like GPT-3 and beyond.
Limitations
Despite its strengths, RoBERTa has several limitations:
- Computational cost: Training RoBERTa required 1,024 V100 GPUs, making it expensive to reproduce. At the time of publication, this represented a significant barrier to entry for academic labs.[1]
- English only: The original RoBERTa models were trained exclusively on English text. While XLM-RoBERTa addressed multilingual needs, the base models are not suitable for non-English tasks.[6]
- Encoder only: As a bidirectional encoder, RoBERTa cannot directly generate text. It is not suitable for tasks like text summarization, translation, or open-ended generation without additional architectural components.
- Fixed sequence length: RoBERTa's maximum input length is 512 tokens, which limits its application to long documents without modifications like those introduced by Longformer.[9]
- No architectural innovation: While this was the paper's deliberate point, it also means RoBERTa does not address any of BERT's structural limitations, such as its inability to model token dependencies beyond the attention window.
Continue reading
- BERTBERT, short for Bidirectional Encoder Representations from Transformers, is a pretrained language model introduced by researchers at Google Research in 2018.Mentioned 57 times above
- SQuADSQuAD (the Stanford Question Answering Dataset) is a large-scale reading comprehension benchmark from Stanford University in which a model must answer a question by extracting the exact span of text that…Mentioned 18 times above
- XLNetXLNet is a generalized autoregressive pretraining method for natural language processing that combines the strengths of autoregressive and autoencoding language models.Mentioned 15 times above
- GLUE benchmarkThe General Language Understanding Evaluation (GLUE) benchmark is a collection of nine natural language understanding (NLU) tasks designed to evaluate and compare the performance of language models across a…Mentioned 14 times above
- ELECTRAELECTRA, which stands for Efficiently Learning an Encoder that Classifies Token Replacements AccuratelyMentioned 5 times above
- Masked Language ModelA masked language model (MLM) is a language model trained to predict missing tokens that have been hidden in a sequence of text, using context from both the left and the right of each blank.Mentioned 4 times above
More from See also
More to read
Topics:Deep LearningMachine LearningNatural Language ProcessingTransformer Models
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32 ^33 ^34 ^35 ^36 ^37 ^38 ^39 ^40 ^41 ^42 ^43 ^44 ^45 ^46 ^47 ^48 ^49 ^50 ^51 ^52Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019). "RoBERTa: A Robustly Optimized BERT Pretraining Approach." arXiv:1907.11692. arxiv.org/...1907.11692
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019). "BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding." Proceedings of NAACL-HLT 2019. arxiv.org/...1810.04805
- ^Yang, Z., Dai, Z., Yang, Y., Carbonell, J., Salakhutdinov, R., & Le, Q. V. (2019). "XLNet: Generalized Autoregressive Pretraining for Language Understanding." NeurIPS 2019. arxiv.org/...1906.08237
- ^Lan, Z., Chen, M., Goodman, S., Gimpel, K., Sharma, P., & Soricut, R. (2020). "ALBERT: A Lite BERT for Self-supervised Learning of Language Representations." ICLR 2020. arxiv.org/...1909.11942
- ^1 ^2Clark, K., Luong, M.-T., Le, Q. V., & Manning, C. D. (2020). "ELECTRA: Pre-training Text Encoders as Discriminators Rather Than Generators." ICLR 2020. arxiv.org/...2003.10555
- ^1 ^2 ^3 ^4Conneau, A., Khandelwal, K., Goyal, N., Chaudhary, V., Wenzek, G., Guzman, F., Grave, E., Ott, M., Zettlemoyer, L., & Stoyanov, V. (2020). "Unsupervised Cross-lingual Representation Learning at Scale." ACL 2020. arxiv.org/...1911.02116
- ^He, P., Liu, X., Gao, J., & Chen, W. (2021). "DeBERTa: Decoding-enhanced BERT with Disentangled Attention." ICLR 2021. arxiv.org/...2006.03654
- ^Lewis, M., Liu, Y., Goyal, N., Ghazvininejad, M., Mohamed, A., Levy, O., Stoyanov, V., & Zettlemoyer, L. (2020). "BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension." ACL 2020. arxiv.org/...1910.13461
- ^1 ^2Beltagy, I., Peters, M. E., & Cohan, A. (2020). "Longformer: The Long-Document Transformer." arXiv:2004.05150. arxiv.org/...2004.05150
- ^Radford, A., Wu, J., Child, R., Luan, D., Amodei, D., & Sutskever, I. (2019). "Language Models are Unsupervised Multitask Learners." OpenAI Technical Report.
- ^1 ^2Facebook AI Research. "fairseq: A Fast, Extensible Toolkit for Sequence Modeling." GitHub. github.com/...fairseq
- ^1 ^2 ^3Hugging Face. "RoBERTa documentation." huggingface.co/...roberta
- ^1 ^2 ^3Semantic Scholar. "RoBERTa: A Robustly Optimized BERT Pretraining Approach" (citation count). semanticscholar.org/...1907.11692
- ^Hugging Face. "distilroberta-base" model card. huggingface.co/...distilroberta-base
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
11 revisions · v11 · 4,857 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (170 claims, 19 sources fetched); 6 material + 18 minor fixed
Cite this page: AI Wiki. "RoBERTa." aiwiki.ai, updated 21 Jun 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/roberta