

Trillium (TPU v6e)
Trillium, also designated TPU v6e, is the sixth-generation Tensor Processing Unit developed by Google for machine learning training and inference workloads on Cloud TPU infrastructure.[1][2] Google announced Trillium at the Google I/O developer conference in May 2024 and made it generally available to Google Cloud customers on December 12, 2024.[5][8][11] According to Google, each Trillium chip delivers a 4.7x increase in peak compute per chip over the prior-generation TPU v5e, doubles both High Bandwidth Memory (HBM) capacity and bandwidth, doubles Inter-Chip Interconnect (ICI) bandwidth, adds a third-generation SparseCore, and is over 67% more energy-efficient than v5e, scaling up to 256 chips in a single high-bandwidth pod.[1][11] Google has stated that it used Trillium TPUs to train Gemini 2.0, its most capable model at the time of the December 2024 launch.[8][11]
The "e" suffix denotes the chip's positioning as an efficiency-optimized member of the TPU family, a lineage convention Google introduced with TPU v5e.[3] Unlike the fifth generation, which Google split into two distinct silicon designs (v5e and v5p), the sixth generation was released only as a single efficiency-class part; there is no publicly announced "TPU v6p" variant, and Trillium has been the sole v6 product line through 2025.[3][4]
Trillium was unveiled by Google CEO Sundar Pichai on May 14, 2024 at the Google I/O developer conference in Mountain View, California, where it was announced as the silicon that would underlie the next generation of Gemini models.[5][6] The chip entered preview availability on Google Cloud on October 31, 2024 and reached general availability on December 12, 2024, coinciding with the public launch of Gemini 2.0 Flash.[7][8] At general availability Google stated, "We used Trillium TPUs to train the new Gemini 2.0, Google's most capable AI model yet," and Pichai separately stated that "TPUs powered 100% of Gemini 2.0 training and inference."[11][43]
Each Trillium chip delivers a peak of approximately 918 BF16 TFLOPS and 1,836 INT8 TOPS, equipped with 32 GB of high-bandwidth memory at 1,640 GB/s, and uses 800 GB/s of inter-chip interconnect (ICI) bandwidth distributed across four ports.[10] Compared to its TPU v5e predecessor, Google reports a 4.7x increase in peak compute per chip, doubled HBM capacity, doubled HBM bandwidth, doubled ICI bandwidth, and a greater-than-67% improvement in energy efficiency.[1][11] Trillium chips are organized into 256-chip pods linked by a 2D torus interconnect, with multiple pods aggregated through Google's data-center-scale Jupiter network fabric, a topology Google has scaled to over 100,000 Trillium chips operating as a single training substrate.[11][12]
Trillium's successor, TPU Ironwood (TPU v7), was announced at Google Cloud Next 2025 on April 9, 2025 and reached general availability in November 2025; Google says it delivers more than 4x better performance per chip than Trillium for both training and inference. Google announced its eighth-generation TPUs, TPU 8t for training and TPU 8i for inference, on April 22, 2026.[13][14][46]
What is Google Trillium?
Trillium is Google's sixth-generation Tensor Processing Unit, a custom application-specific integrated circuit (ASIC) designed in-house by Google to accelerate the large matrix-multiplication operations at the core of deep learning. It is offered exclusively through Cloud TPU on Google Cloud rather than sold as standalone silicon, and it serves both training and inference for large models. Google describes the chip as "the most performant and most energy-efficient TPU to date," citing a 4.7x increase in peak compute per chip over TPU v5e.[1][11] Google says it used Trillium TPUs to train Gemini 2.0.[8][11]
Background and TPU lineage
The TPU program at Google began in 2013 as an internal effort to relieve the company's data centers of the computational load imposed by the rapid growth of deep learning inference, especially for products such as Google Search, Google Photos, and Google Translate.[15][38] According to accounts published by Google engineers, then-Chief Scientist a 2013 internal estimate found that if Android users spoke to their phones for only three minutes a day and Google converted that speech to text with deep learning on CPUs, the company would need two to three times as many servers as it already had. The internal response was to commission a custom silicon design specifically tuned to the matrix-multiplication-heavy inner loops of deep neural network inference.[38] Norm Jouppi, recruited from HP Labs, served as tech lead and principal architect, and the team brought TPU v1 from concept to production deployment in approximately 15 months.[38][15]
The first-generation TPU, designed for inference only, reached internal deployment in 2015 and was first publicly disclosed in 2016; it implemented a 256x256 systolic array of 8-bit multiply-accumulate units delivering 92 TOPS of INT8 compute and famously powered the AlphaGo match against Lee Sedol.[15][16] The second-generation TPU was announced at Google I/O in May 2017 and introduced support for bfloat16 training as well as the inter-chip interconnect that enabled the first TPU Pod deployments, the architectural step that opened TPUs to training workloads and not just serving.[15][16] TPU v3 followed in 2018 with liquid cooling and roughly double the throughput of v2.[15] TPU v4, presented in 2021, doubled v3's performance again, introduced 3D-torus topology and optical-circuit-switched reconfiguration of pod slices, and brought the first generation of the SparseCore accelerator for embedding-heavy workloads such as recommendation models.[15][16]
In 2023 Google split the fifth generation into two parts with different positioning: v5e, optimized for cost-efficient training and serving in mid-size jobs, launched in August 2023; and v5p, optimized for the highest-throughput large-model training, launched in December 2023.[17][18] The two chips differ in topology and pod scale, with v5e using a 2D-torus 256-chip pod and v5p using a 3D-torus pod that scales up to 8,960 chips.[17] The v5e/v5p split established the "e" (efficient) and "p" (performance) suffix convention, which Google carried into v6e before moving to names such as Ironwood (TPU7x) and TPU 8t/8i, and shape how customers reasoned about chip choice for a given workload.[17][18]
Apple foundation models for Apple Intelligence were trained on v4 (the server-side AFM-server, on 8,192 v4 chips) and v5p (the on-device AFM-on-device, on 2,048 v5p chips), disclosed in Apple's foundation-models paper in July 2024, a notable third-party validation of Google's TPU stack for frontier-scale model training arriving just two months after the Trillium announcement.[19][20]
Trillium (v6e) followed v5e and v5p as a generational refresh of the efficiency-class part; Google did not release a separate v6p chip, and the sole v6 silicon design has been used for both training and serving across the v6e generation.[4][11] This represented a small but consequential change of strategy: in v5, the "e" and "p" parts had differentiated form factors and topologies, whereas v6 leaned harder into a single converged design with the efficiency profile. In April 2025 Google announced its seventh-generation TPU under the codename Ironwood, positioned by the company as the first TPU "for the age of inference," with pods of up to 9,216 chips.[13][14]
When was Trillium announced and released?
Google CEO Sundar Pichai announced Trillium at the Google I/O 2024 keynote on May 14, 2024.[5][6] The chip then progressed through Google Cloud's standard rollout: it entered preview on October 31, 2024, and reached general availability on December 12, 2024, the same day Google launched Gemini 2.0 Flash.[7][8][11] The table below summarizes the milestones.
| Milestone | Date | Source |
|---|---|---|
| Announced at Google I/O | May 14, 2024 | Google I/O keynote[5][6] |
| Preview on Google Cloud | October 31, 2024 | Google Cloud Blog[7] |
| General availability | December 12, 2024 | Google Cloud Blog[11] |
| Used to train Gemini 2.0 | Announced December 12, 2024 | Google Cloud Blog[8][11] |
| Successor (Ironwood / TPU v7) announced | April 9, 2025 | Google Blog[13] |
Architecture
Compute and MXU
Each Trillium chip contains one TensorCore, which houses two matrix-multiply units (MXUs), a vector processing unit, and a scalar unit.[10] A core architectural change in v6e is the expansion of the systolic-array MXU from 128x128 (used in TPU v2 through v5p) to 256x256 multiply-accumulators.[16][21] The 256x256 array quadruples the number of multiply-accumulate operations executed per MXU cycle relative to v5p. Combined with a higher clock speed and other microarchitectural improvements, the change delivers approximately 4.7x the BF16 peak throughput of v5e at the chip level.[21]
The MXUs support bfloat16 and INT8 natively, with BF16 inputs producing BF16 or FP32 accumulator outputs.[10]
SparseCore
Trillium ships with Google's third-generation SparseCore, a dataflow processor distinct from the MXU and designed to accelerate the irregular memory-access patterns associated with large embedding tables found in ranking, recommendation, and retrieval-augmented models.[1][22] Google describes the SparseCore in Trillium as "a specialized accelerator for processing ultra-large embeddings common in advanced ranking and recommendation workloads."[1] Where v5p included four SparseCores per chip, v6e includes two SparseCores per chip, each with dedicated memory channels.[22] Google reports a 2x improvement in embedding performance and a 5x improvement on the DLRM DCNv2 recommendation benchmark relative to v5e.[11]
Memory subsystem
Trillium's HBM stack provides 32 GB of capacity per chip, exactly double the 16 GB found in TPU v5e and though well below the 95 GiB per chip of the performance-class v5p.[10][11] Google states that "doubling the HBM capacity and bandwidth allows Trillium to work with larger models with more weights and larger key-value caches."[1] HBM bandwidth is 1,638 GB/s per chip in Google's documentation (often rounded to 1,640 GB/s), roughly double the v5e figure.[10] Each Trillium host VM provides 1,536 GiB of DRAM, a 3x increase over v5e, which Google leverages for "host-offloading" of optimizer state and activations during training of large models such as Llama-3.1-405B.[11][23]
Inter-chip interconnect
Each Trillium chip exposes four ICI ports for a combined 800 GB/s of inter-chip interconnect bandwidth, twice the per-chip ICI capacity of v5e.[10] Google notes that "doubling the ICI bandwidth enables training and inference jobs to scale to tens of thousands of chips."[1] Within a single pod the chips are arranged in a 2D torus, the same topology family used by v2, v3, and v5e (in contrast to the 3D torus used by v4 and v5p).[16][22] Total bisection bandwidth within a Trillium pod is 3.2 TB/s and the pod-wide all-reduce bandwidth is 102.4 TB/s.[10]
What are Trillium's key specifications?
The table below collects Trillium's per-chip and per-pod specifications alongside the corresponding TPU v5e figures, which Google uses as the baseline for its headline comparisons.[1][10][11]
| Specification | Trillium (TPU v6e) | TPU v5e | Change |
|---|---|---|---|
| Peak BF16 compute per chip | ~918 TFLOPS | ~197 TFLOPS | ~4.7x[1][11] |
| Peak INT8 per chip | 1,836 TOPS | ~393 TOPS | ~4.7x[10] |
| HBM capacity per chip | 32 GB | 16 GB | 2x[1][11] |
| HBM bandwidth per chip | 1,638 GB/s | 800 GiB/s | ~2x[1][10] |
| ICI bandwidth per chip | 800 GB/s | 400 GB/s | 2x[1][10] |
| SparseCore | 3rd gen (two per chip) | none | added vs v5e[1][22] |
| Chips per pod | 256 (16x16 2D torus) | 256 (2D torus) | same scale[1][10] |
| Pod all-reduce bandwidth | 102.4 TB/s | (lower) | higher[10] |
| Energy efficiency vs v5e | over 67% better | baseline | >67%[1][11] |
Form factor and pod topology
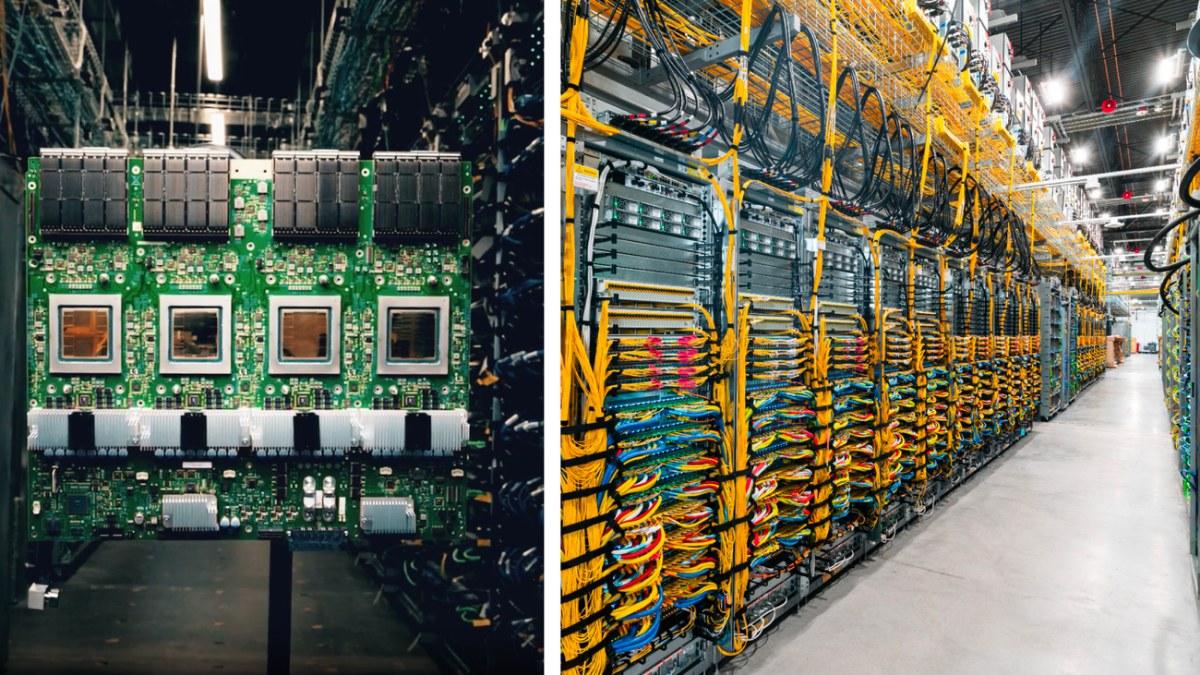
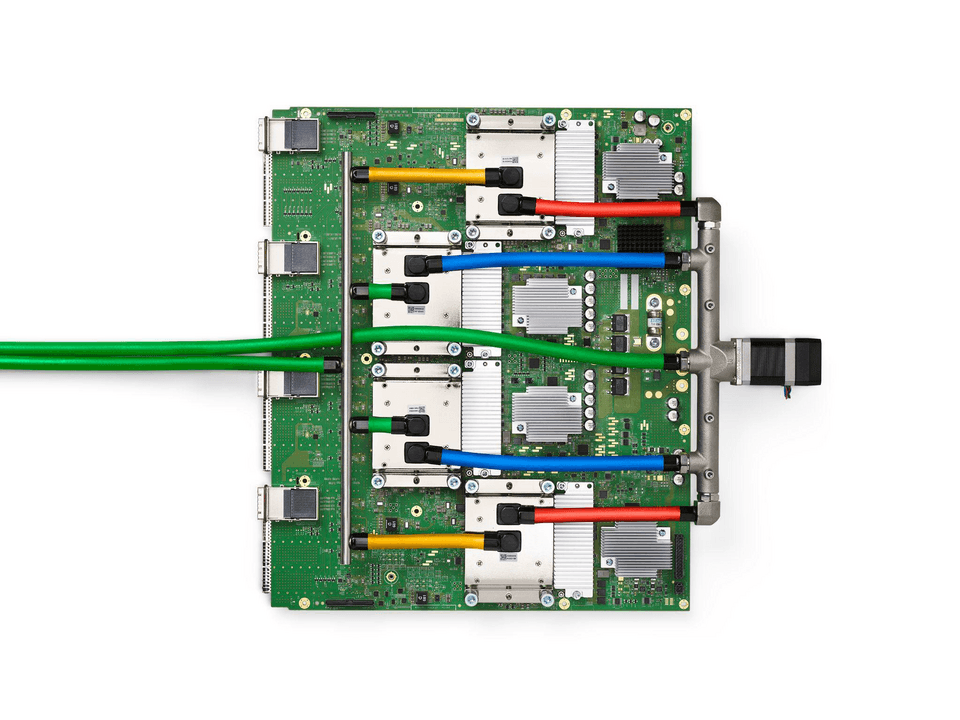
The Trillium board Google showed publicly at SC24 carries four v6e chips.[24] A full host machine pairs eight chips with 1,536 GiB of DRAM and 4x200 Gbps host network connectivity, identified in Google Cloud as the ct6e-standard-8t machine type.[10] Smaller machine types, including ct6e-standard-1t for a single chip and ct6e-standard-4t for a 2x2 slice, are also available for development and small-scale serving.[10]
The 256-chip pod ("Trillium-256") is interconnected as a 16x16 2D torus and serves as the elementary "slice" of Trillium capacity.[10] Google states that "Trillium can scale up to 256 TPUs in a single high-bandwidth, low-latency pod."[1] Supported user-visible slice topologies range from 1x1 (a single chip) up to 16x16 (256 chips); the 2x4 (eight-chip) configuration is highlighted by Google as the recommended sweet spot for inference on a single VM.[10]
Beyond the 256-chip pod, multiple pods can be stitched together with Google's "multislice" software stack and Titanium infrastructure offloads. Titanium uses host adapters, the data-center-wide rail-aligned network, and other accelerator-side offloads to extend Trillium training jobs across pod boundaries.[11][12] At the cluster level, Google has connected more than 100,000 Trillium chips through its Jupiter network fabric, which provides 13 petabits per second of bisection bandwidth, large enough to serve a single distributed training job at hundreds of thousands of accelerators.[11][12]
Software stack
Trillium uses the same XLA, JAX and PyTorch/XLA software stack as previous TPU generations, an intentional design decision that minimizes migration cost for customers moving from v5e or v5p.[25] Workloads are typically expressed in JAX or PyTorch (via PyTorch/XLA) and lowered to the XLA compiler, which targets the TPU instruction set and is jointly maintained by Google as the canonical TPU code generator.[25] Google also supports TensorFlow on TPU and ships reference distributed-training stacks including MaxText, an open-source LLM pre-training and post-training framework written in Python and JAX, and MaxDiffusion for diffusion models.[25][7]
The XLA stack received meaningful improvements alongside Trillium's launch. The compiler exposes new scheduling and host-offloading passes that exploit Trillium's 3x larger host DRAM by moving optimizer state, activations, and infrequently-accessed weights off-chip to host memory, returning them just in time for the next computational step. This is the mechanism behind Google's reported >50% MFU improvement on Llama-3.1-405B training.[11][39] Trillium's GA also introduced "collections scheduling," a scheduling capability that manages multiple TPU slices serving an inference workload as a collection, so the number of replicas can be adjusted to match demand.[11]
Higher-level orchestration on Trillium is provided through Google's "AI Hypercomputer" stack, which combines the chip and pod with Pathways (Google's runtime for orchestrating large-scale TPU jobs across hundreds of pods), Google Kubernetes Engine (GKE) integration, and Dynamic Workload Scheduler (DWS) for queueing and reservations.[11][26] DWS's Flex-start mode allows bursty workloads to consume Trillium capacity without long-term commitments, which Google explicitly highlights as a use case for fine-tuning and short-horizon experimentation.[1] For third-party developers, Hugging Face and Google jointly developed the open-source Optimum-TPU library, which exposes the Hugging Face Transformers and TGI ecosystems on Trillium with TPU-specific optimizations.[1][27]
For inference, Trillium is supported by Google's JetStream serving engine and by community projects including vLLM (via a unified TPU backend that lowers PyTorch and JAX to XLA). Google reports that with JetStream, Trillium delivers 2.9x the throughput of v5e on Llama 2 70B and 2.8x on Mixtral 8x7B, and customer Osmos said it reached over 3,500 tokens per second per v6e node for long-sequence inference on 70B-class models using vLLM and JetStream.[28]
How fast is Trillium compared to TPU v5e?
Google's headline claim is that Trillium delivers a 4.7x increase in peak compute per chip over TPU v5e, and at general availability the company reported "over 4x improvement in training performance" and "up to 3x increase in inference throughput" on representative real-world workloads.[1][11] The deeper per-workload figures are broken out in the subsections that follow. In Google's words, Trillium achieves "an impressive 4.7X increase in peak compute performance per chip compared to TPU v5e."[1]
Training
In Google's own benchmarks comparing Trillium to TPU v5e under matched software stacks, Trillium achieves up to 4x faster training on dense large language models including Llama 2-70B and GPT-3-175B, and up to 3.8x faster training on mixture-of-experts (mixture of experts) models.[11] Across smaller dense models such as Gemma 2-9B and Llama-2-7B, training speedups of 3x or more over v5e are reported.[7] Scaling efficiency across pods is reported at 99% on a 12-pod (3,072-chip) configuration training GPT-3-175B and 94% on a 24-pod (6,144-chip) configuration, with near-99% efficiency for Llama-2-70B across 4-36 pods.[11] Across Gemma 2-27B and MaxText default-32B benchmarks, training speedups above 4x over v5e are reported.[7]
When training the 405-billion-parameter Llama 3.1 model with host-offloading enabled, Trillium demonstrates greater than 50% improvement in model FLOPs utilization (MFU) versus v5e at equivalent settings, illustrating the benefit of the chip's tripled host DRAM and improved compiler scheduling.[11] These figures are gathered on Google's own clusters and use the MaxText reference implementation as a baseline, allowing direct apples-to-apples comparison between v5e and v6e on identical kernels.[7][25]
Google trained Gemini 2.0 Flash and the larger frontier models in the Gemini 2 family on Trillium pods at GA, with Sundar Pichai stating that "TPUs powered 100% of Gemini 2.0 training and inference."[29][43] Although Google does not publish exact chip counts for individual Gemini training runs, the company stated at the Trillium GA event that it has deployed more than 100,000 Trillium chips into a single Jupiter-fabric cluster, and DigiTimes and other outlets have reported this as the primary substrate for the Gemini 2 generation.[12][40]
Inference
For inference on Stable Diffusion XL (stable diffusion), Trillium offers 3.1x higher throughput in offline configuration and 2.9x higher throughput in server configuration relative to v5e.[11] The cost per 1,000 generated images at server-mode is reduced by 22% and at offline-mode by 27% relative to v5e at GA pricing, and a May 2025 Google post put the cost of generating 1,000 SDXL images on Trillium as low as 22 cents at 3-year committed-use prices.[11][28] For Llama-2-70B inference, Trillium delivers nearly 2x the tokens-per-second of v5e.[11]
Trillium was submitted to MLPerf Inference v5.0 in early 2025, where Google said Trillium delivered a 3.5x queries-per-second improvement on Stable Diffusion XL over v5e's result in the previous round.[28][41] Customer Osmos described its vLLM and JetStream deployment on Trillium as giving it "industry leading" tokens per second per dollar for 70B-class models.[28]
Energy efficiency
Trillium chips deliver greater than 67% improvement in energy efficiency over TPU v5e at matched workloads.[1][11] Google's exact phrasing is that "our sixth-generation TPUs are also our most sustainable: Trillium TPUs are over 67% more energy-efficient than TPU v5e."[1] Google describes Trillium as "the most performant and most energy-efficient TPU to date."[1] At the I/O 2024 keynote, Pichai cited the energy advance as a response to a roughly 1,000,000x increase in industry demand for machine-learning compute over the preceding six years.[6][42]
Pricing and availability
At general availability in December 2024, Trillium was made available across multiple Google Cloud regions, including locations in North America, Europe, and Asia-Pacific.[30] Google's Cloud TPU pricing page lists v6e at US$2.70 per chip-hour on demand in us-east1 (more in some other regions), US$1.35 under Dynamic Workload Scheduler Flex-start, and US$1.89 and US$1.22 per chip-hour with 1-year and 3-year commitments.[44]
In published price-performance comparisons against the prior generations, Google reports:
- Up to 2.1x training performance per dollar versus TPU v5e.[11]
- Up to 2.5x training performance per dollar versus TPU v5p.[11]
- Up to 1.4x inference throughput per dollar versus v5e at matched workloads.[11]
These figures reflect Google's internal benchmark normalization and on-demand pricing at GA. Independent third-party benchmarks have reached different conclusions in some categories; for example, Artificial Analysis's hardware benchmarking reported in 2025 that for their composite inference-cost metric, NVIDIA H100 and B200 systems achieved roughly a 5x tokens-per-dollar advantage over Trillium under their test conditions (for Llama 3.3 70B on vLLM, US$1.06 per million input and output tokens on H100 versus US$5.13 on TPU v6e).[32]
What was Trillium used to train?
Google states that it "used Trillium TPUs to train the new Gemini 2.0, Google's most capable AI model yet," and Pichai has said that "TPUs powered 100% of Gemini 2.0 training and inference."[11][43] Beyond Gemini, Google has disclosed that earlier and contemporaneous TPU generations trained and serve models such as Gemini 1.5 Flash, Imagen 3, and Gemma 2.[1] External customers train other model families on Trillium pods, and the full set of publicly disclosed deployments is detailed in the next section.
Customers and deployments
Although the majority of Trillium chips are consumed internally by Google for Gemini training, Search, YouTube, and other workloads, several external customers have publicly disclosed adoption:
-
Anthropic: Anthropic has used Google Cloud TPUs since a strategic partnership announced in 2023, and trains and runs its Claude models on Google TPUs, AWS Trainium and NVIDIA GPUs, with Amazon as its primary training partner.[33][35] In October 2025, Anthropic announced an expansion of its TPU use with Google Cloud covering up to one million TPU chips and well over a gigawatt of capacity coming online in 2026, and in April 2026 it signed a further agreement with Google and Broadcom for multiple gigawatts of next-generation TPU capacity starting in 2027.[33][34][35]
-
Apple: Apple's foundation models that power Apple Intelligence were pretrained on TPU v4 and v5p (not on Trillium), as disclosed in Apple's July 2024 foundation-models paper. Specifically, the server-side AFM-server was trained on 8,192 TPU v4 chips arranged as 8x1,024 slices, and the on-device AFM-on-device was trained on 2,048 TPU v5p chips.[19][20] While Apple has not publicly disclosed Trillium-specific deployments, the relationship is one of the most-cited demonstrations that frontier-scale foundation models can be trained without NVIDIA H100 GPUs.[36]
-
AI21 Labs: A long-standing TPU customer since v4, AI21 trains its Mamba- and Jamba-architecture language models on Trillium pods.[11] CTO Barak Lenz stated at GA that "Trillium will be essential in accelerating the development of our next generation of sophisticated language models."[11]
-
Hugging Face: Hugging Face and Google collaboratively built the Optimum-TPU library, bringing the Hugging Face model and training stack to Trillium for use by community developers.[1][27]
-
Deep Genomics: Uses Trillium for inference on its BigRNA model, scanning tens of millions of RNA variants for drug-discovery applications.[7]
-
HubX: Reported 35% latency reduction and 45% cost-per-image reduction running its MaxDiffusion-based FLUX.1 text-to-image pipeline on Trillium.[7]
-
Lightricks: Plans to scale its text-to-video models on Trillium after achieving 2.5x speedups on v5p; named the AI Hypercomputer stack as a key factor in adoption.[1][7]
-
Essential AI, Nuro, and Deloitte were named at the I/O 2024 announcement as additional Trillium customers.[1]
How does Trillium compare with other AI accelerators?
Industry analysis at the time of Trillium's launch positioned the chip as one of the most credible non-NVIDIA training substrates for frontier models. Trillium's 918 BF16 TFLOPS per chip is below NVIDIA H100's 989 BF16 TFLOPS per device, and its 1,836 INT8 TOPS is also below the H100's dense INT8 throughput, and Trillium's 32 GB HBM and 1.64 TB/s bandwidth are smaller than the 80 GB / 3.35 TB/s of an H100 SXM. However, the chip's interconnect-aware system design and lower per-chip cost change the comparison at pod scale, where Trillium's 256-chip pod with 102 TB/s all-reduce bandwidth competes favorably with NVIDIA NVLink-connected H100 nodes for many distributed training topologies.[10][37] The launch of NVIDIA Blackwell and the NVIDIA Blackwell B200 in 2024-2025 reset the per-chip comparison, with B200 offering substantially more compute and HBM3e per device; Google's response, particularly for inference, has been the Trillium-succeeding TPU Ironwood rather than a v6 die shrink.[14][32]
A 2025 independent benchmarking study by Artificial Analysis compared Trillium against B200 and AMD MI300X for inference economics on a representative LLM workload. The study reported that NVIDIA systems (H100 and B200) achieved approximately 5x the tokens-per-dollar of Trillium and approximately 2x the tokens-per-dollar of MI300X under their test conditions and pricing assumptions, using Llama 3.3 70B on vLLM.[32] Such cost figures depend strongly on serving-framework maturity, batch size and pricing, and Google has continued to invest in the JetStream and vLLM TPU stacks.[28]
Among hyperscaler-designed accelerators, Trillium is most directly compared with AWS Trainium2 from Amazon (announced November 2023, generally available December 2024) and Microsoft Azure's Maia 100. Trillium's 256-chip 2D-torus pod is a larger single interconnect domain than a Trn2 UltraServer, which links 64 Trainium2 chips with NeuronLink and scales further over EFA networking; Trillium's compiler stack is rooted in XLA and JAX.[11][45] Anthropic runs Claude training and serving across both stacks, as well as on NVIDIA GPUs, and has publicly emphasized the resulting heterogeneity as a strategic advantage rather than as a single-vendor dependency.[33][34]
What replaced Trillium? Ironwood (TPU v7)
TPU Ironwood, the seventh-generation TPU, was announced by Google at Cloud Next 2025 in Las Vegas on April 9, 2025 and reached general availability in November 2025.[13][14] Google explicitly positions Ironwood as "the first TPU for the age of inference," while also marketing it for large-scale training; Ironwood adds a much larger 9,216-chip liquid-cooled pod and significantly larger per-chip resources.[13][14]
Per Google's published specifications, Ironwood delivers 192 GB of HBM per chip (6x Trillium), 7.37 TB/s of HBM bandwidth per chip (4.5x Trillium), 1.2 TBps bidirectional ICI bandwidth (1.5x Trillium), and approximately 4,614 FP8 TFLOPS per chip; Google describes Ironwood as offering "more than 4x better performance per chip" than Trillium for both training and inference on representative workloads, and "2x perf/watt" relative to Trillium at the system level.[13][14] A full 9,216-chip Ironwood pod delivers approximately 42.5 exaflops of compute, exceeding the publicly disclosed throughput of the fastest non-AI supercomputers at the time of launch.[14]
Despite Ironwood's larger pod size, Trillium is not retired with the new generation. Google still sells v6e capacity alongside Ironwood, at a much lower per-chip-hour price, which leaves Trillium as a lower-cost option for mid-size training and serving jobs while Ironwood targets very-large-scale training and high-throughput inference.[14][44] In April 2026 Google announced its eighth TPU generation, split for the first time into two chips: TPU 8t for training and TPU 8i for inference, both due to reach Google Cloud customers later in 2026.[46] The continued availability of v6e pods alongside Ironwood reflects a more general TPU lifecycle pattern in which earlier generations remain in production long after the launch of newer parts; for example, v4 and v5p pods remained generally available throughout Trillium's first year on the market.[3][4]
Continue reading
- Gemini (language model)Gemini is a family of natively multimodal large language models developed by Google DeepMind, first announced on December 6, 2023, that can reason across text, images, audio, video, and code within a single…Mentioned 18 times above
- NVIDIA B200The NVIDIA B200 is a data center GPU based on the NVIDIA Blackwell microarchitecture, announced by Jensen Huang at NVIDIA's GTC conference in San Jose on March 18, 2024.Mentioned 5 times above
- Cloud TPUCloud TPU is Google Cloud's offering of Tensor Processing Units (TPUs), the family of custom application-specific integrated circuits (ASICs) that Google builds to accelerate machine learning training and…Mentioned 4 times above
- TPU IronwoodTPU Ironwood (listed as TPU7x in Google Cloud's documentation and also called TPU v7) is Google's seventh-generation Tensor Processing UnitMentioned 3 times above
- NVIDIA H100NVIDIA H100 (also called the H100 Tensor Core GPU) is a data-center graphics processing unit built by NVIDIA on the Hopper microarchitecture, fabricated with over 80 billion transistors on a custom TSMC 4N (4…Mentioned 3 times above
- Tensor Processing Unit (TPU)A Tensor Processing Unit (TPU) is a family of custom application-specific integrated circuits developed by Google to accelerate machine-learning computation.Mentioned twice above
More from See also
Topics:AI ComputeAI HardwareGoogle
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28Google Cloud Blog, \"Introducing Trillium, sixth-generation TPUs,\" May 14, 2024. cloud.google.com/...roducing-trillium-6th-gen-tpus
- ^Google Cloud Documentation, \"TPU v6e.\" docs.cloud.google.com/...v6e
- ^1 ^2 ^3Google Cloud Documentation, \"Cloud TPU release notes.\" docs.cloud.google.com/...release-notes
- ^1 ^2 ^3Introl, \"Google TPU Architecture: 7 Generations Explained.\" introl.com/...tecture-complete-guide-7-generations
- ^1 ^2 ^3 ^4HPCwire, \"Google Announces Sixth-generation AI Chip, a TPU Called Trillium,\" May 17, 2024. hpcwire.com/...ation-ai-chip-a-tpu-called-trillium
- ^1 ^2 ^3 ^4TechCrunch, \"Google's next-gen TPUs promise a 4.7x performance boost,\" May 14, 2024. techcrunch.com/...promise-a-4-7x-performance-boost
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10Google Cloud Blog, \"Trillium sixth-generation TPU is in preview,\" October 30, 2024. cloud.google.com/...h-generation-tpu-is-in-preview
- ^1 ^2 ^3 ^4 ^5 ^6Google blog, \"Trillium TPU, our most powerful AI chip yet, is now generally available,\" December 2024. blog.google/...trillium-tpus
- Hacker News discussion quoting the Google Cloud Trillium GA blog, \"We used Trillium TPUs to train the new Gemini 2.0.\" news.ycombinator.com/item
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18Google Cloud Documentation, \"TPU v6e\" (specifications page). docs.cloud.google.com/...v6e
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32 ^33 ^34 ^35 ^36 ^37 ^38 ^39Google Cloud Blog, \"Trillium TPU is GA,\" December 12, 2024. cloud.google.com/...trillium-tpu-is-ga
- ^1 ^2 ^3 ^4SiliconANGLE, \"Google Cloud moves its AI-focused Trillium chips into general availability,\" December 11, 2024. siliconangle.com/...ium-chips-general-availability
- ^1 ^2 ^3 ^4 ^5 ^6Google Blog, \"Ironwood: The first Google TPU for the age of inference,\" April 9, 2025. blog.google/...ironwood-tpu-age-of-inference
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Google Cloud Blog, \"Ironwood TPUs and new Axion-based VMs for your AI workloads.\" cloud.google.com/...ased-vms-for-your-ai-workloads
- ^1 ^2 ^3 ^4 ^5 ^6Wikipedia, \"Tensor Processing Unit.\" en.wikipedia.org/...Tensor_Processing_Unit
- ^1 ^2 ^3 ^4 ^5Medium / Women in Technology, \"Google Cloud TPU Architecture Versions Explained: From v1 to the Eighth Generation.\" medium.com/...o-the-eighth-generation-3f2371962154
- ^1 ^2 ^3Google Cloud Documentation, \"TPU architecture.\" docs.cloud.google.com/...system-architecture-tpu-vm
- ^1 ^2DEV Community / Grace, \"Google Cloud TPU Architecture Versions Explained.\" dev.to/...ned-from-v1-to-the-eighth-generation-3pm
- ^1 ^2The Register, \"Apple snubs Nvidia for AI training kit, chooses Google,\" July 30, 2024. theregister.com/...apple_google_tpu_ai
- ^1 ^2MacRumors, \"Apple Used Google Tensor Chips to Develop Apple Intelligence,\" July 30, 2024. macrumors.com/...sed-to-develop-apple-intelligence
- ^1 ^2The Next Platform, \"Lots Of Questions On Google's Trillium TPU v6, A Few Answers,\" June 10, 2024. nextplatform.com/...-trillium-tpu-v6-a-few-answers
- ^1 ^2 ^3 ^4Rajat Pandit, \"Demystifying the TPU SparseCore: The Hidden Workhorse of Recommendation Systems.\" rajatpandit.com/...tpu-sparsecore-rec-systems
- ^Gigazine, \"Google's AI processing chip 'Trillium' now available via Google Cloud,\" December 12, 2024. gigazine.net/...20241212-google-tpu-trillium
- ^ServeTheHome, \"Google Cloud TPU v6e Trillium Shown at SC24.\" servethehome.com/...tpu-v6e-trillium-shown-at-sc24
- ^1 ^2 ^3 ^4Google Cloud Documentation, \"Building production AI on Cloud TPUs with JAX.\" docs.cloud.google.com/...jax-ai-stack
- ^SiliconANGLE, \"Google Cloud turbocharges its AI Hypercomputer stack with next-gen TPUs and bigger GPU clusters.\" siliconangle.com/...t-gen-tpus-bigger-gpu-clusters
- ^1 ^2Hugging Face, \"Optimum TPU.\" huggingface.co/...index
- ^1 ^2 ^3 ^4 ^5Google Cloud Blog, \"AI Hypercomputer inference updates for Google Cloud TPU and GPU.\" cloud.google.com/...s-for-google-cloud-tpu-and-gpu
- ^VentureBeat, \"Google's new Trillium AI chip delivers 4x speed and powers Gemini 2.0.\" venturebeat.com/...-4x-speed-and-powers-gemini-2-0
- ^Google Cloud Documentation, \"TPU regions and zones.\" docs.cloud.google.com/...regions-zones
- AI News Hub, \"Nvidia to Google TPU Migration 2025: The $6.32B Inference Cost Crisis,\" summarizing Google Cloud TPU pricing. ainewshub.org/...s-google-tpu-2025-cost-comparison
- ^1 ^2 ^3Artificial Analysis, hardware benchmarking comparing Google TPU v6e, AMD MI300X, and NVIDIA H100/B200, 2025. x.com/...1993878037226557519
- ^1 ^2 ^3Anthropic, \"Expanding our use of Google Cloud TPUs and Services.\" anthropic.com/...of-google-cloud-tpus-and-services
- ^1 ^2Anthropic, \"Anthropic expands partnership with Google and Broadcom.\" anthropic.com/...google-broadcom-partnership-compute
- ^1 ^2Google Cloud, \"Anthropic to Expand Use of Google Cloud TPUs and Services,\" October 23, 2025. googlecloudpresscorner.com/...ud-TPUs-and-Services
- ^Tom's Hardware, \"Apple skips Nvidia's GPUs for its AI models, uses thousands of Google TPUs instead.\" tomshardware.com/...ousands-of-google-tpus-instead
- ^Spheron Blog, \"Google TPU Trillium v6 vs NVIDIA B200: LLM Inference Cost and Migration Guide.\" spheron.network/...v6-vs-nvidia-b200-llm-inference
- ^1 ^2 ^3The Chip Letter, \"Google's First Tensor Processing Unit: Origins.\" thechipletter.substack.com/...nsor-processing-unit
- ^Google Cloud Documentation, \"Train an LLM using JAX, Ray Train, and TPU Trillium on GKE.\" docs.cloud.google.com/...distributed-training-tpu
- ^DigiTimes, \"Google unveils Gemini 2.0 and next-gen TPU Trillium, ushering in the era of AI agents.\" digitimes.com/...e-gemini-tpu-performance-training
- ^MLCommons, \"MLPerf Inference v5.0 Benchmark Results.\" mlcommons.org/...mlperf-inference-v5-0-results
- ^Ernest Chiang, \"Think in Context: Google I/O 2024 Keynote With Google CEO Sundar Pichai.\" ernestchiang.com/...-with-google-ceo-sundar-pichai
- ^1 ^2 ^3Google Blog, \"Introducing Gemini 2.0: our new AI model for the agentic era,\" December 11, 2024. blog.google/...google-gemini-ai-update-december-2024
- ^1 ^2Google Cloud, \"Cloud TPU pricing.\" Accessed November 2026. cloud.google.com/...pricing
- ^Amazon Web Services, \"Amazon EC2 Trn2 Instances.\" aws.amazon.com/...trn2
- ^1 ^2Tom's Hardware, \"Inside Google's TPU V8 strategy, delivering two chips for two crucial tasks at incredible scale,\" April 2026. tomshardware.com/...raining-and-inference-variants
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
8 revisions by 1 contributor · v8 · 4,974 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (165 claims, 44 sources fetched); 14 material + 29 minor fixed
Cite this page: AI Wiki. "Trillium (TPU v6e)." aiwiki.ai, updated 28 Jun 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/google_trillium