

MiniMax M2
MiniMax M2 is an open-weight large language model released on October 27, 2025 by the Shanghai-based AI company MiniMax, built as a Mixture of Experts model with 230 billion total parameters and roughly 10 billion active parameters per token and tuned specifically for coding and agentic workflows rather than general chat. At launch it topped the Artificial Analysis Intelligence Index among open-weight systems with a composite score of 61, shipped under a permissive MIT license, and was priced at about US$0.30 per million input tokens and US$1.20 per million output tokens, which MiniMax pitched as roughly 8 percent of the price of Anthropic's Claude Sonnet 4.5 while running at nearly twice the speed.123
MiniMax describes the design as a deliberately compact "mini" model intended to maximize throughput, lower the cost of long agent loops, and run inside developer tools like Claude Code, Cursor, and Cline. The Hugging Face model card frames it as "a Mini model built for Max coding & agentic workflows," and the launch post sums up the guiding idea as: "The core principle is simple: to create a model that meets our requirements, we must first be able to use it ourselves."145
The weights were published on Hugging Face under an MIT license at launch, and the MiniMax Open Platform offered a limited-time free API trial that ran through early November 2025. The list price after the free period was set at 2.1 yuan (around US$0.30) per million input tokens and 8.4 yuan (around US$1.20) per million output tokens.16 On the Artificial Analysis Intelligence Index, M2 took the top spot among open-weight systems at the time of release, with a composite score of 61 and standout numbers on tool-use, search, and end-to-end software-engineering benchmarks such as SWE-bench Verified, Terminal-Bench, and BrowseComp.43
MiniMax M2 has since been succeeded by M2.1 (December 2025), M2.5, M2.7, and MiniMax M3 (June 2026).72 The model is the third generation of MiniMax's open foundation-model line after MiniMax-Text-01 and MiniMax M1, and the first that explicitly trades long-context capacity for active-parameter efficiency. Where M1 advertised a 1 million-token context window built on "lightning attention," M2 ships with a 204,800-token window and a standard MoE transformer, with the savings reinvested into a fast inference path designed for agent harnesses that fire dozens of short tool calls per session.65
What company makes MiniMax M2?
MiniMax (Chinese: Shanghai Xiyu Technology) was founded in December 2021 by computer-vision researchers who had previously worked at SenseTime, including chief executive Yan Junjie, Yun Yeyi, and Zhou Yucong. The company received early backing from MiHoYo, the studio behind Genshin Impact, and went on to raise a $600 million round led by Alibaba in March 2024 at a valuation of roughly $2.5 billion. It listed on the Hong Kong Stock Exchange on January 9, 2026.7
MiniMax is one of China's "Six Little Tigers" (六小虎) of AI alongside Moonshot, Zhipu, Baichuan, 01.AI, and StepFun. Its consumer products include the Hailuo AI text-to-video and image generator, the MiniMax Audio TTS platform, and Talkie, an English-language AI-companion app that the Wall Street Journal reported had around 11 million monthly active users in mid-2024. On the model side, MiniMax has shipped the ABAB series of MoE chat models, the MiniMax-01 family that introduced lightning attention at scale, and the M1 reasoning model released in June 2025.78
M1 was significant in its own right because MiniMax claimed it had trained the 456B-parameter base for around US$534,700 in compute rentals, roughly 1/200th of the estimated training cost of GPT-4o. That number got attention partly because it landed in the wake of DeepSeek's V3 paper, which had already set a low-cost benchmark for Chinese open models, and partly because M1 paired the cheap-training story with a 1 million-token context window. M2 was developed in the same cost-conscious tradition but pointed at a different problem: making agent tool-call loops fast and cheap enough to leave running.89
How is MiniMax M2 built?
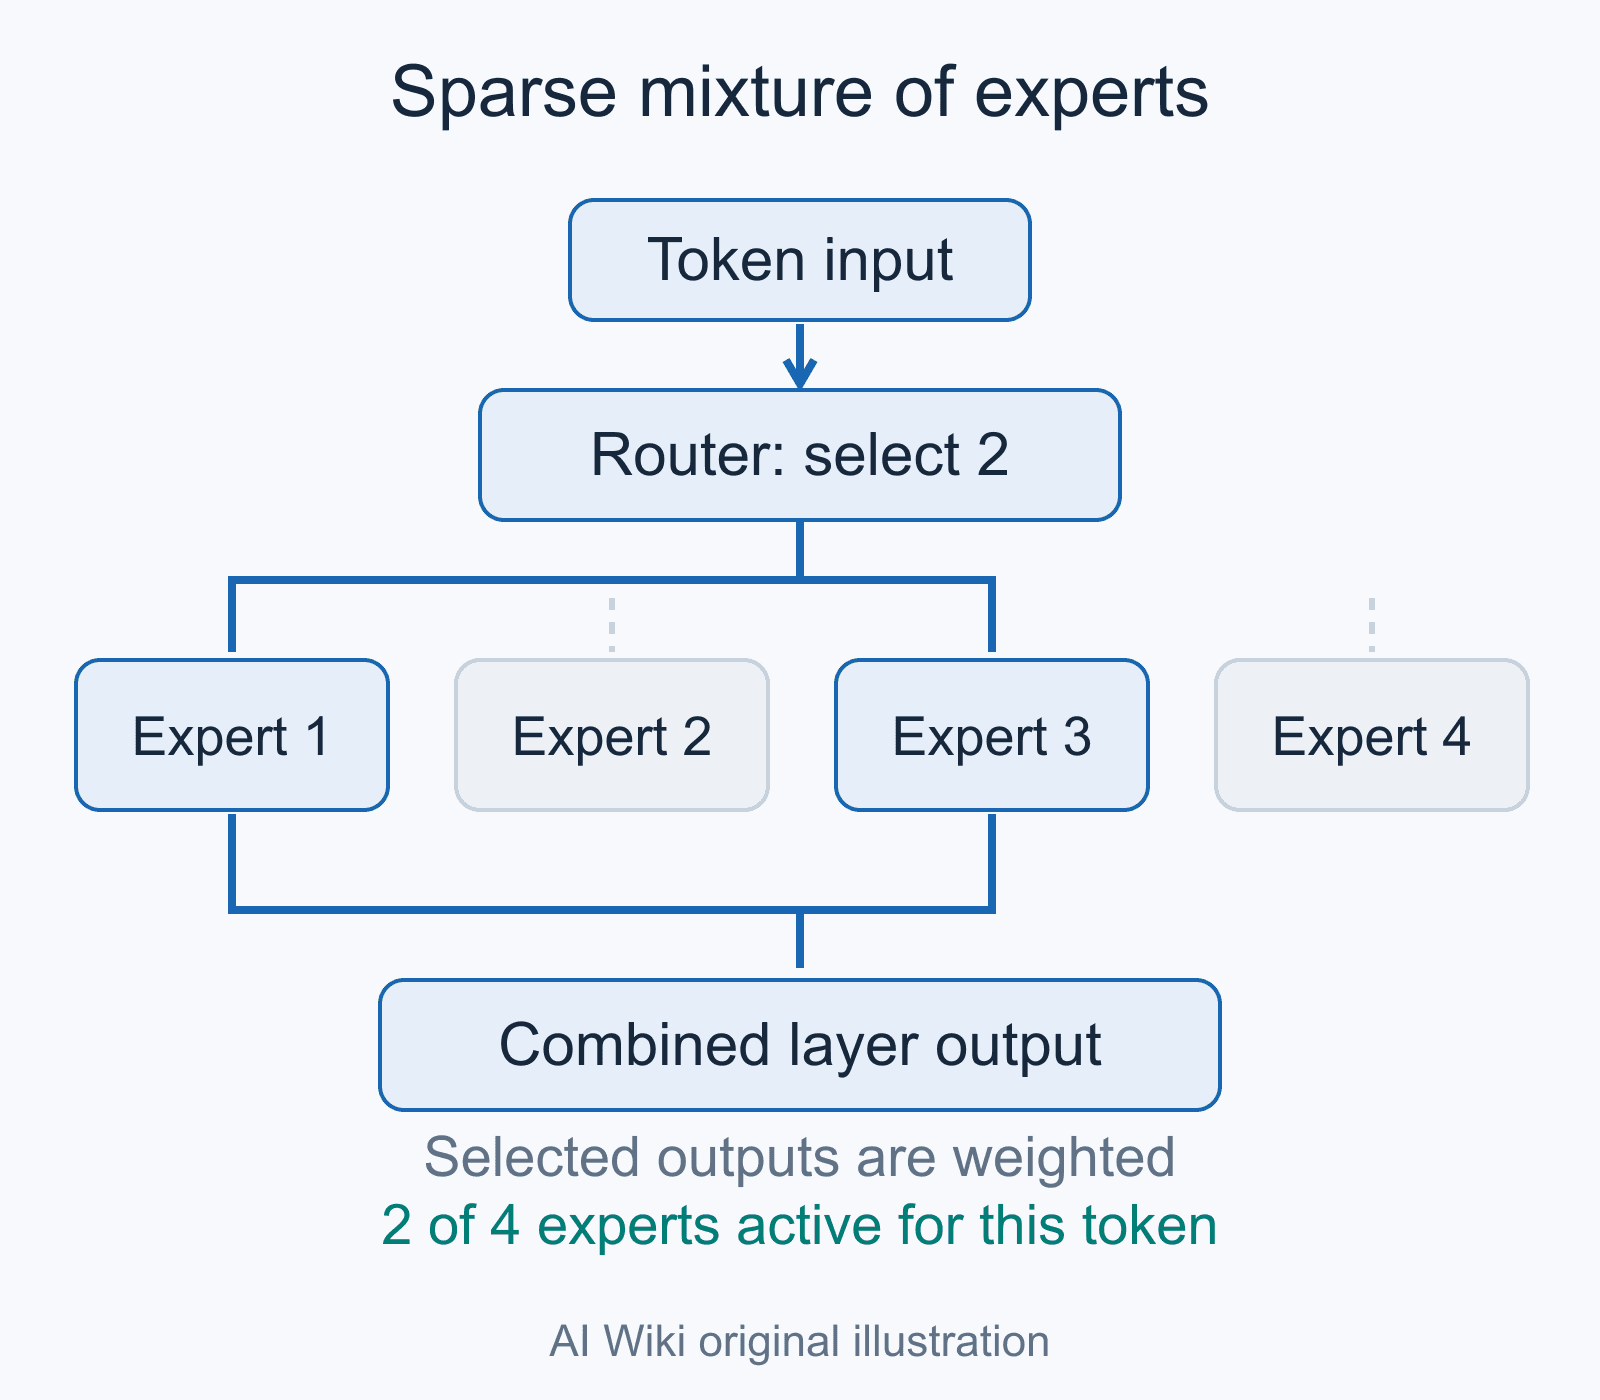
MiniMax M2 is a sparse Mixture of Experts transformer with 229 to 230 billion total parameters and approximately 10 billion active parameters per forward pass, depending on routing. The Hugging Face model card frames the design philosophy as "compact, fast, and cost-effective," with the small active footprint chosen so that interactive agent loops do not have to wait for the full model on every step. Artificial Analysis noted that the model is sparse enough to be served on as few as four NVIDIA H100 GPUs at FP8 precision.452
The architecture details published by MiniMax are deliberately spare. The README on GitHub lists the model as MoE with the 230B/10B split, recommends SGLang and vLLM as first-class inference runtimes with day-zero kernels, and ships an MLX-LM option for local Apple Silicon use. The prose documentation does not describe the layer layout, but the config.json published with the weights specifies 62 layers, 256 routed experts with 8 active per token, 48 attention heads (8 key-value heads), and a hidden size of 3,072.454
Context length and output
M2 supports a context window of 204,800 tokens (often rounded to 205K) and the same on output. That is a substantial step down from M1's million-token window. Caixin noted the cut from M1's 1 million tokens to 204,800 but MiniMax gave no published rationale for it.6
Interleaved thinking
A distinctive feature is what MiniMax calls interleaved thinking. The model is trained to emit reasoning content inside <think>...</think> blocks between assistant turns, and MiniMax instructs callers to keep those blocks in the conversation history rather than stripping them out. The model card warns: "you must ensure that the historical content is passed back in its original format. Do not remove the <think>...</think> part, otherwise, the model's performance will be negatively affected." Removing the thinking traces in multi-turn agent settings, according to the card, significantly degrades performance because later steps lean on the earlier reasoning. The pattern is similar in spirit to Anthropic's interleaved extended thinking but is exposed as a first-class part of the protocol.410
Recommended inference settings
MiniMax recommends temperature 1.0, top-p 0.95, and top-k 40 for M2. 45
How was MiniMax M2 trained?
MiniMax has not published a training paper for M2 as of mid-2026, and the public material is light on specifics about the data mix, total token count, hardware, or reinforcement-learning recipe. The Hugging Face card describes M2 as "engineered for end-to-end developer workflows" and lists the kinds of tasks that drove the post-training mix, including multi-file edits, run-and-fix loops on compilation and test errors, terminal use, web browsing, and structured tool calling. The model is described as having been trained with interleaved thinking as a native output format from early in post-training rather than as a wrapper layer added on top of an existing chat model.45
MiniMax also has not published a training-cost figure for M2 in the same way it did for M1. The general framing in the launch coverage is that the small active-parameter count and aggressive use of agent-style RL on coding traces are what allows the model to outperform much larger open models on agentic benchmarks while staying cheap to serve.36
How does MiniMax M2 perform on benchmarks?
The primary benchmark numbers below come from the Hugging Face model card, where MiniMax publishes its own results alongside the evaluation harness used (an R2E-Gym scaffold on OpenHands for SWE-bench Verified, the claude-code CLI for Multi-SWE-Bench, SWE-bench Multilingual and Terminal-Bench, OpenHands 0.42 for AgentCompany, and so on). Numbers from third parties such as Artificial Analysis are noted where they are relevant.42
Coding and software engineering
| Benchmark | MiniMax M2 score | Notes |
|---|---|---|
| SWE-bench Verified | 69.4 | 100 max steps, 128K context, R2E-Gym scaffold on OpenHands |
| Multi-SWE-Bench | 36.2 | Averaged across 8 runs |
| SWE-bench Multilingual | 56.5 | Cross-language repository tasks |
| LiveCodeBench | 83 | Per Artificial Analysis composite |
| ArtifactsBench | 66.8 | Averaged across 3 runs |
| SciCode | 36 | Scientific coding subset |
The SWE-bench Verified number is the headline figure for coding. At 69.4, M2 lands well above earlier open-weight reasoning models such as DeepSeek-R1 and is within a few points of Anthropic's Claude Sonnet 4.5, which scored around 77.2 on the same benchmark in the period after launch. MiniMax notes that its SWE-bench Verified runs use the R2E-Gym scaffold on top of OpenHands, while its Multi-SWE-Bench, SWE-bench Multilingual, and Terminal-Bench runs use the claude-code CLI.411
Agentic and tool-use
| Benchmark | MiniMax M2 score | Notes |
|---|---|---|
| Terminal-Bench | 46.3 | Averaged across 8 runs |
| Terminal-Bench-Hard | 24.0 | Hard subset |
| BrowseComp | 44.0 | English web research |
| BrowseComp-zh | 48.5 | Chinese variant |
| GAIA (text only) | 75.7 | 103-sample validation subset |
| xbench-DeepSearch | 72.0 | Long-horizon search |
| FinSearchComp-global | 65.5 | Financial document search |
| AgentCompany | 36.0 | OpenHands 0.42 framework |
| tau-squared Bench | 77.2 | Extended thinking with tool use |
The agentic numbers are the part of the table that MiniMax highlights most. Terminal-Bench at 46.3 was the best score among the open-weight models in MiniMax's comparison table (Kimi K2 0905 was next at 44.5), while its BrowseComp score of 44 trailed GLM-4.6's 45.1. The Terminal-Bench result of 46.3 comfortably beat Claude Sonnet 4's 36.4 on the same test and came close to Claude Sonnet 4.5's 50.0. The GAIA text-only score of 75.7 also placed M2 above DeepSeek-V3.2 (63.5) and Kimi K2 0905 (60.2) on the same validation subset, although Kimi K2 Thinking later overtook M2 on some of the same metrics once Moonshot released its reasoning variant.43
General intelligence
| Benchmark | MiniMax M2 score | Notes |
|---|---|---|
| Artificial Analysis composite | 61 | #1 open-weight at launch |
| MMLU-Pro | 82 | Multi-subject reasoning |
| GPQA-Diamond | 78 | Graduate-level physics, biology, chemistry |
| AIME 2025 | 78 | High-school math olympiad |
| HLE (with tools) | 31.8 | Humanity's Last Exam with search and Python |
| HLE (no tools) | 12.5 | Closed-book |
| IFBench | 72 | Instruction following |
| AA-LCR | 61 | Long-context reasoning |
| tau-squared-Telecom | 87 | Telecom domain agents |
At launch, Artificial Analysis reported that "MiniMax's M2 achieves a new all-time-high Intelligence Index score for an open weights model and offers impressive efficiency with only 10B active parameters." Its composite of 61 placed it ahead of DeepSeek-V3.2 (57) and GLM-4.6 (56) but behind Anthropic's Claude Sonnet 4.5 and OpenAI's GPT-5 on overall composite. On agentic sub-scores it sat closer to those proprietary models, which is the part of the index MiniMax pushed hardest in its launch materials. (Artificial Analysis later migrated to a revised index version that re-scored older models downward, so the model's current page shows a lower figure; the 61 reflects the launch-era methodology.)23
It is worth noting that several of these scores are self-reported by MiniMax. The agentic browse results in particular are harder to reproduce because they depend on the exact tool harness, browser state, and rate-limit conditions used during evaluation.312
How much does MiniMax M2 cost?
M2's weights were published on Hugging Face under the plain MIT license at launch. On November 13, 2025, MiniMax amended it to a modified MIT license that requires commercial products with more than 100 million monthly active users or more than US$30 million in annual recurring revenue to prominently display "MiniMax M2" in their user interface.54 This put M2 on a more permissive footing than some peer Chinese releases that ship under custom commercial-use clauses. MiniMax later moved toward more restrictive licenses for its M2.1, M2.5, and M2.7 successors; the original M2 license itself now carries the November 2025 attribution clause, and Artificial Analysis lists it as Modified MIT.413
Hosted API pricing
MiniMax offers M2 directly through the MiniMax Open Platform and also through partners including Vercel AI Gateway, OpenRouter, NVIDIA NIM, and Microsoft Azure AI Foundry, where it was added shortly after launch.1415
| Tier | Input price | Output price | Notes |
|---|---|---|---|
| MiniMax Open Platform | $0.30 / 1M tokens | $1.20 / 1M tokens | 2.1 RMB / 8.4 RMB native |
| Free trial | $0.00 | $0.00 | Through November 7, 2025 |
| MiniMax Agent | Free | Free | Lightning Mode and Pro Mode during trial |
MiniMax described the post-trial pricing as around 8 percent of what Anthropic charges for Claude Sonnet 4.5 on a comparable token-mix basis, and reported a sustained output speed of roughly 100 tokens per second per request during launch tests, with Artificial Analysis measuring about 90 tokens per second on MiniMax's API as of November 2026. On a blended 7:2:1 cache/input/output mix, Artificial Analysis put the effective cost at about $0.39 per million tokens. The free trial covered both the API and the MiniMax Agent product built on top of M2, and the trial period was extended once before the paid tier went live.162
Self-hosting
For teams that want to run the model themselves, MiniMax's GitHub repository ships SGLang and vLLM configurations that boot M2 on a single multi-GPU node with sufficient HBM to hold the 230 billion total parameters in BF16 or FP8. Quantized GGUF builds maintained by community contributors such as Unsloth and the Cerebras MiniMax-M2-REAP-162B-A10B "reaped" variant have lowered the bar further. A 4-bit Q4 GGUF fits within roughly 130 GB of RAM, which makes the model practical for high-end workstations and small inference servers as well as cloud nodes.516
How was MiniMax M2 received?
Reception across English-language coverage was broadly positive, with most reviewers calling out the same three points: M2 was at or near the top of open-weight charts on agentic benchmarks, it was cheap enough to leave running inside coding agents without watching costs, and the small 10B active parameter count made it noticeably faster than peer open models in tight tool-call loops. VentureBeat ran a piece headlined "MiniMax-M2 is the new king of open source LLMs" within two days of the release, citing the Artificial Analysis ranking. MarkTechPost and DigitalOcean published deeper architecture and benchmarking pieces in the days that followed.17318
There was also some skepticism. The 1 million-token context window from M1 was popular with users doing long-document analysis, and dropping back to 205K felt like a step backward for that use case even though the agent-loop case is different. Reviewers also pointed out that the published benchmark results are heavily weighted toward agent and coding tasks where MiniMax had tuned the post-training mix, and that on pure reasoning competitions like AIME and HLE the model still trailed proprietary frontier systems. Hacker News commenters and the Hugging Face discussion threads flagged the usual concerns about self-reported benchmarks and asked for independent re-runs.619
How does MiniMax M2 compare to other open-weight models?
The table below compares the headline benchmark numbers for MiniMax M2 against the leading open-weight contemporaries from China and a frontier proprietary model. Where numbers come from the publishers' own materials they are noted as self-reported.
| Metric | MiniMax M2 | Kimi K2 0905 (Moonshot) | GLM-4.6 (Zhipu) | Qwen 3 Max | Claude Sonnet 4.5 |
|---|---|---|---|---|---|
| Total parameters | 230B | 1T | 355B | over 1T | undisclosed |
| Active parameters | ~10B | 32B | 32B | undisclosed | undisclosed |
| Context window | 205K | 256K | 200K | 256K | 200K |
| SWE-bench Verified | 69.4 | 69.2 | 68 | 69.6 | 77.2 |
| Terminal-Bench | 46.3 | 44.5 | 40.5 | not reported | 50.0 |
| BrowseComp | 44.0 | 14.1 | 45.1 | not reported | 19.6 |
| MMLU-Pro | 82 | 82 | 83 | not reported | 88 |
| AIME 2025 | 78 | 57 | 86 | not reported | 88 |
| License | MIT at launch (modified MIT from Nov 2025) | Modified MIT | MIT | Proprietary | Proprietary |
| Approx. price, input / output ($/1M tokens) | 0.30 / 1.20 | not verified | not verified | 1.20 / 6.00 | 3.00 / 15.00 |
The shape of M2's strengths is clear in this table. It does not lead on raw math reasoning or general MMLU-Pro, where GLM-4.6 and Claude Sonnet 4.5 score higher, and GLM-4.6 edges it on BrowseComp, but it leads this open-weight group on Terminal-Bench and SWE-bench Verified, where its 69.4 sits just ahead of Kimi K2 0905 (69.2) and just behind the closed-weight Qwen3-Max (69.6). Against Claude Sonnet 4.5 it trails by about 8 points on SWE-bench and a few points on Terminal-Bench, but it costs roughly an order of magnitude less per token.41211
A separate point worth flagging is the comparison with DeepSeek. By the time of M2's release, DeepSeek-V3.1 and the experimental V3.2-Exp were in the open-weight conversation as well (DeepSeek V3.2 proper followed in December 2025 and DeepSeek V4 in April 2026). DeepSeek-V3.1 outscored M2 on a few raw reasoning benchmarks but lagged it on agentic tool-use, and DeepSeek had not yet released a fully matched coding-agent variant at the time M2 launched. By December 2025 the open-weight leaderboard had reshuffled again, with Kimi K2 Thinking overtaking M2 on several agentic metrics, and MiniMax followed with M2.1 on December 23, 2025 and M2.5 in February 2026.320
How is MiniMax M2 used inside coding agents?
MiniMax's marketing leans heavily on the picture of M2 running inside developer-agent harnesses, and several of the early reviews tested it in exactly that way. M2 worked out of the box inside Claude Code (through MiniMax's Anthropic-compatible API), Cursor's agent mode, Cline, and the open-source OpenDevin and OpenHands frameworks. The 10B active footprint translated into noticeably snappier tool calls compared with Kimi K2 or DeepSeek-V3.1 on the same hardware, which is exactly the point MiniMax was making about agent throughput.1718
Independent reviewers running their own tasks reported that M2 was particularly good at coding-run-fix loops, where the model proposes an edit, sees the compiler or test output, and tries again. It was less consistent on long-form planning tasks where the agent has to hold a complex strategy in mind across dozens of steps without external feedback, an area where Claude Sonnet 4.5 and GPT-5 still had an edge as of late 2025.1211
Continue reading
- MiniMaxMiniMax (稀宇科技; listed as MiniMax Group Inc.) is a publicly traded artificial intelligence (AI) company headquartered in Shanghai, China that develops large language models, multimodal AI systems, and…Mentioned 64 times above
- SWE-benchSWE-bench is an execution-based benchmark for evaluating whether a language-model system can resolve real software issues.Mentioned 14 times above
- Kimi K2Kimi K2 is an open-weights Mixture of Experts language model from Moonshot AI, a Beijing startup, released on July 11, 2025 with 1.04 trillion total parameters and 32.6 billion activated per tokenMentioned 7 times above
- Mixture of Experts (MoE)A mixture of experts (MoE) is a machine-learning architecture that contains multiple component functions called experts and a gating or routing mechanism that determines how their outputs contribute to a…Mentioned twice above
- Qwen3Qwen3 is the third-generation family of large language models developed by the Qwen Team at Alibaba Cloud (also known as Tongyi Qianwen lab).Mentioned twice above
- MiniMax M1MiniMax M1 (stylised MiniMax-M1) is an open-weight large language reasoning model released on 16 June 2025 by the Shanghai-based artificial-intelligence company MiniMaxListed in See also
More from See also
More to read
Topics:AI AgentsAI ModelsChinese AILarge Language ModelsMixture of ExpertsOpen Source AI
References
Footnotes
-
MiniMax. "MiniMax M2 & Agent: Ingenious in Simplicity." October 27, 2025. https://www.minimax.io/news/minimax-m2 ↩ ↩2 ↩3 ↩4
-
Artificial Analysis. "MiniMax-M2: Intelligence, Performance & Price Analysis." https://artificialanalysis.ai/models/minimax-m2 ↩ ↩2 ↩3 ↩4 ↩5 ↩6
-
MarkTechPost. "MiniMax Releases MiniMax M2: A Mini Open Model Built for Max Coding and Agentic Workflows at 8% Claude Sonnet Price and ~2x Faster." October 28, 2025. https://www.marktechpost.com/2025/10/28/minimax-open-sources-minimax-m2-a-mini-model-built-for-max-coding-and-agentic-workflows-at-8-claude-sonnet-price-and-2x-faster/ ↩ ↩2 ↩3 ↩4 ↩5 ↩6 ↩7 ↩8
-
MiniMaxAI. "MiniMax-M2 model card." Hugging Face. https://huggingface.co/MiniMaxAI/MiniMax-M2 ↩ ↩2 ↩3 ↩4 ↩5 ↩6 ↩7 ↩8 ↩9 ↩10 ↩11 ↩12 ↩13 ↩14
-
MiniMax-AI. "MiniMax-M2 GitHub repository." Accessed via https://github.com/MiniMax-AI/MiniMax-M2 ↩ ↩2 ↩3 ↩4 ↩5 ↩6 ↩7 ↩8
-
Caixin Global. "MiniMax Unveils M2 Model to Compete on Speed and Cost." October 28, 2025. https://www.caixinglobal.com/2025-10-28/minimax-unveils-m2-model-to-compete-on-speed-and-cost-102376624.html ↩ ↩2 ↩3 ↩4 ↩5 ↩6
-
Wikipedia. "MiniMax (company)." https://en.wikipedia.org/wiki/MiniMax_(company) ↩ ↩2 ↩3
-
Fortune. "China's MiniMax debuts M1 model it says cost 200x less to train than OpenAI's GPT-4." June 18, 2025. https://fortune.com/2025/06/18/chinas-minimax-m1-ai-model-200x-less-expensive-to-train-than-openai-gpt-4/ ↩ ↩2
-
InfoQ. "MiniMax Releases M1: a 456B Hybrid-Attention Model for Long-Context Reasoning and Software Tasks." June 2025. https://www.infoq.com/news/2025/06/minimax-m1/ ↩
-
Perficient. "Minimax M2: Innovative Reasoning Strategy from Open-Source Model Showing Big Results." November 19, 2025. https://blogs.perficient.com/2025/11/19/minimax-m2-open-source-interleaved-reasoning-model/ ↩
-
Daily Dose of Data Science. "MiniMax-M2 vs. Kimi-K2 vs. Sonnet 4.5 on Code Generation." https://blog.dailydoseofds.com/p/minimax-m2-vs-kimi-k2-vs-sonnet-45 ↩ ↩2 ↩3
-
Barnacle Goose. "MiniMax M2 Review and Comparison With Open-Weight Rivals." Medium. https://medium.com/@leucopsis/minimax-m2-review-and-comparison-with-open-weight-rivals-60c676ef5346 ↩ ↩2 ↩3
-
Let's Data Science. "MiniMax Revises License After Releasing M2.7 Weights." https://letsdatascience.com/news/minimax-revises-license-after-releasing-m27-weights-04b47c74 ↩
-
Vercel. "MiniMax M2 by MiniMax on Vercel AI Gateway, Specs, Pricing and API." https://vercel.com/ai-gateway/models/minimax-m2 ↩
-
Microsoft. "MiniMax-M2: The Open-Source Innovator in Coding and Agentic Workflows Now in Azure AI Foundry." Azure AI Foundry Blog. https://techcommunity.microsoft.com/blog/azure-ai-foundry-blog/minimax-m2-the-open-source-innovator-in-coding-and-agentic-workflows-now-in-azur/4466045 ↩
-
MarkTechPost. "Cerebras Releases MiniMax-M2-REAP-162B-A10B: A Memory Efficient Version of MiniMax-M2 for Long Context Coding Agents." November 15, 2025. https://www.marktechpost.com/2025/11/15/cerebras-releases-minimax-m2-reap-162b-a10b-a-memory-efficient-version-of-minimax-m2-for-long-context-coding-agents/ ↩
-
VentureBeat. "MiniMax-M2 is the new king of open source LLMs (especially for agentic tool calling)." 2025. https://venturebeat.com/ai/minimax-m2-is-the-new-king-of-open-source-llms-especially-for-agentic-tool ↩ ↩2
-
DigitalOcean. "MiniMax-M2: MoE Model for Agentic and Coding Capabilities." https://www.digitalocean.com/community/tutorials/minimax-m2-moe-model-agentic-coding ↩ ↩2
-
Hacker News. "MiniMax M2 release discussion." https://news.ycombinator.com/ ↩
-
Maniac. "Chinese frontier models compared: GLM-5, MiniMax M2.5 and M2.7, Kimi K2.5, Qwen 3.5, and MiMo-V2-Pro." https://www.maniac.ai/blog/chinese-frontier-models-compared-glm5-minimax-kimi-qwen ↩
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
7 revisions · v7 · 3,451 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (110 claims, 20 sources fetched); 11 material + 10 minor fixed
Cite this page: AI Wiki. "MiniMax M2." aiwiki.ai, updated 28 Oct 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/minimax_m2