

Mixture of Depths
Mixture of Depths (MoD) is a technique for dynamically allocating computation to individual tokens within transformer-based language models. Introduced by David Raposo, Sam Ritter, Blake Richards, Timothy Lillicrap, Peter Conway Humphreys, and Adam Santoro at Google DeepMind in April 2024, MoD departs from the conventional design of transformers, which apply the same amount of computation uniformly to every token in a sequence.[1] Instead, MoD uses a learned router in each routing block to decide which tokens receive full processing through the block's self-attention and feed-forward network (MLP) computations and which tokens skip the block via a residual connection.[1] The authors report that MoD models match baseline performance for equivalent training FLOPs and wall-clock time while requiring a fraction of the floating-point operations (FLOPs) per forward pass, and that they "can be upwards of 50% faster to step during post-training sampling."[1]
The paper was released as arXiv:2404.02258 on 2 April 2024.[1] The technique inspired follow-up work across language, vision, multimodal and diffusion models, including methods that retrofit MoD routing into pretrained models, the recursive variant Mixture-of-Recursions, and token-skipping schemes for vision-language models.[10][12][13][20] It is closely related to Mixture of Experts, the other main form of routed conditional computation in transformers, and the original paper shows that the two can be combined.[1]
Motivation
Standard transformer models apply an identical sequence of operations to every token at every layer. As the MoD paper puts it, "not all tokens and sequences require the same time or effort to accurately make a prediction. And yet, transformer models expend the same amount of compute per token in a forward pass."[1]
Prior work on adaptive computation had explored the idea that different inputs deserve different amounts of processing. Alex Graves introduced Adaptive Computation Time (ACT) in 2016, allowing recurrent neural networks to learn how many computational steps to take for each input.[2] The Universal Transformer (Dehghani et al., 2019) extended this idea to transformer architectures by applying a per-position halting mechanism.[3] The MoD authors argue that such general formulations "may not work well with existing hardware constraints since they tend to introduce dynamic computation graphs," and that the most promising conditional computation methods may be those compatible with a hardware stack that "prioritizes static computation graphs, and known tensor sizes."[1]
Mixture of Depths addresses this problem differently. Rather than varying the number of steps with dynamic graph structures, it enforces a fixed compute budget by capping the number of tokens that participate in each routing block's computation.[1] This keeps tensor sizes static and known in advance, while still allowing the model to decide on a per-token basis where to spend its compute. In the paper's words, "compute expenditure is entirely predictable in sum total, but dynamic and context-sensitive at the token-level."[1]
Core mechanism
Router architecture
For each transformer block that routes, a linear projection produces a scalar weight for every token in the sequence. Given the token embeddings of a sequence of length S at layer l, X^l = {x_i^l | 1 ≤ i ≤ S}, the router weight for the i-th token is:
r_i^l = w_θ^T x_i^l
where w_θ is a learnable weight vector. The paper describes this scalar as expressing "the router's preference for that token to participate in a block's computations or to route around it."[1] Because the router is a single projection to a scalar, it adds one weight vector per routing block, a negligible parameter count next to the attention and MLP weights it gates.
Top-k token selection and the block output
The compute budget is set through a capacity C: a user-defined integer smaller than S giving the number of tokens per sequence that a routing block processes (the paper also calls this k).[1] Let P_β(R^l) be the β-th percentile of the router weights R^l, with β = 1 - C/S. The block output for token i is then:[1]
- x_i^(l+1) = r_i^l f_i(X̃^l) + x_i^l, if r_i^l > P_β(R^l)
- x_i^(l+1) = x_i^l, if r_i^l < P_β(R^l)
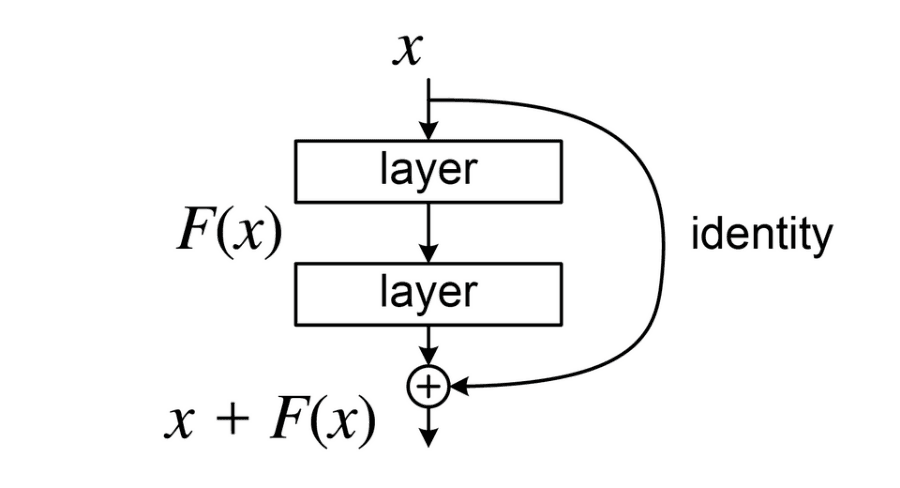
Here X̃^l is the set of the top-k tokens by router weight, and f is the block's self-attention followed by its MLP. The selected tokens attend only to each other inside the routed block, so the routing decides "not only about which tokens to update, but also which tokens are made available to attend to."[1] Tokens that are not selected pass through unchanged via the residual connection and incur no block computation.
Capacity is often quoted as a fraction of the sequence. In the paper's best configuration, with a sequence length of 2,048, the top-k is 256, so 12.5% of tokens are processed by self-attention and the MLP while 1,792 tokens (87.5%) route around the block.[1]
The output of f is multiplied by the router weight. This "puts the router weights along the 'gradient path'," so the router is trained by gradient descent on the ordinary language modeling loss.[1] The authors also tried including router weights on the bypass path, but found it "sufficient" and "implementationally simpler" to apply them only to tokens that take the computational path.[1]
Static computation graph
Because exactly k tokens participate in each routing block, "the computation graph and tensor sizes remain static throughout training; it is merely the tokens' participation that is dynamic and context-sensitive."[1] This contrasts with earlier adaptive computation methods whose per-input step counts change tensor shapes at run time.[1] In a typical community implementation, the routed block selects the chosen tokens with a mask computed from the top-k threshold, runs the wrapped transformer block on those tokens alone, and writes the router-weighted outputs back into their original positions.[25]
Compute budget and FLOP accounting
The paper explains the savings through capacity rather than through a closed-form FLOP formula. Its own example: if a block's capacity is set to half the tokens (T/2), the query-times-key matrix multiplication in self-attention becomes 25% as FLOP-intensive as in a vanilla transformer ((T/2)^2 versus T^2), and "similar calculations can determine the FLOP-savings for the MLP."[1] By the same arithmetic, a 12.5% capacity block performs 1/64 (about 1.6%) of the dense query-key product, and its per-token projections and MLP run on one eighth of the tokens. Blocks that do not route are unchanged, so the saving for a whole model depends on how many blocks route.
The paper reports its results as FLOPs per forward pass normalized to the isoFLOP-optimal baseline (its Figure 4), not as an analytic formula.[1] Two framings of the gain appear in the paper, and they should not be mixed:
- Better loss at equal training compute: an MoD transformer "improves upon vanilla transformers by as much as 1.5% on the final log probability training objective for equivalent training FLOPs (isoFLOP), and while taking an equivalent amount of wall-clock time to train."[1]
- Equal loss with cheaper forward passes: an MoD transformer can reach "training loss parity with an isoFLOP optimal vanilla transformer," while using "a fraction of the FLOPs (upwards of 50%) per forward pass, and hence is faster to step."[1]
A further finding is that the isoFLOP-optimal MoD transformer is the one that "uses as many FLOPs per forward pass as the isoFLOP optimal baseline," which lets practitioners predict the best MoD model size for a given training budget by matching per-forward-pass FLOPs.[1] The compute-optimal MoD model is therefore larger, not cheaper per step, than the optimal baseline; the step-speed gains come from smaller MoD variants that still match the baseline's loss.[1]
Routing strategies
The paper discusses two learned routing schemes borrowed from the Mixture of Experts (MoE) literature, token-choice and expert-choice, and adopts expert-choice.[1] It also tests stochastic routing as a control.
Token-choice routing
In token-choice routing, a router produces a probability distribution over computational paths for each token, and each token is sent to the path it prefers. Because nothing guarantees that tokens divide themselves evenly, auxiliary losses are used to keep tokens from converging on the same path.[1][4]
Expert-choice routing
In expert-choice routing, introduced for MoE by Zhou et al. (2022), each computational path selects the top-k tokens by router weight, which guarantees a balanced load.[8] The MoD authors chose it for three reasons: it removes the need for an auxiliary balancing loss; because top-k depends on the magnitude of router weights, routers "can try to ensure that the most critical tokens are among the top-k"; and with only two paths (the block or the residual), a single top-k splits tokens into two mutually exclusive sets, avoiding the over- or under-processing that expert-choice can cause with many experts.[1]
The drawback is that top-k over a sequence is non-causal: whether a token is selected depends on router weights of later tokens. The paper handles this at sampling time with auxiliary predictors, discussed below.[1]
Stochastic routing control
As a control, the authors trained MoD transformers whose routing was a top-k over router weights sampled from a Gaussian distribution. These "perform drastically worse than both the baseline and normal MoD transformer," which the paper takes as evidence that learned routing is crucial.[1]
Relationship to adaptive computation approaches
Mixture of Depths sits within a broader family of techniques that vary the amount of computation per input (dynamic inference). The following table summarizes the approaches discussed in this article.
| Approach | Mechanism | Granularity | Computation graph | Year |
|---|---|---|---|---|
| Adaptive Computation Time (ACT) | Learned halting probability per step[2] | Per-input step count | Dynamic | 2016 |
| Universal Transformer | Recurrent transformer with per-position halting[3] | Per-position | Dynamic | 2019 |
| Early exit (DeeBERT, PABEE) | Inputs exit at intermediate layers based on confidence or prediction agreement[5][6] | Per-sample | Dynamic | 2020 |
| Token dropping | Drop unimportant tokens from an intermediate layer during pretraining; last layer picks them up again[7] | Per-token | Fixed drop schedule | 2022 |
| CoLT5 conditional computation | All tokens take a light branch; routed tokens also take a heavy branch[9] | Per-token, per-layer | Static | 2023 |
| Mixture of Depths | Router selects top-k tokens per routing block; others skip via residual[1] | Per-token, per-block | Static | 2024 |
| LayerSkip | Layer dropout and a shared early-exit loss in training; self-speculative decoding at inference[17] | Exit layer chosen for drafting | Static training, early-exit drafting | 2024 |
| Mixture of Recursions | Routes tokens to varying numbers of applications of a shared block[12] | Per-token | Fixed capacities (expert-choice) | 2025 |
Early exit methods
Early exit approaches, such as DeeBERT (Xin et al., 2020)[5] and PABEE (Zhou et al., 2020),[6] stop processing an input at an intermediate layer when an exit criterion is met. The MoD paper draws the contrast: "In MoD, unlike in early-exit methods, a token can skip middle layers, then be updated via self-attention with tokens that have gone through all the middle layers. We speculate that this might be a useful property."[1]
Meta's LayerSkip (2024) trains with layer dropout (low rates for early layers, higher rates for later ones) and an early exit loss in which all layers share the same exit, then uses self-speculative decoding: it drafts by exiting at an early layer and verifies and corrects with the remaining layers.[17] The authors report speedups of up to 2.16x on CNN/DM summarization, 1.82x on coding and 2.0x on TOPv2 semantic parsing.[17] Unlike MoD, LayerSkip does not route individual tokens around particular blocks; it trains the model to produce usable predictions from earlier layers.
Token dropping
Token dropping (Hou et al., 2022) accelerates BERT pretraining by dropping unimportant tokens starting from an intermediate layer, using the masked language modeling loss to identify them; the dropped tokens are picked up again by the last layer so the model still produces full-length outputs.[7] The authors report a 25% reduction in BERT pretraining cost with similar fine-tuning performance.[7] MoD differs in that a learned router makes a fresh selection at every routing block, and tokens that skip one block can be processed again in later blocks.[1]
Adaptive computation time
ACT (Graves, 2016) lets a recurrent network learn how many computational steps to take per input by introducing a halting unit and a ponder cost.[2] ACT varies the number of repeated recurrent steps, whereas MoD selectively engages or bypasses standard transformer blocks with a fixed per-block capacity, avoiding a dynamic computation graph.[1]
CoLT5 and conditional routing variants
CoLT5 (Ainslie et al., 2023) applies conditional computation to long-input T5-style models. Every token is processed by a light branch (a smaller MLP, and attention with fewer heads over a local window), and a routed subset of tokens is additionally processed by a heavy branch with a larger MLP and more attention heads.[9] The MoD paper notes that, like MoD, CoLT5 uses a soft top-k for routing, but that CoLT5 works in an encoder-decoder setting where the non-causal top-k is less of a problem, while MoD targets decoder-only models and therefore needs a predictive router for sampling.[1] Where CoLT5 chooses between a light and a heavy path, MoD chooses between the full block and no computation at all.[1]
Comparison with Mixture of Experts
Mixture of Depths is frequently compared with Mixture of Experts (MoE) because both use routing mechanisms. The MoD paper describes its method as "using the routing logic from MoE transformers, but rather than having multiple experts, MoD deploys a single expert which can be dynamically skipped."[1]
| Feature | Standard transformer | Mixture of Experts (MoE) | Mixture of Depths (MoD) |
|---|---|---|---|
| Compute per token | Uniform across all layers | Roughly constant total compute; tokens routed among expert MLPs[1] | Variable; some tokens skip routed blocks entirely[1] |
| What the router decides | N/A | Which expert(s) process each token | Whether a token is processed by the block or skipped |
| What is routed | N/A | Usually the MLP (FFN) only | Both self-attention and the MLP of a block[1] |
| Total FLOPs per forward pass | Fixed | Fixed, roughly that of the active parameters | Reduced, set by the capacity of routed blocks[1] |
| Stored vs. active parameters | Equal | Stored parameters exceed those active per token | All parameters are dense blocks; each routed block sees only a fraction of tokens |
| Load balancing | N/A | Auxiliary losses (token-choice) or expert-choice routing[4][8] | Guaranteed by top-k selection[1] |
In a standard MoE transformer, tokens are routed to expert sub-networks (typically MLPs), and because multiple experts share the load, total capacity stays roughly equal to that of a vanilla transformer; the benefit is more parameters at similar compute.[1][4] In MoD, the routing decision is binary, the full block or the residual path, so lowering capacity directly lowers FLOPs per forward pass.[1] Because MoD also routes self-attention, skipping a block changes which tokens later tokens can attend to at that block.[1]
Mixture of Depths and Experts (MoDE)
The paper also combines MoD with MoE, calling the result Mixture-of-Depths-and-Experts (MoDE), and reports that "the performance improvements offered by MoD compound with those of MoE."[1] Two variants were tried.[1]
Staged MoDE
Staged MoDE "routes tokens around or towards blocks prior to the self-attention step," then applies MoE routing to the tokens that enter the block.[1] Its advantage is that tokens can skip the self-attention step as well as the experts.[1]
Integrated MoDE
Integrated MoDE "implements MoD routing by integrating 'no-op' experts among the conventional MLP experts," so a single routing operation sends each token either to a real expert or to a no-op.[1] Its advantage is that it "simplifies the routing machinery."[1]
The authors found integrated MoDE "distinctly better than simply reducing the capacity of experts in conventional MoE models, and relying on token dropping to implement residual routing." They attribute this to tokens explicitly learning to choose the residual path around the experts, rather than preferring an expert and then being dropped when its capacity is exceeded.[1]
Training
Language modeling objective
MoD models are trained end-to-end on the standard language modeling objective (next-token prediction). Because the block output is multiplied by the router weight, the router receives gradients from that loss through backpropagation, and expert-choice routing needs no auxiliary load-balancing loss.[1] Only tokens that take the computational path carry the router weight; the authors found this sufficient.[1]
Configuration
All models used the same basic hyperparameters, including cosine schedules equal to the number of training steps, a batch size of 128 and a sequence length of 2,048, varying only the number of layers, heads and embedding size to produce different model sizes.[1] Model sizes in the isoFLOP analysis ranged from 60 million to 3 billion parameters.[1]
The authors tested routing every block or every other block, with capacities from 12.5% to 95% of the sequence. "Routing every other block was crucial for strong performance," and aggressive capacity reduction worked best: performance improved gradually as capacity was lowered to 12.5% and degraded beyond that point.[1] The paper concludes that the network "is robust to significant capacity reductions as long as there is frequent opportunity for full capacity self-attention and MLP computations," and recommends "12.5% capacity blocks, every other block."[1]
Autoregressive sampling considerations
The top-k routing used in training is non-causal: whether a token falls in the top-k depends on router weights of tokens that come after it, which are not available when sampling one token at a time.[1] The paper tests two workarounds:[1]
- Auxiliary loss on the router: a binary cross-entropy loss in which the router's outputs are the logits and the top-k selections are the targets (1 if a token was selected, 0 otherwise). This pushes the sigmoid of selected tokens' router outputs above 0.5 and of the others below 0.5. The authors report that it affects the primary language modeling objective by approximately 0.2 to 0.3%.[1]
- Auxiliary MLP predictor: a small MLP, "akin to a second router," that receives the same inputs as the router through a stop-gradient and predicts whether each token will be among the top-k. This method "does not affect the language modeling objective, and empirically does not significantly impact the step speed."[1]
With either method, routing at sampling time depends only on the current token's router output. The paper describes the prediction task as relatively easy: it "quickly achieves 99% accuracy," and the predictor is "upwards of 97% accurate soon into training."[1] The discussion section concludes that either "a simple auxiliary classifier, or auxiliary loss on the router" is sufficient to mimic the top-k decisions "with minimal to no performance degradation."[1]
Experimental results
isoFLOP analysis
The paper first trained models with a 6 x 10^18 FLOP budget to tune hyperparameters, then ran isoFLOP analyses at 6 x 10^18, 2 x 10^19 and 1 x 10^20 total training FLOPs using the 12.5% capacity variant, with models from 60 million to 3 billion parameters.[1] The authors summarize the effect as MoD transformers dragging the baseline isoFLOP curve "down and to the right": the optimal MoD transformer reaches a lower loss than the optimal baseline and has more parameters.[1]
Key findings reported by the authors:
- Better loss at equal compute: the MoD transformer improved on the vanilla transformer by as much as 1.5% on the final log probability training objective at equal training FLOPs.[1]
- Faster variants at equal or better loss: because the optimal MoD model is larger than the baseline, smaller MoD variants exist that perform as well as or better than the isoFLOP-optimal baseline while being faster to step.[1]
- Larger optimal model size: the trend that FLOP-optimal MoD transformers have more parameters than the baseline held at the larger budgets.[1]
- Depth over width: "it is better to add depth than to add width when adding FLOPs to the model."[1]
- Memory: MoD transformers showed memory savings relative to equivalently sized baselines at larger sizes, with some variants needing a smaller TPU topology. The authors did not study this extensively but anticipate positive effects on KV cache size during autoregressive sampling.[1]
The paper does not discuss scaling laws explicitly. Its relevant finding is that, at the same training budget, compute-optimal MoD models have more parameters than compute-optimal dense baselines.[1]
Step speed
In the hyperparameter sweep, a 220-million-parameter MoD variant (model #3 in the paper's Figure 3) slightly outperformed the isoFLOP-optimal baseline (also 220 million parameters) while being "upwards of 60% faster to step during training"; the figure caption gives the figure as 66% faster.[1] The two models took approximately the same wall-clock time to train on equivalent hardware.[1] The paper's abstract separately states that MoD models "can be upwards of 50% faster to step during post-training sampling."[1]
The authors give two sources for the step-speed gains. First, MoD transformers have a lower FLOP-per-parameter ratio because some tokens route around blocks, so a model of a given size needs fewer FLOPs per forward pass. Second, because isoFLOP-optimal MoD models are bigger and better than the isoFLOP-optimal baseline, there exist smaller MoD variants that match the baseline, and these are faster because they are smaller.[1] The paper plots normalized FLOPs per forward pass rather than wall-clock step time, but states that the two are tightly correlated in its experiments.[1]
Autoregressive evaluation
The authors evaluated MoD variants during autoregressive sampling on the same held-out data of 256,000 sequences (500 million tokens). Switching from top-k routing to predictor-based routing caused "little performance degradation," and MoD variants still existed that outperformed the isoFLOP-optimal baseline while requiring fewer FLOPs per forward pass.[1]
Token routing patterns
The paper's routing analysis of a model with interleaved 12.5% capacity routing blocks observed patterns it says might warrant further study: some tokens appear to engage each block along the depth while others route around blocks whenever possible. "Preliminary analyses suggest that the tokens that engage with blocks more frequently are correlated with output predictions that have higher entropy, which possibly corresponds to predictions that are more difficult to make."[1] The router weight histogram matched what the auxiliary loss dictates: about 12.5% of weights above 0.5 and 87.5% below.[1]
Relationship to speculative decoding
Speculative decoding accelerates autoregressive inference at the system level: a smaller draft model proposes tokens and a larger target model verifies them in parallel.[16] MoD works inside a single model's forward pass. Both rest on the observation that not every token needs the full computation of the network, and early-exit methods connect the two: LayerSkip drafts with the model's own early layers and verifies with the full network.[17]
Implementation considerations
Open-source implementations
Unofficial PyTorch implementations appeared within days of the paper. As of 31 October 2026, the GitHub repositories astramind-ai/Mixture-of-depths (created 12 April 2024, 176 stars), kyegomez/Mixture-of-Depths (created 5 April 2024, 124 stars) and sramshetty/mixture-of-depths (created 6 April 2024, 35 stars) are the most-starred of these; each describes itself as an implementation of the paper.[25][26][27] Follow-up papers including Router-Tuning, D-LLM, γ-MoD, p-MoD and Mixture-of-Recursions released their own code.[12][13][18][19][20]
KV cache and serving
In MoD, tokens that skip a routed block contribute no keys or values at that block, and later tokens cannot attend to them there.[1] Follow-up work treats the resulting gaps as a practical issue. D-LLM, which skips layers per token in pretrained LLMs, describes "the missing KV-cache when layers are skipped" and handles it with an eviction policy that excludes skipped layers from subsequent attention, which also saves KV storage.[18] Mixture-of-Recursions notes that tokens exiting early "will have missing KV pairs" at deeper levels and addresses this with recursion-wise caching, in which each level caches only the tokens routed to it.[12]
Extensions and follow-up work
The following table lists dated follow-up work that builds directly on MoD. All results are the respective authors' own.
| Work | First posted | Venue | Setting | Key change |
|---|---|---|---|---|
| CNN MoD (Cakaj et al.)[15] | September 2024 | ACCV 2024 | CNNs | Selects channels instead of tokens |
| MoMa + MoD (Lin et al., Meta)[21] | July 2024 | arXiv | Early-fusion mixed-modal pretraining | Combines modality-aware MoE with MoD |
| D-LLM (Jiang et al.)[18] | 2024 | NeurIPS 2024 | Pretrained LLMs | Per-token layer-skip decision module plus KV eviction |
| MoDification (Zhang et al.)[10] | October 2024 | NAACL 2025 | Converting pretrained LLMs (3B to 70B) | Threshold-p operator replaces top-k |
| Router-Tuning (He et al.)[19] | October 2024 | EMNLP 2025 | Pretrained LLMs | Trains only the routers; routes attention layers |
| γ-MoD (Luo et al.)[13] | October 2024 | ICLR 2025 | Multimodal LLMs | ARank picks which layers to convert |
| MD-DiT (Shen et al.)[22] | 2024 | NeurIPS 2024 workshop (AFM) | Diffusion transformers | Timestep-aware block skipping and caching |
| p-MoD (Zhang et al.)[20] | December 2024 | ICCV 2025 | Multimodal LLMs | Progressive ratio decay of vision-token retention |
| A-MoD (Gadhikar et al.)[11] | December 2024 | ICLR 2025 workshop (SCOPE) | Vision transformers | Routing from the previous layer's attention map |
| UniMoD (Mao et al.)[14] | February 2025 | arXiv | Unified multimodal transformers | Separate router per task |
| Mixture-of-Recursions (Bae et al.)[12] | July 2025 | NeurIPS 2025 | Recursive transformers | Routes tokens to different recursion depths |
MoDification
MoDification (Zhang et al., October 2024; NAACL 2025) addresses converting existing pretrained large language models to MoD. Its authors report that MoD "can barely transform existing LLMs without costly training over an extensive number of tokens," and propose promoting the top-k operator to a threshold-p operator, together with architecture and data refinements.[10] Across model scales from 3B to 70B, they report up to about 1.2x speedup in latency and about 1.8x reduction in memory compared with the original LLMs, "especially in long-context applications."[10]
Router-Tuning
Router-Tuning (He et al., October 2024; EMNLP 2025) targets two costs of MoD: training the whole model together with its routers, and the quality loss when important layers are skipped.[19] It fine-tunes only the routers, each a single-layer projector accounting for less than 0.01% of total parameters, on a small dataset with the backbone frozen.[19] Earlier arXiv versions called its attention-layer variant MindSkip ("Attention with Dynamic Depths"); the published version investigates routing at the level of attention layers and MoE layers.[19] The authors report results such as a 21% speedup with only a 0.2% performance drop.[19]
D-LLM
D-LLM (Jiang et al., Huawei, Zhejiang University and CUHK; NeurIPS 2024) adds a dynamic decision module to each transformer layer that decides, per token, whether the layer is executed or skipped.[18] It pairs this with the KV eviction policy described above. The authors report reductions of up to 45% in computational cost and KV storage on Q&A, summarization and math tasks, and 50% on commonsense reasoning tasks; in their comparisons they reproduce MoD with routing on even layers and k set to 12.5% of the sentence length.[18]
A-MoD (attention-based MoD)
A-MoD (Gadhikar et al., December 2024; ICLR 2025 SCOPE workshop) replaces the learned linear router with routing that "leverages the existing attention map of the preceding layer for routing decisions within the current layer."[11] It introduces no additional trainable parameters and can be adapted from pretrained transformer models. The authors report up to 2% higher accuracy on ImageNet than standard routing and isoFLOP vision transformer baselines, and up to 2x faster transfer learning.[11]
Mixture of Recursions
Mixture-of-Recursions (MoR) (Bae et al., KAIST, Mila, Google Cloud, Google DeepMind and Google Research; July 2025, NeurIPS 2025) brings MoD-style routing into a recursive transformer. A shared stack of layers is reused across recursion steps for parameter efficiency, and lightweight routers assign each token its own recursion depth.[12] Its expert-choice router is described as "inspired by top-k gating in MoD models."[12] Across model scales from 135M to 1.7B parameters, the authors report a new Pareto frontier: at equal training FLOPs and smaller model sizes, lower validation perplexity, better few-shot accuracy, and higher throughput than vanilla and recursive baselines.[12] In throughput tests at the 360M scale, MoR-4 reached up to a 2.06x speedup with the maximum batch size, with what the authors describe as a slight performance degradation.[12]
MoD in vision-language models
γ-MoD (Luo et al., October 2024; ICLR 2025) adapts MoD to existing multimodal large language models.[13] The authors report that directly converting the dense layers of an MLLM to MoD layers leads to substantial performance degradation, and introduce the rank of attention maps (ARank) to identify which layers are redundant and should become MoD layers.[13] Two further designs, a shared vision-language router and masked routing learning (which prevents critical tokens, such as instruction tokens, from being skipped during training), let more than 90% of dense layers be converted.[13] For LLaVA-HR, the authors report a 31.0% reduction in training time and 53.2% in inference time with a -1.5% performance change.[13]
p-MoD (Zhang et al., Nanjing University with China Mobile Research Institute and Shanghai AI Lab; December 2024, ICCV 2025) applies MoD to vision tokens in MLLMs, with each LLM layer selecting essential vision tokens to process.[20] It adds tanh-gated weight normalization (TanhNorm) and symmetric token reweighting (STRing) for stability, and a progressive ratio decay (PRD) schedule that lowers the token retention ratio layer by layer, based on the observation that vision tokens are more redundant in deeper layers.[20] Across 15 benchmarks on two baseline models, the authors report matching or exceeding the baselines while using 55.6% of the inference TFLOPs, 53.7% of the KV cache storage, and 77.7% of the training GPU hours.[20]
UniMoD for unified multimodal transformers
UniMoD (Mao, Yang and Shou, February 2025) applies MoD to unified multimodal transformers that handle both generation and understanding in a shared parameter space.[14] The authors find that token redundancy depends mainly on the task and the layer, so UniMoD uses a separate router for each task to decide which tokens to prune.[14] Applied to Show-o and Emu3, it reduces training FLOPs by approximately 15% in Show-o and 40% in Emu3 while maintaining or improving performance on several benchmarks.[14]
MoMa
MoMa (Lin et al., Meta, July 2024) is a modality-aware MoE architecture for early-fusion mixed-modal pretraining. Under a 1-trillion-token budget, its 1.4B model with 4 text and 4 image experts achieves 3.7x overall FLOPs savings relative to a compute-equivalent dense baseline, measured by pretraining loss.[21] Adding MoD raises the pretraining FLOPs savings to 4.2x overall (3.4x for text, 5.3x for image), "although this combination hurts performance in causal inference due to increased sensitivity to router accuracy."[21]
CNN Mixture-of-Depths
CNN MoD (Cakaj, Mehnert and Yang, ACCV 2024) adapts MoD to convolutional neural networks.[15] Instead of selecting tokens, it selects the channels in feature maps that receive processing inside convolutional blocks, while skipping less relevant channels.[15] Like the language model version it keeps a static computation graph with fixed tensor sizes, and the authors state that it needs no customized CUDA kernels, unique loss functions or fine-tuning.[15]
The authors report that on ImageNet, ResNet75-MoD matches ResNet50 with a 25% speedup on CPU and 15% on GPU, and that ResNet86-MoD exceeds ResNet50 by 0.45% with a 6% CPU and 5% GPU speedup.[15] MobileNetV2-MoD-L "maintains nearly the same top-1 accuracy" as standard MobileNetV2 while achieving an 11% speedup on CPU and 10% on GPU.[15]
MD-DiT for diffusion models
MD-DiT (Shen et al., NeurIPS 2024 workshop) draws on mixture-of-depths models to make diffusion transformers cheaper at inference.[22] Starting from the observation that each block contributes differently at each timestep, it combines block skipping and block caching (reusing results from previous timesteps), selecting blocks per timestep through gradient-free search.[22] The authors report a 20% reduction in computational cost for a 4-step Latent Consistency Model and 59% in a 40-step setup, and that MD-DiT exceeds training-free methods such as DeepCache, TGATE and T-Stitch.[22]
Use in released and research models
The models trained in the original MoD paper were research models used for the isoFLOP study.[1] Published uses of MoD since then are mostly retrofits or research architectures: D-LLM and Router-Tuning add routers to pretrained LLMs, including Llama 2 7B in D-LLM's experiments and Llama-2 and Mistral 7B in Router-Tuning's;[18][19] γ-MoD and p-MoD build MoD into LLaVA-style vision-language models;[13][20] and Meta's MoMa study combined MoD with modality-aware experts in mixed-modal pretraining.[21]
A related idea appears in a released model. Meituan's open-weight LongCat-Flash (technical report, September 2025) adds "zero-computation experts" that "simply return the input" to its MoE layers, so the number of activated parameters varies per token between 18.6B and 31.3B (about 27B on average).[23] This resembles the no-op experts of integrated MoDE, but the LongCat-Flash report credits the mechanism to MoE++ (Jin et al., 2024), which introduced zero-computation experts for MoE models, and also cites AdaMoE (Zeng et al., 2024), which uses null experts.[23][24]
Limitations
- Non-causal routing during training: the top-k operation needs router weights for the whole sequence, which conflicts with the causal nature of autoregressive models. An auxiliary loss or predictor is needed for sampling.[1] MoMa reports that combining MoD with its MoE design hurt causal inference because of sensitivity to router accuracy.[21]
- Capacity is a fixed hyperparameter: capacity and routing frequency are set before training. The paper notes that while FLOPs per forward pass predict which model size is isoFLOP-optimal, they do not predict whether the optimal loss will beat the baseline; the best capacity "appears to be empirically determinable," and 12.5% every other block was best in its experiments.[1] MoDification's threshold-p operator lets the number of processed tokens vary, giving up a fixed per-block token count.[10]
- Retrofitting pretrained models: the original models were trained from scratch.[1] MoDification's authors report that plain MoD "can barely transform existing LLMs without costly training over an extensive number of tokens," which motivated threshold-based and router-only adaptation methods.[10][19]
- Attention side effects: "If a token does not participate in self-attention at a certain block, then later tokens will also not be able to attend to it," so each routing decision affects both the current prediction and future ones.[1]
- KV cache gaps: tokens that skip blocks leave no keys or values there, which serving systems must handle; follow-ups use KV eviction or recursion-wise caching.[12][18]
Summary
Mixture of Depths makes transformer computation conditional at the token level. A learned router and a top-k selection let each routing block process only a fixed fraction of tokens, while the rest pass through the residual connection. The approach keeps a static computation graph, and in the authors' experiments it improved the final log probability by as much as 1.5% at equal training FLOPs, or matched the isoFLOP-optimal baseline with variants that need a fraction of the FLOPs per forward pass. It can be combined with Mixture of Experts.[1]
Since 2024, follow-up work has carried the idea to pretrained LLMs (MoDification, Router-Tuning, D-LLM), recursive transformers (Mixture-of-Recursions), vision-language models (γ-MoD, p-MoD), unified multimodal models (UniMoD), vision transformers (A-MoD), CNNs and diffusion transformers.[10][12][13][14][15][18][19][20][22]
Continue reading
- TransformersA Transformer is a deep learning architecture, introduced by eight Google researchers in the 2017 paper "Attention Is All You Need", that uses attention as the sole mechanism for modeling relationships between…Mentioned 46 times above
- AttentionAttention is a family of operations in neural networks that computes an output by assigning data-dependent weights to a collection of representations and combining them.Mentioned 24 times above
- FLOPSFLOPS (floating-point operations per second, also written FLOP/s) is a measure of computing speed: the number of arithmetic operations on floating-point numbers that a processor, accelerator or supercomputer…Mentioned 22 times above
- Residual connectionA residual connection (also called a skip connection or shortcut connection) is a structural element in neural networks that adds the input of a layer or block directly to its output.Mentioned 3 times above
- Google DeepMindGoogle DeepMind is an artificial intelligence research and model-development organization at Google.Mentioned twice above
- Feedforward Neural Network (FFN)A feedforward neural network (FFN), also called a multilayer perceptron (MLP) when it has multiple layers, is a type of artificial neural network in which information flows in one direction only, from the…Linked in the introduction
More to read
Topics:Deep LearningMachine LearningModel ArchitectureTransformer Models
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32 ^33 ^34 ^35 ^36 ^37 ^38 ^39 ^40 ^41 ^42 ^43 ^44 ^45 ^46 ^47 ^48 ^49 ^50 ^51 ^52 ^53 ^54 ^55 ^56 ^57 ^58 ^59 ^60 ^61 ^62 ^63 ^64 ^65 ^66 ^67 ^68 ^69 ^70 ^71 ^72 ^73 ^74 ^75 ^76 ^77 ^78 ^79 ^80 ^81 ^82 ^83 ^84 ^85 ^86Raposo, D., Ritter, S., Richards, B., Lillicrap, T., Humphreys, P. C., & Santoro, A. (2024). Mixture-of-Depths: Dynamically allocating compute in transformer-based language models. *arXiv preprint arXiv:2404.02258*. arxiv.org/...2404.02258
- ^1 ^2 ^3Graves, A. (2016). Adaptive Computation Time for Recurrent Neural Networks. *arXiv preprint arXiv:1603.08983*.
- ^1 ^2Dehghani, M., Gouws, S., Vinyals, O., Uszkoreit, J., & Kaiser, L. (2019). Universal Transformers. *Proceedings of ICLR 2019*.
- ^1 ^2 ^3Shazeer, N., Mirhoseini, A., Maziarz, K., Davis, A., Le, Q., Hinton, G., & Dean, J. (2017). Outrageously Large Neural Networks: The Sparsely-Gated Mixture-of-Experts Layer. *Proceedings of ICLR 2017*.
- ^1 ^2Xin, J., Tang, R., Lee, J., Yu, Y., & Lin, J. (2020). DeeBERT: Dynamic Early Exiting for Accelerating BERT Inference. *Proceedings of ACL 2020*.
- ^1 ^2Zhou, W., Xu, C., Ge, T., McAuley, J., Xu, K., & Wei, F. (2020). BERT Loses Patience: Fast and Robust Inference with Early Exit. *Proceedings of NeurIPS 2020*.
- ^1 ^2 ^3Hou, L., Pang, R. Y., Zhou, T., Wu, Y., Song, X., Song, X., & Zhou, D. (2022). Token Dropping for Efficient BERT Pretraining. *Proceedings of ACL 2022*. arXiv:2203.13240.
- ^1 ^2Zhou, Y., Lei, T., Liu, H., Du, N., Huang, Y., Zhao, V., Dai, A., Chen, Z., Le, Q., & Laudon, J. (2022). Mixture-of-Experts with Expert Choice Routing. *Proceedings of NeurIPS 2022*. arXiv:2202.09368.
- ^1 ^2Ainslie, J., Lei, T., de Jong, M., Ontañón, S., Brahma, S., Zemlyanskiy, Y., et al. (2023). CoLT5: Faster Long-Range Transformers with Conditional Computation. *Proceedings of EMNLP 2023*. arXiv:2303.09752.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Zhang, C., Zhong, M., Wang, Q., Lu, X., Ye, Z., Lu, C., et al. (2024). MoDification: Mixture of Depths Made Easy. *arXiv preprint arXiv:2410.14268*. Published in *Proceedings of NAACL 2025*, pp. 5137-5149. aclanthology.org/2025.naacl-long.265
- ^1 ^2 ^3Gadhikar, A., Majumdar, S. K., Popp, N., Saranrittichai, P., Rapp, M., & Schott, L. (2024). Attention Is All You Need For Mixture-of-Depths Routing. *arXiv preprint arXiv:2412.20875*. ICLR 2025 Workshop (SCOPE).
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11Bae, S., Kim, Y., Bayat, R., Kim, S., Ha, J., Schuster, T., Fisch, A., Harutyunyan, H., Ji, Z., Courville, A., & Yun, S.-Y. (2025). Mixture-of-Recursions: Learning Dynamic Recursive Depths for Adaptive Token-Level Computation. *Proceedings of NeurIPS 2025*. arXiv:2507.10524. Code: github.com/...mixture_of_recursions
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Luo, Y., Luo, G., Ji, J., Zhou, Y., Sun, X., Shen, Z., & Ji, R. (2024). γ-MoD: Exploring Mixture-of-Depth Adaptation for Multimodal Large Language Models. *Proceedings of ICLR 2025*. arXiv:2410.13859.
- ^1 ^2 ^3 ^4 ^5Mao, W., Yang, Z., & Shou, M. Z. (2025). UniMoD: Efficient Unified Multimodal Transformers with Mixture-of-Depths. *arXiv preprint arXiv:2502.06474*.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Cakaj, R., Mehnert, J., & Yang, B. (2024). CNN Mixture-of-Depths. *Proceedings of ACCV 2024*. arXiv:2409.17016.
- ^Leviathan, Y., Kalman, M., & Matias, Y. (2023). Fast Inference from Transformers via Speculative Decoding. *Proceedings of ICML 2023*.
- ^1 ^2 ^3 ^4Elhoushi, M., et al. (2024). LayerSkip: Enabling Early Exit Inference and Self-Speculative Decoding. *Proceedings of ACL 2024*. arXiv:2404.16710.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Jiang, Y., Wang, H., Xie, L., Zhao, H., Zhang, C., Qian, H., & Lui, J. C. S. (2024). D-LLM: A Token Adaptive Computing Resource Allocation Strategy for Large Language Models. *Proceedings of NeurIPS 2024*. Code: github.com/...D-LLM
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9He, S., Ge, T., Sun, G., Tian, B., Wang, X., & Yu, D. (2025). Router-Tuning: A Simple and Effective Approach for Dynamic Depth. *Proceedings of EMNLP 2025*, pp. 1925-1938. arXiv:2410.13184. aclanthology.org/2025.emnlp-main.99
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Zhang, J., Meng, D., Zhang, Z., Huang, Z., Wu, T., & Wang, L. (2024). p-MoD: Building Mixture-of-Depths MLLMs via Progressive Ratio Decay. *Proceedings of ICCV 2025*. arXiv:2412.04449.
- ^1 ^2 ^3 ^4 ^5Lin, X. V., Shrivastava, A., Luo, L., Iyer, S., Lewis, M., et al. (2024). MoMa: Efficient Early-Fusion Pre-training with Mixture of Modality-Aware Experts. *arXiv preprint arXiv:2407.21770*.
- ^1 ^2 ^3 ^4 ^5Shen, M., Chen, P., Ye, P., Xia, G., Chen, T., Bouganis, C.-S., & Zhao, Y. (2024). MD-DiT: Step-Aware Mixture-of-Depths for Efficient Diffusion Transformers. *NeurIPS 2024 Workshop (AFM)*. mlanthology.org/...shen2024neuripsw-mddit
- ^1 ^2Meituan LongCat Team (2025). LongCat-Flash Technical Report. *arXiv preprint arXiv:2509.01322*.
- ^Jin, P., Zhu, B., Yuan, L., & Yan, S. (2024). MoE++: Accelerating Mixture-of-Experts Methods with Zero-Computation Experts. *arXiv preprint arXiv:2410.07348*.
- ^1 ^2astramind-ai/Mixture-of-depths (unofficial implementation), GitHub. github.com/...Mixture-of-depths (accessed 31 October 2026).
- ^kyegomez/Mixture-of-Depths, GitHub. github.com/...Mixture-of-Depths (accessed 31 October 2026).
- ^sramshetty/mixture-of-depths (unofficial implementation), GitHub. github.com/...mixture-of-depths (accessed 31 October 2026).
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
9 revisions · v9 · 6,471 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independently verified 2026-10-31 against the Mixture-of-Depths paper (arXiv 2404.02258 PDF) and each follow-up paper's arXiv/OpenReview/ACL/NeurIPS record; 4 minor verifier defects fixed before stamping.
Cite this page: AI Wiki. "Mixture of Depths." aiwiki.ai, updated 31 Oct 2026, fact-checked 31 Oct 2026. CC BY 4.0. https://aiwiki.ai/wiki/mixture_of_depths