

GPU computing
GPU computing is the use of a graphics processing unit (GPU) to perform general-purpose computation that was traditionally handled by the central processing unit (CPU). Also known as general-purpose computing on graphics processing units (GPGPU), it exploits the massively parallel architecture of GPUs, which pack thousands of cores onto a single chip, to accelerate workloads in scientific computing, data analytics, and, most notably, artificial intelligence and machine learning.[2] GPU computing is the backbone of modern deep learning, powering the training and inference of large language models, computer vision systems, and other neural network applications at scale. Its commercial impact is now enormous: NVIDIA, whose CUDA platform dominates the field, reported a record $193.7 billion in Data Center revenue for fiscal 2026 (ended January 2026), up 68% year over year, almost all of it driven by GPUs sold for AI.[21]
History
Early Graphics Hardware
GPUs were originally designed for a single purpose: rendering graphics. Throughout the 1990s, companies like NVIDIA, ATI (later acquired by AMD), and 3dfx developed dedicated hardware to accelerate the pixel-level calculations required for 3D video games and visualization software. These early GPUs contained fixed-function pipelines optimized for transforming vertices and shading pixels, with no provision for arbitrary computation.[1]
The Emergence of Programmable Shaders
A turning point arrived in the early 2000s with the introduction of programmable shaders. Rather than locking developers into a fixed rendering pipeline, GPUs began offering small programmable stages (vertex shaders and pixel shaders) where custom code could execute on each vertex or pixel.[2] Researchers quickly recognized that these programmable stages could be repurposed for non-graphics tasks by encoding data as textures and reading back results from the framebuffer.
In 2003, two research groups independently demonstrated that GPUs could solve general linear algebra problems faster than CPUs, a milestone that drew significant attention from the scientific computing community. The same year, researchers at Stanford University began formalizing the concept of "stream programming" for GPUs.[2]
BrookGPU and the Road to CUDA
Ian Buck, a PhD student at Stanford, led the development of BrookGPU, a programming language and compiler that abstracted the graphics-specific details of GPUs into general-purpose programming concepts. Brook allowed scientists to write code for the GPU without understanding 3D graphics APIs like OpenGL or DirectX. Buck's dissertation work demonstrated the potential for GPUs as parallel compute engines and attracted the attention of the industry.[3]
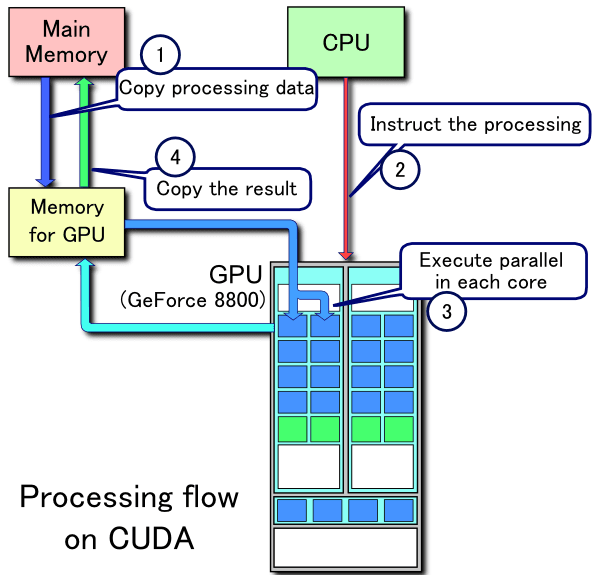
In 2004, Buck joined NVIDIA and, alongside John Nickolls, NVIDIA's director of architecture for GPU computing, began transforming Brook into a production-ready platform.[3] The result was CUDA (Compute Unified Device Architecture), which NVIDIA released publicly in November 2006 alongside its GeForce 8800 GTX GPU based on the Tesla microarchitecture. The initial CUDA SDK became available on February 15, 2007, for Windows and Linux.[3]
OpenCL and Broader Adoption
In response to CUDA's proprietary nature, the Khronos Group released OpenCL (Open Computing Language) in 2008 as a vendor-neutral standard for parallel programming across GPUs, CPUs, and other accelerators.[2] While OpenCL offered portability, CUDA retained a performance and ecosystem advantage on NVIDIA hardware, and the two frameworks coexisted throughout the 2010s.
How did GPU computing enter AI?
In 2009, Stanford researchers Rajat Raina, Anand Madhavan, and Andrew Ng published a seminal paper demonstrating that GPU computing could speed up the training of deep belief networks and other unsupervised learning models by an order of magnitude compared to CPUs.[17] The authors reported that their GPU implementation of deep belief network learning was "up to 70 times faster than a dual-core CPU implementation for large models," which reduced the time to learn a four-layer network with 100 million free parameters "from several weeks to around a single day."[17] This work, alongside subsequent research by Geoffrey Hinton, Yann LeCun, and others, set the stage for the deep learning revolution.
By 2012, when AlexNet won the ImageNet Large Scale Visual Recognition Challenge using two NVIDIA GTX 580 GPUs, GPU-accelerated deep learning had firmly entered the mainstream. Trained on roughly 1.2 million labeled images, AlexNet cut the top-5 error rate from about 26% to 15.3%. Its authors, Alex Krizhevsky, Ilya Sutskever, and Geoffrey Hinton, credited the hardware directly: "To make training faster, we used non-saturating neurons and a very efficient GPU implementation of the convolution operation."[23] They split the network across two GPUs because a single 3 GB GTX 580 could not hold the whole model, an early illustration of why GPU memory and multi-GPU scaling matter for deep learning.[23]
Why do GPUs work so well for AI?
Massive Parallelism
The fundamental advantage of GPUs for AI workloads is their massively parallel architecture. While a modern CPU may contain 8 to 64 high-performance cores, a single data center GPU can contain thousands of smaller cores.[14] The NVIDIA H100, for example, has 16,896 CUDA cores.[6] Each of these cores can execute simple arithmetic operations simultaneously, making GPUs exceptionally well suited for workloads that involve applying the same operation across large datasets.
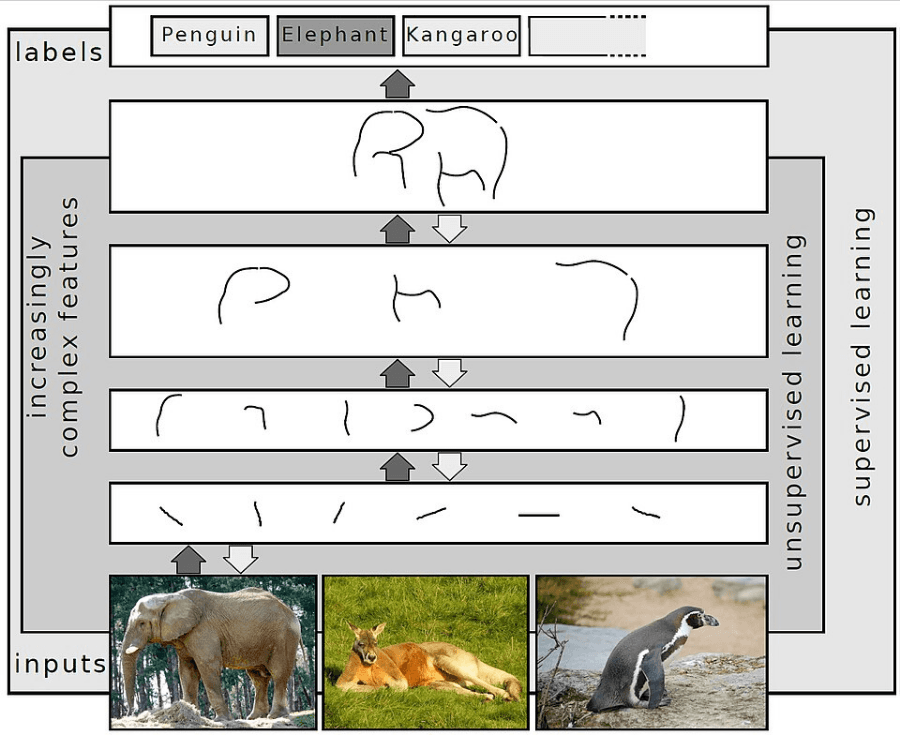
Neural networks are inherently parallel. During a forward pass, each layer applies a set of weights to input activations through matrix multiplications, and these multiplications can be decomposed into thousands of independent operations that execute concurrently on GPU cores.
SIMT Architecture
NVIDIA GPUs use a Single Instruction, Multiple Threads (SIMT) execution model, a variation of the classical SIMD (Single Instruction, Multiple Data) paradigm. In SIMT, groups of 32 threads called warps execute the same instruction in lockstep across different data elements.[14] This model maps naturally to the regular, data-parallel structure of neural network computations such as matrix multiplications and element-wise activation functions.
High Memory Bandwidth
AI training workloads move enormous quantities of data between memory and compute units. GPUs address this with high-bandwidth memory (HBM) technologies that provide far greater throughput than the DDR memory used by CPUs. The NVIDIA A100 offers up to 2,039 GB/s of memory bandwidth using HBM2e,[5] while the H100 reaches 3,350 GB/s with HBM3,[6] and the B200 delivers approximately 8,000 GB/s with HBM3e.[7] This bandwidth is critical for feeding data to the thousands of compute cores fast enough to keep them utilized.
Tensor Cores
Starting with the Volta architecture in 2017, NVIDIA introduced Tensor Cores, specialized hardware units designed to accelerate matrix multiply-and-accumulate operations at reduced precision (FP16, BF16, INT8, and later FP8 and FP4).[4] Tensor Cores can perform a 4x4 matrix multiply-and-accumulate in a single clock cycle, providing massive speedups for deep learning operations compared to standard CUDA cores.[16] This mixed-precision capability aligns with the observation that many neural network operations tolerate reduced numerical precision without meaningful loss in accuracy.
GPU for Deep Learning
Matrix Multiplication
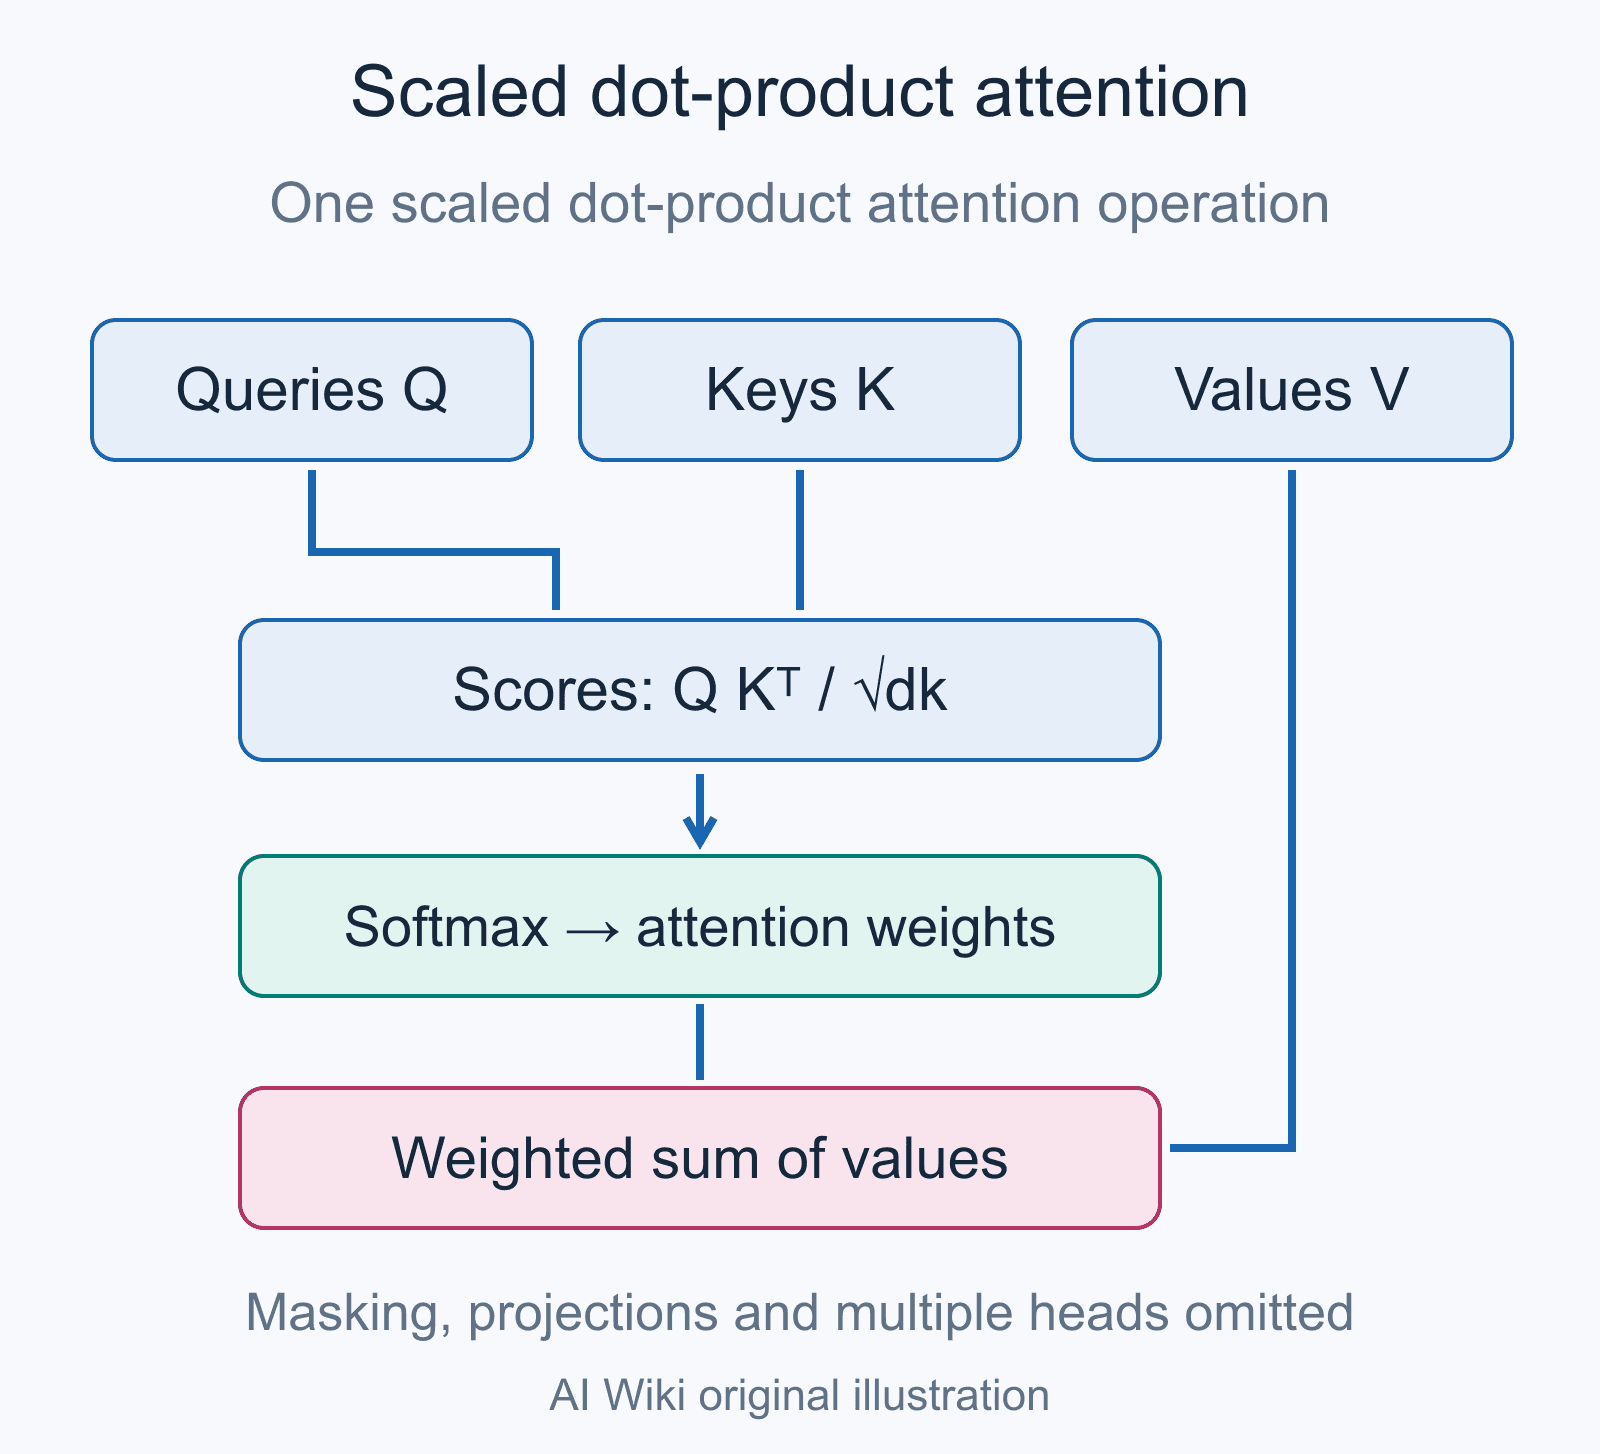
General matrix multiplications (GEMMs) are the fundamental building block of deep learning. Fully connected layers, recurrent neural network layers (including LSTMs and GRUs), attention layers in transformers, and even convolutional layers are all implemented internally as matrix multiplications. GPU computation can typically perform matrix products two orders of magnitude faster than CPU computation, primarily because GPUs assign each element of the resulting matrix to a separate thread for parallel computation.
Convolution Operations
Convolutional layers apply learned filters to input feature maps. For computational efficiency, these convolution operations are transformed into matrix multiplications using techniques such as im2col (image to column), which rearranges input patches into rows of a matrix so that the convolution becomes a standard GEMM. This transformation allows GPUs to leverage their highly optimized matrix multiplication routines, such as those in NVIDIA's cuDNN library.
Training and Inference
During training, GPUs accelerate both the forward pass (computing predictions) and the backward pass (backpropagation, computing gradients). The optimizer step, which updates model weights based on gradients, is also parallelized across GPU cores. Modern training runs for large language models involve thousands of GPUs running in parallel for weeks or months.
During inference, GPUs provide the throughput needed to serve predictions at scale. Techniques such as batching multiple inference requests together and using lower-precision formats (INT8, FP8, FP4) maximize GPU utilization and reduce latency.
How does a GPU differ from a CPU?
The following table summarizes the key architectural differences between CPUs and GPUs that explain their complementary roles in computing.
| Feature | CPU | GPU |
|---|---|---|
| Core count | 4 to 128 high-performance cores | Thousands of simpler cores (e.g., 16,896 CUDA cores on H100) |
| Clock speed | 3.0 to 5.5 GHz | 1.0 to 2.5 GHz |
| Design philosophy | Optimized for low-latency sequential tasks | Optimized for high-throughput parallel tasks |
| Instruction handling | Complex out-of-order execution, branch prediction, speculative execution | SIMT execution; groups of threads run the same instruction |
| Cache per core | Large (MB-scale L2/L3 caches) | Small per-core cache; large shared L2 |
| Memory type | DDR4/DDR5 (up to ~100 GB/s) | HBM2e/HBM3/HBM3e (up to 8,000 GB/s) |
| Memory capacity | Up to several TB (system RAM) | 16 GB to 288 GB per GPU |
| Floating-point units | Fewer but more versatile ALUs | Thousands of specialized FP/INT units and Tensor Cores |
| Power consumption | 65 W to 350 W (typical server CPU) | 250 W to 1,400 W (data center GPU) |
| Best suited for | Operating systems, databases, serial logic, branching code | Matrix math, image processing, neural network training/inference |
CUDA: NVIDIA's Parallel Computing Platform
CUDA (Compute Unified Device Architecture) is NVIDIA's proprietary parallel computing platform and programming model. Released in 2006/2007, CUDA allows developers to write programs in C, C++, Python, and Fortran that execute on NVIDIA GPUs.[3] CUDA abstracts the GPU's hardware into a hierarchy of threads, blocks, and grids, enabling fine-grained control over parallel execution.
CUDA Software Ecosystem
CUDA's dominance in AI is reinforced by a deep software ecosystem:
| Library | Purpose |
|---|---|
| cuDNN | Optimized primitives for deep neural networks (convolution, pooling, normalization, activation) |
| cuBLAS | GPU-accelerated basic linear algebra (GEMM, GEMV) |
| NCCL | Multi-GPU and multi-node collective communication (all-reduce, broadcast) |
| TensorRT | Inference optimization and runtime for deploying trained models |
| Triton Inference Server | Model serving framework for production deployment |
| cuDF / RAPIDS | GPU-accelerated data science and analytics |
| Thrust | High-level parallel algorithms library (sort, scan, reduce) |
All major deep learning frameworks, including PyTorch, TensorFlow, and JAX, rely on CUDA for GPU acceleration on NVIDIA hardware. This ecosystem lock-in, built over nearly two decades, represents one of NVIDIA's most significant competitive advantages.
NVIDIA GPU Generations for AI
NVIDIA has released a series of data center GPU architectures, each delivering significant performance improvements for AI workloads.
Tesla Architecture (2006)
The original Tesla architecture, powering the GeForce 8800 series and the Tesla C870 data center card, was the first to support CUDA. It introduced unified shaders, replacing the separate vertex and pixel shader units of earlier GPUs with a single pool of programmable processors.[1] While modest by modern standards, it proved the viability of general-purpose GPU computing.
Fermi (2010)
Fermi introduced error-correcting code (ECC) memory, a true L1/L2 cache hierarchy, and improved double-precision floating-point performance, making GPUs viable for scientific high-performance computing (HPC) workloads for the first time.
Kepler (2012) and Maxwell (2014)
Kepler improved energy efficiency with its SMX streaming multiprocessor design and introduced Dynamic Parallelism, allowing GPU threads to launch new GPU threads. Maxwell further refined power efficiency and was widely used in early deep learning research.
Pascal (2016)
The Tesla P100, based on the Pascal architecture, was the first NVIDIA GPU to use HBM2 memory, providing 732 GB/s of bandwidth. It introduced NVLink 1.0 for high-speed GPU-to-GPU communication and delivered 10.6 TFLOPS of FP32 performance.[4]
Volta (2017) and the V100
The Tesla V100 was a watershed moment for AI computing. It introduced first-generation Tensor Cores, specialized hardware for mixed-precision matrix operations that delivered up to 125 TFLOPS of deep learning performance (SXM2 variant).[4] Key specifications:
- 5,120 CUDA cores and 640 Tensor Cores
- 16 GB or 32 GB HBM2 memory at 900 GB/s bandwidth
- 300 W TDP (SXM2)
- NVLink 2.0 at 300 GB/s total bandwidth
The V100 became the standard GPU for AI research from 2017 to 2020.[4]
Ampere (2020) and the A100
The A100 introduced third-generation Tensor Cores with support for TF32, BF16, and structured sparsity (2:4), which could double effective throughput for compatible models. Key specifications:[5]
- 6,912 CUDA cores and 432 Tensor Cores
- 40 GB or 80 GB HBM2e memory at up to 2,039 GB/s bandwidth
- 312 TFLOPS FP16 Tensor (624 TFLOPS with sparsity)
- 400 W TDP (SXM variant)
- Multi-Instance GPU (MIG) technology, allowing a single GPU to be partitioned into up to seven isolated instances
- NVLink 3.0 at 600 GB/s total bandwidth
Hopper (2022) and the H100/H200
The H100 brought fourth-generation Tensor Cores and the Transformer Engine, which dynamically selects between FP8 and FP16 precision to maximize throughput for transformer-based models. Key specifications of the H100 SXM:[6]
- 16,896 CUDA cores and 528 Tensor Cores
- 80 GB HBM3 memory at 3,350 GB/s bandwidth
- 1,979 TFLOPS FP16 Tensor and 3,958 TFLOPS FP8 Tensor with sparsity (989 and 1,979 dense)
- 700 W TDP
- NVLink 4.0 at 900 GB/s total bandwidth
The H200, released in late 2024, retained the Hopper architecture but upgraded to 141 GB of HBM3e memory at 4,800 GB/s, providing significantly more memory capacity and bandwidth for large model inference.[8]
Blackwell (2024) and the B200/GB200
The B200 was NVIDIA's most powerful single GPU for AI at its 2024 launch; it has since been followed by Blackwell Ultra, with 288 GB of HBM3E,[18] and NVIDIA unveiled its next platform, Vera Rubin, in early 2026.[21] It uses a novel dual-die design, connecting two reticle-limited dies with a 10 TB/s chip-to-chip interconnect to function as a single unified GPU. Key specifications:[7]
- 208 billion transistors on TSMC 4NP process
- 192 GB HBM3e memory at approximately 8,000 GB/s bandwidth
- Fifth-generation Tensor Cores with FP4 and FP6 support
- About 9 PFLOPS at FP8 and 18 PFLOPS at FP4 per GPU with sparsity (half that dense), based on the 8-GPU DGX B200[24]
- 1,000 W TDP
- NVLink 5.0 at 1,800 GB/s total bandwidth
The GB200 is a "Superchip" that pairs two B200 GPUs with one Grace CPU on a single board, providing 372 GB of combined GPU memory.[25] The GB200 NVL72 system connects 72 Blackwell GPUs and 36 Grace CPUs via NVLink 5 and NVSwitch, delivering 130 TB/s of aggregate system bandwidth as a single, unified accelerator.[7] Announcing NVIDIA's fiscal 2025 fourth-quarter results, CEO Jensen Huang said that "demand for Blackwell is amazing as reasoning AI adds another scaling law" and that NVIDIA had "successfully ramped up the massive-scale production of Blackwell AI supercomputers, achieving billions of dollars in sales in its first quarter."[22]
Summary of NVIDIA Data Center GPU Generations
| GPU | Architecture | Year | Tensor TFLOPS (FP16) | Memory | Bandwidth | TDP |
|---|---|---|---|---|---|---|
| Tesla P100 | Pascal | 2016 | N/A (no Tensor Cores) | 16 GB HBM2 | 732 GB/s | 300 W |
| Tesla V100 | Volta | 2017 | 125 | 16/32 GB HBM2 | 900 GB/s | 300 W |
| A100 | Ampere | 2020 | 312 (624 sparse) | 40/80 GB HBM2e | 2,039 GB/s | 400 W |
| H100 SXM | Hopper | 2022 | 989 (1,979 sparse) | 80 GB HBM3 | 3,350 GB/s | 700 W |
| H200 SXM | Hopper | 2024 | 989 (1,979 sparse) | 141 GB HBM3e | 4,800 GB/s | 700 W |
| B200 | Blackwell | 2024 | ~2,500 (~5,000 sparse; GB200 configuration) | 192 GB HBM3e | ~8,000 GB/s | 1,000 W |
AMD: Instinct GPUs and ROCm
AMD has emerged as NVIDIA's primary competitor in the AI accelerator market with its Instinct series of data center GPUs and the ROCm (Radeon Open Compute) open-source software stack.
Instinct GPU Lineup
| GPU | Architecture | Memory | Memory Bandwidth | Key Features |
|---|---|---|---|---|
| MI250X | CDNA 2 | 128 GB HBM2e | 3,277 GB/s | Dual-die design; 383 TFLOPS FP16 |
| MI300X | CDNA 3 | 192 GB HBM3 | 5,300 GB/s | 8 XCDs on single package; chiplet design |
| MI325X | CDNA 3 | 256 GB HBM3E | 6,000 GB/s | 1.8x the memory capacity of NVIDIA H200 |
| MI350X | CDNA 4 | 288 GB HBM3E | 8,000 GB/s | Launched June 2025; day-zero framework support |
AMD said in June 2025 that seven of the ten largest model builders and AI companies were running production workloads on Instinct GPUs, including Meta, OpenAI, Microsoft, and xAI.[26]
ROCm Software Stack
ROCm is AMD's answer to CUDA. It provides an open-source collection of drivers, compilers, libraries, and tools for running HPC and AI workloads on AMD GPUs. ROCm includes HIP (Heterogeneous-compute Interface for Portability), which allows developers to write code that can compile and run on both AMD and NVIDIA GPUs with minimal changes. Key ROCm libraries include rocBLAS (linear algebra), MIOpen (deep learning primitives), and RCCL (collective communications).
ROCm 7, released in 2025, demonstrated up to 3.5x performance improvements in AI inference over ROCm 6.0, with AMD-reported inference gains of up to 3.2x on Llama 3.1 70B and 3.8x on DeepSeek R1, and about 3x for training.[10][27] Despite these advances, the ROCm ecosystem remains smaller than CUDA's, with some frameworks and libraries offering less mature AMD support.
Google TPUs
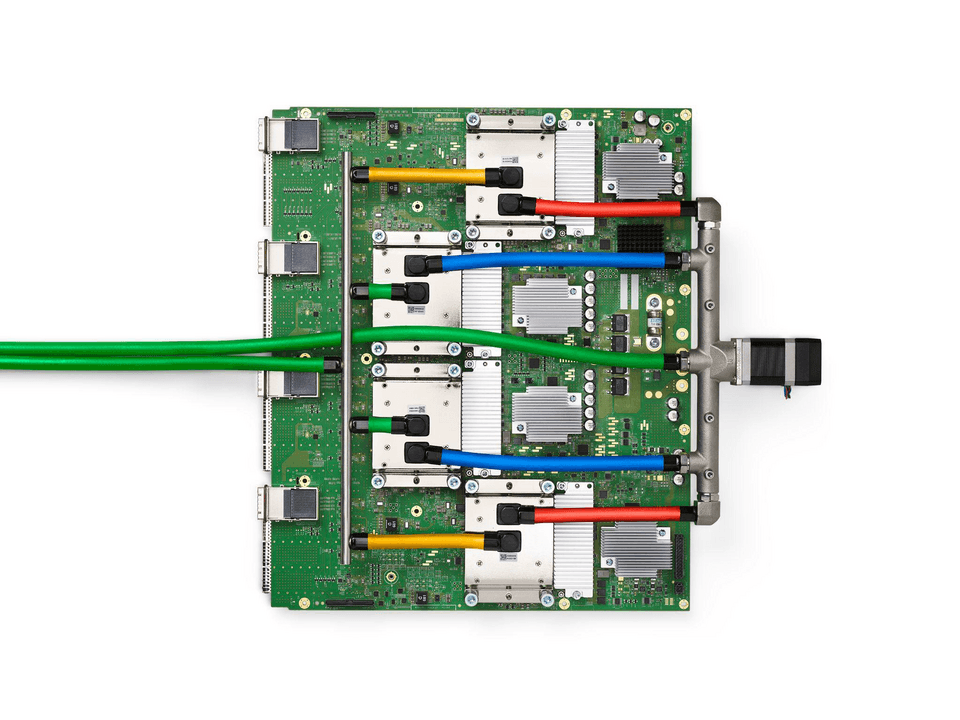
Google has taken a different approach with its Tensor Processing Units (TPUs), custom-designed ASICs (application-specific integrated circuits) built specifically for machine learning workloads. Unlike GPUs, which are general-purpose parallel processors repurposed for AI, TPUs are designed from the ground up to accelerate matrix multiplications and other neural network operations.
TPU Generations
| TPU Version | Year | Key Improvements |
|---|---|---|
| TPU v1 | 2016 | Inference only; deployed internally at Google |
| TPU v2 | 2017 | Added training support; 45 TFLOPS BF16; HBM |
| TPU v3 | 2018 | Liquid cooling; 420 TFLOPS BF16; 128 GB HBM in pod |
| TPU v4 | 2021 | 275 TFLOPS BF16; up to 4,096 chips per pod |
| TPU v5e | 2023 | Cost-optimized; 393 TOPS INT8; 2.5x throughput/dollar vs. v4 |
| TPU v5p | 2023 | Performance-optimized; 2x FLOPS and 3x HBM over v4 |
| Trillium (v6e) | 2024 | 4.7x performance over v5e; doubled HBM capacity and bandwidth |
| Ironwood (v7) | 2025 | Inference-focused; 4,614 TFLOPS peak per chip; 192 GB HBM at 7.37 TB/s; up to 9,216 chips per pod[29] |
TPUs are available exclusively through Google Cloud and are used internally to train Google's largest models, including Gemini. The TPU v5p pod can connect up to 8,960 chips, with a peak of 459 TFLOPS of BF16 compute per chip, for large-scale distributed training.[11][28]
Other AI Accelerators
The demand for AI compute has sparked a wave of specialized hardware beyond traditional GPUs and TPUs.
AWS Trainium and Inferentia
Amazon Web Services develops its own AI chips. Trainium2 is designed for large-scale model training, while Inferentia2 targets cost-efficient inference at 190 TFLOPS of FP16 performance. AWS's Trainium3, now offered in UltraServers of up to 144 chips, delivers up to 2x the MXFP8 compute throughput of Trainium2, about 2.5 PFLOPS per chip.[35]
Intel Gaudi
Intel's Gaudi accelerators (Gaudi 2 and Gaudi 3) were designed as cost-effective alternatives to NVIDIA GPUs for AI training and inference. Gaudi 3, launched in 2024, increased memory capacity for improved LLM efficiency. However, Gaudi 3 fell short of Intel's sales goals, and in January 2025 Intel said it would not bring the planned successor, Falcon Shores, to market, shifting its focus to a rack-scale system called Jaguar Shores.[34]
Cerebras
Cerebras Systems takes a radical approach with its Wafer-Scale Engine (WSE). Rather than cutting a silicon wafer into individual chips, Cerebras uses the entire wafer as a single processor. The WSE-3, announced in 2024, contains approximately 4 trillion transistors, over 900,000 compute cores, and delivers 125 PFLOPS of peak performance. The WSE eliminates the memory bandwidth bottleneck by placing 44 GB of on-chip SRAM directly adjacent to compute cores, achieving approximately 21 PB/s of memory bandwidth.
Groq
Groq designs a Language Processing Unit (LPU) optimized for low-latency inference. Each Groq chip contains 230 MB of on-chip SRAM with up to 80 TB/s of on-die memory bandwidth, delivering 750 TOPS at INT8. Groq's deterministic, compiler-driven architecture eliminates the scheduling overhead of traditional GPUs, achieving exceptionally low latency for inference tasks.
SambaNova
SambaNova Systems develops reconfigurable dataflow architecture accelerators. Its SN40L chip and the newer SN50 (unveiled in February 2026) are designed for enterprise AI workloads. The SN50 claims 5x more compute per accelerator and 4x more network bandwidth than its predecessor.
Comparison of Major AI Accelerators
| Accelerator | Vendor | Type | Memory | Peak Performance | Strengths |
|---|---|---|---|---|---|
| H100 SXM | NVIDIA | GPU | 80 GB HBM3 | 3,958 TFLOPS FP8 (sparse) | Ecosystem, Transformer Engine, versatility |
| B200 | NVIDIA | GPU | 192 GB HBM3e | ~9 PFLOPS FP8 (sparse) | Dual-die design, FP4 support, NVLink 5 |
| MI300X | AMD | GPU | 192 GB HBM3 | 1,307 TFLOPS FP16 | High memory capacity, open-source ROCm |
| MI325X | AMD | GPU | 256 GB HBM3E | 1,307 TFLOPS FP16 | Large memory capacity (1.8x H200) |
| TPU v5p | ASIC | HBM (per chip) | 459 TFLOPS BF16 | Tight cloud integration, pod scalability | |
| Trillium (v6e) | ASIC | Doubled HBM | 4.7x v5e perf | Energy efficiency, cost per FLOP | |
| Trainium2 | AWS | ASIC | HBM | Custom benchmarks | AWS ecosystem integration |
| Gaudi 3 | Intel | ASIC | HBM2e | Competitive with H100 | Cost-effective training |
| WSE-3 | Cerebras | Wafer-scale | 44 GB SRAM on-chip | 125 PFLOPS peak | Eliminates memory bandwidth bottleneck |
| LPU | Groq | ASIC | 230 MB SRAM on-chip | 750 TOPS INT8 | Ultra-low latency inference |
Multi-GPU and Distributed Training
Training modern AI models, especially large language models with billions or trillions of parameters, requires distributing computation across multiple GPUs and often multiple servers. Several parallelism strategies have been developed to accomplish this.
Data Parallelism
Data parallelism is the simplest distributed training strategy. Multiple copies of the entire model are placed on different GPUs, and each GPU processes a different mini-batch of training data. After computing gradients, the GPUs synchronize by performing an all-reduce operation to average the gradients before updating the model weights. PyTorch's DistributedDataParallel (DDP) is the most widely used implementation.
Data parallelism works well when the model fits in the memory of a single GPU. It scales efficiently to hundreds of GPUs, with communication overhead as the primary bottleneck.
Model Parallelism
Model parallelism splits the model itself across GPUs rather than the data. This is necessary when a model is too large to fit in a single GPU's memory.
-
Tensor parallelism splits individual layers (typically large matrix multiplications) across multiple GPUs. For example, a large weight matrix can be divided column-wise across four GPUs, with each GPU computing its portion and then communicating to reconstruct the full result. Tensor parallelism is best suited for GPUs within the same node connected by high-bandwidth NVLink.
-
Pipeline parallelism assigns different sequential layers (or groups of layers) to different GPUs. GPU 1 computes the first few layers, passes activations to GPU 2 for the next layers, and so on. To minimize idle time ("pipeline bubbles"), micro-batching techniques like GPipe and PipeDream interleave multiple micro-batches through the pipeline.
Fully Sharded Data Parallel (FSDP)
Fully Sharded Data Parallel (FSDP) combines the benefits of data and model parallelism. It shards model parameters, gradients, and optimizer states across all GPUs, gathering the full parameters only when needed for forward and backward computation and then immediately re-sharding. FSDP, originally developed at Meta and now integrated into PyTorch, is based on the same principles as DeepSpeed ZeRO Stage 3.[12]
FSDP dramatically reduces per-GPU memory usage, making it possible to train models that would not fit using standard data parallelism, while maintaining competitive throughput.[12]
Expert Parallelism
With the rise of Mixture of Experts (MoE) architectures, expert parallelism distributes different expert sub-networks across different GPUs. Only a subset of experts is activated for each input token, reducing computation while allowing the total model to have an extremely large parameter count.
3D Parallelism
State-of-the-art training systems for the largest models combine data, tensor, and pipeline parallelism simultaneously, an approach commonly called 3D parallelism. Frameworks like Megatron-LM (NVIDIA), DeepSpeed (Microsoft), and Fully Sharded Data Parallel (Meta/PyTorch) provide the tools to orchestrate these complex parallel configurations.
GPU Interconnects
High-bandwidth, low-latency communication between GPUs is critical for efficient distributed training. Three interconnect technologies dominate the landscape.
NVLink
NVLink is NVIDIA's proprietary high-speed point-to-point interconnect for GPU-to-GPU communication within a node. Each generation has dramatically increased bandwidth:[13]
| NVLink Version | GPU Architecture | Per-GPU Bidirectional Bandwidth |
|---|---|---|
| NVLink 1.0 | Pascal (P100) | 160 GB/s |
| NVLink 2.0 | Volta (V100) | 300 GB/s |
| NVLink 3.0 | Ampere (A100) | 600 GB/s |
| NVLink 4.0 | Hopper (H100) | 900 GB/s |
| NVLink 5.0 | Blackwell (B200) | 1,800 GB/s |
NVSwitch
NVSwitch is a dedicated switch chip that enables all-to-all NVLink connectivity among all GPUs within a node. In a DGX system with 8 GPUs and NVSwitch, every GPU can communicate directly with every other GPU at full NVLink bandwidth, avoiding the reduced bandwidth of ring or mesh topologies.[13] The Blackwell-generation DGX B200 connects 8 B200 GPUs via NVLink 5 for up to 14.4 TB/s of aggregate GPU-to-GPU bandwidth per node.
The GB200 NVL72 extends this concept further, using NVSwitch to interconnect 72 GPUs across multiple trays as a single logical accelerator with 130 TB/s of total system bandwidth.[7]
InfiniBand
While NVLink connects GPUs within a node, InfiniBand connects nodes across a cluster. InfiniBand is an industry-standard networking protocol designed for high-performance computing, providing low latency and high bandwidth between servers. NVIDIA's Quantum-2 InfiniBand switches support NDR (400 Gb/s per port), and the roadmap includes higher-bandwidth generations. InfiniBand remains the preferred fabric for large-scale AI training clusters, though some deployments use RoCE (RDMA over Converged Ethernet) as an alternative.
The complementary architecture is straightforward: NVLink and NVSwitch handle fast communication within each server node, while InfiniBand connects the nodes for distributed training across the cluster.
GPU Cloud Providers
Accessing GPU compute for AI training and inference has shifted predominantly to the cloud, where organizations can rent GPU capacity without the capital expenditure of building their own infrastructure.
Hyperscale Cloud Providers
| Provider | GPU Instances | Key Offerings |
|---|---|---|
| AWS | P5 (H100), P5e (H200), P6 (Blackwell) | SageMaker, EC2 UltraClusters, Trainium instances |
| Azure | ND H100 v5, ND H200 v5 | Azure Machine Learning, Azure AI |
| Google Cloud | A3 (H100), A3 Ultra (H200), TPU pods | Vertex AI, GKE with GPU support |
Specialized GPU Cloud Providers
A new category of "GPU-first" cloud providers (sometimes called "NeoClouds") has emerged to address the specific needs of AI workloads:
- CoreWeave pivoted from cryptocurrency mining to become one of the largest GPU cloud providers, raising significant capital including investment from NVIDIA and completing a $1.5 billion IPO in 2025.
- Lambda offers H100 GPU instances at competitive prices (around $2.99/hour per H100 as of 2025), focused specifically on AI researchers and developers.
- Together AI provides GPU clusters optimized for distributed training and inference, with early access to GB200 systems.
- RunPod and Vast.ai offer marketplace-style GPU rental, including spot instances at steep discounts.
Pricing Trends
GPU cloud pricing has dropped significantly since the peak of the 2023 shortage. H100 GPU instances, which initially commanded premium prices, have seen costs decrease as supply expanded. Specialized providers generally offer 50-70% savings compared to hyperscale cloud providers. AWS cut H100 pricing by approximately 44% in June 2025, and competitive pressure continues to drive costs lower. Spot and preemptible instances can reduce costs by 60-90% below on-demand rates, though with the risk of interruption.
GPU Shortage and Economics (2023-2024)
The release of ChatGPT in November 2022 triggered an unprecedented surge in demand for AI compute. Throughout 2023 and 2024, the AI industry experienced a severe GPU shortage that reshaped the economics of AI development.
Demand Surge
Hyperscale cloud providers (AWS, Azure, Google Cloud, Oracle) purchased AI GPUs at unprecedented scale, with H100 GPUs sold out through Q1 2024 as of summer 2023.
The scale of this demand is visible in NVIDIA's financials. The company's full-year Data Center revenue, which is overwhelmingly AI GPUs, rose 142% to $115.2 billion in fiscal 2025 and then a further 68% to $193.7 billion in fiscal 2026, while total company revenue reached $215.9 billion.[21][22] By contrast, NVIDIA's total Data Center revenue had been around $15 billion in fiscal 2023, underscoring how quickly GPU computing became the dominant driver of the company's business.
Supply Chain Bottlenecks
Several factors constrained GPU supply:
- Advanced packaging: NVIDIA's GPUs require TSMC's CoWoS (Chip-on-Wafer-on-Substrate) advanced packaging to integrate HBM memory with the GPU die. CoWoS capacity was extremely limited, and in 2023 TSMC announced a roughly $2.9 billion advanced packaging plant in Taiwan to expand capacity.[30]
- HBM memory production: High-bandwidth memory is manufactured by only three companies (SK Hynix, Samsung, and Micron), and supply could only support a fraction of the demand.
- Geopolitical restrictions: U.S. export controls on advanced AI chips to China further complicated supply chains and pushed Chinese companies to stockpile GPUs before restrictions took effect.
"GPU Rich" vs. "GPU Poor"
The shortage created a visible divide in the AI industry between well-funded organizations with access to large GPU clusters ("GPU rich") and smaller companies, startups, and academic researchers who struggled to secure compute ("GPU poor"). This disparity influenced AI research priorities, with some groups shifting focus to efficiency techniques, smaller models, and inference optimization rather than large-scale training.
Power Consumption and Sustainability
The rapid expansion of GPU computing for AI has raised significant concerns about energy consumption and environmental impact.
Rising Power Demands
Each generation of data center GPUs has increased power consumption. The V100 consumed 300 W, the A100 rose to 400 W, the H100 reached 700 W, and the B200 now draws 1,000 W. NVIDIA's Blackwell Ultra GPUs are rated at up to 1,400 W.[18] A single DGX B200 server with 8 GPUs consumes over 8 kW of GPU power alone, not including CPUs, networking, storage, and cooling.
Data Center Impact
U.S. data centers consumed approximately 176 terawatt-hours (TWh) of electricity in 2023, about 4.4% of total U.S. electricity, according to Lawrence Berkeley National Laboratory estimates.[19] LBNL projects 325 to 580 TWh, or 6.7% to 12% of U.S. electricity, by 2028.[32] In Virginia alone, data center capacity under contract with the utility Dominion Energy reached 40.2 GW in December 2024, nearly double the 21.4 GW of July 2024.[31]
The average power density per server rack is expected to increase from 36 kW in 2023 to 50 kW by 2027, driving a shift from air cooling to liquid cooling solutions.[15]
Sustainability Initiatives
In response to these challenges, the industry is pursuing several approaches:
- Liquid cooling: Both direct-to-chip liquid cooling and immersion cooling are being deployed to handle higher thermal densities more efficiently than air cooling.
- Nuclear power: Several major AI companies have signed agreements to revive retired nuclear plants or invest in small modular reactors (SMRs) for low-carbon baseload power.[15]
- Hardware efficiency: Each GPU generation improves performance per watt. NVIDIA's Blackwell Ultra adds features aimed at processing more work per watt.[18]
- Software efficiency: Techniques such as mixed-precision training, model quantization, sparsity, and more efficient architectures (e.g., Mixture of Experts) reduce the total compute required.
- Renewable energy: Major cloud providers have committed to matching their electricity consumption with renewable energy purchases, though the gap between commitments and actual 24/7 clean energy matching remains significant.
Water consumption for cooling AI data centers has also drawn scrutiny, particularly in drought-prone regions. Estimates suggest that training a single large language model can consume millions of liters of water when accounting for both direct cooling and the water used in electricity generation.
Future of AI Compute
Photonic Computing
Photonic computing uses light instead of electrical signals to perform computations. Photonic processors can perform matrix multiplications at the speed of light with extremely low energy consumption. In April 2025, researchers at Singapore-based Lightelligence reported in Nature a large-scale integrated photonic accelerator with ultralow latency,[20] and companies like Lightmatter and Q.ANT are developing commercial photonic accelerators. Q.ANT says its NPU 2 processor, launched in November 2025, delivers up to 30x lower energy use and 50x higher performance for certain AI and HPC workloads.[33] However, photonic computing faces challenges in precision, programmability, and integration with existing digital systems.
Neuromorphic Computing
Inspired by the structure of biological brains, neuromorphic chips use spiking neural networks and event-driven computation. Intel's Loihi 2 and IBM's NorthPole are research-stage neuromorphic processors that consume orders of magnitude less power than GPUs for certain pattern recognition tasks. Neuromorphic computing is particularly promising for edge AI applications where power budgets are extremely constrained, though it has not yet demonstrated competitiveness with GPUs for training large models.
Chiplet and Advanced Packaging
The trend toward chiplet-based designs, exemplified by AMD's MI300X (which uses multiple compute dies on a single package) and NVIDIA's Blackwell (with its dual-die design), will continue. Advanced packaging technologies like TSMC's CoWoS and its successors allow multiple dies, HBM stacks, and interconnects to be integrated into ever-larger and more powerful composite processors.
Quantum Computing
While quantum computing is often discussed as a potential successor to classical accelerators for certain AI tasks, practical quantum advantage for machine learning remains years or decades away. Near-term quantum computers lack the qubit counts and error correction needed for useful AI workloads. Hybrid quantum-classical approaches, where a quantum processor handles specific subroutines within a larger classical training pipeline, are an active area of research.
Continue reading
- NvidiaNvidia Corporation is an American technology company that designs graphics processing units (GPUs) and is the world's dominant supplier of hardware for artificial intelligenceMentioned 41 times above
- CUDACUDA (Compute Unified Device Architecture) is NVIDIA's platform and programming model for general-purpose computation on its graphics processing units.Mentioned 22 times above
- Deep LearningDeep learning is a subset of machine learning that uses artificial neural networks with multiple layers to automatically learn representations of data at multiple levels of abstractionMentioned 11 times above
- PyTorchPyTorch is an open-source software library for tensor computation and machine learning.Mentioned 4 times above
- Tensor Processing Unit (TPU)A Tensor Processing Unit (TPU) is a family of custom application-specific integrated circuits developed by Google to accelerate machine-learning computation.Listed in See also
- TransformersA Transformer is a deep learning architecture, introduced by eight Google researchers in the 2017 paper "Attention Is All You Need", that uses attention as the sole mechanism for modeling relationships between…Listed in See also
More from See also
- Prefix caching (automatic prefix caching)
- Self-speculative decoding (LayerSkip)
- TensorFlow
- Distributed computing
More to read
Topics:AI ComputeAI HardwareAI InfrastructureDeep LearningMachine Learning
References
- ^1 ^2NVIDIA Developer Blog. "CUDA Refresher: Reviewing the Origins of GPU Computing." developer.nvidia.com/...e-origins-of-gpu-computing
- ^1 ^2 ^3 ^4Wikipedia. "General-purpose computing on graphics processing units." en.wikipedia.org/...g_on_graphics_processing_units
- ^1 ^2 ^3 ^4Wikipedia. "CUDA." en.wikipedia.org/...CUDA
- ^1 ^2 ^3 ^4NVIDIA. "NVIDIA Tesla V100 GPU Architecture Whitepaper." images.nvidia.com/...a-architecture-whitepaper.pdf
- ^1 ^2NVIDIA. "NVIDIA A100 Tensor Core GPU Datasheet." nvidia.com/...-datasheet-nvidia-us-2188504-web.pdf
- ^1 ^2 ^3NVIDIA. "NVIDIA H100 Tensor Core GPU Datasheet." nvidia.com/...h100
- ^1 ^2 ^3 ^4NVIDIA. "NVIDIA Blackwell Architecture." nvidia.com/...blackwell-architecture
- ^NVIDIA. "NVIDIA H200 Tensor Core GPU." nvidia.com/...h200
- AMD. "AMD Instinct MI300 Series Accelerators." amd.com/...mi300
- ^AMD. "AMD Instinct MI350 Series and Beyond." amd.com/...d-accelerating-the-future-of-ai-and-hpc
- ^Google Cloud Blog. "Introducing Cloud TPU v5p and AI Hypercomputer." cloud.google.com/...d-tpu-v5p-and-ai-hypercomputer
- ^1 ^2Meta Engineering. "Fully Sharded Data Parallel: faster AI training with fewer GPUs." engineering.fb.com/...fsdp
- ^1 ^2NVIDIA. "NVLink and NVSwitch." nvidia.com/...nvlink
- ^1 ^2Cornell Virtual Workshop. "Understanding GPU Architecture." cvw.cac.cornell.edu/...design
- ^1 ^2Deloitte. "As generative AI asks for more power, data centers seek more reliable, cleaner energy solutions." deloitte.com/...-for-more-sustainable-data-centers
- ^SemiAnalysis. "NVIDIA Tensor Core Evolution: From Volta To Blackwell." newsletter.semianalysis.com/...-volta-to-blackwell
- ^1 ^2Raina, R., Madhavan, A., & Ng, A. (2009). "Large-scale Deep Unsupervised Learning using Graphics Processors." Proceedings of the 26th International Conference on Machine Learning. web.archive.org/...UnsupervisedDeepLearningGPU.pdf
- ^1 ^2 ^3NVIDIA Developer Blog. "Inside NVIDIA Blackwell Ultra." developer.nvidia.com/...owering-the-ai-factory-era
- ^Congress.gov. "Data Centers and Their Energy Consumption." congress.gov/...R48646
- ^Nature. "An integrated large-scale photonic accelerator with ultralow latency." nature.com/...s41586-025-08786-6
- ^1 ^2 ^3NVIDIA. "NVIDIA Announces Financial Results for Fourth Quarter and Fiscal 2026." (February 25, 2026). nvidianews.nvidia.com/...h-quarter-and-fiscal-2026
- ^1 ^2NVIDIA. "NVIDIA Announces Financial Results for Fourth Quarter and Fiscal 2025." (February 26, 2025). nvidianews.nvidia.com/...h-quarter-and-fiscal-2025
- ^1 ^2Krizhevsky, A., Sutskever, I., & Hinton, G. (2012). "ImageNet Classification with Deep Convolutional Neural Networks." Advances in Neural Information Processing Systems 25. proceedings.neurips.cc/...onal-neural-networks.pdf
- ^NVIDIA. "NVIDIA DGX B200." nvidia.com/...dgx-b200
- ^NVIDIA. "NVIDIA GB200 NVL72." nvidia.com/...gb200-nvl72
- ^AMD. "AMD Unveils Vision for an Open AI Ecosystem, Detailing New Silicon, Software and Systems at Advancing AI 2025." (June 12, 2025). newsroom.amd.com/...for-an-open-ai-ecosystem-detai
- ^Wccftech. "AMD ROCm 7 launch: MI350 support, new algorithms, models and advanced features, 3.5x inference uplift." (June 2025). wccftech.com/...s-advanced-features-ai-3-5x-uplift
- ^Google Cloud. "TPU v5p." Cloud TPU documentation. cloud.google.com/...v5p
- ^Google. "Ironwood: The first Google TPU for the age of inference." (April 9, 2025). blog.google/...ironwood-tpu-age-of-inference
- ^Packaging Insights. "TSMC to invest US$2.9B in advanced semiconductor packaging project." (August 1, 2023). packaginginsights.com/...nductor-packaging-project
- ^Data Center Knowledge (Bloomberg). "Data Center Power Demand Almost Doubled in Virginia." (February 13, 2025). datacenterknowledge.com/...ost-doubled-in-virginia
- ^Lawrence Berkeley National Laboratory. "Berkeley Lab Report Evaluates Increase in Electricity Demand from Data Centers." (January 15, 2025). newscenter.lbl.gov/...ity-demand-from-data-centers
- ^The Quantum Insider. "Q.ANT Releases New Photonic Processor for AI and HPC." (November 19, 2025). thequantuminsider.com/...qant-next-gen-photonic-npu
- ^TechCrunch. "Intel won't bring its Falcon Shores AI chip to market." (January 30, 2025). techcrunch.com/...-falcon-shores-ai-chip-to-market
- ^AWS. "AWS Trainium." aws.amazon.com/...trainium
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
12 revisions · v12 · 6,204 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (170 claims, 44 sources fetched); 12 material + 25 minor fixed
Cite this page: AI Wiki. "GPU computing." aiwiki.ai, updated 20 Jun 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/gpu_computing