

DenseNet
DenseNet (Densely Connected Convolutional Networks) is a convolutional neural network architecture that connects every layer to every other layer in a feed-forward fashion, so that each layer receives the feature maps of all preceding layers as input. It was introduced by Gao Huang, Zhuang Liu, Laurens van der Maaten, and Kilian Q. Weinberger in the 2016 paper "Densely Connected Convolutional Networks," which received the Best Paper Award at the IEEE Conference on Computer Vision and Pattern Recognition (CVPR) in 2017.[1] Whereas a traditional convolutional network with L layers has L connections, a DenseNet has L(L+1)/2 direct connections.[1] This dense connectivity promotes extensive feature reuse, improves gradient flow during training, and achieves strong image classification accuracy with far fewer parameters than prior architectures like VGG and ResNet: on CIFAR-10 with augmentation, the authors report that DenseNet-BC needs "around 1/3 of the parameters of ResNets" to reach comparable accuracy.[1]
The paper's abstract summarizes the four core benefits: DenseNets "alleviate the vanishing-gradient problem, strengthen feature propagation, encourage feature reuse, and substantially reduce the number of parameters."[1]
Background and Motivation
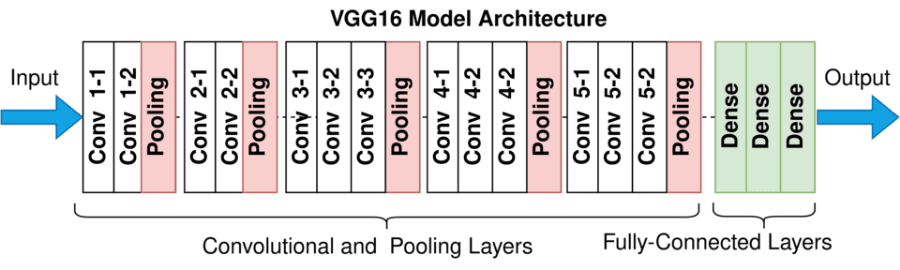
As deep learning models grew deeper throughout the mid-2010s, researchers encountered recurring challenges related to vanishing gradients, diminishing feature propagation, and parameter inefficiency. Networks like VGGNet (2014) demonstrated that increasing depth could improve accuracy on benchmarks like ImageNet, but doing so came at the cost of enormous parameter counts (VGG-16 has roughly 138 million parameters) and substantial computational demands.[9]
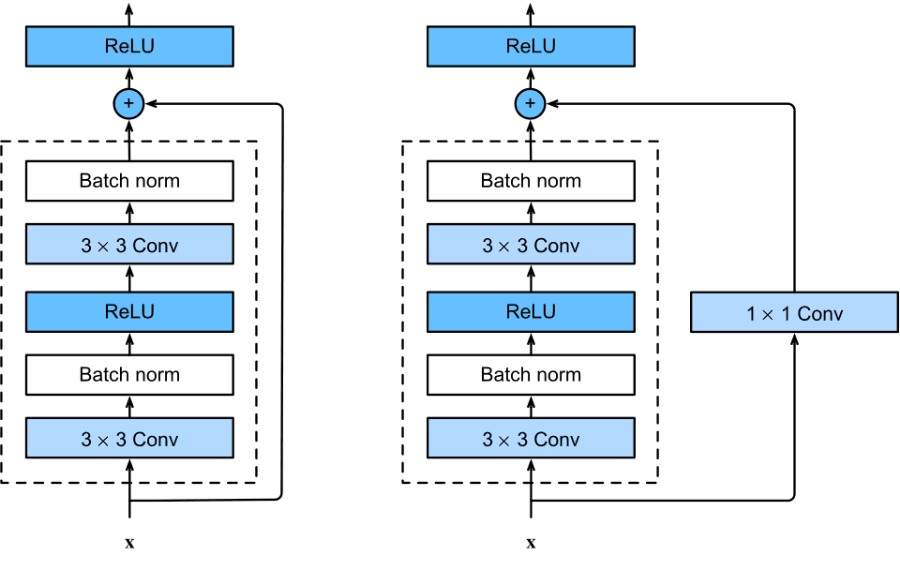
ResNet (2015) addressed the vanishing gradient problem by introducing skip connections (also called shortcut connections or residual connections) that allow gradients to flow directly through identity mappings.[4] While ResNet proved that training very deep networks (100+ layers) was feasible, its connections only link a layer to the one or two layers immediately before it. Highway Networks, proposed around the same time, used gating mechanisms to regulate information flow but added complexity.
The DenseNet authors framed their work as embracing a single observation: "convolutional networks can be substantially deeper, more accurate, and efficient to train if they contain shorter connections between layers close to the input and those close to the output."[1] DenseNet extends the idea of shortcut connections to its logical extreme: rather than connecting each layer to just the preceding layer, DenseNet connects each layer to all preceding layers within the same block. The authors hypothesized that creating shorter connections between layers close to the input and layers close to the output would make training more effective and lead to more compact models. This hypothesis proved correct across multiple benchmarks.
What is dense connectivity?
The defining feature of DenseNet is its dense connectivity pattern. In a traditional feed-forward neural network with L layers, there are L connections (one between each pair of consecutive layers). In a DenseNet, there are L(L+1)/2 direct connections because each layer receives input from all preceding layers.[1] As the paper puts it, "for each layer, the feature-maps of all preceding layers are used as inputs, and its own feature-maps are used as inputs into all subsequent layers."[1]
Formally, let x₀ denote the input to a dense block. The output of the l-th layer, xₗ, is defined as:
xₗ = Hₗ([x₀, x₁, ..., xₗ₋₁])
Here, [x₀, x₁, ..., xₗ₋₁] denotes the concatenation of the feature maps produced by layers 0 through l-1, and Hₗ is a composite function that typically consists of Batch Normalization (BN), a ReLU activation, and a convolution operation.
This concatenation-based approach is a crucial distinction from ResNet, which uses element-wise addition of feature maps. By concatenating rather than adding, DenseNet preserves all previously computed features in their original form. Each layer can access the "collective knowledge" of the entire network up to that point, which the authors refer to as feature reuse.
Architecture Components
Dense Blocks
A dense block is a sequence of convolutional layers where each layer receives the concatenated feature maps of all preceding layers within that block. Within a dense block, the spatial dimensions (height and width) of feature maps remain constant, which is necessary for the concatenation operation to work.
Each layer in a dense block produces a fixed number of new feature maps, denoted by the hyperparameter k (called the growth rate). If the input to a dense block has k₀ feature maps, then the l-th layer within the block receives k₀ + k(l-1) input feature maps (the original k₀ features plus k features from each of the l-1 preceding layers).
The composite function Hₗ within a standard dense block follows the sequence:
- Batch Normalization
- ReLU activation
- 3x3 Convolution (producing k feature maps)
This ordering (BN-ReLU-Conv) is known as the pre-activation design, following the approach introduced by He et al. in their work on pre-activation ResNets.[11]
Growth Rate (k)
The growth rate k controls how much new information each layer contributes to the collective feature maps. Unlike traditional architectures where layers often produce hundreds of feature maps, DenseNet layers typically produce a modest number (commonly k = 32 or k = 48). On the CIFAR benchmarks the authors experimented with configurations of "{L=40,k=12}, {L=100,k=12} and {L=100,k=24}."[1] Even with a small growth rate, the total number of feature maps at the end of a dense block can be large due to the cumulative concatenation from all preceding layers.
The authors found that relatively narrow layers (small k) were sufficient for strong performance because each layer has access to all preceding feature maps. This is in contrast to architectures like VGG, where each layer must independently learn all necessary features from only the immediately preceding layer's output.
Transition Layers
Since dense blocks maintain constant spatial dimensions, the network uses transition layers between consecutive dense blocks to perform downsampling. Each transition layer consists of:
- Batch Normalization
- 1x1 Convolution (to reduce the number of feature maps)
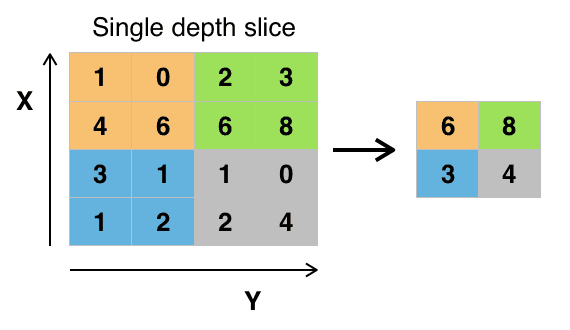
- 2x2 Average Pooling with stride 2 (to halve the spatial dimensions)
Transition layers serve the critical role of controlling model complexity. Without them, the number of feature maps would grow indefinitely as the network deepens, making computation impractical.
Bottleneck Layers (DenseNet-B)
Although each layer in a dense block produces only k feature maps, the number of input feature maps to each layer can be quite large due to concatenation. To reduce computational cost, the authors introduced a bottleneck variant called DenseNet-B.
In DenseNet-B, each layer uses a two-step convolution process:
- BN-ReLU-Conv(1x1): produces 4k feature maps (reduces dimensionality)
- BN-ReLU-Conv(3x3): produces k feature maps
The 1x1 convolution acts as a bottleneck that compresses the input to 4k channels before the more expensive 3x3 convolution. This significantly reduces the number of floating-point operations without sacrificing accuracy.
Compression (DenseNet-C)
To further improve model compactness, the authors introduced a compression mechanism at the transition layers. If a dense block outputs m feature maps, the subsequent transition layer produces floor(θm) output feature maps, where θ is the compression factor (0 < θ <= 1).
When θ = 1, the transition layer does not reduce the number of feature maps. When θ < 1, the model is called DenseNet-C. The authors state, "we set θ=0.5 in our experiment," meaning the transition layer reduces the number of feature maps by half.[1]
DenseNet-BC
When both bottleneck layers and compression are used together, the resulting model is called DenseNet-BC. This is the most parameter-efficient variant and is the configuration used for all ImageNet experiments reported in the paper. DenseNet-BC models achieve the best trade-off between accuracy and parameter count.
Initial Layers
For ImageNet-scale models, the network begins with a single 7x7 convolution layer with stride 2 and 2k (or 64) output channels, followed by a 3x3 max pooling layer with stride 2. This initial downsampling reduces the spatial resolution from 224x224 to 56x56 before the first dense block.
For smaller datasets like CIFAR-10 and CIFAR-100, the initial layer is a single 3x3 convolution with 16 (or 2k) output channels, without pooling.
Classification Layer
After the final dense block, a global average pooling layer reduces each feature map to a single value, followed by a fully connected (dense) layer with softmax activation that produces the final class predictions.
Network Configurations
The ImageNet variants of DenseNet-BC all use four dense blocks with varying numbers of layers per block. The following table summarizes the standard configurations; errors for DenseNet-121, -169 and -201 are the paper's single-crop results, DenseNet-161 is a later k=48 model from the authors' code release, and parameter counts are those of the torchvision implementations:[1][12][13]
| Variant | Layers per Dense Block | Growth Rate (k) | Parameters | Top-1 Error (%) | Top-5 Error (%) |
|---|---|---|---|---|---|
| DenseNet-121 | 6, 12, 24, 16 | 32 | 7.98M | 25.02 | 7.71 |
| DenseNet-169 | 6, 12, 32, 32 | 32 | 14.15M | 23.80 | 6.85 |
| DenseNet-201 | 6, 12, 48, 32 | 32 | 20.01M | 22.58 | 6.34 |
| DenseNet-161 | 6, 12, 36, 24 | 48 | 28.68M | 22.2 | Not reported |
The number in each variant's name corresponds to the total depth of the network, counting all convolutional layers (including those in transition layers and the initial convolution). For example, DenseNet-121 has 6 + 12 + 24 + 16 = 58 dense layers, plus 3 transition layers (each with one 1x1 conv), plus 1 initial conv, plus 1 final classification layer, totaling 121 layers when bottleneck layers are included (since each dense layer has two convolutions in the bottleneck design, the total is 2 x 58 + 3 + 1 + 1 = 121).
DenseNet-264 (k=32) already appears in the original paper; the memory-efficient technical report later trained larger 264-layer models, including a cosine-schedule k=48 version:[1][3][12]
| Variant | Layers per Dense Block | Growth Rate (k) | Parameters | Top-1 Error (%) |
|---|---|---|---|---|
| DenseNet-264 (k=32) | 6, 12, 64, 48 | 32 | ~33M | 22.15 |
| DenseNet-264 (k=48, cosine schedule) | 6, 12, 64, 48 | 48 | ~73M | 20.26 |
The DenseNet-264 variant with k=48 and a cosine learning rate schedule achieved a single-crop top-1 error of 20.26% on the ImageNet validation set in the technical report (the authors' code repository lists 20.4%), the strongest single-model result reported by the DenseNet authors.[3][12]
How does DenseNet differ from ResNet and VGG?
DenseNet vs. ResNet
DenseNet and ResNet share the philosophy of creating shorter paths for information and gradients, but they differ in important ways:
| Feature | ResNet | DenseNet |
|---|---|---|
| Connection type | Additive skip connections | Concatenation of feature maps |
| Feature combination | Element-wise addition | Channel-wise concatenation |
| Feature reuse | Implicit (through addition) | Explicit (original features preserved) |
| Parameter efficiency | Moderate | High |
| Typical growth per layer | 64-2048 channels | 32-48 channels (growth rate k) |
| Memory during training | Lower | Higher (naive implementation) |
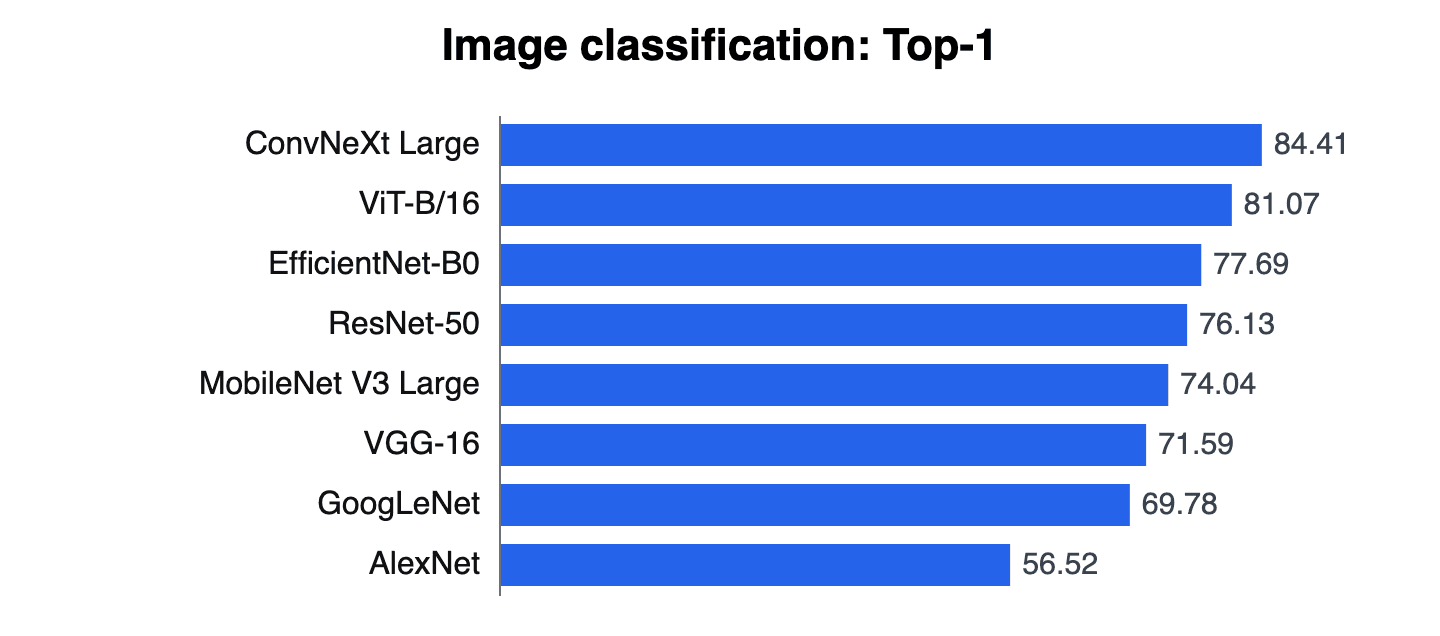
In terms of performance on ImageNet, the following comparison highlights DenseNet's parameter efficiency (DenseNet errors from the paper and the authors' code release; ResNet errors are the 1-crop results of the original ResNet authors' released models):[1][12][14]
| Model | Parameters | Top-1 Error (%) |
|---|---|---|
| ResNet-50 | 25.6M | 24.7 |
| DenseNet-121 | 7.98M | 25.0 |
| DenseNet-201 | 20.01M | 22.6 |
| ResNet-101 | 44.5M | 23.6 |
| ResNet-152 | 60.2M | 23.0 |
| DenseNet-161 | 28.68M | 22.2 |
The authors report that "a DenseNet-201 with 20M parameters model yields similar validation error as a 101-layer ResNet with more than 40M parameters," and on computation that "a DenseNet that requires as much computation as a ResNet-50 performs on par with a ResNet-101, which requires twice as much computation."[1] The memory-efficient technical report adds that a 201-layer DenseNet matches a ResNet-101's top-1 error with about half the parameters (20M vs 44M) and half the floating point operations (80B vs 155B per image).[3] On CIFAR-10, the paper reports that DenseNet-BC "only requires around 1/3 of the parameters of ResNets" to achieve comparable accuracy.[1]
DenseNet vs. VGG
VGG networks (VGG-16, VGG-19) were among the first architectures to demonstrate the benefit of depth, but they rely on large fully connected layers that result in enormous parameter counts.[9] VGG-16 has approximately 138 million parameters, while DenseNet-121 achieves comparable or better accuracy with just 7.98 million parameters, roughly 1/17th the size. The parameter efficiency of DenseNet comes from its narrow layers and extensive feature reuse, which eliminates the need for each layer to independently learn redundant feature representations.
Performance Results
ImageNet (ILSVRC 2012)
On the ImageNet Large Scale Visual Recognition Challenge 2012 validation set, DenseNet models achieved competitive results with far fewer parameters than comparably performing architectures.[1] All ImageNet results use DenseNet-BC configurations with θ = 0.5.
Among the variants in the original CVPR paper, DenseNet-264 (k=32) achieved the best result, with a 22.15% single-crop top-1 error and 6.12% top-5 error (20.80% and 5.29% with 10-crop testing).[1] The authors' later DenseNet-161 (k=48) reached 22.2% top-1, and in the memory-efficient technical report a 264-layer DenseNet with k=48 and a cosine learning rate schedule reached 20.26% single-crop top-1 error.[3][12]
CIFAR-10 and CIFAR-100
DenseNet achieved state-of-the-art results on the CIFAR-10 and CIFAR-100 benchmarks at the time of publication. Selected results (with data augmentation, denoted by "+"):[1]
| Model | Parameters | CIFAR-10+ Error (%) | CIFAR-100+ Error (%) |
|---|---|---|---|
| DenseNet (L=40, k=12) | 1.0M | 5.24 | 24.42 |
| DenseNet (L=100, k=12) | 7.0M | 4.10 | 20.20 |
| DenseNet (L=100, k=24) | 27.2M | 3.74 | 19.25 |
| DenseNet-BC (L=100, k=12) | 0.8M | 4.51 | 22.27 |
| DenseNet-BC (L=250, k=24) | 15.3M | 3.62 | 17.60 |
| DenseNet-BC (L=190, k=40) | 25.6M | 3.46 | 17.18 |
The DenseNet-BC (L=190, k=40) model achieved a 3.46% error rate on CIFAR-10 with augmentation, which was state-of-the-art at the time. On CIFAR-100, the same model achieved 17.18% error. Notably, the DenseNet-BC (L=100, k=12) model achieved a respectable 4.51% error on CIFAR-10 with only 0.8 million parameters.[1]
SVHN
DenseNet was also evaluated on the Street View House Numbers (SVHN) dataset, where it achieved competitive error rates.[1] With dropout, the basic DenseNet with L=100 and k=24 reached 1.59% error, surpassing the previous best result from wide ResNets, while the 250-layer DenseNet-BC did not improve further, which the authors attribute to SVHN being a relatively easy task.[1]
What are the advantages of DenseNet?
Feature Reuse
The most significant advantage of DenseNet is its ability to reuse features across the entire network. The authors conducted a feature reuse analysis by examining the average absolute weights of connections between layers. They found that layers within a dense block spread their weights across many earlier layers, confirming that features produced by early layers are directly used by later layers throughout the block.[1] This stands in contrast to ResNet, where later layers may not effectively utilize features from much earlier layers.
Improved Gradient Flow
Dense connections create multiple short paths from the loss function back to early layers. During backpropagation, gradients can flow directly from the loss to any layer through these short paths, which helps mitigate the vanishing gradient problem.[1] This property makes it possible to train very deep DenseNets (250+ layers) without the optimization difficulties that plagued earlier deep architectures.
Parameter Efficiency
Because each layer can access all preceding features, it does not need to re-learn redundant information. This means DenseNet layers can be narrow (small k), leading to far fewer parameters than architectures with wider layers. DenseNet-BC (L=100, k=12) achieves strong results on CIFAR with only 0.8 million parameters, while a comparable ResNet would require several times more.[1]
Implicit Deep Supervision
The authors noted that DenseNet performs a form of implicit deep supervision. Because every layer has direct access to the gradients from the loss function through the dense connections, each layer receives additional supervision. This is conceptually similar to deeply supervised networks, but without the need for explicit auxiliary classifiers.[1]
Regularization Effect
On smaller datasets, the authors observed that DenseNet's dense connectivity has a regularizing effect that reduces overfitting.[1] Despite having high capacity, DenseNet-BC models trained on CIFAR-10 and CIFAR-100 showed less overfitting compared to alternative architectures with similar parameter counts. The feature reuse mechanism effectively acts as a form of regularization by encouraging the network to use compact representations.
Why does DenseNet use so much memory during training?
While DenseNet is parameter-efficient, its naive implementation consumes significant GPU memory during training. The source of this problem is the concatenation operation: each layer must store intermediate feature maps for all preceding layers, and the batch normalization and convolution operations in standard deep learning frameworks (e.g., cuDNN) require contiguous memory allocations. In a naive implementation, the memory required to store feature maps grows quadratically with network depth.[3]
This memory bottleneck initially limited the practical depth of DenseNet models on single GPUs. Before the memory-efficient implementation, the authors report, only DenseNets of about 4 million parameters could be trained on a single GPU.[3]
Memory-Efficient Implementation
In 2017, Pleiss, Chen, Huang, Li, van der Maaten, and Weinberger published a companion paper titled "Memory-Efficient Implementation of DenseNets" that addressed this issue.[3] Their approach uses shared memory allocations across layers: rather than allocating new memory for each concatenation operation, all layers write their intermediate results (batch normalization and concatenation outputs) to a pre-allocated shared memory buffer. During the forward pass, subsequent layers overwrite the intermediate results of previous layers. During the backward pass, these values are recomputed as needed.
This strategy reduces the memory cost of storing feature maps from quadratic to linear in the number of layers, at the expense of a 15-20% increase in training time due to recomputation.[3] With this optimization, the authors report that networks with 14M parameters could now be trained on a single GPU (up from 4M previously), and a DenseNet-264 with 73 million parameters could be trained on a single workstation with 8 NVIDIA Tesla M40 GPUs.[3]
PyTorch's torchvision DenseNet constructors include a memory_efficient option that uses checkpointing to cut memory use at some cost in speed.[13]
What is DenseNet used for?
Medical Imaging
DenseNet has become one of the most widely adopted architectures in medical imaging, particularly for radiological analysis. Its popularity in the medical domain stems from several properties: strong performance with limited training data (common in medical settings), parameter efficiency that allows deployment on constrained hardware, and effective feature reuse that captures both low-level textures and high-level semantic patterns in medical images.
CheXNet (Rajpurkar et al., 2017) is one of the most prominent medical applications of DenseNet.[5] Built on a DenseNet-121 backbone, CheXNet was trained on the ChestX-ray14 dataset containing over 100,000 frontal-view chest X-ray images labeled with up to 14 thoracic pathologies, including pneumonia, cardiomegaly, and pleural effusion. CheXNet achieved an F1 score of 0.435 (95% CI 0.387, 0.481) on pneumonia detection, exceeding the average radiologist F1 score of 0.387 (95% CI 0.330, 0.442), and demonstrated the potential of DenseNet-based models for clinical decision support.[5]
The architecture has since been applied to numerous other medical imaging tasks, including:
- COVID-19 detection from chest X-rays, where DenseNet-121-based models achieved high classification accuracies in several studies
- Retinal disease classification from fundus photographs and optical coherence tomography (OCT) scans
- Skin lesion classification in dermatological imaging, with DenseNet-201 achieving strong results on datasets such as HAM10000 and ISIC 2019
- Histopathological image analysis for cancer detection
- Brain tumor segmentation from MRI scans
General Computer Vision
Beyond medical imaging, DenseNet has been used as a feature extractor backbone in object detection frameworks, image segmentation systems, and various transfer learning applications. DenseNet-121 pretrained on ImageNet is a common starting point for fine-tuning on domain-specific tasks.
Remote Sensing
DenseNet architectures have found applications in satellite and aerial image classification, land use mapping, and vegetation analysis, where the ability to capture multi-scale features through dense connections proves beneficial.
Influence on Later Architectures
DenseNet's dense connectivity pattern has influenced several subsequent network designs:
Dual Path Networks (DPN)
Dual Path Networks (Chen et al., 2017) combine the strengths of ResNet and DenseNet by using a dual-path architecture.[6] One path uses residual connections (addition) to reuse features, while the other uses dense connections (concatenation) to discover new features. DPN achieves better performance than either ResNet or DenseNet alone under comparable computational budgets.
Cross Stage Partial Networks (CSPNet)
CSPNet (Wang et al., 2020) modifies the dense block by partitioning the feature maps into two parts: one part passes through the dense block, while the other bypasses it.[7] This cross-stage partial design reduces computation by 10-20% compared to standard DenseNet while maintaining or improving accuracy. CSPNet was subsequently integrated into the YOLO family of object detectors (YOLOv4 and later).
HarDNet
Harmonic DenseNet (HarDNet) reduces the memory traffic overhead of DenseNet by using a harmonic connection pattern that limits which layers are connected. Rather than connecting every layer to every preceding layer, HarDNet only connects layers based on harmonic denseness, reducing memory access cost while retaining much of the benefit of dense connectivity.
VoVNet
VoVNet (Lee et al., 2019) introduced a "one-shot aggregation" approach inspired by DenseNet.[8] Instead of concatenating features from all preceding layers at every layer, VoVNet concatenates all intermediate features only once at the end of a module. This reduces the intermediate computation and memory overhead while preserving the benefits of multi-layer feature aggregation. VoVNet-based detectors were shown to outperform DenseNet-based ones with roughly 2x faster speed.
Implementation Availability
DenseNet is widely available in all major deep learning frameworks:
| Framework | Module/Function |
|---|---|
| PyTorch (torchvision) | torchvision.models.densenet121, densenet161, densenet169, densenet201 |
| TensorFlow/Keras | tf.keras.applications.DenseNet121, DenseNet169, DenseNet201 |
| MXNet/GluonCV | gluoncv.model_zoo.densenet121 |
| PaddlePaddle | paddle.vision.models.densenet121 |
The authors released code and pretrained models alongside the paper.[1] Pretrained weights on ImageNet are available for all standard DenseNet variants in these frameworks, making it straightforward to use DenseNet as a feature extractor or starting point for fine-tuning.
Limitations
Despite its strengths, DenseNet has several practical limitations:
-
Memory consumption: Even with memory-efficient implementations, DenseNet requires more memory during training than ResNet for comparable accuracy, because feature map concatenation inherently stores more intermediate data than additive skip connections.
-
Inference speed: The concatenation operations in DenseNet can be slower than the addition operations in ResNet on some hardware, particularly GPUs optimized for regular computation patterns. DenseNet's memory access patterns are less regular, which can reduce hardware utilization.
-
Complexity of hyperparameter tuning: DenseNet introduces additional hyperparameters (growth rate k, compression factor θ, number of layers per dense block) that require careful tuning for optimal performance.
-
Diminishing returns at scale: For very large-scale applications where model size is not a primary constraint, the parameter efficiency advantage of DenseNet becomes less important, and simpler architectures like ResNet or more modern designs like EfficientNet may be preferred.
These limitations help explain why, despite winning the CVPR 2017 Best Paper Award and demonstrating clear advantages in parameter efficiency, DenseNet has not replaced ResNet as the default backbone architecture in the broader computer vision community. ResNet's simpler design, lower memory footprint, and well-understood training dynamics have kept it as the more commonly used architecture for general-purpose tasks. However, DenseNet remains particularly popular in medical imaging and other domains where data efficiency and compact models are priorities.
Who created DenseNet and when was it published?
The DenseNet paper was authored by researchers from Cornell University, Tsinghua University, and Facebook AI Research (FAIR):[1]
- Gao Huang (Cornell University): Co-first author (equal contribution with Zhuang Liu).
- Zhuang Liu (Tsinghua University): Co-first author (equal contribution with Gao Huang).
- Laurens van der Maaten (Facebook AI Research): Co-author known for his earlier work on t-SNE visualization.
- Kilian Q. Weinberger (Cornell University): Senior author and advisor who guided the research direction.
The paper was first posted on arXiv on August 25, 2016 (arXiv:1608.06993), and the final version was presented at CVPR at the Hawaii Convention Center in Honolulu, Hawaii on July 21-26, 2017, where it received the Best Paper Award.[1] An extended journal version titled "Convolutional Networks with Dense Connectivity" (with Geoff Pleiss as an additional co-author) was accepted by IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI) and published in the journal in December 2022 (Volume 44, Issue 12, pp. 8704-8716).[2] The journal version added a section on memory-efficient implementation, a study of architecture hyperparameters, and an analysis of DenseNet variants.[2]
Mark Zuckerberg publicly highlighted the DenseNet paper in 2017 as an example of impactful AI research, noting the collaboration between Cornell and Facebook AI Research.
Continue reading
- ResNetResNet, short for residual network, is a family of deep convolutional neural networks introduced by Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun at CVPR 2016.Mentioned 30 times above
- VGGVGG (also called VGGNet) is a deep convolutional neural network architecture, introduced in 2014 by Karen Simonyan and Andrew Zisserman of the Visual Geometry Group at the University of OxfordMentioned 9 times above
- Computer VisionComputer vision is the study of computational methods that extract, estimate, or generate useful representations from visual measurements.Mentioned 3 times above
- Image classificationImage classification is the task of assigning a whole image to one category drawn from a fixed set of labels.Mentioned twice above
- Convolutional Neural NetworkA convolutional neural network (CNN, or ConvNet) is a neural network that uses convolution-like linear operators in at least some layers.Linked in the introduction
- Pattern RecognitionPattern recognition is the automatic discovery of regularities in data through the use of computer algorithmsLinked in the introduction
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28Huang, G., Liu, Z., Van Der Maaten, L., & Weinberger, K. Q. (2017). "Densely Connected Convolutional Networks." *Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR)*, pp. 4700-4708. arXiv:1608.06993. arxiv.org/...1608.06993
- ^1 ^2Huang, G., Liu, Z., Pleiss, G., Van Der Maaten, L., & Weinberger, K. Q. (2022). "Convolutional Networks with Dense Connectivity." *IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI)*, 44(12), pp. 8704-8716. arXiv:2001.02394. arxiv.org/...2001.02394
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Pleiss, G., Chen, D., Huang, G., Li, T., Van Der Maaten, L., & Weinberger, K. Q. (2017). "Memory-Efficient Implementation of DenseNets." arXiv:1707.06990. arxiv.org/...1707.06990
- ^He, K., Zhang, X., Ren, S., & Sun, J. (2016). "Deep Residual Learning for Image Recognition." *Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR)*, pp. 770-778.
- ^1 ^2Rajpurkar, P., Irvin, J., Zhu, K., Yang, B., Mehta, H., Duan, T., ... & Ng, A. Y. (2017). "CheXNet: Radiologist-Level Pneumonia Detection on Chest X-Rays with Deep Learning." arXiv:1711.05225. arxiv.org/...1711.05225
- ^Chen, Y., Li, J., Xiao, H., Jin, X., Yan, S., & Feng, J. (2017). "Dual Path Networks." *Advances in Neural Information Processing Systems (NeurIPS)*, pp. 4467-4475.
- ^Wang, C. Y., Liao, H. Y. M., Wu, Y. H., Chen, P. Y., Hsieh, J. W., & Yeh, I. H. (2020). "CSPNet: A New Backbone that can Enhance Learning Capability of CNN." *Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition Workshops (CVPRW)*.
- ^Lee, Y., Hwang, J., Lee, S., Bae, Y., & Park, J. (2019). "An Energy and GPU-Computation Efficient Backbone Network for Real-Time Object Detection." *Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition Workshops (CVPRW)*. arXiv:1904.09730.
- ^1 ^2Simonyan, K., & Zisserman, A. (2015). "Very Deep Convolutional Networks for Large-Scale Image Recognition." *Proceedings of the International Conference on Learning Representations (ICLR)*. arXiv:1409.1556.
- Irvin, J., Rajpurkar, P., Ko, M., Yu, Y., Ciurea-Ilcus, S., Chute, C., ... & Ng, A. Y. (2019). "CheXpert: A Large Chest Radiograph Dataset with Uncertainty Labels and Expert Comparison." *Proceedings of the AAAI Conference on Artificial Intelligence*, 33(01), pp. 590-597.
- ^He, K., Zhang, X., Ren, S., & Sun, J. (2016). "Identity Mappings in Deep Residual Networks." *European Conference on Computer Vision (ECCV)*. arXiv:1603.05027. arxiv.org/...1603.05027
- ^1 ^2 ^3 ^4 ^5Liu, Z., & Huang, G. "DenseNet: Densely Connected Convolutional Networks (code and pretrained models)." GitHub. github.com/...DenseNet
- ^1 ^2PyTorch. "torchvision.models.densenet." GitHub. github.com/...densenet.py
- ^He, K. "Deep Residual Networks (original ResNet-50/101/152 models)." GitHub. github.com/...deep-residual-networks
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
7 revisions · v7 · 4,492 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (110 claims, 14 sources fetched); 8 material + 11 minor fixed
Cite this page: AI Wiki. "DenseNet." aiwiki.ai, updated 23 Jun 2026, fact-checked 4 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/densenet