

Machine learning terms/Google Cloud
See also: Machine learning terms, Vertex AI, Cloud TPU, TPU, Google, Google Cloud
Google Cloud is the public cloud arm of Google and one of the three dominant providers of machine learning infrastructure, alongside Amazon Web Services and Microsoft Azure. Its machine learning portfolio is built around three layers: a managed ML and generative AI service called Vertex AI (renamed Gemini Enterprise Agent Platform in April 2026), a custom silicon family called the Tensor Processing Unit (TPU), and an integrated supercomputing fabric called AI Hypercomputer that ties accelerators, networking, storage, and software into a single offering. What distinguishes the platform is that it is the same stack Google DeepMind and Google's own product teams use to train and serve flagship models such as Gemini, Imagen, Veo, Lyria, Chirp, and AlphaFold. Vertex AI launched as a unified platform on May 18, 2021, and Google said at launch it required roughly 80% fewer lines of code to train a model than competing platforms [9]. The TPU underneath it has shipped seven public generations since the first chips went into Google data centers in 2015 [3][10], and in October 2025 Anthropic committed to up to one million Google Cloud TPUs and "well over a gigawatt of capacity" coming online in 2026 [11]; in April 2026 it signed a further agreement with Google and Broadcom for multiple gigawatts of next-generation TPU capacity expected to come online starting in 2027 [24].
This page is the gateway hub for Google Cloud machine learning entries on the AI Wiki. It introduces the major products, surveys the TPU generations and their pricing, compares the platform with AWS and Azure equivalents, and provides a curated index of every Google Cloud term with its own dedicated wiki page.
what is google cloud machine learning?
Google Cloud's ML offerings span the full lifecycle of artificial intelligence work: data ingestion, feature engineering, custom training, hyperparameter tuning, serving, monitoring, and the building of generative AI applications and agents. Customers can either use prebuilt APIs that wrap a single capability (vision, speech, translation, document parsing) or take full control through Vertex AI's notebooks, training jobs, pipelines, and inference endpoints. Most of the same accelerators that power Google's first-party products are exposed to enterprises through Vertex AI, the Google Kubernetes Engine (GKE), and the Compute Engine virtual machine surface.
The portfolio reached its current shape through a series of consolidations. In 2017 Google released Cloud ML Engine for managed TensorFlow training, then in 2018 added AutoML for no-code modeling. On May 18, 2021, at Google I/O, Google merged the two into a single managed service called Vertex AI, which it described as unifying its AutoML and Cloud AI Platform capabilities behind one API [9]. After the launch of Bard and Gemini, Vertex AI became the primary path for enterprise customers to consume frontier Google models alongside third-party models from Anthropic, Mistral AI, and Meta. At Google Cloud Next 2026, Google rebranded the surface as the Gemini Enterprise Agent Platform while continuing to ship the underlying Vertex AI services [1][2].
vertex ai
Vertex AI is the unified machine learning and generative AI platform offered by Google Cloud. It consolidates data labeling, AutoML training, custom training, hyperparameter tuning, pipelines, feature stores, model registries, online and batch prediction, model evaluation, and monitoring into a single API and console. Customers do not run the underlying training schedulers or inference endpoints themselves: they call Vertex AI services, and Google manages the queues, autoscalers, and accelerator fleets behind the scenes. At launch Google framed the design goal directly: "Vertex AI requires nearly 80% fewer lines of code to train a model versus competitive platforms, enabling data scientists and ML engineers across all levels of expertise the ability to implement Machine Learning Operations (MLOps)" [9].
The service has three broad surfaces:
| Surface | Purpose | Typical entry points |
|---|---|---|
| Predictive AI | Train and serve classical supervised learning models, regression, classification, forecasting, and ranking | AutoML, custom training jobs, hyperparameter tuning, feature store, batch prediction, online endpoints |
| Generative AI | Use foundation models and large language models for text, code, image, video, audio, and multimodal applications | Vertex AI Studio, Model Garden, tuning jobs, evaluation, RAG Engine, prompt management |
| Agentic AI | Build agents that call tools, retrieve documents, and reason in multi-step workflows | Vertex AI Agent Builder (now Gemini Enterprise Agent Platform), Agent Development Kit, Agent Engine (now Agent Runtime), Agent Starter Pack |
automl, custom training, and the model registry
AutoML is Vertex AI's no-code path. Users upload a labeled tabular, image, text, or video dataset and Vertex AI runs an architecture search and hyperparameter search to produce a deployable model. Custom training, in contrast, runs arbitrary container images on managed GPUs or TPUs. It supports TensorFlow, PyTorch, JAX, scikit-learn, and XGBoost out of the box, and integrates with Vertex AI Pipelines for orchestration. The model registry is a versioned catalog of trained artifacts that ties model lineage to deployments, evaluations, and tuning jobs.
model garden
Model Garden is Vertex AI's curated catalog of models. It exposes Google's first-party models (Gemini, Gemma, Imagen, Veo, Lyria, Chirp), third-party models (Anthropic's Claude family, Mistral models, Llama), and open models from Hugging Face. Each entry can be deployed to a Vertex AI endpoint, fine-tuned, or queried via the Vertex AI API, with billing and quotas handled by Google Cloud.
gemini api on vertex
The Gemini family of multimodal models is available on Google Cloud through two complementary surfaces: Google AI Studio for prototyping with personal accounts, and the Vertex AI Gemini API for production use with enterprise governance, regional endpoints, VPC Service Controls, and Customer-Managed Encryption Keys. Gemini has been available on Vertex AI since December 2023, and Vertex remains the default channel for enterprise deployments.
The table below summarizes the main Gemini variants available on Vertex AI in early 2026. Google has since retired Gemini 2.5 Pro and Gemini 2.5 Flash on the platform (on October 20, 2026) and added newer models, including Gemini 3.5 Flash (May 2026), Gemini 3.8 Flash (September 2026) and Gemini 4 Argon (October 2026) [21].
| Model | Context window | Strengths | Typical use |
|---|---|---|---|
| Gemini 3 Pro | 1,000,000 tokens | Most advanced reasoning, agentic workflows, code, multimodal | Complex enterprise reasoning, long-document analysis |
| Gemini 3 Flash | 1,000,000 tokens | Lower latency, lower cost, multimodal | High-throughput consumer and customer-support apps |
| Gemini 2.5 Pro | 1,000,000 tokens | Adaptive thinking, deep reasoning, code | Coding agents, RAG, structured extraction |
| Gemini 2.5 Flash | 1,000,000 tokens | Cheap, fast, capable enough for most tasks | Bulk inference, classification, summarization |
Vertex AI exposes Gemini through several inference modes, including standard online inference, provisioned throughput for predictable capacity, batch prediction for large offline jobs, and global endpoints that route requests to the nearest healthy region. The same models can also be tuned with supervised fine-tuning, reinforcement learning from human feedback, or distillation directly inside Vertex AI tuning jobs.
tensor processing unit (tpu)
The Tensor Processing Unit is Google's family of custom application-specific integrated circuits (ASICs) for deep learning workloads. TPUs are organized around a systolic array for matrix multiplication and use bfloat16 as their primary low-precision number format. The first TPU was deployed inside Google data centers in 2015 to serve voice search and was publicly disclosed by CEO Sundar Pichai at Google I/O on May 18, 2016, where he said the chips had been running in production for more than a year [10]. Google's 2017 paper reported the first-generation TPU delivering 15 to 30 times higher performance and 30 to 80 times higher performance per watt than contemporary CPUs and GPUs on inference [12]. Google has since shipped seven public generations, of which TPU v5e, TPU v5p, Trillium (TPU v6e), and Ironwood (TPU v7) are still actively sold through Cloud TPU [1][3]. In April 2026 Google announced an eighth generation split into two chips, TPU 8t for training and TPU 8i for inference, to reach cloud customers later [1].
when did each tpu generation ship?
The table below summarizes the main TPU generations on Google Cloud.
| Generation | Year | Focus | Peak performance per chip | HBM | Max pod size | Notable customers |
|---|---|---|---|---|---|---|
| TPU v1 | 2015 | Inference (8-bit integer) | 92 TOPS (INT8) | 8 GB DDR3 | Single chip in server | Google internal only |
| TPU v2 | 2017 | Training, bfloat16 | 45 TFLOPS (BF16) | 16 GB HBM | 256 chips per pod | Cloud TPU launch customers |
| TPU v3 | 2018 | Larger training | 123 TFLOPS (BF16) | 32 GB HBM | 1,024 chips per pod | Liquid-cooled |
| TPU v4 | 2021 | Optical reconfigurable pods | 275 TFLOPS (BF16) | 32 GB HBM | 4,096 chips per pod | Used to train PaLM and early Gemini |
| TPU v5e | 2023 | Cost-efficient training and inference | 197 TFLOPS (BF16) | 16 GB HBM | 256 chips per pod | Anthropic, Hugging Face, AssemblyAI |
| TPU v5p | 2023 | Highest training performance | 459 TFLOPS (BF16) | 95 GB HBM | 8,960 chips per pod | Salesforce, Lightricks [17] |
| Trillium (TPU v6e) | 2024 | High performance per dollar, third-gen SparseCore | 918 TFLOPS (BF16) | 32 GB HBM | 256 chips per pod | Used to train Gemini 2.0 |
| Ironwood (TPU v7) | 2025 | Inference-first | 4,614 TFLOPS (FP8) | 192 GB HBM3E | 9,216-chip superpods | Anthropic, Lightricks, Essential AI |
Trillium reached general availability in December 2024, providing a 4.7x increase in peak compute performance per chip over TPU v5e, double the HBM capacity and bandwidth, double the interchip interconnect bandwidth, three times the host DRAM, scaling to 256 chips per pod, and a 67% gain in energy efficiency [3]. Google reports Trillium delivering up to 2.1x better performance per dollar than TPU v5e and 2.5x better than TPU v5p when training dense LLMs such as Llama 2 70B and Llama 3.1 405B, and up to 4x faster training for those dense models than v5e [3]. Ironwood is the first TPU generation explicitly designed for inference, reflecting the industry shift toward serving rather than training-dominated compute. Each Ironwood chip delivers 4,614 teraFLOPS at FP8 precision and carries 192 GB of HBM3E with about 7.4 TB/s of bandwidth, and a full Ironwood superpod links 9,216 liquid-cooled chips through optical circuit switching to reach 42.5 exaFLOPS of FP8 performance and 1.77 PB of shared memory [13].
cloud tpu vocabulary
Cloud TPU exposes a specific vocabulary that maps physical hardware to logical resources. Each term has its own dedicated wiki page (linked in the index at the bottom of this article).
| Term | Meaning |
|---|---|
| TPU chip | A single ASIC with one or more TensorCores |
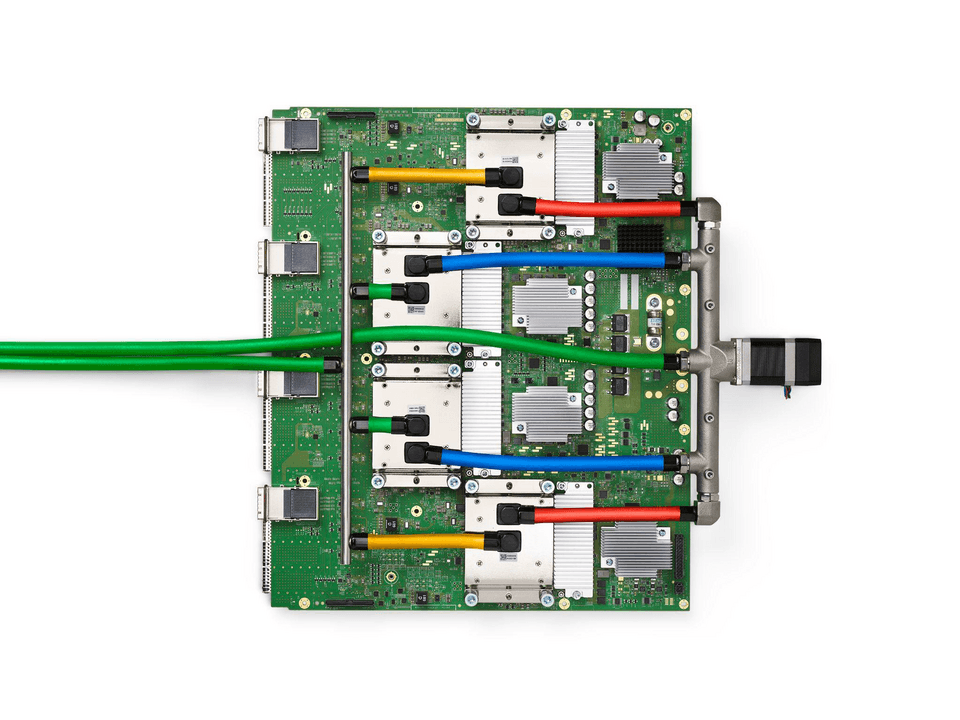
| TPU device | A printed circuit board with multiple TPU chips, high-bandwidth network interfaces, and cooling hardware |
| TPU node | A logical Cloud TPU resource exposed to a user, possibly spanning many chips |
| TPU slice | A subset of a TPU pod allocated to one job |
| TPU pod | The full set of interconnected chips in a single ICI fabric |
| TPU type | The hardware generation and topology requested at provisioning time |
| TPU master | The control plane host that drives a TPU job |
| TPU worker | A process that runs on a host machine and executes machine learning programs on TPU devices |
| TPU resource | A TPU entity on Google Cloud that you create, manage, or consume, such as a TPU node or TPU type |
cloud tpu pricing model
Cloud TPU pricing is published per chip-hour. Customers can buy time through three contract types: on-demand pricing, one-year and three-year committed use discounts (CUDs), and Spot/preemptible pricing for fault-tolerant workloads. Spot TPUs typically save more than 50% relative to on-demand and are widely used for long pretraining runs that checkpoint frequently. TPUs are billed for the entire slice (rather than per active chip), so the unit economics reward dense scheduling and efficient use of the Dynamic Workload Scheduler.
ai hypercomputer and gke for ai workloads
AI Hypercomputer is Google Cloud's branding for the integrated supercomputing system that combines compute (TPU and GPU), networking, storage, and software (orchestration, frameworks, libraries) into one offering. AI Hypercomputer underpins nearly every AI workload on Google Cloud and is the deployment fabric used by Google's own product teams as well as external research labs.
The major components are:
| Component | Role |
|---|---|
| Cloud TPU and GPU instances | Accelerator compute |
| Cluster Director | Cluster management and job scheduling for GPU and TPU pods |
| Dynamic Workload Scheduler | Queueing system that bin-packs accelerator demand to maximize utilization |
| Managed Lustre | High-throughput file system, multiple performance tiers, up to 8 PiB |
| GKE | Managed Kubernetes for AI workloads |
| GKE Inference Gateway | Prefix-aware load balancer for LLM inference workloads with recurring prompts |
| MaxText and MaxDiffusion | Reference JAX implementations of LLMs and diffusion models tuned for TPU pods |
| vLLM TPU | Port of vLLM inference engine to JAX and TPU |
Google Kubernetes Engine is the primary container surface for AI Hypercomputer. GKE supports both TPU and GPU node pools, exposes the Container Storage Interface (CSI) drivers needed for high-throughput data access, and provides specialized features such as the GKE Inference Gateway, prefix-aware autoscalers, and topology-aware scheduling. Customers running large-scale training or serving on GKE typically combine these features with Kueue for batch job queueing and the Dynamic Workload Scheduler for accelerator reservations.
bigquery ml
BigQuery ML (BQML) lets data analysts train and run machine learning models using only SQL inside Google's serverless data warehouse. The product was first released in 2018 and originally supported only linear regression and logistic regression. It has since expanded to cover k-means clustering, matrix factorization, time-series forecasting, boosted trees (powered by XGBoost), deep neural networks (powered by TensorFlow and Keras), and autoencoders.
BigQuery ML also exposes a REMOTE model type that calls Cloud AI APIs from inside SQL. The most common forms are:
| SQL function | Backing service | Use |
|---|---|---|
ML.GENERATE_TEXT | Vertex AI Gemini | Generate or transform text from BigQuery rows |
ML.GENERATE_EMBEDDING | Vertex AI text and multimodal embedding models | Vector embeddings for retrieval and clustering |
ML.PROCESS_DOCUMENT | Document AI | Parse PDFs and other structured documents |
ML.TRANSCRIBE | Speech-to-Text | Convert audio files into text |
ML.UNDERSTAND_TEXT | Cloud Natural Language API | Sentiment, entity, and syntax analysis |
ML.ANNOTATE_IMAGE | Vision API | Label detection, OCR, and face analysis |
ML.TRANSLATE | Cloud Translation | Translate text between languages |
Because BigQuery already governs the data, BQML is a popular path for analytics teams who want to add ML and generative AI to existing dashboards without writing Python code or managing GPUs.
prebuilt cloud ai apis
Google Cloud offers a set of focused, prebuilt APIs that wrap a single ML capability. These services existed before the Vertex AI consolidation and continue to evolve as both standalone products and as services callable from Vertex AI and BigQuery.
document ai
Document AI is a managed platform for parsing structured and unstructured documents. It exposes pretrained processors for common document types (invoices, receipts, contracts, IRS tax forms, identity documents, mortgage and lending packets) and a Custom Extractor that uses generative AI to extract structured data from arbitrary documents with little training data. Document AI integrates with Workflows, Eventarc, Cloud Functions, and BigQuery, and is a common building block for accounts payable automation, KYC pipelines, and contract review.
cloud translation
Cloud Translation, historically known as the Translation API, provides neural machine translation across more than 100 languages. The Basic (v2) tier exposes pretrained NMT for fast batch translation, while the Advanced (v3) tier adds custom AutoML translation models, glossaries for consistent terminology, batch document translation for PDFs, DOCX, and PPTX files, and Gemini-powered Adaptive Translation. Pricing is volume based: the first 500,000 characters per month are free, with additional usage at roughly $20 per million characters and $0.08 per page for document translation.
speech-to-text and text-to-speech
Speech-to-Text is the Chirp-powered transcription API. It supports more than 125 languages and variants, real-time streaming and asynchronous batch transcription, multi-speaker diarization, profanity filtering, and word-level timestamps. The latest models are based on Universal Speech Model (USM) and Chirp foundation models. The companion Text-to-Speech API uses WaveNet and Studio voices to generate natural-sounding speech.
vision api
The Vision API provides label detection, optical character recognition (OCR), face and landmark detection, logo recognition, explicit content detection, object localization, and product search through pretrained models. It can be called directly or through BigQuery's ML.ANNOTATE_IMAGE function. The first 1,000 units per month for most features are included in the free tier.
video intelligence
Video Intelligence API extends similar capabilities to video. It identifies shot changes, labels objects and scenes over time, transcribes speech, detects faces and text, recognizes logos and celebrities, and flags explicit or violent content. The first 1,000 minutes of video analysis per month are free, with per-minute pricing for additional usage rounded up to the next full minute.
natural language and discovery engine
The Cloud Natural Language API exposes sentiment analysis, entity recognition, syntactic parsing, and content classification. The Discovery Engine backs Vertex AI Search and Conversation by indexing structured and unstructured corpora with vector and lexical retrieval.
vertex ai search and conversation
Vertex AI Search and Conversation, originally launched as Generative App Builder (Gen App Builder) and later folded into Vertex AI Agent Builder, is the platform for building generative AI search experiences and chat agents on top of Google's enterprise search index. The service has three main pieces:
- Vertex AI Search for retrieval-augmented question answering across websites, BigQuery, Cloud Storage, Confluence, Jira, and other connected sources, with built-in citations and grounding.
- Vertex AI Conversation for building chatbots that can transact (for example, take payments, schedule appointments, or look up account information).
- Vertex AI Agent Builder for assembling agents that combine retrieval, tool use, and orchestration into multi-step workflows.
At Google Cloud Next 2026, Google rebranded Vertex AI as the Gemini Enterprise Agent Platform, renaming Vertex AI Search to Agent Search and Vertex AI Conversation to Agent Conversation and bringing Vertex AI Agent Builder's capabilities under the new platform [1][22]. (Agentspace had already been folded into the separate Gemini Enterprise app in October 2025 [23].) The platform exposes new capabilities such as Agent Studio (visual builder), Agent-to-Agent Orchestration, Agent Registry, Agent Identity, Agent Gateway, and Agent Observability [1].
alphafold via vertex
AlphaFold is the Google DeepMind protein-structure-prediction system that won the CASP 14 competition in 2020, where AlphaFold 2 achieved a median score of 92.4 on the global distance test (GDT) across all targets; CASP co-founder John Moult has said a score of around 90 GDT is informally considered competitive with experimental methods, and DeepMind described the result as a solution to the 50-year-old protein folding problem [14]. Google Cloud exposes AlphaFold to enterprises in two ways: as a hosted Vertex AI Pipelines workflow that runs end-to-end inference on managed accelerators, and through a user-friendly AlphaFold Portal on Vertex AI that lets researchers submit amino-acid sequences without writing Python or managing notebooks. The pipeline takes a sequence, performs multiple-sequence-alignment and feature-engineering steps, runs the neural network inference on GPUs, and produces predicted 3D structures. The biotech company Nuclera has partnered with Google Cloud to serve AlphaFold2 on Vertex AI alongside its protein-expression system [18].
comparison with aws and azure
Google Cloud, Amazon Web Services, and Microsoft Azure are the three dominant enterprise machine learning clouds. Each platform exposes a managed end-to-end ML service plus a generative AI front door. The table below summarizes the main analogues.
| Capability | Google Cloud | AWS | Azure |
|---|---|---|---|
| Managed ML platform | Vertex AI | Amazon SageMaker AI | Azure Machine Learning |
| Foundation-model marketplace | Vertex AI Model Garden | Amazon Bedrock | Microsoft Foundry Models (formerly Azure AI Foundry) [19] |
| First-party model family | Gemini, Imagen, Veo, Lyria, Chirp, Gemma | Amazon Nova, Titan | Phi family, plus deep OpenAI integration via Azure OpenAI |
| Custom AI accelerator | TPU | Trainium, Inferentia | Maia 100, Maia 200 [20] |
| GPU partner | NVIDIA (H100, B200), AMD | NVIDIA, AMD | NVIDIA, AMD |
| Generative app surface | Vertex AI Search and Conversation, Gemini Enterprise Agent Platform | Amazon Q, Bedrock Agents | Foundry Agent Service, Copilot Studio |
| Data warehouse with ML | BigQuery ML | Amazon SageMaker Lakehouse, Redshift ML | Microsoft Fabric, Synapse Analytics |
| Vector database | Vertex AI Vector Search, AlloyDB for pgvector | OpenSearch Serverless, Aurora pgvector | Azure AI Search |
The three platforms differ less in scope than in default model partner. Google ships its own frontier family on Vertex; AWS leans on Anthropic, Meta, and Mistral inside Bedrock; and Azure is the privileged channel for OpenAI's GPT-5 and o-series models through Azure OpenAI and Microsoft Foundry (formerly Azure AI Foundry) [19]. Industry coverage in 2025 and 2026 generally credits SageMaker with the strongest MLOps tooling and instance variety, Azure AI Foundry with the deepest enterprise productivity integrations, and Vertex AI with the cleanest first-party generative model integration and Vertex AI with the cleanest first-party generative model integration, backed by Google's own TPU training silicon [5][6].
tpu vs gpu trade-offs
A recurring question for ML teams adopting Google Cloud is whether to train on Google's TPU or to keep using NVIDIA GPUs. Both are available on Vertex AI and GKE. The main trade-offs follow.
where do tpus win?
- Tensor-heavy workloads at scale. TPUs are purpose-built around a systolic array for matrix multiplication. Standard transformer training and inference fit this shape almost perfectly.
- Performance per dollar at large batch sizes. Trillium delivers up to 2.1x better performance per dollar than TPU v5e and up to 2.5x better than TPU v5p on dense LLM training [3]. Introl, an AI infrastructure services firm, has written that TPU v6e offers up to 4x better performance per dollar than NVIDIA H100 GPUs for specific workloads [7].
- Energy efficiency. Google reports Trillium is 67% more energy efficient than TPU v5e, and that Ironwood is roughly 30x more power efficient than the first Cloud TPU (v2) on a performance-per-watt basis [3][13].
- Inference at very large scale. Ironwood is the first TPU built primarily for inference. Customers such as Anthropic and Lightricks have publicly cited TPU inference economics as a reason to adopt Cloud TPU. Third-party analyses report that Midjourney cut its inference costs by about 65% after moving from GPUs to TPUs, with one putting monthly compute spending at $2 million before and $700,000 after [7][15].
where do gpus win?
- Software ecosystem. CUDA, cuDNN, and the broader NVIDIA stack remain the default in academic and open-source code. Most third-party libraries are tested first on NVIDIA hardware.
- Workload diversity. GPUs handle non-tensor workloads (graph algorithms, scientific computing, reinforcement learning environments, diffusion model sampling at low batch sizes) more flexibly than TPUs.
- Mixed framework usage. Teams that need to switch between PyTorch, JAX, and TensorFlow often find GPU drivers more uniform than TPU runtimes, where peak performance still requires JAX or PyTorch/XLA tuning.
- Single-node debugging. Single-GPU developer machines and modest 2 to 8 GPU nodes are easier to provision and iterate on than minimum-size TPU slices.
Many Google Cloud customers run a hybrid: large-scale pretraining and high-throughput inference on Cloud TPU pods, exploration and short fine-tuning runs on NVIDIA GPUs, and edge deployment on Edge TPU or NVIDIA Jetson devices.
notable customers and case studies
Google's own running list of customer generative AI deployments had grown to 1,302 use cases by April 2026 [8]. The most prominent commitments are Anthropic's: in October 2025 it agreed to expand to up to one million Google Cloud TPUs and more than a gigawatt of capacity coming online in 2026, an expansion it said was worth tens of billions of dollars [11], and in April 2026 it signed a further agreement with Google and Broadcom for multiple gigawatts of next-generation TPU capacity starting in 2027 [24]. A non-exhaustive list of widely cited deployments follows.
| Customer | Industry | Use of Google Cloud ML |
|---|---|---|
| Anthropic | AI research | Trains and serves Claude on Cloud TPU at very large scale; ~1M TPUs, >1 GW in 2026 [11] |
| Salesforce | Enterprise SaaS | Native Gemini support in its Atlas Reasoning Engine for Agentforce [8] |
| Etsy | E-commerce | Personalization for ~90 million shoppers via Vertex AI, BigQuery, Dataflow, Gemini; Gemini alt text lifted SEO visits 5% and conversions 3% [16] |
| BMW Group | Manufacturing | SORDI.ai 3D digital twins built on Vertex AI |
| Harvey | Legal AI | Gemini 2.5 Pro on Vertex AI for long-document legal review |
| Domina | Logistics | Predicts package returns across 20 million annual shipments |
| Amdocs | Telecom software | Telco Customer Experience Agent on Gemini Enterprise |
| Huge | Business services | AI agents for market research and contract analysis |
| Lightricks | Creative apps | Inference workloads on Ironwood TPU |
| Essential AI | Foundation models | Training on Ironwood TPU |
| Nuclera | Biotech | Runs AlphaFold inference on Vertex AI [18] |
| Mercedes-Benz | Automotive | Gemini via Vertex AI powers the MBUX Virtual Assistant [8] |
| Wendy's | QSR | Drive-thru voice ordering on Vertex AI and Google speech |
| Uber | Mobility | AI agents that summarize user communications for customer-service staff [8] |
Google's own products are large internal users too: Google says TPUs have long been the basis for training and serving AI-powered products such as YouTube, Gmail, Google Maps, Google Play, and Android [17].
index of google cloud term wiki pages
See also: Machine learning terms
-
Cloud TPU
-
Tensor Processing Unit (TPU)
-
TPU
Continue reading
- Tensor Processing Unit (TPU)A Tensor Processing Unit (TPU) is a family of custom application-specific integrated circuits developed by Google to accelerate machine-learning computation.Mentioned 102 times above
- GoogleGoogle LLC is a United States technology company and the largest operating business within Alphabet Inc. Its activities include internet search, online advertising, video, mobile and web platforms, consumer…Mentioned 68 times above
- Google Vertex AIGoogle Vertex AI is the unified machine learning and generative artificial intelligence platform offered by Google Cloud, announced at Google I/O on May 18Mentioned 55 times above
- Gemini (language model)Gemini is a family of natively multimodal large language models developed by Google DeepMind, first announced on December 6, 2023, that can reason across text, images, audio, video, and code within a single…Mentioned 35 times above
- Google CloudGoogle Cloud is the enterprise cloud business of Google and the name of a reportable segment in Alphabet's financial statements.Mentioned 25 times above
- Cloud TPUCloud TPU is Google Cloud's offering of Tensor Processing Units (TPUs), the family of custom application-specific integrated circuits (ASICs) that Google builds to accelerate machine learning training and…Mentioned 15 times above
More to read
references
- ^1 ^2 ^3 ^4 ^5Google Cloud Blog, "Welcome to Google Cloud Next 26," 2026, cloud.google.com/...welcome-to-google-cloud-next26.
- ^Google Cloud, "Gemini Enterprise Agent Platform (formerly Vertex AI)," 2026, cloud.google.com/...gemini-enterprise-agent-platform.
- ^1 ^2 ^3 ^4 ^5 ^6Google Cloud Blog, "Trillium TPU is GA," December 12, 2024, cloud.google.com/...trillium-tpu-is-ga.
- Google Cloud Blog, "AlphaFold Portal on Vertex AI," cloud.google.com/...i-alphafold-inference-pipeline.
- ^Index.dev, "Vertex AI vs AWS Bedrock vs Azure AI Foundry: Features, Pricing in 2026," 2026, index.dev/...ai-aws-bedrock-vs-azure-ai-vs-vertex.
- ^AWS in Plain English, "AWS Bedrock/SageMaker vs Azure AI Foundry vs Google Vertex AI: The Ultimate Cloud AI Platform (2026 Edition)," 2026, aws.plainenglish.io/...-platform-2026-03bbbab919b2.
- ^1 ^2Introl Blog, "TPU v6e vs GPU: 4x Better AI Performance Per Dollar," introl.com/...tter-ai-performance-per-dollar-guide.
- ^1 ^2 ^3 ^4Google Cloud Blog, "Real-world gen AI use cases from the world's leading organizations," cloud.google.com/...se-cases-from-industry-leaders.
- ^1 ^2 ^3Google Cloud, "Google Cloud Launches Vertex AI, Making Machine Learning More Accessible and Useful For Developers and Businesses," May 18, 2021, googlecloudpresscorner.com/...opers-and-Businesses.
- ^1 ^2Google Cloud Blog, "Google supercharges machine learning tasks with TPU custom chip," May 18, 2016, cloud.google.com/...earning-tasks-with-custom-chip.
- ^1 ^2 ^3Anthropic, "Expanding our use of Google Cloud TPUs and Services," October 2025, anthropic.com/...of-google-cloud-tpus-and-services.
- ^Norman P. Jouppi et al., "In-Datacenter Performance Analysis of a Tensor Processing Unit," ISCA 2017, arxiv.org/...1704.04760.
- ^1 ^2Google Cloud Blog, "Inside the Ironwood TPU codesigned AI stack," 2025, cloud.google.com/...onwood-tpu-codesigned-ai-stack.
- ^DeepMind, "AlphaFold: a solution to a 50-year-old grand challenge in biology," November 30, 2020, deepmind.google/...-old-grand-challenge-in-biology.
- ^FourWeekMBA, "Why Midjourney's 65% Cost Cut Reveals AI's Hardware Future," 2025, fourweekmba.com/...cut-reveals-ais-hardware-future.
- ^Google Cloud, "Etsy case study," cloud.google.com/...etsy-ai.
- ^1 ^2Google Cloud Blog, "Enabling next-generation AI workloads: Announcing TPU v5p and AI Hypercomputer," December 7, 2023, cloud.google.com/...d-tpu-v5p-and-ai-hypercomputer.
- ^1 ^2Google Cloud Blog, "Nuclera aims to accelerate drug discovery with Google DeepMind AlphaFold2 on Vertex AI," December 19, 2023, cloud.google.com/...a-runs-alphafold2-on-vertex-ai.
- ^1 ^2Microsoft Learn, "What is Microsoft Foundry?," 2026, learn.microsoft.com/...what-is-azure-ai-foundry.
- ^Microsoft, "Maia 200: The AI accelerator built for inference," January 26, 2026, blogs.microsoft.com/...lerator-built-for-inference.
- ^Google Cloud, "Model versions and lifecycle," Gemini Enterprise Agent Platform documentation, accessed November 2026, cloud.google.com/...model-versions.
- ^Google Cloud, "Gemini Enterprise Agent Platform name changes," documentation, accessed November 2026, docs.cloud.google.com/...vertex-ai-name-changes.
- ^The Register, "Google folds Agentspace into Gemini Enterprise," October 9, 2025, theregister.com/...arranges_agentspace_into_gemini.
- ^1 ^2Anthropic, "Anthropic expands partnership with Google and Broadcom for multiple gigawatts of next-generation compute," April 6, 2026, anthropic.com/...google-broadcom-partnership-compute.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
6 revisions · v6 · 4,794 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (150 claims, 31 sources fetched); 6 material + 36 minor fixed
Cite this page: AI Wiki. "Machine learning terms/Google Cloud." aiwiki.ai, updated 21 Jun 2026, fact-checked 4 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/machine_learning_terms_google_cloud