

TPU v5p
TPU v5p (Cloud TPU v5p) is Google's fifth-generation, performance-tier Tensor Processing Unit, a custom AI accelerator that delivers 459 bfloat16 TFLOPS per chip and scales to pods of 8,960 chips (about 4.1 exaFLOPS of BF16 compute) for training frontier-class large language models. Announced on December 6, 2023 alongside the launch of the Gemini family of foundation models and offered through Google Cloud, the v5p was positioned as Google's "most powerful, scalable, and flexible AI accelerator thus far," targeting the training of frontier large language models, mixture-of-experts systems, and dense embedding workloads.[1][2] The "p" suffix denotes the performance variant of the fifth generation, complementing the earlier efficiency-tier TPU v5e introduced in August 2023.
Each TPU v5p chip delivers a peak throughput of 459 TFLOPS in bfloat16 and 918 TFLOPS (also reported as TOPS) at INT8 precision, paired with 95 GB of HBM2e high-bandwidth memory at roughly 2.76 TB/s.[1][3][4][20] A full v5p "pod" connects 8,960 chips through a reconfigurable 3D-torus inter-chip interconnect at 4,800 Gbps per chip, representing more than double the FLOPS per chip, triple the HBM capacity, and roughly four times the per-pod scale of its predecessor, the TPU v4.[1][2] Google has stated that the chip can train large LLMs up to 2.8 times faster than v4 and embedding-dense models up to 1.9 times faster owing to its second-generation SparseCores.[1][2]
Cloud TPU v5p entered limited "early access" in December 2023 and reached general availability at Google Cloud Next on April 9, 2024.[5][6] Google later trained its Gemini 2.5 model family on v5p pods,[39] and external v5p users included Apple (for the on-device tier of Apple Foundation Models), Salesforce and Lightricks, while Anthropic and Hugging Face became major Google Cloud TPU partners.[1][7][8][9] In May 2024, Google previewed its successor, the sixth-generation TPU code-named Trillium (TPU v6e), and in April 2025 unveiled the seventh generation, Ironwood (generally available from late 2025), followed in April 2026 by an eighth generation split into the TPU 8t and TPU 8i, positioning v5p as a transitional but enormously influential platform in the modern AI-accelerator landscape.[10][11][37]
What are the TPU v5p's key specifications?
The following table summarizes the TPU v5p's verified specifications as documented by Google Cloud and its launch materials.[1][3][4]
| Specification | TPU v5p |
|---|---|
| Announced | December 6, 2023 |
| General availability | April 9, 2024 (Google Cloud Next) |
| Peak compute per chip (BF16) | 459 TFLOPS |
| Peak compute per chip (INT8) | 918 TOPS |
| HBM capacity per chip | 95 GB HBM2e[20] |
| HBM bandwidth per chip | 2,765 GB/s (2.76 TB/s) |
| ICI bandwidth per chip | 4,800 Gbps (1,200 GB/s bidirectional) |
| Chips per pod | 8,960 |
| Peak BF16 compute per pod | approximately 4.1 exaFLOPS |
| Max single-slice topology | 6,144 chips (16×16×24) |
| Max Multislice job | 18,432 chips |
| Host VM | 4 chips (ct5p-hightpu-4t), 208 vCPUs, 448 GB RAM |
| Matrix unit | 128×128 systolic-array MXU (8 per chip across 2 TensorCores) |
| SparseCores | 4 (second generation) |
| On-demand list price | $4.20 per chip-hour[28] |
Background
TPU lineage
The TPU program was started inside Google around 2013 to address the explosive compute demand of deep-learning workloads such as Google Brain-derived voice and translation systems. The first-generation TPU, deployed in 2015 and publicly disclosed in 2016, was an inference-only ASIC; subsequent generations added training capability and high-bandwidth memory.[12] The architecture is anchored by a systolic-array matrix multiply unit (MXU), originally 128×128 multiply-accumulators in the v2/v3/v4/v5 generations, surrounded by vector and scalar units within "TensorCores."[4][12]
By the early 2020s the lineage looked roughly:
| Generation | Year | Role |
|---|---|---|
| TPU v1 | 2015-16 | Inference (8-bit) |
| TPU v2 | 2017 | First-gen training |
| TPU v3 | 2018 | Liquid-cooled training |
| TPU v4 | 2021 (public 2022) | First optical-switched pods, 4,096 chips |
| TPU v5e | Aug 2023 | Cost-efficient inference/training |
| TPU v5p | Dec 2023 | Performance-tier training |
| Trillium (TPU v6e) | 2024 | 4.7× per-chip compute over v5e |
| Ironwood (TPU v7) | 2025 | Inference-era flagship |
| TPU 8t / TPU 8i | 2026 | Separate training and inference chips |
TPU v4 introduced Google's now-signature use of optical circuit switches (OCS) to dynamically reconfigure 3D-torus inter-chip topologies, an innovation that v5p inherited and scaled.[13][14]
Two flavors of v5
Google's fifth generation diverged into two SKUs serving different market segments:
- TPU v5e: announced in August 2023 and generally available from November 2023, optimized for inference and cost-sensitive training. Each chip pairs ~197 BF16 TFLOPS (393 INT8) with 16 GB of HBM and pods of up to 256 chips.[4][15]
- TPU v5p: announced December 6, 2023, the performance variant for large-scale frontier training. Each chip more than doubles v5e's compute, carries roughly six times its HBM capacity, and scales to pods of 8,960 chips.[1][4]
Later generations varied the approach: Trillium was marketed only as the v6e, Ironwood shipped as a single design, and the 2026 eighth generation split into the TPU 8t for training and the TPU 8i for inference.[11][37]
Announcement context
The v5p was unveiled in a joint announcement on December 6, 2023, alongside the launch of Gemini 1.0 (Ultra, Pro, and Nano) and the broader AI Hypercomputer architecture from Google Cloud, a phrase Google used to describe its integrated stack of accelerators, networking, software, and consumption models.[1][2][16] In the post announcing the chip, Amin Vahdat, VP/GM of Machine Learning, Systems, and Cloud AI at Google, wrote that Cloud TPU v5p is "our most powerful, scalable, and flexible AI accelerator thus far" and that "Gemini, Google's most capable and general AI model announced today, was trained on, and is served, using TPUs."[1] Google's Gemini launch post said the newly announced v5p "will accelerate Gemini's development."[40]
How is the TPU v5p architected?
Chip overview
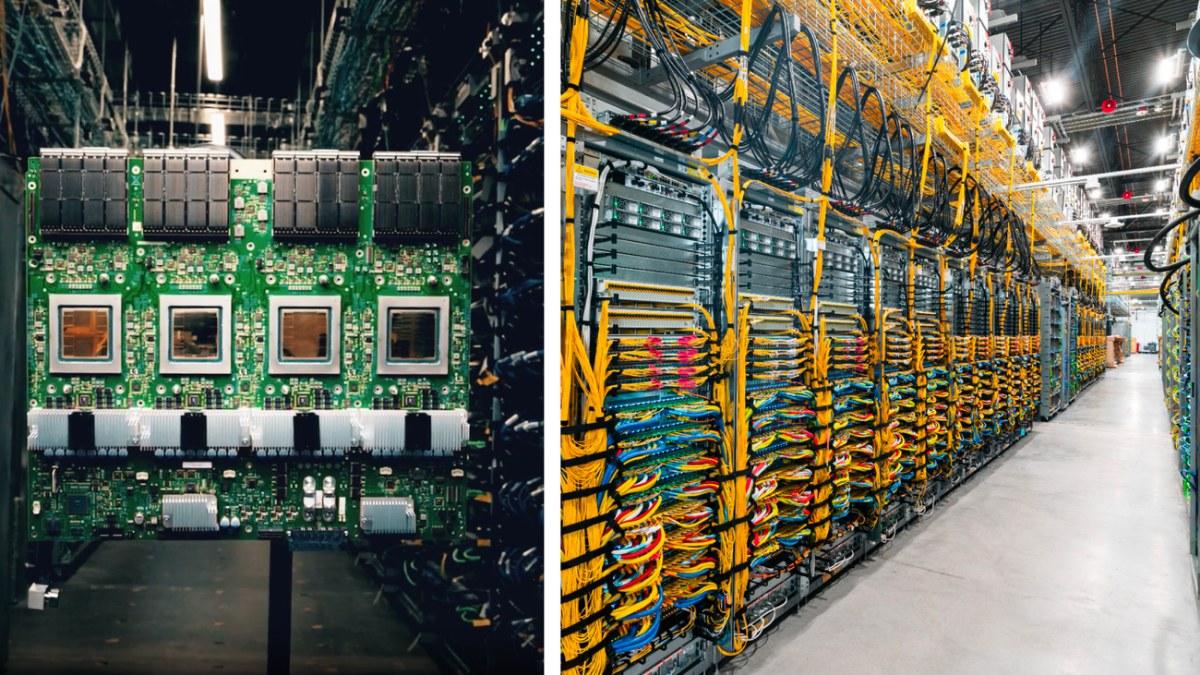
A TPU v5p chip is a custom Google-designed ASIC built around two TensorCores, each of which contains four 128×128 Matrix Multiply Units (MXUs) implemented as systolic arrays, a vector unit, and a scalar unit.[4][17] Across the two TensorCores, the chip therefore carries eight MXUs in total, twice the per-chip MXU count of TPU v5e, which uses a single TensorCore. The v5p preserves the 128×128 MXU dimension established with v2 (Trillium would later expand the MXU to 256×256).[17]
The reported peak per-chip throughput is 459 TFLOPS in bfloat16 and 918 TFLOPS/TOPS at INT8.[1][3][4] The clock speed has been documented at approximately 1,750 MHz.[4] Google has not publicly disclosed the process node, transistor count, or die area for the v5p chip; Wikipedia's TPU table lists these fields as undisclosed.[4]
SparseCores (second generation)
Each v5p chip integrates four second-generation SparseCores, small dataflow processors specialized for embedding and sparse-tensor operations, particularly important for recommendation systems and embedding-dense workloads.[17] Google has described SparseCores as occupying roughly 5% of chip die area and power while delivering 5-7× speedups on the operations they target versus equivalent code on the MXU or vector unit.[17] The second-generation SparseCores in v5p underpin Google's claim that v5p trains embedding-dense models 1.9× faster than v4.[1][2]
Host VM and node
A v5p TPU node exposes four chips per host (machine type ct5p-hightpu-4t), pairing them with 208 vCPUs (104 usable per NUMA node), 448 GB of host RAM, two NUMA nodes, and a 200 Gbps host NIC for data-center networking.[3] Each chip is connected to the host through PCIe and to its neighbors over the dedicated inter-chip interconnect, with 50 Gbps per chip reserved for data-center-network (DCN) traffic that crosses pod boundaries.[3]
How much memory and interconnect bandwidth does the TPU v5p have?
HBM2e
Each v5p chip carries 95 GB of HBM2e memory at approximately 2,765 GB/s of bandwidth (2.76 TB/s).[3][4][20] This is three times the HBM capacity of the 32 GB present on TPU v4 chips and represents a nearly 2.3× increase in HBM bandwidth.[1][4] In real-world workloads, Lightricks reported that the "ample memory capacity" of v5p allowed it to fit an entire generative text-to-video model on a single chip without splitting across processes, materially accelerating each training cycle.[1]
ICI bandwidth and topology
Inter-chip interconnect (ICI) is Google's high-bandwidth, low-latency proprietary fabric that wires TPU chips into 3D-torus configurations. On v5p, the ICI delivers 4,800 Gbps per chip (cited as 1,200 GBps bidirectional in Google's documentation), Google's highest per-chip ICI bandwidth in the v4/v5 era.[1][3] Each chip is connected to its six nearest neighbors, forming a 3D torus.[3][4]
Optical circuit switching
Following the precedent set by TPU v4, the v5p pod uses Optical Circuit Switches (OCS) to dynamically wire chips into reconfigurable 3D-torus topologies. A full v5p pod arranges its 8,960 chips as a 16×20×28 3D torus.[20] Published analyses of Google's OCS fabric describe 48 OCS units in the 4,096-chip TPU v4 pod and 48 OCS units with 13,824 optical ports in the 9,216-chip Ironwood pod, with the switches allowing traffic to be routed around failures.[14][18]
How large is a TPU v5p pod?
A full TPU v5p pod comprises 8,960 chips, making it 2.19× the size of a 4,096-chip TPU v4 pod and providing roughly 4× the per-pod aggregate FLOPS of v4 when accounting for the doubled per-chip throughput.[1][2] At pod scale, a full v5p pod delivers approximately 4.1 exaFLOPS of BF16 compute (8,960 x 459 TFLOPS).[20]
Topologies and slices
The maximum single-slice schedulable job (i.e., a topology connected fully via ICI without DCN hops) is 6,144 chips in a 16×16×24 configuration (96 "cubes," where a cube is a 4×4×4 sub-volume).[3][4][20] Larger workloads can be assembled via Google's Multislice software, which links multiple ICI-coupled slices over DCN; Multislice scales v5p workloads to 18,432 chips.[3] OCS-based topology wrapping means even sub-pod slices receive full toroidal connectivity once they reach cube size.[3]
Single-slice topology examples documented by Google include sizes from 2×2×1 (4 chips) up to 16×16×24 (6,144 chips), with intermediate shapes such as 8×8×8 (512 chips) and 16×16×16 (4,096 chips).[3]
What software supports the TPU v5p?
The v5p is supported across Google's open-source and proprietary AI software stack, including:
- JAX: Google's preferred high-performance training framework for TPUs, used by both DeepMind and external customers. Salesforce cited the "seamless and easy transition from Cloud TPU v4 to v5p using JAX."[1]
- PyTorch/XLA: PyTorch workloads execute on TPUs via the XLA (Accelerated Linear Algebra) compiler, which lowers high-level graph IR onto TPU primitives.[1][16]
- TensorFlow: supported via XLA as well.[1]
- Pathways: Google's distributed-systems runtime for coordinating model execution across very large numbers of accelerators, providing a "single Python client" abstraction for multi-pod workloads, megascale-XLA compilation services, and remote-Python execution.[21]
- MaxText: Google's open-source reference implementation of high-performance LLM training pipelines on TPUs and GPUs; v5p MLPerf submissions and customer references regularly use MaxText.[22]
- AXLearn: Apple's JAX-based deep-learning library, used in production to pre-train the Apple Foundation Models on Cloud TPU v4 and v5p clusters.[7][23]
- Multislice training and multi-host inferencing software: Google's first-party tools for scaling jobs beyond a single ICI domain via DCN-coupled slices.[21][16]
- Google Kubernetes Engine (GKE): added native support for v5p (including multi-host serving) when v5p reached GA in April 2024.[6]
The compiler underpinning the stack is the open-source XLA compiler, which lowers JAX, PyTorch, and TensorFlow programs to TPU kernels.[16]
How fast is the TPU v5p?
Headline claims
Google's launch positioning compared v5p to v4 with the following claims:
- >2× the FLOPS per chip vs. v4 (459 BF16 TFLOPS vs. 275 BF16 TFLOPS).[1][2][4]
- 3× more HBM per chip (95 GB vs. 32 GB).[1][4]
- 4× more FLOPS per pod when accounting for the larger 8,960-chip pod versus v4's 4,096.[1]
- 2.8× faster training of large LLMs (e.g., a GPT-3 175B-class workload) vs. v4.[1][2]
- 1.9× faster training of embedding-dense models, driven by the second-generation SparseCores.[1][2]
- ~2.1× better performance per dollar vs. v4 on GPT-3 175B training in Google's launch chart; the 2.3× figure repeated in some coverage was Google's claim for v5e.[1][16][19]
Jeff Dean, then chief scientist of Google DeepMind and Google Research, said at launch that "Google DeepMind and Google Research have observed 2× speedups for LLM training workloads using TPU v5p chips compared to the performance on our TPU v4 generation. ... With the 2nd generation of SparseCores we also see significant improvement in the performance of embeddings-heavy workloads."[1]
MLPerf 4.0 / 4.1
In MLCommons' MLPerf Training v4.0 (June 2024), Google submitted v5p results showing near-linear scaling (≈99.9% efficiency) on the GPT-3 175B pre-training task across slices ranging from 512 to 6,144 chips, the result of hardware/runtime/compiler/framework co-design.[25]
In MLPerf Training v4.1 (November 2024), Google submitted GPT-3 175B results for three v5p configurations alongside its first Trillium results. The same round disclosed that Trillium reduced training cost by up to 1.8× (45% lower) versus v5p while achieving the same validation accuracy. Convergence-scaling efficiency at the largest cluster sizes was reported to be comparable between Trillium and v5p.[22]
Real-world Gemini training
Google said it trained Gemini 1.0 on TPU v4 and v5e rather than v5p; its Gemini launch post said the newly announced v5p "will accelerate Gemini's development."[40] The Gemini 2.5 technical report later described that model family as "the first to be trained on TPUv5p architecture," using multiple 8,960-chip v5p pods across several data centers.[39]
Real-world customer benchmarks
- Salesforce: Erik Nijkamp, senior research scientist, said: "Cloud TPU v5p compute outperforms the previous generation TPU v4 by as much as 2× ... we love how seamless and easy the transition has been from Cloud TPU v4 to v5p using JAX."[1]
- Lightricks: Yoav HaCohen, PhD, core generative-AI research team lead, reported "remarkable performance and ample memory capacity," training a generative text-to-video model without splitting it into separate processes.[1]
- Apple: pre-trained the on-device Apple Foundation Model on a single slice of 2,048 v5p chips (see § Customers); the approximately 52% MFU Apple reported was for its AFM-server run on TPU v4.[23]
How much does the TPU v5p cost, and when was it released?
Public list pricing
When v5p reached general availability in April 2024, Google published list pricing of $4.20 per chip-hour for on-demand v5p capacity in supported zones, up from $3.22/chip-hour for v4 and $1.20/chip-hour for v5e.[28] One- and three-year committed-use discounts brought effective list rates down to approximately $2.94 and $1.89 per chip-hour respectively.[28][24]
General availability
v5p was first made available on December 6, 2023 through a private "request via your Google Cloud account manager" allocation process timed to the Gemini 1.0 launch.[2] General availability was announced at Google Cloud Next 2024 in early April 2024, when Google also disclosed GKE-native v5p support and multi-host inferencing.[6][29]
Regional availability
As of November 2026, Google's TPU pricing page listed v5p in us-east5 (Columbus, Ohio) and us-east1 (South Carolina).[28]
Who uses the TPU v5p?
Google internal: Gemini family
The earliest and largest tenant of v5p capacity was Google itself, which used the chip to train its Gemini family of frontier models. Google stated at launch that "Gemini, Google's most capable and general AI model announced today, was trained on, and is served, using TPUs," though Gemini 1.0 itself was trained on TPU v4 and v5e; Gemini 2.5 was the first model family trained on v5p.[1][40][39]
Apple Foundation Models
In July 2024, Apple published its first technical report on the Apple Foundation Models (AFM) underlying Apple Intelligence. The paper disclosed that the AFM-on-device model, a roughly 3-billion-parameter model targeting on-device inference on Apple Silicon, was pre-trained on a single slice of 2,048 TPU v5p chips, while the larger AFM-server model was pre-trained on 8,192 TPU v4 chips provisioned as eight 1,024-chip slices.[23][7] Training used the AXLearn JAX-based library; Apple reported about 52% sustained model-FLOP utilization (MFU) for the AFM-server run on TPU v4, continued pre-training at a sequence length of 8,192 tokens followed by context lengthening at 32,768 tokens, and a core pre-training budget of 6.3 trillion tokens. Apple's deliberate decision to use Google TPUs for on-device foundation-model training (rather than NVIDIA GPUs) was widely covered as one of the most significant external endorsements of the TPU platform.[7][23]
Anthropic
Anthropic has been a major Google Cloud TPU customer and trained Claude models using a diversified compute strategy spanning Google TPUs, AWS Trainium, and NVIDIA GPUs.[30] In October 2025 the company announced an expansion of its TPU footprint to up to one million chips and "well over a gigawatt" of capacity coming online in 2026,[8][30][31] and in April 2026 it agreed to access about 3.5 gigawatts of next-generation Google TPU capacity via Broadcom starting in 2027.[38]
Salesforce
Salesforce announced at the v5p launch that it would use the chip and the AI Hypercomputer architecture to pre-train its proprietary foundation models for specialized production use cases. The company's quote on the launch blog highlighted both the 2× v4-to-v5p speedup and the seamless migration via JAX.[1]
Lightricks
The Israeli generative-AI app developer Lightricks was a v5p launch customer, saying the chip's "ample memory capacity" let it train a generative text-to-video model without splitting it into separate processes.[1] A November 2025 Google Cloud post described Lightricks rewriting its LTX-Video training stack in JAX and training on thousands of TPU cores through Google Compute Engine.[27]
Hugging Face
Hugging Face partnered with Google Cloud to make TPUs (including the v5 family) accessible to its user base via its Inference Endpoints and Spaces products, and developed the open-source optimum-tpu library to ease deployment of Hugging Face Transformers on Cloud TPUs.[32]
Other customers
Google has not published a full list of v5p customers beyond those named at launch.[1]
How does the TPU v5p compare to NVIDIA GPUs?
Industry coverage at launch positioned v5p as Google's most credible response to NVIDIA's H100 GPU, particularly for large-scale training where the v5p's pod-level scale of 8,960 chips and 4,800 Gbps ICI bandwidth competed with Nvidia's NVLink/InfiniBand-based clusters.[4][33] Analysts at SemiAnalysis, ServeTheHome, and others described the v5p as a major step in Google's vertically-integrated AI-infrastructure strategy, with the AI Hypercomputer framing emphasizing co-design across hardware, networking (optical circuit switching, Jupiter data-center network), and software (XLA, JAX, Pathways, Multislice).[1][14] For a broader side-by-side of accelerators across memory, bandwidth, and FP4/FP8/BF16 compute, see the AI accelerator comparison.
A noteworthy point in third-party analysis was the constraint that v5p was a Google-Cloud-exclusive device: unlike NVIDIA GPUs, TPUs are not sold for on-premises or multi-cloud deployments, which limited their addressable market but reinforced Google Cloud's strategic moat around the chip.[19] By late 2024, the v5p's market position was being eclipsed by Trillium (TPU v6e), which roughly doubled v5p's peak BF16 compute per chip (918 vs. 459 TFLOPS) and was advertised as 67% more energy-efficient than v5e, with a 4.7× peak compute per chip uplift over v5e.[4][10][34]
What replaced the TPU v5p?
Trillium (TPU v6e)
Google previewed Trillium at Google I/O on May 14, 2024 and reached general availability on December 11, 2024. Trillium is the v6e (efficiency-tier) successor in Google's TPU naming convention. It delivers approximately 4.7× the peak compute per chip vs. TPU v5e, doubles HBM and ICI bandwidth over v5e, has about twice v5p's peak BF16 compute per chip (918 vs. 459 TFLOPS), and Google advertised it as 67% more energy-efficient than v5e. MLPerf 4.1 results showed Trillium training the GPT-3 175B benchmark at 1.8× lower cost than v5p for the same validation accuracy, and Google reported up to 2.5× better performance per dollar than v5p on dense LLMs such as Llama2-70B and Llama3.1-405B.[10][22][34]
Trillium expanded the MXU from 128×128 to 256×256, increasing matrix-multiply throughput per cycle, while the per-pod scale dropped to 256 chips per ICI domain, relying more heavily on Multislice for very large jobs.[17][34]
Ironwood (TPU v7)
Google unveiled Ironwood in April 2025 as the first TPU "for the age of inference" and on November 6, 2025 said it would be generally available in the coming weeks. Ironwood delivers 4,614 FP8 TFLOPS per chip, 192 GB of HBM3e at 7.37 TB/s, and "superpod" scale of 9,216 chips producing 42.5 FP8 exaFLOPS per superpod (about 1.77 PB of shared HBM and 9.6 Tb/s ICI). Google has cited a 10× peak performance improvement over TPU v5p and a 3.7× improvement in compute-carbon-intensity vs. v5p.[11][35][36] Announcing Anthropic's late-2025 commitment to use up to one million TPUs and "well over a gigawatt" of capacity, Google Cloud pointed to its TPU portfolio "including our seventh generation TPU, Ironwood."[8][31]
Strategic positioning
In Google's overall AI-accelerator roadmap as of the mid-2020s, v5p occupies the role of the first production-grade frontier-training TPU whose performance and pod-scale enabled the Gemini program and external customers' largest models. Trillium, Ironwood and the 2026 TPU 8 generation subsequently surpassed it in absolute performance; as of November 2026, v5p was still offered on Google Cloud's TPU pricing page.[11][28][37]
Continue reading
- Gemini (language model)Gemini is a family of natively multimodal large language models developed by Google DeepMind, first announced on December 6, 2023, that can reason across text, images, audio, video, and code within a single…Mentioned 18 times above
- Cloud TPUCloud TPU is Google Cloud's offering of Tensor Processing Units (TPUs), the family of custom application-specific integrated circuits (ASICs) that Google builds to accelerate machine learning training and…Mentioned 15 times above
- Trillium (TPU v6e)Trillium, also designated TPU v6e, is the sixth-generation Tensor Processing Unit developed by Google for machine learning training and inference workloads on Cloud TPU infrastructure.Mentioned 14 times above
- TPU IronwoodTPU Ironwood (listed as TPU7x in Google Cloud's documentation and also called TPU v7) is Google's seventh-generation Tensor Processing UnitMentioned 9 times above
- JAXJAX is an open-source Python library for accelerator-oriented array computation and program transformation.Mentioned 9 times above
- XLA (Accelerated Linear Algebra)XLA (Accelerated Linear Algebra) is Google's open-source machine learning compiler that takes computational graphs from frameworks such as TensorFlow, JAX, and PyTorch and transforms them into highly optimized…Mentioned 6 times above
More from See also
- Tensor Processing Unit (TPU)
- TPU Pod
- AI Accelerator Comparison (H100 vs B200 vs MI300 vs TPU)
- Apple Foundation Models
- Apple Intelligence
- PyTorch
- TensorFlow
- bfloat16
- Systolic array
- Mixture of Experts (MoE)
- High Bandwidth Memory (HBM)
- NVIDIA H100
- AWS Trainium
- Google DeepMind
- Sundar Pichai
- Jeff Dean
- Anthropic
- Claude (language model)
- MLPerf
Topics:AI ComputeAI HardwareGoogle
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32"Introducing Cloud TPU v5p and AI Hypercomputer," Google Cloud Blog, Dec 6, 2023. cloud.google.com/...d-tpu-v5p-and-ai-hypercomputer
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10"Google announces the Cloud TPU v5p, its most powerful AI accelerator yet," TechCrunch, Dec 6, 2023. techcrunch.com/...most-powerful-ai-accelerator-yet
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12"TPU v5p," Google Cloud Documentation. docs.cloud.google.com/...v5p
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17"Tensor Processing Unit," Wikipedia. en.wikipedia.org/...Tensor_Processing_Unit
- ^"Cloud TPU release notes," Google Cloud Documentation. docs.cloud.google.com/...release-notes
- ^1 ^2 ^3"Google Cloud Next 2024 wrap up," Google Cloud Blog. cloud.google.com/...google-cloud-next-2024-wrap-up
- ^1 ^2 ^3 ^4"Apple says its AI models were trained on Google's custom chips," CNBC, Jul 29, 2024. cnbc.com/...-were-trained-on-googles-custom-chips-
- ^1 ^2 ^3"Anthropic to Expand Use of Google Cloud TPUs and Services," Google Cloud Press Corner, Oct 23, 2025. googlecloudpresscorner.com/...ud-TPUs-and-Services
- ^"Google Cloud TPUs made available to Hugging Face users," Hugging Face Blog. huggingface.co/...tpu-inference-endpoints-spaces
- ^1 ^2 ^3"Introducing Trillium, sixth-generation TPUs," Google Cloud Blog. cloud.google.com/...roducing-trillium-6th-gen-tpus
- ^1 ^2 ^3 ^4 ^5"Ironwood TPUs and new Axion-based VMs for your AI workloads," Google Cloud Blog. cloud.google.com/...ased-vms-for-your-ai-workloads
- ^1 ^2 ^3"Google TPU Architecture: 7 Generations Explained," Introl Blog. introl.com/...tecture-complete-guide-7-generations
- ^"Google Details TPUv4 and its Crazy Optically Reconfigurable AI Network," ServeTheHome. servethehome.com/...ally-reconfigurable-ai-network
- ^1 ^2 ^3"Highly Customized Optical Networking Critical for Google's TPUs," NextBigFuture, Nov 2025. nextbigfuture.com/...-tensor-processing-units-tpus
- ^"Cloud TPU v5e is generally available," Google Cloud Blog. cloud.google.com/...announcing-cloud-tpu-v5e-in-ga
- ^1 ^2 ^3 ^4 ^5"Google announces AI chip 'TPU v5p'," GIGAZINE. gigazine.net/...20231207-google-tpu-v5p
- ^1 ^2 ^3 ^4 ^5"Google TPUs Explained: Architecture & Performance for Gemini 3," IntuitionLabs. intuitionlabs.ai/...google-tpu-architecture-gemini-3
- ^"Unveiling Google's TPU Architecture: OCS Optical Circuit Switching," FiberMall. fibermall.com/...unveiling-google-tpu-architecture
- ^1 ^2"Google TPU v5p AI Chip Launches Alongside Gemini," ServeTheHome. servethehome.com/...chip-launches-alongside-gemini
- ^1 ^2 ^3 ^4 ^5 ^6"How to Think About TPUs," Jax ML Scaling Book. jax-ml.github.io/...tpus
- ^1 ^2"Building production AI on Cloud TPUs with JAX," Google Cloud Documentation. docs.cloud.google.com/...jax-ai-stack
- ^1 ^2 ^3"Trillium MLPerf 4.1 training benchmarks," Google Cloud Blog. cloud.google.com/...-mlperf-41-training-benchmarks
- ^1 ^2 ^3 ^4"Apple Intelligence Foundation Language Models," Apple/arXiv, 2024. arxiv.org/...2407.21075v1
- ^"Google TPU v5p · Specs, Pricing, Buyers," BenchGecko. benchgecko.ai/...tpu-v5p
- ^"MLPerf Training 4.0: Nvidia Still King," HPCwire, Jun 2024. hpcwire.com/...ing-power-and-llm-fine-tuning-added
- "Google reveals Gemini AI model, plus new chip and hypercomputer," TechMonitor. techmonitor.ai/...ni-ai-deepmind-tpu-hypercomputer
- ^"How Lightricks trains video diffusion models at scale with JAX on TPU," Google Cloud Blog. cloud.google.com/...odels-at-scale-with-jax-on-tpu
- ^1 ^2 ^3 ^4 ^5"TPU Pricing," Google Cloud. cloud.google.com/...pricing
- ^"Google launches Cloud TPU v5p GA," LinkedIn / Gang Chen. linkedin.com/...-activity-7183575344824696833-d79v
- ^1 ^2"Anthropic Taps Over a Gigawatt of Google Cloud TPUs," Cloud Wars, 2025. cloudwars.com/...s-to-power-next-gen-claude-models
- ^1 ^2"Anthropic expands partnership with Google and Broadcom," Anthropic news. anthropic.com/...of-google-cloud-tpus-and-services
- ^"Hugging Face and Google Cloud partner to improve AI model access and TPU support," ETIH EdTech News. edtechinnovationhub.com/...security-and-tpu-access
- ^"Apple skips Nvidia's GPUs for its AI models, uses thousands of Google TPUs instead," Tom's Hardware. tomshardware.com/...ousands-of-google-tpus-instead
- ^1 ^2 ^3"Trillium TPU is GA," Google Cloud Blog. cloud.google.com/...trillium-tpu-is-ga
- ^"Ironwood: The first Google TPU for the age of inference," Google Blog. blog.google/...ironwood-tpu-age-of-inference
- ^"Ironwood TPUs deliver 3.7x carbon efficiency gains," Google Cloud Blog. cloud.google.com/...er-37x-carbon-efficiency-gains
- ^1 ^2 ^3 ^4"Google has announced its 8th generation of AI processing chips, the TPU 8t, which is specialized for training, and the TPU 8i, which is specialized for inference," GIGAZINE, Apr 23, 2026. gigazine.net/...20260423-google-tpu-8t-8i
- ^"Anthropic signs biggest compute deal yet with Google and Broadcom as revenue run rate hits $30bn," The Next Web, Apr 7, 2026. thenextweb.com/...pic-google-broadcom-compute-deal
- ^1 ^2 ^3"Gemini 2.5: Pushing the Frontier with Advanced Reasoning, Multimodality, Long Context, and Next Generation Agentic Capabilities," Google/arXiv, 2025. arxiv.org/...2507.06261
- ^1 ^2 ^3"Introducing Gemini: our largest and most capable AI model," Google Blog, Dec 6, 2023. blog.google/...google-gemini-ai
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
8 revisions by 1 contributor · v8 · 4,090 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (130 claims, 38 sources fetched); 16 material + 18 minor fixed
Cite this page: AI Wiki. "TPU v5p." aiwiki.ai, updated 7 Jul 2026, fact-checked 4 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/google_tpu_v5p