

ImageBind
ImageBind is a multimodal model from Meta AI (its Fundamental AI Research lab) that learns a single joint embedding space across six different modalities: images and video, text, audio, depth, thermal (infrared) data, and inertial measurement unit (IMU) signals. It was announced on 9 May 2023, alongside open-source code and model weights, and the accompanying paper, "ImageBind: One Embedding Space To Bind Them All" by Rohit Girdhar and colleagues, was published as a highlight at CVPR 2023 [1][2][3].
The central idea is that you do not need training data in which all six modalities appear together. Instead, each modality is aligned only to images, and that shared anchor is enough for the rest of the modalities to line up with one another. Meta calls this an "emergent" alignment: pairs the model never saw together, such as audio and text, end up close in the embedding space because each was independently bound to images [2][3]. This lets a single model perform zero-shot tasks like retrieving an image from a sound, and even combine embeddings arithmetically across modalities.
The binding idea
Most prior work on joint embeddings needed paired examples for each combination of modalities it wanted to relate. Collecting such data for every pair (audio with depth, thermal with text, and so on) does not scale. ImageBind sidesteps this by treating images as a hub. Images naturally co-occur with many other signals: a video frame comes with its soundtrack, a photo from an RGB-D camera comes with a depth map, a scene from a thermal camera comes with an infrared frame, and footage from a head-mounted camera comes with motion sensor readings. By binding each non-image modality to images, all of the modalities become mutually comparable through that common reference [2][3].
Training uses the standard InfoNCE contrastive objective. For each modality, the model is given naturally paired (image-or-video, modality) examples and learns to pull matching pairs together and push non-matching pairs apart in the embedding space [4][5]. Only image-paired data is used; no (audio, depth) or (text, thermal) pairs are ever shown, yet those relationships emerge. The strength of the emergent behavior scales with the quality of the image encoder: a stronger vision backbone produces better zero-shot results on the non-vision modalities [1][6].
Architecture and backbone
ImageBind reuses large-scale pretrained image-text models rather than training vision and language understanding from scratch. The image and text encoders are initialized from a pretrained CLIP-style model (OpenCLIP) and kept frozen; the image encoder is a ViT-H with roughly 630M parameters and the text encoder has on the order of 300M parameters. The encoders for the remaining modalities are trained to map their inputs into the same space as these frozen image features [4][5].
Each modality has a dedicated encoder, but they share the Transformer family of architectures. Depth and thermal data are treated as single-channel images and passed through a Vision Transformer. Audio is converted to a mel-spectrogram and encoded with a Vision Transformer over spectrogram patches. IMU data (a multi-channel time series of accelerometer and gyroscope readings) is split into fixed-length clips, projected with a 1D convolution, and encoded with a Transformer [4][5].
| Modality | Encoder | Paired data source for binding |
|---|---|---|
| Image / video | ViT-H, frozen OpenCLIP weights (~630M params) | Web-scale image-text (with text encoder) |
| Text | Frozen OpenCLIP text encoder (~300M params) | Web-scale image-text |
| Audio | Vision Transformer over mel-spectrogram patches | AudioSet (video paired with its audio) |
| Depth | Vision Transformer (depth as 1-channel image) | SUN RGB-D (images paired with depth) |
| Thermal | Vision Transformer (thermal as 1-channel image) | LLVIP (visible images paired with infrared) |
| IMU | 1D convolution then Transformer | Ego4D (egocentric video paired with IMU) |
The naturally occurring pairings come from existing datasets: video and audio from AudioSet, image and depth from SUN RGB-D, image and thermal from LLVIP, and video and IMU from Ego4D, in addition to large web image-text collections for the vision-language side [4][5]. Because depth, thermal, and audio are recast into image-like or spectrogram representations, the same contrastive recipe applies uniformly across them.
Emergent zero-shot capabilities
Once trained, ImageBind supports several behaviors without any task-specific fine-tuning:
- Cross-modal retrieval. Given a query in one modality, retrieve matching items in another. The model can fetch images from audio clips, retrieve audio for a text prompt, or find depth maps for an image, including pairs it never saw together during training [2][3].
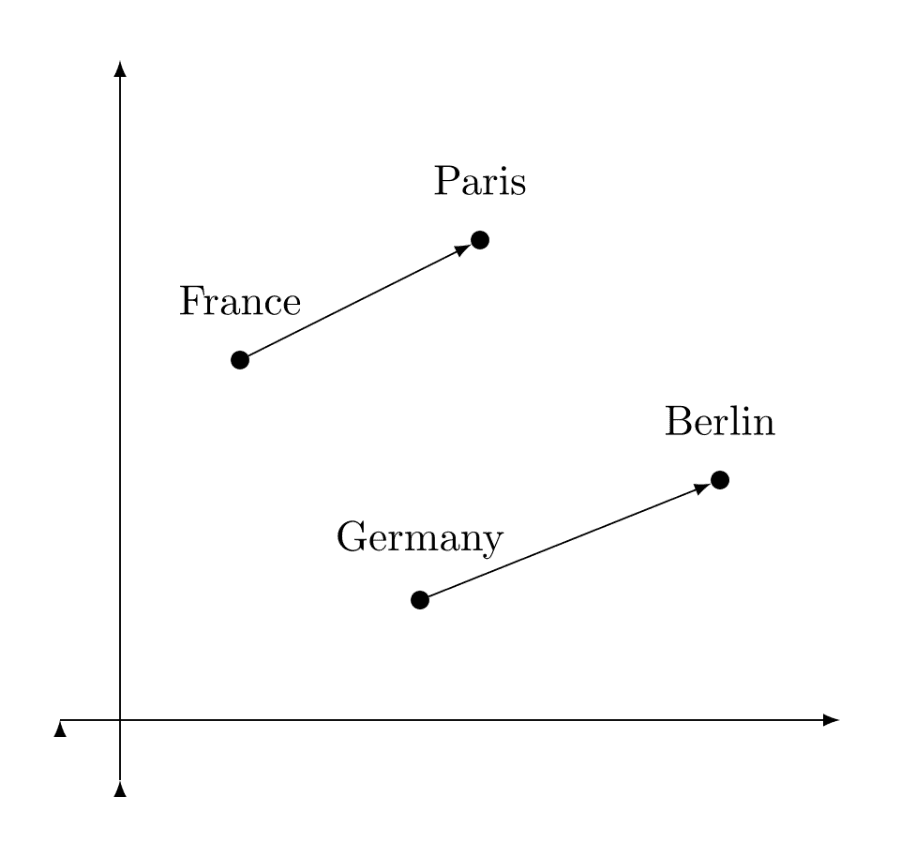
- Embedding-space arithmetic. Because all modalities share one space, their embeddings can be added to compose meaning. Combining an image of fruits on a table with the sound of chirping birds, for example, retrieves an image of fruits on trees with birds [1].
- Audio-driven generation. Feeding ImageBind audio embeddings into the decoder of a pretrained image generator (Meta demonstrated this with a DALLE-2-style decoder) produces images from sounds such as rain, waves, fire, or an engine [1].
- Cross-modal detection and few-shot recognition. The paper also shows the embeddings can upgrade detectors to new modalities and serve as strong few-shot recognizers [1][6].
On standard benchmarks, ImageBind set new results for emergent zero-shot recognition across modalities, in several cases matching or surpassing specialist models trained with direct supervision on the target modality. Meta's released checkpoint (imagebind_huge) reports the following zero-shot classification accuracies [3][6]:
| Benchmark | Modality | Top-1 accuracy |
|---|---|---|
| ImageNet-1k | Image | 77.7% |
| Kinetics-400 | Video | 50.0% |
| NYU Depth v2 | Depth | 54.0% |
| ESC-50 | Audio | 66.9% |
| LLVIP | Thermal | 63.4% |
| Ego4D | IMU | 25.0% |
On audio specifically, ImageBind's emergent zero-shot classification and retrieval matched or beat prior specialist audio-text models on tasks built from datasets such as ESC, Clotho, and AudioCaps, despite never being trained on paired audio-text data [1][6].
Release, license, and use in later work
Meta released the code and the imagebind_huge weights publicly on GitHub (facebookresearch/ImageBind), under a non-commercial Creative Commons license, which permits research use but not commercial use. The repository is inconsistent about which one: the README names CC-BY-NC 4.0, while the LICENSE file it points to is the text of CC BY-NC-SA 4.0, which adds a share-alike condition [3]. A project page with interactive demos was published at imagebind.metademolab.com [2].
Meta framed ImageBind partly as a foundation for generative and search systems. The announcement noted that the embeddings could let a text-to-image system such as Make-A-Scene generate images from audio (for example, the sounds of a market or a rainforest), and more broadly enable richer multimodal search and content understanding [2]. The work sits in a line of Meta research on aligning many modalities to a single representation and on extending pretrained vision-language models to senses beyond sight and language.
Relationship to other multimodal binders
ImageBind should not be confused with Meta-Transformer, a separate framework introduced in July 2023 by a different group (Yiyuan Zhang, Kaixiong Gong and colleagues, arXiv 2307.10802). Meta-Transformer targets twelve modalities, including point clouds, hyperspectral and X-ray images, graphs, tabular and time-series data, and uses a modality-shared encoder with frozen parameters and a unified tokenizer; it does not rely on a pretrained large language model (its shared encoder is a ViT pretrained contrastively on LAION-2B) and reports results on several tasks where it outperforms ImageBind [7][8]. The naming is coincidental: Meta-Transformer is not a Meta AI product [8]. ImageBind's distinguishing contribution is specifically the image-as-hub binding that produces emergent alignment from image-paired data alone.
Continue reading
- EmbeddingsIn machine learning, an embedding is a learned representation that maps an input into a vector, usually so that a downstream model or comparison rule can use relationships encoded in the vector's geometry.Mentioned 11 times above
- Embedding SpaceAn embedding space is a continuous, typically high-dimensional vector space in which data objects (words, sentences, images, users, audio clips, code, or other entities) are represented as dense numerical…Mentioned 4 times above
- Multimodal ModelA multimodal model is a machine learning model, or a model-based system, that processes, relates, or produces information across more than one kind of data. Each kind is called a modality.Mentioned 3 times above
- Meta AIMeta AI is the name Meta Platforms uses for two related but distinct things: the company's artificial intelligence research and engineering organizationMentioned twice above
- Inertial Measurement UnitAn inertial measurement unit (IMU) is an electronic device that measures a body's specific force and angular rateLinked in the introduction
- ModalityA modality in machine learning and artificial intelligence is a distinct type, form, or structure of data that a model can process, learn from, or generate.Mentioned 10 times above
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6Girdhar, R., El-Nouby, A., Liu, Z., Singh, M., Alwala, K. V., Joulin, A., Misra, I. "ImageBind: One Embedding Space To Bind Them All." arXiv:2305.05665, May 2023. arxiv.org/...2305.05665
- ^1 ^2 ^3 ^4 ^5 ^6Meta AI. "ImageBind: Holistic AI learning across six modalities." Meta AI Blog, 9 May 2023. ai.meta.com/...imagebind-six-modalities-binding-ai
- ^1 ^2 ^3 ^4 ^5 ^6facebookresearch/ImageBind, GitHub repository (README, checkpoints, license, benchmark table). github.com/...ImageBind
- ^1 ^2 ^3 ^4"ImageBind: One Embedding Space To Bind Them All." CREATIS MYRIAD paper review (encoder and dataset details). creatis-myriad.github.io/...ImageBind
- ^1 ^2 ^3 ^4"ImageBind MultiJoint Embedding Model from Meta Explained." Encord Blog. encord.com/...imagebind-embedding-model-explained
- ^1 ^2 ^3 ^4Girdhar et al. "ImageBind: One Embedding Space To Bind Them All." CVPR 2023 Open Access. openaccess.thecvf.com/..._Them_All_CVPR_2023_paper
- ^Zhang, Y., Gong, K., et al. "Meta-Transformer: A Unified Framework for Multimodal Learning." arXiv:2307.10802, July 2023. arxiv.org/...2307.10802
- ^1 ^2"Meta-Transformer: A Unified Framework for Multimodal Learning." Encord Blog. encord.com/...meta-transformer-explained
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
7 revisions · v7 · 1,409 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (45 claims, 9 sources fetched); 0 material + 5 minor fixed
Cite this page: AI Wiki. "ImageBind." aiwiki.ai, updated 17 Nov 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/imagebind