

Sapiens (computer vision)
Sapiens is a family of human-centric computer vision foundation models developed by Meta (Reality Labs), introduced in 2024 and presented as an oral paper at the European Conference on Computer Vision (ECCV) 2024. Sapiens models are Vision Transformers that target four fundamental human-centric vision tasks defined over images of people: 2D human pose estimation, body-part segmentation, depth estimation, and surface-normal prediction. The models are pretrained by masked autoencoding on a curated corpus of over 300 million in-the-wild human images, scale from roughly 0.3 billion up to 2 billion parameters, and run natively at 1K (1024-pixel) high resolution. [1][2][3]
The paper summarizes the approach in one sentence: "We present Sapiens, a family of models for four fundamental human-centric vision tasks -- 2D pose estimation, body-part segmentation, depth estimation, and surface normal prediction." [1] The project page describes the result more plainly as "high-resolution vision transformers pretrained on 300 million human images." [3]
What is Sapiens?
Sapiens is a single, openly released Vision Transformer backbone, pretrained once on a very large human-only image corpus, that can be finetuned with lightweight task heads to perform four distinct human-centric perception tasks at high resolution. Rather than maintaining a separate specialized model for each task, Sapiens shows that one scaled, human-pretrained encoder transfers across all four and generalizes to unconstrained real-world photos. The accompanying paper, "Sapiens: Foundation for Human Vision Models," was authored by Rawal Khirodkar, Timur Bagautdinov, Julieta Martinez, Zhaoen Su, Austin James, Peter Selednik, Stuart Anderson, and Shunsuke Saito. It was posted to arXiv on 22 August 2024 and published in the ECCV 2024 proceedings, with code and model weights released openly on GitHub and Hugging Face. [1][4][5]
Why was Sapiens built?
Human-centric perception underpins applications such as augmented and virtual reality, telepresence avatars, motion capture, and photography. Historically each of the four tasks above had its own specialized models, datasets, and architectures, which made systems hard to maintain and limited generalization to unconstrained imagery. Sapiens takes the opposite stance: a single backbone, pretrained once on a very large collection of human images, is finetuned with lightweight task-specific heads. The central bet is that scaling both the model and a human-only pretraining corpus, while keeping inference resolution high, produces representations that transfer across all four tasks and generalize to in-the-wild photos. [1][6]
The design follows the broader foundation model recipe: self-supervised pretraining on a large unlabeled corpus, followed by supervised finetuning for downstream tasks. Sapiens specializes that recipe to humans by curating its pretraining data exclusively from human images and by operating at a resolution high enough to capture fine structure such as fingers and facial detail. As the abstract puts it, "given the same computational budget, self-supervised pretraining on a curated dataset of human images significantly boosts the performance for a diverse set of human-centric tasks." [1]
What tasks does Sapiens perform?
Sapiens performs the four fundamental human-centric vision tasks listed below. Each is handled by the shared pretrained encoder plus a lightweight task-specific head.
| Task | Output | Evaluation benchmark |
|---|---|---|
| 2D pose estimation | Keypoint coordinates (up to 308 whole-body keypoints in training) | Humans-5K (114 common keypoints) |
| Body-part segmentation | Per-pixel class label (28-class body-part scheme) | Humans-2K |
| Depth estimation | Per-pixel metric/relative depth | THuman2.0, Hi4D |
| Surface-normal prediction | Per-pixel 3D normal vector | THuman2.0, Hi4D |
For pose estimation, the released models support several keypoint vocabularies: a 17-point COCO body skeleton, the 133-point COCO-WholeBody format (body, face, hands, and feet), and a dense 308-point set with detailed facial and hand landmarks. The dense vocabulary is what makes Sapiens useful for high-fidelity face and hand tracking, not just coarse body pose. [7]
How was Sapiens trained?
Sapiens is pretrained with masked autoencoding (MAE), a self-supervised objective in which a large fraction of image patches are masked and the model learns to reconstruct the missing content. The standard configuration masks 75 percent of patches, and the paper reports that performance held up even at mask ratios as high as 95 percent, reflecting the redundancy of human imagery. Images are split into 16x16 pixel patches at a 1024-pixel input resolution. [1]
The pretraining corpus, called Humans-300M, was built by starting from roughly one billion in-the-wild images and filtering aggressively for humans. The authors discarded images with watermarks, text, or unnatural elements, then ran a person detector and kept images with a detection score above 0.9 and a bounding box larger than 300 pixels in its dimensions. The result is about 300 million diverse human images, of which over 248 million contain multiple subjects. Pretraining used no human annotations, only the raw images. Each model was trained on 1.2 trillion tokens; the largest variant was trained on 1024 NVIDIA A100 GPUs for roughly 18 days. [1]
For downstream tasks, the pretrained encoder is paired with a lightweight, task-specific decoder head (built from deconvolution and convolution layers) that is initialized randomly. The encoder and decoder are then finetuned end-to-end on labeled data for each task. [1]
How large are the Sapiens models?
Sapiens is released in four sizes spanning roughly 0.3 billion to 2 billion parameters. All variants are plain Vision Transformers with a 16x16 patch size operating at 1024-pixel resolution; they differ in depth (number of transformer layers), width (hidden dimension), and head count.
| Model | Parameters | Layers | Hidden size | Heads | FLOPs |
|---|---|---|---|---|---|
| Sapiens-0.3B | 0.336 B | 24 | 1024 | 16 | 1.242 T |
| Sapiens-0.6B | 0.664 B | 32 | 1280 | 16 | 2.583 T |
| Sapiens-1B | 1.169 B | 40 | 1536 | 24 | 4.647 T |
| Sapiens-2B | 2.163 B | 48 | 1920 | 32 | 8.709 T |
A consistent finding across the paper is that accuracy improves smoothly as the model is scaled up across all four tasks. In the authors' words, the "simple model design also brings scalability -- model performance across tasks improves as we scale the number of parameters from 0.3 to 2 billion," which they present as evidence that human-centric perception benefits from the same scaling behavior seen in other foundation models. [1][5]
How well does Sapiens perform on benchmarks?
The paper evaluates against task-specific state-of-the-art baselines and reports sizeable gains, driven by the largest Sapiens-2B model. Improvements quoted below are relative to the prior best methods. [1]
| Task | Benchmark | Metric | Sapiens-2B result | Improvement over prior SOTA |
|---|---|---|---|---|
| Pose estimation | Humans-5K | AP | 61.1 AP | +7.6 mAP |
| Body-part segmentation | Humans-2K | mIoU | 81.2 mIoU (89.4 mAcc) | +17.1 mIoU |
| Depth estimation | Hi4D | RMSE | 0.114 RMSE | 22.4% relative |
| Surface normals | THuman2.0 | Mean angular error | ~11.8 degrees | 53.5% relative |
On surface normals, Sapiens-2B also reports about 12.14 degrees mean angular error on the multi-person Hi4D benchmark. For depth on the single-person THuman2.0 splits, reported RMSE values are roughly 0.008 (face), 0.010 (upper body), and 0.016 (full body). [1]
Beyond the headline numbers, the paper emphasizes generalization: because pretraining covers a very large and varied set of real-world human images, the models perform well on unconstrained photos with occlusion, crowds, and unusual poses, conditions where models trained only on smaller labeled datasets tend to degrade. The abstract notes that "the resulting models exhibit remarkable generalization to in-the-wild data, even when labeled data is scarce or entirely synthetic." [1][6]
Is Sapiens open source?
Meta released the Sapiens code on GitHub (facebookresearch/sapiens) and published pretrained encoders plus finetuned task checkpoints for all four sizes on Hugging Face. The release includes a person detector (RTMPose-based) used in the pose pipeline, and a "Sapiens-lite" inference path for deployment. [3][5][7]
The model weights are distributed under the Creative Commons Attribution-NonCommercial 4.0 license (CC BY-NC 4.0), which permits use, sharing, and modification with attribution but prohibits commercial use; the accompanying code repository carries the same CC BY-NC 4.0 license, and only the portions derived from other open-source projects are under Apache 2.0. [2][5][8]
How was Sapiens received, and what came after it?
Sapiens drew attention as one of the first attempts to build a unified, openly released foundation model dedicated specifically to human perception rather than general scene understanding. Coverage in the computer-vision community highlighted the combination of high native resolution, the human-only pretraining corpus, and consistent improvements across four distinct tasks from a single backbone. [6][9]
In April 2026, Meta released a successor, Sapiens2, extending the approach with additional outputs including surface normals, pointmaps, and albedo estimation alongside the original pose and segmentation tasks, again positioned as a high-resolution human-centric vision model. [10]
Continue reading
- Pose estimationPose estimation is the computer vision task of detecting and localizing the keypoints (also called landmarks or joints) of a human body, hand, face, animal, or rigid object in images and video, then connecting…Mentioned 5 times above
- Meta AIMeta AI is the name Meta Platforms uses for two related but distinct things: the company's artificial intelligence research and engineering organizationMentioned 4 times above
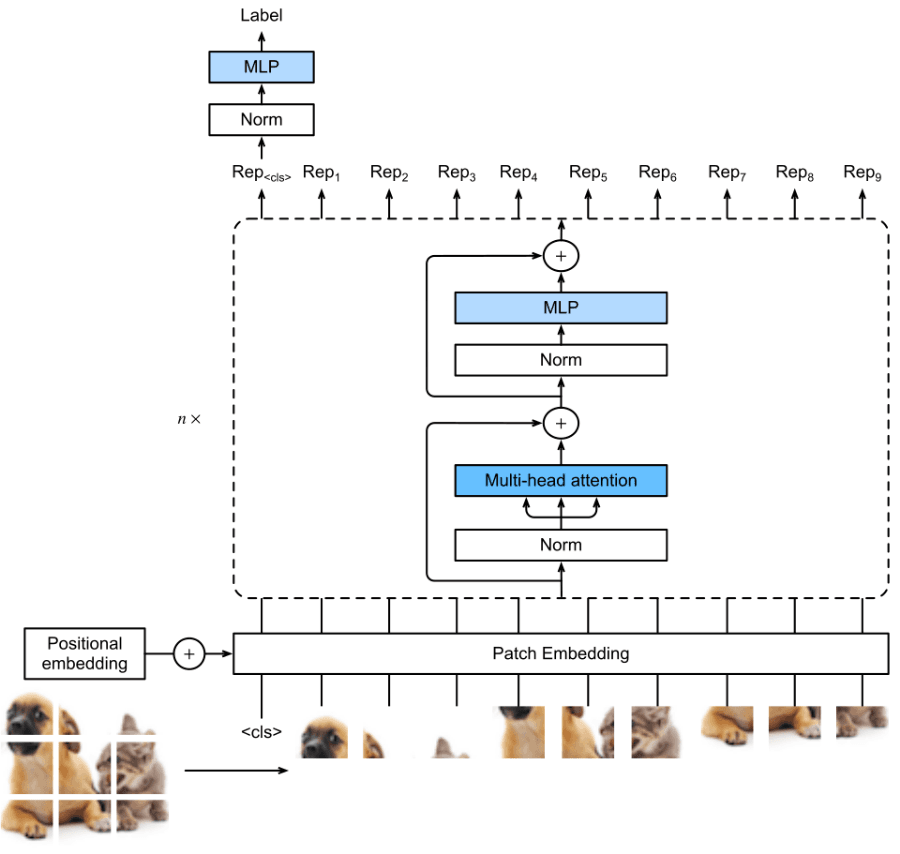
- Vision TransformerThe Vision Transformer (ViT) is a deep learning architecture that represents an image as a sequence of fixed-size patches and processes that sequence with a Transformer encoder.Mentioned 4 times above
- Depth estimationDepth estimation is the computer vision task of predicting how far each surface in a scene is from the camera, producing a dense per-pixel depth map from one or more images.Mentioned 4 times above
- Computer VisionComputer vision is the study of computational methods that extract, estimate, or generate useful representations from visual measurements.Mentioned twice above
- Foundation ModelsA foundation model is a machine learning model trained on broad data, generally with self-supervision at scale, that can be adapted to a wide range of downstream tasks.Mentioned twice above
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12Rawal Khirodkar, Timur Bagautdinov, Julieta Martinez, Zhaoen Su, Austin James, Peter Selednik, Stuart Anderson, Shunsuke Saito. "Sapiens: Foundation for Human Vision Models." arXiv:2408.12569 (HTML version). arxiv.org/...2408.12569v1
- ^1 ^2"Sapiens: Foundation for Human Vision Models." arXiv abstract page. arxiv.org/...2408.12569
- ^1 ^2 ^3"Sapiens: Foundation for Human Vision Models." Project page, Rawal Khirodkar. rawalkhirodkar.github.io/sapiens
- ^"Sapiens: Foundation for Human Vision Models." ECCV 2024 proceedings, Springer. link.springer.com/...978-3-031-73235-5_12
- ^1 ^2 ^3 ^4facebookresearch/sapiens. "High-resolution models for human tasks." GitHub repository. github.com/...sapiens
- ^1 ^2 ^3"Sapiens: Foundation for Human Vision Models by Meta." LearnOpenCV. learnopencv.com/sapiens-human-vision-models
- ^1 ^2facebookresearch/sapiens. Pose estimation documentation (POSE_README.md). github.com/...POSE_README.md
- ^facebook/sapiens-pose-0.6b. Model card (license: cc-by-nc-4.0). Hugging Face. huggingface.co/...sapiens-pose-0.6b
- ^"Meta Presents Sapiens: Foundation for Human Vision Models." MarkTechPost, 23 August 2024. marktechpost.com/...dation-for-human-vision-models
- ^"Meta AI Releases Sapiens2: A High-Resolution Human-Centric Vision Model for Pose, Segmentation, Normals, Pointmap, and Albedo." MarkTechPost, 27 April 2026. marktechpost.com/...on-normals-pointmap-and-albedo
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
6 revisions · v6 · 1,638 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Cite this page: AI Wiki. "Sapiens (computer vision)." aiwiki.ai, updated 17 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/sapiens