

Stable Video Diffusion
Stable Video Diffusion (SVD) is a latent video diffusion model released by Stability AI on 21 November 2023, and it was released alongside a technical report that documented its data-curation and training recipe in unusual detail.[1][2] The release was accompanied by a technical report titled "Stable Video Diffusion: Scaling Latent Video Diffusion Models to Large Datasets" by Andreas Blattmann, Tim Dockhorn, Sumith Kulal, and collaborators (arXiv:2311.15127).[1][2] The first iteration shipped two image-to-video checkpoints, SVD (14 frames) and SVD-XT (25 frames), each producing 576x1024 clips at user-selectable frame rates between 3 and 30 frames per second.[1][3] Architecturally, SVD reuses the spatial backbone of Stable Diffusion 2.1 and inserts temporal convolution and attention layers after every spatial layer, then trains the resulting video U-Net through a three-stage recipe of image pretraining, large-scale video pretraining on a curated dataset called LVD-F, and a high-quality finetuning stage on a small premium subset.[2][3] SVD became the foundation for follow-up systems including SVD-XT 1.1 (February 2024), Stable Video 3D (March 2024), Stable Video 4D (July 2024), and the commercial Stable Video API.[4][5][6][7]
The paper's opening sentence defines the system directly: "We present Stable Video Diffusion - a latent video diffusion model for high-resolution, state-of-the-art text-to-video and image-to-video generation."[2]
Infobox
| Attribute | Value |
|---|---|
| Developer | Stability AI |
| Initial release | 21 November 2023 (research preview, weights on Hugging Face) |
| Paper | Blattmann et al., arXiv:2311.15127, 25 November 2023 |
| Modality | Image-to-video latent diffusion |
| Resolution | 576x1024 (base/XT); 576x576 (multi-view fine-tune) |
| Frame count | 14 (SVD), 25 (SVD-XT, SVD-XT 1.1) |
| Frame-rate range | 3 to 30 fps (configurable via fps_id) |
| Spatial backbone | Stable Diffusion 2.1 U-Net with added temporal layers |
| Training compute | ~200,000 A100 80GB GPU-hours |
| License (research preview) | Stable Video Diffusion Research / Community License |
| Commercial access | Self-hosted under the Stability AI Community License (enterprise license above $1M revenue); hosted API deprecated July 2025 |
| Repository | github.com/Stability-AI/generative-models |
When was Stable Video Diffusion released, and who made it?
Stability AI announced Stable Video Diffusion on 21 November 2023, and the accompanying preprint was posted to arXiv four days later, on 25 November 2023.[1][2] The model was developed by a Stability AI research team led by Andreas Blattmann, Tim Dockhorn, Sumith Kulal, Daniel Mendelevitch, Maciej Kilian, Dominik Lorenz, Yam Levi, Zion English, Vikram Voleti, Adam Letts, Varun Jampani, and Robin Rombach, several of whom had earlier co-authored the original latent diffusion and Stable Diffusion work.[2] In the official announcement Stability AI described the launch in concrete terms: "Stable Video Diffusion is released in the form of two image-to-video models, capable of generating 14 and 25 frames at customizable frame rates between 3 and 30 frames per second."[1]
What problem did Stable Video Diffusion solve?
By late 2023 the open-weights image generation ecosystem had matured around Stable Diffusion 1.5 and SDXL, while video generation remained dominated by closed commercial systems. Runway had announced Runway Gen-2 in March 2023, and Pika Labs followed with the early-access launch of Pika 1.0 on 28 November 2023.[8][9] Plug-and-play motion modules for LoRA- and DreamBooth-personalized image models, notably AnimateDiff (Guo et al., arXiv:2307.04725, July 2023), had shown that personalized image models could be coaxed into producing short looping clips, but they did not match the temporal coherence or resolution of closed video systems.[10] Earlier work by Blattmann, Rombach, Dockhorn and NVIDIA collaborators on Video LDM (Blattmann et al., CVPR 2023, "Align your Latents") had already demonstrated that a frozen image diffusion U-Net could be temporally extended, and open-weights video diffusion models such as ModelScopeT2V (August 2023) and VideoCrafter1 (October 2023) had been released, but the SVD authors argued that the field had yet to agree on a unified strategy for curating video data.[2][21][22]
Stability AI announced Stable Video Diffusion on 21 November 2023, framing the release as a research preview intended to study generative video models rather than as a consumer product.[1] The accompanying preprint, posted to arXiv on 25 November 2023, identifies three distinct training stages for video latent diffusion models and provides what the authors call a "systematic curation process" for assembling and filtering a large video pretraining corpus, addressing a gap in prior literature that had described training procedures only at a high level.[2] The release included weights for two image-to-video checkpoints on Hugging Face (stabilityai/stable-video-diffusion-img2vid and stabilityai/stable-video-diffusion-img2vid-xt), reference inference code in the Stability-AI/generative-models GitHub repository, and a Streamlit demo.[3][11]
Is Stable Video Diffusion open source?
The November 2023 release was governed by a non-commercial research license, so it is open-weights rather than fully open-source under a permissive license such as Apache 2.0 or MIT. Commercial deployment was not permitted at launch. From December 2023 commercial use required a paid Stability AI Membership, and in July 2024 Stability AI moved its models to the Stability AI Community License, which allows free commercial use for organizations with under $1 million in annual revenue and requires an enterprise license above it.[4][5][23] A hosted API on the Stability AI Developer Platform was offered from December 2023 until it was deprecated on 24 July 2025.[7][20]
How does Stable Video Diffusion work?
What is the SVD architecture?
The Stable Video Diffusion U-Net is constructed by taking the spatial backbone of Stable Diffusion 2.1, a latent image diffusion model trained at 768x768 with an OpenCLIP-ViT/H text encoder, and inserting temporal convolution and temporal attention layers after every existing spatial convolution and spatial attention block.[2][3] During the temporal extension the spatial weights are initialized from the pretrained image model. The U-Net therefore operates on five-dimensional latents shaped (batch, time, channel, height, width), with spatial layers processing each frame independently and temporal layers mixing information across time.[2]
The model uses the same Stable Diffusion 2.1 first-stage latent diffusion autoencoder for the spatial latent representation (8x spatial downsampling, four-channel latents), but Stability AI also trained a temporally-aware decoder, sometimes called the f8-decoder, that is finetuned for temporal consistency and reduces flicker during the latent-to-pixel decoding step.[3] A frame-wise decoder is also released for use cases where temporal consistency in the decoder is not critical.
For conditioning, the image input is encoded with a CLIP image encoder and supplied through the cross-attention layers, replacing the text-conditioning pathway of the original image model. SVD does not accept text prompts; it is a pure image-to-video model.[3][11]
How do fps_id and motion_bucket_id control the output?
A distinctive feature of SVD is its use of two scalar micro-conditioning signals supplied alongside the noisy latent at every denoising step. The first, fps_id, encodes the target frame rate of the output clip; during training the models are conditioned on each clip's frame rate and motion score, which lets the amount of motion be varied at inference.[2][11] The second, motion_bucket_id, encodes how much motion to synthesize: at inference time higher values produce more vigorous motion, while lower values produce slower or near-static clips.[11][13] Both signals are exposed to users at inference and allow rough control over the dynamics of the generated clip without retraining.
A third inference-time parameter, noise_aug_strength, controls how much noise is added to the conditioning image before it is encoded; higher values reduce the model's tendency to copy the input frame verbatim and tend to increase motion, at the cost of input fidelity.[11]
Why does SVD shift the EDM noise schedule for high-resolution video?
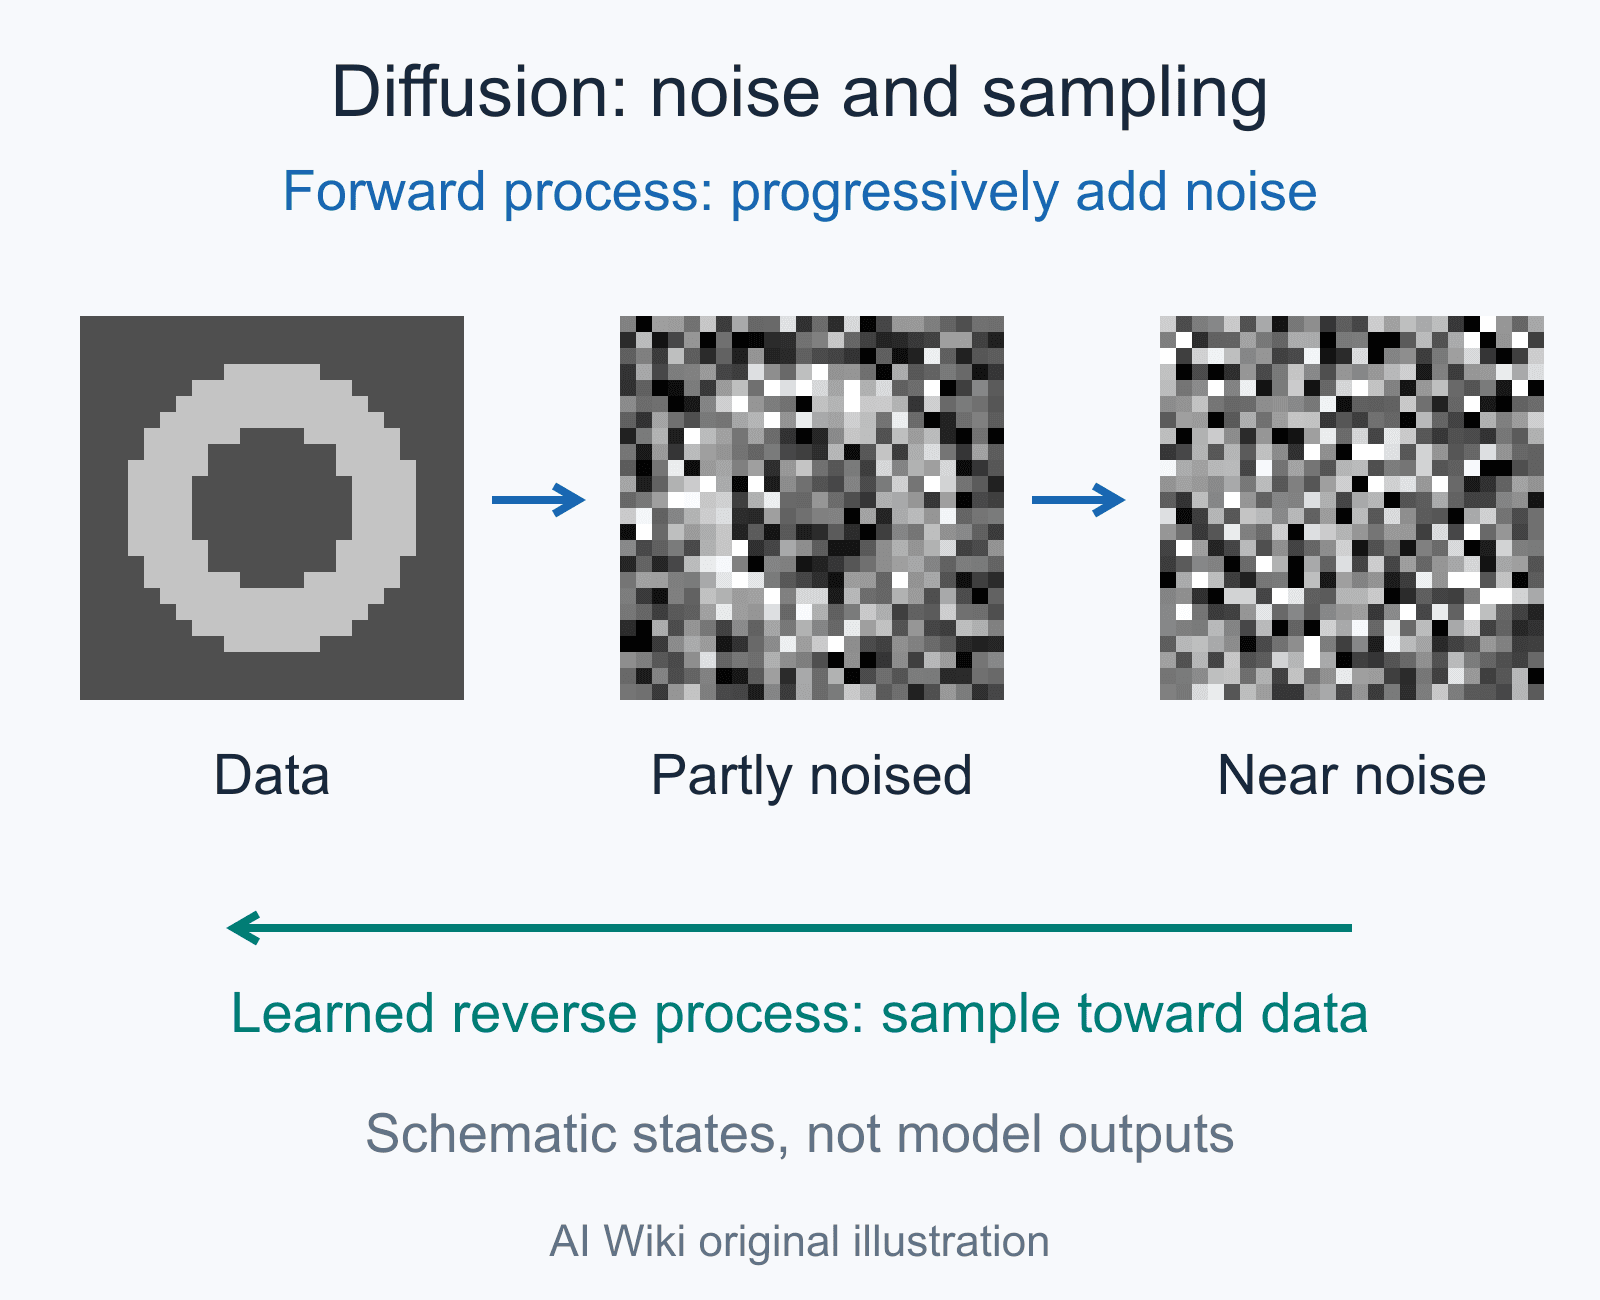
Training of the temporal model adopts the EDM framework of Karras et al. (2022), which parameterizes the diffusion process in continuous noise levels and applies preconditioning to the network inputs and outputs.[2] The paper notes that for high-resolution video the noise schedule must be shifted toward higher noise levels relative to the schedule used for image training, because larger spatial extents lower the effective signal-to-noise ratio at any given noise level. This shifted schedule is applied during the high-resolution finetuning stage and is reported to be important for stable convergence at 576x1024.[2] See EDM (Elucidating Diffusion Models) for the underlying framework.
What are the three training stages of SVD?
Stable Video Diffusion is trained in three sequential stages, each consuming a different data mixture and resolution.[2]
Stage I, image pretraining. The model is initialized from the released Stable Diffusion 2.1 checkpoint, which provides a strong visual prior for natural images and serves as the spatial backbone. The paper notes that initializing video training from a well-tuned image model is a substantially stronger starting point than training from scratch.[2]
Stage II, video pretraining. Temporal layers are inserted, and the model is trained on the curated LVD-F corpus at lower spatial resolution (256x384) and 14 frames per clip. The pretraining set is constructed by starting from approximately 580 million video-clip pairs collected with cut detection, captioning, and filtering, then reducing to roughly 152 million examples that pass thresholds on optical flow magnitude (to remove static clips), aesthetic and CLIP-score quality, and OCR text density (to remove clips dominated by overlaid text).[2][14] Captions are generated automatically: the central frame is captioned with CoCa, the whole clip is captioned with V-BLIP, and a large language model fuses the two captions into a single summary description.[2][14]
Stage III, high-quality video finetuning. The pretrained video model is finetuned on a high-quality dataset of roughly 1 million clips at 576x1024, producing a 14-frame model (the released SVD checkpoint) and a 25-frame model; Stability AI's model card describes SVD-XT as finetuned from the 14-frame SVD.[2][3][19]
Stability AI reports that total training compute for the released checkpoints was approximately 200,000 A100 80GB GPU-hours with most training run on 48 x 8 A100 GPUs, with energy consumption of roughly 64,000 kWh and estimated CO2 emissions of about 19,000 kg CO2 equivalent.[3]
What downstream tasks can the SVD backbone support?
Beyond core image-to-video generation, the paper shows that the SVD weights provide a useful initialization for several downstream video and 3D tasks. Stability AI trained a family of camera-motion LoRA adapters within the temporal attention blocks, trained on a small dataset with rich camera-motion metadata split into three categories (horizontally moving, zooming, and static), enabling post-hoc camera-motion control.[2] The same backbone, finetuned on Objaverse and MVImgNet multi-view object data, produces SVD-MV, a multi-view diffusion model the paper reports outperforms image-based novel-view-synthesis baselines (Zero123XL, SyncDreamer) at lower compute cost.[2]
What versions of Stable Video Diffusion were released?
The Stable Video Diffusion family comprises several checkpoints released between November 2023 and mid-2024. The first two (SVD and SVD-XT) appeared with the original research preview; the third (SVD-XT 1.1) was an opinionated finetune released in February 2024.
| Checkpoint | Release date | Resolution | Frames | Notable feature |
|---|---|---|---|---|
| SVD Image-to-Video | 21 Nov 2023 | 576x1024 | 14 | Base latent video diffusion model |
| SVD-XT Image-to-Video | 21 Nov 2023 | 576x1024 | 25 | Finetuned from SVD for longer clips |
| SVD-XT 1.1 | Feb 2024 | 576x1024 | 25 | Fixed conditioning at 6 fps, motion_bucket_id 127 |
| SV3D_u | 18 Mar 2024 | 576x576 | 21 | Orbital novel-view synthesis |
| SV3D_p | 18 Mar 2024 | 576x576 | 21 | Camera-path conditioned multi-view |
| SV4D | 24 Jul 2024 | 576x576 | 5 frames x 8 views | Video-to-multi-view-video |
SVD and SVD-XT (November 2023)
The two checkpoints in the original release share the same architecture and training pipeline but differ in clip length. The base SVD model generates 14 frames at 576x1024, while SVD-XT is a continuation finetune of SVD that produces 25 frames at the same resolution.[3][11] On an NVIDIA A100 80GB GPU, Stability AI quotes inference times of approximately 100 seconds per clip for SVD and 180 seconds for SVD-XT.[3] Both models were distributed under a non-commercial research-preview license at first release and later moved to the Stable Video Diffusion Community License framework.[1][3]
SVD-XT 1.1 (February 2024)
In early February 2024, Stability AI CTO Tom Mason announced SVD 1.1 (officially stable-video-diffusion-img2vid-xt-1-1), a finetune of SVD-XT explicitly optimized for consistency rather than flexibility.[4][5] The 1.1 checkpoint was finetuned with fixed micro-conditioning at 6 fps and motion_bucket_id 127, which Stability AI states improves output consistency at the cost of being tuned for a narrower operating point. The values remain user-adjustable at inference, but quality is best at the trained defaults.[5] Stability AI offered SVD 1.1 through the Stability AI Membership program it had introduced in December 2023: commercial use required a paid membership tier, while the model stayed free for research use.[4][23]
SVD-Image2Video and pipeline variants
The diffusers library exposes the SVD checkpoints under the StableVideoDiffusionPipeline interface, which accepts a PIL image plus the micro-conditioning scalars and returns a list of decoded frames.[11] Both the temporally consistent f8-decoder and a frame-wise decoder are shipped as separate weights; users can swap them at inference time depending on whether temporal stability of fine texture or per-frame fidelity is preferred.[3]
Stable Video 3D (March 2024)
On 18 March 2024 Stability AI released Stable Video 3D (SV3D), a model that adapts the SVD image-to-video formulation to multi-view 3D generation by treating the "video" axis as a camera trajectory around a single object.[6] SV3D ships in two variants: SV3D_u generates orbital videos around an object from a single image without explicit camera input, while SV3D_p additionally accepts a target camera trajectory.[6] SV3D was trained to generate 21 frames at 576x576 from a single context frame by adapting the SVD image-to-video model with camera path conditioning.[6][18] At release, the weights were available on Hugging Face for non-commercial use, and commercial use required a Stability AI Membership.[6]
Stable Video 4D (July 2024)
Stable Video 4D (SV4D), announced on 24 July 2024, extends SV3D to dynamic objects by accepting an input video and producing dynamic novel-view videos at eight viewpoints simultaneously.[15] The model emits a spatio-temporal grid of five frames across eight novel camera views at 576x576 resolution, for a total of 40 frames per generation, and is described in the SV4D technical report (arXiv:2407.17470).[15] The SV4D paper describes a unified diffusion model trained on a dynamic 3D object dataset curated from Objaverse. A successor, SV4D 2.0, was described in March 2025 and released in May 2025 with improved robustness to occlusion and large motion.[16][18]
Stable Video API and Stability platform
In addition to weights, Stability AI made Stable Video Diffusion available as a hosted API on the Stability AI Developer Platform. At launch on 20 December 2023 the API generated 2 seconds of MP4 video (25 generated frames plus 24 frames of FILM interpolation, output at 24 fps) in an average of 41 seconds, supported motion-strength control and layouts including 1024x576, 768x768 and 576x1024, and included safety measures and watermarking; in February 2024 Tom Mason described it as generating 4 seconds of video at 24 fps.[7][17][4] Stability AI targeted it at advertising, marketing, TV, film, and gaming.[7] The hosted Stable Video Diffusion API was deprecated on 24 July 2025, and Stability AI now directs users to self-host the weights.[20]
How was Stable Video Diffusion used?
The combination of openly distributed weights, a published training recipe, and a freely downloadable (if initially non-commercial) license made SVD broadly used by the open-source video-generation community in late 2023 and 2024. After release the checkpoints were integrated into the ComfyUI node graph framework and the Hugging Face diffusers library, enabling local image-to-video generation on consumer GPUs with appropriate quantization.[11][18] The model became a common starting point for academic work on video diffusion, video super-resolution, and 3D generation, and for downstream finetunes targeting specific domains such as human-image animation, character motion, and product visualization.
By mid-2024 the open video-model landscape had begun to expand around SVD with models that were either trained from scratch or built on top of SVD weights. Open Sora, Open-Sora-Plan, Mochi 1, HunyuanVideo, Wan 2.1, and NVIDIA Cosmos all entered the open-weights video space in 2024 and 2025, while commercial competitors Runway Gen-3, Runway Gen-4, Kling, Veo 3, and Sora 2 continued to push closed-model quality. Stable Video Diffusion's role within this ecosystem shifted from leading open model to a well-understood baseline and a source of pretrained weights for subsequent finetunes.
How does SVD compare to Runway, Pika, and AnimateDiff?
The Stable Video Diffusion paper reports user-preference evaluations against the strongest closed image-to-video systems available at the time of release (Runway Gen-2 and the pre-1.0 Pika Labs model), in which raters were shown clips generated from the same conditioning image by each system and asked to pick the more visually appealing result. In its announcement Stability AI stated: "At the time of release in their foundational form, through external evaluation, we have found these models surpass the leading closed models in user preference studies."[1] The paper states that its 25-frame image-to-video model was preferred by human voters over both closed baselines in terms of visual quality.[2][19]
| System | Developer | Release | Image-to-video | Text-to-video | Open weights |
|---|---|---|---|---|---|
| Stable Video Diffusion (SVD/SVD-XT) | Stability AI | Nov 2023 | Yes (576x1024, 14 or 25 frames) | No (no text input) | Yes (research/community license) |
| Runway Gen-2 | Runway | Mar 2023 | Yes | Yes | No |
| Pika 1.0 | Pika Labs | Nov 2023 | Yes | Yes | No |
| AnimateDiff | Guo et al. (academic) | Jul 2023 | Indirect (via personalized SD checkpoints) | Yes (via SD text prompts) | Yes (open code, motion module weights) |
Several differences are worth flagging. SVD is strictly image-to-video, while Runway Gen-2 and Pika 1.0 also accept text prompts; Pika and Runway provide hosted services with no open weights, while SVD's weights are downloadable.[1][8][9] AnimateDiff is conceptually different: it is not a standalone video model but a motion module that attaches to existing personalized Stable Diffusion checkpoints and reuses their spatial weights to animate generated frames, exposing text conditioning through the underlying SD model.[10] At the time of SVD's release, SVD's per-clip motion control via motion_bucket_id and its open weights gave researchers an extensible substrate that the closed competitors did not provide.
The released SVD checkpoints do not take text as input. Subsequent open video models including HunyuanVideo and Wan 2.1 reintroduced text conditioning at much higher quality, and by 2025 these models, along with closed systems such as Sora 2 and Veo 3, substantially exceeded SVD's quality on direct preference evaluations. Stable Video Diffusion's principal historical role is as an early open-weights latent video diffusion model with an unusually well-documented data-curation and training recipe rather than as a current state-of-the-art system.
Why is Stable Video Diffusion significant?
Several elements of the Stable Video Diffusion release have outlasted the model itself.
First, the three-stage training recipe (image pretraining, large-scale low-resolution video pretraining on curated data, high-resolution video finetuning on a small premium set) became a de facto template for subsequent open and closed video diffusion models. The paper's detailed account of cut detection, dual-captioning, optical-flow and aesthetic filtering, and OCR-based text removal gave practitioners a concrete pipeline that they could replicate or adapt to other corpora.[2]
Second, the practice of feeding scalar micro-conditioning signals (frame rate, motion magnitude) directly into the U-Net at every denoising step provided a simple alternative to text-only conditioning for video.
Third, the paper found that shifting the EDM noise schedule toward higher noise levels is essential for high-resolution video finetuning, extending to video an observation earlier work had made for high-resolution images.[2]
Fourth, SVD demonstrated that an image diffusion model's pretrained spatial weights can be used as the basis for high-quality video, multi-view, and (via SV4D) 4D generation. The same backbone supports image-to-video, novel-view synthesis, and dynamic 3D asset generation with comparatively small additional training, suggesting that learned visual priors transfer well across these tasks. This insight underpins subsequent video-3D systems including SV3D, SV4D, and external research on video diffusion as a general visual prior.[6][15]
What are the limitations of Stable Video Diffusion?
Stability AI's own model cards enumerate substantial limitations of the released SVD checkpoints.[3][11] Generated clips are short (4 seconds or less). The model does not achieve perfect photorealism, and faces and people in general may not be generated properly. SVD has no text conditioning, so it cannot follow textual instructions and cannot render legible text in the output. It sometimes generates videos with very little motion (effectively static images) or only slow camera pans. The latent autoencoder is lossy, so very fine high-frequency detail in the input image can be smoothed out in the output. Stability AI also notes that the model is not intended to generate factual depictions of real people or events, and the released inference and demo code enables image-level watermarking by default via the imWatermark library.[3][11]
The human-preference comparisons in the paper were run against closed systems as they existed in late 2023,[2] and later versions of Runway, Pika, and new commercial entrants have since moved well beyond the original SVD checkpoints. Open follow-up models including HunyuanVideo, Wan, and Mochi 1 have also exceeded SVD on length, resolution, and text-conditionability.
Finally, the non-commercial nature of the research preview, and the revenue-threshold structure of the later Stable Video Diffusion Community License, place constraints on commercial use that differ from fully permissive open-source licenses such as Apache 2.0 or MIT. Commercial deployers above the revenue threshold must obtain an enterprise license from Stability AI (the hosted API was deprecated in July 2025);[20] this is a more restrictive arrangement than that of some subsequent open video models, although less restrictive than the closed-only release model of Runway, Pika, Sora, and Veo.[4][7]
Related work
- Stable Diffusion: the image latent diffusion model whose 2.1 release provides SVD's spatial backbone.
- Latent diffusion model: the general framework of operating diffusion in a learned latent space rather than pixel space, originally introduced for images and extended to video by SVD and contemporaries.
- SDXL (Stable Diffusion XL): Stability AI's larger image diffusion model, parallel to SVD but for still images.
- EDM (Elucidating Diffusion Models): the Karras et al. preconditioning and noise-schedule framework SVD adopts during temporal training.
- U-Net: the convolutional encoder-decoder architecture used as the SVD denoiser, augmented with temporal layers.
- LoRA (Low-Rank Adaptation): the parameter-efficient finetuning method used for SVD's camera-motion adapters.
- CLIP (Contrastive Language-Image Pre-training): provides the image encoder used to embed the conditioning frame.
- Diffusion model and Diffusion models: the broader family of generative models SVD belongs to.
- Text-to-video generation: the broader task SVD's siblings address, although SVD itself is image-to-video.
- AI Video Generation: encyclopedic overview of the field SVD helped open up.
- Runway (company), Runway Gen-3 Alpha, Runway Gen-4: commercial video-generation systems by Runway, successors to Gen-2.
- Pika Labs and Pika (video generation): commercial video startup whose Pika 1.0 launched within a week of SVD.
- Sora and Sora 2: OpenAI's later text-to-video systems, of much larger scale.
- Veo, Veo 2, Veo 3: Google DeepMind's video-generation family.
- Kling (video generation) and Kling 2.1: Kuaishou's commercial video systems.
- HunyuanVideo: Tencent's open-weights video diffusion model.
- Wan 2.1, Wan 2.5, Wan 2.1-VACE: Alibaba's open video model family.
- Mochi 1: Genmo's open-weights text-to-video model.
- NVIDIA Cosmos: NVIDIA's open foundation model platform for world generation.
Continue reading
- Stability AIStability AI is a generative artificial intelligence company best known for helping fund and release the Stable Diffusion family of image models.Mentioned 33 times above
- CLIP (Contrastive Language-Image Pre-training)CLIP, short for Contrastive Language-Image Pre-training, is a family of neural networks developed by OpenAI researchers to learn a shared representation of images and natural-language descriptions.Mentioned 21 times above
- Diffusion modelA diffusion model is a generative model that learns to transform samples from a simple reference distribution into samples resembling a data distribution by reversing a gradual corruption process.Mentioned 20 times above
- Runway (company)Runway is a New York based artificial intelligence company that builds generative AI tools for video, with its Gen series of models and its GWM-1 world models.Mentioned 16 times above
- Pika (video generation)Pika is an artificial intelligence video generation platform developed by Pika Labs (legal name Mellis, Inc.) that lets users create and edit short videos from text prompts, images, and existing clips, and it…Mentioned 13 times above
- Stable DiffusionStable Diffusion is a family of generative image models that can synthesize and edit images from text and other conditions.Mentioned 10 times above
More from See also
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Stability AI, "Introducing Stable Video Diffusion", Stability AI News, 2023-11-21. stability.ai/...ideo-diffusion-open-ai-video-model. Accessed 2026-06-28.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24Andreas Blattmann, Tim Dockhorn, Sumith Kulal, Daniel Mendelevitch, Maciej Kilian, Dominik Lorenz, Yam Levi, Zion English, Vikram Voleti, Adam Letts, Varun Jampani, Robin Rombach, "Stable Video Diffusion: Scaling Latent Video Diffusion Models to Large Datasets", arXiv preprint, 2023-11-25. arxiv.org/...2311.15127. Accessed 2026-06-28.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14Stability AI, "stabilityai/stable-video-diffusion-img2vid-xt model card", Hugging Face, 2023-11-21. huggingface.co/...stable-video-diffusion-img2vid-xt. Accessed 2026-06-28.
- ^1 ^2 ^3 ^4 ^5 ^6Shubham Sharma, "Stability AI launches SVD 1.1, a diffusion model for more consistent AI videos", VentureBeat, 2024-02-06. venturebeat.com/...l-for-more-consistent-ai-videos. Accessed 2026-06-28.
- ^1 ^2 ^3 ^4Stability AI, "stabilityai/stable-video-diffusion-img2vid-xt-1-1 model card", Hugging Face, 2024-02-02. huggingface.co/...e-video-diffusion-img2vid-xt-1-1. Accessed 2026-06-28.
- ^1 ^2 ^3 ^4 ^5 ^6Stability AI, "Introducing Stable Video 3D: Quality Novel View Synthesis and 3D Generation from Single Images", Stability AI News, 2024-03-18. stability.ai/...introducing-stable-video-3d. Accessed 2026-06-28.
- ^1 ^2 ^3 ^4 ^5Stability AI, "Stable Video Diffusion Now Available on Stability AI Developer Platform API", Stability AI News, 2023-12-20. stability.ai/...oducing-stable-video-diffusion-api. Accessed 2026-06-28.
- ^1 ^2Runway, "Gen-2: Generate novel videos with text, images or video clips", Runway Research, 2023-03-20. research.runwayml.com/gen2. Accessed 2026-06-28.
- ^1 ^2Kyle Wiggers, "Pika, which is building AI tools to generate and edit videos, raises \$55M", TechCrunch, 2023-11-28. techcrunch.com/...erate-and-edit-videos-raises-55m. Accessed 2026-06-28.
- ^1 ^2Yuwei Guo, Ceyuan Yang, Anyi Rao, Zhengyang Liang, Yaohui Wang, Yu Qiao, Maneesh Agrawala, Dahua Lin, Bo Dai, "AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning", arXiv preprint, 2023-07-10. arxiv.org/...2307.04725. Accessed 2026-06-28.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10Hugging Face, "Stable Video Diffusion documentation (diffusers)", Hugging Face Docs, 2023-2024. huggingface.co/...svd. Accessed 2026-06-28.
- Stability AI, "Stable Video Diffusion Community License Agreement", Stability AI Legal, 2024. stability.ai/license. Accessed 2026-06-28.
- ^GitHub users, "[Stable Video Diffusion] parameters meaning (issue #237)", Stability-AI/generative-models, GitHub, 2023. github.com/...237. Accessed 2026-06-28.
- ^1 ^2Andreas Blattmann et al., "Stable Video Diffusion: Scaling Latent Video Diffusion Models to Large Datasets (HTML rendering)", arXiv, 2023-11-25. arxiv.org/...2311.15127. Accessed 2026-06-28.
- ^1 ^2 ^3Stability AI, "Stable Video 4D", Stability AI News, 2024-07-24. stability.ai/...stable-video-4d. Accessed 2026-06-28.
- ^Stability AI, "SV4D 2.0: Enhancing Spatio-Temporal Consistency in Multi-View Video Diffusion for High-Quality 4D Generation", Stability AI Research, 2025-03-25. stability.ai/...ion-for-high-quality-4d-generation. Accessed 2026-06-28.
- ^Shubham Sharma, "Stable Video Diffusion is now available through Stability AI API", VentureBeat, 2023-12-21. venturebeat.com/...ilable-through-stability-ai-api. Accessed 2026-06-28.
- ^1 ^2 ^3Stability AI, "Stability-AI/generative-models GitHub repository", GitHub, 2023-2024. github.com/...generative-models. Accessed 2026-06-28.
- ^1 ^2Shubham Sharma, "Stability AI debuts Stable Video Diffusion models in research preview", VentureBeat, 2023-11-23. venturebeat.com/...sion-models-in-research-preview. Accessed 2026-06-28.
- ^1 ^2 ^3Stability AI, "How to Access Stable Video Diffusion", Stability AI Knowledge Base, 2025. kb.stability.ai/...o-access-stable-video-diffusion. Accessed 2026-11-05.
- ^Jiuniu Wang, Hangjie Yuan, Dayou Chen, Yingya Zhang, Xiang Wang, Shiwei Zhang, "ModelScope Text-to-Video Technical Report", arXiv preprint, 2023-08-12. arxiv.org/...2308.06571. Accessed 2026-11-05.
- ^Haoxin Chen et al., "VideoCrafter1: Open Diffusion Models for High-Quality Video Generation", arXiv preprint, 2023-10-30. arxiv.org/...2310.19512. Accessed 2026-11-05.
- ^1 ^2Stability AI, "Introducing the Stability AI Membership", Stability AI News, 2023-12-14. stability.ai/...introducing-stability-ai-membership. Accessed 2026-11-05.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
7 revisions by 1 contributor · v7 · 4,429 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (120 claims, 27 sources fetched); 6 material + 33 minor fixed
Cite this page: AI Wiki. "Stable Video Diffusion." aiwiki.ai, updated 28 Oct 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/stable_video_diffusion