

Qwen2-VL
Qwen2-VL is a family of open-weight vision-language models released by the Qwen team at Alibaba Cloud between August and September 2024, in 2B, 7B, and 72B Instruct sizes. Its two defining innovations are Naive Dynamic Resolution, which lets the vision encoder process images of any size into a variable number of visual tokens, and Multimodal Rotary Position Embedding (M-RoPE), which unifies positional information across text, images, and video.[1][2] The 72B flagship reached state-of-the-art results at release, including a 96.5 DocVQA score and an 877 OCRBench score, and the technical report claims parity with proprietary frontier models such as GPT-4o and Claude 3.5 Sonnet on several multimodal benchmarks.[1][7] Qwen2-VL succeeded the original Qwen-VL of August 2023 and was itself superseded in January 2025 by Qwen2.5-VL.[3][4]
Infobox
| Attribute | Value |
|---|---|
| Developer | Qwen team, Alibaba Cloud |
| Series | Qwen2-VL-2B-Instruct, Qwen2-VL-7B-Instruct, Qwen2-VL-72B-Instruct |
| Initial release | 29 August 2024 (2B and 7B) |
| Flagship release | 19 September 2024 (72B Instruct) |
| Architecture | Vision Transformer encoder (about 675M parameters) plus Qwen2 LLM decoder |
| Training data | Approximately 1.4 trillion tokens across two pretraining stages |
| Knowledge cutoff | June 2023 (image data) |
| License (2B, 7B) | Apache 2.0 |
| License (72B) | Tongyi Qianwen License (custom) |
| Paper | arXiv:2409.12191, 18 September 2024 |
| Repository | github.com/QwenLM/Qwen2-VL |
What is Qwen2-VL?
Qwen2-VL is a multimodal model that accepts text plus images or video and produces text, built by pairing a shared Vision Transformer encoder with a Qwen2 language decoder. The Qwen team framed the August 2024 launch around perception, writing that the goal was to help the model "see the world more clearly," and described Qwen2-VL as a "visual agent" that, "with the abilities of complex reasoning and decision making, can be integrated with devices like mobile phones, robots, etc."[2] Three Instruct variants were released, at 2B, 7B, and 72B parameters, all sharing the same roughly 675 million parameter vision encoder.[1][7]
Background
The Qwen vision-language line began with Qwen-VL, posted to arXiv on 24 August 2023 by Jinze Bai, Shuai Bai, and collaborators. The first paper, titled "Qwen-VL: A Versatile Vision-Language Model for Understanding, Localization, Text Reading, and Beyond," paired the Qwen language backbone with a visual receptor and introduced a three-stage training pipeline together with image-caption-box alignment data to enable grounding and OCR-style text reading.[3] Qwen-VL and its Qwen-VL-Chat instruction-tuned variant established the design ethos that later iterations would inherit: dense visual feature extraction, autoregressive decoding, and emphasis on multilingual coverage. The first generation used a fixed input resolution and a learned re-sampler to compress visual tokens to a constant length, an approach Qwen2-VL would explicitly abandon.[3] The Qwen language stack itself moved to the Qwen2 generation in mid-2024, and a vision-language follow-up built on that backbone became the natural next step.[5]
By mid-2024, open-weight vision-language models were proliferating across labs in China, the United States, and Europe. The pre-Qwen2-VL landscape included LLaVA-NeXT, InternVL 1.5, MiniCPM-V 2.5, CogVLM2, and the Idefics line from Hugging Face, all of which competed on a shifting frontier of OCR fidelity, document understanding, and instruction following. Most of these systems still relied on tiled or windowed handling of high-resolution inputs, a workaround whose limitations the Qwen team explicitly used to motivate their dynamic-resolution design.[1][7]
When was Qwen2-VL released?
Qwen2-VL was announced on 29 August 2024, with the 2B and 7B Instruct weights published immediately on Hugging Face and ModelScope. At launch Alibaba released only an API for the 72B model, offered through DashScope under the model name qwen-vl-max-0809, and the official repository said the open-source 72B was "coming soon."[2][10] The 72B-Instruct weights and quantized AWQ and GPTQ Int4 and Int8 variants were published on 19 September 2024 (Beijing time) alongside the technical report, which arXiv timestamps as 18 September 2024 (UTC).[1][10] A revised version 2 of the paper was posted on 3 October 2024.[1]
The named lead authors on the technical report are Peng Wang and Shuai Bai. Co-authors include Sinan Tan, Shijie Wang, and roughly fifteen further collaborators from the Qwen team; the work credits collective contributions across the Alibaba group's multimodal and Tongyi Lab efforts.[1] Shuai Bai had also been a lead author on the original Qwen-VL paper, providing personnel continuity across the two generations.[3] Five months later, the team released Qwen2.5-VL (26 January 2025), which kept the dynamic-resolution and M-RoPE design but added window attention in the vision encoder and absolute time encoding for video, while extending the size lineup to 3B, 7B, and 72B variants.[4]
How does Qwen2-VL work?
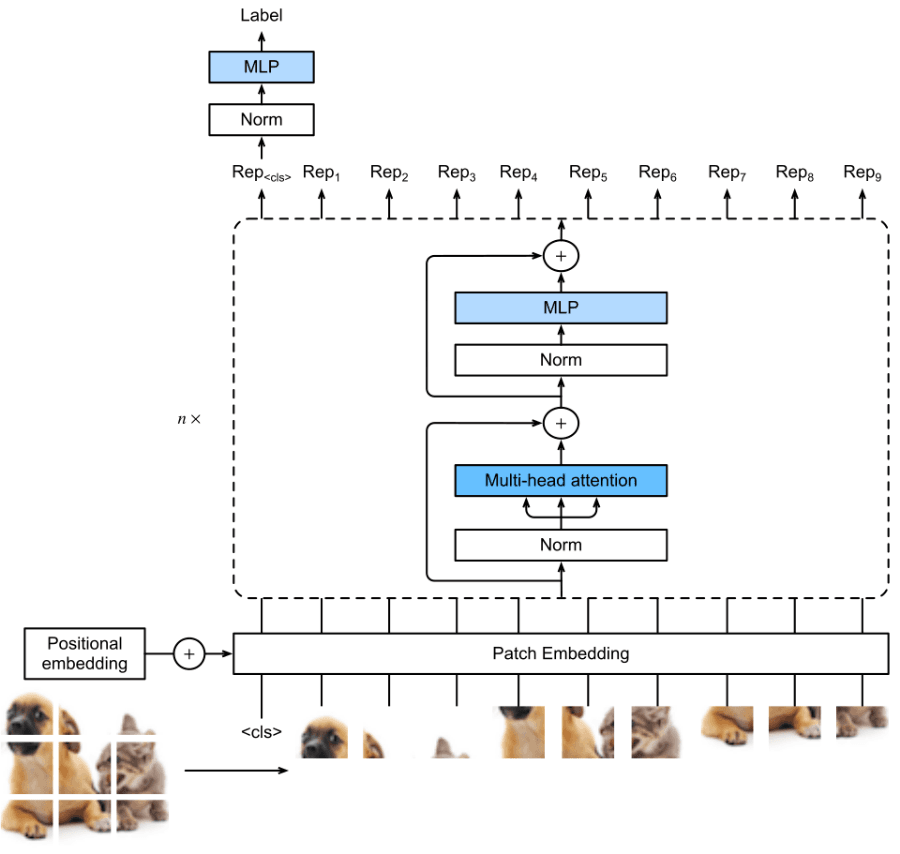
Qwen2-VL keeps the same broad shape as most modern vision-language models: a Vision Transformer encoder produces a sequence of visual tokens that is concatenated with the text token sequence and fed into an autoregressive language model. Two design choices distinguish it from contemporaries.[1]
What is Naive Dynamic Resolution?
Traditional vision encoders are trained at a fixed input size (commonly 224 or 336 pixels square) and either resize, pad, or tile larger inputs. Qwen2-VL instead trains its encoder to process inputs at the resolution they arrive in, mapping the image to a number of visual tokens proportional to its area. The mechanism is called Naive Dynamic Resolution because no learned re-sampler or Q-Former is involved; the ViT (Vision Transformer) operates on 14 by 14 patches and emits one token per patch, modulo a 2 by 2 token-merging step that reduces the sequence by a factor of four before it reaches the LLM.[1][7]
To make this work, the ViT was retrofitted with 2D rotary position embeddings rather than the fixed learned absolute position embeddings used in the original Vision Transformer (ViT). The 2D RoPE applies separate rotary frequencies to the height and width axes, so the same encoder can interpret patch positions at any resolution it encounters at inference. The Qwen team contrasts this with the alternative of tiling a large image into many fixed-size crops, an approach that fragments long-range visual context and inflates the visual-token budget by duplicating overlap regions.[1][7]
The result is that a small thumbnail might generate only a handful of visual tokens while a high-resolution document image may produce thousands. This makes the model behave more like human perception (devoting representation budget to the available detail) and lets it handle extreme aspect ratios and very dense documents without the lossy fixed-window tiling used by some earlier systems.[1][2] The shared encoder has roughly 675 million parameters and is reused unchanged across the 2B, 7B, and 72B configurations so the vision compute does not scale with the language model.[7] This shared-encoder design also keeps the cost of running the small variant low: a 1.5B language decoder is paired with the same 675M ViT used by the 72B, which is significant since the encoder dominates inference cost for small models on high-resolution inputs.
How does M-RoPE work?
The second key contribution is M-RoPE (Multimodal Rotary Position Embedding), a generalization of Rotary position embedding (RoPE) that decomposes positional information into three components: a temporal index, a height index, and a width index. Text tokens use identical values across the three components, behaving like the standard 1D RoPE. Image tokens carry a fixed temporal index but distinct spatial coordinates. Video tokens increment the temporal index with each frame while preserving spatial layout. The decomposition lets a single embedding scheme address 1D text, 2D images, and 3D video sequences inside the same context window without ad hoc switching.[1][7]
Concretely, when an image is inserted into a chat context, the image's patch tokens share a single temporal index while their height and width indices vary across the image, and position numbering for each modality starts one past the maximum position ID of the preceding modality, so text after an image resumes just beyond the image's largest index. For video, the temporal index increments with each sampled frame, providing a natural ordering signal that the model uses to answer questions about event order in long clips. The Qwen team argues that because M-RoPE keeps the position IDs of images and videos small, the model can extrapolate to longer sequences at inference.[1][7]
How was Qwen2-VL trained?
The report describes a three-stage training procedure. In the first stage, only the ViT is trained on image-text pairs to align visual features with the LLM's token space; this stage focuses on image-text relationships, text recognition within images (OCR), and image classification.[7] The second stage unfreezes all parameters and trains on a large mixed-modality corpus that includes image-text pairs, OCR data, interleaved documents, and visual question answering tasks. The final stage freezes the ViT and instruction-tunes the language model on multimodal chat data using the ChatML format. Pretraining used approximately 600 billion tokens in the first phase and around 800 billion in the second, for roughly 1.4 trillion tokens of multimodal data overall.[7]
The post-training stage for the Instruct variants was supervised fine-tuning on ChatML-formatted data mixing pure-text dialogue with multimodal conversations, including image question answering, document parsing, multi-image comparison, video comprehension, video-stream dialogue, and agent interactions; the report does not describe a separate preference-optimization stage.[7] The report states that Qwen2-VL supports a 32K-token context length.[7]
Each variant pairs the 675M ViT with a Qwen2 language model: the 2B and 7B use the respective dense Qwen2 backbones, while the 72B variant pairs with Qwen2-72B.[1] The 72B-Instruct release lists 73 billion total parameters and BF16 precision on its Hugging Face model card.[6] Quantization variants released alongside the 72B used 4-bit and 8-bit AWQ and GPTQ to reduce memory requirements; the BF16 weights alone total about 147 GB.[6]
Variants and Release Channels
| Variant | LLM backbone | Vision encoder | Release | License |
|---|---|---|---|---|
| Qwen2-VL-2B-Instruct | Qwen2-1.5B class | 675M ViT | 29 Aug 2024 | Apache 2.0[8] |
| Qwen2-VL-7B-Instruct | Qwen2-7B | 675M ViT | 29 Aug 2024 | Apache 2.0[9] |
| Qwen2-VL-72B-Instruct | Qwen2-72B | 675M ViT | 19 Sep 2024 | Tongyi Qianwen License[6] |
| Qwen2-VL-72B-Instruct-AWQ / GPTQ-Int4 / GPTQ-Int8 | Quantized 72B | 675M ViT | 19 Sep 2024 | Tongyi Qianwen License[6] |
All weights are mirrored on Hugging Face under the Qwen/Qwen2-VL-* namespace and on ModelScope, the Alibaba Cloud model hub. In May 2026 the 2B-Instruct card reported more than 3.7 million monthly downloads on Hugging Face (about 1.0 million by November 2026), indicating the small variant became a popular building block for on-device and research use.[8] The license terms differ between the small and flagship models: the 2B and 7B weights are distributed under the permissive Apache 2.0 license, while the 72B uses Alibaba's custom Tongyi Qianwen License that imposes commercial-use thresholds and other conditions.[2][6][8][9]
How does Qwen2-VL perform on benchmarks?
The technical report and the official Qwen2-VL blog publish per-variant scores across image, video, and agent benchmarks. The headline figures for the Instruct variants are reproduced below.[2][6][7]
The reported evaluation followed the standard practice of reporting on widely used multimodal suites. The team selected six image benchmarks (MathVista, RealWorldQA, MMBench-EN, MTVQA, OCRBench, DocVQA) and four video benchmarks (Video-MME, MVBench, EgoSchema, PerceptionTest) as headline results, alongside the agent suites discussed below. Comparisons in the technical report span GPT-4o, Claude 3.5 Sonnet, Gemini 1.5 Pro, InternVL 2, and LLaVA-OneVision.[7]
Image benchmarks
| Benchmark | Qwen2-VL-2B | Qwen2-VL-7B | Qwen2-VL-72B |
|---|---|---|---|
| MathVista (testmini) | 43.0 | 58.2 | 70.5 |
| RealWorldQA | 62.9 | 70.1 | 77.8 |
| MMBench-EN (test) | 74.9 | 83.0 | 86.5 |
| MTVQA | 18.1 | 25.6 | 30.9 |
| OCRBench | 794 | 845 | 877 |
| DocVQA (test) | 90.1 | 94.5 | 96.5 |
Video benchmarks
The team reports that Qwen2-VL-72B set a state-of-the-art DocVQA score of 96.5 and an OCRBench score of 877 at release, ahead of contemporaneous proprietary systems, while exceeding GPT-4o on most general benchmarks in the report's comparison table, though trailing it on MMMU (64.5 vs 69.1) and MathVision (25.9 vs 30.4) and surpassing it on multilingual OCR for most languages except Arabic.[2][7] On MathVista the 72B scored 70.5 against GPT-4o's reported 63.8 in the same evaluation table, and on RealWorldQA its 77.8 exceeded GPT-4o's 75.4 and the previous open state of the art of 72.2.[7] The official blog summarizes the result by noting that the 72B variant achieves "top-tier performance across most metrics, often surpassing even closed-source models like GPT-4o and Claude 3.5-Sonnet."[2] The 2B and 7B Instruct variants also became reference points for the open-weights community: at release, Qwen2-VL-2B's 90.1 DocVQA score was ahead of InternVL2-2B's 86.9 on the model card's comparison table.[8]
Agentic capabilities
Qwen2-VL was one of the first openly released vision-language models to publish strong results on visual-agent tasks. The 72B model recorded a 93.1 type-match and 53.2 exact-match score on the team's internal function calling benchmark (FnCall), 89.6 type-match and 72.1 exact-match on the AITZ Android UI-operation benchmark (against GPT-4o's 70.0 and 35.3), and reported additional results on card games, ALFRED robotic control, and vision-language navigation in the technical report.[6][7] The Qwen2-VL blog frames the model as a "visual agent" capable of operating mobile phones, robots, and other devices through screen understanding plus tool calls.[2]
The agent evaluation in the paper is notable because it spans both UI control (which requires reading screenshots and emitting structured action tokens such as click coordinates and keystrokes) and embodied tasks like ALFRED. The AITZ numbers, in particular, demonstrated that an open-weight model could approach the kind of GUI automation that frontier closed models such as Claude with computer use were beginning to advertise around the same time.[7]
What can Qwen2-VL do?
Beyond raw benchmark numbers, the released variants support several concrete capabilities highlighted by Alibaba and by independent secondary coverage:
- Long video understanding. The vision encoder samples frames and feeds them through the M-RoPE temporal index. Alibaba states that Qwen2-VL "can understand videos over 20 minutes for high-quality video-based question answering, dialog, content creation," and evaluation in the report used up to 768 frames per clip.[2][7]
- Multilingual text-in-image reading. The reported MTVQA scores cover Arabic, German, French, Italian, Japanese, Korean, Russian, Thai, and Vietnamese, and the model cards list support for "most European languages" plus Chinese.[2][9]
- Function calling and tool use. The Qwen2-VL chat templates expose tool-call schemas that let the model emit structured JSON requests to external APIs such as weather, flight status, and package tracking endpoints.[2]
- Computer use and GUI control. The 72B variant's Android evaluation tests its ability to interpret screenshots and emit action sequences, an early version of the visual-agent pattern that frontier labs later popularized under names like Anthropic Computer Use.[7]
- Document and code understanding. Naive Dynamic Resolution makes the model effective on dense documents, formula-heavy pages, handwritten text, and code-from-screenshot tasks, and the team published recipes for diagram-to-code workflows.[2]
The combination of these capabilities lets a single model serve as the perception layer for a broad range of pipelines: an enterprise might use the 7B variant to parse a stream of invoices, summarize a security-camera feed, and answer end-user chat questions on documentation screenshots, all without swapping in specialized models.
Ecosystem and Adoption
The official QwenLM/Qwen2-VL repository on GitHub provides example inference code, evaluation scripts, and a qwen-vl-utils helper package used by the Hugging Face Transformers integration. The model class Qwen2VLForConditionalGeneration and matching AutoProcessor were merged into the Hugging Face Transformers library shortly after release, enabling a one-line .from_pretrained() workflow that closely mirrors text-only Qwen2 usage.[9] Within weeks of launch, Qwen2-VL was supported by vLLM for high-throughput serving, by AutoGPTQ and AutoAWQ for low-bit quantization, by Llama-Factory for fine-tuning.[2]
The 2B variant became especially popular in edge and research settings. Its small footprint (around 4 GB at BF16) and Apache 2.0 license made it a common starting point for downstream fine-tuning on niche document-understanding and OCR tasks, including chart parsing, receipt recognition, and form extraction. The 7B Instruct variant served as the default mid-size baseline for downstream agentic and document tasks during late 2024.[9]
Independent secondary coverage credited the release with raising the bar for open multimodal models. SiliconANGLE described the launch as bringing video reasoning of "advanced" caliber into open weights, while emphasizing Alibaba's claim that the 72B variant could match or exceed GPT-4o and Claude 3.5 Sonnet on selected benchmarks.[12] The hub statistics for the 2B and 7B variants (millions of downloads per month) made Qwen2-VL one of the most-used open-weight multimodal models in the second half of 2024.[8] Within Alibaba's own ecosystem, the 72B model was offered as a managed API through DashScope.[2]
Limitations
The model cards for all three variants enumerate the same set of caveats, which match the discussion in the technical report:[6][7][9]
- The model cannot process audio tracks in video inputs.
- The training corpus has an image data cutoff of June 2023, so it lacks awareness of events and entities introduced afterward.
- Its ability to recognize specific individuals or intellectual property (well-known personalities and brands) is limited.
- Performance degrades on long multi-step instructions that require many tool calls in sequence.
- Object counting in cluttered scenes remains unreliable.
- 3D spatial reasoning (depth, occlusion, geometric layout) is weaker than 2D understanding.
The Apache 2.0 grant for the small variants is more permissive than the bespoke license attached to the 72B model, which complicates downstream redistribution and commercial deployment when the flagship is required.[2][6] The next release kept a split: Qwen2.5-VL-7B used Apache 2.0, while the 3B used the non-commercial Qwen Research License and the 72B the Qwen License.[14][15]
Is Qwen2-VL open source?
Qwen2-VL is partly open and partly source-available. The 2B and 7B Instruct weights are released under the permissive Apache 2.0 license, allowing free commercial use, modification, and redistribution.[8][9] The 72B flagship and its quantized derivatives are distributed under Alibaba's custom Tongyi Qianwen License, which adds commercial-use thresholds and other conditions, so it is source-available rather than fully open source.[6] All weights are publicly downloadable from Hugging Face and ModelScope, and the inference and evaluation code in the QwenLM/Qwen2-VL repository is open. With the next generation, licensing remained split: Qwen2.5-VL-7B is Apache 2.0, the 3B uses the Qwen Research License, and the 72B uses the Qwen License.[14][15]
Related Work and Successors
Qwen2-VL sits within a wave of late-2024 open-weight vision-language releases. Direct contemporaries include InternVL from Shanghai AI Lab, LLaVA (Large Language and Vision Assistant) derivatives such as LLaVA-OneVision, DeepSeek Janus from DeepSeek, and Llama 3.2's 11B and 90B vision variants from Meta.[1] Among Chinese labs, DeepSeek-VL2 followed shortly after, and the broader Multimodal Models field consolidated around the dynamic-resolution plus M-RoPE recipe that Qwen2-VL helped popularize.[4]
In terms of design philosophy, Qwen2-VL contrasts with two adjacent approaches. Models like LLaVA-NeXT and InternVL 1.5 relied on tiling high-resolution inputs into multiple fixed-size crops, while models such as Idefics-2 used learned re-samplers (Perceiver-style attention) to compress visual tokens to a fixed budget. Qwen2-VL's argument is that doing neither, and instead training the encoder directly on variable-length inputs, simplifies the architecture, improves long-context fidelity on dense visuals, and avoids quality losses from resampling.[1] The recipe was widely adopted: The Qwen3-VL series, for example, builds on the design with an upgraded "Interleaved-MRoPE" position embedding.[13]
How does Qwen2-VL differ from Qwen2.5-VL?
The direct successor, Qwen2.5-VL, was released on 26 January 2025 with 3B, 7B, and 72B variants (Apache 2.0 for the 7B, the Qwen Research License for the 3B, and the Qwen License for the 72B), an updated vision encoder using window attention, and absolute-time encoding for video to enable second-level temporal grounding.[4] Qwen2.5-VL extended the agent narrative further with explicit GUI-control prompting and structured "QwenVL HTML" document outputs, and Alibaba reported that the 3B successor exceeded Qwen2-VL-7B on most image benchmarks.[4] Subsequent releases in the family include Qwen3-VL (2B through 235B variants released across late 2025) which extended the architecture further with native long-context support and additional agentic capabilities, including a separate "Thinking" track that interleaves reasoning chains with visual observations.[13]
Continue reading
- QwenQwen is a family of large language models and multimodal models developed by the Qwen Team at Alibaba Cloud.Mentioned 26 times above
- GPT-4oGPT-4o (Generative Pre-trained Transformer 4 Omni) is a natively multimodal large language model developed by OpenAI and announced on May 13, 2024 at the company's "Spring Update" livestream.Mentioned 8 times above
- Qwen2.5-VLQwen2.5-VL is a series of open-weight vision-language models released on 26 January 2025 by the Qwen team at Alibaba (Alibaba Cloud), succeeding the earlier Qwen2-VL family.Mentioned 7 times above
- Tongyi QianwenTongyi Qianwen (通义千问), the brand often glossed in English as "seeking truth by asking a thousand questions," is Alibaba Group's flagship large language model and conversational AI brand, launched by Alibaba…Mentioned 5 times above
- Vision TransformerThe Vision Transformer (ViT) is a deep learning architecture that represents an image as a sequence of fixed-size patches and processes that sequence with a Transformer encoder.Mentioned 5 times above
- LLaVA (Large Language and Vision Assistant)LLaVA (Large Language and Vision Assistant) is an open-source family of multimodal large language models that connects a frozen vision encoder to a pre-trained large language model through a single learned…Mentioned 5 times above
More from See also
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16Peng Wang, Shuai Bai, Sinan Tan, Shijie Wang, et al., "Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution", arXiv:2409.12191, 2024-09-18 (v1), 2024-10-03 (v2). arxiv.org/...2409.12191. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16Qwen Team, "Qwen2-VL: To See the World More Clearly", Qwen Blog (Alibaba Cloud), 2024-08-29. qwenlm.github.io/...qwen2-vl. Accessed 2026-06-23.
- ^1 ^2 ^3 ^4Jinze Bai, Shuai Bai, Shusheng Yang, et al., "Qwen-VL: A Versatile Vision-Language Model for Understanding, Localization, Text Reading, and Beyond", arXiv:2308.12966, 2023-08-24. arxiv.org/...2308.12966. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4 ^5Qwen Team, "Qwen2.5-VL! Qwen2.5-VL! Qwen2.5-VL!", Qwen Blog (Alibaba Cloud), 2025-01-26. qwenlm.github.io/...qwen2.5-vl. Accessed 2026-05-21.
- ^Qwen Team, "Qwen2 Technical Report", arXiv:2407.10671, 2024-07-15. arxiv.org/...2407.10671. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10Qwen Team, "Qwen/Qwen2-VL-72B-Instruct Model Card", Hugging Face, 2024-09-18. huggingface.co/...Qwen2-VL-72B-Instruct. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21Peng Wang, Shuai Bai, et al., "Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution (HTML version)", arXiv:2409.12191v1, 2024-09-18. arxiv.org/...2409.12191v1. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4 ^5 ^6Qwen Team, "Qwen/Qwen2-VL-2B-Instruct Model Card", Hugging Face, 2024-08-29. huggingface.co/...Qwen2-VL-2B-Instruct. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Qwen Team, "Qwen/Qwen2-VL-7B-Instruct Model Card", Hugging Face, 2024-08-29. huggingface.co/...Qwen2-VL-7B-Instruct. Accessed 2026-05-21.
- ^1 ^2Qwen Team, "QwenLM/Qwen2-VL GitHub Repository", GitHub, 2024-08-29. github.com/...Qwen2-VL. Accessed 2026-05-21.
- OpenLM.ai, "Qwen2-VL Benchmark Compilation", OpenLM.ai, 2024-09. openlm.ai/qwen2-vl. Accessed 2026-05-21.
- ^Kyt Dotson, "Alibaba announces Qwen2-VL AI model with advanced video analysis and reasoning capabilities", SiliconANGLE, 2024-08-30. siliconangle.com/...nalysis-reasoning-capabilities. Accessed 2026-05-21.
- ^1 ^2Qwen Team, "QwenLM/Qwen3-VL GitHub Repository", GitHub, 2025-09-23. github.com/...Qwen3-VL. Accessed 2026-05-21.
- ^1 ^2Qwen Team, "Qwen/Qwen2.5-VL-3B-Instruct Model Card" (license: Qwen Research License), Hugging Face, 2025-01-26. huggingface.co/...Qwen2.5-VL-3B-Instruct. Accessed 2026-11-03.
- ^1 ^2Qwen Team, "Qwen/Qwen2.5-VL-72B-Instruct Model Card" (license: Qwen License), Hugging Face, 2025-01-27. huggingface.co/...Qwen2.5-VL-72B-Instruct. Accessed 2026-11-03.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
7 revisions by 1 contributor · v7 · 3,718 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (120 claims, 15 sources fetched); 7 material + 29 minor fixed
Cite this page: AI Wiki. "Qwen2-VL." aiwiki.ai, updated 1 Nov 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/qwen2_vl